




Impact statement
Fast and accurate reduced-order models (ROMs) are essential in many areas of science and engineering. To fully benefit from the recent GPU computing revolution and from deep-learning-based error correction, we need ROM techniques that remain efficient on modern hardware. This work provides the first detailed GPU implementation and systematic benchmarking of the ECSW hyper-reduction method, compared against standard tensor-based ROMs. Focusing on quadratic convective nonlinearities, we quantify how performance depends on the number of reduced modes and sampled points, and identify when hyper-reduction is faster than the quadratic ROM. Our results give clear, practical guidelines on when the extra approximation of ECSW is worthwhile, helping researchers design ROM and hybrid ROM–deep learning pipelines that are accurate and computationally efficient.
1. Introduction
Model order reduction has become an important class of methods to reduce the computational cost of high-fidelity numerical simulations. Among classical reduction techniques, the Proper Orthogonal Decomposition (POD) combined with Galerkin projection remains the cornerstone of projection-based reduced-order modeling (Lumley, Reference Lumley1979; Sirovich, Reference Sirovich1987; Holmes et al., Reference Holmes, Lumley and Berkooz1996; Noack et al., Reference Noack, Afanasiev, Morzyński, Tadmor and Thiele2003). POD extracts an optimal set of orthonormal modes that capture the dominant energetic structures of the flow, while Galerkin projection yields a low-dimensional dynamical system governing the temporal evolution of their amplitudes. This formulation provides a mathematically grounded and physically interpretable surrogate directly derived from the full-order equations. POD–Galerkin ROMs have been successfully applied to canonical fluid flows such as the cylinder wake or cavity oscillations, offering drastic cost reductions while preserving key physical mechanisms.
By projecting the governing equations onto a low-dimensional subspace spanned by data-driven modes, reduced-order models (ROMs) can accelerate transient fluid flow computations by several orders of magnitude. However, this gain in efficiency is often achieved at the expense of accuracy and robustness, especially for nonlinear, advection-dominated systems. Moreover, even in their simplest formulations, classical ROMs can become computationally expensive when nonlinear terms must be evaluated in the full space of the original degrees of freedom.
For quadratic nonlinearities, which appear in many canonical fluid dynamics equations such as Burgers, Kuramoto–Sivashinsky, Korteweg–de Vries, or the incompressible Navier–Stokes equations, it is possible to derive a closed reduced model entirely in the latent space through tensorial projection of the quadratic term. While this removes the need to return to the full-order space, two limitations remain. First, evaluating the quadratic term in reduced coordinates scales cubically with the number of retained modes, resulting in rapidly increasing online cost and memory requirements. Second, standard Galerkin ROMs remain poorly suited to strongly convective dynamics, often requiring intrusive stabilization or closure modeling to achieve predictive accuracy.
To address these issues, two main research directions have emerged almost independently. A first class of approaches seeks to alleviate the cubic cost of nonlinear evaluation by approximating the nonlinear operator without resorting to full-space computations. These so-called hyper-reduction methods approximate the nonlinear residual using a restricted set of sampling points or degrees of freedom, and reconstruct the reduced projection through interpolation or weighted quadrature. The most widely used among these are the Discrete Empirical Interpolation Method (DEIM) (Barrault et al., Reference Barrault, Maday, Nguyen and Patera2004; Chaturantabut and Sorensen, Reference Chaturantabut and Sorensen2010) and Gappy POD (Everson and Sirovich, Reference Everson and Sirovich1995), which follows a similar philosophy and is often used for sensor placement and incomplete-data problems. More recent methods, such as the Energy-Conserving Sampling and Weighting (ECSW) technique (Chapman et al., Reference Chapman, Avery, Collins and Farhat2017), approximate the nonlinear term through a weighted sampling of quadrature points, with optimized weights ensuring that the reduced operator reproduces the full-order projection. All share the same objective: replacing the global nonlinear evaluation with a reduced, efficiently computable surrogate that operates entirely in a reduced subspace, thereby circumventing the need for costly evaluations in the full-order space. However, these methods do not aim to improve the intrinsic accuracy of ROMs for a given level of reduction; they merely introduce additional approximations to make the nonlinear evaluation tractable without addressing the underlying limitations of the reduced representation itself.
Among these, ECSW has proven particularly well suited for finite element formulations. It preserves the symmetry and positive definiteness of reduced operators and guarantees numerical stability during time integration, features crucial for conservative systems. Furthermore, ECSW is structure-preserving, compatible with conservation laws and Hamiltonian formulations, and has demonstrated greater robustness and accuracy than DEIM for highly nonlinear or stiff dynamics. Recent implementations (Carlino, Reference Carlino2021; Riffaud et al., Reference Riffaud, Bergmann, Farhat, Grimberg and Iollo2021) have also shown that ECSW naturally extends to nonlinear manifolds and mappings, improving its generality for complex geometries and multiphysics problems.
A second body of work has attempted to improve the accuracy of ROMs using data-based corrections and closure. In particular, with the recent rise of deep learning in physics applications, neural networks have been used as data-driven error correctors, enhancing ROM fidelity while retaining some level of physical interpretability. A first closure modeling approach, inspired by the Mori–Zwanzig formalism and Takens’ embedding theorem (Zwanzig, Reference Zwanzig1961; Mori, Reference Mori1965; Takens, Reference Takens, Rand and Young1981), introduces time-dependency and memory effects to account for the influence of truncated modes. Representative examples include LSTM-ROMs (Wang et al., Reference Wang, Ripamonti and Hesthaven2020) and CDROM (Menier et al., Reference Menier, Bucci, Yagoubi, Mathelin and Schoenauer2023), which employ recurrent or convolutional architectures to reconstruct the temporal correlations neglected by standard Galerkin projections. Other studies, such as our recent hybrid autoencoder–Galerkin framework (Lepage et al., Reference Lepage, Beneddine, Fiorini, Mortazavi, Sipp and Thome2025), exploit deep learning both to enhance the latent-space representation and to correct integration errors of the reduced model. Finally, alternative formulations, such as the PROM-ANN approach of Barnett et al. (Reference Barnett, Farhat and Maday2023), use neural networks to reconstruct the dynamics of subdominant POD coefficients from the leading ones, and even couple this strategy with ECSW hyper-reduction for efficient physics-based time stepping.
Overall, these efforts demonstrate a growing convergence between deep learning and model reduction, with neural networks being used not only for closure modeling but also for representation learning and computational acceleration. This emerging community provides the broader context for our present work, which focuses on assessing the effective cost of hyper-reduction within such deep-learning-augmented ROM frameworks.
Despite the growing popularity of both paradigms, their interaction remains largely unexplored. In particular, it is unclear whether hyper-reduction techniques such as ECSW still offer a net computational benefit when executed on GPU hardware. Deep learning correction increases accuracy for a given latent dimension but also shifts the computational burden toward neural network inference, often already optimized for massively parallel architectures. Consequently, the relative cost of the ROM evaluation may change drastically compared to traditional CPU-based implementations, altering the efficiency of the additional hyper-reduction approximation in this new context.
In this work, we aim to answer a fundamental question:
When is ECSW hyper-reduction still computationally beneficial in a deep-learning-based hybrid ROM, and what are the related hardware-specific bottlenecks?
To this end, we implement ECSW within a differentiable GPU-accelerated framework and compare its theoretical and practical cost against the standard tensorial ROM formulation. The implementation follows the formulation and practical details proposed by Carlino (Reference Carlino2021) and Riffaud et al. (Reference Riffaud, Bergmann, Farhat, Grimberg and Iollo2021), and is fully integrated into a deep learning framework supporting GPU acceleration. Our contributions are threefold:
-
1. We provide a detailed implementation of ECSW adapted to GPU-based deep learning frameworks, ensuring compatibility with automatic differentiation and batched tensor operations (details in Section 2).
-
2. We derive analytical expressions for the asymptotic and exact operation counts of both standard and hyper-reduced ROMs, highlighting their respective memory and computational scaling (details in Section 4.1).
-
3. We perform an extensive benchmarking campaign on both CPU and GPU hardware, analyzing wall-clock performance, scaling behavior, and numerical bottlenecks, and provide guidelines to help practitioners assess whether hyper-reduction is advantageous for their specific hybrid architectures (details in Section 4.4).
2. Hyper-reduction and Galerkin models
Having established the motivation for replacing the standard ROM evaluation with ECSW, we now describe its implementation in our workflow. To address the scarcity of documentation regarding ECSW in open-source finite element settings, particularly concerning the Navier–Stokes equations and GPU-based inference, we detail the extraction of empirical operators and the associated modeling choices.
Although we operationalize this workflow using FreeFem++ and PyTorch, the underlying principles remain agnostic to the specific FEM solver or GPU framework. However, because the performance of hyper-reduction depends on low-level implementation decisions, a transparent description of this architecture is required to contextualize the cost analysis. In this section, we therefore highlight the components of the ECSW workflow that are most relevant to the present study, while a detailed description of the method construction and inner workings is provided in Appendix A.
2.1. Hyper-reduction and Galerkin projection at a glance
Let us consider the simple PDE problem:

where
$ u\left(x,t\right) $
 is a scalar dependent on space and time, while
$ f:u\to f(u) $
 is a nonlinear function, possibly involving space derivatives of solution
$ u $
 . The general procedure is the following:
-
1. Finite element discretization. Introducing a basis of local functions $ \Theta (x)=\left({\theta}_1(x),\cdots, {\theta}_N(x)\right)\in {\unicode{x211D}}^{1\times N} $
 where
$ N $
is the total number of degrees of freedom. Introducing the unknown
$ u\left(x,t\right)=\Theta (x)\mathbf{u}(t) $
, where
$ \mathbf{u}(t)\in {\unicode{x211D}}^{N\times 1} $
, the finite element methodology allows one to write the weak-form:(2.2) $$ \mathbf{M}{\partial}_t\mathbf{u}=\mathbf{F}\left(\mathbf{u}\right), $$where
(2.3) $$ \mathbf{F}\left(\mathbf{u}\right)=\sum \limits_{\mathrm{\ell}}\Theta {\left({x}_{\mathrm{\ell}}\right)}^Tf\left(\Theta \left({x}_{\mathrm{\ell}}\right)\mathbf{u}\right){\delta}_{\mathrm{\ell}},\hskip1.48em \mathbf{M}=\sum \limits_{\mathrm{\ell}}\Theta {\left({x}_{\mathrm{\ell}}\right)}^T\Theta \left({x}_{\mathrm{\ell}}\right){\delta}_{\mathrm{\ell}} $$with $ \left({x}_{\mathrm{\ell}},{\delta}_{\mathrm{\ell}}\right) $
being
$ \tilde{m}\sim N $
quadrature points in the mesh.
-
2. Generation of snapshots. The finite element code allows to generate $ P $
snapshots stacked in
$ \mathbf{U}=\left({\mathbf{u}}_1,\cdots, {\mathbf{u}}_P\right)\in {\unicode{x211D}}^{N\times P} $
. These snapshots are rewritten as
$ {\mathbf{u}}_p=\overline{\mathbf{u}}+{\mathbf{u}}_p^{\prime } $
, where
$ \overline{\mathbf{u}} $
is an arbitrary flow-field (lifting function) containing the non-homogeneous boundary conditions (for example, the time-average of the snapshots
$ {\mathbf{u}}_p $
or a fixed point of
$ f\left(\cdot \right)=0 $
). The homogeneous snapshots are then stacked in
$ {\mathbf{U}}^{\prime }=\left({\mathbf{u}}_1^{\prime}\cdots {\mathbf{u}}_P^{\prime}\right)\in {\unicode{x211D}}^{N\times P} $
. -
3. Generation of POD basis. In a classical way, we generate POD modes by solving:
(2.4) $$ \left({{\mathbf{U}}^{\prime}}^T\mathbf{M}{\mathbf{U}}^{\prime}\right)\mathbf{T}=\mathbf{T}\Lambda, $$where $ \mathbf{T} $
are the chronos modes and
$ \Lambda $
is a diagonal matrix containing positive eigenvalues ranked in decreasing order. We can then select the leading
$ r\le P $
eigenvectors/eigenvalues and compute
$ r $
POD modes
$ \Phi \in {\unicode{x211D}}^{N\times r} $
, with
$ r\ll N $
:(2.5) $$ \Phi ={\mathbf{U}}^{\prime}\mathbf{T}{\Lambda}^{-1/2},\hskip0.48em {\Phi}^T\mathbf{M}\Phi =\mathbf{I}. $$
-
4. Projection of the finite element solver on the POD basis:
(2.6) $$ {\partial}_t\mathbf{a}=\sum \limits_{\mathrm{\ell}}\Phi {\left({x}_{\mathrm{\ell}}\right)}^Tf\left(\overline{u}\left({x}_{\mathrm{\ell}}\right)+\Phi \left({x}_{\mathrm{\ell}}\right)\mathbf{a}\right){\delta}_{\mathrm{\ell}}, $$where $ \mathbf{u}(t)=\Phi \mathbf{a}(t) $
in which
$ \mathbf{a}(t)\in {\unicode{x211D}}^{r\times 1} $
is the dynamics within the POD basis,
$ \Phi (x)=\Theta (x)\Phi =\left({\phi}_1(x),\cdots, {\phi}_r\right)\in {\unicode{x211D}}^{1\times r} $
and
$ \overline{u}(x)=\Theta (x)\overline{\mathbf{u}} $
. This model still scales on the
$ \tilde{m}\approx N $
and is therefore not yet a reduced-order model.


Then, we have two cases, depending on the reduction technique: either hyper-reduction (Section 2.1.1), which is valid in the general case, or Galerkin projection (Section 2.1.2), which is valid only for polynomial nonlinearities.
2.1.1. Hyper-reduction
The algorithm for hyper-reduction follows in two steps:
-
5. NNLS (offline). The Non-Negative Least Squares (NNLS) algorithm allows us to approximate the sum within (Equation 2.6) with a subset of $ m\ll \tilde{m} $
points listed in
$ \mathcal{S} $
weighted by new quadrature coefficients
$ {\delta}_{\mathrm{\ell}}^{\prime } $
:(2.7) $$ \sum \limits_{\mathrm{\ell}}\Phi {\left({x}_{\mathrm{\ell}}\right)}^Tf\left({\overline{u}}_{\mathrm{\ell}}+{u}_{\mathrm{\ell}}\right){\delta}_{\mathrm{\ell}}\approx \sum \limits_{\mathrm{\ell}\in \mathcal{S}}\Phi {\left({x}_{\mathrm{\ell}}\right)}^Tf\left({\overline{u}}_{\mathrm{\ell}}+{u}_{\mathrm{\ell}}\right){\delta}_{\mathrm{\ell}}^{\prime }. $$This approximation should be valid for all snapshots $ \mathbf{u} $
within the learning basis
$ \mathbf{u}\in {\mathbf{U}}^{\prime } $
and the notations
$ {\overline{u}}_{\mathrm{\ell}} $
,
$ {u}_{\mathrm{\ell}} $
refer to the
$ {\mathrm{\ell}}^{th} $
element within
$ \overline{\mathbf{u}} $
and
$ \mathbf{u} $
.
-
6. Hyper-Reduced-Order model (online). The model then reads
(2.8) $$ {\partial}_t\mathbf{a}=\sum \limits_{\mathrm{\ell}\in \mathcal{S}}\Phi {\left({x}_{\mathrm{\ell}}\right)}^Tf\left(\overline{u}\left({x}_{\mathrm{\ell}}\right)+\Phi \left({x}_{\mathrm{\ell}}\right)\mathbf{a}\right){\delta}_{\mathrm{\ell}}^{\prime }, $$where we have the scaling $ r\times m $
compared to the initial
$ N\times \tilde{m} $
.


2.1.2. Galerkin projection
In the case where function
$ f $
 is polynomial, for example, considering here quadratic symmetric nonlinearities,
$ f(u)=f\left(u,u\right) $
 with
$ f\left(u,v\right)=f\left(v,u\right) $
 , steps 5 and 6 are replaced by:
-
5. Tensorization (offline). The $ {k}^{th} $
component of the r.h.s. of Equation (2.6) reads(2.9) $$ {\displaystyle \begin{array}{l}\sum \limits_{\mathrm{\ell}}{\phi}_k\left({x}_{\mathrm{\ell}}\right)f\left(\overline{u}\left({x}_{\mathrm{\ell}}\right)+\sum \limits_i{\phi}_i\left({x}_{\mathrm{\ell}}\right){a}_i,\overline{u}\left({x}_{\mathrm{\ell}}\right)+\sum \limits_j{\phi}_j\left({x}_{\mathrm{\ell}}\right){a}_j\right){\delta}_{\mathrm{\ell}}\\ {}=\underset{b_k}{\underbrace{\sum \limits_{\mathrm{\ell}}{\phi}_k\left({x}_{\mathrm{\ell}}\right)f\left(\overline{u}\left({x}_{\mathrm{\ell}}\right),\overline{u}\left({x}_{\mathrm{\ell}}\right)\right){\delta}_{\mathrm{\ell}}}}+\sum \limits_i{a}_i\underset{L_{ki}}{\underbrace{\sum \limits_{\mathrm{\ell}}2{\phi}_k\left({x}_{\mathrm{\ell}}\right)f\left(\overline{u}\left({x}_{\mathrm{\ell}}\right),{\phi}_i\left({x}_{\mathrm{\ell}}\right)\right){\delta}_{\mathrm{\ell}}}}\\ {}+\sum \limits_{i,j}{a}_i{a}_j\underset{N_{ki j}}{\underbrace{\sum \limits_{\mathrm{\ell}}{\phi}_k\left({x}_{\mathrm{\ell}}\right)f\left({\phi}_i\left({x}_{\mathrm{\ell}}\right),{\phi}_j\left({x}_{\mathrm{\ell}}\right)\right){\delta}_{\mathrm{\ell}}}}.\end{array}} $$All coefficients $ {b}_k $
,
$ {L}_{ki} $
and
$ {N}_{kij} $
can be computed offline.
-
6. Galerkin model (online). The model then reads:
(2.10) $$ {\partial}_t{a}_k={b}_k+\sum \limits_i{L}_{ki}{a}_i+\sum \limits_{i,j}{N}_{ki j}{a}_i{a}_j, $$where the scaling is in $ {(r)}^3 $
.


2.2. NNLS algorithm and considerations
The ECSW hyper-reduction method relies on solving large-scale NNLS problems to identify sparse quadrature weights. As established in Section 2.1, each hyper-reduction problem has the form:

where
$ \mathcal{A}\in {\mathrm{\mathbb{R}}}^{rN_{\mathrm{snap}}\times \tilde{m}} $
 contains nonlinear evaluations at Gauss points, and
$ \boldsymbol{\omega} \in {\mathrm{\mathbb{R}}}^{\tilde{m}} $
 is the empirical quadrature weight vector. In our application:
-
• The reduced dimension is typically $ r\sim \mathcal{O}(10) $
; -
• The number of snapshots is $ {N}_{\mathrm{snap}}\sim \mathcal{O}\left({10}^3\right) $
; -
• The number of Gauss points is $ \tilde{m}\sim \mathcal{O}\left({10}^5\right) $
.


This leads to NNLS problems of size
$ \sim {10}^4\times {10}^5 $
 , which are challenging to even store in memory—let alone solve using dense methods. Indeed, the classical Lawson and Hanson (Reference Lawson and Hanson1995) active set method for NNLS has worst-case complexity:

which, when inserting our scaling, gives:

Such complexity renders direct solvers impractical for our setting.
2.2.1. Greedy algorithm for efficient sparsification
To alleviate this computational burden, we use a greedy subset selection strategy (Yaghoobi et al., Reference Yaghoobi, Wu and Davies2015) classically used in orthogonal matching pursuit on top of the classical Lawson and Hanson method. The algorithm iteratively constructs a sparse active set
$ S\subset \left\{1,\dots, \tilde{m}\right\} $
 of retained quadrature points by maximizing correlation with the residual. At each iteration, a small NNLS problem of size
$ \#S\ll \tilde{m} $
 is solved over the active set using the Lawson and Hanson method from SciPy (Virtanen et al., Reference Virtanen, Gommers, Oliphant, Haberland, Reddy, Cournapeau, Burovski, Peterson, Weckesser, Bright, van der Walt, Brett, Joshua Wilson, Mayorov, Andrew, Jones, Kern, Eric Larson, Polat, Feng, Moore, VanderPlas, Laxalde, Perktold, Cimrman, Ian Henriksen, Harris, Archibald, Ribeiro and Pedregosa2020).
Algorithm 1: Greedy Non-Negative Selection for ECSW.
Input: Matrix
$ \mathbf{A}\in {\mathrm{\mathbb{R}}}^{rN_{\mathrm{snap}}\times \tilde{m}} $
 , vector
$ \mathbf{b}\in {\mathrm{\mathbb{R}}}^{rN_{\mathrm{snap}}} $
 , sparsity budget
$ k $
 , precision
$ \unicode{x025B} $
 .
Output: Weights
$ \mathbf{x} $

$ \mathbf{r}\leftarrow \mathbf{b} $
 ;
$ S\leftarrow \mathrm{\varnothing} $
 ;
$ \mathbf{x}\leftarrow \mathbf{0} $
 ;
for
$ t\leftarrow 1 $
 to
$ k $
 $ \parallel \mathbf{r}\parallel \le \unicode{x025B} $
 do.
Compute correlations
$ {c}_j\leftarrow {\mathbf{A}}_{:,j}^{\top}\mathbf{r} $
 for all
$ j\notin S $
 ;
$ {j}^{\star}\leftarrow \arg {\max}_{j\notin S}{c}_j $
 ;
$ S\leftarrow S\cup \left\{{j}^{\star}\right\} $
 ;
Solve NNLS:
$ {\mathbf{x}}_S\leftarrow \arg {\min}_{\mathbf{z}\ge 0}\parallel {\mathbf{A}}_S\mathbf{z}-\mathbf{b}{\parallel}_2 $
 ;
$ \mathbf{r}\leftarrow \mathbf{b}-{\mathbf{A}}_S{\mathbf{x}}_S $
 ;
Set
$ {\mathbf{x}}_j\leftarrow {\left({\mathbf{x}}_S\right)}_j $
 for
$ j\in S $
 (zero elsewhere);
return
$ \mathbf{x} $
 ;
This algorithm reduces the cost of weight selection by restricting the search to a small subset of highly informative quadrature points, often representing less than 1% of the original set. However, as a greedy method, it does not guarantee the optimal selection of Gauss-point locations for a given budget. Results presented in Section 3 show that our more economical Gauss-point selection performs effectively, although a comparison with the full-space Lawson and Hanson approach is not included in this study.
2.3. Online evaluation after hyper-reduction
Let us now summarize the structure and complexity of the reduced-order model during the online phase after hyper-reduction.
Recall the full-order Navier–Stokes system in semi-discrete perturbed form
$ {\mathbf{w}}_t=\overline{\mathbf{w}}+\mathbf{w} $
 with

where
$ \mathbf{M} $
 is the mass matrix,
$ \mathcal{L} $
 the discrete linear operator, and
$ \mathcal{B}\left(\cdot, \cdot \right) $
 the quadratic convection operator.
The reduced-order model obtained via projection onto the reduced basis
$ \Phi $
 reads:

with
$ \mathbf{a}\in {\mathrm{\mathbb{R}}}^r $
 the reduced coordinates. When the nonlinear term is treated explicitly, it becomes a time-dependent source term:

Using the matrix formulation derived earlier and applying ECSW, this nonlinear term is computed via:

2.3.1. Implementation and cost
After hyper-reduction, the integration involves only a sparse subset of quadrature points of size
$ m\ll \tilde{m} $
 , where
$ \tilde{m} $
 denotes the total number of Gauss points in the original problem. The online evaluation of the nonlinear convection term is then reduced to a sequence of matrix–vector operations with matrices of size
$ m\times r $
 or
$ r\times m $
 , together with a few element-wise operations over
$ m $
 -dimensional vectors. The complete numerical cost of the method is therefore
$ {\mathcal{C}}_{\mathrm{nonlin}}=\mathcal{O}\left( rm+m\right) $
 , which scales linearly with both
$ r $
 and
$ m $
 and remains drastically cheaper than the full-order computation or the tensorial ROM formulation. A detailed analysis of implementation cost, including operation counts and hardware runtimes on both CPU and GPU, is provided in Section 4.
2.3.2. Time integration
Assuming a backward Euler scheme and denoting by
$ \mathbf{A}={\Phi}^{\top}\mathrm{\mathcal{L}\Phi } $
 the reduced linear operator, the time integration step becomes:

The cost of solving this reduced system scales as
$ \mathcal{O}\left({r}^3\right) $
 for a direct solve, but can be reduced to
$ \mathcal{O}\left({r}^2\right) $
 using an lower-upper (LU) decomposition pre-computed once and reused at each time step.
2.3.3. Conclusion
After hyper-reduction, each time step of the reduced model requires only:
-
• A single evaluation of the nonlinear term with cost $ \mathcal{O}(rm) $
, -
• One linear solve of size $ r\times r $
.


This ensures that the online complexity is independent of the full-order degrees of freedom (DOF) size
$ n $
 and scales only with the reduced basis size
$ r $
 and the retained quadrature size
$ m $
 , enabling orders-of-magnitude speed-up over the original model.
3. Numerical experiments for hyper-reduction alone
3.1. Test case selection and setup
To validate the proposed hyper-reduction methodology, we consider the fluidic pinball configuration. This geometry consists of three identical cylinders placed at the vertices of an equilateral triangle, generating a rich variety of wake dynamics as the Reynolds number increases. It provides a compact yet versatile benchmark that captures essential features of vortex shedding, symmetry breaking, and nonlinear coupling between wake modes, while remaining computationally manageable for systematic analysis.
The validation test case corresponds to the periodic regime of the fluidic pinball, obtained at
$ \mathit{\operatorname{Re}}=30 $
 . Dynamically, this configuration behaves similarly to the classical cylinder flow in the Von Kármán vortex shedding regime. A single trajectory is simulated from the steady base flow toward the periodic limit cycle, and
$ 1000 $
 snapshots are extracted along this trajectory. These snapshots are used both to construct the reduced POD basis and to assemble the ECSW NNLS hyper-reduction problem. The resulting hyper-reduced model is then evaluated on the same trajectory to verify correct implementation and basic dynamical consistency.
This periodic configuration serves as a controlled validation case. It is simple enough that any properly implemented reduced-order model should reproduce the correct limit cycle dynamics, yet dynamic enough to test stability and temporal accuracy. The regime’s transient growth rate, shedding frequency, and limit cycle amplitude are well documented in the literature and have been used extensively in earlier work to benchmark ROM performance, enabling direct consistency checks with earlier results.
Only the periodic regime is considered here, as it provides a transparent and interpretable sanity check confirming that the ECSW implementation reproduces expected reduced-order behavior. Since the goal of this work is to analyze computational cost rather than model accuracy, extending the study to more complex or chaotic regimes would not provide additional insight into numerical performance. The following sections, therefore, focus exclusively on quantifying the computational efficiency and scaling properties of ECSW hyper-reduction (Figure 1).
Mesh for the fluidic pinball test case, featuring three cylinders in an equilateral triangle configuration.

Figure 1. Long description
A two-dimensional triangular mesh is displayed on a Cartesian coordinate system with X-coordinate from negative 6 to 20 and Y-coordinate from negative 6 to 6.
* At the center-left of the domain, three white circular voids representing cylinders are arranged in an equilateral triangle. One cylinder is centered at X equals negative 1.5, Y equals 0, while the other two are positioned further right at X equals 0, with one at Y equals 1 and the other at Y equals negative 1.
* The mesh density is highest immediately surrounding these cylinders, where the triangular elements are smallest and appear as a solid blue mass.
* A rectangular region of high-density refinement extends from X equals negative 3 to X equals 10, spanning Y equals negative 2 to 2, capturing the immediate wake area.
* A second, slightly less dense refinement zone continues from X equals 10 to the right boundary at X equals 20, spanning the same vertical range.
* The outermost regions of the domain, particularly toward the top, bottom, and far-left boundaries, feature the coarsest mesh with large, clearly visible triangular elements.
3.2. Validating the implementation on a periodic test case
We evaluate the hyper-reduction method on the periodic regime of the fluidic pinball. This configuration provides a controlled yet representative test case: the dynamics evolve from a steady base flow toward a stable limit cycle, allowing us to assess both transient behavior and long-term accuracy.
The reduced-order model is constructed using a quadratic Galerkin formulation with a basis size chosen as the minimal number of modes required to capture both the transient evolution and the limit cycle dynamics accurately. In this regime, the reference ROM provides a qualitatively correct representation of the full-order dynamics, both in terms of growth toward the attractor and its final periodic behavior.
We then investigate whether the ECSW hyper-reduction is able to recover a similar level of accuracy under different sparsity regimes. Two configurations are considered, corresponding to different tolerances in the NNLS greedy selection of quadrature points.
In the first case, a relative residual threshold of
$ \varepsilon =7.5\cdot {10}^{-2} $
 is used. This results in retaining 50 Gauss points for the
$ u $
 -component and 54 for the
$ v $
 -component in the ECSW method. As shown in Figure 2, the hyper-reduced model at this size does not match the performance of the quadratic ROM or the FOM. It appears to overdamp the system, resulting in a relatively accurate transient but an incorrect limit cycle.
First three POD coordinates over time for the periodic test case. Comparison between full-order solution (black), quadratic Galerkin ROM (blue), and hyper-reduced model with NNLS tolerance
$ \varepsilon =7.5\cdot {10}^{-2} $
 (red).

Figure 2. Long description
The figure consists of three vertically aligned panels sharing a common x-axis labeled Time, ranging from 20 to 140. The y-axes represent Mode 1, Mode 2, and Mode 3 respectively, with values ranging from approximately -10 to 10. A legend in the top panel identifies three data series: a solid black line for F O M projected, a solid blue line for Quadratic R O M with 18 modes, and a dashed red line for E C S W R O M with 18 modes and N N L S threshold 0.075.
* Top Panel (Mode 1): All three models show an initial oscillating growth from time 20 to 60. Beyond time 60, the black and blue lines stabilize into a high-amplitude oscillation around a mean of 9. The dashed red line deviates, stabilizing at a lower mean of approximately 7.5 with smaller oscillations.
* Middle Panel (Mode 2): All models show increasing oscillatory amplitude until time 60. From time 60 to 140, the black and blue lines overlap perfectly, oscillating between -11 and 11. The dashed red line shows a phase shift and slightly lower peak amplitudes compared to the other two.
* Bottom Panel (Mode 3): Similar to Mode 2, the black and blue lines show identical high-frequency oscillations between -11 and 11 after time 60. The dashed red line exhibits a noticeable phase lead and reduced amplitude peaks relative to the F O M and Quadratic R O M results.
In the second configuration, the relative tolerance is tightened to
$ \varepsilon =5\cdot {10}^{-2} $
 , leading to 65 Gauss points for both the
$ u $
 and
$ v $
 components. Notably, the two selected sets share only a single common index out of 130 unique points, confirming that the nonlinear terms for each velocity component are supported in largely distinct spatial regions and justifying the use of separate ECSW decompositions. In this case (Figure 3), the hyper-reduced model recovers dynamics that are qualitatively indistinguishable from the quadratic ROM, both during the transient growth and on the limit cycle. This indicates that a moderate increase in quadrature size is sufficient to fully restore the reduced model’s accuracy.
Same setup as Figure 2, but with NNLS tolerance
$ \varepsilon =5\cdot {10}^{-2} $
 . The hyper-reduced model and quadratic ROM are nearly indistinguishable.

Figure 3. Long description
A multi-panel line graph with three vertical sections sharing a common x-axis labeled Time, ranging from 20 to 140. The y-axes represent Mode 1, Mode 2, and Mode 3. A legend in the top panel identifies three data series: a solid black line for F O M projected, a solid blue line for Quadratic R O M 18 modes, and a dashed red line for E C S W R O M 18 modes, N N L S threshold equals 0.05.
* The top panel for Mode 1 shows an initial value near 0, followed by a sigmoid-like increase between time 40 and 80, reaching a plateau around 10. The curve exhibits small, high-frequency oscillations throughout the ascent and plateau. The blue and black lines are perfectly overlapped, while the red dashed line shows a slight lag during the steep ascent.
* The middle panel for Mode 2 shows a centered oscillation around y equals 0. The amplitude increases linearly from time 20 to 60, then stabilizes with peaks at positive 11 and troughs at negative 11. All three lines are nearly indistinguishable.
* The bottom panel for Mode 3 shows a similar oscillating pattern to Mode 2, with amplitude growth stabilizing around time 60. The oscillations are centered at 0 with a range between positive 11 and negative 11. The red dashed line shows very minor deviations from the solid lines during the amplitude growth phase.
These results validate ECSW on this classical benchmark and identify the minimal quadrature size required for an accurate representation of this test case with the chosen POD quadratic ROM.
From a computational perspective, we compare the wall-clock time required for full trajectory integration on CPU. The quadratic ROM requires a total simulation time of
$ 1.60 $
 seconds. The hyper-reduced models significantly reduce this cost, with total simulation times of
$ 0.76 $
 seconds and
$ 0.81 $
 seconds for the two configurations, respectively. More precisely, when isolating the right-hand side evaluation, the computational cost drops from
$ 5.2\cdot {10}^{-4} $
 s to
$ 1.45\cdot {10}^{-4} $
 s and
$ 1.95\cdot {10}^{-4} $
 s. This corresponds to an overall speed-up of approximately
$ 2\times $
 , and up to
$ 2.6\times $
 when considering only the nonlinear term, while maintaining comparable accuracy in the refined regime.
3.3. Assessment of numerical cost for the considered architecture
One of the main advantages of hyper-reduction is its lower numerical complexity compared to the tensorial quadratic ROM method. In earlier standalone tests on CPU, we showed clear gains, with the hyper-reduced model running about twice as fast in wall-clock time for the chosen number of retained modes and Gauss points. In the present experiments, however, the context is different: the models now run directly on the GPU and are optimized for this hardware. Under these conditions, the results are surprising. Despite using the same reduction sizes as before, the hyper-reduced model no longer shows the expected advantage. To understand this, we measured the runtime of the quadratic ROM alone and the hyper-reduced ROM alone, isolating their computation while keeping the same optimization strategy for the algorithm and hardware. For the full trajectory (18,001 time steps), the quadratic ROM integrates in about 6.1 s, with each nonlinear evaluation costing
$ 153\hskip0.22em \mu \mathrm{s} $
 on average. By contrast, the hyper-reduced model requires 6.9 s, with nonlinear evaluations taking
$ 208\hskip0.22em \mu \mathrm{s} $
 each on average. These results run counter to both previous empirical evidence and the theoretical scaling of the method, which should favor hyper-reduction. Section 4 investigates this discrepancy by analyzing cost scaling in more detail and examining how GPU hardware influences the benefits of hyper-reduction.
Although the isolated nonlinear evaluation is about 36% more time-consuming for the hyper-reduced model (
$ 208 $
 vs
$ 153\hskip0.22em \mu \mathrm{s} $
 ), the full trajectory cost increases by only about 13% (
$ 6.9 $
 vs
$ 6.1\hskip0.1em $
 s). This is because the nonlinear right-hand side is only one component of each time step: the remainder is spent on the implicit
$ r\times r $
 linear solve and on time-stepping bookkeeping, both of which are identical for the two models. Indeed, over the
$ 18\hskip0.22em 001 $
 steps the right-hand-side evaluation accounts for
$ 2.75\hskip0.1em $
 s for the quadratic ROM and
$ 3.74\hskip0.1em $
 s for the hyper-reduced model, leaving
$ 3.35\hskip0.1em $
 s and
$ 3.16\hskip0.1em $
 s respectively for the shared remaining workload—consistent up to timing noise, as expected for model-independent operations. The right-hand-side penalty is therefore amortized over these shared costs.
4. Numerical cost assessment considering deep learning hardware
4.1. Theoretical operation count scaling for nonlinearity computation
Before examining wall-clock timings for the tensorized quadratic ROM and the hyper-reduced ROM, we first estimate the exact number of operations required for both approaches. Earlier, we described their asymptotic complexity:
$ \mathcal{O}\left({r}^3\right) $
 for the tensorial ROM and
$ \mathcal{O}(mr) $
 for the hyper-reduction, where
$ r $
 is the size of the retained POD subspace and
$ m $
 the number of retained Gauss points in ECSW. Here, we go beyond asymptotics and compute the exact non-asymptotic operation counts, which provide a hardware-agnostic baseline for comparing methods and identifying where the trade-off between them shifts.
4.1.1. Numerical cost of the quadratic ROM nonlinearity evaluation
The quadratic ROM computes the quadratic nonlinearity entirely in the reduced space. As expressed in Section 2.1.2, the explicit nonlinear term for one unbatched evaluation is

In practice, this is not implemented with triple loops but with the torch.einsum operator, which supports batching and calls optimized basic linear algebra subprograms (BLAS) kernels. The batched version can be written as

with
$ b $
 the batch size.
The contraction is typically performed in two steps. First, compute the intermediate tensor

This requires
$ {br}^3 $
 multiplications and
$ {br}^3-{br}^2 $
 additions.
Then compute

which requires
$ {br}^2 $
 multiplications and
$ {br}^2- br $
 additions.
In total, the quadratic ROM costs

for an overall count of
$ 2{br}^3+{br}^2- br $
 operations (not accounting for MAC optimization).
4.1.2. Numerical cost of hyper-reduction nonlinearity evaluation
For hyper-reduction, the nonlinear evaluation is written as in Section 2.3:

Where the shorthand matrices are defined from the pre-computed products of the POD basis and FEM sampling operators (see Section 2.3 and Appendix A):
$ {M}_1={\Phi}^{\top }{\Theta}_u^{\top }W\in {\unicode{x211D}}^{r\times m} $
 ,
$ {M}_2={\Phi}^{\top }{\Theta}_v^{\top }W\in {\unicode{x211D}}^{r\times m} $
 , and the eight projection matrices
$ {M}_3,\dots, {M}_{10}\in {\unicode{x211D}}^{m\times r} $
 correspond to
$ {\Theta}_u\Phi $
 ,
$ {\partial}_x{\Theta}_u\Phi $
 ,
$ {\Theta}_v\Phi $
 ,
$ {\partial}_y{\Theta}_u\Phi $
 ,
$ {\Theta}_u\Phi $
 ,
$ {\partial}_x{\Theta}_v\Phi $
 ,
$ {\Theta}_v\Phi $
 ,
$ {\partial}_y{\Theta}_v\Phi $
 , respectively. In batched form:

Each of the six matrix–vector products costs
$ brm $
 multiplications and
$ b\left(r-1\right)m $
 additions. The element-wise products add
$ bm $
 multiplications, and the element-wise sums add
$ bm $
 additions. Finally, the two projections back to reduced space each cost
$ brm $
 multiplications and
$ br\left(m-1\right) $
 additions.
In total, the hyper-reduction costs

that is
$ 16 brm- br $
 operations overall.
4.1.3. Trade-off between methods
From these counts, hyper-reduction is cheaper whenever

For example, with
$ r=20 $
 , hyper-reduction is cheaper if
$ m<50 $
 ; for
$ r=40 $
 , if
$ m<200 $
 ; and for
$ r=100 $
 , if
$ m<1256 $
 .
These thresholds are broadly consistent with earlier empirical results, although small discrepancies remain. For instance, the 20-mode ROM was observed to be more costly than the 20-mode hyper-reduction with 200 Gauss points, despite the theoretical bound. Such deviations can be explained by hardware effects, parallelization strategies, and optimization details. For a more robust view of performance, Subsection 4.2 reports averaged wall-clock results for isolated nonlinear computations (Table 1).
Exact operation counts for quadratic nonlinearity evaluation using quadratic ROM and ECSW hyper-reduction

Table 1. Long description
The table consists of three columns and four rows including the header.
Column 1: Operation Type
Column 2: Quadratic R O M
Column 3: Hyper-reduction
Row 1 (Multiplications):
- Quadratic R O M: b r cubed plus b r squared
- Hyper-reduction: 8 b r m plus 4 b m
Row 2 (Additions):
- Quadratic R O M: b r cubed minus b r
- Hyper-reduction: 8 b r m minus 4 b m minus b r
Row 3 (Total ops):
- Quadratic R O M: 2 b r cubed plus b r squared minus b r
- Hyper-reduction: 16 b r m minus b r
4.2. Empirical cost scaling and asymptotic behavior on CPU
After establishing the theoretical operation counts, we now evaluate empirical runtimes. The goal is to test how the wall-clock cost of nonlinear evaluations scales with the number of POD modes, and to confirm whether the observed scaling agrees with theoretical predictions: cubic for the quadratic Galerkin ROM and linear for ECSW hyper-reduction.
We run the nonlinear evaluation functions introduced in Section 3 on a single Intel Xeon(R) Gold 5118 core. To obtain a robust estimate of runtime for each configuration, we perform
$ 7\times 100 $
 function calls. Each block of 100 runs is averaged to reduce measurement noise, and we then take the median of the seven block averages as the final reported value. This procedure combines the precision of averaging with the robustness of a median, limiting the impact of occasional outliers. For consistency with the deep learning code, all computations are batched with batch size
$ b=256 $
 .
The experiment covers:
-
• Quadratic ROMs with POD sizes between 5 and 250 modes (245 data points).
-
• Hyper-reduced ROMs over the same POD range, combined with Gauss-point ensemble sizes $ m\in \left\{10,100,200,300,400,500,600,700,800,900,1000\right\} $
, yielding
$ 11\times 245=2695 $
configurations.


In total, this corresponds to 171,500 function calls for the quadratic ROM and 1,886,500 for the hyper-reduced models.
Figure 4 plots the results on log–log axes. For the quadratic ROM, the slope of the curve is close to cubic, with an empirical exponent of ≈ 3.25. The slightly super-cubic behavior can be attributed to hierarchical memory effects on the CPU. For hyper-reduction, we illustrate two representative cases (
$ m=100 $
 and
$ m=1000 $
 ). Their asymptotic slopes are ≈ 0.94 and ≈ 1.13, respectively, confirming the predicted linear complexity with respect to the POD size.
Empirical wall-clock time (log–log scale) for nonlinear evaluation. Comparison between quadratic ROMs and ECSW hyper-reduced models with varying Gauss-point sizes, executed on CPU hardware.

Figure 4. Long description
The x-axis represents the Number of Modes r on a logarithmic scale from 10 super 0 to 10 super 2. The y-axis represents Time per Evaluation in seconds on a logarithmic scale from 10 super minus 4 to 10 super minus 1.
At the top left, a legend lists Quadratic R O M median and E C S W m equals 10 through 1000 median in increments of 100.
Data trends:
* The Quadratic R O M curve is the uppermost line, showing a steep power-law increase. An annotation indicates a slope of Delta y over Delta x equals 3.25.
* Below this, a cluster of E C S W curves shows significantly lower evaluation times. The highest in this group is E C S W m equals 1000, with an annotated slope of Delta y over Delta x equals 1.13.
* As m decreases, the curves shift downward, indicating faster performance.
* The lowest curve, E C S W m equals 10, remains nearly flat across the entire range of r, with an annotated slope of Delta y over Delta x equals 0.94.
* All E C S W models maintain a significant performance advantage over the Quadratic R O M as the number of modes increases beyond 20.
Beyond asymptotics, the point of intersection between the curves is of practical importance. Across all tested Gauss-point sizes, hyper-reduction becomes cheaper than the quadratic ROM at around 50 POD modes. For the case
$ m=200 $
 , which is most relevant to our applications, hyper-reduction already outperforms the quadratic ROM from about 10 POD modes onward. At 20 modes, the hyper-reduced model requires
$ 5\times {10}^{-5} $
 s per evaluation, compared to
$ 7\times {10}^{-5} $
 s for the quadratic ROM. This crossover behavior agrees with our earlier tests.
These experiments confirm that, on CPU hardware, quadratic ROMs scale cubically with POD size, while ECSW hyper-reduction scales linearly. Although hyper-reduction can be more expensive at very small reduced spaces, its advantage grows rapidly with dimension, making it the more efficient choice for realistic POD sizes.
4.3. Empirical cost scaling and asymptotic behavior running on GPU hardware
As a final test, we run the same experiment with both models now running on our NVIDIA Tesla V100S 32GB VRAM GPU chip. This is the hardware we use to run our hybrid model training and inference. The same hardware where we observed slower run times for hyper-reduction compared to the quadratic ROM.
The test follows the same isolated-evaluation setup as on CPU, except that on GPU we report the median over 100 single evaluations together with the inter-quartile range, since the per-call launch jitter is itself of interest and is better shown directly than hidden inside block averages. The Gauss-point ensemble size grid search is also slightly different, with
$ m\in \left\{\mathrm{10,20,50,100,500,1000}\right\} $
 . This more logarithmic grid-search scale allows us to more clearly see the effects at the extreme ends of the spectrum.
The results for the scaling for the new hardware experiment are very different from the previous ones. Analyzing first the cost of the hyper-reduction models, the cost is nearly constant with respect to both the size of the POD modes and the size of the Gauss-point ensemble, or at least the cost increases only at discrete values.
Concerning the quadratic ROM scaling, initially we see the same near-constant cost scaling with several discrete cost values, but then for models over
$ \sim 80 $
 POD modes the compute time blows up and follows a new cost scaling that seems exponential or at least asymptotically of high polynomial order of around
$ \mathcal{O}\left({r}^{5.5}\right) $
 .
These results broadly agree with the timings reported in Section 3.3. In both cases only the nonlinear evaluation itself is timed; what differs is the context surrounding the timed region. During trajectory integration, each right-hand-side evaluation is interleaved with the implicit linear solve and time-stepping bookkeeping, whereas in the present experiment it is called repeatedly in a tight loop. These two settings are not strictly equivalent, so a small difference in absolute cost is to be expected: the
$ 18 $
 -mode quadratic ROM evaluates in
$ 138\hskip0.22em \mu \mathrm{s} $
 and the
$ 18 $
 -mode,
$ 200 $
 -Gauss-point hyper-reduced model in
$ 184\hskip0.32em \mu \mathrm{s} $
 , both marginally below the trajectory values of
$ 153 $
 and
$ 208\hskip0.32em \mu \mathrm{s} $
 . Crucially, the relative gap between the two methods is preserved:
$ 33\% $
 here, close to the
$ 36\% $
 measured during trajectory integration in Section 3.3.
Figure 5 also reports the experimental variability, plotting the median over
$ 100 $
 evaluations together with the shaded inter-quartile range (IQR), which is visually narrow throughout. The IQR peaks at about
$ 28\% $
 of the median for the quadratic ROM (at
$ r=5 $
 ) and at about
$ 16\% $
 for the hyper-reduced model, confirming that the median is a reliable indicator of practical performance.
Empirical wall-clock time (log–log scale) showing the computational-cost scaling of quadratic reduction vs hyper-reduction on GPU hardware. Results are reported as medians with inter-quartile ranges.

Figure 5. Long description
A log-log scale line graph titled G P U runtime: quadratic R O M vs E C S W on G P U.
* Axes: The horizontal X-axis represents the Number of modes r, ranging from 10 super 0 to approximately 3 times 10 super 2. The vertical Y-axis represents Time per evaluation in microseconds, ranging from 10 super 2 to 10 super 3.
* Data Series:
- Quadratic R O M (median and I Q R): Represented by a thick blue line. It starts at the lowest point (approx. 40 microseconds) and shows a steep, near-exponential increase as r exceeds 10 super 2, reaching nearly 10 super 3.
- E C S W hyper-reduction (median and I Q R): Multiple lines for m equals 10, 50, 100, 200, 500, and 1000. These lines are clustered horizontally between 200 and 300 microseconds.
* Trends: While the Quadratic R O M is faster for low values of r (below 10 super 2), it scales poorly. The E C S W methods maintain a nearly constant, flat computational cost regardless of the number of modes. The blue Quadratic R O M line intersects and surpasses all E C S W lines at approximately r equals 100, indicating the point where hyper-reduction becomes more efficient on G P U hardware.
To ensure that these observations were not artifacts of a particular implementation, we repeated the profiling experiments with both implementations expressed as torch.nn.Module objects compiled with torch.compile, and also reproduced the benchmark in JAX. In all cases, the relative performance and scaling trends remained unchanged.
Several steps are needed to understand these results: why the hardware scaling appears almost linear at small sizes, and why the cost suddenly explodes at
$ r=79 $
 for the quadratic ROM. We begin by examining how each method can be parallelized, and then turn to memory scaling and GPU hardware effects.
4.3.1. Parallelization of the nonlinearity evaluation
For the quadratic ROM, the lower compute time can be explained by two factors. First, as shown in the operation counts above, at typical sizes (e.g.,
$ r=20 $
 POD modes and
$ m=200 $
 Gauss points), the quadratic ROM tensor evaluation requires fewer total operations than hyper-reduction. Second, GPU optimization reduces the effective cost even further.
The computation involves essentially two steps. First,

followed by

In both steps, the
$ {br}^2 $
 (first) and
$ br $
 (second) repeated operations are non-sequential and can be executed in parallel. In practice, they are likely handled by a batched general matrix–multiplication (GEMM) kernel. Ignoring bandwidth limits, each step can be treated as a near constant-time operation. Thus, the quadratic ROM reduces to two sequential, highly optimized GPU kernels.
The hyper-reduction is more sequential by design. It can be broken down into three main stages: (1) projection into the empirical Gauss-point basis, (2) point-wise products and additions within this space, and (3) projection back into the POD subspace.
For the projection stage, the matrices can be stacked to exploit GPU parallelism. For example,
$ {M}_3,{M}_4,{M}_5,{M}_6 $
 are grouped into
$ {M}_{\mathrm{large}1}\in {\unicode{x211D}}^{4m\times r} $
 , and
$ {M}_7,{M}_8,{M}_9,{M}_{10} $
 into
$ {M}_{\mathrm{large}2}\in {\unicode{x211D}}^{4m\times r} $
 . In practice, we have 2 Gauss-point ensembles of slightly different sizes, so two separate stacks are required. This allows all projections to be evaluated efficiently using the highly optimized torch.linear routine (perhaps the highest optimized torch GPU function thanks to its role in neural networks), which can again be considered constant-time for small
$ m $
 and
$ r $
 .
Once the
$ m $
 -sized vectors are computed, the element-wise products are trivially parallelizable with compute unified device architecture (CUDA) kernels. The subsequent additions are equally efficient. Together, these operations can be treated as one or perhaps several constant-time extremely fast operations.
Finally, the projection back to POD space is performed by stacking
$ {M}_1 $
 and
$ {M}_2 $
 into
$ {M}_{\mathrm{large}3}\in {\unicode{x211D}}^{r\times 2m} $
 and applying a batched torch.linear. This again corresponds to one constant-time operation.
When memory and bandwidth limits are ignored, the quadratic ROM reduces to two sequential constant-time kernels, while the hyper-reduction requires at least three, and typically more, sequential stages. This explains both the near-constant cost observed for small
$ r $
 and why hyper-reduction is consistently about 35% slower in this regime: it involves roughly
$ 3/2 $
 as many sequential steps.
This sequential-stage argument can be complemented by an arithmetic intensity perspective. The quadratic ROM consists entirely of dense GEMM operations; at typical sizes (
$ r=20 $
 ,
$ b=256 $
 ), each contraction achieves roughly 9 FLOP/byte, placing it comfortably in the compute-efficient regime of the GPU. The ECSW GEMM stages (forward projections and back-projection) reach a comparable arithmetic intensity of about 8–9 FLOP/byte. However, between these GEMM stages, ECSW requires element-wise Hadamard products over
$ b\times m $
 vectors, which perform a single floating-point operation per element while reading two operands and writing one result, yielding an arithmetic intensity of approximately 0.08 FLOP/byte—two orders of magnitude lower. Whether these heterogeneous operations are fused by the compiler into a single kernel (as observed with the XLA backend) or dispatched separately, the overall arithmetic intensity of the ECSW evaluation is diluted by the element-wise stages, contributing to its higher wall-clock cost despite comparable GEMM-level performance.
4.3.2. Hardware bandwidth limitations
We now account for hardware limits to explain the near-constant cost at small
$ r $
 and the sharp increase at
$ r\ge 79 $
 for the quadratic ROM. The key object is the intermediate tensor
$ T\in {\unicode{x211D}}^{b\times r\times r} $
 formed in the first contraction. Its size is
$ \mid T\mid =4\hskip0.1em b\hskip0.1em {r}^2 $
 bytes (float32). While
$ N\in {\unicode{x211D}}^{r\times r\times r} $
 is streamed slice-by-slice (working set
$ \mathcal{O}\left({r}^2\right) $
 ) and
$ \mathbf{a},\mathbf{f}\in {\unicode{x211D}}^{b\times r} $
 are tiny,
$ T $
 must be repeatedly updated and then consumed. If
$ T $
 fits entirely in the GPU’s L2 cache, all those updates and reads occur on-chip; dynamic random-access memory (DRAM) traffic is dominated by streaming the tensor
$ N $
 slice-by-slice from memory, and wall time appears flat. The threshold is set by L2 capacity
$ {S}_{L2} $
 :

With
$ b=256 $
 and
$ {S}_{L2}\approx \mathrm{6,291,456} $
 B (V100, ~6 MB), this gives
$ r\lesssim 78.38 $
 , this exactly matches our observed constant cost breaking point. Beyond this point,
$ T $
 no longer resides in L2. Kernels must tile
$ T $
 and perform read–modify–write to DRAM for each
$ i $
 -slice of
$ N $
 , introducing a dominant bandwidth term
$ \propto b\hskip0.1em {r}^3 $
 . This is why the cost “cliff” appears precisely around
$ r=79 $
 : below it,
$ T $
 reuse is on-chip, and cost is nearly constant; above it, repeated DRAM traffic for
$ T $
 drives the high-order scaling.
4.4. Guidelines for using hyper-reduction to speed up learning and inference in hybrid deep learning models
The initial motivation for adopting hyper-reduction in hybrid deep learning ROM architectures was its reported computational efficiency. While this remains theoretically true, our results show that scaling arguments alone do not justify its use. In practice, the tight coupling between the ROM and the neural network means both must run on the same hardware. Since deep learning gains enormous speed-ups on GPUs, it is natural to place the ROM there as well. The relevant question is therefore: given a target accuracy, POD size, GPU hardware, and the structure of the nonlinearity, does hyper-reduction actually accelerate the hybrid method?
Before giving practical guidelines, it is useful to discuss how the required quadrature support may evolve for more complex flows. ECSW is an empirical approximation on top of the quadratic POD–Galerkin ROM; in general it cannot be more accurate than the underlying ROM, and coincides with it only when a sufficiently rich quadrature rule is retained. At high Reynolds numbers, two scenarios arise.
In the first, all turbulent scales are resolved through DNS. The Kolmogorov barrier (Ahmed and San, Reference Ahmed and San2020) slows the decay of the POD singular spectrum, forcing the retention of a large number of modes
$ r $
 . Since Hernández et al. (Reference Hernández, Caicedo and Ferrer2017) show that the number of quadrature points
$ m $
 scales between
$ \mathcal{O}(r) $
 and
$ \mathcal{O}\left({r}^2\right) $
 for greedy non-negative cubature rules (including ECSW), for a given NNLS residual tolerance the number of retained quadrature points grows substantially with turbulence intensity.
In the second, one retains a moderate reduced basis (possibly larger than in the laminar regime studied here, but not drastically so) and closes the unresolved scales through a turbulence model (Lorenzi et al., Reference Lorenzi, Cammi, Luzzi and Rozza2016; Hijazi et al., Reference Hijazi, Stabile, Mola and Rozza2019), a learned closure, or both. Because fewer scales need to be represented, the required number of POD modes
$ r $
 stays restrained; the same cubature scaling (Hernández et al., Reference Hernández, Caicedo and Ferrer2017) then implies that
$ m $
 also remains moderate, and ECSW preserves its cost advantage.
Our GPU profiling results support this second scenario. Section 4.3 shows that the hyper-reduced cost remains nearly constant for quadrature sizes up to
$ m\approx {10}^3 $
 , well above the values needed in our experiments. For moderately richer bases, the dominant operations reduce to batched
$ m\times r $
 matrix–vector products that better exploit GPU parallelism; the advantage would diminish only when these products become large enough to saturate memory bandwidth or kernel parallelization capacity. These observations remain qualitative projections; dedicated turbulent benchmarks would be needed to confirm them.
From our experiments, we suggest the following:
-
• If your nonlinearity is more complex than the quadratic convective term, hyper-reduction is the only practical option.
-
• If your application involves a moderately large reduced basis (on the order of a hundred modes, as may arise in industrial turbulent configurations) and your chosen method resolves all retained POD modes through the physics-based operator (Barnett et al., Reference Barnett, Farhat and Maday2023; Menier et al., Reference Menier, Bucci, Yagoubi, Mathelin and Schoenauer2023), then the quadratic ROM computational cost exceeds the efficient threshold. At this scale, the number of quadrature points required remains manageable, making ECSW computable and the preferred option.
-
• In contrast, for hybrid ROM–DL approaches where only a small subset of dominant POD modes is evolved through the physics-based operator and the remaining dynamics are captured by a neural correction (Wang et al., Reference Wang, Ripamonti and Hesthaven2020; Menier et al., Reference Menier, Bucci, Yagoubi, Mathelin and Schoenauer2023; Lepage et al., Reference Lepage, Beneddine, Fiorini, Mortazavi, Sipp and Thome2025), the reduced dimension is intentionally kept very small. In this setting, the quadratic nonlinear term can already be evaluated extremely efficiently on GPU. As a result, the hyper-reduced formulation is less efficient than the standard tensorial ROM in this low-dimensional regime.
5. Conclusion
This work set out to assess the computational relevance of the ECSW hyper-reduction method in modern reduced-order modeling workflows. While hyper-reduction is traditionally introduced to accelerate nonlinear term evaluation, its practical benefit in GPU-accelerated and deep-learning-augmented settings remains unclear. Our objective was therefore not to improve model accuracy, but to rigorously quantify the numerical cost of ECSW and determine under which conditions it remains advantageous compared to standard tensorial ROM formulations.
After validating the implementation on a simple periodic flow configuration of the fluidic pinball at
$ \mathit{\operatorname{Re}}=30 $
 , we focused exclusively on computational aspects. We derived exact operation counts for both tensorial and hyper-reduced formulations, showing that their theoretical complexities scale respectively as
$ \mathcal{O}\left({r}^3\right) $
 and
$ \mathcal{O}(rm) $
 , where
$ r $
 is the reduced dimension and
$ m $
 the number of retained quadrature points. Extensive numerical experiments on both CPU and GPU hardware confirmed these asymptotic trends but also revealed strong hardware dependencies. On CPUs, hyper-reduction behaves as expected, providing linear scaling and consistent speed-ups even for moderately sized reduced models. On GPUs, however, the picture is more nuanced: for small to medium reduced spaces—typical of hybrid ROM–deep learning architectures—the quadratic tensorial formulation can in fact be faster, owing to its tighter integration with highly optimized batched matrix kernels.
Overall, our results demonstrate that ECSW hyper-reduction remains a powerful tool for CPU-based reduced-order modeling, especially for large reduced systems or higher-order nonlinearities. However, in GPU-based hybrid frameworks where the ROM must coexist with neural-network components, its computational advantage is not guaranteed. The study therefore provides practical guidance: hyper-reduction should be employed when the reduced system is sufficiently large, when nonlinear operators dominate the cost, or when CPU-based execution remains necessary. In contrast, for small latent spaces running on GPU hardware, standard tensorial reduction already offers near-optimal performance.
By clarifying these trade-offs, this work contributes a concrete benchmark for future hybrid ROMs and helps practitioners decide when hyper-reduction genuinely improves computational efficiency.
Data availability statement
The data, code, and materials supporting the findings of this study are openly available on GitHub at the following repository: nicolaslepagecnam/ECSW-hyper-reduction-for-GPU. This repository contains all scripts required to reproduce the simulations, reduced-order models, hyper-reduction weights, and GPU performance experiments.
Author contribution
Author contributions follow the CRediT taxonomy (https://www.casrai.org/credit.html). Conceptualization: All authors; Data curation: N.L., D.S.; Final approval: All authors; Formal Analysis: N.L., M.G.C., S.B., C.F., D.S.; Investigation: N.L.; Software: N.L., M.G.C.; Supervision: C.F., S.B., D.S., I.M., N.T.; Validation: N.L., M.G.C.; Visualization: N.L.; Writing – original draft preparation: N.L.; Writing – review and editing: All authors. All authors approved the final manuscript.
Funding statement
This work was supported by the French National Research Agency (ANR) under grant ANR-20-THIA-0002.
Competing interests
The authors declare that they have no known financial, professional, or personal relationships that could be perceived as influencing the research reported in this article.
Ethical standards
The research meets all ethical guidelines, including adherence to the legal requirements of the study country.
Use of Generative AI
Generative AI tools (specifically GPT-5) were used solely for minor proofreading and language refinement during the preparation of this manuscript. All scientific content, analyses, and conclusions are entirely the authors’ own, and the authors take full responsibility for the final text.
Appendix A. Detailed explanation of our implementation of the ECSW method
A.1. Quadrature rule for FEM and quantities to export
A.1.1. Quadrature in the finite element method
Consider a generic evolution problem in strong form

where
$ \mathcal{L} $
 is a spatial differential operator. Introducing a test function
$ {\varphi}_j $
 and integrating over the domain yields the weak form

With the finite element approximation
$ u\left(x,t\right)={\sum}_{i=1}^n{u}_i(t)\hskip0.1em {\varphi}_i(x) $
 , we obtain a semi-discrete system

The evaluation of these integrals is performed numerically using a quadrature rule.
A.1.2. Numerical quadrature
Over each triangular element
$ {K}_e $
 , the integral of a generic function
$ f $
 is approximated by a weighted sum over
$ {n}_g $
 Gauss points:

The quadrature points
$ \left({\xi}_{\mathrm{\ell}},{\eta}_{\mathrm{\ell}}\right) $
 and weights
$ {\omega}_{g,\mathrm{\ell}} $
 are defined on the reference triangle,

and mapped to each physical element by

In this work, we employ the
$ 7 $
 -point Dunavant rule, which is exact for all polynomials up to degree
$ 5 $
 (see Figure A1).
Triangular reference element: Dunavant
$ 7 $
 -point quadrature rule.

Figure A1. Long description
A two-dimensional plot features a right-angled triangle with vertices at (0,0), (1,0), and (0,1) on a coordinate system where the horizontal axis is xi and the vertical axis is eta. Inside the triangle, seven colored and numbered circular points are distributed.
* Point 1 (blue) is located near the center.
* Point 2 (orange), Point 6 (olive), and Point 4 (brown) are positioned near the bottom edge.
* Point 7 (cyan) and Point 3 (red) are near the left vertical edge.
* Point 5 (pink) is near the hypotenuse.
A legend titled Gauss points on the right provides the following data:
* Point 1: xi = 1/3, eta = 1/3, omega = 0.225.
* Point 2: xi = (6 minus square root of 15) all over 21, eta = (6 minus square root of 15) all over 21, omega = (155 minus square root of 15) all over 1200.
* Point 3: xi = (6 minus square root of 15) all over 21, eta = (9 plus 2 times square root of 15) all over 21, omega = (155 minus square root of 15) all over 1200.
* Point 4: xi = (9 plus 2 times square root of 15) all over 21, eta = (6 minus square root of 15) all over 21, omega = (155 minus square root of 15) all over 1200.
* Point 5: xi = (6 plus square root of 15) all over 21, eta = (6 plus square root of 15) all over 21, omega = (155 plus square root of 15) all over 1200.
* Point 6: xi = (6 plus square root of 15) all over 21, eta = (9 minus 2 times square root of 15) all over 21, omega = (155 plus square root of 15) all over 1200.
* Point 7: xi = (9 minus 2 times square root of 15) all over 21, eta = (6 plus square root of 15) all over 21, omega = (155 plus square root of 15) all over 1200.
A.1.3. Matrix representation
After applying the quadrature rule and inserting the finite element expansion, each weak-form term can be expressed as a weighted sum of basis evaluations:

Introducing the matrices

the discrete operator can be written compactly as

A.1.4. Quantities to export from FEM framework
Therefore, to reproduce the full quadrature algebra externally and enable ECSW hyper-reduction, the following data must be extracted from the FEM solver:
-
• the physical coordinates $ \left({x}_{\mathrm{\ell}},{y}_{\mathrm{\ell}}\right) $
of all Gauss quadrature points over the mesh, -
• the corresponding quadrature weights $ {\omega}_{\mathrm{\ell}} $
forming the diagonal matrix
$ W $
, -
• and the sampling matrices $ \Theta $
,
$ {\partial}_x\Theta $
, and
$ {\partial}_y\Theta $
, containing the basis and derivative evaluations at those points.


These objects fully describe the numerical integration process and form the interface between the FEM solver and the ECSW procedure.
A.2. Description of the term to empirically approximate
A.2.1. Expressing the nonlinearity as a source term in weak form
Since the reduction of the linear system components is straightforward and computationally inexpensive, we focus our application of hyper-reduction exclusively on the nonlinear contributions.
The 2D incompressible Navier–Stokes equations are given by:

where
$ {\mathbf{w}}_t={\left[{u}_t\left(x,y,t\right),{v}_t\left(x,y,t\right)\right]}^{\top } $
 is the velocity field and
$ {p}_t\left(x,y,t\right) $
 is the pressure.
After lifting
$ {\mathbf{w}}_t(t)=\overline{\mathbf{w}}+\mathbf{w}(t) $
 , the explicit nonlinear convection term that appears in the equation governing
$ \mathbf{w} $
 reads:

However, in our code, as is often the case in computational fluid dynamics, this term is treated explicitly. This effectively makes the system linear, as the nonlinear term is now essentially a fixed source term that no longer depends on the unknown:

A.2.2. Numerical quadrature
We now clarify how this source term is treated in the finite element framework. Since the velocity field has two components,
$ u $
 and
$ v $
 , and each component is associated with its own finite element space, we denote by
$ {\left\{{\varphi}_i^u\right\}}_{i=1}^{n_u} $
 and
$ {\left\{{\varphi}_i^v\right\}}_{i=1}^{n_v} $
 the basis functions corresponding to the
$ u $
 - and
$ v $
 -velocity components, respectively. The pressure component
$ p $
 does not appear in the convection term and is therefore excluded from this step.
The explicit nonlinear term
$ \mathbf{f}\left({\mathbf{w}}^{t-\Delta t}\right) $
 is projected independently onto the
$ u $
 and
$ v $
 test spaces, resulting in two sets of integrals:


These integrals are approximated using Gauss quadrature with
$ \tilde{m} $
 points
$ {\left\{{x}_{\mathrm{\ell}}\right\}}_{\mathrm{\ell}=1}^{\tilde{m}} $
 and weights
$ {\left\{{\omega}_{\mathrm{\ell}}\right\}}_{\mathrm{\ell}=1}^{\tilde{m}} $
 :


Mathematically, each field is associated with its own finite element space:
$ {H}^1\left(\Omega \right) $
 for velocity components and
$ {L}^2\left(\Omega \right) $
 for pressure. However, in practice, these fields are stored in a single global vector of degrees of freedom that spans the product space of all three variables. This means that the source term vector must match the structure of the full discrete unknown vector, which includes the pressure degrees of freedom—even though they do not receive any contribution from the convection term.
Accordingly, the global source vector
$ \mathbf{f}\in {\mathrm{\mathbb{R}}}^n $
 , where
$ n={n}_u+{n}_v+{n}_p $
 , is assembled by interleaving the
$ u $
 and
$ v $
 contributions and inserting zeros at the pressure dof positions:

We will express this finite element quadrature term with the matrices discussed in Appendix A.1.
Given the global finite element vector
$ \mathbf{w}={\left[\hskip0.1em \mathbf{u},\mathbf{v},\mathbf{p}\hskip0.1em \right]}^{\top}\in {\mathrm{\mathbb{R}}}^n $
 , which stacks the degrees of freedom of the streamwise velocity
$ u $
 , cross-stream velocity
$ v $
 , and pressure
$ p $
 , we define the following sampling operators acting on the
$ \tilde{m} $
 Gauss points of the mesh:
-
• $ {\Theta}_u,{\Theta}_v\in {\mathrm{\mathbb{R}}}^{\tilde{m}\times n} $
: interpolate the discrete velocity fields onto Gauss points, such that
$ {\left({\Theta}_u\mathbf{w}\right)}_{\mathrm{\ell}}=u\left({x}_{\mathrm{\ell}}\right) $
and
$ {\left({\Theta}_v\mathbf{w}\right)}_{\mathrm{\ell}}=v\left({x}_{\mathrm{\ell}}\right) $
; -
• $ {\partial}_x{\Theta}_u,{\partial}_y{\Theta}_u,{\partial}_x{\Theta}_v,{\partial}_y{\Theta}_v\in {\mathrm{\mathbb{R}}}^{\tilde{m}\times n} $
: provide spatial derivatives of the velocity basis, for example,
$ {\left({\partial}_x{\Theta}_u\mathbf{w}\right)}_{\mathrm{\ell}}={\partial}_xu\left({x}_{\mathrm{\ell}}\right) $
and
$ {\left({\partial}_y{\Theta}_v\mathbf{w}\right)}_{\mathrm{\ell}}={\partial}_yv\left({x}_{\mathrm{\ell}}\right) $
; -
• $ W=\operatorname{diag}\left({\omega}_1,\dots, {\omega}_{\tilde{m}}\right)\in {\mathrm{\mathbb{R}}}^{\tilde{m}\times \tilde{m}} $
: diagonal matrix of Gauss weights used for numerical integration.


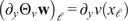

Each
$ \Theta $
 thus acts as a linear projection from the nodal degrees of freedom to weak form function or derivative evaluations at all quadrature points, filtered by variable component (
$ u $
 ,
$ v $
 , or
$ p $
 ).
Here is the complete matrix form where
$ \odot $
 is the Hadamard product:


A.2.3. Reduced weak form in vector-valued FEM
We now introduce reduced-order modeling by constructing a low-dimensional approximation space from full-order snapshot data. Select
$ r\ll n $
 POD modes
$ {\{{\boldsymbol{\phi}}_j\}}_{j=1}^r $
 and define the reduced approximation as:

where
$ \mathbf{a}(t)\in {\mathrm{\mathbb{R}}}^r $
 denotes the vector of reduced coefficients. Each POD mode
$ {\boldsymbol{\phi}}_j:\Omega \to {\unicode{x211D}}^3 $
 is a vector-valued function containing degrees of freedom from all three finite element fields: the two velocity components and the pressure. We thus write:

In other words, the reduced approximation
$ {\mathbf{w}}_h\left(x,t\right) $
 lives in a reduced subspace of the full-order space:

While the FE weak form treats each component separately—testing the equations against
$ {\varphi}_i^u $
 ,
$ {\varphi}_i^v $
 , or
$ {\varphi}_i^p $
 depending on the PDE being discretized—the reduced-order model uses global modes
$ {\boldsymbol{\phi}}_j $
 as both trial and test functions. Therefore, we define the reduced test space to be the same as the reduced trial space:

Projecting the nonlinear term onto the reduced test space gives the reduced weak form:

Using the reduced approximation
$ {\mathbf{w}}_h\left(x,t\right)\approx {\sum}_{j=1}^r{\boldsymbol{\phi}}_j(x){a}_j(t) $
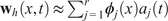 and applying Gauss quadrature, the
$ i $
 -th component of the nonlinear vector becomes:

Using the matrix notations from Subsection A.2.2, we now express the entire reduced nonlinear term compactly using the POD basis and Gauss-point sampling matrices. We recall that the nonlinear convection term is evaluated explicitly using the velocity fields only, so only the
$ u $
 and
$ v $
 components of the reduced modes and sampling matrices appear.
We obtain:

This expression is now entirely written in terms of matrix–vector operations involving the reduced basis, the FEM interpolation matrices at Gauss points, and the reduced coordinates
$ \mathbf{a} $
 . It is therefore suitable for further acceleration using hyper-reduction techniques such as ECSW, which will be introduced in Section A.3.
A.3. Hyper-Reduction Targets
ECSW hyper-reduction acts directly on the discrete inner product defining the quadratic nonlinear term. By replacing the full quadrature matrix
$ W $
 with a sparse surrogate, supported only on a limited set of retained Gauss points, the cost of evaluating the nonlinear operator is drastically reduced. In practice, sparsifying the weighted inner product modifies three categories of quantities:
-
• Nonlinear function evaluations at Gauss points, obtained from the POD state through $ {\Theta}_u $
,
$ {\Theta}_v $
,
$ {\partial}_x{\Theta}_u $
,
$ {\partial}_y{\Theta}_u $
,
$ {\partial}_x{\Theta}_v $
,
$ {\partial}_y{\Theta}_v $
. -
• The quadrature weights, where its ECSW-compressed version replaces the full diagonal matrix $ W $
, supported only on the retained points. -
• The reduced projection operators mapping nonlinear Gauss-point contributions back to the reduced space, such as $ {\Phi}^{\top }{\Theta}_u^{\top }W $
and
$ {\Phi}^{\top }{\Theta}_v^{\top }W $
, which now only involve the retained quadrature points and their modified weights.


Once hyper-reduction is applied, evaluating the nonlinear term requires accessing these quantities only at the retained Gauss points, yielding a significant reduction in online computational cost. Moreover, this sparsified structure preserves Galerkin consistency and leverages precomputations to eliminate any operations scaling with the full-order dimension
$ n $
 during the online phase.
A.4. Construction of the NNLS problems for 2D hyper-reduction
To reduce the computational cost of evaluating the explicit nonlinear convection term online, we apply the Energy-Conserving Sampling and Weighting (ECSW) method to sparsify the quadrature points and determine optimal empirical weights. As shown previously, the reduced nonlinear term involves matrix–vector operations combining the POD basis
$ \Phi $
 , the FEM sampling matrices at Gauss points (e.g.,
$ {\Theta}_u $
 ,
$ {\partial}_x{\Theta}_u $
 , etc.), and the reduced coordinates
$ \mathbf{a} $
 . To efficiently approximate this reduced nonlinear term, we now formulate two independent non-negative least squares (NNLS) problems targeting the two separate vector contributions to the nonlinear source term.
A.4.1. Snapshot-based reformulation of the nonlinear term
Let
$ {\mathbf{a}}^{(k)}\in {\mathrm{\mathbb{R}}}^r $
 denote the reduced coefficients of snapshot
$ k=1,\dots, {N}_{\mathrm{snap}} $
 . For each snapshot, we evaluate the reduced nonlinear term:

where the intermediate Gauss-point contributions
$ {\mathbf{f}}_{m,u}^{(k)},{\mathbf{f}}_{m,v}^{(k)}\in {\unicode{x211D}}^{\tilde{m}} $
 are defined component-wise as:


A.4.2. Energy-conserving sampling and weighting via non-negative least squares
We now approximate the matrix–vector product
$ {\Phi}^{\top }{\Theta}_u^{\top }W\hskip0.1em {\mathbf{f}}_{m,u}^{(k)} $
 using a sparse set of quadrature weights
$ {\boldsymbol{\omega}}_u\in {\unicode{x211D}}^{\tilde{m}} $
 by solving the following empirical approximation:

To determine the optimal sparse weights, we collect all
$ {N}_{\mathrm{snap}} $
 snapshots into a single least-squares problem. Define the stacked system:

and solve the NNLS problem:

An identical procedure is applied independently to the second contribution, corresponding to the
$ v $
 -component:

with

and the corresponding NNLS problem:

A.4.3. Remarks
Note that these two NNLS problems are solved once during the offline stage and yield sparse weight vectors
$ {\boldsymbol{\omega}}_u $
 and
$ {\boldsymbol{\omega}}_v $
 with many zero entries. The associated non-zero quadrature points constitute the empirical integration rule. This approach preserves Galerkin consistency and ensures that only a reduced set of quadrature points is needed during the online phase, significantly decreasing the cost of evaluating the nonlinear term. The result is a sparse, yet accurate approximation of the reduced nonlinear operator that scales independently of the full-order DOF size
$ n $
 .


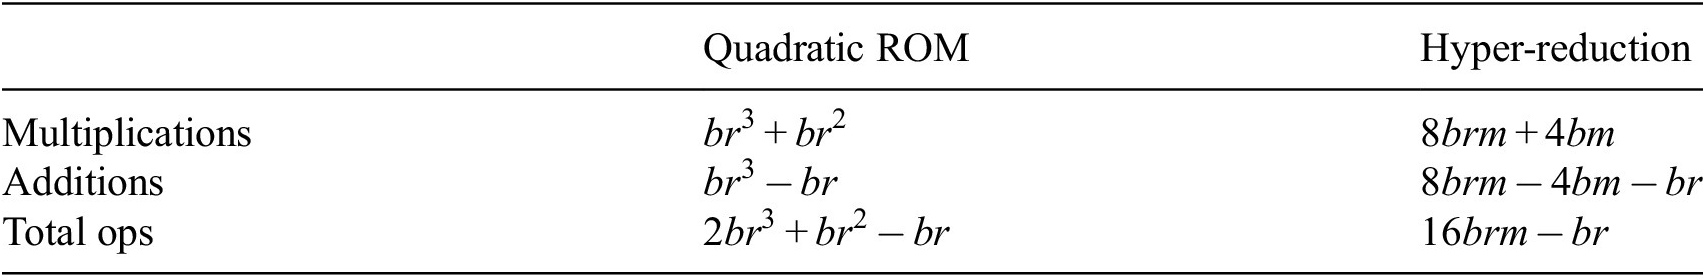


 Open access


Comments
No Comments have been published for this article.