





1. Introduction
Finite-dimensional inverse problems are ubiquitous in the computational sciences, as they naturally appear in a plethora of applications. An incomplete list of examples includes most types of computational imaging [Reference Adcock and Hansen1, Reference Barrett and Myers16, Reference Bouman30], matrix completion [Reference Candes and Recht34], parametric PDEs/system identification [Reference Adcock, Brugiapaglia and Webster2], phase retrieval [Reference Candes, Strohmer and Voroninski36, Reference Fannjiang and Strohmer52, Reference Shechtman, Eldar, Cohen, Chapman, Miao and Segev97], quantised sampling [Reference Boufounos and Baraniuk29], etc. Most often, we can express these problems using the following general model:
 \begin{align} \text{Given noisy measurements } y = F(x,e) \text{ of } x \in \mathscr{M}_1 \quad\text{ and }\quad e \in \mathscr{E}, \text{ recover } x. \end{align}
Here,
 $x$
represents the signal of interest, while
 $e$
represents the noise. The sets
 $\mathscr{M}_1$
and
 $\mathscr{E}$
describe the signals of interest and the potential noise, respectively. The function
 $F \colon \mathscr{M}_1\times \mathscr{E} \to \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
models the forward process and is deliberately kept general to encompass many known models. Examples include
 \begin{align} y &= G(x) + e, &\text{(additive noise)}\\[-10pt]\nonumber \end{align}
 \begin{align} y &= G(x)\odot e, &\text{(multiplicative noise)}\\[-10pt]\nonumber \end{align}
 \begin{align} y &= G(x)\odot e_1 + e_2, &\text{(mixture of multiplicative and additive noise)} \end{align}
where
 $G \colon \mathscr{M}_1 \to \mathscr{M}_2$
is a linear or non-linear forward map, and the dimension of the set
 $\mathscr{E}$
depends on the considered model in such a way that the point-wise multiplication
 $\odot$
is defined.
In most instances of interest, the problem of recovering
 $x$
given
 $y$
is ill-posed or undersampled, unless further assumptions are made. An inverse problem is ill-posed if it is not well-posed in the sense of Hadamard [Reference Hadamard63, Reference Hadamard64]. In particular, it is ill-posed if either there does not exist a solution
 $x$
for every
 $y$
, or the solution is not unique, or the solution does not depend continuously on
 $y$
. We consider the case when the solution is not unique. This can be the case if the forward model
 $F$
is either poorly conditioned or dimensionality reducing. A standard assumption for making the problem (1) tractable is to assume that the noiseless forward model is injective when restricted to the model class
 $\mathscr{M}_1$
. This assumption is a cornerstone for models with additive noise, as it allows for accurate reconstruction up to the noise level in both the linear [Reference Bourrier, Davies, Peleg, Pérez and Gribonval31, Reference Foucart and Rauhut56, Reference Traonmilin and Gribonval104] and non-linear [Reference Keriven and Gribonval73] settings. Traditionally, the set
 $\mathscr{M}_1$
has been given a precise mathematical description, and reconstruction methods have been designed for the given choice of
 $\mathscr{M}_1$
. Examples of sets
 $\mathscr{M}_1$
include sparse vectors [Reference Candes35], unions of subspaces [Reference Blumensath26], manifolds [Reference Baraniuk and Wakin15], sparsity in a given basis [Reference Adcock, Hansen, Poon and Roman4] or frame [Reference Poon92], matrices with low rank [Reference Candès and Plan37, Reference Kabanava, Kueng, Rauhut and Terstiege70], etc.
More recently, data-driven approaches [Reference Arridge, Maass, Öktem and Schönlieb12, Reference Jin, McCann, Froustey and Unser69] have emerged as an alternative to many of these standard methods, often promising superior performance [Reference Zhu, Liu, Cauley, Rosen and Rosen112]. Methods based on data typically do not specify the solution set
 $\mathscr{M}_1$
, but aim to learn the reconstruction mapping
 $\Psi \colon \mathscr{M}_2\to \mathscr{M}_1$
given a finite number of training data
 $\mathscr{T}\subset \mathscr{M}_1$
and access to the forward model
 $F$
[Reference Arridge, Maass, Öktem and Schönlieb12]. This approach has the advantage that the learned set
 $\mathscr{M}_1$
might provide a better approximation of the underlying data stemming from a real-world process, rather than a potentially simplistic abstract mathematical modelling of the set
 $\mathscr{M}_1$
. However, the challenge with these methods is that the learned mapping
 $\Psi$
tends to produce accurate reconstructions of all elements in
 $\mathscr{T}$
, regardless of whether the noiseless problem is injective on
 $\mathscr{M}_1$
or not. This has made these methods susceptible to both hallucinations [Reference Gottschling, Antun, Hansen and Adcock62, Reference Muckley, Riemenschneider, Radmanesh, Kim, Jeong, Ko, Jun, Shin, Hwang, Mostapha and Arberet85] and instabilities [Reference Antun, Renna, Poon, Adcock and Hansen10].
The purpose of this work is to develop a mathematical framework for inverse problems which provides a notion of optimality when
 $F$
is not necessarily injective on
 $\mathscr{M}_1$
, and to provide a variational expression for the optimal mappings in this setting. In summary, this work answers the question posed by M. Burger and T. Roith in Learning in Image Reconstruction: A Cautionary Tale [Reference Burger and Roith33],
Can we ever quantify the reconstruction error [of ill-posed inverse problems]?
Our main contributions are the following:
-
1. We provide a framework which allows for the classification of the lowest achievable reconstruction accuracy for (1). Note that many such frameworks exist in the literature. For example, Gelfand widths in the noiseless linear setting [Reference Pinkus89], best
 $k$
-term approximation [Reference Cohen, Dahmen and DeVore41], and to obtain the worst-case bounds set-valued decoders on Banach spaces have been considered in [Reference Arestov11] and then extended to metric spaces in [Reference Magaril-Il’yaev and Osipenko81], and when noise is included, one has the notion of optimal learning [Reference Binev, Bonito, DeVore and Petrova25] and generalised instance optimality [Reference Bourrier, Davies, Peleg, Pérez and Gribonval31]. See also [Reference Micchelli and Rivlin83] for a survey of early works on optimal recovery. In many of these works, the underlying spaces are infinite- or finite-dimensional Banach spaces, and the reconstruction error is measured by the given norm. A contribution of this work is to consider the general setting of metric spaces, to allow for set-valued decoders which naturally arise as solutions of undersampled inverse problems and to extend previous studies on worst-case scenarios to the average error scenario.
-
2. We derive explicit formulas for set-valued reconstruction mappings which achieve the lowest possible reconstruction error, both in a worst-case sense and in a probabilistic sense. Finding and analysing reconstruction mappings which achieve optimal or near-optimal recovery – given some notion of optimality – is an essential question in inverse problems, and many mappings exist [Reference Binev, Bonito, DeVore and Petrova25, Reference Bourrier, Davies, Peleg, Pérez and Gribonval31, Reference Foucart and Rauhut56, Reference Plaskota90, Reference Traonmilin and Gribonval104]. In this work, we provide explicit formulas for possibly set-valued reconstruction mappings that achieve the lowest possible reconstruction error. Moreover, a contribution of this work is to prove that the optimal mappings in the average error scenario are measurable, compact valued and admit a measurable single-valued selector by utilising the Measurable Maximum Theorem, [Reference Aliprantis and Border6, Theorem 18.19] and Hausdorff distance. As such, this work provides a first and necessary step before any numerical procedure can provide statistical approximations to these mappings.
-
3. We provide lower and upper bounds on the lowest achievable reconstruction accuracy described in Section 1. The bounds solely depend on the forward operator, signal and noise class of the inverse problem and not on the method or decoder used to solve (1). Hence, the performance of any – possibly set-valued – method can be evaluated with respect to the problem’s intrinsic optimal accuracy. However, obtaining lower bounds comes at a price: in contrast to compressed sensing results, which typically provide upper bounds (see [Reference Bourrier, Davies, Peleg, Pérez and Gribonval31, Reference Foucart and Rauhut56]), fewer assumptions are required, and for a non-zero lower bound, the reconstruction error can not vanish. Specifically, the trade-off is as follows: lower bounds can be derived without assuming that the forward model
$F$
is injective on
$\mathscr{M}_1$
, at the cost that the reconstruction error admits a non-zero limit. A key point in order to obtain lower bounds on reconstruction accuracy is to consider worst-case and average errors instead of point-wise approximation errors. Such worst-case error bounds can be related to the Chebyshev radius, as in [Reference Binev, Bonito, DeVore and Petrova25], and analogous worst-case and average error bounds are established in [Reference Plaskota90] in the case of normed spaces and single-valued decoders.


Remark.
Extending previous work from normed spaces to metric spaces is of particular relevance in imaging applications. In fact, the
 $\ell ^2$
or
 $\ell ^1$
norm are not the only candidates considered for image quality assessment. A prominent example is the structural similarity index (SSI), firstly proposed to assess image quality in [
Reference Wang, Bovik, Sheikh and Simoncelli108
], does not constitute a norm but can rather be related to a metric [
Reference Brunet, Vrscay and Wang32
]. Note that the proposed framework encompasses all metrics, except trivial degenerate metrics.
Remark. (Set-valued decoders, computability and randomised algorithms). Many of the decoders provided in theory will not be computable, as the phenomenon of generalised hardness of approximation [
Reference Antun, Colbrook and Hansen9, Reference Bastounis, Hansen and Vlačić17, Reference Colbrook, Antun and Hansen45, Reference Fefferman, Hansen and Jitomirskaya53, Reference Gazdag and Hansen61
] – within the Solvability Complexity Index (SCI) hierarchy [
Reference Ben-Artzi, Colbrook, Hansen, Nevanlinna and Seidel20, Reference Ben-Artzi, Marletta and Rösler21, Reference Colbrook and Hansen43, Reference Colbrook44, Reference Hansen65
] – happen in many inverse problems. This includes a wide range of neural network decoders, as well as compressed sensing decoders. Typically, they can only be computed to a certain accuracy
 $\epsilon _0 \gt 0$
, referred to as the approximation threshold, and it is the size of the approximation threshold that determines if the decoder can be used in practice. However, as demonstrated in [
Reference Bastounis, Hansen and Vlačić17
], when the decoder is set-valued, randomised algorithms may actually help mitigate the non-computability. This is only possible for set-valued decoders, as single-valued decoders that are non-computable will have no help from randomised algorithms [
Reference Bastounis, Hansen and Vlačić17, Reference de Leeuw, Moore, Shannon and Shapiro47
].
2. Preliminaries
2.1. The forward map and the model class
In the following, we introduce the main assumptions and setup. Let
 $\mathscr{X}$
,
 $\mathscr{Y}$
and
 $\mathscr{Z}$
be non-empty sets. Furthermore, consider subsets
 $\mathscr{M}_1 \subset \mathscr{X}$
and
 $\mathscr{E}\subset \mathscr{Z}$
, referred to as the model class and the noise class, respectively. As outlined in the introduction, we consider inverse problems with a given forward map
 $F \colon \mathscr{M}_1\times \mathscr{E} \to \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \subset \mathscr{Y}$
, with
 \begin{equation*} \mathscr{M}_2^{\kern0.5pt\mathscr{E}} = F(\mathscr{M}_1\times \mathscr{E}\kern1.6pt) = \{y \in \mathscr{Y}\,:\, \exists (x,e) \in \mathscr{M}_1\times \mathscr{E}\text{ s.t.} \ y=F(x,e) \} \end{equation*}
denote the image of
 $F\colon \mathscr{X}\times \mathscr{Z}\to \mathscr{Y}$
on the class
 $\mathscr{M}_1\times \mathscr{E}$
. We consider inverse problems as:
 \begin{align} \text{Given noisy measurements } y = F(x,e) \text{ of } x \in \mathscr{M}_1\quad \text{ and }\quad e \in \mathscr{E}, \text{ recover } x, \end{align}
where
 $e$
represents noise and
 $x$
is the signal of interest. The goal of solving the inverse problem is to produce an approximation
 $\hat {x}$
of the true solution
 $x$
. In order to quantify the error of the approximation
 $\hat {x} \in \mathscr{X}$
to the sample signal
 $x\in \mathscr{M}_1$
, it is common to assume [Reference Cohen, Dahmen and DeVore41, Reference Foucart and Rauhut56, Reference Pinkus89] that
 $\mathscr{X}$
is a normed space, or even a Banach or Hilbert space. In the current work, we extend the scope to the more general setting of metric spaces. The use of metrics – rather than norms – allows for a more general theory, in which normed vector spaces are a special case. Thus, we equip the sets
 $\mathscr{X}$
,
 $\mathscr{Y}$
and
 $\mathscr{Z}$
with metrics
 $d_{\mathscr{X}}$
,
 $d_{\mathscr{Y}}$
and
 $d_{\mathscr{Z}}$
, respectively, and on each set, we consider the topology induced by the respective metric. To avoid certain pathological cases for metric spaces, we make assumptions on the choice of metrics involved. Our first assumption is the following.
Assumption 1.
-
(1) We assume that the metrics
$d_{\mathscr{X}}$
,
$d_{\mathscr{Y}}$
,
$d_{\mathscr{Z}}$
are chosen so that the topologies induced by the metrics are second countable (they admit a countable base).
-
(2) We assume that the metrics
$d_{\mathscr{X}}$
and
$d_{\mathscr{Z}}$
satisfy the Heine-Borel property, i.e., that all closed and bounded sets are compact.


Here, the first assumption ensures that the topologies induced by the metrics are separable, which is a convenient assumption for both theoretical and practical purposes. In particular, this assumption excludes metrics such as the discrete metric over an uncountable set, as one cannot find a countable base for an uncountable set using this metric.
For the second assumption, we recall that in metric spaces, a compact subset is automatically closed and bounded; however, the converse does not necessarily hold, unless the metrics satisfy the Heine-Borel property. Note that this 2 is not implied by 1, as for example the bounded metric
 $d_{\mathscr{X}}(x,y) = \min \{\|x-y\|_{\ell ^2}, 1\}$
on
 $\mathscr{X} = {\mathbb{C}}^N$
satisfies assumption1 (since
 $d_{\mathscr{X}}$
induces the same topology as the Euclidean topology, which is second countable), but not assumption2 (since
 ${\mathbb{C}}^N$
is closed and bounded but not compact with respect to
 $d_{\mathscr{X}}$
). Finally, note that together with second countability, the Heine-Borel property implies in particular that
 $\mathscr{X}$
is a complete separable metric space, usually referred to as a Polish space.
2.2. Set-valued reconstruction maps
Now that the preliminaries have been clarified, we return to the problem of solving the inverse problem in (5). A reconstruction mapping for (5) is a mapping that takes a measurement
 $y=F(x,e)$
and returns one or more approximations
 $\hat {x}$
to the unknown signal
 $x$
. That is, a reconstruction mapping is a set-valued function
 $\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
, where
 $\varphi$
takes values in the power set
 $2^{\mathscr{X}}$
of the set
 $\mathscr{X}$
. Note that it is necessary to consider set-valued maps, as model-based methods often write the reconstruction mapping as an optimisation problem. These problems might not have unique solutions; see, e.g., [Reference Colbrook, Antun and Hansen45, SI, Section 3.B] for a few standard examples. Finally, we mention that given a set-valued mapping
 $\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
, we call a function
 $f \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \to \mathscr{X}$
a selector for
 $\varphi$
if it satisfies
 $f(y) \in \varphi (y)$
for each
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
.
Distances between sets in
 $\mathscr{X}$
will be measured via the Hausdorff distance. Given subsets
 $A,B \subseteq \mathscr{X}$
, their Hausdorff distance is
 \begin{equation*} d_{\kern-1pt \mathscr{X}}^H(A,B)\,:\!=\, \max \Big \{\sup_{a \in A} \inf_{b\in B} d_{\mathscr{X}}(a,b), \sup _{b \in B} \inf _{a\in A} d_{\mathscr{X}}(a,b)\Big \}. \end{equation*}
The Hausdorff distance satisfies all the properties of a metric only when restricted to the subsets of
 $\mathscr{X}$
that are bounded (which ensures
 $d_{\kern-1pt \mathscr{X}}^H$
is finite) and closed (which ensures that
 $d_{\kern-1pt \mathscr{X}}^H(A,B)=0$
only if
 $A=B$
). With a slight abuse of notation, we will denote
 $d_{\kern-1pt \mathscr{X}}^H(\{a\},B)$
by
 $d_{\kern-1pt \mathscr{X}}^H(a,B)$
. The Hausdorff distance between a point and a set should not be confused with the usual distance between a point and a set,
 $\operatorname {dist}_{\mathscr{X}}(a,B)\,:\!=\, \inf _{b\in B} d_{\mathscr{X}}(a,b)$
. Indeed, note that
 $\operatorname {dist}_{\mathscr{X}}(a,B)=\inf _{b\in B} d_{\mathscr{X}}(a,b)\leq \sup _{b\in B} d_{\mathscr{X}}(a,b)=d_{\kern-1pt \mathscr{X}}^H(a,B)$
.
We require an extra assumption that relates the forward map
 $F$
and the model class
 $\mathscr{M}_1$
. In particular, we require that for every
 $y$
, the set of possible true solutions
 $x$
’s is bounded. Throughout the text, we denote by
 $\pi _1\colon \mathscr{X} \times \mathscr{Z} \to \mathscr{X}, (x,e) \mapsto x$
the projection on the first component.
Assumption 2.
We assume that for every
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
the feasible set
 \begin{align} F_y\,:\!=\,\pi _1(F^{-1}(y)) = \{x \in \mathscr{M}_1\,:\, \exists e\in \mathscr{E} \text{ s.t. } F(x,e)=y\} \end{align}
is bounded.
The feasible set
 $F_y$
consists of all the candidate solutions
 $x$
’s that are consistent with the measurement
 $y$
, for some realisation of the noise
 $e$
. Note that the definition of
 $\mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
implies that the feasible set is non-empty. Additionally, in Remark 3.2, we outline assumptions on the forward map such that the feasible set contains more than one element.
The previous condition is satisfied, for example, if the model class
 $\mathscr{M}_1$
is compact, as assumed in e.g., [Reference Binev, Bonito, DeVore and Petrova25].
Finally, we clarify our notation for objects in a metric space
 $(X,d)$
. We denote by
 $B_d(x,r)$
the closed ball of centre
 $x\in X$
and radius
 $r\geq 0$
. If
 $A\subseteq X$
, then the closed ball around
 $A$
of radius
 $r\geq 0$
is
 \begin{align*} B_d(A,r) = \{x \in X\,:\, \operatorname {dist}_d(x,A) \leq r\} = \bigcup _{x \in A} B_d(x,r) \end{align*}
where we recall that
 $\operatorname {dist}_d(x,A) = \inf _{a \in A} d(x,a)$
.
Finally, the diameter of
 $A\subseteq X$
is denoted by
 $\operatorname {diam}_d(A)\,:\!=\,\sup \{d(a,a')\,:\,a,a'\in A\}$
. The subscript
 $d$
is omitted whenever the metric is unambiguous from context.
3. Main results
This section introduces the inverse problem framework studied in this paper, highlighting the key concepts of an optimal mapping and the kernel size, which serve as bounds on the reconstruction error. The section is divided into two subsections that both introduce the definitions of an optimal mapping and the kernel size, but for different measures of accuracy. In particular, Section 3.1 presents an analysis based on the worst-case error, whereas Section 3.2 considers a probabilistic model class, where an average error is analysed. The main results, given in Theorems3.1 and 3.2 for Sections 3.1 and 3.2, respectively, bound the optimality constant of an optimal mapping in terms of the kernel sizes and provide an explicit construction of an optimal reconstruction mapping. Finally, in Section 4, we elaborate on how these quantities relate to common frameworks in the literature. The proofs of the main results are referred in Section 7.
3.1. Worst-case optimality bounds and an optimal map with worst-case noise
What is the best possible reconstruction error one can achieve for a given model class
 $\mathscr{M}_1$
? This is an old question [Reference Micchelli and Rivlin83] that has been asked many times and in different settings [Reference Binev, Bonito, DeVore and Petrova25, Reference Bourrier, Davies, Peleg, Pérez and Gribonval31, Reference Cohen, Dahmen and DeVore41, Reference Ettehad and Foucart50, Reference Foucart, Liao, Shahrampour and Wang58, Reference Keriven and Gribonval73, Reference Traonmilin and Gribonval104, Reference Traonmilin, Gribonval and Vaiter105]. In the definition below, we investigate this question for measurements contaminated by worst-case noise. This definition has appeared in [Reference Ettehad and Foucart50, Reference Foucart, Liao, Shahrampour and Wang58] for the linear model with additive noise in a normed vector space and is here generalised to metric spaces.
Definition 1 (Optimality constant with worst-case noise). The optimality constant with worst-case noise of the inverse problem (1) is
 \begin{align*} c_{\mathrm{opt}}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt) & = \inf _{\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}} \sup _{x\in \mathscr{M}_1} \sup _{e \in \mathscr{E}} \ d_{\kern-1pt \mathscr{X}}^H(x, \varphi (F(x,e))). \end{align*}
A mapping
 $\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
that attains such an infimum is called an optimal map with worst-case noise.
Given the optimality constant with worst-case noise of an inverse problem (1), the question arises on how to upper and lower bound such an optimality constant. As shown in Theorem3.1, the upper and lower bounds can be obtained by referring to a constant intrinsic to the problem, its kernel size with worst-case noise, as defined below.
Definition 2 (Kernel size with worst-case noise). The kernel size with worst-case noise of the problem (1) is
 \begin{align} \operatorname {kersize}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt) &= \sup _{\substack { (x,e),(x',e')\in \mathscr{M}_1\times \mathscr{E} \text{ s.t. }\\ F(x,e) = F(x',e')} } d_{\mathscr{X}}(x,x'). \end{align}
Remark.
The kernel size with worst-case noise has been considered under different names in previous work. This includes, but is not limited to, the supremum taken over the measurements
 $y$
of the diameter of the Chebyshev balls of the feasible sets
 $F_y$
, similar to [
Reference Binev, Bonito, DeVore and Petrova25
], or the diameter of information in [
Reference Plaskota90
]. However, as this work focuses on characterising accuracy bounds for undersampled and ill-posed inverse problems, we opt for referring to the above-defined constant as kernel size. In Example 1 in Section
4
, more details on this relation are presented.
The kernel size with worst-case noise gives the maximum distance between any two points
 $x,x'\in \mathscr{M}_1$
with identical measurement
 $y = F(x,e) = F(x',e')$
for some noise vectors
 $e,e'\in \mathscr{E}$
. It is worth observing that the optimality constant and the kernel size with worst-case noise also can be expressed as follows.
 \begin{align} c_{\mathrm{opt}}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt) & = \inf _{\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}} \sup _{y\in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \sup _{x \in F_y} \ d_{\kern-1pt \mathscr{X}}^H(x, \varphi (y)) \nonumber \\ \text{kersize}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt) & =\sup _{y \in \mathscr{M}_{2}^{\mathscr{E}}} \mathrm{diam}_{d_{\mathscr{X}}}(F_y). \end{align}
This establishes a connection of the optimality constant and the kernel size with the worst-case to the feasible sets
 $F_y$
. In our first theorem, we provide an upper and lower bound on the optimality constant in terms of the kernel size with worst-case noise. Moreover, we provide a variational expression for an optimal map with worst-case noise.
Theorem 3.1 (Worst-case optimality bounds). Under Assumptions 1 and 2 , the following holds.
-
(1) We have that
(9)
\begin{equation} \text{kersize}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt)/2 \leq c_{\text{opt}}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt) \leq \text{kersize}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt). \end{equation}
-
(2) The map
(10)has non-empty, compact values and it is an optimal map with worst-case noise.
\begin{equation} \Psi (y) = \mathop{\mathrm{argmin}}\limits_{z \in \mathscr{X}}\sup _{x \in F_y} d_{\mathscr{X}}(x,z) = \mathop{\mathrm{argmin}}\limits_{z \in \mathscr{X}} d_{\kern-1pt \mathscr{X}}^H(z, F_y), \end{equation}


The previous theorem illustrates a fundamental limit for the inverse problem (5). Indeed, for (5), one would hope to find a solution whose error is as close to zero as possible. However, the lower bound in (9) shows that there is a fundamental constant intrinsic to the problem – the kernel size with worst-case noise – such that no worst-case reconstruction error can be made smaller than this constant for all possible choices of
 $x \in \mathscr{M}_1$
. Moreover, note that in the definition of the worst-case optimality constant, all potentially set-valued maps are included – in particular, no single-valued selector can obtain a smaller worst-case reconstruction error. Additionally, we can apply the axiom of choice to select a single-valued map
 $\bar {\Psi }$
from the set-valued optimal map in (10). By the definition of the Hausdorff distance, we have that this single-valued selection satisfies
 $d_{\mathscr{X}}(x,\bar {\Psi }(F(x,e))) \leq \sup _{z \in \Psi (F(x,e))}d_{\mathscr{X}}(x,z)=d_{\kern-1pt \mathscr{X}}^H(x,\Psi (F(x,e)))$
for all
 $x \in \mathscr{M}_1$
and
 $e \in \mathscr{E}$
. Hence, by the minimisation property of the optimal map in (10), the bounds also hold for any single-valued selector.
Remark. Note that analogous bounds as in (9) under slightly different assumptions have been obtained in a variety of previous works, including but not limited to [ Reference Arestov11, Reference Binev, Bonito, DeVore and Petrova25, Reference Magaril-Il’yaev and Osipenko81, Reference Plaskota90 ]. However, to the best of our knowledge, the characterisation of the set-valued optimal map (10) as compact-valued has not been considered under the same assumptions.
3.2. Average optimality bounds and optimal map with average error
The previous theorem provides fundamental limits when performance is assessed by considering worst-case reconstruction error for a given inverse problem of the form (5). Such bounds naturally lead to very pessimistic estimates of performance. This motivates the need for a model that considers the average error of a reconstruction mapping, given a probabilistic model of the data. Below, we will adapt the worst-case setup considered in the previous section to a probabilistic model. Note that in the machine learning literature, this notion of average error is often referred to as the risk of a given reconstruction mapping [Reference Shalev-Shwartz and Ben-David96, Chapter 3] [Reference Foucart57, Chapter 1].
We start by introducing the notation. For a topological space
 $(X,\tau )$
, the Borel
 $\sigma$
-algebra of
 $X$
, denoted by
 $\mathscr{B}(X)$
, is the
 $\sigma$
-algebra generated by the family
 $\tau$
of open sets. Elements of
 $\mathscr{B}(X)$
are called Borel sets. If
 $X$
is a metric space, then
 $\mathscr{B}(X)$
is the smallest family of sets containing all the open sets that are closed under countable intersections and countable disjoint unions. See, e.g., [Reference Aliprantis and Border6, Cor. 4.16] for further reference. A Borel measure on
 $X$
is a measure defined on the Borel
 $\sigma$
-algebra
 $\mathscr{B}(X)$
. Borel measurable functions are defined analogously.
Assumption 3.
We consider the measurable spaces
 $(\mathscr{X}\times \mathscr{Z}, \mathscr{B}(\mathscr{X}\times \mathscr{Z}\kern1.7pt))$
,
 $(\mathscr{M}_1\times \mathscr{E}, \mathscr{B}(\mathscr{M}_1\times \mathscr{E}\kern1.6pt))$
,
 $(\mathscr{M}_2^{\kern0.5pt\mathscr{E}},\mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}}))$
and assume that
 $F\colon \mathscr{M}_1\times \mathscr{E} \to \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
is Borel measurable. We equip
 $\mathscr{X}\times \mathscr{Z}$
with a finite Borel measure
 $\mu$
supported on
 $\mathscr{M}_1\times \mathscr{E}$
, such that
 $\mu (\mathscr{M}_1\times \mathscr{E}\kern1.6pt)\gt 0$
. We equip
 $\mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
with the pushforward measure
 $F_*\mu$
given by
 $(F_*\mu )(E) = \mu (F^{-1}(E))$
for every
 $E \in \mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}})$
.
Next, we need to define conditional probabilities on
 $\mathscr{M}_1\times \mathscr{E}$
for the considered measure
 $\mu$
for different values of
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. To compute such conditional probabilities, we consider a disintegration of the measure
 $\mu$
. Intuitively, a disintegration of the measure
 $\mu$
given the mapping
 $F$
, is a family of probability measures
 $\{\mu ^y\}_{y\in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
such that for each
 $y\in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
,
 $\mu ^y$
is concentrated on the set
 $F^{-1}(y)$
, and which allows us to reconstruct the original measure
 $\mu$
by integration. Note that these sets
 $\{F^{-1}(y)\}_{y\in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
might have measure zero with respect to
 $\mu$
. The concept of disintegration is introduced in the following definition, which is taken from [Reference Chang and Pollard40] and adapted to our Assumption3. See also [Reference Bogachev27, Chapter 10] or [Reference Kallenberg72, Chapter 1] for more on disintegration. Moreover, note that in [Reference Plaskota90] a similar tool – that of a regular conditional probability density – is used in order to prove analogous bounds when restricted to normed spaces and single-valued decoders.
Definition 3.
A disintegration of the measure
 $\mu$
along the measurable function
 $F\,:\, \mathscr{M}_1\times \mathscr{E} \rightarrow \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
is a family
 $\{\mu ^y\}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
of probability measures on the measurable space
 $(\mathscr{M}_1 \times \mathscr{E}, \mathscr{B}(\mathscr{M}_1\times \mathscr{E}\kern1.6pt))$
such that
-
(1) for
$F_*\mu$
-almost every
$y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
,
$\mu ^y$
is a probability measure concentrated on
$F^{-1}(y)$
, i.e.,
$\mu ^{y}(\mathscr{M}_1\times \mathscr{E}\setminus F^{-1}(y)) = 0$
for
$F_*\mu$
-almost all
$y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
.and such that, for each non-negative Borel measurable function
$f$
on
$(\mathscr{M}_1 \times \mathscr{E}, \mathscr{B}(\mathscr{M}_1\times \mathscr{E}\kern1.6pt))$
, -
(2) the function
is Borel measurable,
\begin{equation*} y \mapsto \int _{\mathscr{M}_1\times \mathscr{E}} f(x,e) \, d\mu ^y(x,e), \quad \text{with}\ y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}},\end{equation*}
-
(3) and
\begin{equation*} \int _{\mathscr{M}_1\times \mathscr{E}} f(x,e) \, d \mu (x,e) = \int _{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \Bigg (\int _{F^{-1}(y)} f(x,e) \, d \mu ^y(x,e) \Bigg )\ d(F_*\mu )(y). \end{equation*}


Remark. Example of a disintegration along a projection. Let
 $\mu$
be Lebesgue measure on
 $\mathbb{R}^2$
and let
 $\pi _1(x,y)=x$
be the projection onto the first coordinate. Then,
 $\mu$
admits a disintegration with respect to
 $\pi _1$
given by the family of measures
 $\{\mu ^x\}_{x \in \mathbb{R}}$
, where
 $\mu ^x$
is Lebesgue measure on the fibre
 $\{x\} \times \mathbb{R}$
. In this case, the disintegration formula
 \begin{equation*} \int _{\mathbb{R}^2} f(x,y)\, d\mu (x,y) = \int _{\mathbb{R}} \left ( \int _{\mathbb{R}} f(x,y)\, d\mu ^x(y) \right ) d\pi _{1*}\mu (x,y) \end{equation*}
for a non-negative, measurable and integrable function
 $f$
is the Fubini-Tonelli’s theorem (see [Reference Folland55
, Theorem 2.37]).
Note that while we assume that
 $\mu$
is a finite measure (and not necessarily a probability measure), the definition above requires that
 $\mu ^{y}$
’s are probability measures. In Section 7.1, we show that a disintegration of
 $\mu$
always exists and that it is essentially unique in our setting given Assumption4, stated below.
Assumption 4.
We assume that
 $\mathscr{M}_1$
is compact, and we assume that
 $\mathscr{E}$
is a Borel set.
Note that Assumption4 implies Assumption2, which will therefore be omitted from now on. Additionally, since
 $\mathscr{M}_1 \times \mathscr{E}$
is a Borel subset of
 $\mathscr{X} \times \mathscr{Z}$
, the Borel
 $\sigma$
-algebra
 $\mathscr{B}(\mathscr{M}_1\times \mathscr{E}\kern1.6pt)$
, that is induced by the subspace topology on
 $\mathscr{M}_1 \times \mathscr{E}$
, coincides with the trace
 $\sigma$
-algebra
 $\mathscr{B}(\mathscr{X}\times \mathscr{Z}\kern1.7pt)_{|\mathscr{M}_1\times \mathscr{E}} =\{ B \cap (\mathscr{M}_1 \times \mathscr{E}\kern1.6pt) \,:\, B \in \mathscr{B}(\mathscr{X} \times \mathscr{Z}\kern1.7pt) \},$
see e.g., [Reference Bogachev27, Section 1.1].
Remark.
As an example for an inverse problem as in (5) satisfying the Assumptions
2
and
4
, we consider a linear forward model with additive noise
 $F(x,e)=Ax+e$
for
 $x \in \mathscr{M}_1 \subset \mathscr{X}= \mathbb{C}^N$
and
 $e \in \mathscr{E} \subset \mathscr{Z}= \mathbb{C}^m$
with
 $m,N \in \mathbb{N}$
and
 $A \in \mathbb{C}^{m\times N}$
. For many relevant applications the linear map
 $A \in \mathbb{C}^{m\times N}$
has a non-trivial null space
 $\mathscr{N}\kern1pt(A)\,:\!=\,\{x \in \mathbb{C}^N\,:\, Ax=0\} \neq \{0\}$
or is ill-conditioned. The linear map typically has a non-trivial null space for undersampled inverse problems. In the case that
 $A$
is ill-conditioned, numerically the condition
 $\mathscr{N}\kern1pt(A) \neq \{0\}$
can in principle be approximated by setting the singular values around or below machine precision to zero, which results in
 $\mathscr{N}\kern1pt(A) \neq \{0\}$
. If the null space is non-trivial, the feasible sets
 $F_y$
can be non-empty. As a subset of the bounded set
 $\mathscr{M}_1$
, the feasible sets are bounded, and by the Heine-Borel property of
 $d_{\mathscr{X}}$
, in Assumption
1
, are also compact. In this case, the feasible sets satisfy Assumption
2
. Thus, the kernel size with worst-case noise can be non-zero. Assumption
4
is likely to be satisfied in applications. The condition that data sets or model classes,
 $\mathscr{M}_1 \subseteq \mathbb{C}^N$
, are bounded, ensures that the set of admissible signals remains within physically or numerically reasonable limits. Additionally, if
 $\mathscr{M}_1$
is considered to be data, it can be assumed to be closed, since they include boundary points as part of the domain. Thus, it is natural to treat
 $\mathscr{M}_1$
as closed, since excluding boundary points would not align with how physical data is collected or interpreted. Finally, many applications involve quantities that vary continuously (or piecewise continuously) with respect to their underlying parameters. This continuity can imply that boundary points do not represent any abrupt change in the physical state and in such cases can be seamlessly included in
 $\mathscr{M}_1$
. This supports modelling
 $\mathscr{M}_1$
as a closed set, as no artificial exclusion of boundary points is required. Hence, assuming that
 $\mathscr{M}_1$
is closed and bounded is consistent with typical modelling assumptions. By the Heine-Borel property of
 $d_{\mathscr{X}}$
, from Assumption
1
, the set
 $\mathscr{M}_1$
is compact, as it is closed and bounded, satisfying Assumption
4
. In probabilistic settings, the set of noise vectors
 $\mathscr{E}$
is assumed to be Borel measurable, satisfying Assumption
4
.
Next, let
 \begin{equation*} r_\varphi \,:\, \mathscr{M}_1 \times \mathscr{E} \to [0,+\infty ], \quad r_\varphi (x,e) = d_{\kern-1pt \mathscr{X}}^H(x,\varphi (F(x,e))) \end{equation*}
denote the residual map of a given reconstruction mapping
 $\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
and let
 \begin{equation} \mathscr{C}\,:\!=\, \{\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}\,:\, r_\varphi \text{ is Borel measurable}\}. \end{equation}
denote the set of all reconstruction mappings with a Borel measurable residual map. For
 $p \in [1,\infty ]$
and a given reconstruction map
 $\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
, we denote its
 $p$
th order error by
 \begin{equation} \mathrm{Err}^{\mathrm{a}}(\varphi ,p) = \begin{cases} \big(\!\int _{\mathscr{M}_1\times \mathscr{E}} d_{\kern-1pt \mathscr{X}}^H\big (x,\varphi (F(x,e))\big )^p \ d\mu (x,e) \big)^{\frac {1}{p}} &\text{for } 1\leq p \lt \infty \\ \operatorname {esssup}_{(x,e) \in \mathscr{M}_1\times \mathscr{E}} \ d_{\kern-1pt \mathscr{X}}^H(x, \varphi (F(x,e))) &\text{for } p=\infty \end{cases} \end{equation}
where the essential supremum for
 $p=\infty$
is taken with respect to the measure
 $\mu$
. Concretely, for
 $p\in [1,\infty ]$
, this quantity is the
 $L^p(\mathscr{M}_1\times \mathscr{E}, \mu )$
norm of the residual function
 $r_\varphi$
.
This definition of reconstruction error generalises the usual
 $L^p$
-norms to include a set-valued mapping and a metric
 $d_{\mathscr{X}}$
that is not necessarily induced by a norm in the single-valued case. However, the proposed setup includes many standard expectations as special cases. Indeed, let
 $\varphi$
be a single-valued map and let
 $d_{\mathscr{X}}$
be given by an
 $\ell ^q$
norm. Then, if we choose
 $p=q= 1$
, we recover the expected absolute error, whereas for
 $p=q=2$
, we find the expected root squared error. Moreover, for
 $p=\infty$
, the choice of metric
 $d_{\mathscr{X}}$
corresponds to the choice of the loss function in a machine learning setting [Reference Shalev-Shwartz and Ben-David96, Chapter 3] [Reference Foucart57, Chapter 1]. One can also view the case where
 $p=\infty$
as a weak form of worst-case error where all irregularities on sets of measure zero are ignored.
With the error term in (12) defined, we can now establish the notion of optimality constant with average error and kernel constant with average error.
Definition 4 (Optimality constant with average error). For
 $p \in [1,\infty ]$
, the optimality constant with average error of order
 $p$
for the inverse problem (5) is
 \begin{align} c_{\mathrm{opt}}^{\text{a}}(F,\mathscr{M}_1,\mathscr{E}, p) = \inf _{\varphi \in \mathscr{C}} \mathrm{Err}^{\mathrm{a}}(\varphi , p). \end{align}
A map
 $\varphi \in \mathscr{C}$
attaining the infimum in (13) for a given
 $p$
is called an optimal map with average error of order
 $p$
.
Definition 5 (Average kernel size). The average kernel size of the inverse problem (1) for
 $p \in [1,\infty )$
is given by
 \begin{align*} {\operatorname {kersize}}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p) &= \Bigg ( \int _{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \int _{F^{-1}(y)} \int _{F^{-1}(y)} d_{\mathscr{X}}(x,x')^p \, d\mu ^y(x,e) \ d\mu ^y(x',e') \ d(F_*\mu )(y) \Bigg )^{\frac {1}{p}}, \end{align*}
and for
 $p = \infty$
it is
 \begin{align} {\operatorname {kersize}}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, \infty ) &= \mathop{\mathrm{esssup}}\limits_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \mathop{\mathrm{esssup}}\limits_{\substack {(x,e) \in F^{-1}(y)\\ (x',e') \in F^{-1}(y)}} d_{\mathscr{X}}(x,x'), \end{align}
where the left and right essential suprema are taken with respect to
 $F_*\mu$
on
 $\mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
and
 $\mu ^y$
on
 $F^{-1}(y)$
, respectively.
Intuitively, the average kernel size measures the average distance between the
 $x$
-components of
 $(x,e), (x',e') \in \mathscr{M}_1\times \mathscr{E}$
that have the same measurement
 $F(x,e) = F(x',e')=y$
in the case of
 $p \in [1,\infty )$
, and the maximum of such distances (up to negligible sets) when
 $p = \infty$
.
Our main theorem in this section is stated below. It bounds the average optimality constant in terms of the average kernel size. It also ensures the existence of an optimal map, provides a variational expression for one such map and establishes some regularity properties of this mapping.
Theorem 3.2 (Average optimality bounds). Under Assumptions
1
,
3
,
4
, the following holds for every
 $p \in [1,\infty ]$
,
-
(1) We have that
\begin{equation*} \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p)/2 \leq c_{\mathrm{opt}}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p) \leq \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p). \end{equation*}
-
(2) Consider
$p \in [1,\infty )$
, and let
$\Psi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}}\rightrightarrows \mathscr{X}$
be given by
(15)Then we have the following:
\begin{align} \Psi (y) &= \mathop{\mathrm{argmin}}\limits_{z \in \mathscr{X}} \int _{F^{-1}(y)} d_{\mathscr{X}}(x,z)^p \ d\mu ^y(x,e). \end{align}
$\Psi$
has compact values, it is measurable, and it admits a measurable selector. Moreover,
$\Psi$
is an optimal map with average error of order
$p$
.
-
(3) Consider
$p = \infty$
, and let
$\Psi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}}\rightrightarrows \mathscr{X}$
be given by
(16)Then we have the following:
\begin{align} \Psi (y) &= \mathop{\mathrm{argmin}}\limits_{z \in \mathscr{X}}\mathop{\mathrm{esssup}}\limits_{(x,e) \in F^{-1}(y)} d_{\mathscr{X}}(x,z). \end{align}
$\Psi$
has compact values, it is measurable, and it admits a measurable selector. Moreover,
$\Psi$
is an optimal map with average error of order
$p$
.


Remark. Measurability of set-valued mappings. There exist several notions of measurability for set-valued mappings. The precise definition of the term used in the theorem above can be found in Definition
7
. A measurable selector from a set-valued mapping
 $\Phi \,:\, \mathscr{Y} \rightrightarrows \mathscr{X}$
between measurable spaces is a measurable function
 $\phi \,:\, \mathscr{Y} \rightarrow \mathscr{X}$
such that
 $\phi (y) \in \Phi (y)$
for all
 $y \in \mathscr{Y}$
, [Reference Aliprantis and Border6
,
 $\S$
. 18.3].
A key finding in Theorem3.2 is that the possibly set-valued
 $\Psi$
admits a measurable selector, i.e., a single-valued function
 $\psi \,:\,\mathscr{M}_2^{\kern0.5pt\mathscr{E}} \to \mathscr{X}$
which is Borel measurable and such that
 $\psi (y) \in \Psi (y)$
for every
 $y$
. Thus, Theorem3.2 not only provides fundamental limits for the reconstruction error of an inverse problem but also gives a (variational) expression for a mapping that is optimal. Moreover, such a reconstruction mapping satisfies some regularity properties, which one usually hopes for when solving an inverse problem. One can argue that measurability is still a weak condition, but in order to obtain stronger conditions (such as continuity of the reconstruction), one would need to impose stronger assumptions on the problem. Moreover, note that in the definition of the average optimality constant, all potentially set-valued maps are included. Hence, the bounds also hold for any measurable single-valued selector.
4. Examples
In this section, we present three examples from research areas in inverse problems and briefly illustrate their connection to the framework developed in this paper. Additionally, we provide examples where the upper and lower bounds in Theorem3.1
 $(i)$
and the upper bound in Theorem3.2
 $(i)$
are attained and, hence, show that the bounds are sharp.
Example 1. Linear inverse problems with the robust null-space property
The robust null space property from compressed sensing was first introduced as a necessary condition for uniform recovery of sparse vectors from linear measurements. See [Reference Foucart and Rauhut56] for a historical overview. Later it has been extended to a wide range of model classes
 $\mathscr{M}_1$
, including low-rank [Reference Kabanava, Kueng, Rauhut and Terstiege70] and sparsity in levels [Reference Bastounis and Hansen18] models. A very general version of the property appears in [Reference Bourrier, Davies, Peleg, Pérez and Gribonval31], which considers general sets
 $\mathscr{M}_1$
. We now recall a specialised version of the property from [Reference Bourrier, Davies, Peleg, Pérez and Gribonval31], and then we relate this to kernel size with worst-case noise.
Let
 $\mathscr{X}, \mathscr{Y}$
and
 $\mathscr{Z}$
be vector spaces, with
 $\mathscr{Y}=\mathscr{Z}$
, and let
 $A\colon \mathscr{X} \to \mathscr{Y}$
be a linear mapping that is onto
 $\mathscr{Y}$
. We consider the additive linear model
 $F(x,e) =Ax+e$
for
 $(x,e) \in \mathscr{M}_1\times \mathscr{E} \subset \mathscr{X}\times \mathscr{Z}$
. Let
 ${\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert \cdot \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{X}_1}$
and
 ${\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert \cdot \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{X}_2}$
be norms on
 $\mathscr{X}$
, and let
 ${\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert \cdot \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{Y}}$
be a norm on
 $\mathscr{Y}$
(slightly weaker conditions are used in [Reference Bourrier, Davies, Peleg, Pérez and Gribonval31]). Furthermore, for the model class
 $\mathscr{M}_1 \subset \mathscr{X}$
, we denote the set
 $\mathscr{M}_1-\mathscr{M}_1\,:\!=\,\{x-x' \,:\, x,x'\in \mathscr{M}_1\}$
, and let
 $\mathrm{dist}_{\mathscr{X}_2}(h,\mathscr{M}_1-\mathscr{M}_1)=\inf _{z \in \mathscr{M}_1-\mathscr{M}_1} {\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert z-h \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{X}_2}$
. Then, the linear mapping
 $A$
is said to satisfy the robust null-space property (rNSP) with constants
 $D_1, D_2 \gt 0$
with respect to the set
 $\mathscr{M}_1$
, if
 \begin{equation} {\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert h \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{X}_1} \leq D_1 \mathrm{dist}_{\mathscr{X}_2}(h, \mathscr{M}_1-\mathscr{M}_1) + D_2 {\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert A(h) \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{Y}} \quad \text{for all } h \in \mathscr{X}. \end{equation}
In Proposition 4.1, we assume that Assumption4 holds, i.e., that
 $\mathscr{M}_1$
is compact. For linear inverse problems, this assumption is often used on the noise level, whereas the set
 $\mathscr{M}_1$
is often an unbounded set (sparse vectors, matrices with low rank, etc.). However, when modelling any practical application, it is not unreasonable to assume that the set of interest is compact or closed and bounded. Now under the assumption that the noise is bounded by
 $\mathrm{diam}_{d_{\mathscr{Y}}}(\mathscr{E}\kern1.6pt) = \sup _{e,e' \in \mathscr{E}}{\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert e-e' \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{Y}} = \eta$
in Proposition 4.1, we show that the kernel size with worst-case noise, with respect to the metrics induced by
 ${\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert \cdot \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{X}_1}$
and
 ${\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert \cdot \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{Y}}$
, is bounded by
 \begin{equation} \mathrm{kersize}^{\mathrm{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt) \leq D_2\eta . \end{equation}
In this sense, Proposition 4.1 provides a relation between the rNSP and the kernel size with worst-case noise.
Proposition 4.1.
Let
 $\eta \geq 0$
. Let
 $\mathscr{X}, \mathscr{Y}$
be normed vector spaces with norms
 ${\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert \cdot \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{X}_1}$
and
 ${\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert \cdot \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{X}_2}$
on
 $\mathscr{X}$
, and
 ${\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert \cdot \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{Y}}$
on
 $\mathscr{Y}$
. Let
 $\mathscr{M}_1 \subseteq \mathscr{X}$
satisfy Assumption
4
, and let
 $\mathscr{E} \subset \mathscr{Y}$
with
 $\mathrm{diam}_{d_{\mathscr{Y}}}(\mathscr{E}\kern1.6pt) = \eta$
. Let
 $F(x,e) =Ax+e$
for
 $(x,e) \in \mathscr{M}_1\times \mathscr{E}$
, where
 $A\colon \mathscr{X} \to \mathscr{Y}$
is a linear map onto
 $\mathscr{Y}$
and that satisfies the rNSP with constants
 $D_1, D_2 \geq 0$
with respect to
 $\mathscr{M}_1$
. Then, the following holds:
-
(1)
$A$
is injective on
$\mathscr{M}_1$
, and this is equivalent to
where
\begin{align*} (\mathscr{M}_1 - \mathscr{M}_1) \cap \mathscr{N}\kern1pt(A) = \{0\}, \end{align*}
$\mathscr{N}\kern1pt(A) =\{x \in \mathscr{X}\,:\, Ax=0\}$
.
-
(2) The kernel size with worst-case noise can be bounded from above as
\begin{align*} \operatorname {kersize}^{\text{w}}(F, \mathscr{M}_1, \mathscr{E}\kern1.6pt) \leq D_2 \eta . \end{align*}


Note that if we take
 $\eta =0$
, i.e., a noiseless forward model
 $\mathscr{E} = \{0\}$
, we have that
 $\mathrm{kersize}^{\mathrm{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt) = 0$
.
Example 2. Optimal learning, Chebyshev centres and Gelfand widths
Recently, the notion of optimal learning was introduced in [Reference Binev, Bonito, DeVore and Petrova25]. Herein, one considers the setting in which the set
 $\mathscr{X}$
is a Banach space with norm
 $\|\cdot \|_{\mathscr{X}}$
and
 $\mathscr{M}_1$
is a compact subset of
 $\mathscr{X}$
. To sample an element
 $x \in \mathscr{M}_1$
, one uses
 $m$
linear functionals
 $\lambda _1,\ldots , \lambda _m \in \mathscr{X}^*$
from the dual space of
 $\mathscr{X}$
. Now, for a given
 $x \in \mathscr{M}_1$
, let
 $y = (\lambda _1(x), \ldots , \lambda _m(x)) \in {\mathbb{C}}^m$
and let
 \begin{equation*}K_{y} = \{x \in \mathscr{M}_1 \,:\, \lambda _i(x)= y_i , i \in \{1,\ldots ,m\}\}\end{equation*}
denote the set of solutions which are data-consistent. The above measurement model is noiseless, so define for convenience
 $\mathscr{M}_2 = \{y=(\lambda _1(x),\ldots ,\lambda _m (x)) \,:\, x \in \mathscr{M}_1\}$
as the set of noiseless measurements.
Now, let
 $B_{\mathscr{X}}(z,r)$
denote the closed ball in
 $\mathscr{X}$
with centre
 $z$
and radius
 $r$
. For a compact set
 $\mathscr{S} \subset \mathscr{X}$
, the Chebyshev radius of
 $\mathscr{S}$
is given by
 \begin{equation*} R_{\mathscr{X}}(\mathscr{S}\kern1.8pt) \,:\!=\, \inf \{r\gt 0 \,:\, \mathscr{S}\subset B_{\mathscr{X}}(z,r) \text{ for some }z\in \mathscr{X}\}. \end{equation*}
In [Reference Binev, Bonito, DeVore and Petrova25], the quantity
 $R_{\mathscr{X}}(K_{y})$
is defined as the optimal recovery rate for a given
 $x \in \mathscr{M}_1$
, with
 $y=(\lambda _1(x),\ldots ,\lambda _m(x))$
. This quantity is zero if
 $K_{y}$
is a singleton; however, here, we follow [Reference Binev, Bonito, DeVore and Petrova25] and focus on the cases for which
 $R_{\mathscr{X}}(K_{y}) \gt 0$
.
While the framework developed in this paper does not extend to general Banach spaces, it does cover the special case of
 $\mathscr{X}={\mathbb{C}}^N$
with the metric induced by a norm
 $\|\cdot \|_{\mathscr{X}}$
. Indeed, by letting
 $A \in {\mathbb{C}}^{m\times N}$
be the matrix given by the linear functionals
 $\lambda _i$
, taking
 $\mathscr{E} =\{0\}$
and using the linear additive model
 $F(x,e) = Ax+e$
, as
 $K_y = F_y$
, it is straightforward to see that
 $R_{\mathscr{X}}(K_y) = \tfrac {1}{2}\mathrm{diam}_{\mathscr{X}}(F_y)$
, since the minimal enclosing ball of a bounded set has radius equal to half its diameter when centred at a Chebyshev centre. By taking the supremum over all
 $y \in \mathscr{M}_2$
, we obtain of
 $\sup _{y\in \mathscr{M}_2} 2R_{\mathscr{X}}(K_y) = \sup _{y\in \mathscr{M}_2} \mathrm{diam}_{\mathscr{X}}(F_y)$
, which coincides with the kernel size with worst-case noise, as characterised in (8). To further analyse the noisy setting, we refer to [Reference Binev, Bonito, DeVore and Petrova25].
The framework proposed in this work is closely related to the concept of Chebyshev centres. In fact, the optimal maps
 $\Psi$
defined in (10) and (15) correspond to the problem of finding the Chebyshev centre or the
 $p$
-centre (see [Reference Novak and Ritter87]) of the set
 $F_y$
of candidate solutions. The setting proposed in this paper guarantees that such centres exist so that the optimal maps are well-defined; however, Chebyshev centres may not exist in general, and other sufficient and necessary conditions for their existence can be found in the literature (see [Reference Amir, Mach and Saatkamp8], [Reference Amir and Mach7], [Reference Ward109], [Reference Rao93]).
In this work, we have kept the forward model
 $F$
fixed. However, in the special case of a linear forward model, it is reasonable to also consider the question of how well we can perform given a fixed budget of
 $m$
linear functionals. This question is well studied in the literature [Reference Pinkus89] and is given by the Gelfand width of
 $\mathscr{M}_1$
,
 \begin{equation*} w^m(\mathscr{M}_1)\,:\!=\, \inf _{A\in {\mathbb{C}}^{m\times N}} \sup _{x\in \mathscr{M}_1}R_{\mathscr{X}}(K_{Ax}). \end{equation*}
We note that this presents a lower bound for
 $c_{\mathrm{opt}}^{\mathrm{w}}(A, \mathscr{M}_1, \{0\})$
in the noiseless setting. We do not consider the question of what the optimal forward model would be any further in this work but remark that it is an interesting question worth investigating.
Example 3. Bayesian inverse problems
Bayesian inverse problems [Reference Arridge, Maass, Öktem and Schönlieb12, Reference Stuart101] take a probabilistic approach. Instead of using a measurement
 $y$
to output a single candidate solution
 $x$
, the goal of a Bayesian approach is to use a measurement
 $y$
to output a distribution on the possible solutions
 $x$
’s.
The following proposition of Theorem3.2 demonstrates how Bayesian inverse problems can be related to the framework presented in this work. The proposition shows that the posterior mean estimator is an optimal map in the average case for
 $p=2$
and for metrics
 $d_{\mathscr{X}}$
that are induced by an inner product.
Proposition 4.2 (Bayesian problems in the current framework). Let
 $(\Omega , \mathscr{F}, \mathbb{P})$
be a probability space. Let
 $(\mathscr{X},d_{\mathscr{X}}), (\mathscr{Y},d_{\mathscr{Y}}), (\mathscr{Z}, d_{\mathscr{Z}})$
and
 $\mathscr{M}_1, \mathscr{E}$
,
 $F \,:\, (\mathscr{X} \times \mathscr{E}, \mathscr{B}(\mathscr{X} \times \mathscr{E}\kern1.6pt)) \to (\mathscr{M}_2^{\kern0.5pt\mathscr{E}}, \mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}}))$
and
 \begin{equation*} (\mathbf{x},\mathbf{e}) \,:\, (\Omega , \mathscr{F}, \mathbb{P}) \to (\mathscr{X} \times \mathscr{E}, \mathscr{B}(\mathscr{X} \times \mathscr{E}\kern1.6pt)) \end{equation*}
be a random variable with (joint) distribution
 $\mu \,:\!=\, \mu _{\mathbf{x},\mathbf{e}} = \mathbb{P}[(\mathbf{x},\mathbf{e}) \in \cdot ]$
satisfying Assumptions
1
,
3
and
4
. Let
 $(\mathscr{Y},d_{\mathscr{Y}})$
be a Polish space. Define the random variable
 $\mathbf{y} \,:\!=\, F(\mathbf{x},\mathbf{e}) = F \circ (\mathbf{x},\mathbf{e})$
whose law is given by
 $\mu _{\mathbf{y}} = F_* \mu = \mathbb{P}[\mathbf{y} \in \cdot ]$
. Denoting by
 $\pi _1 \,:\, \mathscr{X} \times \mathscr{E} \to \mathscr{X}$
the coordinate projection, the following holds:
-
(1) The Bayesian prior distribution of
$\mathbf{x}$
is the distribution of
$\mathbf{x}$
and can be obtained as
$\mu _{\mathbf{x}} = \pi _{1*} \mu$
; -
(2) There exist likelihood distributions
$\{\mu _{\mathbf{y} \mid \mathbf{x} = x}\}_{x \in \mathscr{X}}$
of
$\mathbf{y}$
given
$\mathbf{x}$
; -
(3) The Bayesian posterior distributions
$\{\mu _{\mathbf{x} \mid \mathbf{y} = y}\}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
can be obtained by the pushforward with respect to
$\pi _1$
of the disintegration
$\{\mu ^y\}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
of
$\mu$
along
$F$
as:
$\mu _{\mathbf{x} \mid \mathbf{y} = y} = \pi _{1*} \mu ^y$
; -
(4) If the metric
$d_{\mathscr{X}}$
is replaced with a metric induced by an inner product
$\langle \cdot , \cdot \rangle$
and
$p = 2$
, then the optimal map
$\Psi$
from Theorem
3.2
part (ii) coincides with the posterior mean and
$\Psi (y) = \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}]$
for every
$y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
.


As Proposition 4.2 is intended only to be a brief example, the relevant definitions and its proof are presented in Section 7. This result illustrates how the framework introduced in this chapter is capable of capturing not only inverse problems in their classical sense but also in the Bayesian approach.
Example 4. The kernel sizes are sharp bounds to the optimality constants
In the following, we provide two examples that show that the upper and lower worst-case bounds in Theorem3.1
 $(i)$
can be attained and, hence, are sharp. Then, we provide another example showing that the upper bound is attained in Theorem3.2
 $(i)$
and, hence, is also sharp. We first provide two simple examples that obtain the upper and lower worst-case bounds in Theorem3.1
 $(i)$
. In the following, for fixed
 $n \in \mathbb{N}$
,
 $\{e_1, \ldots , e_n\}$
denotes the canonical basis of
 $\mathbb{R}^n$
.
-
(1) Sharpness of the lower bound in Theorem3.1
$(i)$
: Let
$(\mathscr{X}, d_{\mathscr{X}}) = (\mathbb{R}^2, \|\cdot \|_2)$
,
$(\mathscr{Y}, d_{\mathscr{Y}}) = (\mathscr{E}, d_{\mathscr{E}}) = (\mathbb{R}, |\cdot |)$
,
$\mathscr{M}_1 = \{-e_1, e_1\}$
,
$\mathscr{E} = \{0\}$
and
$F \,:\, \mathbb{R}^2 \times \mathbb{R} \rightarrow \mathbb{R}$
with
$F((x_1, x_2), e) = x_2$
, so that
$\mathscr{M}_2^{\kern0.5pt\mathscr{E}} = \{0\}$
. Then, as
$F^{-1}(0) = \mathscr{M}_1$
, we have thatas the optimal map with worst-case noise is given by
\begin{align*} \operatorname {kersize}^{\text{w}}(F, \mathscr{M}_1, \mathscr{E}\kern1.6pt) = \|e_1-({-}e_1)\|_2=2, \quad c_{\mathrm{opt}}^{\text{w}}(F, \mathscr{M}_1, \mathscr{E}\kern1.6pt) = 1, \end{align*}
$\Psi (0) = \operatorname {argmin}_{z \in \mathbb{R}^2} \sup _{x \in \mathscr{M}_1} \|z-x\|_2 = 0$
.
-
(2) Sharpness of the upper bound in Theorem3.1
$(i)$
: Consider the same setup as above, but replace
$\mathscr{X}$
with
$(\mathscr{X}, d_{\mathscr{X}}) = (\mathscr{M}_1, \|\cdot \|_2)$
and as
$\mathscr{M}_1 \subset \mathbb{R}^2$
restrict
$F$
by
$F : \mathscr{M}_1 \times \mathbb{R} \rightarrow \mathbb{R}$
with
$F((x_1, x_2), e) = x_2$
. Then, we have thatas the optimal maps with
\begin{align*} \operatorname {kersize}^{\text{w}}(F, \mathscr{M}_1, \mathscr{E}\kern1.6pt) = 2 = c_{\mathrm{opt}}^{\text{w}}(F, \mathscr{M}_1, \mathscr{E}\kern1.6pt), \end{align*}
$\Psi _i(0) = \operatorname {argmin}_{z \in \mathscr{M}_1} \sup _{x \in \mathscr{M}_1} \|z-x\|_2$
are given by
$\Psi _i\,:\, \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightarrow \mathscr{M}_1$
for
$i = 1,2,3$
, where
$\Psi _1(0) = e_1$
,
$\Psi _2(0) = -e_1$
and
$\Psi _3(0) = \{-e_1, e_1\}$
.


For the average case by providing examples attaining the bounds, we can also show that the upper bound in Theorem3.2
 $(i)$
is sharp. Consider the same setup as in part
 $(1)$
above. Let
 $\alpha \in [0,1]$
be an arbitrary parameter and equip
 $\mathbb{R}^2 \times \mathscr{E}$
with the measure
 $\mu = \mu _\alpha$
given by
 $\mu _\alpha = \bigl (\alpha \delta _{-e_1} + (1-\alpha )\delta _{e_1}\bigr ) \otimes \delta _0$
, which is supported on
 $\mathscr{M}_1 \times \mathscr{E} = \{-e_1, e_1\} \times \{0\}$
. For
 $p = 1$
and as
 $F^{-1}(0) = \mathscr{M}_1$
, we have that the average kernel size is
 \begin{align*} \operatorname {kersize}^{\text{a}}(F, \mathscr{M}_1, \mathscr{E}, 1) = \alpha ^2 \cdot 0 + 2 \alpha (1-\alpha ) 2 + (1-\alpha )^2 \cdot 0 = 4\alpha (1-\alpha ), \end{align*}
and the optimality constant and the optimal map with average error
 $\Psi \,:\, \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathbb{R}^2$
, obtained by Theorem3.2
 $(ii)$
as
 $\Psi (0) = \operatorname {argmin}_{z \in \mathbb{R}^2} \left (\alpha \|z+e_1\|_2+(1-\alpha ) \|z-e_1\|_2\right )$
, are
 \begin{align*} c_{\mathrm{opt}}^{\text{a}}(F, \mathscr{M}_1, \mathscr{E}, 1) = \begin{cases} 2\alpha , & \text{if } \alpha \in [0, \tfrac {1}{2}), \\ 1, & \text{if } \alpha = \tfrac {1}{2}, \\ 2(1-\alpha ), & \text{if } \alpha \in (\tfrac {1}{2}, 1], \end{cases} \quad \text{ and, } \Psi (0) = \begin{cases} e_1, & \text{if } \alpha \in [0, \tfrac {1}{2}), \\ \{(t,0)\,:\, t \in [-1,1]\}, & \text{if } \alpha = \tfrac {1}{2}, \\ -e_1, & \text{if } \alpha \in (\tfrac {1}{2}, 1]. \end{cases} \end{align*}
For
 $\alpha = \tfrac {1}{2}$
, any single-valued selector
 $\psi \,:\, \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightarrow \mathbb{R}^2$
of
 $\Psi$
is an optimal map. For
 $\alpha = \tfrac {1}{2}$
the upper bound in Theorem3.2
 $(i)$
is attained, as
 $c_{\mathrm{opt}}^{\text{a}}(F, \mathscr{M}_1, \mathscr{E}, 1)=\operatorname {kersize}^{\text{a}}(F, \mathscr{M}_1, \mathscr{E}, 1)=1$
.
5. Relation to previous work
As an ongoing topic of research in many areas of mathematics, undersampled and ill-posed inverse problems have been studied in many different areas. As a non-extensive list of examples, they have been studied from a theoretical standpoint [Reference Engl and Groetsch49], from a statistical perspective [Reference O’Sullivan88], by using iterative deep neural networks [Reference Adler and Öktem5] and in applied fields, such as radio tomography of the ionosphere [Reference Garcia and Crespon59]. For solving undetermined and ill-posed inverse problems, often regularisation methods are utilised – here M. Benning et al. give a comprehensive review of modern methods [Reference Benning and Burger22]. Different noise models have been studied, and while an assumption of additive noise appears ubiquitously [Reference Bertero, Boccacci and De Mol23, Reference Hofinger and Pikkarainen67, Reference Kaipio, Kolehmainen, Vauhkonen and Somersalo71], often multiplicative noise models can be relevant in applications [Reference Aubert and Aujol13, Reference Huang, Ng and Wen68, Reference Shi and Osher98, Reference Zhao, Wang and Ng111]. The authors of [Reference Scarlett, Heckel, Rodrigues, Hand and Eldar94] note that an open challenge in this research field is optimisation guarantees with milder assumptions, which are provided in this work. To the best of the authors’ knowledge, fundamental accuracy bounds for undersampled and ill-posed inverse problems with multiplicative noise have not been produced. Moreover, despite the existing extensive amount of research, there is little to be found on fundamental accuracy bounds of approximate set-valued solutions to undersampled and ill-posed inverse problems.
Undersampled inverse problems and AI hallucinations: In [Reference Gottschling, Antun, Hansen and Adcock62], we provide sufficient conditions for AI hallucinations to occur due to a non-trivial kernel of the forward operator. For example, instabilities, such as false positives, false negatives, and especially AI hallucinations, have been an issue in the fastMRI challenge [Reference Muckley, Riemenschneider, Radmanesh, Kim, Jeong, Ko, Jun, Shin, Hwang, Mostapha and Arberet85] and in microscopy [Reference Belthangady and Royer19, Reference Hoffman, Slavitt and Fitzpatrick66]. In [Reference Burger and Roith33], M. Burger and T. Roith outline that fundamental performance and accuracy limits for data-driven approaches, such as deep learning, for solving ill-posed inverse problems do not exist. Moreover, they outline that the lack of such meaningful error estimates in the context of medical imaging and undetermined inverse problems is demonstrated using AI hallucinations in recent studies [Reference Antun, Renna, Poon, Adcock and Hansen10, Reference Bhadra, Kelkar, Brooks and Anastasio24, Reference Gottschling, Antun, Hansen and Adcock62]. In this work, we provide the missing link between a non-trivial kernel and optimal recovery.
(Set-valued) Decoders arising in deep learning: In the work [Reference Daubechies, DeVore, Foucart, Hanin and Petrova46], the ability of deep neural networks to nonlinearly approximate functions, and thus also decoders, is investigated. A range of results on how the resulting decoder may be constituted is presented by M. Unser in [Reference Unser106]. From an application-based perspective, a detailed overview of deep learning in inverse problems and stability of robustness for deep learning is given in [Reference Arridge, Maass, Öktem and Schönlieb12, Reference Lucas, Iliadis, Molina and Katsaggelos80, Reference McCann, Jin and Unser82]. Compared to standard methods for solving inverse problems, partially data-driven approaches, such as from L. Borcea, J. Garnier et al. [Reference Borcea, Garnier, Mamonov and Zimmerling28], and fully data-driven approaches using deep learning, such as [Reference Belthangady and Royer19, Reference Strack100, Reference Zhu, Liu, Cauley, Rosen and Rosen112], have reported superior accuracy. This can potentially lead to instabilities, which is highlighted by V. Antun et al. in [Reference Antun, Renna, Poon, Adcock and Hansen10] and in [Reference Gottschling, Antun, Hansen and Adcock62]. In fact, a variety of research has established that artificial intelligence techniques based on deep learning are unstable, firstly in image classification [Reference Eykholt, Evtimov, Fernandes, Li, Rahmati, Xiao, Prakash, Kohno and Song51, Reference Kurakin, Goodfellow and Bengio74, Reference Moosavi-Dezfooli, Fawzi and Frossard84, Reference Nguyen, Yosinski and Clune86, Reference Szegedy, Zaremba, Sutskever, Bruna, Erhan, Goodfellow and Fergus102], and later in applications ranging from audio and speech recognition [Reference Carlini and Wagner38, Reference Carlini, Mishra, Vaidya, Zhang, Sherr, Shields, Wagner and Zhou39, Reference Zhang, Yan, Ji, Zhang, Zhang and Xu110] to natural language processing [Reference Liang, Li, Su, Bian, Li and Shi78] and automatic diagnosis in medicine [Reference Finlayson, Bowers, Ito, Zittrain, Beam and Kohane54]. Moreover, many DL-based approaches implicitly include set-valued functions, where examples include, but are not limited to, deep ensembles [Reference Lakshminarayanan, Pritzel and Blundell75] or model-based probabilistic conditional diffusion models as in [Reference Liu, Anirudh, Thiagarajan, He, Mohan, Kamilov and Kim79]. In fact, any probabilistic DL model used to solve an inverse problem that uses sampling from a distribution or predicts parameters of a distribution – see the work of J. Gawlikowski [Reference Gawlikowski, Tassi, Ali, Lee, Humt, Feng, Kruspe, Triebel, Jung, Roscher, Shahzad, Yang, Bamler and Zhu60] for an introduction on uncertainty quantification and probabilistic DL models – can be considered to be a set-valued decoder.
Optimal (set-valued) decoders for undersampled inverse problems: The study of optimal and near-optimal recovery in inverse problems has always been a central question, and many single-valued near-optimal mappings have been proposed and analysed [Reference Binev, Bonito, DeVore and Petrova25, Reference Bourrier, Davies, Peleg, Pérez and Gribonval31, Reference Foucart and Rauhut56, Reference Plaskota90, Reference Traonmilin and Gribonval104]. A survey of early works on optimal recovery is given in [Reference Micchelli and Rivlin83]. For Compressed Sensing (CS) C. Poon provides sampling conditions and error bounds for near-optimal recovery in [Reference Poon91]. The case of set-valued optimal decoders has been considered for obtaining the worst-case bounds on Banach spaces in [Reference Arestov11] and extended to metric spaces in [Reference Magaril-Il’yaev and Osipenko81]. As presented in Example 3, the Bayesian approach to inverse problems aims at recovering a distribution-valued decoder [Reference Arridge, Maass, Öktem and Schönlieb12, Reference Stuart101]. Here, there exist a posteriori accuracy bounds in the case of normed spaces [Reference Leonov76, Reference Leonov77, Reference Wang, Leonov, Lukyanenko and Yagola107].
Accuracy bounds in approximation theory: Approximation theory aims to provide accuracy bounds and theoretical guarantees for function approximation tasks under specific assumptions. However, in [Reference Adcock and Dexter3], B. Adcock and N. Dexter state that despite the ability of deep neural networks to approximate functions relevant to scientific computing, a large gap between expressivity and practical performance remains. An in-depth treatment of sparse polynomial approximations of high-dimensional functions is given by B. Adcock, S. Brugiapaglia and C. Webster in [Reference Adcock, Brugiapaglia and Webster2]. Fundamental accuracy bounds, the Gelfand Widths, have been established in [Reference Pinkus89] for the noiseless linear setting. A framework for obtaining the best
 $k$
-term approximation and corresponding accuracy bounds is established [Reference Cohen, Dahmen and DeVore41]. In [Reference Cohen, Devore, Petrova and Wojtaszczyk42], the authors propose a framework to measure the optimal performance for nonlinear methods of approximation. The notion of optimal learning in a noisy setting and upper worst-case accuracy bounds based on the Chebyshev radius are presented in [Reference Binev, Bonito, DeVore and Petrova25]. B. Adcock et al. [Reference Adcock, Hansen, Poon and Roman4] propose a framework for accuracy bounds extending the classical assumption of CS. Generalised instance optimality and the corresponding accuracy bounds have been presented in [Reference Bourrier, Davies, Peleg, Pérez and Gribonval31]. Related to the CS framework, the Restricted Isometry Property (RIP) is generalised in [Reference Traonmilin and Gribonval104], and the null space property is generalised in [Reference Tran and Webster103]. However, A. Bastounis et al. establish that the RIP is absent in real-world CS applications in [Reference Bastounis and Hansen18] and, hence, propose an extension thereof, the RIP in levels, in order to explain the success of the method. Related to our work, analogous worst-case and average error bounds for normed spaces and single-valued decoders are established in [Reference Plaskota90].
6. Discussion and outlook
A fundamental limitation of this work is that the optimal maps achieving the smallest worst-case and average error in (10), (15) and (16), respectively, are generally not analytically computable. Moreover, these optimal maps are defined via embedded optimisation problems. While, in principle, such problems could be approximated numerically, doing so may be computationally infeasible for inverse problems involving high-dimensional datasets. In the average-case setting, the optimal map admits a measurable selector; however, it remains open to determine conditions under which it also admits a continuous selector or a continuous approximation. This is closely related to identifying structural conditions under which the set-valued map
 $y \mapsto F_y$
is continuous (in an appropriate sense), which in turn depends on properties of the forward map
 $F$
, the model class
 $\mathscr{M}_1$
, the noise set
 $\mathscr{E}$
, and the underlying metrics. Another limitation is that the worst-case and average kernel sizes are not readily computable. Developing computable and provably convergent approximations to these quantities would enable quantitative accuracy guarantees in applications. In Section 4, we presented illustrative examples highlighting connections between this framework and other approaches to inverse problems. In particular, Proposition 4.2 shows that the optimal map in the average-case setting coincides with the posterior mean estimator in Bayesian inverse problems. A natural direction for future work is to investigate how other Bayesian estimators, such as the maximum a posteriori estimator, relate to the present framework. Finally, extending Proposition 4.1 to generalised rNSP conditions such as in [Reference Bourrier, Davies, Peleg, Pérez and Gribonval31] and identifying the corresponding optimal maps in compressed sensing remains an interesting direction.
The proposed theoretical framework for undetermined and ill-posed inverse problems can be seen as a generalisation of a variety of previous frameworks to set-valued decoders. Additionally, commonly used assumptions, such as the convexity of the set
 $\mathscr{M}_1$
and a linear forward operator
 $A$
and additive noise, as well as the condition
 $(\mathscr{M}_1-\mathscr{M}_1)\cap \mathscr{N}\kern1pt(A)=\{0\}$
, which is for example implied by the RIP, are extended or are shown to be unnecessary. Under general assumptions, our work provides relevant accuracy bounds for set- and single-valued decoders and a variational expression for optimal decoders. Due to the generality of the assumptions, these bounds provide a means to bridge the gap between theory and practice. The lower bounds can be used for assessing accuracy and performance of a wide range of models, including ensemble models, diffusion models and sampling-based approaches that have set-valued solutions. Moreover, based on our previous work [Reference Gottschling, Antun, Hansen and Adcock62], these bounds can be used in future research to mitigate AI hallucinations in DL-based reconstructions for ill-posed inverse problems.
7. Proofs
This section contains the proofs of our results and propositions required to prove these. Additionally, where necessary, we include and cite results from prior work that are used in our proofs.
7.1. Existence and uniqueness of a disintegration of a measure given Assumptions1, 3 and 4
In this section, we prove the following proposition, which ensures that our setting guarantees the existence of a disintegration of the measure
 $\mu$
.
Proposition 7.1.
Under Assumptions
1
,
3
and
4
, there exists a disintegration
 $\{\mu ^y\}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
of the measure
 $\mu$
along
 $F$
. Moreover, such disintegration is essentially unique: if
 $\{\tilde \mu ^y\}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
is another family satisfying
 $(i)-(iii)$
in Definition
3
, then
 $\tilde \mu ^y=\mu ^y$
for almost every
 $y$
.
The proof of Proposition 7.1 is a special case of what is found in [Reference Chang and Pollard40]. Before jumping to the proof, in this section, we start by recalling some well-known definitions for measures and stating the relevant theorems from [Reference Chang and Pollard40]. Let
 $(X,\mathscr{B}(X))$
be the Borel measurable space associated with the topological space
 $X$
. A measure
 $\mu$
on
 $(X,\mathscr{B}(X))$
is said to be a Radon measure (sometimes also called a regular measure [Reference Aliprantis and Border6]) if
-
(1)
$\mu (K)\lt +\infty$
for each compact
$K \in \mathscr{B}(X)$
, -
(2)
$\mu (B) = \inf \{\mu (V)\,:\, V \in \mathscr{B}(X), V \text{ open, and } B\subset V \}$
, for every
$B \in \mathscr{B}(X)$
(
$\mu$
is outer regular), and -
(3)
$\mu (B) = \sup \{\mu (K)\,:\, K \in \mathscr{B}(X), K \text{ compact, and } K\subset B \}$
, for every
$B \in \mathscr{B}(X)$
(
$\mu$
is tight).


Moreover, a measure
 $\mu$
is said to dominate a measure
 $\nu$
if
 $\mu (B) = 0$
implies
 $\nu (B)=0$
for every
 $B\in \mathscr{B}(X)$
. Suppose that
 $X$
can be covered by at most countably many Borel measurable sets
 $\{B_{i}\}_{i\in I}$
,
 $I\subset \mathbb{N}$
, and that
 $\mu (B_i) \lt \infty$
for each
 $i\in I$
. Then,
 $\mu$
is said to be a
 $\sigma$
-finite measure. In particular, every finite measure is
 $\sigma$
-finite. We also have the following results for finite measures that are used in the proof of Proposition 7.1.
Theorem 7.2 ([Reference Aliprantis and Border6, Theorem 12.7]). A finite measure on a Polish space (i.e., a complete separable metric space) is Radon.
In Definition3, one may replace the measure
 $F_*\mu$
with another measure
 $\rho$
, in which case
 $\{\mu ^y\}_y$
would be called a
 $(F,\rho )$
disintegration of
 $\mu$
. We refer the reader to [Reference Chang and Pollard40, Definition 1] for the detailed statement.
Theorem 7.3 ([Reference Chang and Pollard40, Theorem 1]). Let
 $\mu$
be a
 $\sigma$
-finite Radon measure on a metric space
 $X$
and let
 $F$
be a measurable map from
 $(X,\mathscr{B}(X))$
to the measurable space
 $(Y,\Sigma )$
. Let
 $\rho$
be a
 $\sigma$
-finite measure on
 $\Sigma$
that dominates the pushforward measure
 $F_*\mu$
. If
 $\Sigma$
is countably generated and contains all the singleton sets
 $\{y\}$
, then
 $\mu$
has a
 $(F,\rho )$
-disintegration. The
 $\mu ^y$
measures are uniquely determined up to an almost sure equivalence: if
 $\{\mu ^y_*\}$
is another
 $(F,\rho )$
-disintegration, then
 $\rho (\{y\in \mathscr{Y}\,:\, \mu ^y_*=\mu ^y\})=0$
.
Theorem 7.4 ([Reference Chang and Pollard40, Theorem 2 (iii)]). Let
 $\mu$
have a
 $(F,\rho )$
-disintegration
 $\{\mu ^y\}$
, with
 $\mu$
and
 $\rho$
each
 $\sigma$
-finite. Then, the measures
 $\{\mu ^y\}$
are probabilities for
 $\rho$
-almost all
 $y \in \mathscr{Y}$
if and only if
 $\rho = F_*\mu$
.
Proof of Proposition
7.1. Let
 $d\,:\!=\, \max \{d_{\mathscr{X}},d_{\mathscr{Z}}\}$
be one of the standard metrics on the product
 $\mathscr{X} \times \mathscr{Z}$
. The spaces
 $(\mathscr{X},d_{\mathscr{X}})$
and
 $(\mathscr{Z},d_{\mathscr{Z}})$
are separable, as they are second countable by Assumption 11, and complete by Assumption 12. Thus the product space
 $(\mathscr{X} \times \mathscr{Z}, d)$
is complete and separable, [Reference Steen, Seebach and Steen99] (pg. 26). Thus,
 $(\mathscr{X} \times \mathscr{Z}, d)$
is a Polish space. Since by Assumption3,
 $\mu$
is a finite measure on the Polish space
 $\mathscr{X}\times \mathscr{Z}$
, Theorem7.2 guarantees that
 $\mu$
is Radon. Moreover, since by Assumption3,
 $\mu$
is finite, it is in particular
 $\sigma$
-finite. Taking
 $\rho =F_*\mu$
, clearly
 $\rho$
dominates
 $F_*\mu$
trivially, as they are the same measure. By Assumption1
1,
 $(\mathscr{M}_2^{\kern0.5pt\mathscr{E}},d_{\mathscr{Y}})$
is second countable; hence, its topology is countably generated, and so is the corresponding Borel
 $\sigma$
-algebra
 $\mathscr{B}=\mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}})$
. Furthermore, since singletons
 $\{y\} \subseteq \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
are closed, the Borel
 $\sigma$
-algebra contains all singletons. Lastly, as the mapping
 $F$
is measurable by Assumption3 and as by Assumption4
 $\mathscr{M}_1 \times \mathscr{E}$
is a Borel subset of
 $\mathscr{X} \times \mathscr{Z}$
, we extend
 $F$
trivially to be a measurable function on
 $\mathscr{X} \times \mathscr{Z}$
, for instance by defining it to be constant outside
 $\mathscr{M}_1 \times \mathscr{E}$
. Thus, all the conditions of Theorem7.3 are satisfied. Hence, there exists a disintegration of the measure
 $\mu$
along
 $F$
. Such a disintegration is essentially unique in the sense of Theorem7.3. Finally, since
 $\mu$
and
 $\rho =F_*\mu$
are both finite and in particular
 $\sigma$
-finite, Theorem7.4 guarantees that
 $\rho =F_*\mu$
implies that the measures
 $\mu ^y$
are probability measures for
 $F_*\mu$
-almost every
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
.
7.2. Proof of Theorem3.1
Proof of Theorem
3.1. We begin with the proof of (ii). First, let us introduce some notation: for fixed
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
, define the function
 \begin{align*} f_y\colon \mathscr{X} \to [0,+\infty ), \quad f_y(z) = \sup _{x \in F_y} d_{\mathscr{X}}(x, z) = d_{\kern-1pt \mathscr{X}}^H(z, F_y) \end{align*}
and notice that
 $f_y$
appears in the definition of
 $\Psi$
in (10). Note that
 $f_y$
does not attain the value
 $+\infty$
, as by Assumption2 the feasible set
 $F_y$
is bounded. That is, we have the relation,
 \begin{equation} \Psi (y)= \mathop{\mathrm{argmin}}\limits_{z \in \mathscr{X}} f_y(z). \end{equation}
Furthermore, for each
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
let
 \begin{equation*} r_y = \sup _{\substack {x \in F_y\\x' \in F_y}} d_{\mathscr{X}}(x, x') = {\operatorname {diam}}_{d_{\mathscr{X}}}(F_y). \end{equation*}
Next, we make a claim which, once it is established, we use to prove that
 $\Psi$
has non-empty, compact values. This ensures that
 $\Psi$
is well-defined.
Claim.
For every
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
, we have that,
-
(1)
$f_y$
is continuous,
-
(2) for any
$x \in F_y$
, we have that
\begin{equation*} \underset {z \in \mathscr{X}}{\operatorname {argmin}}\,f_y(z) =\underset {z \in {B}(x,r_y)}{\operatorname {argmin}}\,f_y(z),\end{equation*}
-
(3)
$\Psi (y)$
is closed.


We proceed to prove the claim and start by considering (I). We consider a general setting, and let
 $(X,d)$
be a metric space,
 $A \subseteq X$
be a bounded subset and
 $g(x)\,:\!=\, d^H(x,A) = \sup _{a \in A} d(x,a)$
. We claim that
 $|g(x)-g(y)|\leq d(x,y)$
for all
 $x,y \in X$
. To see this, consider
 $a, x, y \in X$
and note that
 \begin{align*} d(x,a) \leq d(x,y) + d(y,a) \quad \implies \quad \sup _{a \in A}d(x,a) \leq d(x,y) + \sup _{a \in A} d(y,a). \end{align*}
Switching the roles of
 $x$
and
 $y$
, leads to the desired inequality. It follows that
 $g$
is continuous. Moreover,
 $ F_y$
is bounded by Assumption2. Thus, letting
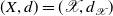 $(X,d)=(\mathscr{X}, d_{\mathscr{X}})$
,
 $A = F_y$
,
 $g=f_y$
above, proves (I).
To prove (II), we show that no point outside of the closed ball
 ${B}_{d_{\mathscr{X}}}(x,r_y)$
can be a minimiser of
 $f_y$
. First, note that
 $r_y = {\operatorname {diam}}_{d_{\mathscr{X}}}(\pi _1 (F_y))\lt \infty$
as
 $\pi _1 (F_y)$
is bounded. Moreover, by definition, we have that
 \begin{align*} r_y = \sup _{x \in F_y} \sup _{x' \in F_y} d_{\mathscr{X}}(x, x') = \sup _{x \in F_y} f_y(x), \end{align*}
which implies that
 $r_y \geq f_y(x)$
for all
 $x \in F_y$
. Now, pick an
 $\hat {x} \in F_y$
. If
 $z\in \mathscr{X} \setminus {B}(\hat {x},r_y)$
is a point outside of the ball, then
 $d_{\mathscr{X}}(z,\hat {x}) \gt r_y$
, and
 \begin{equation*} f_y(z) = \sup _{x' \in F_y} d_{\mathscr{X}}(x',z) \geq d_{\mathscr{X}}(\hat {x},z) \gt r_y \geq f_y(\hat {x}). \end{equation*}
It follows that any minimiser of
 $f_y$
must lie in the ball
 ${B}(\hat {x},r_y)$
. This proves our claim in (II).
Part (III) of the claim follows directly from the continuity of
 $f_y$
. Indeed, let
 $\alpha _y \,:\!=\, \min f_y \in [0, +\infty )$
. Then, since
 $\{\alpha _y\}\subset [0,\infty )$
is closed and
 $f_y$
is continuous, the preimage
 $f_y^{-1}(\{\alpha _y\}) = \Psi (y)$
is closed. This proves (III) and concludes our proof of the claim.
Next, we prove the following properties of
 $\Psi$
. These properties finalise the proof of statement (ii) of the theorem.
-
(1)
$\Psi$
has non-empty and compact values; -
(2)
$\Psi$
is an optimal map;


We start with the proof of (a). Let
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
and consider
 $x \in F_y$
. From (II) and (19), we see that
 \begin{equation} \Psi (y) = \mathop{\mathrm{argmin}}\limits_{z \in \mathscr{X}}\,f_y(z) = \mathop{\mathrm{argmin}}\limits_{z \in {B}(x,r_y)}\, f_y(z). \end{equation}
By Assumption 12,
 $d_{\mathscr{X}}$
satisfies the Heine-Borel property, which implies that the closed and bounded ball
 $\mathscr{B}(x,r_y)$
is compact. Moreover, from (I), we know that the objective function
 $f_y$
is continuous. Thus, it follows from the Extreme Value Theorem that
 $f_y$
attains its minimum in (20). This implies that
 $\Psi$
has non-empty values. To see that
 $\Psi$
has compact values, observe that
 $\Psi (y)$
is closed by (III) and that
 $\Psi (y) \subseteq {B}(x,r_y)$
, where
 ${B}(x,r_y)$
is compact. Since a closed subset of a compact set is compact, we conclude that
 $\Psi (y)$
is compact.
Next, we prove (b). We will show that the minimum worst-case reconstruction error of
 $\Psi$
equals the optimality constant as given in Definition1. To this end, let
 $\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
and fix
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. Recall from above that
 $\Psi$
is non-empty. By construction, we have that
 \begin{equation*} \sup _{x \in F_y} d_{\kern-1pt \mathscr{X}}^H(\Psi (y),x) \leq \sup _{x \in F_y} d_{\mathscr{X}}(x,z),\quad \text{for all $z \in \varphi (y)$.} \end{equation*}
It follows that
 \begin{align*} \sup _{x \in F_y} d_{\kern-1pt \mathscr{X}}^H(\Psi (y),x) \leq \sup _{x \in F_y} \sup _{z \in \varphi (y)} d_{\mathscr{X}}(x,z) = \sup _{x \in F_y} d_{\kern-1pt \mathscr{X}}^H(x,\varphi (y)). \end{align*}
By taking the supremum with respect to
 $y\in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
on both sides, we obtain
 \begin{align*} \sup _{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \sup _{x \in F_y}d_{\mathscr{X}}^{H} (\Psi (y), x) \leq \sup _{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \sup _{x \in F_y} d_{\mathscr{X}}^{H}(\varphi (y), x). \end{align*}
As
 $F\colon \mathscr{M}_1\times \mathscr{E} \to \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
is surjective, the previous inequality can be rewritten as
 \begin{align*} \sup _{(x,e)\in \mathscr{M}_1 \times \mathscr{E}} d_{\mathscr{X}}^{H} (\Psi (F(x,e)), x) \leq \sup _{(x,e)\in \mathscr{M}_1 \times \mathscr{E}} d_{\mathscr{X}}^{H} (\varphi (F(x,e)), x). \end{align*}
Now, since
 $\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
was arbitrary, the above inequality holds for any
 $\varphi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
. Taking the infimum over all mappings on the right-hand side, we obtain the optimality constant:
 \begin{align*} \sup _{(x,e)\in \mathscr{M}_1 \times \mathscr{E}} d_{\mathscr{X}}^{H} (\Psi (F(x,e)), x) \leq c_{\mathrm{opt}}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt). \end{align*}
The opposite inequality is trivial, since
 $\Psi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
is one of the reconstruction mappings over which the infimum is taken. Therefore,
 \begin{align*} \sup _{(x,e)\in \mathscr{M}_1 \times \mathscr{E}} d_{\mathscr{X}}^{H} (\Psi (F(x,e)), x) = c_{\mathrm{opt}}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt), \end{align*}
and we conclude that
 $\Psi$
is an optimal map. This concludes the proof of statement (ii) in the theorem.
We proceed with the proof of (i) and start with the lower bound in (9). Let
 $\varphi \,:\,\mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
and
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. Then
 \begin{align*} {\operatorname {diam}}_{d_{\mathscr{X}}}(F_y) = \sup _{x,x' \in F_y} d_{\mathscr{X}}(x,x') &\leq \sup _{x \in F_y} 2d_{\kern-1pt \mathscr{X}}^H(x, \varphi (y)). \end{align*}
Now, taking the supremum over all
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
gives the inequality
 \begin{align} \operatorname {kersize}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt)\leq \sup _{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \sup _{x \in F_y} 2d_{\kern-1pt \mathscr{X}}^H(x, \varphi (y)). \end{align}
Finally, since
 $\varphi$
was arbitrary, taking the infimum over all
 $\varphi \,:\,\mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
in (21) gives
 \begin{equation*} \operatorname {kersize}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt) \leq 2c_{\mathrm{opt}}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt). \end{equation*}
which proves the lower bound in (9).
For proving the upper bound in (9), we will make use of the mapping
 $\Psi$
in (10), which we know from statement (ii) is an optimal map. Let
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
and
 $x' \in F_y$
. Then by construction of
 $\Psi$
, we have that
 \begin{equation*} \sup _{x \in F_y} d_{\kern-1pt \mathscr{X}}^H(\Psi (y),x) \leq \sup _{x \in F_y} d_{\mathscr{X}}(x,x')\leq \operatorname {diam}(F_y). \end{equation*}
Taking the supremum over all
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
on both sides above, gives
 \begin{equation*} \sup _{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \sup _{x \in F_y} d_{\kern-1pt \mathscr{X}}^H(\Psi (y),x) =c_{\mathrm{opt}}^{\text{w}}(F, \mathscr{M}_1, \mathscr{E}\kern1.6pt) \leq \operatorname {kersize}^{\text{w}}(F,\mathscr{M}_1, \mathscr{E}\kern1.6pt), \end{equation*}
where we used the fact that
 $\Psi$
is an optimal map in the first equality. This establishes statement (i).
7.3. Preliminaries from measure theory
In order to prove Theorem3.2, we need to state and cite some existing results from measure theory and prove a preliminary lemma.
7.3.1. Carathéodory functions
Let
 $(S,\Sigma _{S}), (X,\Sigma _{X})$
and
 $(Y,\Sigma _{Y})$
be measurable spaces. For functions
 $f\colon S\times X \to Y$
, whose domain is a product of two measurable spaces, several notions of measurability exist. The function
 $f$
could be jointly measurable, i.e., measurable with respect to the product
 $\sigma$
-algebra
 $\Sigma _{S}\otimes \Sigma _{X}$
. For fixed
 $s \in S$
or
 $x \in X$
, the functions
 $f^s = f(s,\cdot ) \colon X \to Y$
and
 $f^x = f(\cdot ,x) \colon S \to Y$
, could be measurable with respect to
 $\Sigma _{X}$
and
 $\Sigma _{S}$
, respectively. A function
 $f$
which is measurable in one variable for each fixed
 $s \in S$
and for each fixed
 $x \in X$
is said to be separately measurable. In general, joint measurability implies separate measurability, but the converse is not true [Reference Aliprantis and Border6, p. 152].
A class of functions which are jointly measurable in many important cases are Carathéodory functions.
Definition 6 ([Reference Aliprantis and Border6, Definition 4.50]). Let
 $(S,\Sigma )$
be a measurable space, and let
 $X$
and
 $Y$
be topological spaces. A function
 $ f\colon S\times X \to Y$
is a Carathéodory function if:
-
(1) for each
$x \in X$
, the function
$f^{x} = f(\cdot ,x)\colon S\to Y$
is
$(\Sigma , \mathscr{B}(Y))$
-measurable, and
-
(2) for each
$s \in S$
, the function
$f^{s}=f(s,\cdot ) \colon X\to Y$
is continuous.

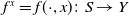


In particular, if
 $X$
is a separable metric space and
 $Y$
is a metric space, then every Carathéodory function
 $f\colon S\times X \to Y$
is jointly measurable [Reference Aliprantis and Border6, Lemma 4.51]. It is also straightforward to see that if
 $f$
is continuous in both arguments separately, then
 $f$
is a Carathéodory function.
7.3.2. Measurability of set-valued functions
For a single-valued function
 $f \colon Y\to X$
, the inverse image of a set
 $A \subset X$
is
 $f^{-1}(A) \,:\!=\, \{y \in Y \colon f(y) \in A\}$
. For a set-valued function
 $\varphi \colon Y \rightrightarrows X$
, there are different ways to generalise the concept of an inverse image: Given a set
 $A \subset X$
, we say that the upper inverse of
 $A$
is
 $\varphi ^{\mathrm{u}}(A) \,:\!=\, \{y \in Y \,:\,\varphi (y) \subset A\}$
and we say that the lower inverse of
 $A$
is
 \begin{equation*}\varphi ^{\ell }(A) \,:\!=\,\{y \in Y \,:\,\varphi (y) \cap A\neq \emptyset \}.\end{equation*}
Naturally, the notion of continuity of set-valued mappings between topological spaces depends on the definition of inverse. Interested readers are referred to [Reference Aliprantis and Border6, Chapter 17]. In this work, we shall be most concerned with the lower inverse of a set-valued mapping, since this notion of inverse allows us to pick a measurable selector. Next, we define two different notions of measurability for set-valued mappings based on the concept of lower inverse.
Definition 7 ([Reference Aliprantis and Border6, Definition 18.1]). Let
 $(Y, \Sigma )$
be a measurable space and
 $X$
a topological space. We say that a set-valued mapping
 $\varphi \,:\, Y \rightrightarrows X$
is:
-
• weakly measurable, if
$\varphi ^{\ell }(V) \in \Sigma$
for each open subset
$V$
of
$X$
, -
• measurable, if
$\varphi ^{\ell }(A)\in \Sigma$
for each closed subset
$A$
of
$X$
.


Importantly, one needs to remark here that the definition of weakly measurable for set-valued mappings in [Reference Aliprantis and Border6, Definition 18.1] is equivalent to that of measurable set-valued mappings [Reference Aubin and Frankowska14, Definition 8.1.1. (i), (ii)]. Additionally, we have that in some cases measurability implies weak measurability for set-valued mappings.
Lemma 7.5 ([Reference Aliprantis and Border6, Lemma 18.2]). Let
 $\varphi \,:\, Y \rightrightarrows X$
be a set-valued mapping from a measurable space
 $(Y,\Sigma )$
into a metric space. Then the following hold:
-
(1) If
$\varphi$
is measurable, then it is also weakly measurable.
-
(2) If
$\varphi$
is compact-valued and weakly measurable, then it is measurable.


Note that if the topology of
 $X$
above is induced by a metric, then every set-valued measurable mapping is also weakly measurable [Reference Aliprantis and Border6, Lemma 18.2]. Our main tool for proving Theorem3.2 is the following result.
Theorem 7.6 (Measurable maximum theorem, [Reference Aliprantis and Border6, Theorem 18.19]). Let
 $X$
be a separable metric space and
 $(S,\Sigma )$
a measurable space. Let
 $\varphi \colon S \rightrightarrows X$
be weakly measurable with non-empty compact values, and suppose
 $f\colon S \times X \to {\mathbb{R}}$
is a Carathéodory function. Define the value function
 $m\colon S \to {\mathbb{R}}$
by
 \begin{equation*} m(s) = \max _{x \in \varphi (s)} \ f(s,x), \end{equation*}
and the correspondence
 $\Phi \colon S \rightrightarrows X$
of maximisers by
 \begin{equation*} \Phi (s) = \{x \in \varphi (s) \ : \ f(s,x) = m(s)\}=\operatorname *{argmax}_{x \in \varphi (s)} f(s,x). \end{equation*}
Then
 $m$
is measurable,
 $\Phi$
has non-empty and compact values, and
 $\Phi$
is measurable and admits a measurable selector.
Note that for real-valued functions
 $\min _{x \in X} f(x) = \max _{x \in X} ({-}f(x))$
and the Measurable Maximum Theorem can be applied to minimisation problems as well. The Measurable Maximum Theorem will be applied in two ways. The first can be found in Proposition 7.7, which gives sufficient conditions for a map
 $\phi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
to be in the set
 $\mathscr{C}$
given by (11). The second use of the theorem above is found in the proof of part (ii) and (iii) of Theorem3.2.
Proposition 7.7.
If
 $\phi \,:\, \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
is measurable and has non-empty compact values, then
 $\phi \in \mathscr{C}.$
Proof. By definition of
 $\mathscr{C}$
, we need to prove that the function
 \begin{align*} r_\phi \,:\, \mathscr{M}_1 \times \mathscr{E} \to {\mathbb{R}}, \quad r_\phi (x,e) = d_{\kern-1pt \mathscr{X}}^H (x, \phi (F(x,e))) = \sup _{z \in \phi (F(x,e))} d_{\mathscr{X}}(x,z) \end{align*}
is measurable. Denote
 $S \,:\!=\, \mathscr{M}_1 \times \mathscr{E}$
,
 $X \,:\!=\, \mathscr{X}$
, and
 \begin{align*} &\varphi \,:\!=\, \phi \circ F\,:\, \mathscr{M}_1\times \mathscr{E} \rightrightarrows \mathscr{X}, & \varphi (x,e) = \phi (F(x,e)), \\ &f \,:\!=\, d_{\mathscr{X}} \circ (\pi _1, \text{id}_{\mathscr{X}})\,:\, (\mathscr{M}_1 \times \mathscr{E}\kern1.6pt) \times \mathscr{X} \to {\mathbb{R}}, &f((x,e), z) = d_{\mathscr{X}}(x,z). \end{align*}
We now show that the set-valued mapping
 $\varphi \,:\!=\, \phi \circ F\,:\, \mathscr{M}_1\times \mathscr{E} \rightrightarrows \mathscr{X}$
is weakly measurable. Let
 $V \subset \mathscr{X}$
be an open set. Then, by the definition [Reference Aliprantis and Border6, Section 17.1] of the lower inverse,
 $\varphi$
is given by
 \begin{align*} \varphi ^\ell (V) = \{(x,e) \in \mathscr{M}_1 \times \mathscr{E} \,:\, \varphi (x,e) \cap V \neq \emptyset \} = \{(x,e) \in \mathscr{M}_1 \times \mathscr{E} \,:\, \phi (F(x,e)) \cap V \neq \emptyset \}. \end{align*}
Observe that this set can be written as
 $\varphi ^\ell (V) = F^{-1}(\phi ^\ell (V)),$
where
 $\phi ^\ell (V) = \{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \,:\, \phi (y) \cap V \neq \emptyset \}$
denotes the lower inverse of
 $V$
under
 $\phi$
. Since
 $\phi$
is a set-valued mapping that is measurable, by Lemma 7.5, it follows that
 $\phi$
is also weakly measurable. As
 $\phi \,:\, \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
is weakly measurable and as
 $V \subset \mathscr{X}$
is an open set, we have
 $\phi ^\ell (V) \in \mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}})$
. Moreover,
 $F\colon (\mathscr{M}_1\times \mathscr{E}, \mathscr{B}(\mathscr{M}_1\times \mathscr{E}\kern1.6pt)) \to (\mathscr{M}_2^{\kern0.5pt\mathscr{E}}, \mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}}))$
is Borel measurable by Assumption3. Therefore, the preimage of the Borel set
 $\phi ^\ell (V) \in \mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}})$
under
 $F$
is Borel measurable
 \begin{equation*} \varphi ^\ell (V) = F^{-1}(\phi ^\ell (V)) \in \mathscr{B}(\mathscr{M}_1 \times \mathscr{E}\kern1.6pt). \end{equation*}
Hence, the set-valued mapping
 $\varphi \,:\, \mathscr{M}_1\times \mathscr{E} \rightrightarrows \mathscr{X}$
is weakly measurable. Moreover,
 $\varphi \,:\, \mathscr{M}_1\times \mathscr{E} \rightrightarrows \mathscr{X}$
has non-empty compact values because
 $\phi \,:\, \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
has non-empty compact values by assumption. By Assumption3,
 $(\mathscr{M}_1\times \mathscr{E}, \mathscr{B}(\mathscr{M}_1\times \mathscr{E}\kern1.6pt), \mu )$
is a
 $\sigma -$
finite measure space. The space
 $(\mathscr{X},d_{\mathscr{X}})$
is separable, as it is second countable by Assumption 11, and together with Assumption 12, it is also complete. Finally, the function
 $f$
is continuous in both arguments and hence Carathéodory. Thus, the assumptions in Theorem7.6 are satisfied, and its application implies that the value function
 $m\,:\, \mathscr{M}_1 \times \mathscr{E}\to {\mathbb{R}}$
 \begin{align*} m(x,e) = \max _{z \in \phi (F(x,e))} d_{\mathscr{X}}(x,z) \end{align*}
is measurable. It is immediate to notice that
 $m = r_\phi$
, so we conclude that
 $r_\phi$
is measurable. Hence we have proven that
 $\phi \in \mathscr{C}$
.
7.3.3. Disintegration of measures
Next, we prove a useful proposition that will be applied in the proof of Theorem3.2. For completeness, we start by recalling that every time we write an expression of the form
 \begin{align*} \mathop{\mathrm{esssup}}\limits_{(x,e) \in \mathscr{M}_1 \times \mathscr{E}} f(x,e), \quad \quad \mathop{\mathrm{esssup}}\limits_{(x,e) \in F^{-1}(y)} f(x,e), \quad \quad \mathop{\mathrm{esssup}}\limits_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} f(y). \end{align*}
Whenever it is clear from context, it is implicit that we are taking the essential supremum with respect to
 $\mu$
on
 $\mathscr{M}_1 \times \mathscr{E}$
, with respect to
 $\mu ^y$
on
 $F_y$
, and with respect to
 $F_*\mu$
on
 $\mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. We also recall that
 $\pi _1\colon \mathscr{X}\times \mathscr{Z}\to \mathscr{X}$
refers to the projection on the first component
 $\pi _1(x,e)=x$
.
Proposition 7.8. Given Assumptions 1 , 3 and 4 , we have the following:
-
(1) For
$A \in \mathscr{B} (\mathscr{M}_1\times \mathscr{E}\kern1.6pt)$
,
$\mu (A) =0$
if and only if
$\mu ^y(A) = 0$
for almost every
$y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. -
(2) Let
$f\,:\, \mathscr{M}_1\times \mathscr{E}\to [0,+\infty )$
be Borel measurable. Then the function
is Borel measurable.
\begin{align*} m\colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \to {\mathbb{R}}, \quad m(y) = \mathop{\mathrm{esssup}}\limits_{(x,e) \in F^{-1}(y)} f(x,e) \end{align*}
-
(3) Let
$f\,:\, \mathscr{M}_1\times \mathscr{E} \to [0,+\infty )$
be Borel measurable. Then
\begin{align*} \mathop{\mathrm{esssup}}\limits_{(x,e) \in \mathscr{M}_1\times \mathscr{E}} f(x,e) = \mathop{\mathrm{esssup}}\limits_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \mathop{\mathrm{esssup}}\limits_{(x,e) \in F^{-1}(y)} f(x,e). \end{align*}
-
(5) Let
$g\,:\, \mathscr{M}_1 \to [0,+\infty )$
be Borel measurable. Then
and
\begin{align*} \int _{F^{-1}(y)} g(\pi _1(x,e))d\mu ^y(x,e) = \int _{F_y} g(x) d\big (\pi _{1*}\mu ^y\big )(x), \end{align*}
where
\begin{align*} \mu ^y-\mathop{\mathrm{esssup}}\limits_{(x,e) \in F^{-1}(y)} g(\pi _1(x,e)) = \pi _{1*}\mu ^y-\mathop{\mathrm{esssup}}\limits_{x\in F_y} g(x), \end{align*}
$\mu ^y-\operatorname {esssup}$
, respectively, and
$\pi _{1*}\mu ^y-\operatorname {esssup}$
, denote the essential supremum with respect to the disintegration of measure
$\mu ^y$
and, respectively, the pushforward of the disintegration of measure
$\pi _{1*}\mu ^y$
.


Proof. We start with
 $(i)$
. Let
 $1_A$
denote the indicator function on
 $A \in \mathscr{B}(\mathscr{M}_1\times \mathscr{E}\kern1.6pt)$
. Suppose that
 $\mu (A) = 0$
, then by (iii) in Definition3, we have that
 \begin{equation*} 0 = \mu (A) = \int _{\mathscr{M}_1 \times \mathscr{E}} 1_A \ d\mu = \int _{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \Bigg ( \int _{F^{-1}(y)} 1_A \ d\mu ^y \Bigg )\ d(F_*\mu )(y). \end{equation*}
The integral of a positive function with respect to a positive measure is zero if and only if the integrand function is zero almost everywhere, so the previous equality is equivalent to
 \begin{equation*} \int _{F^{-1}(y)} 1_A \ d\mu ^y = \mu ^{y}(A) = 0 \quad \text{for }\text{ almost every } y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}. \end{equation*}
The reverse argument can be made with the same steps. Let us now prove
 $(ii)$
. Since the Borel
 $\sigma$
-algebra on
 $\mathbb{R}$
is generated by sets of form
 $(a, +\infty )$
, we proceed to show that
 $m^{-1}((a, +\infty ))$
is Borel measurable for any
 $a \in {\mathbb{R}}$
. We have
 \begin{align*} m^{-1}((a,+\infty )) & = \big\{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}\,:\, m(y) \gt a\big\} \\ & = \big\{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}\,:\, \mu ^y(\{(x,e) \in \mathscr{M}_1\times \mathscr{E}\,:\, f(x,e) \gt a\})\gt 0\big\} \\ & = \big\{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}\,:\, \int _{\mathscr{M}_1\times \mathscr{E}} 1_{f^{-1}((a,\infty ))} \ d\mu ^y\gt 0\big\} \\ & = \big\{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}\,:\, h_a(y) \gt 0\big\} = h_a^{-1}((0,+\infty )), \end{align*}
where
 $h_a(y) = \int _{\mathscr{M}_1\times \mathscr{E}} 1_{f^{-1}((a,\infty ))} \ d\mu ^y$
. In particular, since
 $f$
is Borel measurable,
 $f^{-1}((a,\infty ))$
is a measurable set, and hence,
 $1_{f^{-1}((a,\infty ))}$
is a measurable function on
 $(\mathscr{M}_1\times \mathscr{E},\mathscr{B}(\mathscr{M}_1\times \mathscr{E}\kern1.6pt))$
. Now, from (ii), in Definition3, we know that the function
 $y \mapsto h_a(y) = \int _{\mathscr{M}_1\times \mathscr{E}} 1_{f^{-1}((a,\infty ))} \ d\mu ^y$
is measurable, and so
 $h_a^{-1}((0,+\infty )) = m^{-1}((a,+\infty ))$
is a Borel measurable subset of
 $\mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. As
 $a \in {\mathbb{R}}$
was arbitrary, this proves that
 $m$
is Borel-measurable. This concludes
 $(ii)$
. Next we consider
 $(iii)$
, and let
 $m$
be as in
 $(ii)$
. We start by showing that
 \begin{align} \mathop{\mathrm{esssup}}\limits_{(x,e) \in \mathscr{M}_1\times \mathscr{E}} f(x,e) \geq \mathop{\mathrm{esssup}}\limits_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} m(y). \end{align}
Let
 $K= \operatorname {esssup}_{(x,e) \in \mathscr{M}_1\times \mathscr{E}} f(x,e)$
. By definition, we have
 $\mu (\{(x,e) \in \mathscr{M}_1\times \mathscr{E}\,:\, f(x,e) \gt K \})=0$
. Hence, by Proposition 7.8,
 $(i)$
, and the fact that
 $\mu ^y$
is concentrated on
 $F^{-1}(y)$
, we have
 \begin{align*} 0&=\mu ^y(\{(x,e) \in \mathscr{M}_1\times \mathscr{E}\,:\, f(x,e) \gt K\}) =\mu ^y(\{(x,e) \in F^{-1}(y)\,:\, f(x,e) \gt K \}) \end{align*}
for almost every
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. So
 $m(y) = \operatorname {esssup}_{(x,e) \in F^{-1}(y)} f(x,e) \leq K = \operatorname {esssup}_{\mathscr{M}_1\times \mathscr{E}} f$
for almost every
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. This proves (22). Next, we consider the reverse inequality. By definition of
 $\operatorname {esssup}_{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} m$
, we have
 \begin{align*} m(y) =\mathop{\mathrm{esssup}}\limits_{(x,e) \in F^{-1}(y)} f(x,e) \leq \mathop{\mathrm{esssup}}\limits_{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} m \end{align*}
for almost every
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. Hence, as
 $\mu ^y$
is concentrated on
 $F^{-1}(y)$
 \begin{align*} \mu ^y(\{(x,e) \in F^{-1}(y)\,:\, f(x,e) \gt \mathop{\mathrm{esssup}}\limits_{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} m \})=\mu ^y(\{(x,e) \in \mathscr{M}_1\times \mathscr{E}\,:\, f(x,e) \gt \mathop{\mathrm{esssup}}\limits_{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} m \})=0 \end{align*}
for almost every
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. By Proposition 7.8,
 $(i)$
, this is equivalent to
 $\mu (\{(x,e) \in \mathscr{M}_1\times \mathscr{E}\,:\, f(x,e) \gt \operatorname {esssup}_{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} m \})=0$
, which implies
 $\operatorname {esssup}_{(x,e) \in \mathscr{M}_1\times \mathscr{E}} f(x,e) \leq \operatorname {esssup}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} m(y)$
, as desired. This concludes the proof of
 $(iii)$
.
Finally, let us prove
 $(iv)$
. Equality between integrals
 \begin{align*} \int _{F^{-1}(y)} (g \circ \pi _1) \, d\mu ^y = \int _{F_y} g d\pi _{1*}\mu ^y \end{align*}
comes directly from the definition of pushforward measure and can be found in detail [Reference Aliprantis and Border6, Theorem 13.46]. To see the equality between essential suprema, take
 $M \in [0,+\infty )$
, then note that
 \begin{align*} (\pi _{1*}\mu ^y)(g^{-1}(M, +\infty )) = \mu ^y(\pi _1^{-1}(g^{-1}(M, +\infty ))) = \mu ^y((g\circ \pi _1)^{-1}(M, +\infty )). \end{align*}
Taking
 $M = \operatorname {esssup}_{F^{-1}(y)} (g\circ \pi _1)$
, then the definition of essential supremum gives
 $\mu ^y((g\circ \pi _1)^{-1}(M, +\infty ))=0$
, which by the previous chain of equalities implies that
 $0 =(\pi _{1*}\mu ^y)(\{x \in F_y\,:\, g(x) \gt \operatorname {esssup}_{F^{-1}(y)} (g\circ \pi _1)\})$
, so that
 $g(x) \leq \operatorname {esssup}_{F^{-1}(y)} (g\circ \pi _1)$
for
 $\pi _{1*}\mu ^y$
-almost every
 $x \in F_y$
. This gives
 $\operatorname {esssup}_{x \in F_y} g(x) \leq \operatorname {esssup}_{F^{-1}(y)} (g\circ \pi _1)$
, by taking instead
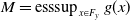 $M = \operatorname {esssup}_{x \in F_y} g(x)$
, the same reasoning proves the reverse inequality between essential suprema. Hence equality is proven, concluding the proof of
 $(iv)$
.
7.4. Proof of Theorem3.2
Having established the above preliminaries, we now proceed to proving Theorem3.2. In order to do so, we will split the Theorem up into two results, Propositions 7.9 and 7.10, and prove these. These results combined provide the proof of Theorem3.2.
Proposition 7.9 (Lower bound of part
 $(i)$
, Theorem3.2). Given the assumptions in Theorem
3.2
, then the following holds for every
 $p \in [1,\infty ]$
:
 \begin{align*} \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p) \leq 2c_{\mathrm{opt}}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p). \end{align*}
Proof of Proposition
7.9. Let
 $\varphi \,:\,\mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
be an arbitrary reconstruction mapping. Fix
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
and consider
 $(x,e),(x',e') \in \mathscr{M}_1\times \mathscr{E}$
such that
 $F(x,e) = F(x',e')= y$
. Then, by the triangle inequality, we deduce
 \begin{equation} d_{\mathscr{X}}(x,x') \leq d_{\kern-1pt \mathscr{X}}^H(x, \varphi (F(x,e))) + d_{\kern-1pt \mathscr{X}}^H(x',\varphi (F(x',e'))). \end{equation}
Let us now distinguish the two cases where
 $p = \infty$
and
 $p\in [1, \infty )$
. The structure of the proof will be very similar in the two cases, with the main difference that the case
 $p = \infty$
involves essential suprema, while the case
 $p \in [1,+ \infty )$
involves integrals. We will fully prove the case
 $p\in [1, \infty )$
and provide a sketch of the proof of the case
 $p=\infty$
, as it is virtually identical. In both cases, however, Equation (23) will play a crucial role. To ensure that the essential suprema and integrals are well-defined, we assume that
 $\varphi \in \mathscr{C}$
.
Case
 $p\in [1, \infty )$
; here, we use that for
 $a \in [0,\infty )$
the map
 $a \mapsto a^p$
is convex, and by the definition of convexity, we have that for
 $a,b \in [0,\infty )$
that
 $( \tfrac {1}{2} a + \tfrac {1}{2} b)^{p} \leq \tfrac {1}{2} a^{p} + \tfrac {1}{2} b^{p}$
. Replacing
 $a,b$
with
 $2a,2b$
yields
 $(a+b)^p \leq 2^{p-1}(a^p + b^p)$
for
 $a,b\geq 0$
. Now integrating (23) twice with respect to
 $\mu ^y$
and using that
 $(a+b)^p \leq 2^{p-1}(a^p + b^p)$
for
 $a,b\geq 0$
, we obtain
 \begin{align*} &\int _{F^{-1}(y)} \int _{F^{-1}(y)} d_{\mathscr{X}}(x,x')^p \, d\mu ^y(x,e) \, d\mu ^y(x',e') \\& \leq \int _{F^{-1}(y)} \int _{F^{-1}(y)} \big(d_{\kern-1pt \mathscr{X}}^H(x, \varphi (F(x,e))) + d_{\kern-1pt \mathscr{X}}^H(x',\varphi (F(x',e'))) \big)^p \ d\mu ^y(x,e) \, d\mu ^y(x',e') \\& = 2^p\int _{F^{-1}(y)} d_{\kern-1pt \mathscr{X}}^H(x, \varphi (F(x,e)))^p \ d\mu ^y(x,e) \end{align*}
where in the last step we also used the fact that
 $\mu ^y$
is a probability measure and the integrals are well-defined as
 $\varphi \in \mathscr{C}$
. Now, integrating the above inequality with respect to
 $F_*\mu$
on
 $\mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
, by (iii) in Definition3, and raising to the power
 $\frac {1}{p}$
gives that
 \begin{align*} \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p) & = \Bigg (\int _{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \int _{F_y} \int _{F_y} d_{\mathscr{X}}(x,x')^p \ d\mu ^y(x,e) \ d\mu ^y(x',e') \, d(F_*\mu )(y) \Bigg )^{\frac {1}{p}} \\ &\leq \Bigg ( 2^p \int _{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \int _{F_y} d_{\kern-1pt \mathscr{X}}^H(x, \varphi (F(x,e)))^p \ \ d\mu ^y(x,e) \ d(F_*\mu )(y)\Bigg )^{\frac {1}{p}} \\ & = 2 \Bigg ( \int _{\mathscr{M}_1\times \mathscr{E}} d_{\kern-1pt \mathscr{X}}^H(x, \varphi (F(x,e)))^p \ d\mu (x,e) \Bigg )^{\frac {1}{p}}. \end{align*}
Since
 $\varphi \in \mathscr{C}$
was arbitrary, by taking the infimum over
 $\varphi \in \mathscr{C}$
we obtain:
 \begin{align*} \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p) &\leq 2\inf _{\varphi \in \mathscr{C}}\Bigg ( \int _{\mathscr{M}_1\times \mathscr{E}} d_{\kern-1pt \mathscr{X}}^H(x, \varphi (F(x,e)))^p \ d\mu (x,e) \Bigg )^{\frac {1}{p}} \\ & = 2c_{\mathrm{opt}}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p). \end{align*}
The proposition is therefore also proven in the case
 $p \in [1,+\infty )$
.
Case
 $p = \infty$
; the proof follows the basic structure of the case
 $p \in [1,\infty )$
. In (23), instead of integrating, we take the essential supremum respect to the measure
 $\mu ^y$
. Then in the next step, instead of integrating, we take the essential supremum in
 $y$
with respect to the measure
 $F_*\mu$
on
 $\mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
and apply Proposition 7.8. Finally, as
 $\varphi \,:\,\mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
was arbitrary, taking the infimum over
 $\varphi \in \mathscr{C}$
concludes the proof.
Proposition 7.10 (Part
 $(ii)$
and
 $(iii)$
and upper bound in (i) of Theorem3.2). The following holds for every
 $p \in [1,\infty ]$
:
 \begin{equation*} c_{\mathrm{opt}}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p) \leq \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p), \end{equation*}
and the map
 $\Psi \colon \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
given by,
 \begin{align} \Psi (y) &= \operatorname {argmin}_{z \in \mathscr{X}}\operatorname {esssup}_{(x,e) \in F^{-1}(y)} d_{\mathscr{X}}(x,z) & (p = \infty )\\[-10pt]\nonumber \end{align}
 \begin{align} \Psi (y) &= \operatorname {argmin}_{z \in \mathscr{X}} \int _{F^{-1}(y)} d_{\mathscr{X}}(x,z)^p \ d\mu ^y(x,e) & (p \in [1, \infty )) \end{align}
is an optimal map with average error of order
 $p$
. Moreover,
 $\Psi$
has non-empty compact values, is measurable and it admits a measurable selector.
Proof of Proposition
7.10. We distinguish the cases
 $p = \infty$
and
 $p \in [1,\infty )$
. In both cases, the structure of the proof consists in proving the following steps:
-
(1)
$\Psi$
, defined either by (24) or (25), has non-empty values;
-
(2)
$\Psi$
is measurable, has compact values and admits a measurable selector;
-
(3)
$\Psi \in \mathscr{C} = \{\varphi \,:\, \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}\,:\, (x,e) \mapsto d_{\kern-1pt \mathscr{X}}^H(x,\varphi (F(x,e)) \text{is measurable}\}$
; -
(4)
$\Psi$
is an optimal map with average error of order
$p$
; -
(5) Upper bound:
$c_{\mathrm{opt}}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p) \leq \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1,\mathscr{E},p)$
with
$p=\infty$
or
$p \in [1,+\infty )$
.


First, we consider the case
 $p \in [1,\infty )$
. Again, let us first introduce some notation, similar to above. Fix
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
. Define
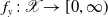 $f_y\,:\, \mathscr{X} \to [0,\infty )$
,
 \begin{equation*} f_y(z) = \int _{F^{-1}(y)} d_{\mathscr{X}}(x, z)^p \ d\mu ^y(x,e) \end{equation*}
for
 $z \in \mathscr{X}$
. Define also
 \begin{align*} r_y &= \mathop{\mathrm{esssup}}\limits_{\substack {(x,e) \in F^{-1}(y)\\(x',e') \in F^{-1}(y)}} d_{\mathscr{X}}(x, x'), \\ E_y^{(x,e)} &= \{(x',e') \in F^{-1}(y)\,:\, d_{\mathscr{X}}(x,x') \gt r_y\} \quad \text{ for } (x,e) \in F^{-1}(y),\\ G_y &= \{(x,e) \in F^{-1}(y)\,:\, \mu ^y(E_{y}^{(x,e)}) = 0 \}. \end{align*}
Note that
 $f_y$
is Borel measurable. The function
 $((x,e),z) \mapsto 1_{F^{-1}(y)}(x,e)\, d_{\mathscr{X}}(x,z)$
is non-negative and Borel measurable. By the Fubini-Tonelli [Reference Folland55, Theorem 2.37]
 $f_y$
, as
 $z \mapsto \int _{F^{-1}(y)} d_{\mathscr{X}}(x, z)^p \ d\mu ^y(x,e)$
, is Borel measurable. Additionally, by a similar line of reasoning, one can show that the function
 $y \mapsto r_y$
is Borel measurable. Additionally, as the metric space
 $(\mathscr{M}_1,d_{\mathscr{X}})$
is compact by Assumption4, the set
 $\mathscr{M}_1$
is bounded. Thus, as
 $F^{-1}(y) \subset \mathscr{M}_1\times \mathscr{E}$
, we have that
 \begin{align*} r_y \leq \sup _{\substack {(x,e) \in F^{-1}(y)\\(x',e') \in F^{-1}(y)}} d_{\mathscr{X}}(x, x') \leq \operatorname {diam}(\mathscr{M}_1)\lt \infty . \end{align*}
We now show that the set
 $G_y$
is non-empty and
 $\mu ^y(G_y)=1$
. Fix
 $y \in \mathscr{M}^{\mathscr{E}}$
. By definition of the essential supremum, it follows that
 \begin{align*} (\mu ^y \otimes \mu ^y)\big (\big \{((x,e),(x',e')) \in F^{-1}(y)\times F^{-1}(y) \,:\, d_{\mathscr{X}}(x,x') \gt r_y \big \}\big )=0. \end{align*}
Then, by Fubini-Tonelli [Reference Folland55, Theorem 2.37],
 \begin{align*} 0 &= (\mu ^y \otimes \mu ^y)\left (\big \{((x,e),(x',e')) \in F^{-1}(y)\times F^{-1}(y) \,:\, d_{\mathscr{X}}(x,x') \gt r_y \big \}\right )\\ &= \int _{F^{-1}(y)} \mu ^y\big (E_y^{(x,e)}\big )\, d\mu ^y(x,e). \end{align*}
Since the integrand is nonnegative, we conclude that
 \begin{align*} \mu ^y\big (E_y^{(x,e)}\big )=0 \quad \text{for } \mu ^y\text{-a.e. } (x,e)\in F^{-1}(y). \end{align*}
Recall the definition
 $G_y = \{(x,e) \in F^{-1}(y) \,:\, \mu ^y(E_y^{(x,e)}) = 0\}$
. As the disintegration
 $\mu ^y$
is a probability measure that is concentrated on
 $F^{-1}(y)$
, Definition3 (i), we have that
 $\mu ^y(G_y)=1$
and, in particular,
 $G_y \neq \emptyset$
.
Claim. We claim that the following holds: for every
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
-
(I)
$f_y$
is continuous, -
(II)
$\underset {\mathscr{X}}{\operatorname {argmin}}\, f_y =\underset {B(x,2r_y)}{\operatorname {argmin}}\, f_y$
for
$\mu ^y$
-almost every
$(x,e)\in F^{-1}(y)$
.


We proceed to prove the claim and start by considering (I). We consider a general setting and let
 $(X,d)$
be a metric space equipped with a probability measure
 $\nu$
concentrated on a bounded subset
 $A\subseteq X$
, and define
 \begin{equation*} g(x) \,:\!=\, \Big ( \int _A d(x,a)^p \, d\nu (a)\Big )^{\frac {1}{p}}=\|d(x,\cdot )\|_{L^p(X,\nu )} = \|d(x,\cdot )\|_p. \end{equation*}
We claim that
 $|g(x)-g(z)|\leq d(x,z)$
for all
 $x,y \in X$
. To see this, consider
 $a, x, z \in X$
and note that by the triangle inequality
 $d(x,a) \leq d(x,z) + d(z,a)$
. Taking
 $L^p(X,\nu )$
-norms in the variable
 $a$
and applying Minkowski’s inequality gives
 \begin{align*} g(x) = \|d(x,\cdot )\|_p \leq \|d(x,z)+d(z,\cdot )\|_p \leq \|d(x,z)\|_p+\|d(z,\cdot )\|_p = d(x,z) + g(z), \end{align*}
where in the last passage we used that
 $\nu$
is a probability measure. Switching the roles of
 $x$
and
 $z$
, leads to the desired inequality. It follows that
 $g$
is continuous. By assumption4, since
 $\mathscr{M}_1$
is compact and
 $F_y\subseteq \mathscr{M}_1$
, then
 $F_y$
is bounded. Thus, letting
 $(X,d) = (\mathscr{X},d_{\mathscr{X}})$
,
 $\nu = \pi _{1*}\mu ^y$
,
 $A = F_y$
above, and recalling Proposition 7.8, (iv), then
 $g^p=f_y$
, which proves (I).
To prove (II), we will show that for
 $\mu ^y$
-almost every
 $(x,e) \in F^{-1}(y)$
we have
 \begin{align} \Psi (y) = \operatorname {argmin}_{z\in \mathscr{X}} \int _{F^{-1}(y)}d_{\mathscr{X}}(x',z)^p\ d\mu ^y(x',e') = \operatorname {argmin}_{z\in B_{d_{\mathscr{X}}}(x,2r_y)} f_y(z). \end{align}
Fix
 $(x,e) \in G_y$
. If
 $z\in \mathscr{X} \setminus B_{d_{\mathscr{X}}}(x,2r_y)$
, then for
 $\mu ^y$
-almost every
 $(x',e')\in F^{-1}(y)$
,
 \begin{equation*} d_{\mathscr{X}}(z,x') \geq d_{\mathscr{X}}(z,x)-d_{\mathscr{X}}(x,x') \gt 2r_y - r_y = r_y. \end{equation*}
Thus, the previous inequality holds for any
 $z\in \mathscr{X} \setminus B_{d_{\mathscr{X}}}(x,2r_y)$
. Thus,
 \begin{align*} f_y(z) &= \int _{F^{-1}(y)}d_{\mathscr{X}}(z,x')^p\ d\mu ^y(x',e') \\ &\gt \int _{F^{-1}(y)} r_y^p \, d\mu ^y(x',e') = r_y^p. \end{align*}
On the other hand,
 \begin{align*} f_y(x) &= \int _{F^{-1}(y)}d_{\mathscr{X}}(x,x')^p\ d\mu ^y(x',e') \\ & \leq \int _{F^{-1}(y)} r_y^p \ d\mu ^y(x',e') = r_y^p. \end{align*}
Therefore,
 $f_y(z) \gt f_y(x)$
whenever
 $z \notin B(x,2r_y)$
, which implies that points
 $z$
outside of such a ball cannot be minimisers, hence proving (26). This concludes part (II) of the claim.
With the claim, we can prove the required (a)–(e) properties of
 $\Psi$
. First, let us prove (a), namely that
 $\Psi$
in (25) has non-empty values. By the Heine-Borel property of the metric
 $d_{\mathscr{X}}$
, the set
 $B_{d_{\mathscr{X}}}(x,2r_y) \subset \mathscr{X}$
is compact, since it is a closed ball with respect to the metric
 $d_{\mathscr{X}}$
. Hence, the function
 $f_y$
is continuous by (I) and its minimisers are by (II) restricted to the compact set
 $B_{d_{\mathscr{X}}}(x,2r_y)$
. Therefore, the minimum in (25) is attained by the Extreme Value Theorem. This shows that the argmin is non-empty, and hence that
 $\Psi$
has non-empty values on
 $\mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
.
We now proceed to prove (b), namely that
 $\Psi$
is measurable and has compact values. Recall that above we have shown that
 $\operatorname {diam}(\mathscr{M}_1)\lt \infty$
. We will apply the Maximum Measurable Theorem, 7.6, with
 $S = \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
,
 $X = \mathscr{X}$
, and
 \begin{align*} \varphi &\,:\, \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}, \qquad \varphi (y) = B_{d_{\mathscr{X}}}(\mathscr{M}_1,2\operatorname {diam}(\mathscr{M}_1)), \\ f &\,:\,\mathscr{M}_2^{\kern0.5pt\mathscr{E}} \times \mathscr{X} \to {\mathbb{R}}, \ f(y,z) = f_y(z) = \int _{F^{-1}(y)} d_{\mathscr{X}}(x ,z)^p \ d\mu ^y(x,e). \end{align*}
In order to apply the theorem, we need to verify that the assumptions are satisfied. We start by proving that
 $\varphi$
is weakly measurable with non-empty compact values. Firstly, it is clear that, since
 $\varphi$
is constant, then
 $\varphi$
is weakly measurable and has non-empty values. Moreover, the only value
 $\varphi$
takes is
 $B_{d_{\mathscr{X}}}(\mathscr{M}_1,2\operatorname {diam}(\mathscr{M}_1))$
, which we now prove to be compact. Recall that the distance is
 $\operatorname {dist}_{d_{\mathscr{X}}}(x,A) = \inf _{a \in A} d_{\mathscr{X}}(x,a)$
. Note that, since
 $\mathscr{M}_1$
is compact by Assumption4, then
 $\mathscr{M}_1$
is bounded and hence
 $B_{d_{\mathscr{X}}}(\mathscr{M}_1,2\operatorname {diam}(\mathscr{M}_1))= \{x\in \mathscr{X}\,:\, \operatorname {dist}_{d_{\mathscr{X}}}(x, \mathscr{M}_1) \leq 2\text{diam}(\mathscr{M}_1)\}$
is bounded too.
We now show that the function
 $\operatorname {dist}_{d_{\mathscr{X}}}(\cdot , \mathscr{M}_1)$
is continuous. We consider a general setting, and let
 $(X,d)$
be a metric space,
 $A \subseteq X$
be a bounded subset and
 $g(x)\,:\!=\, \operatorname {dist}_{d}(x,A) = \inf _{a \in A} d(x,a)$
. We claim that
 $|g(x)-g(y)|\leq d(x,y)$
for all
 $x,y \in X$
. To see this, consider
 $a, x, y \in X$
and note that
 \begin{align*} d(x,a) \leq d(x,y) + d(y,a) \quad \implies \quad \inf _{a \in A}d(x,a) \leq d(x,y) + \inf _{a \in A} d(y,a). \end{align*}
Switching the roles of
 $x$
and
 $y$
, leads to the desired inequality. It follows that
 $g$
is continuous. Moreover, since the function
 $\operatorname {dist}_{d_{\mathscr{X}}}(\cdot , \mathscr{M}_1)$
is continuous, the set
 \begin{equation*}B_{d_{\mathscr{X}}}(\mathscr{M}_1,2\operatorname {diam}(\mathscr{M}_1)) = \operatorname {dist}_{d_{\mathscr{X}}}(\cdot ,\mathscr{M}_1)^{-1}([0,2\operatorname {diam}(\mathscr{M}_1)])\end{equation*}
is closed. Hence, we have proven that
 $B_{d_{\mathscr{X}}}(\mathscr{M}_1,2\text{diam}(\mathscr{M}_1))$
is closed and bounded, and by the Heine Borel property of
 $d_{\mathscr{X}}$
granted by Assumption4 it follows that
 $B_{d_{\mathscr{X}}}(\mathscr{M}_1,2\text{diam}(\mathscr{M}_1))$
is compact. This proves that
 $\varphi$
is weakly measurable with non-empty compact values. Secondly, to prove that
 $f$
is Carathéodory, we need to show that
 $f(y, \cdot ) = f_y$
is continuous for every fixed
 $y\in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
and that
 $f(\cdot ,z)$
is measurable for every fixed
 $z\in \mathscr{M}_1$
. On the one hand, for every fixed
 $y\in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
, the function
 $f_y$
is continuous on
 $\mathscr{X}$
as proven in claim (I). On the other hand, for every fixed
 $z$
, the function
 $f(\cdot ,z)\,:$
 $y \mapsto \int _{F^{-1}(y)} d_{\mathscr{X}}(x ,z)^p \ d\mu ^y(x,e)$
is Borel measurable, described by Definition3 (ii). Then, by Theorem7.6, the possibly set-valued function
 $\Phi \,:\, \mathscr{M}_2^{\kern0.5pt\mathscr{E}} \rightrightarrows \mathscr{X}$
given by
 \begin{align*} \Phi (y) = \mathop{\mathrm{argmin}}\limits_{z \in B_{d_{\mathscr{X}}}(\mathscr{M}_1,2\text{diam}(\mathscr{M}_1)) } \ \int _{F^{-1}(y)} d_{\mathscr{X}}(x ,z)^p \ d\mu ^y(x,e) \end{align*}
is measurable and has non-empty, compact values. Moreover, by combining (26) and the fact that for
 $(x,e) \in G_y$
,
 $B_{d_{\mathscr{X}}}(x,2r_y) \subseteq B_{d_{\mathscr{X}}}(\mathscr{M}_1,2\text{diam}(\mathscr{M}_1))$
, we deduce that
 $\Phi = \Psi$
. Hence,
 $\Psi$
is measurable and has non-empty, compact values.
We now prove (c), namely that
 $\Psi \in \mathscr{C}$
. This follows directly from Proposition 7.7.
We now proceed to prove (d), namely that
 $\Psi$
is an optimal map. Let
 $\varphi \in \mathscr{C}$
. By the minimising definition of
 $\Psi$
,
 \begin{align*} \int _{F^{-1}(y)} d_{\kern-1pt \mathscr{X}}^H(\Psi (y),x)^p \ d\mu ^y(x,e) \leq \int _{F^{-1}(y)} d_{\mathscr{X}}(z,x)^p \ d\mu ^y(x,e) \end{align*}
for every
 $z \in \varphi (y)$
. In particular, taking the supremum with respect to
 $z \in \varphi (y)$
, which coincides with considering the Hausdorff distance, and using Fatou’s Lemma yields
 \begin{align*} \int _{F^{-1}(y)} d_{\kern-1pt \mathscr{X}}^H(\Psi (y),x)^p \ d\mu ^y(x,e) & \leq \sup _{z \in \varphi (y)} \int _{F^{-1}(y)} d_{\mathscr{X}}(z,x)^p \ d\mu ^y(x,e) \\ & \leq \int _{F^{-1}(y)} \sup _{z \in \varphi (y)} d_{\mathscr{X}}(z,x)^p \ d\mu ^y(x,e) \\ & \leq \int _{F^{-1}(y)} d_{\kern-1pt \mathscr{X}}^H(\varphi (y),x)^p \ d\mu ^y(x,e). \end{align*}
By integrating with respect to
 $y\in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
, we obtain
 \begin{align*} & \int _{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \int _{F^{-1}(y)} d_{\kern-1pt \mathscr{X}}^H(\Psi (y),x)^p \ d\mu ^y(x,e) \ d(F_*\mu )(y) \\ & \quad \leq \int _{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \int _{F^{-1}(y)} d_{\kern-1pt \mathscr{X}}^H(\varphi (y),x)^p \ d\mu ^y(x,e) \ d(F_*\mu )(y). \end{align*}
Due to Definition3 (iii) of the disintegration of measure, the above integrals can be rewritten as
 \begin{align*} \int _{\mathscr{M}_1\times \mathscr{E}} d_{\kern-1pt \mathscr{X}}^H(\Psi (F(x,e)),x)^p \ d\mu (x,e) \leq \int _{\mathscr{M}_1\times \mathscr{E}} d_{\kern-1pt \mathscr{X}}^H(\varphi (F(x,e)),x)^p \ d\mu (x,e). \end{align*}
Now, as
 $\varphi \in \mathscr{C}$
was arbitrary and by raising both sides to the power
 $\frac {1}{p}$
, we obtain
 \begin{align*} \Bigg (\int _{(x,e)\in \mathscr{M}_1\times \mathscr{E}} d_{\kern-1pt \mathscr{X}}^H(\Psi (F(x,e)),x)^p \ d\mu (x,e) \Bigg )^{\frac {1}{p}} \leq c_{\mathrm{opt}}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p). \end{align*}
The opposite inequality holds trivially, as
 $\Psi \in \mathscr{C}$
. Therefore,
 $\Psi$
is an optimal map.
Finally, we proceed to prove (e), namely the upper bound
 $ c_{\mathrm{opt}}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p) \leq \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p).$
By the minimisation property of
 $\Phi$
, hence also of
 $\Psi$
, for every
 $(x',e') \in F^{-1}(y)$
and for
 $F_*\mu$
-a.e.
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
:
 \begin{align} \int _{F^{-1}(y)} d_{\kern-1pt \mathscr{X}}^H(x ,\Psi (y))^p \ d\mu ^y(x,e) \leq \int _{F^{-1}(y)} d_{\mathscr{X}}(x ,x')^p \ d\mu ^y(x,e). \end{align}
Integrating (27) with respect to
 $\mu ^y$
in the
 $(x',e')$
variables yields,
 \begin{align*} \int _{F^{-1}(y)} d_{\kern-1pt \mathscr{X}}^H(x, \Psi (y))^p \ d\mu ^y(x,e) \leq \int _{F^{-1}(y)} \int _{F^{-1}(y)} d_{\mathscr{X}}(x, x')^p \ d\mu ^y(x,e) \ d\mu ^y(x',e'). \end{align*}
where we used that
 $\mu ^y$
is a probability measure. Integrating both sides over
 $y\in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
with respect to
 $F_*\mu$
we obtain
 \begin{align*} &\int _{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \int _{F_y} d_{\kern-1pt \mathscr{X}}^H(x, \Psi (y))^p \ d\mu ^y(x,e) \ d(F_*\mu )(y)\\ & \quad \leq \int _{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \int _{F^{-1}(y)} \int _{F^{-1}(y)} d_{\mathscr{X}}(x, x')^p\ d\mu ^y(x,e) \ d\mu ^y(x',e') \ d(F_*\mu )(y). \end{align*}
Using the definition of disintegration of the measure
 $\mu$
on the left hand side of the above inequality yields
 \begin{align*} \int _{\mathscr{M}_1\times \mathscr{E}} d_{\kern-1pt \mathscr{X}}^H(x, \Psi (F(x,e)))^p \ d\mu (x,e) \leq \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p)^p. \end{align*}
Then, raising both sides to the
 $\frac {1}{p}$
-th power, gives
 \begin{align*} \Bigg (\int _{\mathscr{M}_1\times \mathscr{E}} d_{\kern-1pt \mathscr{X}}^H(x, \Psi (F(x,e)))^p \ d\mu (x,e) \Bigg )^{\frac {1}{p}} \leq \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p). \end{align*}
And finally, since
 $\Psi \in \mathscr{C}$
, we conclude
 \begin{align*} c_{\mathrm{opt}}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p) \leq \operatorname {kersize}^{\text{a}}(F,\mathscr{M}_1, \mathscr{E}, p). \end{align*}
This concludes the case
 $p \in [1,+\infty )$
. Hence, the proof is complete.
Now we consider the case
 $p=\infty$
. The proof only requires minor modifications to the case
 $p \in [1,\infty )$
, that we will describe in the following. The objective function for
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
and
 $z \in \mathscr{X}$
is
 \begin{equation*} f_y(z) = \mathop{\mathrm{esssup}}\limits_{(x,e) \in F^{-1}(y)} d_{\mathscr{X}}(x, z). \end{equation*}
where the essential supremum is taken with respect to
 $\mu ^y$
. Then
 $\Psi (y) = \operatorname {argmin}_{\mathscr{X}} f_y$
. Define, as before,
 \begin{equation*} r_y = \mathop{\mathrm{esssup}}\limits_{\substack {(x,e) \in F^{-1}(y)\\(x',e') \in F^{-1}(y)}} d_{\mathscr{X}}(x, x'). \end{equation*}
Claim.
For every
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
:
-
(I)
$f_y$
is continuous;
-
(II)
$\underset {\mathscr{X}}{\operatorname {argmin}}\,f_y =\underset {B(x,2r_y)}{\operatorname {argmin}}\,f_y$
for
$\mu ^y$
-almost every
$(x,e)\in F^{-1}(y)$
.


The claims are proven analogously to the case
 $p \in [1,\infty )$
, except that to prove (I), Minkowski’s inequality is replaced by the following. We consider a general setting, and let
 $(X,d)$
be a metric space,
 $A\subseteq X$
be a bounded subset,
 $\nu$
be a probability measure on
 $X$
concentrated on
 $A$
and
 $g(x)\,:\!=\, \operatorname {esssup}_{a \in A} d(x,a)$
. We claim that
 $|g(x)-g(z)|\leq d(x,z)$
for all
 $x,z \in X$
. To see this, consider
 $a, x, z \in X$
and notice that
 \begin{align*} d(x,a) \leq d(x,z) + d(z,a) \quad \implies \quad \operatorname {esssup}_{a \in A}d(x,a) \leq d(x,z) + \operatorname {esssup}_{a \in A} d(z,a). \end{align*}
Switching the roles of
 $x$
and
 $z$
, leads to the desired inequality. It follows that
 $g$
is continuous. Claim (II) follows the same line of reasoning as in the case
 $p \in [1,\infty )$
by replacing the integration with the essential supremum with respect to
 $\mu ^y$
.
With the claim, we can show the properties given by the list (a)-(e) stated at the beginning of the proof, similarly to the case
 $p \in [1,\infty )$
. For the sake of brevity, we provide a sketch of the proof.
Part (a) follows the same line of reasoning as in the case
 $p \in [1,\infty )$
. In part (b) we again apply the Maximum Measurable Theorem7.6 with
 $f(y,z) = f_y(z) \,:\!=\, \operatorname {esssup}_{(x,e) \in F^{-1}(y)} d_{\mathscr{X}}(x ,z)$
and apply Proposition 7.8 to show that
 $f(\cdot ,z)\,:\, y \mapsto \operatorname {esssup}_{(x,e)\in F^{-1}(y)}d_{\mathscr{X}}(x,z)$
is Borel measurable. Part (c) is again a direct consequence of (b) and Proposition 7.7. Parts (d) and (e) follows the same line of reasoning as in the case
 $p \in [1,\infty )$
by replacing the integration with the essential supremum. This concludes the proof of the proposition in the case
 $p = \infty$
.
7.5. Proof of Proposition 4.1
Proof. We begin with part
 $(1)$
by showing that if
 $A$
satisfies the rNSP, (17), with respect to the set
 $\mathscr{M}_1$
, then
 $A$
is injective on
 $\mathscr{M}_1$
. Let
 $x,x' \in \mathscr{M}_1$
such that
 $Ax=Ax'$
, then
 $A(x-x')=0$
. Now we apply the rNSP, (17), to
 $h\,:\!=\, x-x'$
, and since
 $x-x' \in \mathscr{M}_1 - \mathscr{M}_1$
, this yields
 \begin{align*} {\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert x-x' \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{X}_1} \leq D_1 \mathrm{dist}_{\mathscr{X}_2}(x-x',\mathscr{M}_1-\mathscr{M}_1) + 0 = 0. \end{align*}
This implies that
 $h=x-x'=0$
. Hence
 $A$
is injective on
 $\mathscr{M}_1$
.
Additionally, if
 $A$
is injective on
 $\mathscr{M}_1$
, then for
 $x,x' \in \mathscr{M}_1$
such that
 $Ax=Ax'$
, then
 $x-x'=0$
and we have that
 \begin{align*} (\mathscr{M}_1 - \mathscr{M}_1) \cap \mathscr{N}\kern1pt(A) = \{0\}. \end{align*}
For the converse direction, let
 $x,x' \in \mathscr{M}_1$
such that
 $Ax=Ax'$
. This is equivalent to
 $A(x-x')=0$
and as
 $(\mathscr{M}_1 - \mathscr{M}_1) \cap \mathscr{N}\kern1pt(A) = \{0\}$
, we have that
 $x-x'=0$
. Thus,
 $x=x'$
and
 $A$
is injective.
For part
 $(2)$
, let
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
and
 $x,x'\in \mathscr{M}_1$
and
 $e,e'\in \mathscr{E}$
be such that
 $y=F(x,e) = Ax+e =Ax'+e'= F(x',e')$
. From the rNSP (17), as
 $\mathrm{diam}_{d_{\mathscr{Y}}}(\mathscr{E}\kern1.6pt) = \sup _{e,e' \in \mathscr{E}}{\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert e-e' \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{Y}} = \eta$
and since
 $x-x' \in \mathscr{M}_1 - \mathscr{M}_1$
, we then have that
 \begin{align*} {\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert x-x' \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{X}_1} &\leq D_1\mathrm{dist}_{\mathscr{X}_2}(x-x', \mathscr{M}_1 -\mathscr{M}_1) + D_2 {\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert A(x-x') \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{Y}} \\ &= D_2{\left \vert \kern -0.25ex\left \vert \kern -0.25ex\left \vert e-e' \right \vert \kern -0.25ex\right \vert \kern -0.25ex\right \vert }_{\mathscr{Y}} \leq D_2\eta . \end{align*}
Taking supremum over all
 $x, x' \in F_y$
and, then, over
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
yields
 \begin{align*} \mathrm{kersize}^{\text{w}}(F, \mathscr{M}_1, \mathscr{E}\kern1.6pt) = \sup _{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \ \sup _{x,x' \in F_y} d_{\mathscr{X}}(x,x') \le D_2\eta . \end{align*}
7.6. Proof of Proposition 4.2
Before introducing the Bayesian framework for inverse problems, we recall the concept of regular conditional distribution.
Definition 8 (Regular conditional distribution, [Reference Dudley48, Section 10.2]). Let
 $(\Omega , \mathscr{F}, \mathbb{P})$
be a probability space, and let
 $\mathbf{x} \,:\, (\Omega , \mathscr{F}) \to (\mathscr{X}, \mathscr{B}(\mathscr{X}\kern1pt))$
and
 $\mathbf{y} \,:\, (\Omega , \mathscr{F}) \to (\mathscr{Y}, \mathscr{B}(\mathscr{Y}))$
be random variables. The regular conditional distribution of
 $\mathbf{x}$
given
 $\mathbf{y}$
is a function
 $\mathbb{P}_{\mathbf{x} \mid \mathbf{y} = \cdot } = \mathbb{P}_{\mathbf{x}}[\cdot \mid \mathbf{y} = \cdot ] \,:\, \mathscr{B}(\mathscr{X}\kern1pt) \times \mathscr{Y} \to [0,1]$
such that:
-
(1) For every
$y \in \mathscr{Y}$
, the function
$\mathbb{P}_{\mathbf{x} \mid \mathbf{y} = y} \,:\, \mathscr{B}(\mathscr{X}\kern1pt) \to [0,1]$
is a probability measure;
-
(2) For every
$A \in \mathscr{B}(\mathscr{X}\kern1pt)$
, the function
$\mathbb{P}_{\mathbf{x} \mid \mathbf{y} = \cdot }(A) \,:\, \mathscr{Y} \to [0,1]$
is
$(\mathscr{B}(\mathscr{Y}), \mathscr{B}([0,1]))$
-measurable and
(3.5.1)where
\begin{equation} \mathbb{P}_{\mathbf{x}}(A)= \int _{\mathscr{Y}} \mathbb{P}_{\mathbf{x} \mid \mathbf{y} = y}(A)\, d\mathbb{P}_{\mathbf{y}}(y), \tag {3.5.1} \end{equation}
$\mathbb{P}_{\mathbf{x}} = \mathbb{P} \circ \mathbf{x}^{-1}$
and
$\mathbb{P}_{\mathbf{y}} = \mathbb{P} \circ \mathbf{y}^{-1}$
are the laws of
$x$
on
$(\mathscr{X}, \mathscr{B}(\mathscr{X}\kern1pt))$
and of
$y$
on
$(\mathscr{Y}, \mathscr{B}(\mathscr{Y}))$
, respectively.


Regular conditional distributions do not always exist. The following positive result guarantees that a regular conditional distribution exists when the random variable that is being conditioned takes values in a completely metrisable and separable topological space, also referred to as a Polish space.
Theorem 7.11 (Existence and uniqueness of regular conditional distributions [Reference Dudley48, Theorem 10.2.2] or [Reference Schervish95, Theorem B.32 and Lemma B.40]). Let
 $(\Omega , \mathscr{F}, \mathbb{P})$
be a probability space and let
 $\mathscr{Y}$
be a Polish space. Let
 $\mathbf{x} \,:\, (\Omega , \mathscr{F}) \to (\mathscr{X}, \mathscr{B}(\mathscr{X}\kern1pt))$
and
 $\mathbf{y} \,:\, (\Omega , \mathscr{F}) \to (\mathscr{Y}, \mathscr{B}(\mathscr{Y}))$
be random variables. Then, there exists a regular conditional distribution
 $\mathbb{P}_{\mathbf{x} \mid \mathbf{y} = \cdot } = \mathbb{P}_{\mathbf{x}}[ \cdot \mid \mathbf{y} = \cdot ] \,:\, \mathscr{B}(\mathscr{X}\kern1pt) \times \mathscr{Y} \to [0,1]$
of
 $\mathbf{x}$
given
 $\mathbf{y}$
. Moreover, the regular conditional distribution is unique up to
 $\mathbb{P}$
-almost sure equivalence.
Remark. Disintegrations of measure are regular conditional probabilities. Let
 $(\Omega , \mathscr{F}, \mathbb{P})$
be a probability space and let
 $\mathscr{X}$
be a Polish space. Let
 $\mathbf{x} \,:\, (\Omega , \mathscr{F}) \to (\mathscr{X}, \mathscr{B}(\mathscr{X}\kern1pt))$
be a random variable. Equip
 $(\mathscr{X}, \mathscr{B}(\mathscr{X}\kern1pt))$
with a probability measure given by the law of
 $\mathbf{x}$
, as
 $\mu _{\mathbf{x}} = \mathbb{P}_{\mathbf{x}}({\cdot})$
. Let
 $F\,:\, (\mathscr{X}, \mathscr{B}(\mathscr{X}\kern1pt)) \rightarrow (\mathscr{Y}, \mathscr{B}(\mathscr{Y}))$
be measurable. Define the random variable
 $\mathbf{y} \,:\!=\, F \circ \mathbf{x}$
on
 $\mathscr{Y}$
. Then, a disintegration
 $\{\mu _{\mathbf{x}}^y\}_{y\in \mathscr{Y}}$
of
 $\mu _{\mathbf{x}}$
along
 $F$
defines a regular conditional distribution of
 $\mathbf{x}$
given
 $\mathbf{y}$
. The reverse, that a regular conditional distribution is a disintegration of measure, in general does not hold; as in Definition
3
(i) of the disintegration of measure, the support is required to concentrate on the preimages
 $F^{-1}(y)$
.
Proof. We start with part
 $(1)$
. Starting from the joint random variable
 $(\mathbf{x},\mathbf{e}) \sim \mu _{\mathbf{x},\mathbf{e}} = \mathbb{P}[(\mathbf{x},\mathbf{e}) \in \cdot ]$
, the random variable
 $\mathbf{x}$
can be obtained by the composition
 $\mathbf{x} = \pi _1 \circ (\mathbf{x},\mathbf{e})$
. Then, its distribution is the Bayesian prior of the inverse problem, and is given by the marginal distribution
 $\mu _{\mathbf{x}} = \pi _{1*} \mu _{\mathbf{x},\mathbf{e}} = \mathbb{P}[\mathbf{x} \in \cdot ]$
.
For part
 $(2)$
apply Proposition 7.1, but consider a different measurable function and different spaces. We disintegrate
 $\mu$
along the projection
 $\pi _1 \,:\, (\mathscr{X} \times \mathscr{E}, \mathscr{B}(\mathscr{X} \times \mathscr{E}\kern1.6pt)) \to (\mathscr{X}, \mathscr{B}(\mathscr{X}\kern1pt))$
. By Proposition 7.1 there exists a disintegration
 $\{\mu ^x\}_{x \in \mathscr{X}}$
of
 $\mu$
along
 $\pi _1$
and each measure
 $\mu ^x$
is a probability measure that is concentrated on
 $\{x\} \times \mathscr{E}$
. Then, this disintegration
 $\mu ^x$
can be pushed forward via
 $F$
, as
 $\mu _{\mathbf{y} \mid \mathbf{x} = x} \,:\!=\, F_* \mu ^x$
. Now we show that
 $\mu _{\mathbf{y} \mid \mathbf{x} = \cdot }$
is a regular conditional distribution of
 $\mathbf{y}$
given
 $\mathbf{x}$
. As
 $\mu ^x$
is a probability measure, for
 $A \in \mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}})$
we have that
 $\mu _{\mathbf{y} \mid \mathbf{x} = x}(A) = \mu ^x(F^{-1}(A)) \in [0,1]$
. Additionally, we have that
 $\mu _{\mathbf{y} \mid \mathbf{x} = x}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}}) = \mu ^x(F^{-1}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}}))=1$
, since
 $\mu ^x$
is a probability measure and as
 $\mu$
is supported on
 $\mathscr{M}_1 \times \mathscr{E}$
by Assumption3. Thus
 $\mu _{\mathbf{y} \mid \mathbf{x} = x}$
is a probability measure. For all
 $V \in \mathscr{B}(\mathscr{X}\times \mathscr{E}\kern1.6pt)$
the function
 $x \mapsto \mu ^x(V)$
is measurable. For
 $A \in \mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}})$
as
 $F$
is measurable,
 $V = F^{-1}(A)$
is measurable, and we have that
 $x \mapsto \mu _{\mathbf{y} \mid \mathbf{x} = x}(A) = \mu ^x(F^{-1}(A))$
is measurable. Now recall that by Definition3 (iii), we have that the disintegration of measure satisfies
 \begin{align*} \mu (A) = \int _{\mathscr{X} \times \mathscr{E}} 1_A(x,e) d\mu (x,e) = \int _{\mathscr{X}} \left (\int _{\mathscr{E}} 1_A(x,e) d\mu ^x(x,e)\right ) d\pi _{1*}\mu (x) = \int _{\mathscr{X}} \mu ^x(A) d\pi _{1*}\mu (x). \end{align*}
Now by Definition3 (iii) and as
 $\mu _{\mathbf{y}} = F_* \mu _{\mathbf{x},\mathbf{e}}$
, the property
 $(2)$
in Definition8 of conditional distributions is verified:
 \begin{align*} \mu _{\mathbf{y}}(A) &= F_* \mu (A) = \mu _{\mathbf{x},\mathbf{e}}(F^{-1}(A))\\ &= \int _{\mathscr{X}} \mu ^x(F^{-1}(A))\, d\pi _{1*}\mu (x) = \int _{\mathscr{X}} F_* \mu ^x(A)\, d\pi _{1*}\mu (x)\\ &= \int _{\mathscr{X}} \mu _{\mathbf{y} \mid \mathbf{x} = x}(A)\, d\mu _{\mathbf{x}}(x), \end{align*}
for every
 $A \in \mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}})$
. This construction proves that
 $\{\mu _{\mathbf{y} \mid \mathbf{x} = x}\}_{x \in \mathscr{X}}$
is a likelihood distribution in the Bayesian sense. For part
 $(3)$
, we apply Proposition 7.1 to disintegrate
 $\mu$
along the function
 $F \,:\, (\mathscr{X} \times \mathscr{E}, \mathscr{B}(\mathscr{X} \times \mathscr{E}\kern1.6pt)) \to (\mathscr{M}_2^{\kern0.5pt\mathscr{E}}, \mathscr{B}(\mathscr{M}_2^{\kern0.5pt\mathscr{E}}))$
and, then, pushforward the resulting disintegration
 $\{\mu ^y\}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
with respect to
 $\pi _1$
to obtain the Bayes posterior
 $\{\pi _{1*}\mu ^y\}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
. The Bayes posterior is a family of regular conditional distributions
 $\{\mu _{\mathbf{x} \mid \mathbf{y} = y}\}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
that is uniquely defined (up to
 $\mu _{\mathbf{y}}$
-almost sure equivalence) by satisfying the condition
 \begin{align} \mu _{\mathbf{x}}(A) = \int _{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \mu _{\mathbf{x} \mid \mathbf{y} = y}(A)\, d\mu _{\mathbf{y}}(y), \end{align}
for all
 $A \in \mathscr{B}(\mathscr{X}\kern1pt)$
. By Proposition 7.1, there exists a disintegration
 $\{\mu ^y\}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
of
 $\mu$
along
 $F$
and each measure
 $\mu ^y$
is a probability measure that is concentrated on
 $F^{-1}(y) \subset \mathscr{X} \times \mathscr{E}$
. We now prove that the family
 $\{\pi _{1*} \mu ^y\}_{y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}}$
satisfies the condition (28) of a regular conditional distribution. For
 $A \in \mathscr{B}(\mathscr{X}\kern1pt)$
, by Definition3 (iii), we have
 \begin{align*} \mu _{\mathbf{x}}(A) = \big(\pi _{1*} \mu \big)(A) = \mu \big(\pi _1^{-1}(A)\big) = \int _{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \mu ^y\big(\pi _1^{-1}(A)\big)\, dF_*\mu (y) = \int _{\mathscr{M}_2^{\kern0.5pt\mathscr{E}}} \pi _{1*}\mu ^y(A)\, d\mu _{\mathbf{y}}(y). \end{align*}
Therefore, the defining condition for the posterior is verified. Since
 $(\mathscr{Y},d_{\mathscr{Y}})$
is a Polish space, the regular conditional distribution
 $\mu _{\mathbf{x} \mid \mathbf{y} = \cdot }$
exists and is unique up to
 $\mu _{\mathbf{y}}$
-almost sure equivalence by [Reference Dudley48, Theorem 10.2.2]. We conclude that
 $\pi _{1*} \mu ^y = \mu _{\mathbf{x} \mid \mathbf{y} = y}$
for
 $\mu _{\mathbf{y}}$
-a.e.
 $y \in \mathscr{M}_2^{\kern0.5pt\mathscr{E}}$
.
Now for part
 $(4)$
, we apply Theorem3.2 part (ii). As the integrand does not depend on
 $e$
, the optimal map can be rewritten depending on the posterior distribution from part
 $(3)$
 \begin{align} \Psi (y) &= \mathop{\mathrm{argmin}}\limits_{z \in \mathscr{X}} \int _{F^{-1}(y)} d_{\mathscr{X}}(x,z)^p \ d\mu ^y(x,e),\\[-10pt]\nonumber \end{align}
 \begin{align} &= \mathop{\mathrm{argmin}}_{z \in \mathscr{X}} \int _{\pi _1(F^{-1}(y))} d_{\mathscr{X}}(x,z)^p \ d(\pi _{1*}\mu ^y)(x) \end{align}
Recall that
 $\pi _{1*}\mu ^y = \mu _{\mathbf{x} \mid \mathbf{y}=y}$
. As
 $d_{\mathscr{X}}$
is induced by an inner product
 $\langle \cdot , \cdot \rangle$
and the norm
 $\|\cdot \|$
induced by the inner product, for
 $p = 2$
, and the measure
 $\pi _{1*}\mu ^y$
is supported on
 $\pi _1(F^{-1}(y))$
, the optimal map reduces to
 \begin{align*} \Psi (y) = \mathop{\mathrm{argmin}}\limits_{z \in \mathscr{X}} \int _{\mathscr{X}} \|x - z\|^2\, d\mu _{\mathbf{x} \mid \mathbf{y}=y}(x) = \arg \min _{z \in \mathscr{X}} \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}\big [\|\mathbf{x} - z\|^2\big ], \end{align*}
which is the Minimum Mean Squared Error (MMSE) for the posterior distribution
 $\pi _{1*}\mu ^y = \mu _{\mathbf{x} \mid \mathbf{y}=y}$
. Using the bilinearity of the inner product and the linearity of expectation, the objective function to be minimised in the expression for the optimal map
 $\Psi$
can be rewritten as:
 \begin{align*} \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}\big [\|\mathbf{x} - z\|^2\big ] &= \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}\big [\|\mathbf{x} - \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] + \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] - z\|^2\big ] \\[2pt] &= \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}\big [\|\mathbf{x} - \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] \|^2\big ] + \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}\big [\|\mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] - z\|^2\big ] \\[2pt] & \quad + 2\mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}\big \langle \mathbf{x} - \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}], \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] - z\big \rangle \\[2pt] &= \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}\big [\|\mathbf{x} - \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] \|^2\big ] + \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}\big [\|\mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] - z\|^2\big ] \\[2pt] & \quad + 2\big \langle \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] - \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}], \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] - z\big \rangle \\[2pt] &= \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}\big [\|\mathbf{x} - \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] \|^2\big ] + \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}\big [\|\mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}] - z\|^2\big ] \end{align*}
which is the sum of two non-negative quantities and is thus minimised when
 $z = \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}]$
. Thus, the optimal map is given by
 $\Psi (y) = \mathbb{E}_{\mu _{\mathbf{x} \mid \mathbf{y}=y}}[\mathbf{x}]$
and coincides with the posterior mean.
Funding statement
The work of the first author was supported by the UK EPSRC Centre for Doctoral Training. The work of the last author was supported by the Royal Society University Research Fellowship and the Leverhulme Prize 2017. The first author also acknowledges research sponsored by the Laboratory Directed Research and Development (LDRD) Program of Oak Ridge National Laboratory, managed by UT-Battelle, LLC, for the U. S. DOE.
Competing interests
The authors declare no competing interests.


 Open access

