1. Overview
This paper proposes a new explanation for a cross-linguistic tendency that was first discussed in Croft (Reference Croft and Tsohatzidis1990) and first documented in Haspelmath (Reference Haspelmath, Comrie and Polinsky1993): Certain types of causal–noncausal verb pairs, such as those in (1a–c) below, show a greater propensity for causative coding (i.e. with an extra marker on the verb), while others, such as those in (2a–c), show a greater propensity for anticausative coding (i.e. with an extra marker on the noncausal verb). Intuitively, the verb pairs in (1) can be characterized as having a more ‘spontaneous’ core-event, while the verb pairs in (2) have a less spontaneous core-event (where by core-event we mean the event that is shared by the meanings of both verbs).
(1) More spontaneous core-events: ‘dry’, ‘melt’, ‘freeze’
causal noncausal
(a) ‘dry (tr.)’ ‘dry (intr.)’
(b) ‘melt (tr.)’ ‘melt (intr.)’
(c) ‘freeze (tr.)’ ‘freeze (intr.)’
(2) Less spontaneous core-events: ‘break’, ‘open’, ‘split’
causal noncausal
(a) ‘break (tr.)’ ‘break (intr.)’
(b) ‘open (tr.)’ ‘open (intr.)’
(c) ‘split (tr.)’ ‘split (intr)’
Thus, we typically find situations such as those in Japanese and Swahili, shown in (3), where the more spontaneous ‘freeze’ pair shows causative coding (marked by -ase in Japanese and -isha in Swahili), while the less spontaneous ‘break’ pair shows anticausative coding (marked by -e in Japanese and -ika in Swahili).
(3) causal noncausal
Japanese koor-ase- koor- (causative coding)
Swahili gand-isha ganda
‘freeze (tr.)’ ‘freeze (intr.)’
Japanese war- war-e- (anticausative coding)
Swahili vunja vunj-ika
‘break (tr.)’ ‘break (intr.)’
The basic idea that is new here is that in addition to form–meaning parallelisms, languages also exhibit form–frequency correspondences, and that these are actually more important in determining grammatical coding such as causative and anticausative coding of causal–noncausal verb pairs. In verb pairs of type (1) above, the noncausal member is relatively more frequent, so that the causal member tends to be coded overtly (as causative). In verb pairs of type (2) above, the causal member is relatively more frequent, so that the noncausal member tends to be coded overtly (as anticausative). These claims are supported by corpus data from seven diverse languages.Footnote 2
It thus turns out that coding types in causal–noncausal alternations broadly follow the same principles of economic expression that are found widely elsewhere in grammatical structure (e.g. Greenberg Reference Greenberg1966; Haiman Reference Haiman1983; Croft Reference Croft2003: Chapter 4; Hawkins Reference Hawkins2004: Chapter 4).
Our form–frequency correspondence account solves a problem that has vexed many researchers who assumed some kind of form–meaning parallelism principle. From such a perspective, anticausatives are puzzling because they seem to have ‘less meaning’, but more form, than their causal counterparts (see e.g. Haspelmath Reference Haspelmath, Comrie and Polinsky1993: Section 1), or they are formally derived but semantically basic. And if one turns the analysis around and says that the noncausals are semantically derived from the causals (e.g. Levin & Rappaport Hovav Reference Levin and Hovav1995), then causatives are puzzling, because they are formally derived but semantically basic. On our form–frequency correspondence account, these puzzles disappear, because the trend in the formal patterns is exactly as expected: In general, grammatical coding asymmetries are sensitive to frequency asymmetries, not to semantic derivation, to ‘semantic markedness’ or to semantic complexity (Haspelmath Reference Haspelmath2008a).
Most earlier work on causal–noncausal alternations has had rather different goals. Unlike authors such as Levin & Rappaport Hovav (Reference Levin and Hovav1995), Piñón (Reference Piñón, Hastings, Jackson and Zvolenszky2001), Doron (Reference Doron2003), Alexiadou, Anagnostopoulou & Schäfer (Reference Alexiadou, Anagnostopoulou, Schäfer and Frascarelli2006), Schäfer (Reference Schäfer2008), Koontz-Garboden (Reference Koontz-Garboden2009) (see Schäfer Reference Schäfer2009 for an overview), we do not aim to provide elegant (‘formal’) descriptions or analyses of particular languages. Our goal is restricted to explaining a cross-linguistic trend in the distribution of causatives and anticausatives, and thus our explanatory proposal is in principle compatible with all of these analytical proposals. As noted in Haspelmath (Reference Haspelmath2004, Reference Haspelmath2010), the explanation of cross-linguistic trends is often orthogonal to the issue of language-particular analysis. However, to some extent, many of the analytical proposals are motivated by the desire to make the presence or absence of (anti)causative coding fall out from the analysis, and this motivation disappears if we are right that the coding is best explained by frequency asymmetries and is otherwise quite possibly random (see Spagnol Reference Spagnol2011: 151–152). In this respect, then, our proposal can be seen as relevant to language-particular analysis after all, though it is beyond the scope of this paper to spell this out in detail.
In the following sections, we will lay out the basic concepts (Section 2), contrast the two competing explanatory principles (form–meaning parallelism and form–frequency correspondence; Section 3), present the sample of 20 comparative verb meanings and the sample of seven languages (Section 4), and spell out our predictions (Section 5). Then the results of our corpus studies will be presented (Sections 6–7), and the semantically-based approach of Levin & Rappaport Hovav will be discussed briefly (Section 8), before we conclude the paper (Section 9).
2. Basic concepts
We are interested in causal–noncausal verb pairs that exhibit some cross-linguistic variability of coding.Footnote 3 These are often called ‘inchoative–causative’ verb pairs (following Guerssel et al. Reference Guerssel, Hale, Laughren, Levin and Eagle1985, Borer Reference Borer1991), but we avoid this term here because the causal verb need not be coded as a causative, and the noncausal verb need not be semantically inchoative (i.e. it need not be a change-of-state verb containing a ‘become’ meaning component). We thus limit the terms causative and anticausative to their use for formal patterns,Footnote 4 while the terms causal verb and noncausal verb are used for semantic types.Footnote 5 In the context of this article, a causal verb is a verb (or verbal expression)Footnote 6 that includes a ‘cause’ meaning component (e.g. English break (tr.), which means ‘cause to become broken’), while a noncausal verb is a verb that has the same basic meaning as a causal verb but lacks the ‘cause’ component (e.g. English break (intr.), which means ‘become broken’). The meaning component that is shared by both verbs of a causal–noncausal pair is called the core-event here (this is identical to the meaning of the noncausal verb).
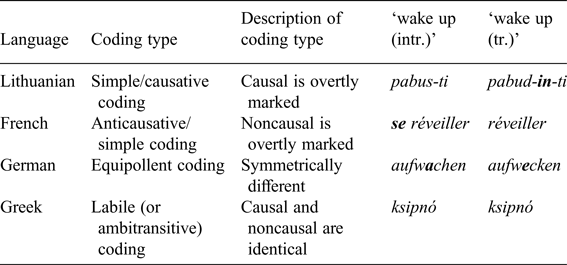
We focus our attention on those kinds of verb pairs that exhibit coding variability across languages (and not uncommonly within languages as well).Footnote 7 For example, the causal–noncausal pair ‘wake up (tr./intr.)’ can be coded in four different ways across languages, see Table 1.Footnote 8
Coding type of ‘wake up’ in four languages.

There are several dozen commonly represented meanings that exhibit coding variability (Haspelmath Reference Haspelmath, Comrie and Polinsky1993), but we should not forget that most verb pairs do not exhibit any variability across languages. For example, the coding of the causal–noncausal pair ‘make someone dance’/‘dance’ is quite uniform: In all languages, the causal verb is overtly coded in some way (whether synthetically or analytically), whereas the noncausal verb ‘dance’ is simple. While logically perfectly possible, the option of coding ‘make dance’ as a simple root and deriving ‘dance’ from this as an anticausative is unattested, as far as we know. In general, when the core-event is itself agentive (i.e. when one participant is a volitional agent) and atelic, languages (virtually) never use anticausative, equipollent or labile coding.Footnote 9 This seems so natural from a form–meaning isomorphism perspective that linguists have not worried about these cases, and we will leave them aside in this paper as well. However, they are fully compatible with our account, as can be easily seen by counting the frequencies of ‘make dance’ and ‘dance’ (see also the concluding section for some discussion).
Most of the verb pairs that do exhibit variability have a core-event that denotes a change of state (i.e. that includes the component ‘become’), so we could limit ourselves to causal–inchoative alternations. However, variability is also found with verb pairs denoting (potentially non-translational) motion such as ‘(cause to) roll’, ‘(cause to) spin’, and even sometimes with two-argument core-events such as ‘(cause to) learn something’. Thus, we consider all causal–noncausal alternations in principle, but focus on those that exhibit interesting cross-linguistic differences.
3. Form–frequency correspondence vs. form–meaning parallelism
The fundamental principle of the form–frequency correspondence approach (Zipf Reference Zipf1935) is the principle in (4).
(4) The form–frequency correspondence principle
Languages tend to use less coding material for more frequent expressions.
This is uncontroversial for word length (e.g. Zipf Reference Zipf1935: 23; Bybee Reference Bybee2006), but it is also generally valid for grammatical patterns. The insight of the principle in (5) below is originally due to Greenberg (Reference Greenberg1966) (see also Croft Reference Croft2003: Chapter 4; Haspelmath Reference Haspelmath2008a, Reference Haspelmath and Goodb).
(5) The grammatical form–frequency correspondence principle
When two grammatical patterns that differ minimally in meaning (i.e. patterns that form a semantic opposition) occur with significantly different frequencies, the less frequent pattern tends to be overtly coded (or coded with more coding material), while the more frequent pattern tends to be zero-coded (or coded with less coding material).
This principle accounts for a wide variety of form asymmetries, for example for the fact that in the oppositions in (6) (Greenberg Reference Greenberg1966), it is the first member that tends to be zero-coded, while the second member tends to be overtly coded.Footnote 10
(6) Asymmetric grammatical oppositions
singular/plural, present/future, 3rd person/2nd person, nominative/accusative, active/passive, affirmative/negative, masculine/feminine, attributive adjective/predicative adjective (including copula), positive/comparative, predicative verb/nominalized verb, action word/agent noun
Alternatively, one could approach these form asymmetries with an expectation of form–meaning parallelism, for example isomorphism of complexity, as in (7).
(7) The form–meaning complexity isomorphism principle
More complex meanings are expressed by more complex forms, i.e. by more coding material.
Such a principle has in fact often been invoked (sometimes called ‘iconicity of complexity’),Footnote 11 but it plainly does not work for word length (consider words such as cat, car, child, which are semantically more complex than their taxonomic superordinates animal, vehicle and person, but strongly tend to be shorter than them across languages),Footnote 12 and Haspelmath (Reference Haspelmath2008a) has argued that it does not work for grammatical patterns either.Footnote 13
Form–meaning parallelism in the sense of (7) (involving isomorphism of complexity) has been invoked for causatives only by Clark & Clark (Reference Clark, Clark and Greenberg1978: 250–251) and Haspelmath (Reference Haspelmath, Comrie and Polinsky1993), as far as we know. But Haspelmath started out with the observation that the principle cannot work in its most simplistic form: If causal verbs are semantically more complex than noncausal verbs (‘cause [core-event]’ vs. ‘core-event’), then isomorphism predicts that anticausatives should not exist. So he argued that instead of complexity in terms of semantic decomposition, what counts is ‘conceptual complexity’: ‘freeze’-type meanings are associated with a noncausal ‘conceptual stereotype’, while ‘break’-type meanings are associated with a causal stereotype. But the status of such a ‘stereotype’ and the way in which it causes the form asymmetries is quite unclear.
Quite a few other authors have invoked a related principle, which also relies on a close link between form and meaning:
(8) The basic–derived form–meaning parallelism principle
Derived meanings are expressed by derived forms, i.e. by forms containing more coding material, or at least not less. Formal and semantic derivation cannot go in opposite directions.
Most earlier work on causal–noncausal verb alternations is concerned not with cross-linguistic trends, but with elegant language-particular description (‘formal analysis’), which typically involves formulating rules that derive one verb from the other one. For example, Levin & Rappaport Hovav (Reference Levin and Hovav1995) argue that in ‘break’-type verb pairs, the causal member is basic and the noncausal member is derived, and in support of this they cite the fact that noncausal ‘break’ needs a special anticausative marker in many languages.Footnote 14 They thus also make a claim about languages in general (not just about English), and they presuppose that overt coding should reflect the derived nature of the meaning. Similarly, Piñón (Reference Piñón, Hastings, Jackson and Zvolenszky2001) seems to presuppose that derived forms should ideally be morphologically more complex, when he says that we want an analysis that ‘respects the morphological facts’. And Schäfer (Reference Schäfer2009: 662–663) says that theories assuming a noncausal-to-causal derivation ‘can easily account for’ causative morphology, while they ‘are challenged by languages that mark (a subset of) their anticausative alternants, as these are assumed to be basic, not derived’.
Thus, form–meaning parallelism seems to be widely assumed, though often implicitly. If we are right that it is primarily form–frequency correspondence that is responsible for overt coding elements in grammar, this may well mean that some of the proposed language-particular analyses will have to be adapted or rethought, at least to the extent that they rely on form–meaning parallelism.Footnote 15 But as we made clear earlier, we will not be concerned with elegant analysis of particular languages, and restrict ourselves to accounting for the cross-linguistic patterns.
Form–meaning isomorphism could plausibly be explained in terms of the general principle of iconicity, but form–frequency correspondence also has a very general explanation in terms of coding efficiency. Frequently used meanings require less expression effort than rarer meanings in any efficient information-conveying system. For example, local phone numbers are usually shorter than numbers for long-distance calls, which is efficient because local numbers are dialed more often. In the case of human language, length of coding is closely related to predictability: Hearers can afford to use shorter expressions for more predictable meanings, and more frequently expressed meanings are automatically more predictable. Thus, we can clearly identify a causal mechanism that is responsible for the principle in (5) above:
(9) Causal mechanism responsible for the grammatical form–frequency correspondence principle
Frequency causes predictability, which causes short form: In human language, there are recurrent diachronic mechanisms which create patterns in which short forms are used for frequent meanings because of their predictability.
The crucial role of diachronic change was recognized by Zipf (Reference Zipf1935) and is discussed in some detail in Haspelmath (Reference Haspelmath and Good2008b). The simplest cases are examples of abbreviations, which tend to replace full forms in proportion to the frequency of use. Abbreviations are a relatively novel (and often writing-based) mechanism, but similar processes are constantly at work throughout the language system. Thus, when a noncausal verb develops in a language that does not fit form–frequency correspondence, there is some pressure (be it ever so slight) on speakers to modify the pattern. For example, the Latin verb fundere ‘pour’ gave rise to French fondre, which came to mean ‘melt’ at some point.Footnote 16 Originally it must have referred only to causal melting (of metal), so noncausal melting was expressed by se fondre (using an anticausative form). Then it was extended to other kinds of melting, specifically to melting of ice, and since in this sense we talk more about noncausal melting than about causal melting, the frequency asymmetry now contradicted form–frequency correspondence. As a result, French speakers increasingly used fondre (without anticausative se) also for noncausal melting, and for causal melting, the new causative faire fondre (‘make melt’) has become quite common. These changes were presumably introduced because they make speaking and understanding more efficient. The change has been going on over many centuries and is not complete yet, but the trend is clear: Following a drastic semantic change, there is pressure to bring the coding type in line with the usage frequency.
The relationship between coding types and frequency is thus not direct, but mediated by lengthy and complex diachronic changes which maintain the efficiency of the system. As a result, coding efficiency is only a general tendency which requires a quantitative cross-linguistic approach to be recognized.
4. Twenty causal–noncausal verb pairs and seven languages
Now in order to test our hypothesis that the coding type of causal–noncausal alternations is determined by the frequency of occurrence of the causal and the noncausal members of the pairs, we need to look at usage frequencies of a representative set of verbs in a representative set of languages. We have chosen to examine twenty verb pairs in seven languages.
The 20 verb-pair meanings are given in (10).Footnote 17
(10) boil, freeze, dry, wake up, go out/put out (fire), sink, melt, stop, turn, burn, fill, rise/raise, improve, rock, connect, gather, open, break, close, split
The seven languages are English, Japanese, Maltese, Romanian, Russian, Swahili and Turkish. They were partly chosen for the practical reason that we had access to corpora of these languages. These seven languages are of course not fully representative of the world's languages: Three of them are Indo-European, and five of them are spoken in Europe, so not all regions and families are represented equally. But they are quite diverse in their coding types (as shown in Table 5 below), and we think that these data suffice for an initial demonstration of our claim. We make the assumption that people tend to talk about more or less the same kinds of basic topics, and it is therefore not expected that languages differ significantly in the usage frequencies of comparable expressions. In all languages, ‘head’ will generally be more frequent than ‘knee’, ‘say’ will be more frequent than ‘wash’, and ‘big’ will be more frequent than ‘soft’, due to some aspects of human nature or the way the world is. Thus, as long as the meanings are not culture-specific or specific to the physical environment of its speakers, a truly balanced sample of languages is not necessarily required to demonstrate universal frequency trends.
In order to test our hypothesis regarding frequency of use, we appealed to language corpora consisting of at least several million words, and wherever possible including both spoken and written linguistic samples. As always, the goal of representativeness is both an important and also partly unattainable one (how does one find a sample that represents linguistic output from every speaker, across all time and all linguistic modalities?). We hope that the surprisingly consistent results of our comparative study will be seen as confirmation for the soundness of our decisions.
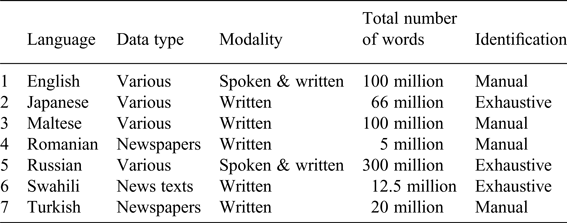
Due to practical considerations, we opted for two different methods of coding the data. In some languages, distinct verb forms are used for causal and noncausal members and these could be identified by simple but exhaustive searches of entire corpora. In other languages, the same verb forms can be used in both causal and noncausal constructions and the only way to disentangle the two is through careful manual checking. Hence for three languages, namely Japanese, Russian and Swahili, it was possible to look at all the occurrences of the causal and noncausal members of the pairs in the entire corpus and conduct exhaustive searches. However, for the remaining four languages, English, Maltese, Romanian and Turkish, causal and noncausal members of the pairs had to be extracted manually, so we limited our counts to the first 50 instances of each verb pair, assuming that these verb sets would be representative (see more details about this decision at the end of Section 6).
The sources of our corpora are given in Appendix A, and Appendix B shows the results for each verb in each of the seven languages. Table 2 above lists the languages included, type of data sampled, total word counts, and how the causal and noncausal verbs were identified (either exhaustively, by automatic search for all forms, or manually, by analyzing the first relevant 50 examples).
Languages and corpus data.
5. Predictions
The form–frequency correspondence principle in (5) above is stated in very general terms, and a number of specific testable predictions can be derived from it. We can test form-to-frequency predictions (overtly coded verbs should be less frequent) or frequency-to-form predictions (more frequent verbs should have less coding). And we can either look at individual verb pairs and individual languages, or aggregate the available cross-linguistic data, allowing us to quantify and compare general trends.
Linguists most often work on individual languages, and they often consider individual items. Thus, we could test the individual-language prediction in (11):
(11) Prediction 1 (form-to-frequency, no aggregation)
In each language, in a causative verb pair, the causal member will be rarer than the noncausal member, while in an anticausative verb pair, the causal member will be more frequent than the noncausal member.
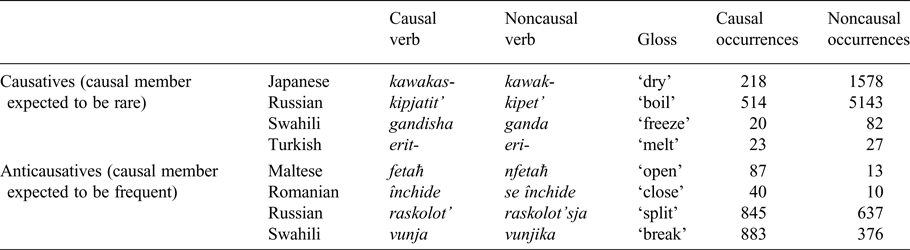
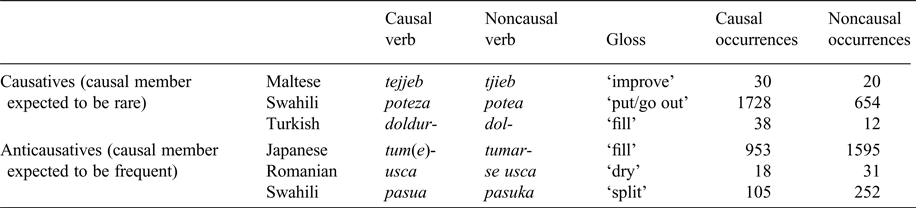
But at the level of individual verb pairs, there are not only many confirming cases (as in Table 3), but also many disconfirming cases (as in Table 4). The figures in these tables are absolute numbers from our corpus studies (see Appendix B for full data).
Some verb pairs confirming Prediction 1.
Some verb pairs disconfirming Prediction 1.
Thus, if one is concerned primarily with the study of individual languages, it is easy not to see any regularities here, especially as there are some languages that have no confirming cases (such as English, which has no causative or anticausative pairs for our 20 verb meanings), and some languages that have more disconfirming than confirming cases (such as Romanian, as discussed below).
But recall that the form–frequency correspondence principle is stated as a tendency, and such tendencies are often easier to see by using aggregated data from a range of languages, which we can take to measure cross-linguistic trends. This has several advantages.
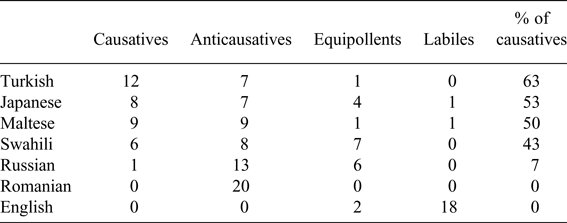
The advantage of aggregating coding types (causative vs. anticausative coding) across languages is that the effect of language-particular macro-types is eliminated. In individual languages, such macro-types can override the frequency effects. For example, Romanian codes ‘dry’ as an anticausative pair (usca/se usca, see Table 4), which goes against Prediction 1, but this clearly has to do with a language-particular macro-type: Romanian has a strong preference for coding causal–noncausal pairs by means of anticausatives using the morpheme se. Conversely, Turkish has a general preference for causative coding, and from this perspective it is not surprising that ‘fill’ (doldur-/dol-, see Table 4) is coded as a causative pair. Such language-specific macro-types are found in many domains of grammar, and they give each language its specific character or ‘genius’. Table 5 above shows that our seven languages differ considerably in their preference for causatives, anticausatives and others: The table ranks the languages by their causative prominence, i.e. the proportion of causatives among those verbs that occur in a causative or an anticausative pair (equipollents and labiles are disregarded for this measure).
Different coding type trends in the seven languages.
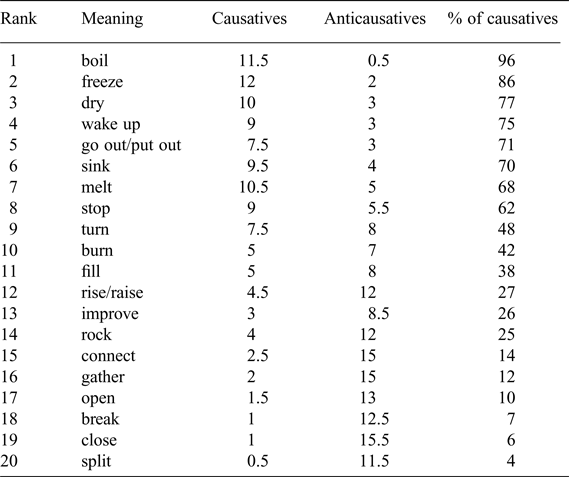
Macro-types interfere with the attempt to identify cross-linguistic frequency-based trends, but if we aggregate the coding types across languages, this gives us a measure of the general preference for causative and anticausative coding for each verb meaning. The aggregated data from 21 languages (from Haspelmath Reference Haspelmath, Comrie and Polinsky1993: 104) are given in Table 6,Footnote 18 which ranks our 20 verb meanings in (10) by causative prominence (again, this refers to the proportion of causatives among those verbs that occur in a causative or an anticausative pair, disregarding other kinds of pairs).
Twenty verb meanings ranked by causative prominence.
Note: Data from 21 languages, from Haspelmath (Reference Haspelmath, Comrie and Polinsky1993). If a language has two counterpart verb pairs which behave differently, each counterpart pair counts 0.5, so that the numbers are not always integers.
We thus see that different core-events are associated with quite different coding preferences. Some core-event meanings are very causative-prominent, others (such as ‘split’, ‘close’, ‘break’) are very anticausative-prominent, while still others occupy the middle ground.
In addition to aggregating the coding types, we can also aggregate the corpus frequencies. One advantage of this is that in this way we can measure the general likelihood that a causal or a noncausal verb will be used for a given core-event, regardless of its coding. After all, a skeptic could reject the frequency-causes-form explanation (of (9) above) and claim that the direction of causation is different: Longer forms are rarer because they are longer, and it is more economical to use shorter forms, so these tend to be more frequent. This reasoning is not absurd,Footnote 19 but if we aggregate the frequencies across languages, we reduce the possible effect from this interfering factor. Another advantage, which is probably even more important, is that the frequency-causes-form explanation really requires generalized frequencies, rather than the frequencies of the items whose form is to be explained. As we saw at the end of Section 3, the mechanism that creates short forms for frequent expressions is a lengthy process of diachronic change. The frequencies that are responsible for the current patterns of languages are not the current frequencies, but the frequencies at the time when the current patterns were created. But we cannot measure the earlier frequencies, so the only way to proceed is to use generalized frequencies (as was already done by Greenberg Reference Greenberg1966, where frequency counts from Sanskrit and Latin were used to explain world-wide trends). The aggregated corpus frequencies will be presented in Section 7 below. On the analogy of the notion of causative prominence for meanings which are often expressed by causative pairs, we can speak of (non)causal prominence for verb meanings in which the (non)causal use is frequent.
With these two aggregated measures, we can make three further predictions:
(12) Prediction 2 (form-to-frequency, only form aggregated)
In verb meanings which are often expressed as causative pairs (verb meanings with high causative prominence, high on Table 6), the causal member will be rarer than the noncausal member in each language, while in verb meanings which are often expressed as anticausative pairs, the causal member will be more frequent.
(13) Prediction 3 (frequency-to-form, only frequency aggregated)
Verb meanings in which the causal member is rarer (verb meanings with low causal prominence, see Table 9 below) will tend to be coded as causative pairs in each language, while verb meanings in which the causal member is more frequent will tend to be expressed as anticausative pairs.
(14) Prediction 4 (both form and meaning aggregated)
Verb meanings with high causative prominence will exhibit low causal prominence, i.e. in verb meanings which are often coded as causatives across languages, the causal member will tend to be rare across languages. And conversely, verb meanings with low causative prominence will exhibit high causal prominence.
These predictions will be discussed further in Section 7 below, where we present the full results from our corpus studies.
6. Corpora and coding decisions
Before moving on to discuss the results obtained, it is worth outlining some of the decisions which needed to be made in order to obtain the frequencies in the case of the manual counts. The decisions fall into two categories: (i) decisions regarding the form of the verbs involved, and (ii) decisions regarding the meaning of the forms identified. We discuss each type in turn.
First, we limited ourselves to verbal formsFootnote 20 and excluded adjectival or nominal uses of our intended verbs (see examples in (15a–d) below). The reason for this was that nominalized and adjectival forms are ambiguous with respect to whether the verb is used causatively or not.
- (15)
(a) English … each morning she asked for boiled rather than scrambled eggs for breakfast.(BNC)
(b) Maltese [Il-bozza] ilha diġà ġimagħtejn tkun mixgħula matul il-ġurnata u mitfija bil-lejl.
‘For the last two weeks [the bulb] was on during the day and off (=put out) at night.’ (MLRS)
(c) Romanian Pentru as se evita crăparea peretelui, este preferată folosirea
holtzsuruburilor.
‘In order to avoid [lit.] the splitting of the wall, it is preferred the use of the metal screws.’ (RCNA)
(d) Turkish Ankara´da toplanan 150 bin işçi hükümeti ve siyasileri uyardı.
‘150.000 workers, gathered in Ankara, warned the government and the politicians.’ (Milliyet)
Passive uses of the verbs were generally included and coded as causative uses, as exemplified in (16a–c), since the situation is presented as having been caused by an external agent (and sometimes this agent is also coded).
- (16)
(a) English The great library of Alexandria was burnt by Christians; in A.D. 411.
(BNC)
(b) Maltese Kull ammont dovut għandu jinġabar mill-awtorità kompetenti.
‘Any amounts due must be gathered/collected by the authorized authority.’
(MLRS)
(c) Romanian De la Bucureşti, cele două tone de cartoane de joc care se adună săptămânal sânt aduse la distrus şi topit.
‘From Bucharest, the two play cartons that are rounded up weekly are brought to be destroyed and melted.’
(RCNA)
(d) Turkish Gemi İstanbul Boğazı´ndan geçerken durduruldu.
‘Ship was stopped while passing the Bosphorus.’
(Milliyet)
While, in many cases, there is a formal distinction between the passive form of a verb and its adjectival form in a construction following a copula, e.g. compare The door was opened (passive, the door was opened by someone) vs. The door was open (attributive construction involving the copula ‘be’ and the adjective ‘open’), this is not always the case for every verb in our sample. Cases where the two constructions were difficult to disentangle due to the lack of a morphological distinction, see the range of examples in (17a–c), were excluded from the analysis, as were any other examples where it was difficult to ascertain whether the verb was used causally or noncausally.
- (17)
(a) English On this occasion I was frozen by anger and fear.
(BNC)
(b) Romanian Şi fiind seară, în ziua aceea, întâia a sămptămânii (duminică), şi uşile fiind încuiate, unde erau adunaţi ucenicii de frica iudeilor, a venit Iisus şi a stat în mijloc şi le-a zis: Pace vouă!
‘And being evening, on that day, the first of the week (Sunday), and the doors being closed, where the workers were gathered due to the fear of the Jews, Jesus came and sat in the middle and said to them: Peace onto you!’
(RCNA)
(c) Turkish … dün toplanan komisyona ifade verdi.
‘[He] declared to the commission gathered yesterday.’
(Milliyet)
This brings us to the second type of decision made, namely one regarding meaning. We only considered examples where the verb under investigation was used with NP arguments (i.e., not including sentences like We stopped wanting a new car). Our goal was to code first and foremost uses of the verbs which preserve the physical aspect of the action, that is, (physical) boiling, (physical) burning and so on, not idiomatic or metaphorical extensions of such uses.
However, as it is next to impossible to draw a neat line between concrete, physical uses of a verb and its idiomatic extensions, we included the latter, so long as they were extensions of the original meaning, rather than uses which no longer preserved any aspect of the physical sense. We also thought that the metaphorical uses of the verbs might tell us something about how the verb is used or conceptualized most saliently in the speakers' minds – causally or noncausally, depending on which type of use would be increasingly extended via metaphor. Thus, any new meanings that were not transparently related to this physical sense were excluded from the analysis, hence we allowed examples of the type in (18a–e), but not of those in (19a–e).
- (18)
(a) English But, if an error of judgement or a bad decision has been made, the vital thing is to recognise that, admit it and take immediate action to break the chain of events while a safe course of action is still possible.
(BNC)
(b) English The words took time to sink in;Footnote 21 to herself as much as to the rest.
(BNC)
(c) Maltese … ħaraqni meta bagħatli SMS bil-mistoqsija.
‘He burnt ( = angered) me when he texted me the question.’
(MLRS)
(d) Romanian Nu bea, nu fuma, femeile se topeau după el.
‘[He] didn't drink, didn't smoke, the women melted after him.’
(RCNA)
(e) Turkish Gençlerbirliği her nedense bu skordan sonra uyandı.
‘Gençlerbirliği woke up after this score for some reason.’
(Milliyet)
- (19)
(a) English And then Woodleigh's secretary even came out last week, so I gather.
(BNC)
(b) Maltese … jekk hemmx xi ħsieb li jitwaqqaf business centre fit- teknoloġija tal-informatika u l-innovazzjoni f'Għawdex.
‘… whether they plan to stop [ = found, set up] a business centre for information technology and innovation in Gozo.’
(MLRS)
(c) Romanian Bogdan s-a legat cu lanţuri de piciorul statuii lui Mihail Kogălnicianu din Capitală.
‘Bogdan tied himself up [se lega also means ‘connect’] with chains to the leg of the statue of Mihail Kogălnicianu in the capital [city].’
(RCNA)
(d) Romanian Ilinca închide telefonul.
‘Ilinca puts down [închide also means ‘close’] the phone.’
(constructed example)
(e) Turkish O son rekorunu da giderken kırdı.
‘He broke his last record while leaving.’
(Milliyet)
However, it seems quite likely that alternative decisions would not have affected the results much. Note that for the three languages that were not coded manually (Japanese, Russian, Swahili), we did include all occurrences of the verbs, regardless of their readings.
Our coding decisions reflect our desire to include as much of the data in the corpus as possible. We felt that such a conservative approach would better mirror the frequency tendencies of the verbs investigated. We limited ourselves to 50 uses of each verb once we convinced ourselves that appealing to 100 uses of 10 of our 20 verbs in Romanian and Maltese gave the same results (hence some of the results in Appendix B for Romanian and Maltese add up to 100 examples, whereas others to 50 examples).
7. Results
In this section, we present the results of our corpus study, the tests of the predictions of Section 5. The full data for all 140 verbs (twenty verbs from each of the seven languages) with verb forms, coding type and frequencies extracted are presented in Appendix B.
Let us first look at Prediction 1, repeated here from Section 5:
(11) Prediction 1 (form-to-frequency, no aggregation)
In each language, in a causative verb pair, the causal member will be rarer than the noncausal member, while in an anticausative verb pair, the causal member will be more frequent than the noncausal member.
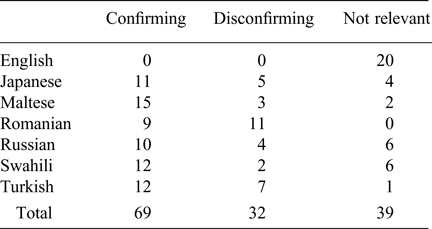
In the last column of Tables A1–A7 in Appendix B, we have indicated for each verb pair whether or not it matches Prediction 1. Table 7 summarizes the data. We see that a clear majority of verb pairs conform to the prediction. Independently of our work, Heidinger (Reference Heidinger2012) tested Prediction 1 for 16 verb pairs in a large French corpus (including a total of 3347 occurrences) and found it strongly confirmed. In addition, Narrog (Reference Narrog, Tsunoda, Sasaki and Shioya2007) tested the prediction for 224 Old Japanese verb pairs, and Narrog, Pardeshi & Sanada (Reference Narrog, Pardeshi and Sanada2014) tested it for over 300 Modern Japanese verb pairs and found it confirmed as well.
Number of verb pairs confirming and disconfirming Prediction 1.
This is encouraging, but recall from Section 5 that there is no direct causal link from language-particular frequencies to language-particular coding types. On the basis of our diachronic explanation in (9) above, we do not actually want to make the very strong Prediction 1. Due to the existence of macro-types, we find many disconfirming verbs, such as those listed in Table 4 above. And Romanian and English are two languages that do not show language-internal evidence for the hypothesis.
The macro-types are a strong interfering factor also for Prediction 3, where frequency is aggregated, but form is not. For this reason, we do not test this prediction in this paper. (The interested reader can easily work out to what extent it is fulfilled.) Instead, in the following we focus on Predictions 2 and 4. Prediction 2 is repeated below.
(12) Prediction 2 (form-to-frequency, only form aggregated)
In verb meanings which are often expressed as causative pairs (verb meanings with high causative prominence, high on Table 6), the causal member will be rarer than the noncausal member in each language, while in verb meanings which are often expressed as anticausative pairs, the causal member will be more frequent.
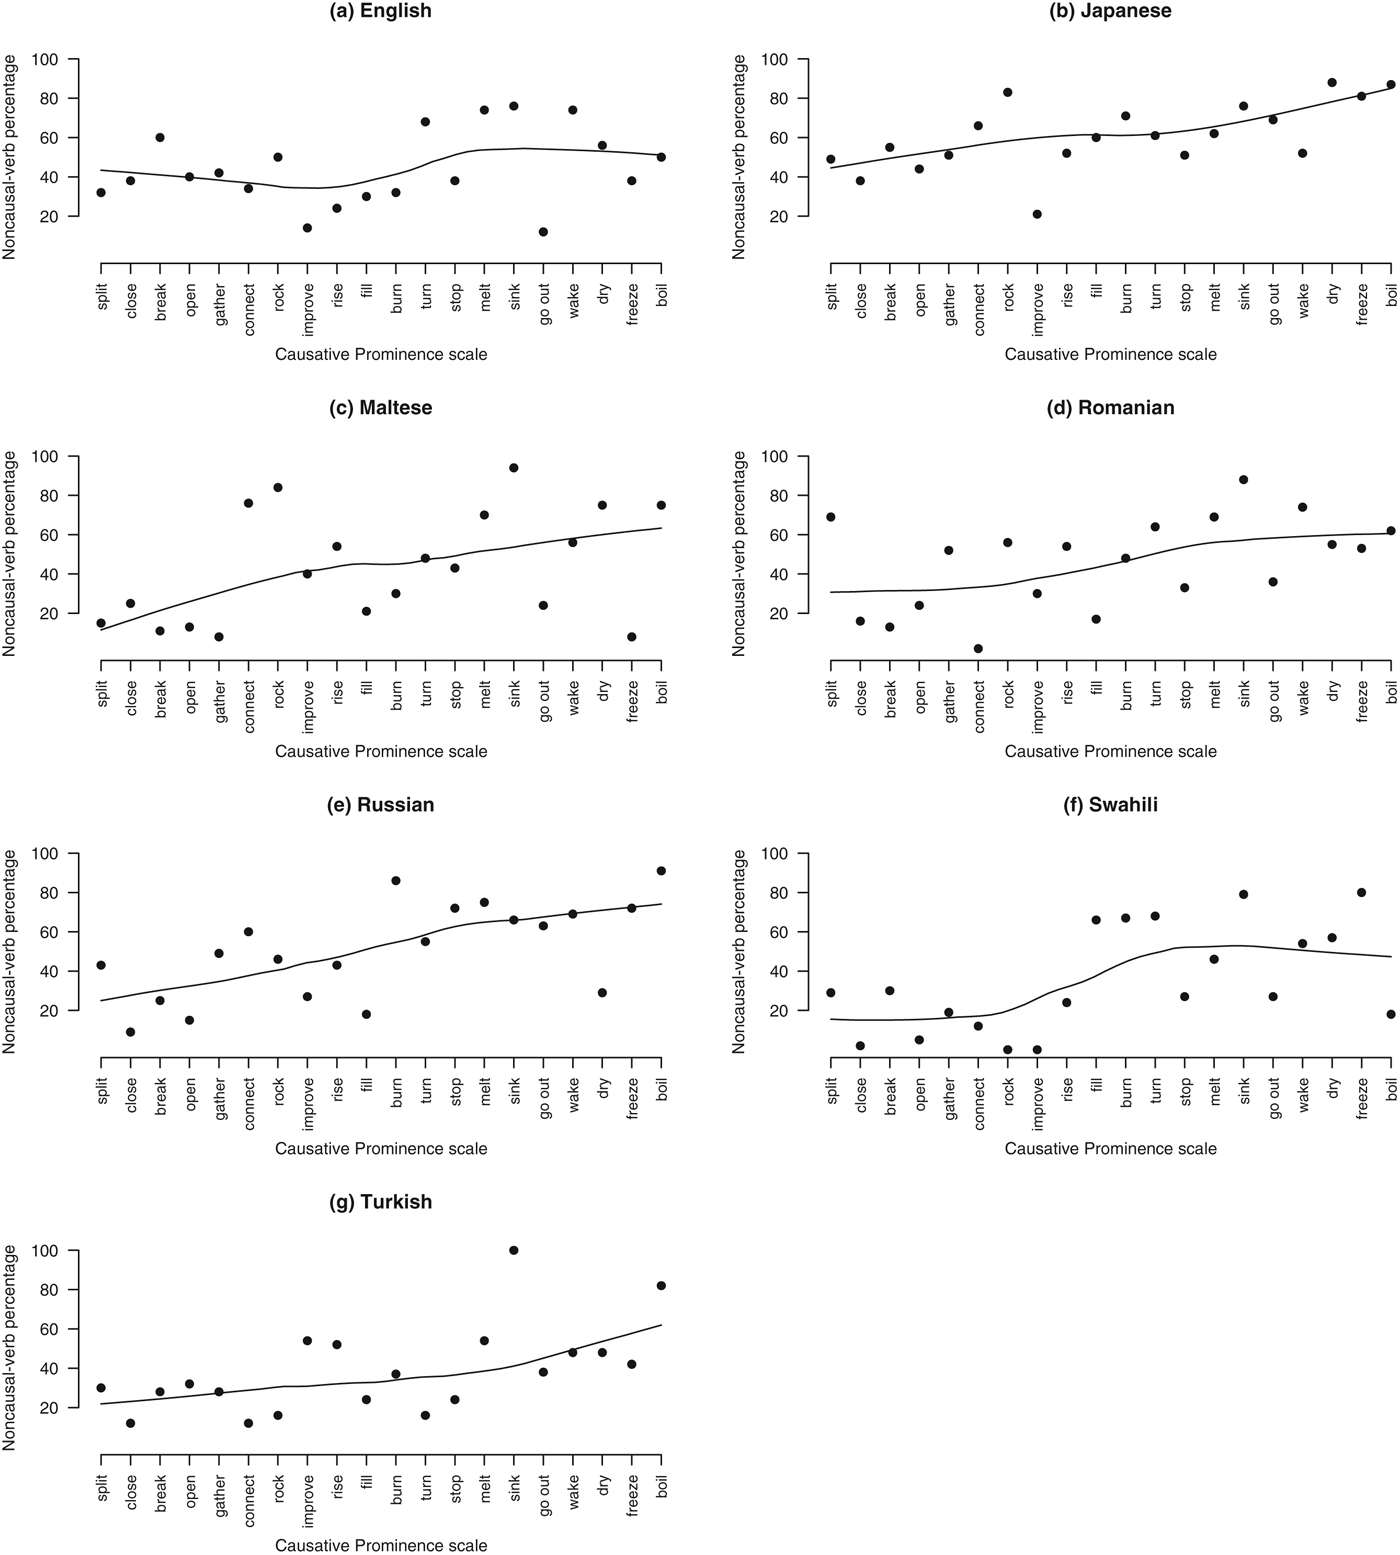
Figures 1(a–g)Footnote 22 are plots for each language that show the percentage of noncausal verbs for each of the 20 verb pairs of our verb sample. We see that in six of the seven languages, there is a tendency for verb pairs with higher causative prominence to occur more frequently as noncausals: The trendline is going up in all seven languages. There is only one trendline where there are noticeable deviations from the general pattern observed, namely English.
Smoothed scatter plots of the causalness ratio for each language ((a)–(g)). The x-axis shows the ordering of the twenty verbs, from least causative prominent to most causative prominent (see Table 6). The y-axis shows the noncausal prominence, i.e. the ratio of noncausal use versus total use of each verb ( = noncausal/(causal + noncausal)).
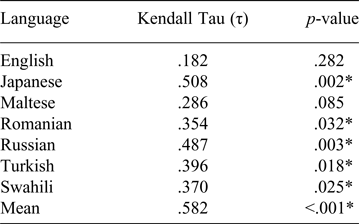
In order to see whether the trends observed were statistically significant, we performed a number of tests, as detailed below. We used the Kendall Tau (τ) Rank test to check whether the trend lines observed for our languages are similarly ordered or not. This nonparametric test provides a Tau value (τ), which is between –1 and +1 (with –1 signalling a decreasing trend, and +1 signalling an increasing trend, and 0 signalling an absence of a trend), and an associated p-value outlining how sure we can be of its significance. The results are given in Table 8 above.
Kendall Tau Rank tests for the seven languages and their mean.
Note: In order to be able to calculate the Kendall Tau value, we filled in one missing value in our twenty items from means across the other languages in our sample for English go out/put out.
All of our seven languages give positive Tau values, which are generally associated with highly significant p-values (exceptions are Maltese, where the p-value is borderline significant, and English). However, if we exclude the verb ‘freeze’ in Maltese, τ = .404, p = .017. (‘Freeze’ is also exceptional in Samardžić & Merlo's (Reference Samardžić and Merlo2012) findings.)
We also tested the meanFootnote 23 values for the twenty verbs investigated across our six languages and it has a Tau score of .747 indicating a strong positive trend, and a very significant associated p-value.
Next, we performed a Principal Component Analysis in order to identify patterns in the data and to see how many dimensions would be required in order to capture the data, without losing much information. The Principal Component Analysis shows that the first principal component explains 48% of the variation and it is the only one with an eigenvector greater than one. This means that one dimension is sufficient to capture the data, while the other factors essentially amount to random variation. Further support of this comes from the fact that the first principal component factor is 70% correlated to the mean of the language values for the twenty verbs (p < .0001).
Thus, the corpus data from the seven languages support Prediction 2 to a very large extent. Independently of the present study, Samardžić & Merlo (Reference Samardžić and Merlo2012) tested Prediction 2 for English on the basis of a much larger corpus (the Europarl corpus, which contains 1.5 million sentences) and found it very strongly confirmed for their data (correlation score r = .77, p < .01).
Next we turn to Prediction 4, repeated here:
(11) Prediction 4 (both form and meaning aggregated)
Verb meanings with high causative prominence will exhibit low causal prominence, i.e. in verb meanings which are often coded as causatives across languages, the causal member will tend to be rare across languages. And conversely, verb meanings with low causative prominence will exhibit high causal prominence.
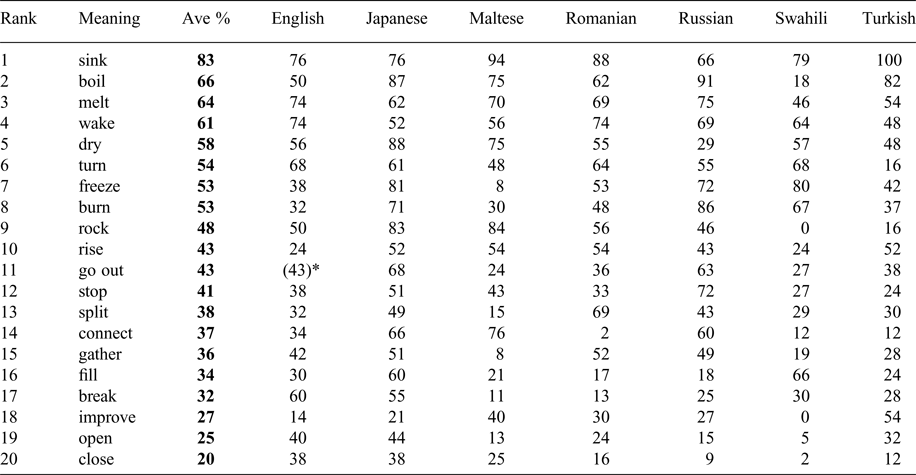
To test this prediction, we had to aggregate the frequencies. We did this by averaging the percentages of causal uses across our seven languages.Footnote 24Table 9 (next page) shows the twenty meanings ranked by percentage of noncausal uses (from highest to lowest).
We also checked at this point that the average percentages still agreed significantly with each of the language-internal rankings in order to make sure that no one language deviated significantly from the average (all Kendall Tau tests between the average frequency scale and the individual languages had at least τ > .390, p < .019).
Twenty verb meanings ranked by average noncausal prominence ( = average percentage of frequency of the noncausal member).
* This figure is calculated by averaging the percentages in the other six languages, because we could not obtain a figure of use for go out in English.
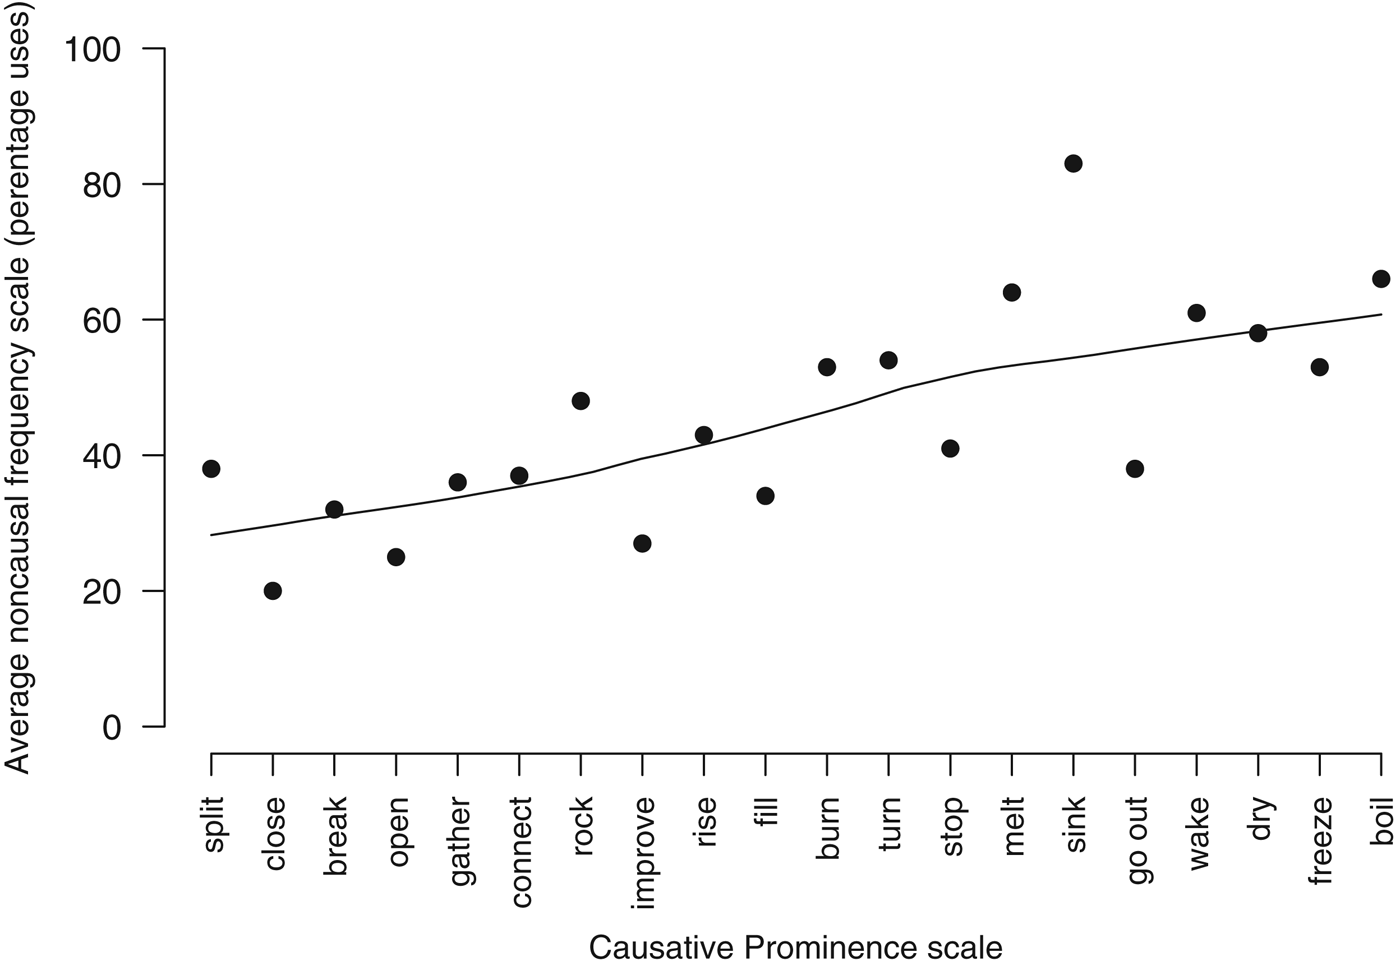
Next, the noncausal prominence scale obtained was compared to our causative prominence scale. Figure 2 below gives the graphical representation of these two scales, showing that there is a close match between them, i.e., verbs which scored high on the average frequency-of-use scale also scored high on the causative prominence scale. As before, we verified the statistical significance of this correlation with the Kendall Tau test, which gives a highly significant result: τ = .653, p < .001. Thus, Prediction 4 is very strongly confirmed as well.
Smoothed scatter plot of the relationship between the average frequency scale and the causal prominence scale (average causal-verb proportion). The x-axis shows the ordering of the twenty verbs, from least causative prominent to most causative prominent. The y-axis shows the average frequency of use (percentage) of the noncausal member (average noncausalness) in the corpora.
We conclude that form–frequency correspondence is a strong effect in the seven languages and the 140 verb pairs that we examined, and we take it to support our explanation in terms of frequency, predictability and efficient coding.
8. Partial vs. full explanation
In addition to showing clear cross-linguistic trends, our frequency data of Section 7 also show a lot of ‘noise’, i.e. unpredicted deviations from the expectations. Linguists are used to explanations that cover 100% of the facts, rather than explanations that only cover part of the data. They usually ask: What explains the rest of the data?
Our answer is that we do not know, but neither did we expect to be able to explain all formal patterns in all languages with a single general principle. The formal coding of meanings by languages depends on a wide variety of factors, including many historical accidents. By and large, languages maintain a balance of coding efficiency and tend to use short forms for frequent expressions and longer forms for rarer expressions. But this coding efficiency comes about as the cumulative effect of a highly diverse set of diachronic adaptive changes, not by any kind of system necessity. Deviations may arise for a variety of reasons, especially semantic change, which is independent of the form of the expression. A word with a specialized meaning may acquire a general meaning and thus become highly frequent without losing its longer form right away (or vice versa, acquire a specialized meaning and become rarer). Examples are the English words information, development and particularly, which are nowadays extremely frequent (at least in formal written language), but have a fairly long form, reflecting their earlier much more specialized meanings. Another factor is cultural change: Words like yoke or louse are nowadays rare, but have not become longer. Frequency distributions can change much more quickly than forms of words. Over time, the balance is likely to be re-established, but speakers are very conservative with respect to language form, so that form–frequency correspondence is not perfect.
Moreover, it should be kept in mind that the ranking of the 20 meanings of Table 1 above in terms of (anti)causative prominence is tentative, as it is not based on a fully representative set of languages. We expect that if a more representative sample of languages is chosen to determine anticausative prominence, the amount of data that is predicted will increase (though it will never approach 100%).
A prominent work that differs from our approach in that it has the ambition to account for all cases in principle is Levin & Rappaport Hovav (Reference Levin and Hovav1995). Let us briefly look at their (ultimately meaning-based) attempt to come to grips with the cross-linguistic diversity of causal–noncausal coding. They propose that break (intr.) is derived from break (tr.) by a rule that eliminates the causer in some way. Although they do not discuss languages other than English in any detail, they expect that the same is true for other languages, so they expect all change-of-state verbs to show anticausative coding if the alternation is overtly marked (and is not labile or equipollent).
In addition to ‘break’-type verbs, they also discuss verbs like ‘blossom’ or ‘decay’, which cannot readily be used transitively in English, so they assume that these are fundamentally intransitive, and if they are to be used transitively, they need to undergo a causal-verb formation process. The contrast between ‘break’ and ‘blossom’ is ascribed to a difference in meaning: ‘Break’-type verbs express externally caused events, while ‘blossom’-type verbs express internally caused events, i.e. in the latter type of event, ‘some property inherent to the argument of the verb is “responsible” for bringing about the eventuality’ (Levin & Rappaport Hovav Reference Levin and Hovav1995: 91). It is thus predicted in general that causative verb pairs should have an internally caused core-event, and anticausative verb pairs should have an externally caused core-event. If this is correct, then form–meaning parallelism can be maintained.
This is an interesting and very clear prediction, but does not match the cross-linguistic data, as causative pairs expressing externally caused events are not uncommon.Footnote 25 Levin & Rappaport Hovav (Reference Levin and Hovav1995) are aware of this, but they still hope that their meaning-based account of English will carry over to other languages. They stress that the meaning of a verb needs to be examined in detail, and they suspect that counterpart verbs in different languages, as they are determined in coarse-grained typological studies like Haspelmath (Reference Haspelmath, Comrie and Polinsky1993), may actually differ with respect to the crucial parameter of internal vs. external causation. Thus, a verb that is roughly translated as ‘melt’ could express an externally caused melting event (as when something is caused to melt by heating it), or it could express an internally caused melting event (as when something melts without any external influence from heat). Only detailed language-particular analysis will tell whether it is internally or externally caused:
It is likely that this cross-linguistic variation arises because the meaning of a verb such as ‘melt’ is consistent with its describing either an internally or an externally caused eventuality. In fact, it should be possible to verify this prediction by looking at the range of subjects found with ‘melt’ in various languages; presumably, in languages where ‘melt’ is internally caused, it will only be found with ice or ice cream or other substances that melt at room temperature as its subject when intransitive. (Levin & Rappaport Hovav Reference Levin and Hovav1995: 100)
In Haspelmath's (Reference Haspelmath, Comrie and Polinsky1993) sample, there are ten languages with a causative pair for ‘melt’, so all these should be internally caused, and hence incompatible with substances that do not melt at room temperatures. Six of them are listed in (20).
(20) Causative pairs for ‘melt (intr.)/melt (tr.)’ (from Haspelmath Reference Haspelmath, Comrie and Polinsky1993)
French fondre/faire fondre
Finnish sulaa/sula-ttaa
Turkish eri-mek/eri-t-mek
Hindi-Urdu pighal-naa/pighl-aa-naa
Indonesian mencair/mencair-kan
Hungarian olvad/olvasz-t
At least in Finnish and Hungarian, it is possible to use the causative (sula-ttaa, olvasz-t) also with melting of wax, which requires a higher temperature (and thus some external causation), thus disconfirming the prediction.
While we agree with Levin & Rappaport Hovav that it is often very fruitful to seriously look for semantic determination of grammatical phenomena, we think that the enormous amount of cross-linguistic variation in the domain of causal–noncausal alternations makes it very unlikely that a semantic explanation will be found for all cases. In many languages, it is clear that there are different historical layers; for example, in Modern Greek, anticausative pairs often represent borrowings from Ancient Greek (e.g. stréfo/stréfome ‘turn’), while native verbs tend to be labile (e.g. jirízo ‘turn’), and in Modern German, old pairs going back to Proto-Germanic (such as aufwachen/aufwecken ‘wake up’) tend to be equipollent, while newly formed pairs tend to be anticausatives (Haspelmath Reference Haspelmath, Comrie and Polinsky1993: 100). Thus, synchronic meaning is only one of the many factors determining the coding type of a particular verb.
9. Concluding remarks
We conclude that causative prominence of a causal–noncausal verb-meaning pair, as determined by studying form asymmetries across languages, correlates significantly with lower frequency of the causal member of the pair across languages. This is explained by our form–frequency correspondence principle in (5), which is itself explained by the tendency for languages to use efficient coding. When a long form becomes frequent, it tends to be shortened in language change, and when a short form becomes rare, it tends to become longer (Zipf Reference Zipf1935, Haspelmath Reference Haspelmath and Good2008b).
As we noted in Section 3 above, this conclusion should not be surprising at all, because form–frequency correspondences are extremely widespread throughout the grammatical systems of languages. Linguists have traditionally had a tendency to explain form contrasts by meaning contrasts, but language structure is ultimately grounded in the communicative needs of speakers and hearers, and here predictability plays a very important role: Predictable meanings can be expressed in shorter ways, or can be omitted, and frequently expressed meanings are predictable. This kind of coding efficiency is reflected not only in the direction of morphological derivation, but also in periphrastic and syntactic patterns: The reason why we say male nurse is not that the concept of a male nurse is more complex than (or derived from) the concept of a (female) nurse, but that it's less frequent and less predictable. Similarly, we say make someone laugh (rather than laugh someone), but there is no need to say that the causation meaning is somehow different here from the causation meaning in break something: make laugh is simply much rarer (and much less expected) than laugh, so using an additional form is an efficient way to express these meanings.
One question that is often asked when someone gives a form–frequency correspondence explanation is what causes the frequency differences, and whether it could not be that a third factor causes both frequency asymmetries and form asymmetries. However, we are not aware of any concrete proposal of a third factor that would provide a serious explanation of the coding asymmetries.Footnote 26
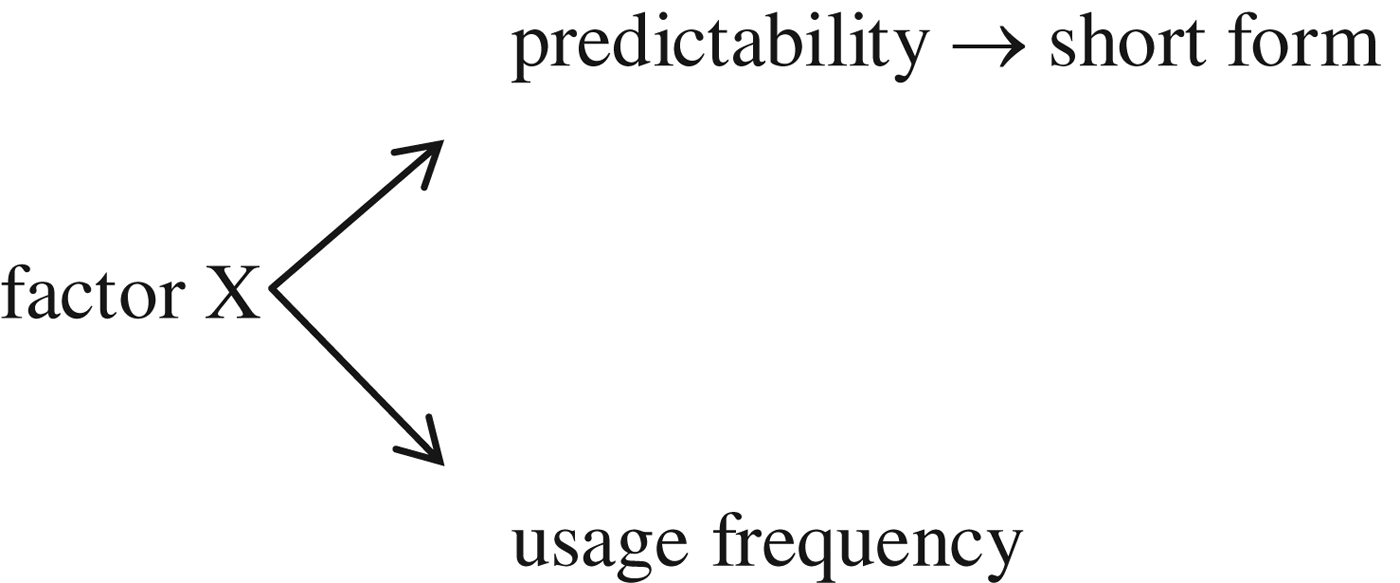
We offer no explanation for the frequency differences that we saw in Table 9 above, other than pointing out that it is intuitively plausible that events such as breaking and splitting which require a considerable input of force should be described more often in terms of a causer carrying out these actions, while natural events such as freezing, drying and melting should be described more often as occurring spontaneously. These differences can be described in terms of ‘spontaneity’ (recall note 16), but since there is no independent way of measuring the spontaneity of an event, we do not regard this as an explanation. However, for our account, this is not necessary: Frequency asymmetries have diverse causes, but uniform consequences. Whatever the reason for the greater frequency of a form may be, it is bound to be shorter because of its higher predictability and the greater efficiency of a language system that exploits this predictability. This is illustrated by the causal chain in Figure 3, where we included a ‘factor X’ that is responsible for frequency of use (but it plays no direct role in the explanation of language form).
Frequency causes predictability, which causes short form (see the formulation in (9) above).

A possibility that we do not want to discount entirely is that predictability could be caused by something else (a factor X), which also causes frequency of use, as illustrated in Figure 4.
Some factor causes both predictability and frequency.
Suppose factor X is real-world frequency: Since we know that drying happens more often spontaneously than under the influence of a causing agent, hearers can predict that speakers probably talk about noncausal drying and thus do not need a special anticausative marker to signal noncausal ‘dry’. This would be an example of a third factor causing both predictability (which causes short coding) and usage frequency. This would be compatible with the second part of Figure 3 above,Footnote 27 and, crucially, even on this alternative scenario, there is no role for form–meaning parallelism. We do not know a good way of measuring predictability independently of usage frequency, so currently we propose the scenario in (9) and Figure 3, but we look forward to further research that might throw light on the issue.
APPENDIX A
Corpus sources – additional information
English BNC, The British National Corpus, version 3 (BNC XML Edition). 2007. Distributed by Oxford University Computing Services on behalf of the BNC Consortium. http://www.natcorp.ox.ac.uk/.
Japanese NINJAL-BCCWJ, National Institute for Japanese Language and Linguistics, Balanced Corpus of Contemporary Written Japanese (http://www.ninjal.ac.jp/kotonoha/ex_8.html), as analyzed through the NINJAL-LWP (http://verbhandbook.ninjal.ac.jp/).
Maltese MLRS, Maltese Language Resource Server, http://mlrs.research.um.edu.mt/.
Romanian http://www.cse.unt.edu/~rada/downloads.html#romanian, see Mihalcea & Năstase (Reference Mihalcea, Năstase, Roth and van den Bosch2002).
Russian National Corpus of Russian, http://www.ruscorpora.ru/.
Swahili HCS 2004. Compilers: Institute for Asian and African Studies, University of Helsinki, and CSC – IT Center for Science.
Turkish Milliyet Newspaper Corpus, provided by Kemal Oflazer, originally compiled by Dilek Hakkani-Tür and Gokhan Tür during the course of their Ph.D. theses, see Hakkani-Tür (Reference Hakkani-Tür2000).
APPENDIX B
Data tables
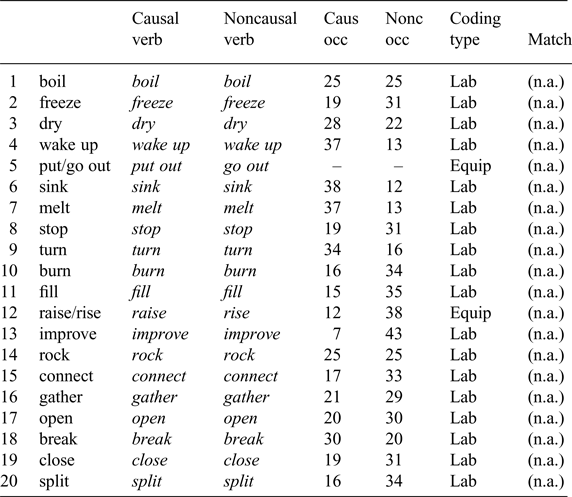
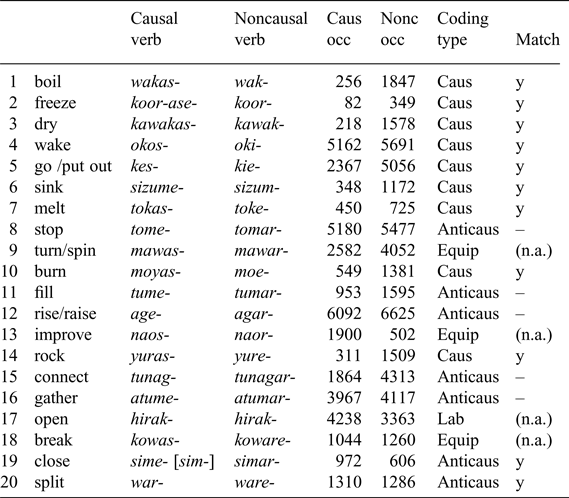
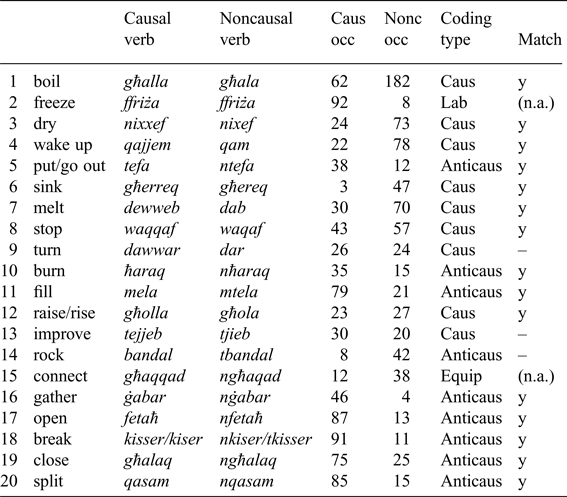
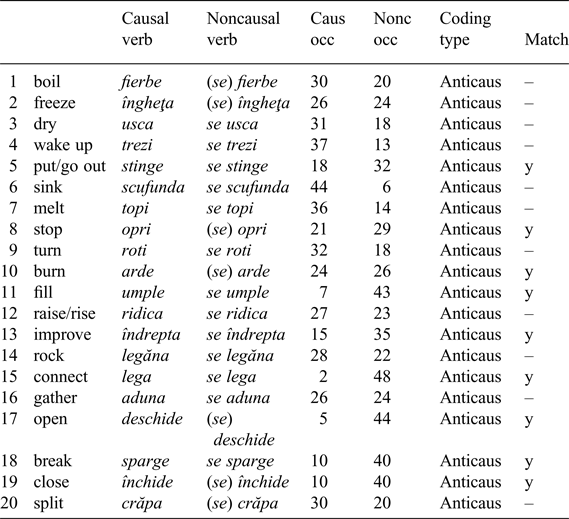
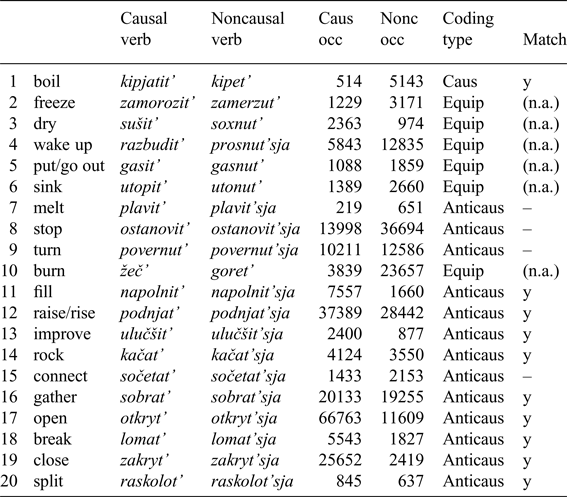
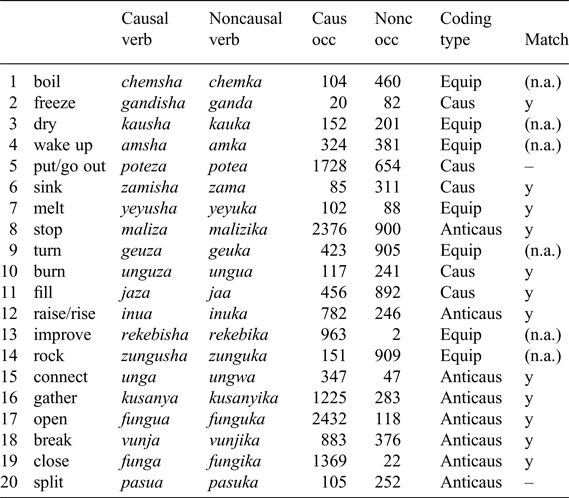
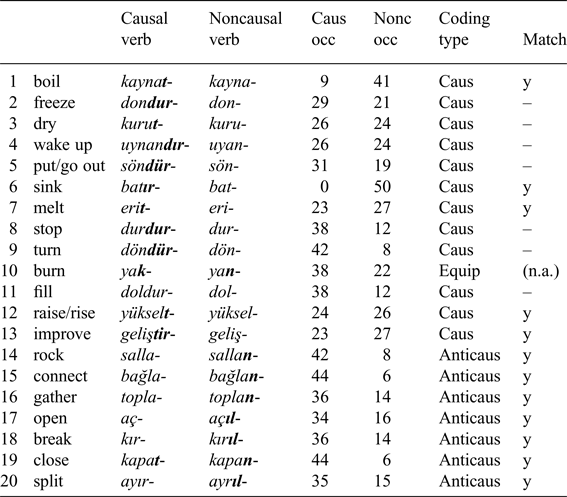
In Tables A1–A7, we give the causal and noncausal members of each pair, then the number of causal and noncausal occurrences in the corpus (caus occ, nonc occ), then the coding type (Caus(ative), Anticaus(ative), Lab(ile), Equip(ollent); recall Tables 1 and 5 in the main body of the paper). In the last column of the tables, we have indicated for each verb pair whether or not it matches Prediction 1 (‘y’ for match, ‘–’ for mismatch, and ‘(n.a.)’ for irrelevant). Table 7 in the main body of the paper summarizes the data.
English (source: British National Corpus).
Japanese (source: NINJAL-BCCWJ corpus, as of 2009, accessed through the NINJAL-LWP Project, by courtesy of Prashant Pardeshi).
Maltese (source: Maltese Language Resource Server, MLRS Corpus).
Romanian (source: Romanian Corpus of Newspaper Articles, see Mihalcea & Năstase 2002).
Russian (source: National Corpus of Russian; only the nonderived aspct was considered).
Swahili (source: Helsinki Corpus of Swahili).
Turkish (source: Milliyet Newspaper Corpus, see Hakkani-Tür Reference Hakkani-Tür2000).