


1. Introduction
In finite populations, the variation in the number of offspring among individuals may result in random fluctuations in allele frequencies. This is the phenomenon of genetic drift or, more economically, drift. Philosophical exploration of drift has focused primarily on understanding how to conceptualize such change. Is it, for instance, a process or set of processes (e.g., Millstein Reference Millstein2002), or is it a mere outcome of sampling error (e.g., Brandon Reference Brandon2005)? What philosophers have not explored much is the very nature of the patterns of drift in natural populations. There are two: The first concerns the probability of survival of a mutant allele in a population; the second concerns reduction in genetic variation. Population geneticists have well-developed models accounting for these patterns. There is a compelling question, however, concerning the evolutionary significance of drift in reducing genetic variation. Indeed, drift is at the core of population genetics explanations of the nature of genetic variation on the assumption that much of that variation is neutral (or nearly neutral) (e.g., Lewontin Reference Lewontin1974; Gillespie Reference Gillespie1991).
In explanations of stochastic evolutionary dynamics, drift is often considered the most significant when considered alongside boundary processes, origination processes such as mutation, and random changes in environment. However, in a series of recent papers in theoretical population genetics, John Gillespie (Reference Gillespie2000a, Reference Gillespie2000b, Reference Gillespie2001) argues that a new stochastic process he calls genetic draft is evolutionarily more significant than drift. In this case study of chance in evolution, I explore Gillespie's proposed stochastic evolutionary force and its significance at reducing genetic variation relative to drift. I begin with a discussion of Gillespie's model of genetic draft. I next examine his argument concerning draft's greater evolutionary significance relative to drift. The purpose here, and the central critical purpose of the essay, is to take a critical look at Gillespie's argument for this claim. The paper concludes with remarks concerning the implications of genetic draft on recent philosophical disagreements over drift.
2. Genetic Draft
In a small handful of theoretical papers, Gillespie (Reference Gillespie2000a, Reference Gillespie2000b, Reference Gillespie2001) has explored a new stochastic evolutionary process he has dubbed genetic draft, or draft.Footnote 1 Draft is a process of linked selection, or a hitchhiking process. Gillespie calls draft a stochastic evolutionary force for two main reasons, namely, because the timing of the hitchhiking event is random and because the hitchhiking alleles are there by chance. There are two remarkable properties of draft. First, it, like drift, removes genetic variation from a population. Second, draft, quite unlike drift, does so virtually independently of population size. In the next section, the second property will prove to be the crucial turn in the argument that draft is evolutionarily more significant than drift. But what is draft?
Philosophers of biology will be generally unfamiliar with draft. But they will be familiar with drift. For that reason, and because of the dynamics draft shares with drift, I begin by setting out fundamental properties of drift and drift models that will come up in the discussion of draft. My discussion follows Gillespie's (Reference Gillespie2004), but it is a standard approach. Gillespie's mathematics makes extensive use of random variables, mean, and variance (or dispersion about the mean); the ensuing discussion relies on familiarity with these concepts.
Random genetic drift is the phenomenon of random, undirected changes in allele frequencies in populations. Now, the random changes in allele frequencies may result in alleles in a population being lost. And those losses (may) result in a loss of genetic variation in the population so that the population is pushed toward homozygosity and away from heterozygosity. The typical model of drift, and the one philosophers of biology will be most familiar with, is binomial sampling. Here, there are assumed to be N diploid adults in a population with a gene that has a frequency
 $p_{0}$
. Further, the adults make an infinite number of gametes having the same allele frequency. And from the pool, 2N gametes are drawn at random to constitute the N diploid individuals for the next generation. The binomial distribution is key. Consider that the probability that i A alleles make it to the next generation is the binomial probability

where i may be 0, 1, …, 2N, N is the population size, and p and q are allele frequencies (and
 $q=1-p$
). The binomial distribution describes the probability of i events of copying allele A, where the probability of copying an A allele is p over
 $n=2N$
(in this case) independent trials. The mean and variance of a binomial random variable with parameters n and p are np and npq. So the mean and the variance of
 $p^{\prime }=i/ 2N$
are

The mean
 $E\{ p^{\prime }\} $
states that the mean allele frequency remains the same under drift, that is, reflecting that changes in allele frequency are undirected. The variance in the allele frequency is in line with Fisher's (Reference Fisher1922) standard deviation,
 $\sigma ^{2}=pq/ 2N$
, which is a fundamental quantity in population genetics. The expressions in (2) will come up several times in the discussion of draft, to which we now turn.
As I said at the outset of the present section, draft is a kind of hitchhiking, or linked selection. Maynard Smith and Haigh (Reference Maynard Smith and Haigh1974) coined the phrase “hitchhiking effect” to describe the change in the frequencies of alleles at loci closely linked to a selectively advantageous mutation that is swept to fixation.Footnote 2 Consider a selectively advantageous mutation arising in a population. As that mutation is swept to fixation by selection, the alleles at loci closely linked to it will also increase in frequency. One effect of this hitchhiking event is a loss of genetic variation in the population. Maynard Smith and Haigh constructed a deterministic model of hitchhiking. In contrast, Gillespie emphasizes stochastic elements in the process, namely, that the timing of a selective sweep is random and that the alleles linked to the advantageous mutant allele are there by chance. These stochastic elements, along with the dynamical properties shared with drift, are what distinguishes draft from hitchhiking. It should be noted that Maynard Smith and Haigh were interested in the significance of hitchhiking relative to drift at reducing neutral genetic variation. Similarly, Gillespie is interested in the significance of draft relative to drift on reducing genetic variation. But more on drift versus draft later.
A main constraint on hitchhiking is recombination: Recombination breaks up linkages, which hitchhiking depends on for its effect. The simplest case of genetic draft to consider, then, is the case in which there is no recombination, or in which the rate of recombination, r, is
 $r=0$
. And that is where Gillespie begins. The mathematics is Gillespie's (Reference Gillespie2004, 111–115).
Consider a mutation, B, at the B-locus that arises in a population and that the mutation is linked to one of two alleles, A and a, at the selectively neutral A-locus. Let the frequency of the A allele be p so that the probability that the new mutation is originally linked to it will also be p. If B is swept to fixation by selection, A will go along with it; if B is eliminated from the population by selection, A will go along with it. These are hitchhiking events, and the possibilities describing the fates of the A allele are

Given that
 $p^{\prime }$
is a random variable, it has a mean and variance of

Take note that the mean allele frequency does not change, and the variance in the allele frequency is proportional to pq. These two properties are shared with drift, from (2) above.
Now, in any particular generation, there are three possible fates of an allele, A, with frequency p at the neutral A-locus linked to a mutant allele, B, at the B-locus: First, there will be no sweep, and so there will be no change in allele frequencies at the B- and A-loci. Second, there will be a sweep that leads to the fixation of the mutant allele, B, taking A along with it. Third, there will be a sweep that leads to the removal of the mutant allele, B, taking A along with it. Let ρ be the probability of a hitchhiking event occurring in a specific generation. Thus, the possibilities are

The mean and the variance for
 $p^{\prime }$
are

Again, note that these are similar to a model for genetic drift in which
 $\rho =\sigma ^{2}/ N$
and σ2 is the variance in the offspring gametes from a single gamete (Gillespie Reference Gillespie2004, 113).
For recurring hitchhiking events, the probability that an event is initiated, ρ, is also the rate of substitution of a selectively favorable mutation. However, Gillespie (Reference Gillespie2004, 113) notes that two simplifying assumptions for modeling recurring hitchhiking events are required for the sake of tractability. The first is the assumption that the time scale of a selective sweep is extremely short compared to the time scale between sweeps. The second assumption is that the time between sweeps is exponentially distributed. The result is that the timing of a selective sweep forms a Poisson process (which makes for a direct comparison to drift under binomial sampling). The simplified model is a one-locus model that Gillespie calls a model of pseudohitchhiking. A full analytical treatment of the two-locus dynamics is extremely complex and has yet to be worked out; the single-locus dynamics approximate computer simulations of two-locus dynamics (see Gillespie Reference Gillespie2000b, 15–16). It should be noted that Maynard Smith and Haigh (Reference Maynard Smith and Haigh1974) approximated the two-locus dynamics for their hitchhiking model by constructing, first, a deterministic, two-locus haploid model and then extrapolating that argument to the diploid case. More recently, Barton (Reference Barton1998, Reference Barton2000) has made these approximations more precise.
Gillespie now allows for recombination, that is,
 $r> 0$
, thus far excluded from the model. Now, recall that recombination breaks up the linkages hitchhiking depends on. Indeed, in order for hitchhiking to have an effect on genetic variation, the ratio of the rate of recombination to the coefficient of selection,
 $r/ s$
, must be very small. In fact, if
 $r/ s\ll 0.1$
, then selection is more powerful than recombination, and so hitchhiking will cause a reduction in variation at the locus linked to the advantageous mutation swept to fixation. Conversely, if
 $r/ s\gg 0.1$
, then recombination is more powerful than selection, and hitchhiking will not have much of an effect at reducing genetic variation. Differently put, consider that for a reasonable recombination rate,
 $r=10^{-8}$
, as the selection coefficient, s, increases from, say,
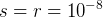 $s=r=10^{-8}$
to
 $s=10^{-2}$
,
 $r/ s$
decreases until
 $r/ s\ll 0.1$
. Thus, it is easy to see that as selection increases in intensity,
 $r/ s$
decreases, and selection becomes more powerful than recombination, thus allowing for hitchhiking to reduce genetic variation.
With that said, Gillespie treats the situation in which recombination is allowed as follows. Consider that if the final frequency of the hitchhiking allele, A, is y, then the pseudohitchhiking model gives the following possibilities for no sweep and no change in allele frequencies at the B- or A-loci, a sweep that takes the advantageous mutant, B, to fixation and A along with it, or a sweep that removes B and A along with it:

The mean and variance are

Note that the mean does not change from (2) above. The variance incorporates y as a random variable because it is determined by the strength of selection, the rate of recombination between the neutral and selected locus, and the boundary process during the initial phase of the sweep. With that said, the variance in
 $p^{\prime }$
is more aptly written to account for that randomness as
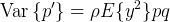 $\mathrm{Var}\,\{ p^{\prime }\} =\rho E\{ y^{2}\} pq$
. (This version of the variance in
 $p^{\prime }$
will be used in subsequent discussion.)
The preceding summary discussion presented Gillespie's mathematical argument for a simplified, one-locus model that provides for an approximation of the two-locus dynamics of genetic draft by way of the pseudohitchhiking model. The stochastic model describes the three possible fates of an allele, A, with frequency p at the neutral A-locus linked to a selectively advantageous mutant allele, B, at the B-locus after a hitchhiking event. At the outset of the present section, I said that there were two especially interesting features of genetic draft: First, it removes genetic variation from a population as drift does. Second, it produces that pattern independent of population size, quite unlike drift. These properties are considered in the next section, in which draft is compared to drift.
3. Drift versus Draft
The two features of draft to be considered here are related and so will be taken together. The discussion begins, as it did in the previous section, with drift. As before, the key reason is that drift is familiar and its properties are well understood. The key points regarding drift of interest here are the rate at which drift decreases a population's genetic variation in a population and that rate's tie to population size.
Recall that drift is the phenomenon of random, undirected changes in allele frequencies in populations. The undirected nature of the changes in allele frequencies is reflected in the mean,
 $E\{ p^{\prime }\} =p$
, from (2). Such random changes in allele frequencies may result in alleles in a population being lost. And those losses (may) result in a loss of genetic variation in the population. The rate of this loss, that is, the rate of decay of heterozygosity, is what is of interest here. It is a fundamental quantity of population genetics that the rate of decay of heterozygosity in a population due to drift is
 $1/ (2N) $
, given a population of size N with two alleles at each locus. The rate of decay of heterozygosity due to drift is related to the variance,
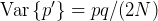 $\mathrm{Var}\,\{ p^{\prime }\} =pq/ (2N) $
, from (2) in the previous section (see Gillespie Reference Gillespie2004, 48–49).
If populations were subject only to drift, then, ultimately, drift would remove all of the generic variation. Of course, populations are subject to several evolutionary factors, namely, mutation, drift, selection, and migration. The neutral variation that is subject to drift is commonly considered to be modulated by the interaction of mutation, which adds variation at rate 2Nu, where N is population size and u is the rate of mutation, and drift, which, from above, removes variation at rate
 $1/ (2N) $
. Over time, an equilibrium state will be reached that balances the dynamics of the interaction between mutation and drift. At equilibrium, the heterozygosity,
 $\hat{H}$
, in a population may be described by

where, again, N is the population size and u is the mutation rate. Equation (9) is another fundamental equation in population genetics (see any population genetics textbook for a derivation; Gillespie's [Reference Gillespie2004, 29–30] is especially clear).
Notice the dependency on the population size, N, for the rate of decay of heterozygosity due to drift and, relatedly, the measure of heterozygosity,
 $\hat{H}$
. Consider first the rate of decay. It is apparent that
 $1/ (2N) $
decreases as N increases. It follows, then, that as N increases, drift's push toward homozygosity and away from heterozygosity decreases. This would be expected from the binomial sampling model. It is also borne out in the measure of heterozygosity,
 $\hat{H}$
. Notice that heterozygosity,
 $\hat{H}$
, is extremely sensitive to population size. Indeed, if 4Nu is small, then one expects little to no heterozygosity; conversely, if 4Nu is large, then one expects almost complete heterozygosity. As an illustration, from equation (9) above, consider that for
 $u=10^{-6}$
and the range of
 $N=10^{3}$
to 107, so that the range of
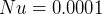 $Nu=0.0001$
to 10, the range of
 $\hat{H}=0.004$
or about 0.4% to 0.976, or about 98%.
Drift's dependence on population size, N, has implications for its relative significance among evolutionary forces, for example, mutation, selection (including linked selection), and migration. Indeed, the significance, or importance, of an evolutionary force may be, and commonly is, quantified as the time required for it to have a significant effect on a population (cf. Beatty Reference Beatty, Wolters and Lennox1995). Drift's dependency on the population size, N, has a profound effect on the time required for it to have a significant effect on a population. The time scale for drift to decrease heterozygosity in a population by half is understood to be proportional to the population size, N. The time scale for mutation to increase heterozygosity is, similarly, proportional to
 $1/ u$
. Consequently, when populations are very large, say
 $N\geq 10^{7}$
, and for a rate of mutation, u, on the order of 10−6, mutation will increase heterozygosity by half faster than drift can decrease it, that is,
 $1/ u\ll N$
. And when populations are smaller, say
 $N\geq 10^{5}$
, drift will decrease heterozygosity by half faster than mutation can increase it, that is,
 $N\ll 1/ u$
. Quantifying the significance of an evolutionary force as the time it takes for the force to have an effect on a population provides one foundation of the well-known claim that as population size increases, the evolutionary significance of drift decreases.
On the metric just described, a direct comparison of the relative significance of the effects of drift and draft on genetic variation can be made. As it turns out, draft will be more significant than drift when the rate at which draft decreases heterozygosity in a population is greater than the rate at which drift does the same, that is, when
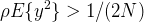 $\rho E\{ y^{2}\} > 1/ (2N) $
(Gillespie Reference Gillespie2004, 115). This happens when N gets sufficiently large so that draft dominates drift. To demonstrate this point, Gillespie combines drift with draft so that both are at work; shows that draft is not (or is at most only weakly) dependent on population size; and then determines the measure of heterozygosity,
 $\hat{H}_{*}$
, for the balance between mutation, drift, and draft and shows that the measure is also only weakly dependent on the population size. Consider the argument.
Gillespie first adds drift to the pseudohitchhiking model so that

where N is the size of the diploid population. Notice that the move here simply reflects that the variance in
 $p^{\prime }$
is now the sum of the variances due to both drift and draft. With equation (10), draft may be situated in a finite population suitable for drift. Thus, in this model population, both drift and draft are at work. Gillespie's next move is to obtain the (variance) effective size of the population for equation (10), that is,
 $1/ 2$
multiplied by the reciprocal of the coefficient of pq, which is

This move makes manifest one of the fascinating features of genetic draft, namely, that its effectiveness is only weakly dependent on the population size, N. Inspection of equation (11) reveals that as population size, N, increases, effective population size,
 $N_{e}$
, decreases as long as the rate of substitution of advantageous mutations, ρ, is
 $\rho =4Nus$
, a conventional estimate for ρ, where u is the mutation rate and s is the selection coefficient. Because draft is only weakly dependent on the population size, it is likely to be evolutionarily more significant than drift at removing genetic variation from a population. Gillespie's next move cinches this claim.
A key property of the model of drift introduced in the previous section, that is, the mean and variance in (2) above, is that the population size is the same as the effective population size, that is,
 $N=N_{e}$
, where the effective population size,
 $N_{e}$
, is the size of a theoretically ideal population having the same magnitude of drift as the actual population. This property is useful since by substituting
 $N_{e}$
from equation (11) for N in equation (9) above, Gillespie finds the analogue to the measure of heterozygosity in equation (9) for the balance of mutation, drift, and draft,
 $\hat{H}_{*}$
:

It should be evident from equation (12) that the relationship between
 $\hat{H}_{*}$
and N mirrors the relationship between N and
 $N_{e}$
in (11) under the same assumptions for ρ (
 $\rho =4Nus$
). That is, as population size, N, increases, heterozygosity,
 $\hat{H}_{*}$
, decreases.
Let me be clear. Recall that
 $\hat{H}$
in equation (9) steadily increases as Nu, and therefore N, increases. Here is the basis for the conclusion that, relative to drift, draft is more significant at decreasing heterozygosity in a population. Drift's effectiveness, its significance, is tied to population size, N, so that its time course increases as population size, N, increases. Because draft is only weakly dependent on the population size, N, which follows from equation (11), its time course does not increase in the same way. The significance of an evolutionary force is quantified by the time it takes to have a measurable effect on a population. Hence, relative to drift, draft is evolutionarily more significant at removing genetic variation from a population.
But notice the way in which draft works to remove genetic variation from the population. If we consider that neutral variation is modulated by mutation, drift, and draft, then what we mean is that all three forces are working simultaneously. In finite populations, drift will dominate draft because the rate at which drift decreases heterozygosity will be faster than that of draft, that is,
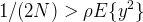 $1/ (2N) > \rho E\{ y^{2}\} $
. But as population size increases to about
 $N\geq 10^{4}$
, draft dominates drift, effectively taking over the role drift has in finite populations, namely, decreasing heterozygosity. In other words, the effect of the interaction of mutation, drift, and draft on genetic variation is a continuous decrease in genetic variation across varying population sizes. The pattern of decrease in heterozygosity, a key property of genetic drift, is also a key property of genetic draft.
It seems to me that there is one key obstacle for Gillespie's (Reference Gillespie2000a, Reference Gillespie2000b, Reference Gillespie2001, Reference Gillespie2004) theoretical exploration of draft. It is that the rate of substitution of advantageous mutations, ρ, is not very well understood. Gillespie alludes to this problem but does not spend a great deal of time on it. The convention in population genetics is that
 $\rho =4Nus$
, yet it is unclear what the relationship is between ρ and N, population size. To be sure, this issue has implications for Gillespie's explorations of draft since a key claim of his concerns the relationship between draft and population size and ρ plays a key role in all the models, as is evident from the preceding. Nevertheless, the implications that genetic draft has for understanding the modulation of neutral genetic variation are quite stunning. More than 30 years ago, Lewontin (Reference Lewontin1974, 207–210) demonstrated that the interaction of mutation and drift (see equation [9]) is not sufficient to explain observed levels of heterozygosity. The upshot of his discussion is that while population genetics theory predicts that levels of heterozygosity are sensitive to population size, observed levels of heterozygosity are not. Gillespie's reinvestigation of Maynard Smith and Haigh's (Reference Maynard Smith and Haigh1974) famous solution provides a clear and elegant response to the problem.
4. Conclusion
In this paper, I have presented a case study of chance in evolution. In the preceding, I explicated the models describing a new stochastic evolutionary force introduced by Gillespie (Reference Gillespie2000a, Reference Gillespie2000b, Reference Gillespie2001) called genetic draft. My main purpose has been to examine draft in relation to drift with respect to its effects on the genetic variation of a population. Philosophers of biology concerned with chance in evolution, and who, in particular, are concerned to “get to the bottom of the issue” of what drift is, for example, whether it is a process or set of processes (and what kinds) or an outcome, may find the present case study of value.
It is apparent that draft is a stochastic process. That is certainly Gillespie's approach to studying it, and anyway, it is linked selection. Yet, draft's effects on genetic variation are similar to those of genetic drift. Indeed, the outcomes of the combined model of drift and draft are indistinguishable from the model of drift (see especially Gillespie Reference Gillespie2000b). And while I tried to remain neutral on the process versus outcome issue with respect to drift, it is clear that I crossed lines toward the process view during the discussion. Certainly Gillespie talks about drift explicitly as a process, that is, as a stochastic evolutionary force. Indeed, Gillespie (Reference Gillespie2004, 49) is critical of the binomial sampling model of drift because “its biological underpinnings can make us queasy.” After all, “[p]opulations do not reproduce by calling in their local statistician and asking her to pick exactly 2N gametes at random (with replacement) and toss them into the next generation. Rather, individuals find mates and have babies, babies survive to reproduce, etc.” (49). Gillespie develops a model he regards as biologically more realistic, even if both models produce the same outcomes.
I submit that Gillespie is exactly right about his approach to drift and stochastic evolutionary processes more generally. Indeed, such an approach is natural when one explores the nature of the patterns in genetic variation that are due to drift. This much seems clear from the comparison of drift and draft presented above.


