

1 Introduction
In a number of languages, the distribution of nasal–stop sequences (NCs) is restricted. The focus of this article is on a class of effects termed nasal cluster dissimilation by McConvell (Reference McConvell1988), which together identify a cross-linguistic dispreference for the co-occurrence of NCs within a single word (e.g. [ambada] and [abanda], but *[ambanda]). The two most common strategies to avoid such a configuration are deletion of the oral component of the first NC (NC1) and deletion of the nasal component of the second (NC2); other strategies are discussed briefly in §6.1. (1) provides examples confirming that the alternations are conditional on the presence of multiple underlying NCs.Footnote 1
(1)

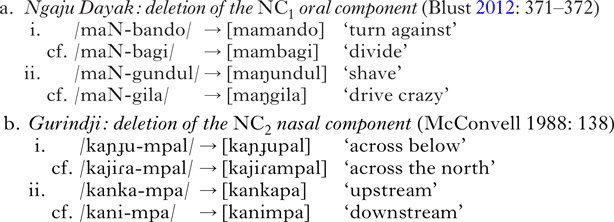
What kind of constraint drives nasal cluster dissimilation? Many analysts (e.g. Alderete Reference Alderete1997, Blust Reference Blust2012) have argued that alternations like those in (1) are driven by a co-occurrence constraint that penalises words containing more than one NC. Others (e.g. Jones Reference Jones2000, and to some extent Herbert Reference Herbert1986) argue that nasal cluster dissimilation is perceptually motivated: in NC1VNC2, NC1 may be confusable with a nasal consonant, as its oral portion is preceded and followed by a nasal consonant, the latter of which likely induces some amount of anticipatory nasalisation in the preceding vowel (so that [NC1ṼNC2] is difficult to distinguish from [N1ṼNC2]). Repairs like those in (1), then, are motivated by a desire to avoid forms in which the contrast between NC1 and a plain nasal consonant, N, is insufficiently distinct.
This article provides support for the claim that nasal cluster dissimilation is perceptually motivated. §2 and §3 discuss various implicational generalisations that hold over the structures targeted by nasal cluster dissimilation, propose an analysis that appeals to perceptual factors and present two case studies, supplemented with acoustic data. §4 presents results of a perceptual experiment that are largely consistent with assumptions of the analysis. §5 verifies a larger typological prediction of the analysis: if nasal cluster dissimilation does not reflect a dispreference for the co-occurrence of nasal clusters per se, but rather a dispreference for NCṼ, languages that exhibit nasal cluster dissimilation should ban NCṼ across the board (regardless of the source of the vowel's nasality), while languages that allow NCṼ should not exhibit nasal cluster dissimilation.
The results described in this article provide further support for the claim that constraints on the distribution of NCs are constraints on contrast (Stanton Reference Stanton2016b, Reference Stanton2018), and by extension for the claim that constraints on contrast are a necessary component of the synchronic grammar (e.g. Flemming Reference Flemming2002, Gallagher Reference Gallagher2010). Alternatives and broader implications for our understanding of the larger typology of dissimilatory processes are discussed in §6.
2 The righthand context: generalisations and analysis
The next two sections present results of a typological survey consisting of 67 languages in which the distribution of NCs is restricted in the environment of Ns or other NCs.Footnote 2 These languages were identified from reference grammars and previous literature (e.g. Meeussen Reference Meeussen1962, Herbert Reference Herbert1977, McConvell Reference McConvell1988); more details and references for each language are given in Appendix A.Footnote 3 This section focuses on generalisations regarding the righthand context (NC2) and proposes an analysis linking these generalisations to acoustic and perceptual factors: nasal cluster dissimilation is more likely when the post-NC1 vowel is more nasalised.
2.1 Preconsonantal vs. prevocalic nasals
While the term ‘nasal cluster dissimilation’ implies that the restriction holds only over co-occurring NCs, many languages that exhibit nasal cluster dissimilation also prohibit nasal–stop clusters from preceding onset nasals (see Herbert Reference Herbert1986, McConvell Reference McConvell1988, among others). The relationship between the two restrictions is implicational: almost all languages that ban NC1VN2V also ban NC1VNC2, but the reverse does not hold. In (2), the surveyed languages are categorised according to the nature of the restrictions they impose. Decisions that led to these classifications were usually based on a combination of multiple sources; for more details see Appendix A.
(2)

The three languages that prohibit NC1VN2V only, Bokote, Bolia and Sango, are worthy of further discussion. The only basis for categorising Bokote in this way is Meeussen's (Reference Meeussen1962: 28) statement that evidence for nasal cluster dissimilation comes from ‘only a few cases of the type -boman-’, and a footnote that lists five other relevant roots. There is no evidence of alternations, and the dictionary cited (Hulstaert Reference Hulstaert1957) does not discuss restrictions on the distribution of NCs. The strength of Meeussen's evidence is thus unclear. In the case of Bolia, Mamet (Reference Mamet1960: 22) notes that the plural suffix is realised as [ɲɟ] before a vowel, but as [ɲ] ‘if the root has as its first consonant a singleton nasal’ (translation mine). But the illustrative examples provided are consistent with an alternative analysis under which [ɲɟ] cannot precede [i]. Finally, it is unclear whether Sango actually exhibits nasal cluster dissimilation. Meeussen's discussion provides one example ([imono] ‘castor oil’), but Samarin's (Reference Samarin1967) grammar contains many words with co-occurring Ns and NCs (e.g. [ŋgunzá] ‘manioc leaves’, [ndóndó] ‘brain’, [mbéní] ‘some’; Reference Samarin1967: 35–36). Treating these languages as ‘NC1VN2V only’ is conservative, as it is quite possible that they do not exhibit nasal cluster dissimilation at all. These possible counterexamples aside, we can maintain the generalisation above that a ban on NC1VN2V asymmetrically implies a ban on NC1VNC2.
2.2 Hypothesis and analysis
I hypothesise that the implicational generalisation in (2) can be attributed to differences in the realisation of the post-NC1 vowel in NC1VNC2vs. NC1VN2V. It has been observed for many languages that coda (i.e. non-prevocalic) nasals induce more regressive nasal coarticulation than do onset (prevocalic) nasals.Footnote 4 Jeong (Reference Jeong2012) documents this pattern for French and Modern Greek, Krakow (Reference Krakow1993) for American English and Herbert (Reference Herbert1977) for a number of languages, including Pashto, Malagasy and Delaware, while Schourup (Reference Schourup1973: 191–192) concludes, on the basis of a large survey, that ‘in no language examined are vowels nasalized before prevocalic nasals when they are not also nasalized before all preconsonantal and word-final nasals’. Thus in many languages the first vowel in NC1VNC2 is likely to be more nasalised than the corresponding vowel in NC1VN2V.
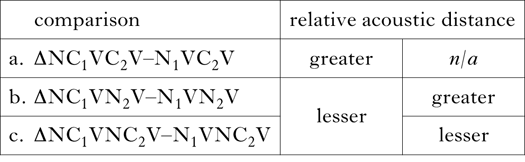
This acoustic difference could lead to a difference in the relative perceptibility of the contrast between N and NC1 (N–NC1). I hypothesise that N–NC1 is more confusable when NC1 is followed by a nasalised vowel than when it is followed by an oral vowel. Furthermore, let us hypothesise that the greater the amount of nasalisation, the more confusable N and NC1. If this is correct, two asymmetries should hold. First, the acoustic distance between N and NC1 before an oral consonant (C2 in Table Ia) should be greater than the acoustic distance between N and NC1 before onset or coda N2 (b, c). Second, the acoustic distance between N and NC1 before an onset nasal (b) should be greater than the acoustic distance between N and NC1 before a coda nasal (c).
Hypothesised perceptual asymmetries.

We can now derive the generalisations in (2) with constraints that penalise insufficiently distinct contrasts. The proposed analysis is framed in Dispersion Theory (Flemming Reference Flemming2002), as its MinDist constraints allow the grammar to reference a contrast's perceptibility in different contexts. To capture the observed generalisations, I propose that NC must be followed by a vowel that is sufficiently oral for the N–NC contrast to be distinct, and I encode this requirement as a set of MinDist constraints that penalise N–NC contrasts according to the amount of nasality in the post-NC vowel.
To formalise these constraints, I assume that language learners divide vowels into a finite number of categories, according to the average amount of coarticulatory nasalisation they exhibit. I refer to these categories as Oralx, where x is the category number. The referents of these category numbers are likely language-specific, as are patterns of coarticulatory nasalisation (see §2.4 for more discussion of this point). For an analysis of the generalisations in (2), however, we only need to reference the three categories in (3): Oral1 (V/_Ncoda), Oral2 (V/_Nonset) and Oral3 (other).
(3)
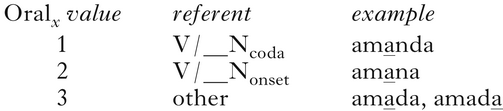
Given the three Oral categories, we can formulate the two constraints on the N–NC contrast in (4a) and (b).Footnote 5
(4)
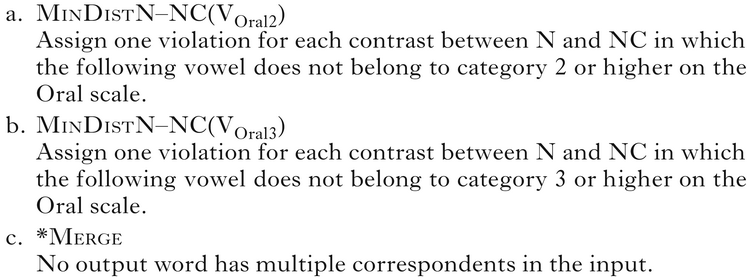
Contrasts that satisfy and violate these constraints are as follows. (4a) is satisfied by contrasting pairs like [amana-ambana] (Oral2) and [amada-ambada] (Oral3), but violated by pairs like [amanda-ambanda] and [amanda-ambanta] (Oral1). (4b) is satisfied only by [amada-ambada] (Oral1), and violated by any pairs with a nasal in second position (e.g. [amana-ambana]; Oral2). I assume that cross-linguistic differences in the righthand context for nasal cluster dissimilation reflect differences in the ranking of MinDist constraints on the Oral scale with respect to *Merge (Padgett Reference Padgett2003) in (4c), a constraint that penalises neutralisation.
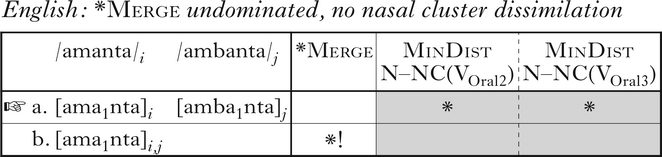
The input–output mapping /amanda/i, /ambanda/j → [amanda]i, [ambanda]j satisfies *Merge; the mapping /amanda/i, /ambanda/j → [amanda]i, j, with neutralisation of N–NC, violates it.Footnote 6 A factorial typology of (4) predicts three types of system. If *Merge ⪢ MinDistN–NC(VOral2), MinDistN–NC(VOral3), nasal cluster dissimilation will not occur. One language instantiating this ranking is English, where contrasting forms like commend–compend are licit, even though /mp/ is followed by a vowel whose Oral category is 1, as shown in (5).
(5)
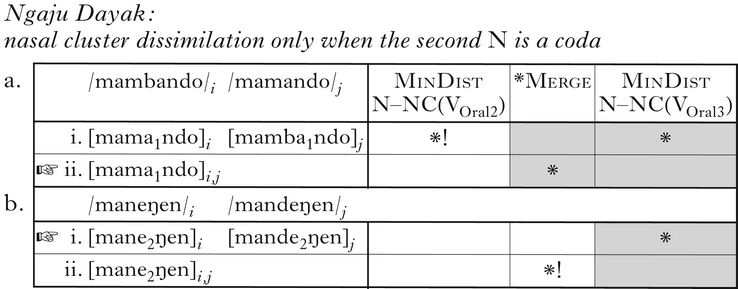
In the second type of system, where *Merge is ranked between MinDist N–NC(VOral2) and MinDistN–NC(VOral3), nasal cluster dissimilation occurs in only those contexts where N–NC is less perceptible. This is the case in Ngaju Dayak, for example, where N–NC is neutralised given a following coda nasal, as in (6a) (though see §3 for a more detailed analysis of Ngaju Dayak nasal cluster dissimilation). In other contexts, N–NC is licit, as shown in (6b).
(6)
Finally, in systems where both MinDistN–NC(VOralx) constraints dominate *Merge, nasal cluster dissimilation occurs in all nasal contexts. Such a ranking characterises languages like Luganda, where nasal cluster dissimilation occurs to repair any sequence in which NC is followed by onset or coda N, as in (7).
(7)

The constraints introduced in (4) cannot derive systems in which nasal cluster dissimilation occurs only preceding onset nasals, because MinDist constraints are unable to penalise a more distinct contrast to the exclusion of a less distinct one. For example, there is no possible MinDistN–NC: NC/_VOralx constraint that can penalise (6b.i), [mane2ŋen]i, [mande2ŋen]j to the exclusion of (6a.i), [mama1ndo]i, [mamba1ndo]j. Given this, the implication that repair of NC1VNC2 implies repair of NC1VN2V is derived. More broadly, if two contexts (Context1 and Context2) differ in that some contrast x–y is better-cued in Context1 than it is in Context2, then the presence of x–y in Context2 (where it is less well-cued) asymmetrically implies its presence in Context1 (where it is better-cued) (see Steriade Reference Steriade1997).Footnote 7
This analysis predicts that all languages with nasal cluster dissimilation should exhibit patterns of nasal coarticulation in line with the cross-linguistically common patterns described above. More specifically, it predicts that in languages that ban NC1VNC2 but not NC1VN2V the intermediate vowel in NC1VNC2 is more nasalised than that of NC1VN2V. This larger point has not been established, and doing so would require large amounts of high-quality acoustic data from each language under consideration.
2.3 Preconsonantal vs. word-final nasals
If the difference between the amounts of coarticulation induced by onset and coda nasals is responsible for the generalisation expressed by (2), we might expect – all else being equal – that languages that allow NC1VN2V but ban NC1VNC2 should also ban NC1VN2 when N2 is word-final. To test this prediction, I focused on the ten surveyed languages that allow NC1VN2V, ban NC1VNC2 and permit word-final nasals. Of these, six ban NC1VN2, as in (8a); four allow it, as in (8b).
(8)
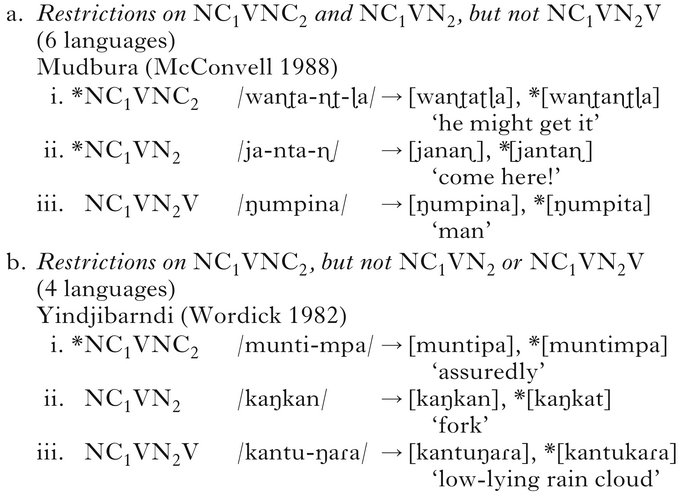
There are independent factors at play for each of the languages that prohibits NC1VCN2 but allows NC1VN2. In Yaunde, it is unclear what the scope of nasal cluster dissimilation is. Meeussen (Reference Meeussen1962: 28) provides an example of nasal cluster dissimilation applying across an imperative suffix boundary (/lúmbu-ŋgu/ → [lúmuŋgu] ‘bow, stoop’), but words like [ndàmbà] ‘rubber’, [ndàmá] ‘to be wide open’ and [m̃bóŋ] ‘palm flower’ in Essono's grammar suggest that nasal cluster dissimilation is not fully general (Reference Essono2000: 48, 45, 29). The most straightforward interpretation of this discrepancy is that nasal cluster dissimilation only occurs across certain morphological boundaries; in this case it is not surprising that monomorphemic words like [mboŋ] exist. The situation in Gooniyandi (McGregor Reference McGregor1990) is similar. Nasal cluster dissimilation occurs in forms suffixed by the ergative postposition [-ŋga] (/goːɳboː-ŋga/ → [goːɳboːga] ‘by the woman’; Reference McGregor1990: 98), but generally not within morphemes ([liɲbaɳɖi] ‘a type of edible leaf’) or across other morpheme boundaries.Footnote 8 It is possible to explain forms like [biɲbiɲ] ‘crimson chat’ (McGregor Reference McGregor1990: 61) by appealing to the morphologically specific nature of nasal cluster dissimilation. In Yindjibarndi, the situation is somewhat different: nasal cluster dissimilation is general throughout the language, but restricted to certain kinds of NC1VNC2 sequences (see §2.4). It occurs when NC2 is labial (as in (8b.i)) or velar (/wuntu-ŋka/ → [wuntuwa] ‘river (loc)’; Wordick Reference Wordick1982: 33), but not otherwise ([kaŋkan-la/ → [kaŋkanta] ‘in the fork’; Reference Wordick1982: 35). All else being equal, we might expect NC1VN2 to be forbidden with labial or velar N2, but permitted otherwise. Yindjibarndi does not allow labial or velar nasals in word-final position (Wordick Reference Wordick1982: 13), so the second half of this prediction cannot be tested.
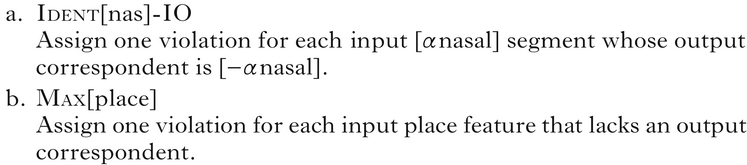
Finally, in Bilinara, nasal cluster dissimilation applies only when NC2 is homorganic, with resulting deletion of N2 (/ɲunu-ɲ-pa-ŋku-lu/ → [ɲunuɲpakulu] (you-dat-link-2sg.obj-3pl.subj); McConvell Reference McConvell1988: 152). In forms like [ŋumpin] ‘man’ (Reference McConvell1988: 149), the failure of [n] to denasalise (as in Gurindji [ŋumpit]) or delete (as in clusters) can be accounted for by adding several faithfulness constraints to the analysis proposed in §2.1.Footnote 9 First, nasal cluster dissimilation never results in denasalisation, consistent with the claim that Ident[nas]-IO in (9a) dominates MinDistN–NC(VOral2). Second, assuming that in a homorganic NC the place feature is shared between N and C, deletion of /ŋ/ from an input like /ɲunu-ɲ-pa-ŋku-lu/ does not result in the loss of the consonant's [dorsal] feature, because that place feature is still linked to the output [k]. By contrast, the /n/ of /ŋumpin/ has no following consonant to share its place feature with, so deletion of /n/ would result in the loss of its [coronal] feature as well. We can account for the failure of the final [n] in [ŋumpin] to delete by claiming that Max[place] in (9b) also dominates MinDistN–NC(VOral2).
(9)
As shown in (10), the ranking Ident[nas]-IO, Max[place] MinDistN–NC(VOral2) ⪢ *Merge predicts that nasal cluster dissimilation should occur in NC1VNC2 but not NC1VN2. The Oralx values in (10) are as assumed in §2.2. The tableaux below consider four-membered candidates, so that *Merge can be evaluated; the repair to insufficiently distinct N–NC1 in Bilinara involves removal of the nasalisation in the intervening vowel through neutralisation of C–NC2.
(10)
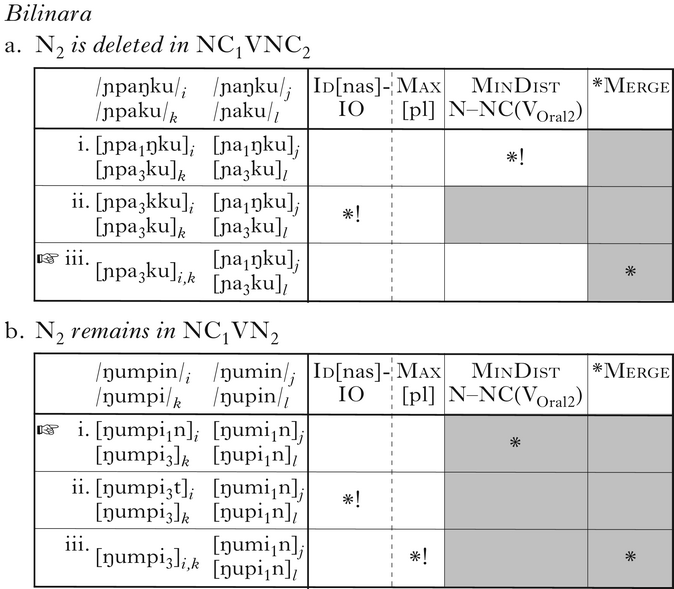
In sum, the data are consistent with an analysis where MinDist constraints penalise NC1VNC2 and NC1VN2 equally. The four cases in which only NC1VNC2 is dispreferred can plausibly be analysed by reference to morphological factors or high-ranked faithfulness constraints.
2.4 Further asymmetries and evidence from Yindjibarndi
The hypothesis introduced above has the potential to help us further understand language-specific restrictions on nasal cluster dissimilation. In Mori Bawah, for example, nasal cluster dissimilation only occurs when NC2 is voiceless (i.e. when NC2’s oral component is voiceless; (11a)). In Yindjibarndi, it only occurs when NC2 is [mp] or [ŋk]; (11b). Note that in (11b.i), the mapping from /ŋka/ to [wa] occurs due to an interaction between nasal cluster dissimilation and lenition: nasal cluster dissimilation maps /ŋka/ to [ka], and lenition maps /ka/ to [wa]. Examples like /paʈu-kaɭaː/ → [paʈuwaɭaː] ‘bird’ demonstrate that this lenition process is fully general; see Wordick (Reference Wordick1982: 28).
(11)
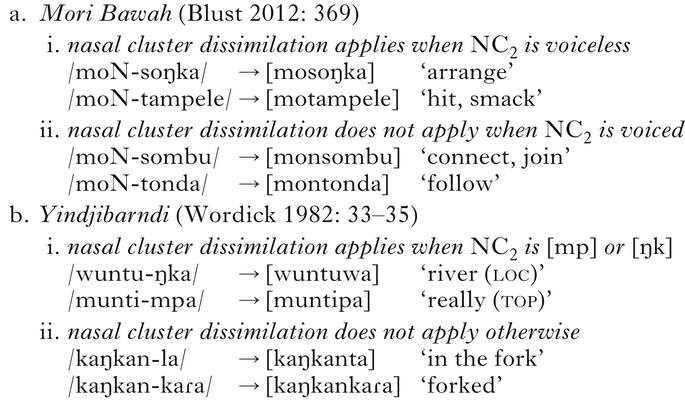
According to the hypothesis above, vowels in Mori Bawah should be more nasalised preceding voiceless NCs than preceding onset Ns or voiced NCs, as is the case in English (Cohn Reference Cohn1990, Beddor Reference Beddor2009). It also allows us to predict that vowels in Yindjibarndi should be more nasalised preceding [mp] and [ŋk] (or ‘peripheral’ NCs, to use Australianist terminology) than preceding non-peripheral (coronal) NCs, heterorganic NCs or onset nasals. I verify below that the prediction regarding Yindjibarndi is correct, and leave further investigation of Mori Bawah to future work.
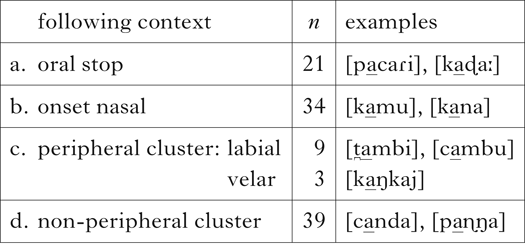
To quantify patterns of nasal coarticulation in Yindjibarndi, I selected 36 words from the UCLA Phonetics Lab Archive,Footnote 10 in which a primary-stressed initial /a/ is followed by an oral stop, an onset N, a peripheral NC or a non-peripheral cluster. Each word was repeated several times, giving a total of 100 tokens. Tokens are divided in Table II into four categories, according to the following context: (a) an oral stop, (b) an onset nasal, (c) a peripheral cluster (subdivided into labial and velar) and (d) a non-peripheral cluster. These words are limited to those in which a nasal appears only post-stress; nasal-initial words like [man̪t̪u] were not considered, to avoid potential confounding effects of perseveratory nasalisation. All tokens were produced by a single male speaker.
Yindjibarndi tokens by following context. The relevant vowel in each case is underlined.

The measure chosen to quantify acoustic nasality was compensated A1-P0, as measured by the Nasality Automeasure Script Package (Styler & Scarborough Reference Styler and Scarborough2015; see Chen Reference Chen1995, Reference Chen1997 on A1-P0) for Praat (Boersma & Weenink Reference Boersma and Weenink2017). A1-P0 is a measure of the amplitude of the first oral formant (A1) relative to the amplitude of a low-frequency nasal peak (P0). A1-P0 is ‘robust, well-studied, and well-correlated with nasality’ and claimed to be ‘the best single-number measure of nasality currently available’ (Styler & Scarborough Reference Styler and Scarborough2015). Only /a/ was considered here, because A1-P0 is mostly useful for non-high vowels, and the only non-high vowel in Yindjibarndi is /a/. Measurements were taken at five equally spaced timepoints throughout each vowel. Timepoints 1 and 5 were offset 5 ms from the beginning and end of the vowel, to avoid influence from neighbouring consonants. Of 500 possible measurements, the script took 496.Footnote 11
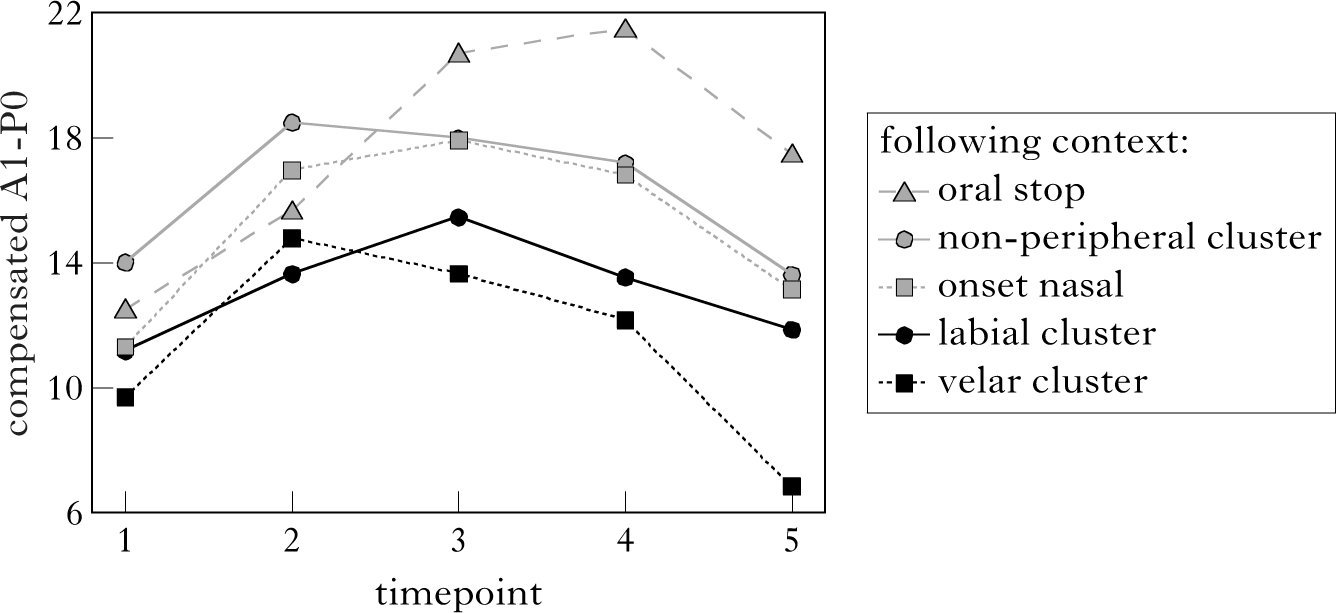
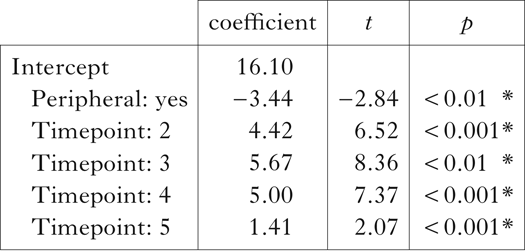
Results are given in Fig. 1 (plots in this article were created with R's ggplot2 package; Wickham Reference Wickham2009). The y-axis reflects the average compensated A1-P0; lower A1-P0 measures are correlated with more nasalisation. The exact A1-P0 values are not important here; what matters are the relative differences in A1-P0 between conditions at each timepoint. Figure 1 shows that the average A1-P0 of the vowels preceding peripheral NCs is lower at each timepoint than the average A1-P0 of the other vowels. To determine if this difference between contexts was meaningful, a mixed-effects linear regression was fitted to the data in Table III. The dependent variable was compensated A1-P0; fixed effects included sum-coded predictors for the type of following context (with a comparison between peripheral NCs and the grand mean) and the timepoint (with comparisons between timepoints 2–5 and the grand mean). A random intercept for token was also included.Footnote 12
Compensated A1-P0 in Yindjibarndi vowels by following context. Contexts classified as ‘peripheral’ are in black, and others are in grey; in the legend for ‘following context’, the top-to-bottom order of the five contexts reflects the relative A1-P0 at timepoint 5, from highest to lowest.

Results of statistical analysis for Yindjibarndi nasalisation. Significant values are indicated by *.

Effects for timepoints 2–5 indicate that A1-P0 is influenced by Timepoint; this is unsurprising, given the variation in Fig. 1. The result of interest is the effect of Peripheral: the negative coefficient indicates that vowels followed by a peripheral NC are associated with lower A1-P0 values than average. Assuming that this speaker is representative of the larger population, these results are consistent with the hypothesis that nasal cluster dissimilation tracks the acoustics of nasalisation. In Yindjibarndi, the context in which nasal cluster dissimilation occurs is the context in which the post-NC1 vowel would be most nasalised.
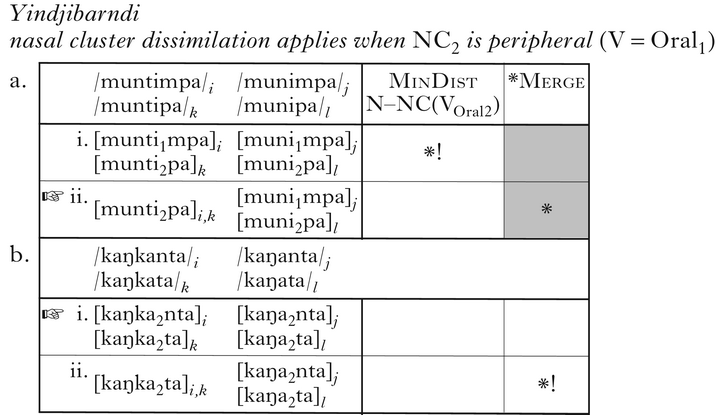
We can analyse the pattern in Yindjibarndi as follows. There is evidence for two Oralx categories: one for vowels that precede a peripheral NC (Oral1), and one for vowels preceding another segment or sequence type (Oral2). By ranking MinDistN–NC(VOral2) above *Merge, we can derive the generalisation that nasal cluster dissimilation occurs before peripheral NCs in Yindjibarndi in (12a) but not elsewhere (b). (The tableau in (12) again considers four-membered candidates, so that *Merge can be evaluated; as in Bilinara, nasal cluster dissimilation here involves neutralisation of the C–NC2 contrast.)
(12)
What has not yet been confirmed is that perception of an N–NC contrast is influenced by the amount of nasalisation in the following V, as measured in this way. I consider this in §4.
3 The lefthand context: generalisations and analysis
As we have seen, the identity of the righthand context plays a role in determining whether or not nasal cluster dissimilation applies, but the lefthand context (NC1, in NC1VNC2) can matter as well. I discuss the roles of stop voicing in §3.1 and place of articulation in §3.2, and in §3.3 propose an analysis under which the resulting generalisations are also linked to acoustic and perceptual factors: nasal cluster dissimilation becomes more likely as the salience of NC1’s oral release decreases.
3.1 Stop voicing
A consistent generalisation throughout the typology of nasal cluster dissimilation is that it rarely targets NC1VNC2 when NC1 is voiceless. In fact, the only language surveyed that exhibits nasal cluster dissimilation with voiceless NC1 is Mori Bawah (for illustrative data see (11a)). While NCs in languages like Gurindji and Yindjibarndi are often transcribed with graphemes indicating voicelessness, such as Üpâ or Ükâ, voicing in these languages is non-contrastive, and post-N stops are generally voiced.
Why does nasal cluster dissimilation prefer to target voiced NC1? Herbert (Reference Herbert1977: 365) attributes the asymmetry to the observation that ‘in a post-nasal environment, the voiced stops evidence the most reduction and are therefore the most susceptible to nasalization … voiceless stops and fricatives are more distinctive in this environment’. Building on this observation, I hypothesise that the relevant factor here has to do with the salience of the release: the longer the release of NC1, the less likely nasal cluster dissimilation is to occur. The idea is that a longer oral release in NC enhances the internal cues to the N–NC contrast (see Steriade Reference Steriade1997 on internal vs. external cues), and renders it less dependent on its external cues, such as the identity of the following vowel. For experimental evidence that the duration of NC's oral component leads to increasingly accurate identification rates, see Beddor & Onsuwan (Reference Beddor, Onsuwan, Sol, Recasens and Romero2003); for experimental evidence consistent with the present hypothesis, see §4.
If this hypothesis is correct, the release phase of voiceless NCs must be longer than the release phase of voiced NCs in all languages where nasal cluster dissimilation targets voiced but not voiceless NCs. While this hypothesis has not been verified for all the languages surveyed, the asymmetry has been documented generally (e.g. Maddieson & Ladefoged Reference Maddieson and Ladefoged1993 for Sukuma; Ladefoged & Maddieson Reference Ladefoged and Maddieson1996 for Bura; Riehl Reference Riehl2008 for Tamambo, Manado Mala and Pamona; Coetzee & Pretorius Reference Coetzee and Pretorius2010 for Tswana; Beguš & Nazarov Reference Beguš and Nazarov2017 for Tarma Quechua; Cho & Ladefoged Reference Cho and Ladefoged1999 on the more general asymmetry in release salience between voiced and voiceless stops).
The prediction of the analysis investigated here is that if nasal cluster dissimilation occurs to avoid relatively more distinct N–NC1 contrasts, it should also occur to avoid less distinct N–NC1 contrasts. Therefore, if a language exhibits nasal cluster dissimilation when NC1 is voiceless (and more easily distinguished from N), it should exhibit nasal cluster dissimilation when NC1 is voiced (and less easily distinguished from N). As noted above, the only language in which nasal cluster dissimilation applies when NC1 is voiceless is Mori Bawah, and in this language there are independent reasons why the prediction cannot be tested. Nasal cluster dissimilation is attested most readily in Mori Bawah in forms prefixed with /moN-/, but the nasal of this prefix only surfaces when the root begins with a voiceless stop, as in (13) (data from Blust Reference Blust2012: 368).
(13)
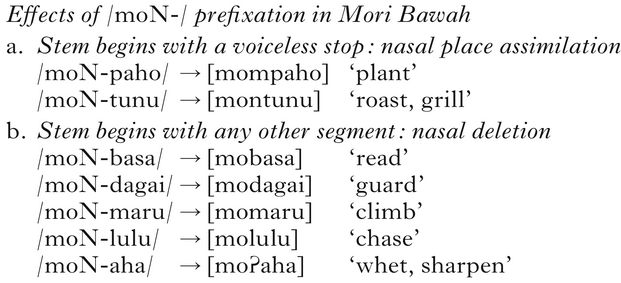
In this context nasal cluster dissimilation is only observable when NC1 is voiceless, as voiced NC1 cannot be created across a morpheme boundary, as in (1b.ii). This means that we cannot verify the prediction that nasal cluster dissimilation with voiceless NC1 implies nasal cluster dissimilation with voiced NC1, as the only language where nasal cluster dissimilation occurs with voiceless NC1 independently prohibits voiced NC1 in the relevant position.
3.2 Place of articulation and evidence from Ngaju Dayak
If nasal cluster dissimilation is influenced by the duration of NC1’s oral release, factors that influence release duration should influence nasal cluster dissimilation. One such factor is place of articulation, which is known to underlie variations in voice onset time (VOT). For example, Cho & Ladefoged (Reference Cho and Ladefoged1999: 219) find that stop VOT tends to increase as the closure moves further back into the vocal tract, though there is variation across languages. Given this, it is impossible to make universal predictions regarding correlations between nasal cluster dissimilation and the place of articulation of NC1, but we can predict that the two should correlate similarly with release duration: the longer NC1’s release, the less likely nasal cluster dissimilation should be.
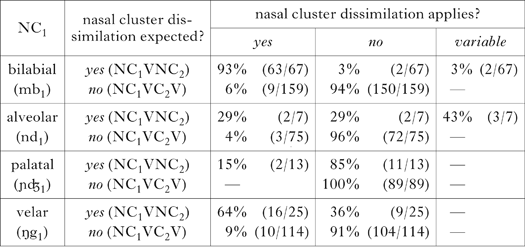
Cases of nasal cluster dissimilation that track NC1’s place of articulation are uncommon; the only well-documented case I am aware of comes from Ngaju Dayak. Table IV (derived from Blust Reference Blust2012: 373, with data from Hardeland Reference Hardeland1859) summarises the rate of nasal cluster dissimilation according to the place of articulation of NC1 and whether or not nasal cluster dissimilation is expected. Across categories, the difference between the rates of nasal cluster dissimilation according to NC1’s following context (NC vs. C) demonstrate that nasal cluster dissimilation is conditioned by the presence of a following NC. Within the class of forms where nasal cluster dissimilation is expected, it applies most frequently when NC1 is labial, less so when NC1 is velar or alveolar and least when NC1 is palatal.
Nasal cluster dissimilation in Ngaju Dayak.

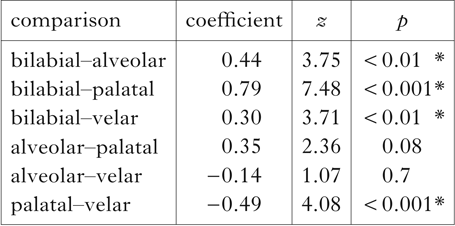
To determine which place-based differences are meaningful, a logistic regression was fitted (using R's glm function) to the forms in Table IV in which nasal cluster dissimilation is expected to apply. The dependent variable was whether or not nasal cluster dissimilation applies; the independent variable was NC1’s place of articulation. Variable cases were counted as nasal cluster dissimilation undergoers and non-undergoers. Pairwise differences in Table V were assessed with Tukey's HSD post hoc tests, using the glht function of R's multcomp package (Hothorn et al. Reference Hothorn, Bretz and Westfall2008). A positive coefficient means that the second member of the comparison is associated with a higher rate of nasal cluster dissimilation, while a negative coefficient means that the first is.
Pairwise comparisons for Ngaju Dayak dictionary data.

The rate of application for [mb]1 is lower than the rate of application for each of the other categories, and the rate of application for [ŋg]1 (and likely [nd]1) is lower than the rate of application for [ɲʤ]1. Taking into account the hypothesis of this section, and given these results, we can make predictions about the phonetics of Ngaju Dayak NCs: the average release duration of [mb] should be shorter than that of other categories, and the average release duration of [ŋg] (and likely [nd]) should be shorter than that of [ɲʤ]. (The data do not allow us to make any predictions about the relationship between [nd] and [ŋg].)Footnote 13
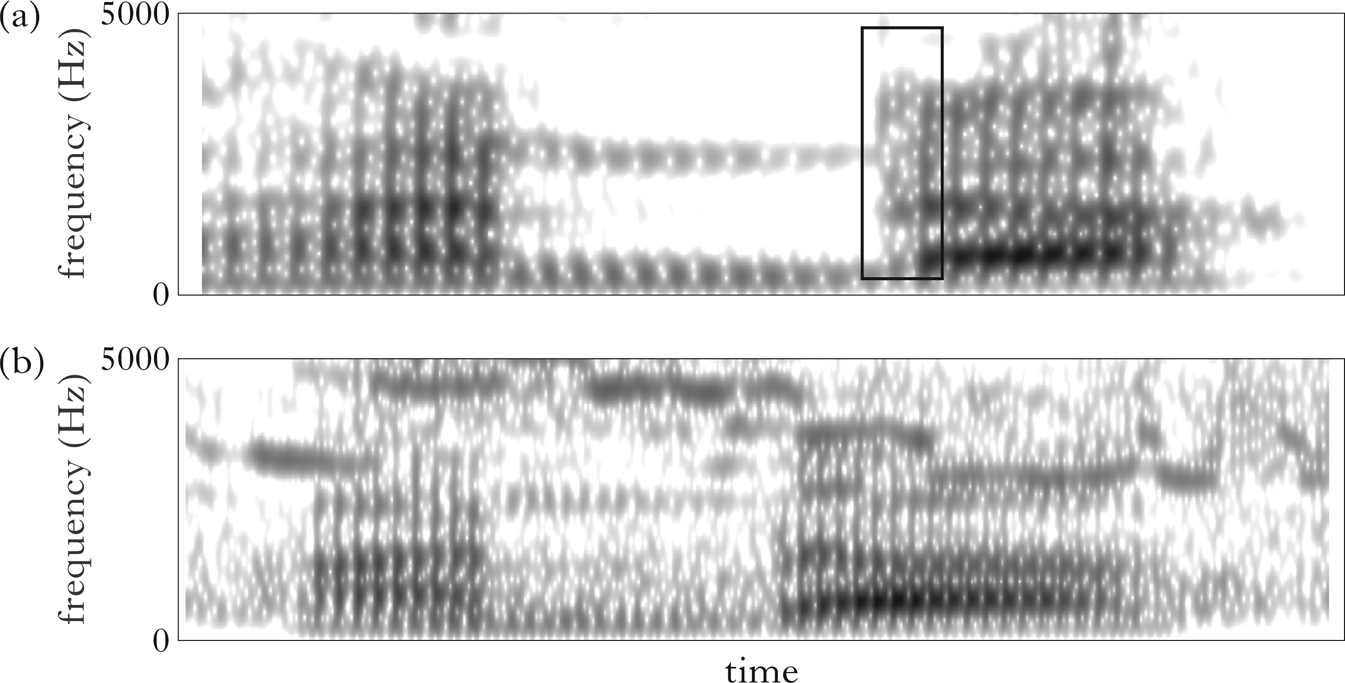
To test these predictions, data on the duration of oral NC releases was collected from recordings of the New Testament in Ngaju Dayak.Footnote 14 446 recordings of prevocalic [mb], [nd], [ɲʤ] and [ŋg] were obtained from the gospels of Matthew and John. For each cluster, the duration of the oral release was measured from the beginning of the stop burst until the onset of the vowel's periodic voicing. Speaker identity was not controlled for, though all speakers sounded male and spoke at similar rates. In 149 of the 446 recordings there was no observable stop burst, but the available Ngaju recordings are not of studio quality, and are often accompanied by background noise. Because of this, it is possible that the stop release was just obscured. Due to this complication, only tokens with clear stop releases were measured. Spectrograms of two tokens (one with a clear and observable stop release, and one without) are given in Fig. 2.
Measuring oral stop releases in Ngaju Dayak. (a) Observable stop release (boxed) in [handak]; (b) no observable stop release.

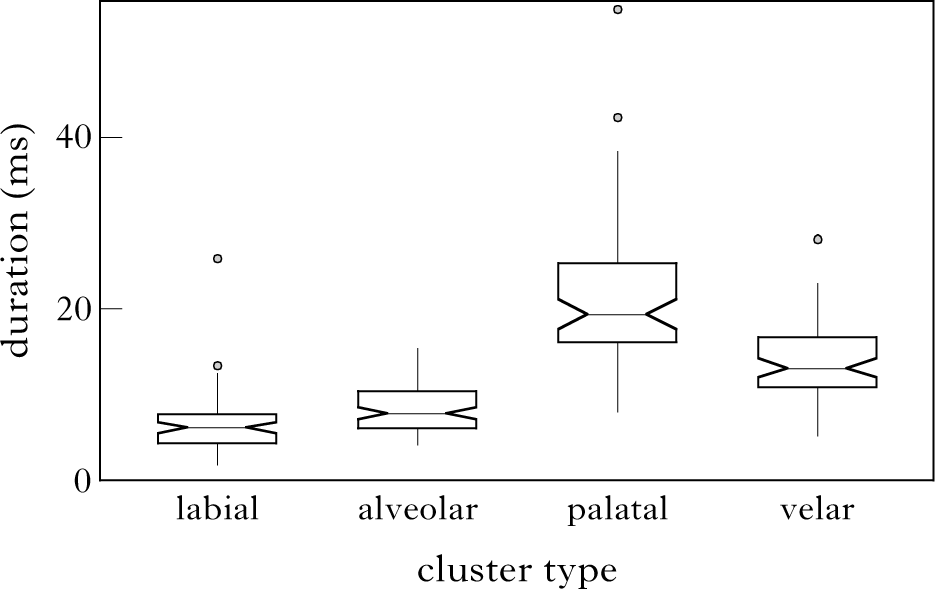
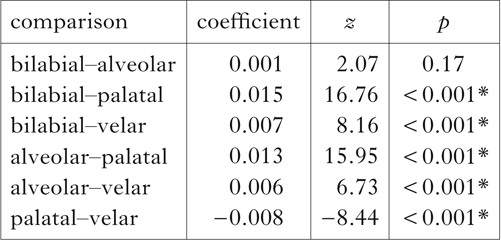
In total, 70 tokens of released [mb], 96 tokens of released [nd] and 65 tokens each of released [ɲʤ] and released [ŋg] were obtained. The resulting measurements are summarised in Fig. 3. These results confirm that asymmetries in release duration are the inverse of asymmetries in nasal cluster dissimilation frequency. [mb] has the shortest release; when NC1 in NC1VNC2 is [mb], nasal cluster dissimilation is most frequent. [ɲʤ] has the longest release; when NC1 is [ɲʤ], nasal cluster dissimilation is least frequent. Pairwise comparisons from a linear model, obtained again with the glht function of R's multcomp package, are given in Table VI; all comparisons except labial–alveolar are significant.
Oral release duration in Ngaju Dayak by place of articulation.

Pairwise comparisons for Ngaju Dayak release data.

The alveolars are involved in discrepancies between the dictionary and acoustic data: as shown in Tables V and VI, the bilabial–alveolar comparison is significant in the dictionary data but not the acoustic data, and the alveolar–velar comparison is significant in the acoustic data but not the dictionary data. Given the low number of alveolar tokens in the dictionary (n = 7), it is likely that these discrepancies reflect limitations in the data. The results of this small study thus indicate a plausible correlation in Ngaju Dayak between the rate of nasal cluster dissimilation and the average duration of the oral release of NC1.
3.3 Analysis
The evidence in this section suggests that NC-internal properties play an independent role in nasal cluster dissimilation. I formalise this by introducing MinDist constraints that require NC to have an oral release of at least a certain duration to be sufficiently distinct from N. I again assume that learners are capable of grouping NCs into separate categories (Relx) according to the duration of their release; the exact constitution of the categories depends on language-specific asymmetries in release duration. The fact that nasal cluster dissimilation only rarely targets NC1VNC2 when NC1 is voiceless suggests that, in most languages, NCs are divided into at least two categories: one for voiceless NCs (with longer releases) and another for voiced NCs (with shorter releases). In addition, the correlation between place of articulation and nasal cluster dissimilation in Ngaju Dayak suggests that these categories can be more fine-grained; it is useful in this case to assume that voiced NCs are divided up as in (14).
(14)
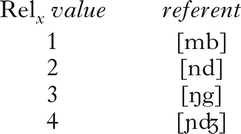
Given this scale, we can define the three MinDist constraints in (15) along the Rel dimension.
(15)
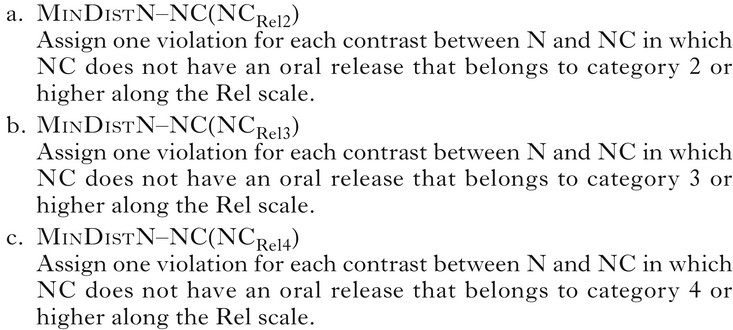
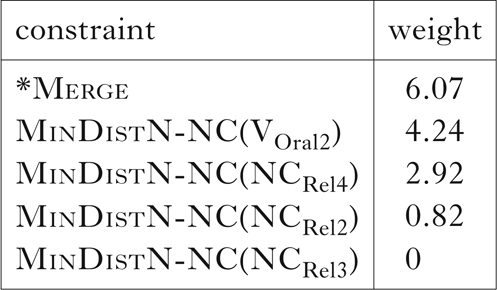
In Ngaju Dayak, the combined influences of the lefthand and righthand contexts can be modelled as additive interactions of MinDist constraints along the Rel and Oral dimensions. Put slightly differently, the penalty assigned to a given N–NC contrast depends on two factors: the identity of the NC and the identity of the righthand context. To illustrate this explicitly, I fitted a MaxEnt grammar to the Ngaju Dayak data in Table IV using five constraints: the MinDist constraints in (15), *Merge in (4c) and MinDistN–NC(VOral2) in (4a); I assume that Oral = 1 for vowels preceding NC and that Oral = 2 for vowels preceding C. The weights discovered by the MaxEnt grammar tool (Hayes et al. Reference Hayes, Wilson and George2008) are given in Table VII.
Weights for Ngaju Dayak count data.

These constraints interact to approximate the frequency counts. In the case of labials, for example, the combined weights of the MinDist constraints along the Oral and Rel dimensions result in an overwhelming likelihood that the [m–mb] contrast neutralises in the NC1VNC2 context. Numeric subscripts in (16a) indicate a value along the Oral or Rel scale; alphabetical subscripts indicate correspondence.
(16)
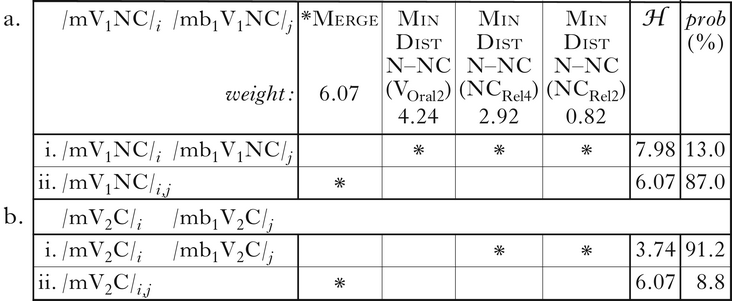
In the NC1VC2 context, MinDistN–NC(VOral2) is satisfied, so the candidate with an [m–mb] contrast has a lower harmony score. As shown in (16b), this results in a lower (though correctly non-zero) probability that neutralisation occurs in this context.
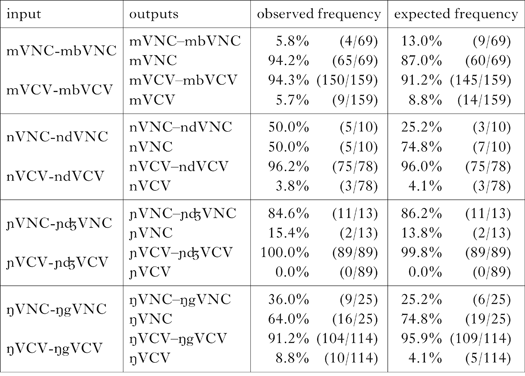
Overall results are summarised in Table VIII. The model captures the fact that nasal cluster dissimilation occurs more frequently with following NC2 than with following C2; the predicted frequencies of nasal cluster dissimilation, like the observed ones, are higher in in the VNC context than they are in the VC context. It also captures the fact that the rate of N–NC1 neutralisation tracks the average duration of NC1’s oral release: the predicted and observed frequencies of nasal cluster dissimilation given palatal N–NC1, for example, are lower than for labial N–NC1.
Results of MaxEnt analysis for Ngaju Dayak count data.

Decomposing MinDist constraints on the N–NC contrast in this way predicts that NCs with longer releases should be generally preferred to those with shorter releases. While this prediction has not been investigated systematically, one potential piece of supporting evidence comes from nasal substitution in Tagalog (Zuraw Reference Zuraw2010): among stems with initial voiced stops, substitution occurs most frequently with [N-b], less frequently with [N-d] and least frequently with [N-g]. If the phonetics of Tagalog voiced NCs mirror those of Ngaju Dayak, then Zuraw's finding is potentially explicable by the factors discussed here.
4 Experimental support
The proposed analysis for asymmetries in the nasal cluster dissimilation typology rests on two hypotheses regarding factors that make an NC more or less confusable with N, as summarised in (17).
(17)
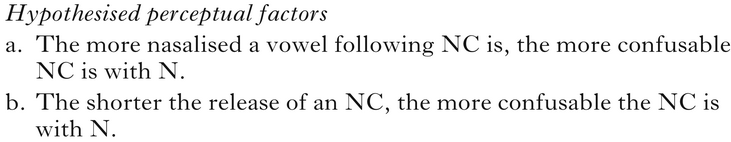
Both of these hypothesised factors are consistent with what is currently known about the perception of NCs, but are not supported in their specific form. Regarding (17a), Beddor & Onsuwan (Reference Beddor, Onsuwan, Sol, Recasens and Romero2003) show that Ikalanga speakers’ ability to correctly identify [mb] is negatively impacted by the presence of nasalisation in a following vowel: speakers correctly identify [mb] most frequently when followed by an oral vowel, less frequently when followed by a vowel whose initial 36% is nasalised, even less frequently when followed by a vowel whose initial 68% is nasalised and least frequently when followed by a fully nasal vowel. But showing that perception of NC depends on the duration of nasalisation immediately following the release is quite different from showing that perception of NC depends on the amount of regressive coarticulatory nasalisation from a following nasal consonant (which may not extend to the first NC's release), so Beddor & Onsuwan's results do not necessarily support (17a). Regarding (17b), Beddor & Onsuwan show that Ikalanga speakers’ ability to correctly identify [mb] is impacted by the duration of the oral closure and release burst: averaging across following contexts, correct identification rates of [mb] were highest when [mb]’s oral closure and release burst was 27 ms, lower at 18 ms, still lower at 9 ms and lowest when it was absent. These results support the general idea that perception of NC is dependent on the salience of its oral release, but not the specific hypothesis in (17b).
This section reports the results of an AX task designed to investigate the hypotheses as they are formulated in (17). An AX task was chosen because it allows for a direct test of the hypothesis that listeners’ ability to discriminate N and NC depends on the contrast's segmental environment, and also because it is a standard task used to investigate hypotheses of this sort (e.g. Gallagher Reference Gallagher2010). In what follows I show that the results are largely consistent with (17).
4.1 Materials
The stimuli for this experiment were trisyllabic nonce words produced by a male native speaker of Peruvian Spanish. Spanish was selected as the language for the stimuli because it is a language with different patterns of coarticulatory nasalisation than are found in English. It is well-known that anticipatory nasal coarticulation in English is extensive, especially when the nasal consonant is preconsonantal or word-final (see Cohn Reference Cohn1990), leading many authors to argue that nasalisation in English is phonological, or ‘part of the programming instructions and not a function of physiological constraints of the vocal organs’ (Solé Reference Solé1992: 30). In Spanish, by contrast, coarticulatory nasalisation is less extensive, suggesting that nasalised vowels are ‘targeted as oral, and nasalization is the result of a physiological time constraint’ (Solé Reference Solé1992: 38). Using productions from a Spanish speaker leads to a more conservative test of the hypothesis in (17a) than using stimuli produced by an English speaker, because, all else being equal, we would expect that in an NC1VNC2 sequence there should be less nasalisation in the intervening V when the sequence is produced by a Spanish speaker.
To facilitate analysis of the productions, a larger number of forms were recorded than were used in the task. For the recorded items, the first consonant (C1) was /p t k/, the second consonant or consonant sequence (C2) was /m mb mp n nd nt ɲ ɲʧ/ and the third consonant or consonant sequence (C3) was /d n nd nt/. In all cases, C1, C2 and C3 were followed by /a/. Crossing these properties led to 120 forms like /pamanta, kantanta, tandada/. The speaker was given a list with these 120 forms, plus a filler form at both ends, and asked to read the list twice, at a normal speech rate. Recordings were made with a Marantz PMD-661 MKIII solid-state recorder and a Shure SM-35 microphone in a soundproof booth at New York University.
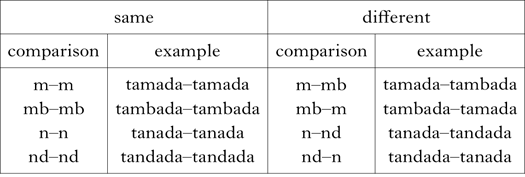
Stimuli were created from the recordings. The contrast of interest in this experiment was N–ND, so C2 in the ‘same’ items contained either identical nasals or identical voiced nasal–stop clusters, and C2 in the ‘different’ items contained one of each (see Table IX). This contrast was compared across four contexts: /d n nd nt/ in C3. C1 was a filler consonant and was balanced across /p t k/. For ‘same’ items, two recordings of the same word were used where possible; for the three forms where there was only one fluent production (/pambanda, pandada, tandanda/), the fluent recording was duplicated. For ‘different’ items, recordings chosen were those whose intonation matched most closely. This resulted in a set of 96 stimuli that were balanced across all conditions.
Examples of ‘same’ and ‘different’ items.

An AX task with these items allows us to test the hypotheses in (17). First, varying the identity of C3 tests the hypothesis that discrimination of N and NC should depend on the amount of nasalisation in the intermediate vowel. If vowels are more nasalised before /nd/ than before /d/, for example, we would expect listeners to be more sensitive to the distinction between /pamada/ and /pambada/ than they are to the distinction between /pamanda/ and /pambanda/. Second, varying the identity of C2 tests the hypothesis that discrimination of N–NC should depend on the duration of NC's release. If releases of /nd/ are longer than those of /mb/, for example, then we might expect listeners to be more sensitive to the distinction between /pananda/ and /pandanda/ than they are to the distinction between /pamanda/ and /pambanda/. As specific predictions regarding listener behaviour depend on acoustic properties of the speakers’ productions, I investigate these next.
4.2 Acoustic properties of productions
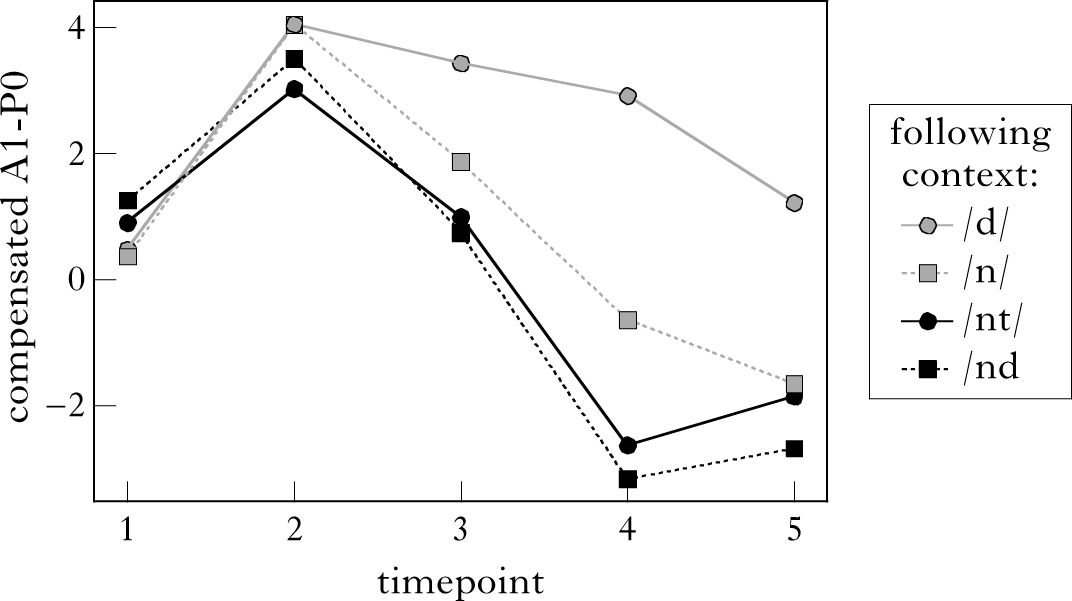
To quantify the amount of nasalisation in vowels preceding /d n nd nt/, I submitted each of the 240 words recorded to the Nasality Automeasure Script Package (Styler & Scarborough Reference Styler and Scarborough2015). The decision to use all recordings (not just those incorporated into the stimuli) was made in response to Styler & Scarborough's statement that ‘the best approach [to A1-P0 measurement] is to compare large groups of tokens across differing conditions’. The compensated A1-P0 was measured at five equally spaced timepoints throughout the vowel between C2 and C3 (e.g. /pambada/); timepoints 1 and 5 were offset 5 ms from the beginning and end of the vowel. Of 1200 possible measurements, the script took 1173. The y-axis in Fig. 4 is compensated A1-P0; lower A1-P0 measures are correlated with an increased amount of nasalisation. The relative ordering of the following contexts in the key represents their relative ordering at timepoint 5. As was the case for Fig. 1, the exact A1-P0 values are not important here – what matters are the relative differences in A1-P0 between conditions at each timepoint.
Compensated A1-P0 in Spanish vowels by following context.

Several things are apparent. First, effects of anticipatory nasalisation in this speaker's productions only extend to around the vowel's midpoint: the mean A1-P0 for vowels preceding /d/ is higher at timepoints 3–5 than the mean values of vowels that precede an onset or a coda nasal, but this difference is mostly neutralised at earlier timepoints. Second, the amount of anticipatory nasalisation depends on the syllabic role of the nasal in C3: starting at timepoints 2–3, vowels preceding /nd nt/ are more nasalised than vowels preceding /n/. Finally, the relationship between /nd/ and /nt/ changes over the vowel's time-course. At timepoints 1–2, the vowel preceding /nt/ is more nasalised than the vowel preceding /nd/; at timepoints 3–5, the reverse holds.
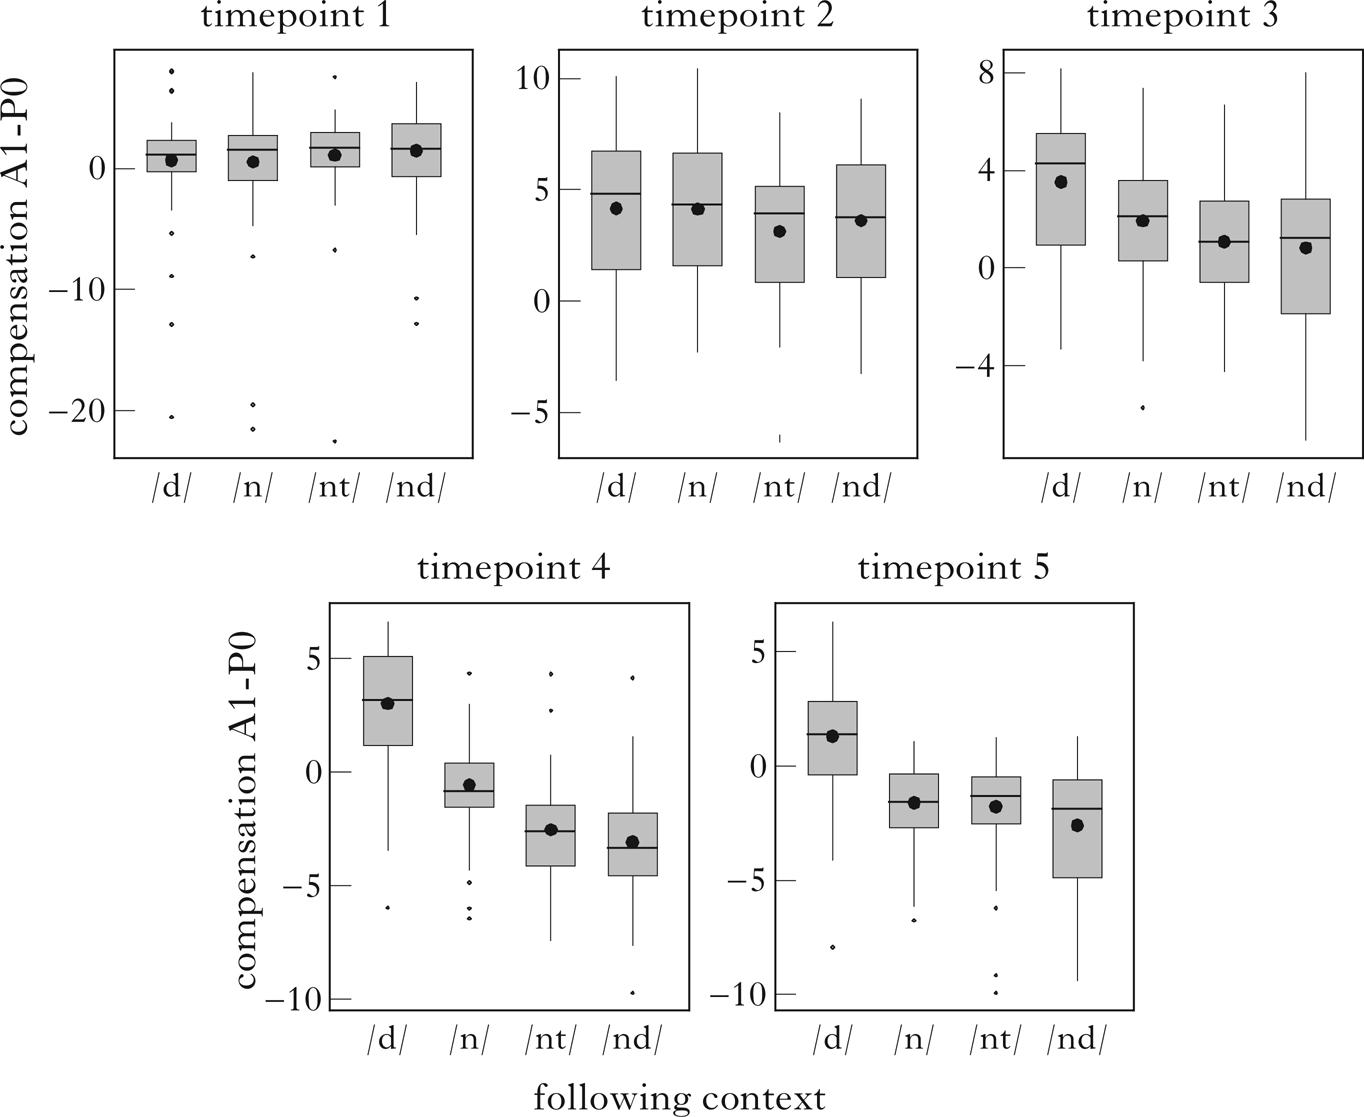
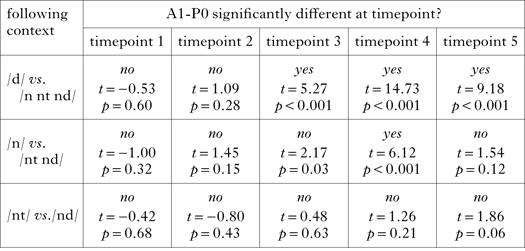
The boxplots in Fig. 5 provide a better sense of the relationship between the categories at each timepoint by plotting by-timepoint A1-P0 values according to the identity of C3. To determine which differences were meaningful, a linear regression was fitted to each timepoint with R's lm function. The dependent variable was compensated A1-P0, and the independent variable was the identity of C3. This predictor was helmert-coded: comparisons were between the oral and nasal contexts (/d/ vs. /n nt nd/), the onset and coda nasal contexts (/n/ vs. /nt nd/) and the voiceless and voiced NCs (/nt/ vs. /nd/). Generally speaking, the models found asymmetries in A1-P0 between the oral and nasal contexts as well as between the prevocalic and non-prevocalic nasal contexts at the midpoint of the vowel and later. Full results are summarised in Table X. A positive coefficient indicates that the first term in the comparison has a higher A1-P0 (or is less nasal); a negative coefficient indicates that A1-P0 in the second term is higher. Note that in Table X the significance level is taken to be p < 0.01, to correct for multiple comparisons (with five tests, the Bonferroni correction is 0.05/5 = 0.01).
Compensated A1-P0 in Spanish vowels by timepoint.

Statistical analyses of nasalisation data.

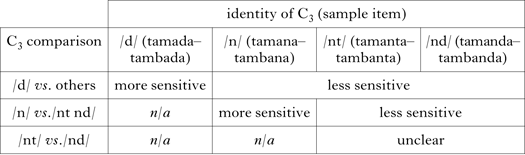
For the purposes of the experiment, predictions regarding listener behaviour depend on what is attended to while the listener attempts to determine whether C2 in a word like /tambanda/ is an N or NC. If the listener makes the distinction using only properties of the consonantal release and the oral vs. nasal quality of the first part of the following vowel, we would not expect discrimination of N vs. NC to depend on the identity of C3. If, however, the listener's decision process takes into account the oral vs. nasal quality of the following vowel at its midpoint or later, we might expect to find that their response patterns mirror acoustic properties of the stimuli at timepoints 3–5. In particular, listeners should be better at discriminating N–NC contrasts before /d/ than before /n nt nd/; they should also be better at discriminating N–NC contrasts before /n/ than before /nt nd/. As there are no significant differences in the amount of nasalisation before /nt/ and /nd/, it is unclear what to expect for this comparison. These predictions are summarised in Table XI.
Predictions regarding discriminability of N-NC by following context (C3).

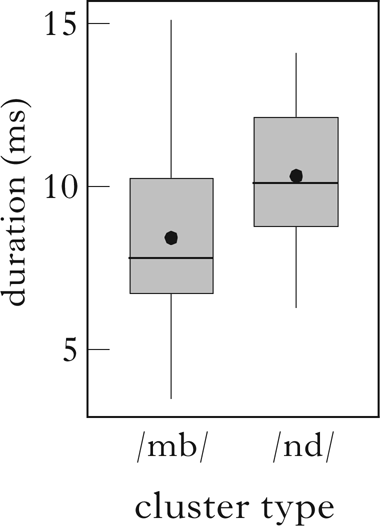
The second manipulation has to do with the identity of C2, which was either labial (/m mb/) or alveolar (/n nd/). To know if listeners are expected to respond differently to these two stimulus types, it is necessary to know if release duration differs by place of articulation. To determine this, I measured the duration of the release, defined here as the combined duration of burst and VOT, of each /mb/ and /nd/ recorded (49 in total: 24 /mb/ and 25 /nd/). Figure 6 shows that the release of /nd/ is significantly longer than the release of /mb/ (t = 2.63, p < 0.05; linear regression). The prediction in this case is straightforward: listeners may be more sensitive to the distinction between /n/ and /nd/ (where the oral release is longer) than they are to the distinction between /m/ and /mb/ (where the release is shorter). Note that the difference between these two categories is small: the mean release durations for /mb/ and /nd/ are 8 ms and 10 ms respectively. Probing this distinction was an intentionally conservative choice. If listeners are more sensitive to the /m/ vs. /mb/ distinction than they are to /n/ vs. /nd/, one can reasonably expect that listeners will also be sensitive to greater differences in release duration (like that for /mb/ vs. /nʤ/ or /mp/).
Release duration of /mb/ and /nd/.

4.3 Procedure
39 participants, all native English speakers, were recruited using flyers, the NYU Facebook community and Craigslist (a classified advertisements website). The experiment was conducted with OpenSesame (Mathôt et al. Reference Mathôt, Schreij and Theeuwes2012) on a laptop computer. Participants completed the experiment in a quiet room wearing Audio Technica ATH-ANC9 headphones, and were compensated for their time.
During the experiment, participants were presented with eight trial items: four ‘same’ (/kananta/, /taɲana/, /tantada/, /paɲʧana/) and four ‘different’, which did not contain comparisons repeated in the test items (/kaɲanta–tampada/, /taɲanta–pampana/, /kananta–kantanta/, /padanta–panata/). The block of 96 test items followed. While a sound file was playing, there was a black dot on the screen; participants were directed to decide during this period whether they were hearing two different recordings of the same word or two recordings of different words. After the recording finished, a new screen appeared, with ‘Same (1)’ at the left edge and ‘Different (0)’ at the right. Participants were instructed to press 1 if they thought the two recordings were of the same word, and 0 if they thought the two recordings were of different words. They were asked to indicate their responses as soon as possible after the black dot disappeared (but not beforehand), and warned that if they did not respond quickly the experiment would move on to the next set of recordings. For all stimuli the interstimulus interval was 250 ms and the maximum response time 1500 ms.
4.4 Results
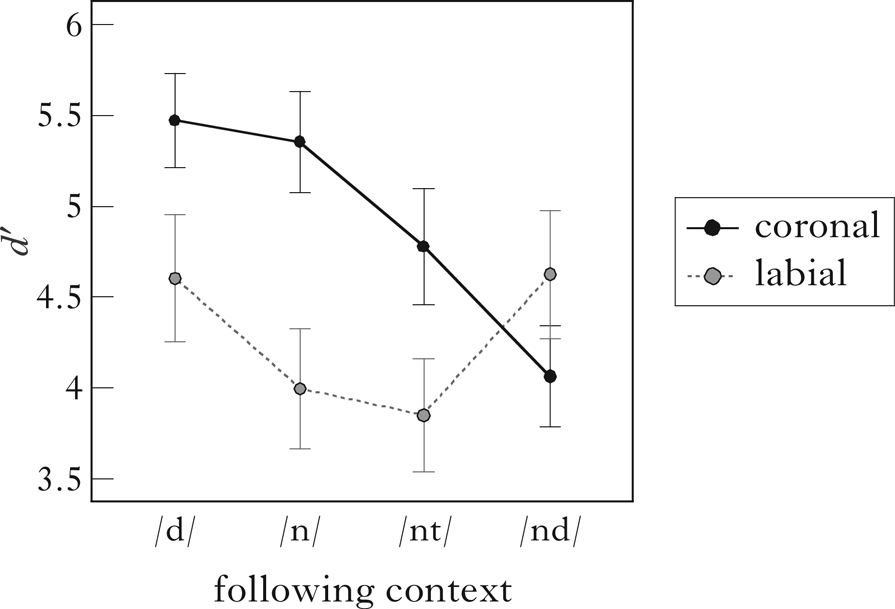
Accuracy was above chance for both types of item; the hit rate (a correct ‘different’ answer for a ‘different’ item) was 81% and the false alarm rate (an incorrect ‘different’ answer for a ‘same’ item) was 12%. Results are plotted by C3 context in Fig. 7, with the two series representing the by-participant d′s for labial and coronal C2 (dots indicate the mean value; error bars indicate the standard error).Footnote 15 These d′ values were obtained from Macmillan & Creelman (Reference Macmillan and Creelman2005: A5.4) and assume the differencing model, as is appropriate for an AX task with a roving design. The lower the d′, the less sensitive participants were to whether items in that group were ‘same’ or ‘different’. The lines in Fig. 7 are included as an aid to interpretation, and do not represent change over time. The d′ values are largely, but not entirely, consistent with the predictions in (17). Focusing on the coronals: the average d′ value for /n–nd/ lowers across C3 contexts (from /d/ to /n/ to /nd/ to /nt/). These results are consistent with the predictions in Table XI, though the difference in d′ between the /nd/ and /nt/ contexts is perhaps unexpected. Focusing on the labials: the average d′ for /m–mb/ contrasts lowers across most C3 contexts (from /d/ to /n/ to /nd/). This much is consistent with the predictions in Table XI. The average d′ for /m–mb/ with /nd/ as C3, however, is higher than all of the other labial d′ values, which is not expected: given the average amount of nasalisation in the /nd/ context, its d′ was predicted to be lower than those of the /d/ and /n/ contexts.
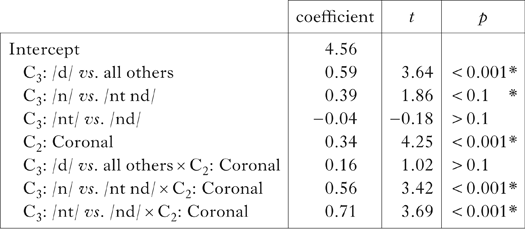
A mixed-effects linear regression was fitted to the d′ values using the lmer function of R's lme4 package (Bates et al. Reference Bates, Mächler, Bolker and Walker2015). The response variable was d′; independent variables included the identity of C3 (helmert-coded, with comparisons of /d/ vs. all others, /n/ vs. /nt nd nt/ vs. /nd/), C2’s place of articulation (sum-coded, with a comparison between Coronal and the grand mean) and an interaction. By-participant random slopes for C3’s identity and C2’s place of articulation were also included. p-values were calculated with R's lmerTest package (Kuznetsova et al. Reference Kuznetsova, Brockhoff and Christensen2017).Footnote 16 A summary of the model is given in Table XII.
Compensated A1-P0 in Spanish vowels by timepoint.

Summary of full statistical model.

The main effect in C3: /d/ vs. all others confirms that N–ND is more distinct when C3 is /d/ than when it is /n/, /nt/ or /nd/ (so Δ/pamada–pambada/ > Δ/pamana–pambana/, /pamanda–pambanda/, /pamanta–pambanta/). The main effect in C2: Coronal confirms that, across contexts, the N–ND distinction is more perceptible for coronals than it is on average; since coronals and labials are the only places of articulation considered, it must the case that N–ND is more perceptible for coronals than it is for labials (so Δ/panada–pandada/ > Δ/pamada–pambada/). These results parallel the acoustic data: the release of /mb/ is shorter than that of /nd/, and vowels preceding /d/ are, from their midpoint onwards, the most oral. (This latter correlation also suggests that listeners’ discrimination of N–ND is at least partially dependent on information later in the vowel.)
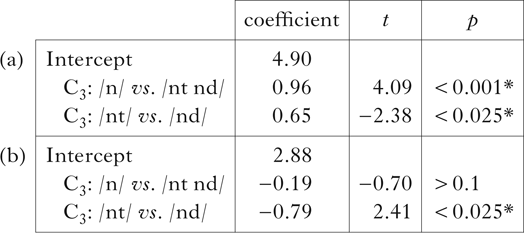
The last two interactions in Table XII indicate that the further comparisons across C3 contexts are dependent on C2’s identity. To investigate these effects more directly, separate models were fitted to the labial and coronal data. The independent variable was C3’s identity (helmert-coded, with all comparisons included above), and a random intercept was included for participant. These models are summarised in Table XIII; note that the significance level is taken to be p < 0.025, to correct for multiple comparisons (with two tests, the Bonferroni correction is 0.05/2 = 0.025).
Summary of full statistical model (a) for coronals in C2 position; (b) for labials in C2 position.

For the coronals, (a) indicates that /n–nd/ is more perceptible when C3 is /n/ than when it is /nt/ or /nd/ (Δ/panana–pandana/ > Δ/pananda–pandanda/, /pananta–pandanta)/. This comparison across contexts was not significant for the labials in (b), indicating that the trending main effect in Table XII was driven by the coronals. The comparison between C3 = /nt/ and C3 = /nd/ was significant for both places of articulation, though in opposite directions. For the coronals, discrimination was better before /nt/ (Δ/pananta–pandanta/ > Δ/pananda–pandanda/ in Table XIIIa); for the labials, discrimination was better before /nd/ (Δ/pamanda–pambanda/ > Δ/pamanta–pambanta/ in (b)).
4.5 Summary
The experiment discussed here tested the two hypotheses in (17) above, which arose from a consideration of both typological and language-specific restrictions on nasal cluster dissimilation. The results are largely consistent with the hypotheses: participants discriminate N–NC more reliably when it is in an oral context than when it is in a nasal context, and when NC's release is longer. Beyond this point, the results differed by place of articulation. The coronal response data are consistent with the further hypothesis that discrimination of N–NC before /n/ should be more reliable than before /nd/ and /nt/, but the labial response data are not. In addition, neither of the significant comparisons between C3 = /nd/ and C3 = /nt/ were predicted from the acoustic data. Given that the most reliable distinction in the acoustic data was that between the oral and nasal contexts, however, the lack of consistent effects for these last comparisons is perhaps not surprising.
A reviewer and the associate editor raise a concern that the labial response data are not consistent with the hypothesis in (17a). First, as shown above, this is not entirely true: as predicted, the average d′ for the labial context was higher when C3 was /d/ than when C3 was /n/ or /nt/. While it is true that the high d′ for C3 as /nd/ runs contrary to the predictions in (17), there is no obvious explanation for this anomaly. Determining whether or not this result presents a problem for the proposed analysis of NCD requires further experimental work, to see if the result replicates. It is unrealistic to expect that one iteration of a single experimental task would find evidence consistent with all stated predictions. Further iterations of this task would be necessary to determine which aspects of the results replicate and, by extension, continue to support or contradict the hypotheses in (17).
5 Further links between NCṼ and nasal cluster dissimilation
Anticipatory nasalisation of the intermediate vowel in NC1VN(C)2 is only one of the ways that an NC can come to precede a nasal(ised) vowel. Many languages also license contrasts in vocalic nasality, and NCṼ sequences (where Ṽ is a phonemically nasal vowel) are in principle possible in these languages. All else being equal, we would expect that languages that prioritise maximally distinct N–NC contrasts should disprefer NCṼ and NC1VN(C)2.
There are, however, differences in the amount of nasalisation exhibited by contrastive and non-contrastively nasalised vowels. In the cases I am aware of, contrastively nasalised vowels are more nasalised than coarticulatorily nasalised vowels in both the extent and intensity of acoustic nasality (e.g. Cohn Reference Cohn1990 on French). We might expect NC to be more distinct from N before VN(C), where the vowel is less nasal, than it is before Ṽ, where the vowel is more nasal. If this asymmetry holds cross-linguistically, the predictions in (18) follow.
(18)
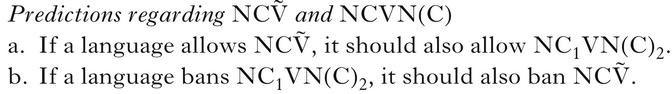
As is true for all of the generalisations discussed in this article, (18) follows from the way that MinDist constraints are defined: if N–NC is penalised in a context where it is more distinct, it must also be penalised in all contexts where it is equally or less distinct. I next show that these predictions hold.
5.1 Prediction 1: NCṼ implies NC1VN2
To test the prediction that NCṼ in a given language implies NC1VN(C)2, I searched for languages that allow NCs and a vocalic nasality contrast. Languages were identified from reference grammars at MIT's Hayden Library and online periodicals. An important criterion for inclusion was that an N–NC contrast exist: languages like Apinayé and Siriono, though identified by Maddieson (Reference Maddieson1984) as allowing NCs and a vocalic nasality contrast, do not qualify. In these and other South American languages, Ns and NCs are allophones conditioned by the quality of the neighbouring vowels (see e.g. Herbert Reference Herbert1986, Stanton Reference Stanton2018). As the focus here is on the effects of vocalic nasality on N–NC, these languages are not directly relevant for the discussion that follows.
Altogether, 23 relevant languages were identified (see Appendix B for a full list). Of these 23, twelve allow NCṼ sequences; the fact that eleven do not speaks to the more general claim that NCṼ sequences are dispreferred. As predicted, all languages that allow NCṼ allow NC1VN(C)2. A representative example comes from Mbay (Keegan Reference Keegan1996), where the presence of minimal pairs indicates that vowel nasality is contrastive following NCs (19a), and NC1VN(C)2 sequences are attested (19b).
(19)
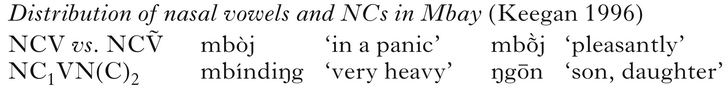
Equivalent forms from each of the other twelve relevant languages are provided in Appendix B.
5.2 Prediction 2: *NC1VN(C)2 implies *NCṼ
To test the prediction that *NC1VN(C)2 implies *NCṼ, I attempted to find information about the vocalic inventories of each language included in the survey of nasal cluster dissimilation. Of the languages surveyed, I was able to find this information for 43, of which only Sango (Samarin Reference Samarin1967), Saramaccan (McWhorter & Good Reference McWhorter and Good2012) and Zande (Gore Reference Gore1931) license a contrast in vocalic nasality, as shown in (20).
(20)
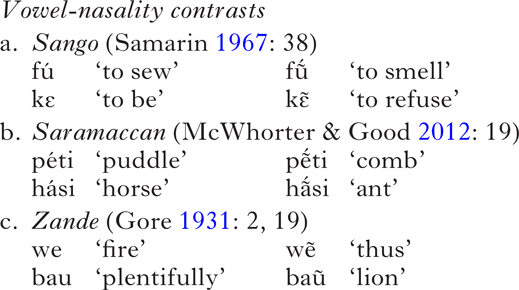
In none of these languages does it appear that NCṼ sequences are robustly attested. McWhorter & Good (Reference McWhorter and Good2012: 26) explicitly note their rarity in Saramaccan: the only NCṼ sequence in Saramaccan occurs in the ideophone [gíŋgí] ~ [giŋgĩ́] ‘stuck fast’, and even in this case, as shown, there is variation between NCV and NCṼ. In the cases of Sango and Zande, these restrictions are not discussed explicitly, but are inferred through the lack of NCṼ-containing forms in the cited sources.
The predictions outlined in (18), then, are verified.
6 Discussion and conclusions
This article has argued that typological, acoustic and perceptual evidence is consistent with an analysis in which nasal cluster dissimilation is driven by constraints on the distinctiveness of the contrast between NC1 and a plain nasal, N. §6.1 and §6.2 discuss two possible alternative analyses, and §6.3 discusses some implications.
6.1 Alternative 1: a diachronic analysis
The analysis proposed in this article claims that considerations of perceptual distinctiveness are an integral part of speakers’ phonological competence (Flemming Reference Flemming2002). But we should also consider the viability of a diachronic alternative (à la Ohala Reference Ohala, Masek, Hendrick and Miller1981, Blevins Reference Blevins2004, Moreton Reference Moreton2008): is it possible that considerations of N–NC contrast distinctiveness correlate with nasal cluster dissimilation not because they are part of the grammar, but because nasal cluster dissimilation reflects the fact that insufficiently distinct N–NC contrasts are more likely to be misapprehended and neutralised over time?
The primary difficulty for this alternative is that the kinds of alternations instantiating nasal cluster dissimilation are diverse, and not all of them can be viewed as the result of diachronic neutralisation. Given an illicit NC1VNC2 sequence, languages in the survey generally display one of three possible responses: deletion of C1 (1a), N1 (1b) or N2 (21) (see also Jones Reference Jones2000).Footnote 17
(21)
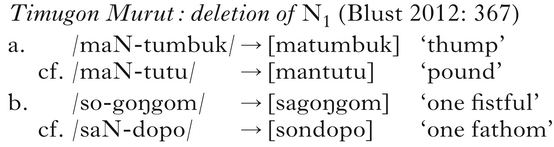
The alternations in (1a) instantiate N–NC1 neutralisation as a response to an insufficiently distinct N–NC contrast, but the alternations in (1b) and (21) cannot be characterised in this way. N2 deletion in (1b) is a type of enhancement: by removing the source of coarticulatory nasalisation, N–NC1 is rendered more distinct. N1 deletion in (21) could also be conceived of as a type of enhancement: the contrast between C1 and nothing could also be enhanced by removing the lefthand N. Contrast enhancement is generally harder to account for in a framework in which the role of phonetic information in phonology is relegated to diachrony: in order to render an insufficiently distinct contrast more distinct, the speaker must be aware that it is insufficiently distinct in the first place (though see Blevins Reference Blevins2004: 285–289). Thus the existence of enhancement phenomena here and elsewhere suggests that contrast is a primitive of the synchronic grammar.
A reviewer notes that it is perhaps possible to account for the apparent enhancement phenomena in (1b) and (21) by appealing to perceptual hypocorrection. While this is of course a possibility, it is not obvious to me what form such an analysis would take, nor am I aware of any existing concrete proposal along these lines. The point is only that, given the current analytical options on the table, I believe that analyses treating contrast as a primitive fare better in accounting for the relationship between neutralisation and enhancement (see also Stanton Reference Stanton2018 on this point).
6.2 Alternative 2: a co-occurrence constraint
A second alternative, proposed by Alderete (Reference Alderete1997), Blust (Reference Blust2012) and others, is that nasal cluster dissimilation arises due to the activity of a co-occurrence constraint (*NC…NC) that penalises words containing sequences of NCs. One of the stronger pieces of evidence against this analysis comes from generalisations discussed in §5: languages that allow NCṼ allow NC1VNC2, and languages that ban NC1VNC2 ban NCṼ. These generalisations would not be expected in a theory where nasal cluster dissimilation is motivated by a co-occurrence constraint. Such a theory would not predict a link between the NC1VNC2 and NCṼ, as the constraint penalising NCVNC (*NC…NC) would not penalise NCṼ. The absence of systems that allow NCṼ but not NC1VNC2, for example, suggests that there is no constraint penalising NC1VNC2 to the exclusion of NCṼ. Put differently, the observed link between the NCṼ and the NC1VN(C)2 typologies suggests that the desire to avoid indistinct N–NC1 contrasts is not just one possible motivation for nasal cluster dissimilation, but that it is the only possible motivation.
Beyond this, some aspects of the results discussed here are difficult for a co-occurrence-based analysis. I first discuss typological generalisations with no obvious explanation under this analysis, and then consider links between the generalisations and the extant acoustic and perceptual data.
In §2, it was shown that two broad generalisations characterise the typology of nasal cluster dissimilation: repair of NC1VNC2 implies repair of NC1VN2V, and repair of one of NC1VNC2 or NC1VN2 implies repair of the other. The second of these generalisations could be captured by proposing that the relevant constraint is actually one on co-occurring coda nasals (*N]σ…N]σ), but the first is more difficult for a co-occurrence-based account. While the ban on NC1VNC2 and NC1VN2 can be straightforwardly captured by *N]σ…N]σ, this constraint does not penalise NC1VN2V. It would be difficult to explain under this alternative analysis why repair of NC1VN2V implies satisfaction of *N]σ…N]σ. Furthermore, even if a co-occurrence constraint existed that was capable of penalising NC1VNC2, NC1VN2 and NC1VN2V, this constraint would not, without further amendment, make predictions about directionality: it would penalise NC1VN2 and N1VNC2 equally. This is not the empirical result we want. Within the languages surveyed, restrictions on NC1VN2V are common, but restrictions on N1VNC2 are unattested. This directional asymmetry is, however, predicted by the contrast-based account. In N1VNC2V, all else being equal, NC2 will be followed by an oral vowel, rendering it maximally distinct along the Oral dimension. Put differently, the problem for NC1VN2V – that anticipatory nasalisation from N2 compromises cues to N–NC1 – does not exist for N1VNC2V. Turning to the generalisations discussed in §3, it is not obvious under a co-occurrence-based account why the identity of NC1, independent of the identity of NC2, should affect the likelihood of nasal cluster dissimilation. In Ngaju Dayak, for example, a co-occurrence-based theory has no reason to expect that nasal cluster dissimilation should be more frequent when NC1 is [mb] than it is when NC1 is [ɲʤ].
Finally, the links established in this article between nasal cluster dissimilation, acoustics and perception would not be explicable under a co-occurrence-based theory of nasal cluster dissimilation. First, consider the relationship between the Yindjibarndi data discussed in §2 and one aspect of the perceptual data in §4. With respect to Yindjibarndi, it was shown that the context in which nasal cluster dissimilation occurs (when NC2 is a labial or velar cluster) is the context in which the intermediate vowel carries the most coarticulatory nasalisation. This finding is consistent with the perceptual data, where listeners generally became less sensitive to the contrast between N and a voiced NC as the amount of coarticulatory nasalisation in the following vowel increased. Second, consider the relationship between the Ngaju Dayak data discussed in §3 and the other aspect of the perceptual data in §4. It was shown that increased rates of nasal cluster dissimilation in Ngaju Dayak are correlated with shorter stop releases. This finding is also consistent with the perceptual data, where listeners were less sensitive to the distinction between N and voiced NC when the release of NC was shorter. This article has thus established that there are links between nasal cluster dissimilation, acoustics and perception; these links are directly captured by the contrast-based analysis proposed here. A co-occurrence-based analysis of these same facts would be forced to treat the links established in this article as coincidental.
6.3 Implications for a theory of dissimilation
The overall conclusion of this article is that nasal cluster dissimilation is motivated by constraints on contrast, not by co-occurrence constraints. This conclusion leads to a new understanding of the entities targeted by co-occurrence constraints, and has connections with prior work that investigates perceptual bases for co-occurrence restrictions (e.g. Ohala Reference Ohala, Masek, Hendrick and Miller1981, Hall Reference Hall2008, Gallagher Reference Gallagher2010). These points are discussed in turn.
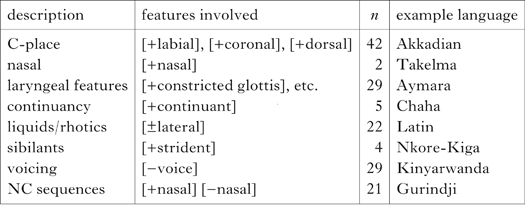
Nasal cluster dissimilation does not fit comfortably within the larger typology of dissimilation. Dissimilatory processes tend to target segments that share one or more features (e.g. [+labial] or [+spread glottis]). Nasal–stop sequences can be (but are not necessarily) treated as single segments by a language's phonology; regardless of its language-specific behaviour, however, an NC can only be characterised using a sequence of features (see especially Anderson Reference Anderson1976 on the difficulties of using a single feature matrix). In Bennett's (Reference Bennett2015) comprehensive survey of long-distance dissimilatory processes, the only processes that target sequences of features involve NCs, as shown in Table XIV.
Summary of Bennett's (2015) survey.

If we adopt the proposal that nasal cluster dissimilation can only be motivated by a constraint on contrast, it is possible to characterise the remaining restrictions in Table XIV by stating that co-occurrence constraints can target only a single feature or a feature bundle whose members are realised simultaneously. Possible co-occurrence constraints take the form *[α,β]…[α,β] (where [α] and [β] are realised simultaneously); I assume that co-occurrence constraints of the form *[α][β]…[α][β] (where [α] and [β] are realised sequentially) are not part of Con. Thus, in addition to its ability to account for generalisations present in the typology of nasal cluster dissimilation, the contrast-based analysis proposed in this article allows us to formulate a more restrictive theory of co-occurrence constraints.
This discussion leads to a larger question regarding the nature of the remaining co-occurrence restrictions in Table XIV: are dissimilatory effects really due to the activity of some constraint of the form *[α]…[α], or can they ultimately be attributed to other factors? The proposal that constraints on contrast drive nasal cluster dissimilation has precedent in work arguing that certain other types of dissimilation are perceptually motivated. Hall (Reference Hall2008), for example, argues that /r/-dissimilation in English is due to perceptual hypercorrection: /r/ is most likely to disappear in contexts where its presence is masked by another /r/ (e.g. in coda position; p[ɚ]ticular vs. p[ə]ticular). Gallagher (Reference Gallagher2010) argues on the basis of typological and experimental evidence that laryngeal co-occurrence restrictions are due to a constraint on contrast distinctiveness: words with multiple laryngeally marked segments (e.g. [k'ap'i]) are confusable with words that have only one (e.g. [k'api]).
Whether or not all of the dissimilatory processes in Table XIV can be attributed to phonetically grounded constraints, as hypothesised by Ohala (Reference Ohala, Masek, Hendrick and Miller1981), remains to be seen (though see Hall et al. Reference Hall, Vasquez, Aguirre, Damanhuri and Tree2017 for some critical discussion). But the current proposal that nasal cluster dissimilation is driven by constraints on contrast advances the discussion in two ways. First, the results discussed here strengthen the claim that at least some types of dissimilation are motivated not by co-occurrence constraints but by constraints that disprefer the perceptual consequences of co-occurrence. Second, it suggests that the targets of co-occurrence constraints must be restricted to single or simultaneously implemented features.