



1. Introduction and preliminaries
Stein-type covariance identities have many applications in several areas of probability and statistics; see [Reference Afendras, Papadatos and Papathanasiou2, Reference Cacoullos and Papathanasiou7, Reference Cacoullos, Papathanasiou and Utev8, Reference Ernst, Reinert and Swan17–Reference Ernst and Swan19, Reference Goldstein and Reinert22, Reference Hudson25, Reference Liu30, Reference Papadatos and Papathanasiou32, Reference Stein39, Reference Stein40]. Furthermore, much attention has been given in the field of actuarial science; see [Reference El Methni, Gardes and Girard16, Reference Gupta and Kirmani23], and references therein. In particular, if X is a random variable that follows a normal distribution with moment
 $\mu$
and variance
 $\sigma^2$
, which is denoted by
 $X \sim \textrm{N}(\mu,\sigma^2)$
, then for every absolutely continuous function g with derivative g
′ such that
 $\mathbb{E}[g{'}(X)] < \infty$
,
 \begin{equation} \textrm{Cov}(X,g(X)) = \mathbb{E}[g{'}(X)] \, \sigma^2.\end{equation}
A generalization of (1.1) provided by [Reference Papadatos and Papathanasiou32] is the following: Let X be an absolutely continuous random variable with probability density function (PDF)
 $f_X(x)$
and finite variance
 $\mathbb{V}(X)$
. Then, for any absolutely continuous function g with derivative g
′, there exists a new random variable
 $X_{\star}$
with
 $\mathbb{E}[g{'}(X_{\star})] < \infty$
and unimodal PDF (the mode of
 $X_{\star}$
is equal to
 $\mathbb{E}(X)$
)
 \begin{equation} f_{X_{\star}}(x) = \frac{1}{\mathbb{V}(X)} \int_x^{\infty} [t-\mathbb{E}(X)] \, f_X(t) \, \textrm{d} t,\end{equation}
such as
 \begin{equation} \textrm{Cov}(X,g(X)) = \mathbb{E}[g{'}(X_{\star})] \,\mathbb{V}(X).\end{equation}
It is also well known that
 $X \sim \textrm{N}(\mu,\sigma^2)$
if and only if
 $X_{\star}\sim \textrm{N}(\mu,\sigma^2)$
, so it is clear that (1.3) is a generalization of (1.1).
The motivation for this paper arises from actuarial science. In particular, let
 $X \geq 0$
be a loss random variable risk and
 $w \colon [0, \infty) \rightarrow [0, \infty)$
be an increasing function such that the expectation
 $\mathbb{E}[w(X)]$
is strictly positive and finite. Then, the weighted premium principle proposed by [Reference Furman and Zitikis20], see also [Reference Heilmann24, Reference Kamps26], is given by
 \begin{equation} H_w(X) = \frac{\mathbb{E}[X w(X)]}{\mathbb{E}[w(X)]} = \mathbb{E}(X) + \frac{\textrm{Cov}(X, w(X))}{\mathbb{E}[w(X)]}.\end{equation}
Since, by assumption, the function w is increasing, we have that
 $\textrm{Cov}(X, w(X)) > 0$
(see [Reference Patil and Rao34]). As a consequence, it follows that
 $H_w(X) > \mathbb{E}(X)$
. Furthermore, [Reference Furman and Zitikis20] studied the generalized weighted premium principle
 \begin{equation} H_{w,g}(X) = \frac{\mathbb{E}[g(X) w(X)]}{\mathbb{E}[w(X)]} = \mathbb{E}[g(X)] + \frac{\textrm{Cov}(g(X), w(X))}{\mathbb{E}[w(X)]},\end{equation}
provided that g is an increasing nonnegative function such that
 $\mathbb{E}[g(X)] \geq \mathbb{E}(X)$
. In view of (1.4) and (1.5), a natural question is the following: Is there any connection between the covariances
 $\textrm{Cov}(g(X),w(X))$
and
 $\textrm{Cov}(X,w(X))$
? Clearly, for
 $w(x)=x$
, we have a connection through (1.3).
Focusing on covariance identities for loss random variables with applications to actuarial science, in the remainder of this paper we assume that the random variables are nonnegative and absolutely continuous. The functions
 $g \colon [0,\infty) \rightarrow [0,\infty)$
and
 $w \colon [0,\infty) \rightarrow [0,\infty)$
are continuous and, furthermore, w is an increasing function. Also, let
 $X_w$
be a weighted random variable of X with PDF
 \begin{equation}f_{X_w}(x)=\frac{w(x)}{\mathbb{E}[w(X)]}f_X(x), \qquad x>0,\end{equation}
provided that
 $0 < \mathbb{E}[w(X)] < \infty$
; for details, see [Reference Patil and Rao34]. Note that
 $\mathbb{E}(X_w ) = H_w (X) > \mathbb{E}(X)$
; in other words, the weight premium principle for a risk is equal to the moment of
 $X_w$
. In the special case where
 $w(x) = x \geq 0$
, the weighted version of X, denoted by
 $X_\textrm{lb}$
, is the well-known length-biased random variable with PDF
 \begin{align*} f_{X_\textrm{lb}}(x)=\frac{x}{\mathbb{E}(X)} f_X(x), \qquad x>0 ,\end{align*}
and moment
 $\mathbb{E}(X_\textrm{lb}) = \mathbb{E}(X^2)/\mathbb{E}(X)$
. Thus, for a nonnegative random variable X, an equivalence formula for the PDF in (1.2) is
 \begin{equation} f_{X_{\star}}(x) = \frac{\overline{F}_{X_\textrm{lb}}(x) - \overline{F}_X(x)}{\mathbb{E}(X_\textrm{lb})-\mathbb{E}(X)}, \qquad x>0,\end{equation}
where
 $\overline{F}_X(x) = \mathbb{P}(X>x)$
and
 $\overline{F}_{X_\textrm{lb}}(x) = \mathbb{P}(X_\textrm{lb}>x)$
are the tail functions of X and
 $X_\textrm{lb}$
, respectively.
The main aim of this paper is to construct a generalized identity for
 $\textrm{Cov}(g(X),w(X))$
. Our method is based on the probabilistic analogue of the mean value theorem proposed by [Reference Di Crescenzo12]; applications of this theorem to actuarial and finance science have been studied by [Reference Di Crescenzo, Martinucci and Mulero14, Reference Di Crescenzo and Psarrakos15]. In our analysis we use the random variable
 $X_w$
instead of
 $X_\textrm{lb}$
, and the random variable
 $X_{\tilde{w}}$
instead of
 $X_{\star}$
, where the PDF of
 $X_{\tilde{w}}$
is
 \begin{align*} f_{X_{\tilde{w}}}(x) = \frac{\overline{F}_{X_{w}}(x) - \overline{F}_X(x)}{\mathbb{E}(X_{w})-\mathbb{E}(X)} = \frac{1}{\textrm{Cov}(X,w(X))} \, \int_x^{\infty} (w(t) - \mathbb{E}[w(X)]) \, f_X(t) \, \textrm{d} t, \quad x \gt 0.\end{align*}
It is worth mentioning that the ratio
 $f_X^{\prime} (x)/f_X(x)$
, i.e. the ‘score function’ of X, can be expressed in terms of the weights w(x) and
 $\tilde{w}(x) = \mathbb{E}[w(X)] \, [\overline{F}_{X_w}(x) - \overline{F}_X(x)]/f_X(x)$
, see (5.2). We also note that for
 $w(x)=x$
it follows that
 $X_w =_\textrm{d} X_\textrm{lb}$
and
 $X_{\tilde{w}}=_\textrm{d} X_{\star}$
, where
 $=_\textrm{d}$
means equality in distribution. This generalization permits us to obtain covariance identities not only associated with variance, but also associated with actuarial and financial measures. In particular, we obtain further covariance identities for measures associated with Bonferroni, De Vergottini, Gini, and Wang indices. We also give an identity for
 $\mathbb{V}[w(X)] = \textrm{Cov}(w(X),w(X))$
, extending the work of [Reference Cacoullos4, Reference Chernoff11].
The rest of the paper is organized as follows: In Section 2, we obtain a covariance identity for
 $\textrm{Cov}(g(X),w(X))$
. In Section 3, we give some characterization results for gamma and Pareto distributions. In Section 4, we provide a variance identity and some covariance identities for actuarial and financial risk measures. By using the weight
 $\tilde{w}(x)$
, in Section 5 we obtain a representation for
 $\mathbb{E}[w(X)\mid X > x]$
in terms of hazard rate, and we apply it to actuarial conditional risk measures. In Section 6, we give some concluding remarks.
Throughout the paper, the random variables are assumed to be nonnegative and absolutely continuous. Moreover, the terms increasing and decreasing are used in a strict sense.
2. A generalized covariance identity
It is well known that the mean value theorem states that if g is a function continuous in [x, y] and differentiable in (x, y), then there exists a point
 $u \in (x, y)$
such that
 $g(y) - g(x) = g'(u) \, (y - x)$
. Let X and Y be two nonnegative absolutely continuous random variables with PDFs
 $f_X(x)$
and
 $f_Y(x)$
, distribution functions
 $F_X(x)$
and
 $F_Y(x)$
, and survival functions
 $\overline{F}_X(x) = 1 - F_X(x)$
and
 $\overline{F}_Y(x) = 1 - F_Y(x)$
, respectively. Under the hypothesis that X is smaller than Y in the usual stochastic order, a probabilistic analogue of this theorem has been given in Theorem 4.1 of [Reference Di Crescenzo12]. Recall that X is smaller than Y in the usual stochastic order if
 $\overline{F}_X(x) \le \overline{F}_Y(x)$
for all x.
Lemma 2.1. If X and Y are nonnegative continuous random variables with X smaller than Y in the usual stochastic order, and
 $0 < \mathbb{E}(X) < \mathbb{E}(Y) < \infty$
, then there exists a suitable nonnegative random variable U such that
 $\mathbb{E}[g(Y)] - \mathbb{E}[g(X)] = \mathbb{E}[g'(U)] \, [\mathbb{E}(Y) - \mathbb{E}(X)]$
, provided that g is a measurable and differentiable function such that
 $\mathbb{E}[g(X)]$
and
 $\mathbb{E}[g(Y)]$
are finite, and that its derivative g′ is measurable and Riemann-integrable. Here, the PDF of the random variable U is
 \begin{align*} f_{U}(x) = \frac{\overline{F}_Y(x) - \overline{F}_X(x)}{\mathbb{E}(Y) - \mathbb{E}(X)}.\end{align*}
Remark 2.1. In the remainder of the paper, we assume that the function g(x) satisfies the assumptions of Lemma 2.1. The same assumptions also hold for the weight functions w(x) and
 $\xi(x)$
when this is necessary.
Theorem 2.1. Let X be a nonnegative absolutely continuous random variable and
 $X_w$
be a weighted version of X, where w is an increasing function. Then,
 \begin{equation} \textrm{Cov}(g(X),w(X)) = \mathbb{E}[g{'}(X_{\tilde{w}})] \, \textrm{Cov}(X,w(X)),\end{equation}
where
 $X_{\tilde{w}}$
is a weighted random variable with weight
 \begin{equation} \tilde{w}(x) = \mathbb{E}[w(X)] \, \frac{\overline{F}_{X_w}(x) - \overline{F}_X(x)}{f_X(x)}\end{equation}
and PDF
 \begin{equation} f_{X_{\tilde{w}}}(x) = \frac{1}{\textrm{Cov}(X,w(X))} \, \int_x^{\infty} (w(t)-\mathbb{E}[w(X)]) \, f_X(t) \, \textrm{d} t.\end{equation}
Proof. We have
 \begin{align*} \textrm{Cov}(g(X),w(X)) & = \mathbb{E}[g(X) w(X)] - \mathbb{E}[g(X)] \, \mathbb{E}[w(X)] \\ & = \mathbb{E}[w(X)] \, \mathbb{E}[g(X_w)] - \mathbb{E}[g(X)] \, \mathbb{E}[w(X)] \\ & = \mathbb{E}[w(X)] \, (\mathbb{E}[g(X_w)] - \mathbb{E}[g(X)]) .\end{align*}
Moreover,
 $\textrm{Cov}(X,w(X)) = \mathbb{E}[w(X)] \, [\mathbb{E}(X_w) - \mathbb{E}(X)]$
. By applying Lemma 2.1 for the random variables
 $X_w$
and X, we obtain
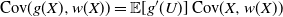 $\textrm{Cov}(g(X),w(X)) = \mathbb{E}[g{'}(U)] \, \textrm{Cov}(X,w(X))$
, where
 \begin{align*} f_{U}(x) = \frac{\overline{F}_{X_w}(x) - \overline{F}_X(x) }{\mathbb{E}(X_w) - \mathbb{E}(X)}.\end{align*}
It remains to prove that
 $U=_\textrm{d}X_{\tilde{w}}$
. In fact, we have
 \begin{align} \mathbb{E}(\tilde{w}(X)) & = \int_{0}^{\infty} \tilde{w}(x) \, f_X(x) \, \textrm{d} x \nonumber \\[3pt] & = \mathbb{E}[w(X)] \, \int_{0}^{\infty} [\overline{F}_{X_w}(x) - \overline{F}_X(x)] \, \textrm{d} x \nonumber \\[3pt] & = \mathbb{E}[w(X)] \, [\mathbb{E}(X_w) - \mathbb{E}(X)] \nonumber \\[3pt] & = \textrm{Cov}(X,w(X)) \end{align}
and
 \begin{equation} f_{X_{\tilde{w}}}(x) = \frac{\tilde{w}(x)}{\mathbb{E}[\tilde{w}(X)]} \, f_X(x) = \frac{\overline{F}_{X_w}(x) - \overline{F}_X(x) }{\mathbb{E}(X_w) - \mathbb{E}(X)},\end{equation}
i.e.
 $f_{X_{\tilde{w}}}(x) = f_{U}(x)$
. Moreover, the PDF in (2.5) can be alternatively written as
 \begin{align*} f_{X_{\tilde{w}}}(x) = \frac{\int_x^{\infty} \frac{w(t)}{\mathbb{E}[w(X)]} \, f_X(t) \, \textrm{d} t - \int_x^{\infty} f_X(t) \, \textrm{d} t}{\mathbb{E}(X_w) - \mathbb{E}(X)} = \frac{\int_x^{\infty} (w(t)-\mathbb{E}[w(X)]) \, f_X(t) \, \textrm{d} t}{\textrm{Cov}(X,w(X))},\end{align*}
and the proof is complete.
Remark 2.2. For
 $w(x) = x$
, we have
 $X_{\tilde{w}}=_\textrm{d} X_{\star}$
, and (2.1) yields (1.3).
Corollary 2.1. Let
 $X_{\star}$
and
 $X_{\tilde{w}}$
be two random variables with PDFs given in (1.7) and (2.5), respectively, where w is an increasing function. Then, the following hold:
 \begin{align} \textrm{(i)} & \qquad \textrm{Cov}(g(X),w(X)) = \mathbb{E}[g{'}(X_{\tilde{w}})] \, \mathbb{E}[w{'}(X_{\star})] \,\mathbb{V}(X) ; \end{align}
 \begin{align} \textrm{(ii)} & \qquad \textrm{Cov}(g(X),w(X)) = \mathbb{E}[g{'}(X) \, \tilde{w}(X)]. \qquad\qquad\quad\nonumber\end{align}
Proof. (i) By using the function w instead of g in (1.3), we have
 $\textrm{Cov}(X,w(X)) = \mathbb{E}[w{'}(X_{\star})] \,\mathbb{V}(X)$
, and (2.1) completes the proof.
(ii) We have
 \begin{equation*} \mathbb{E}[g{'}(X_{\tilde{w}})] = \int_0^{\infty} g{'}(x) \, f_{X_{\tilde{w}}}(x) \, \textrm{d} x = \int_0^{\infty} g{'}(x) \, \frac{\tilde{w}(x)}{\mathbb{E}[\tilde{w}(X)]} \, f_{X}(x) \, \textrm{d} x = \frac{\mathbb{E}[g{'}(X) \, \tilde{w}(X)]}{\textrm{Cov}(X,w(X))},\end{equation*}
where, in the last equality, we used (2.4). Then, by (2.1), the result follows.
Remark 2.3. (i) In (2.6), the factors
 $\mathbb{E}[g{'}(X_{\tilde{w}})]$
and
 $\mathbb{E}[w{'}(X_{\star})]$
follow by applying the probabilistic analogue of the mean value theorem given in Lemma 2.1 for
 $X_w$
and X (by using the function g), and for
 $X_\textrm{lb}$
and X (by using the function w), respectively.
(ii) Representations for the covariance
 $\textrm{Cov}(g(X),w(X))$
have recently been given by [Reference Ernst, Reinert and Swan17, Reference Ernst, Reinert and Swan18] and by [Reference Ernst and Swan19] in a more general framework by using Stein operators and, among them, a generalized score function. It is worth mentioning that, in our work, the weight functions w(x) and
 $\tilde{w}(x)$
are related to the score function of X, see (5.2).
Next, we provide an analogous covariance identity in the case where the weight function is decreasing. In this case, applications arise naturally in the field of social welfare; see [Reference Castaño-Martínez, Pigueiras, Psarrakos and Sordo9] and references therein. Consider a weighted random variable
 $X_{\xi}$
with PDF
 \begin{align*} f_{X_{\xi}}(x)=\frac{\xi(x)}{\mathbb{E}[\xi(X)]}f_X(x), \qquad x>0,\end{align*}
where
 $\xi$
is a decreasing function and
 $0 < \mathbb{E}[\xi(X)] < \infty$
. Recall also that
 $\textrm{Cov}(X,\xi(X)) < 0$
and
 $\overline{F}_{X_{\xi}}(x) \le \overline{F}_X(x)$
for all x. Moreover, assuming that
 $0 < - \textrm{Cov}(X,\xi(X)) < \infty$
, consider the random variable
 $X_{\tilde{\xi}}$
with PDF
 \begin{equation} f_{X_{\tilde{\xi}}}(x) = \frac{\overline{F}_X(x)-\overline{F}_{X_{\xi}}(x)}{\mathbb{E}(X) - \mathbb{E}(X_{\xi})} = \frac{1}{-\textrm{Cov}(X,\xi(X))} \, \int_x^{\infty} (\mathbb{E}[\xi(X)]-\xi(t)) \, f_X(t) \, \textrm{d} t.\end{equation}
In the following theorem, we give a covariance identity in the case where the weight function is decreasing. We omit the proof since it is similar to the proof of Theorem 2.1.
Theorem 2.2. Let X be a nonnegative absolutely continuous random variable, and
 $X_{\xi}$
be a weighted version of X, where
 $\xi$
is a decreasing function. Then,
 \begin{equation} \textrm{Cov}(g(X),\xi(X)) = \mathbb{E}[g{'}(X_{\tilde{\xi}})] \, \textrm{Cov}(X,\xi(X)),\end{equation}
where
 $X_{\tilde{\xi}}$
is a weighted random variable with PDF given in (2.7), with weight
 \begin{align*} \tilde{\xi}(x) = \mathbb{E}[\xi(X)] \, \frac{\overline{F}_X(x) - \overline{F}_{X_{\xi}}(x)}{f_X(x)}.\end{align*}
As a consequence of Theorem 2.2, Corollary 2.1 can be extended to the case of decreasing weight functions.
Corollary 2.2. Let
 $X_{\star}$
and
 $X_{\tilde{\xi}}$
be two random variables with PDFs given in (1.7) and (2.7), respectively, where
 $\xi$
is a decreasing function. Then, the following hold:
 \begin{align} \textrm{(i)} & \qquad \textrm{Cov}(g(X),\xi(X)) = \mathbb{E}[g{'}(X_{\tilde{\xi}})] \, \mathbb{E}[\xi{'}(X_{\star})] \,\mathbb{V}(X) ; \end{align}
 \begin{align} \textrm{(ii)} & \qquad \textrm{Cov}(g(X),\xi(X)) = \mathbb{E}[g{'}(X) \, \tilde{\xi}(X)].\end{align}
3. Some characterization results including gamma and Pareto distributions
In this section, for
 $n =1,2,\ldots$
we study the weights
 $w(x) = w_n(x)= x^n$
and
 \begin{align*} \tilde{w}(x) = \tilde{w}_n(x) = \mathbb{E}(X^n) \, \frac{\overline{F}_{X_{w_n}}(x)-\overline{F}_X(x)}{f_X(x)},\end{align*}
and we obtain some characterization results between
 $X_{\tilde{w}_n}$
and X, including gamma and Pareto distributions. Before that, we give the following auxiliary result. The proof of the next lemma follows immediately, so we omit it.
Lemma 3.1. The PDF
 $f_{X_{\tilde{w}}}(x)$
in (2.3), where w is an increasing function, is unimodal with mode
 $w^{-1}(\mathbb{E}[w(X)])$
.
Theorem 3.1. Let X be a continuous random variable supported on
 $[0, \infty)$
with moment
 $0 < \mathbb{E}(X ) <\infty$
, and
 $0 < \textrm{Cov}(X,X^n ) < \infty$
for
 $n = 1,2,\ldots$
Then, for
 $w_n (x) = x^n$
and two parameters
 $a, b > 0$
,
 $X_{\tilde{w}_n}$
follows a mixture of n gamma distributions with PDF
 \begin{align*} f_{X_{\tilde{w}_n}}(x) = \frac{1}{n} \, \sum_{i=1}^{n} \frac{b^{a+i}}{\Gamma(a+i)} \, x^{a+i-1} \, \textrm{e}^{-bx}, \qquad x>0 ,\end{align*}
if and only if
 $X \sim \textrm{Gamma}(a,b)$
with PDF
 \begin{align*} f_X(x) = \frac{b^a}{\Gamma(a)} \, x^{a-1} \, \textrm{e}^{-bx}, \qquad x>0.\end{align*}
Proof. (
 $\Rightarrow$
) Let
 \begin{align*} f_{X_{\tilde{w}_n}}(x) = \frac{1}{n} \, \sum_{i=1}^{n} \frac{b^{a+i}}{\Gamma(a+i)} \, x^{a+i-1} \, \textrm{e}^{-bx}, \qquad x>0 .\end{align*}
By differentiation, we obtain
 \begin{equation} f^{\prime}_{X_{\tilde{w}_n}}(x) = \frac{1}{n} \, \bigg(\sum_{i=1}^{n} \bigg [\frac{b^{a+i}}{\Gamma(a+i-1)} \, x^{a+i-2} - \frac{b^{a+i+1}}{\Gamma(a+i)} \, x^{a+i-1} \bigg ] \bigg) \, \textrm{e}^{-bx} .\end{equation}
Moreover, we have
 \begin{align*} \sum_{i=1}^{n} \bigg [\frac{b^{a+i}}{\Gamma(a+i-1)} \, x^{a+i-2} & - \frac{b^{a+i+1}}{\Gamma(a+i)} \, x^{a+i-1} \bigg ] \\ & = \sum_{i=1}^{n} \frac{b^{a+i}}{\Gamma(a+i-1)} \, x^{a+i-2} - \sum_{i=2}^{n+1} \frac{b^{a+i}}{\Gamma(a+i-1)} \, x^{a+i-2} \\ & = \frac{b^{a+1}}{\Gamma(a)} \, x^{a-1} - \frac{b^{a+n+1}}{\Gamma(a+n)} \, x^{a+n-1},\end{align*}
and (3.1) yields
 \begin{equation} f^{\prime}_{X_{\tilde{w}_n}}(x) = \frac{1}{n} \, \bigg( \frac{b^{a+1}}{\Gamma(a)} \, x^{a-1} - \frac{b^{a+n+1}}{\Gamma(a+n)} \, x^{a+n-1} \bigg) \, \textrm{e}^{-bx}.\end{equation}
Let m be the mode of
 $X_{\tilde{w}_n}$
. Then, by Lemma 3.1, it follows that
 \begin{equation} m=(\mathbb{E}(X^n))^{1/n} = \bigg( \frac{\Gamma(a+n)}{\Gamma(a) b^n} \bigg)^{1/n}.\end{equation}
Furthermore, by (2.3) and (3.2), we obtain
 \begin{align*} (x^n-\mathbb{E}(X^n)) \, f_X(x) = \frac{\textrm{Cov}(X,X^n) \, b^{a+n+1}}{n \, \Gamma(a+n)} \, x^{a-1} \, \textrm{e}^{-bx} \bigg(x^n - \frac{\Gamma(a+n)}{\Gamma(a) \, b^n} \bigg),\end{align*}
and using (3.3), we have
 $f_X(x) = c \, x^{a-1} \, \textrm{e}^{-bx}$
, where
 \begin{align*} c=\frac{\textrm{Cov}(X,X^n) \, b^{a+n+1}}{n \, \Gamma(a+n)}.\end{align*}
By normalizing, we have
 $c = b^a /\Gamma(a)$
, and the proof is complete.
(
 $\Leftarrow$
) Let
 $X \sim \textrm{Gamma}(a,b)$
with tail function
 $\overline{F}_X(x)=\Gamma(a,bx)/\Gamma(a)$
, where
 $\Gamma(a,y)=\int_y^{\infty} t^{a-1} \, \textrm{e}^{-t} \, \textrm{d} t$
is the upper incomplete gamma function. Then,
 $X_{w_n} \sim \textrm{Gamma}(a+n,b)$
, and
 \begin{align} \overline{F}_{X_{w_n}}(x) & - \overline{F}_X(x) \nonumber \\ & = \frac{\Gamma(a+n,bx)}{\Gamma(a+n)} - \frac{\Gamma(a,bx)}{\Gamma(a)} \nonumber \\ & = \sum_{i=1}^n \bigg[ \frac{\Gamma(a+i,bx)}{\Gamma(a+i)} - \frac{\Gamma(a+i-1,bx)}{\Gamma(a+i-1)} \bigg] \nonumber \\ & = \sum_{i=1}^n \bigg[ \frac{(a+i-1) \, \Gamma(a+i-1,bx) + (bx)^{a+i-1} \, \textrm{e}^{-bx}}{\Gamma(a+i)} - \frac{\Gamma(a+i-1,bx)}{\Gamma(a+i-1)} \bigg] \nonumber \\ & = \sum_{i=1}^n \frac{(bx)^{a+i-1} \, \textrm{e}^{-bx}}{\Gamma(a+i)}. \end{align}
Moreover,
 \begin{align*}\mathbb{E}(X_{w_n}) - \mathbb{E}(X) = \frac{a+n}{b} - \frac{a}{b} = \frac{n}{b},\end{align*}
and the result follows by (2.5).
Corollary 3.1.
-
(i) Let X be a continuous random variable supported on
 $[0,\infty)$
with moment
$0<\mathbb{E}(X)<\infty$
and variance
$0<\mathbb{V}(X)<\infty$
. Then,
$X_{\star} \sim \textrm{Gamma}(a+1,b)$
if and only if
$X \sim \textrm{Gamma}(a,b)$
.
-
(ii) Let X be a continuous random variable supported on
$[0,\infty)$
with moment
$0<\mathbb{E}(X) < \infty$
and
$0<\textrm{Cov}(X,X^2)<\infty$
. Then, for
$w(x)=x^2$
,
$X_{\tilde{w}}$
follows a mixture of
$\textrm{Gamma}(a+1,b)$
and
$\textrm{Gamma}(a+2,b)$
with weights 0.5 and 0.5, respectively, if and only if
$X \sim \textrm{Gamma}(a,b)$
.


Remark 3.1. By part (i) of Corollary 3.1., it follows that for
 $X \sim \textrm{Gamma}(a,b)$
, we have
 $X_{\star} =_\textrm{d} X_\textrm{lb}$
. Moreover, in part (ii) of Corollary 3.1., for
 $w(x) = x^2$
,
 $X_{\tilde{w}}$
follows a generalized Lindley distribution; see [Reference Zakerzadeh and Dolati44].
Theorem 3.2. Let X be a continuous random variable supported on
 $[k, \infty)$
,
 $k>0$
, with moment
 $\mathbb{E}(X)<\infty$
, and
 $0 < \textrm{Cov}(X,X^n) < \infty$
for
 $n = 1,2,\ldots$
Then, for
 $w_n (x) = x^n$
and a parameter
 $a > n+1$
,
 $X_{\tilde{w}_n}$
follows a generalized mixture of two Pareto distributions with PDF
 \begin{align*} f_{X_{\tilde{w}_n}}(x) = \frac{a-1}{n} \, \frac{(a-n-1) k^{a-n-1}}{x^{a-n}} - \frac{a-n-1}{n} \, \frac{(a-1) k^{a-1}}{x^{a}} , \qquad x>k ,\end{align*}
if and only if
 $X \sim \textrm{Pareto}(a,k)$
with PDF
 \begin{align*} f_X(x) = \frac{a k^a}{x^{a+1}}, \qquad x>k.\end{align*}
Proof. (
 $\Rightarrow$
) Let
 \begin{align*} f_{X_{\tilde{w}_n}}(x) = \frac{a-1}{n} \, \frac{(a-n-1) k^{a-n-1}}{x^{a-n}} - \frac{a-n-1}{n} \, \frac{(a-1) k^{a-1}}{x^{a}} , \qquad x>k .\end{align*}
By differentiation and after some calculations, we conclude that
 \begin{equation} f^{\prime}_{X_{\tilde{w}_n}}(x) = \frac{-(a-1) (a-n-1) (a-n) k^{a-n-1}}{n x^{a+1}} \, \bigg(x^n - \frac{a k^n}{a-n} \bigg) .\end{equation}
Let m be the mode of
 $X_{\tilde{w}_n}$
. Then, by Lemma 3.1., it follows that
 \begin{equation} m=(\mathbb{E}(X^n))^{1/n} = \bigg ( \frac{a k^n}{a-n} \bigg)^{1/n}.\end{equation}
Moreover, by (2.3) and (3.5), we obtain
 \begin{align*} (x^n-\mathbb{E}(X^n)) \, f_X(x) = \frac{\textrm{Cov}(X,X^n) \, (a-1) (a-n-1) (a-n) k^{a-n-1}}{n x^{a+1}} \, \bigg(x^n - \frac{a k^n}{a-n} \bigg),\end{align*}
and using (3.6), we have
 \begin{align*} f_X(x) = c \, \frac{k^a}{x^{a+1}},\end{align*}
where
 \begin{align*} c=\frac{\textrm{Cov}(X,X^n) \, (a-1) (a-n-1) (a-n)}{n \, k^{n+1}}.\end{align*}
By normalizing, we have
 $c = a$
, and the proof is complete.
(
 $\Leftarrow$
) Let
 $X \sim \textrm{Pareto}(a,k)$
with tail function
 $\overline{F}_X(x) = k^a/x^a$
,
 $x \geq k$
. Then,
 $X_{\tilde{w}_n} \sim \textrm{Pareto}(a-n,b)$
,
 \begin{align*} \overline{F}_{X_{w_n}}(x) - \overline{F}_X(x) = \frac{k^{a-n}}{x^{a-n}} - \frac{k^{a}}{x^{a}} ,\end{align*}
and
 \begin{align*} \mathbb{E}(X_{w_n}) - \mathbb{E}(X) = \frac{k(a-n)}{a-n-1} - \frac{ka}{a-1} = \frac{kn}{(a-n-1) (a-1)}.\end{align*}
The result follows by (2.5).
Corollary 3.2.
-
(i) Let X be a continuous random variable supported on
$[k,\infty)$
with moment
$\mathbb{E}(X)<\infty$
and variance
$0<\mathbb{V}(X)<\infty$
. Then, for
$a>2$
and
$k>0$
,
$X_{\star}$
follows a generalized mixture of
$\textrm{Pareto}(a-2,k)$
and
$\textrm{Pareto}(a,k)$
with weights
$a-1$
and
$2-a$
, respectively, if and only if
$X \sim \textrm{Pareto}(a,k)$
. -
(ii) Let X be a continuous random variable supported on
$[k,\infty)$
,
$k>0$
, with moment
$\mathbb{E}(X) < \infty$
and
$0 < \textrm{Cov}(X,X^2) < \infty$
. Then, for
$w(x)=x^2$
and
$a>3$
,
$X_{\tilde{w}}$
follows a generalized mixture of
$\textrm{Pareto}(a-3,k)$
and
$\textrm{Pareto}(a,k)$
with weights
$(a-1)/2$
and
$(3-a)/2$
, respectively, if and only if
$X \sim \textrm{Pareto}(a,k)$
.


4. Applications
4.1. A variance identity
A two-side bound for the variance
 $\mathbb{V}[w(X)]$
without the assumption of monotonicity for the function w is
 \begin{equation} (\mathbb{E}[w{'}(X_{\star})])^2 \, \mathbb{V}(X) \le \mathbb{V}[w(X)] \le \mathbb{E}[(w{'}(X_{\star}))^2] \, \mathbb{V}(X) ; \end{equation}
for more details, see [Reference Afendras and Papadatos1, Reference Afendras, Papadatos and Papathanasiou2, Reference Cacoullos4, Reference Cacoullos and Papathanasiou6, Reference Cacoullos and Papathanasiou7, Reference Chen10, Reference Chernoff11, Reference Papadatos and Papathanasiou32, Reference Papathanasiou33, Reference Vitale42]. In the following result, we obtain an identity for
 $\mathbb{V}[w(X)]$
under the assumption that w is an increasing function.
Corollary 4.1. Let
 $X_{\star}$
and
 $X_{\tilde{w}}$
be two random variables with PDFs given in (1.7) and (2.5), respectively, where w is an increasing function. Then,
 \begin{equation} \mathbb{V}[w(X)] = \mathbb{E}[w{'}(X_{\tilde{w}})] \, \mathbb{E}[w{'}(X_{\star})] \,\mathbb{V}(X) .\end{equation}
Proof. For
 $w(x)=g(x)$
in (2.6), the result follows.
Next, we give two examples in order to verify the variance identity in (4.2) and the two bounds in (4.1).
Example 4.1. Suppose that
 $X \sim \textrm{Gamma}(a,b)$
, where
 $a>0$
and
 $b>0$
, with PDF
 \begin{align*} f_X(x) = \frac{b^a}{\Gamma(a)} \, x^{a-1} \, \textrm{e}^{-bx}, \qquad x>0.\end{align*}
Let us also assume that
 $w(x) = x^2$
. By Corollary 3.1., we have
 \begin{align*} f_{X_{\star}}(x) = \frac{b^{a+1}}{\Gamma(a+1)} \, x^a \, \textrm{e}^{-bx}\end{align*}
and
 \begin{align*} f_{X_{\tilde{w}}}(x) = \frac{1}{2} \, \frac{b^{a+1}}{\Gamma(a+1)} \, x^a \, \textrm{e}^{-bx} + \frac{1}{2} \, \frac{b^{a+2}}{\Gamma(a+2)} \, x^{a+1} \, \textrm{e}^{-bx}.\end{align*}
Thus,
 \begin{equation*} \mathbb{E}(X_{\star}) = \frac{a+1}{b} , \qquad \mathbb{E}(X_{\tilde{w}}) = \frac{2a+3}{2b}.\end{equation*}
By (4.2), the variance of
 $X^2$
is
 \begin{equation} \mathbb{V}(X^2) = 4 \, \mathbb{E}(X_{\tilde{w}}) \, \mathbb{E}(X_{\star}) \, \mathbb{V}(X) = \frac{2 a (a+1) (2a+3)}{b^4}.\end{equation}
After some computation, the upper bound of
 $\mathbb{V}(X^2)$
in (4.1) becomes
 \begin{align*} 4 \, \mathbb{E}(X_{\star}^2) \, \mathbb{V}(X) = \frac{4a(a+1)(a+2)}{b^4},\end{align*}
while the lower bound of
 $\mathbb{V}(X^2)$
in (4.1) becomes
 \begin{align*} 4 \, [\mathbb{E}(X_{\star})]^2 \, \mathbb{V}(X) = \frac{4a(a+1)^2}{b^4}.\end{align*}
Example 4.2. Suppose that
 $X \sim \textrm{Pareto}(a,k)$
, where
 $a > 4$
and
 $k > 0$
, with PDF
 \begin{align*} f_X(x) = \frac{a k^a}{x^{a+1}} , \qquad x>k.\end{align*}
Let us also assume that
 $w(x) = x^2$
. By Corollary 3.2., we have
 \begin{align*} f_{X_{\star}}(x) = (a-1) \, \frac{(a-2) k^{a-2}}{x^{a-1}} - (a-2) \, \frac{(a-1) k^{a-1}}{x^a}\end{align*}
and
 \begin{align*} f_{X_{\tilde{w}}}(x) = \frac{a-1}{2} \, \frac{(a-3) k^{a-3}}{x^{a-2}} - \frac{a-3}{2} \, \frac{(a-1) k^{a-1}}{x^a} .\end{align*}
Thus,
 \begin{equation*} \mathbb{E}(X_{\star}) = \frac{(a-1)k}{a-3} , \qquad \mathbb{E}(X_{\tilde{w}}) = \frac{(a-1)(a-3)k}{(a-2)(a-4)}.\end{equation*}
By (4.2), the variance of
 $X^2$
is
 \begin{equation} \mathbb{V}(X^2) = 4 \, \mathbb{E}(X_{\tilde{w}}) \, \mathbb{E}(X_{\star}) \, \mathbb{V}(X) = \frac{4 a k^4}{(a-2)^2 (a-4)}.\end{equation}
After some computation, the upper bound of
 $\mathbb{V}(X^2)$
in (4.1) becomes
 \begin{align*} 4 \, \mathbb{E}(X_{\star}^2) \, \mathbb{V}(X) = \frac{4ak^4}{(a-1)(a-3)(a-4)},\end{align*}
while the lower bound of
 $\mathbb{V}(X^2)$
in (4.1) becomes
 \begin{align*} 4 \, [\mathbb{E}(X_{\star})]^2 \, \mathbb{V}(X) = \frac{4ak^4}{(a-2)(a-3)^2}.\end{align*}
Remark 4.1. Since, for Gamma and Pareto distributions, we have known expressions for the moments, we can verify (4.3) and (4.4) by using the (well-known) identity
 $\mathbb{V}(X^2) = \mathbb{E}(X^4) - [\mathbb{E}(X^2)]^2$
.
The variance identity (4.2) can be extended to the case where the weight function is decreasing. In particular, by (2.6), for
 $g(x) = \xi(x)$
we have the following result.
Corollary 4.2. Let
 $X_{\star}$
and
 $X_{\tilde{\xi}}$
be random variables with PDFs given in (1.7) and (2.7), respectively, where
 $\xi$
is a decreasing function. Then,
 \begin{equation} \mathbb{V}[\xi(X)] = \mathbb{E}[\xi{'}(X_{\tilde{\xi}})] \, \mathbb{E}[\xi{'}(X_{\star})] \,\mathbb{V}(X) .\end{equation}
Next, we give an example in order to verify the variance identity (4.5).
Example 4.3. Suppose that
 $X \sim \textrm{Gamma}(a,b)$
, as in Example 4.1, and
 $\xi(x) = \textrm{e}^{-\lambda x}$
for a parameter
 $\lambda > 0$
. Then, after some computation, we obtain
 \begin{align*} f_{X_{\tilde{\xi}}}(x) = \frac{b(b+\lambda)}{a \lambda \Gamma(a)} \, [\Gamma(a,bx)-\Gamma(a,(b+\lambda)x)] \end{align*}
and
 \begin{align*} \mathbb{E}(\textrm{e}^{-\lambda X_{\tilde{\xi}}}) = \frac{b(b+\lambda)}{a \lambda^2} \, \bigg[ \bigg(\frac{b+\lambda}{b+2 \lambda} \bigg)^a - \bigg(\frac{b}{b+\lambda} \bigg)^a \bigg ].\end{align*}
Moreover, recalling that
 $X_{\star} \sim \textrm{Gamma}(a + 1, b)$
, we have
 \begin{align*} \mathbb{E}(\textrm{e}^{-\lambda X_{\star}}) = \bigg(\frac{b}{b+\lambda} \bigg)^{a+1}.\end{align*}
Thus, by (4.5), we obtain
 \begin{align*} \mathbb{V}(\textrm{e}^{-\lambda X}) = \lambda^2 \, \mathbb{E}(\textrm{e}^{-\lambda X_{\tilde{\xi}}}) \, \mathbb{E}(\textrm{e}^{-\lambda X_{\star}}) \, \mathbb{V}(X) = \bigg(\frac{b}{b+2 \lambda} \bigg)^a - \bigg(\frac{b}{b+\lambda} \bigg)^{2a}; \end{align*}
in other words, we have the well-known representation
 $\mathbb{V}(\textrm{e}^{-\lambda X}) = \mathbb{E}[(\textrm{e}^{-\lambda X})^2] - [\mathbb{E}(\textrm{e}^{-\lambda X})]^2$
.
4.2. Covariance identities for actuarial and financial risk measures
In this section we apply Theorems 2.1 and 2.2 for some measures that are associated with well-known actuarial and financial indices, and also have a covariance representation. We consider the quantities
 \begin{align*} D_r(X) = & \left \{ \begin{array}{ll} \int_0^{\infty} [\overline{F}_X(x)]^r \, \textrm{d} x - \mathbb{E}(X) = \textrm{Cov}(X,r[\overline{F}_X(X)]^{r-1}), & 0<r<1, \\[4pt] \mathbb{E}(X) - \int_0^{\infty} [\overline{F}_X(x)]^r \, \textrm{d} x = - \textrm{Cov}(X,r[\overline{F}_X(X)]^{r-1}) , &\quad r>1, \end{array} \right. \\[4pt] &\mathcal{E}(X) = -\int_0^{\infty} \overline{F}_X(x) \, \log \overline{F}_X(x) \, \textrm{d} x = \textrm{Cov}(X,-\log \overline{F}_X(X)) , \\[4pt] & \mathcal{CE}(X) = -\int_0^{\infty} F_X(x) \, \log F_X(x) \, \textrm{d} x = \textrm{Cov}(X,\log F_X(X)).\end{align*}
In particular,
 $D_{0.5}(X)/\mathbb{E}(X)$
is an actuarial index that measures the right tail of distributions,
 $D_2(X)/\mathbb{E}(X)$
is the Gini index,
 $\mathcal{E}(X)/\mathbb{E}(X)$
is the De Vergottini index, and
 $\mathcal{CE}(X)/\mathbb{E}(X)$
is the Bonferroni index; for more details, see [Reference Lerman and Yitzhaki29, Reference Piesch35, Reference Tarsitano, Dagum, Zenga and Springer41, Reference Wang43]. In reliability theory, the quantities
 $\mathcal{E}(X)$
and
 $\mathcal{CE}(X)$
are known as cumulative residual entropy and cumulative past entropy, respectively; for more details, see [Reference Di Crescenzo and Longobardi13, Reference Rao36, Reference Rao, Chen, Vemuri and Wang37].
Proposition 4.1. Let X be a nonnegative absolutely continuous random variable. Then
 \begin{equation} \textrm{Cov}(g(X),r[\overline{F}_X(X)]^{r-1}) = \mathbb{E}[g{'}(X_{\tilde{w}})] \, D_r(X) \qquad {for} \ 0<r<1,\end{equation}
where
 \begin{align*} f_{X_{\tilde{w}}}(x) = \frac{1}{D_r(X)} \, \int_x^{\infty} (r [\overline{F}_X(t)]^{r-1}-1) \, f_X(t) \, \textrm{d} t,\end{align*}
and
 \begin{equation} \textrm{Cov}(g(X),r[\overline{F}_X(X)]^{r-1}) = \mathbb{E}[g{'}(X_{\tilde{\xi}})] \, D_r(X) \qquad {for}\ r>1,\end{equation}
where
 \begin{align*} f_{X_{\tilde{\xi}}}(x) = \frac{1}{D_r(X)} \, \int_x^{\infty} (1-r [\overline{F}_X(t)]^{r-1}) \, f_X(t) \, \textrm{d} t.\end{align*}
Proof. The result in (4.6) follows by applying Theorem 2.1 for
 $w(x) = r[\overline{F}_X(x)]^{r-1}$
,
 $0 < r < 1$
. The result in (4.7) follows by applying Theorem 2.2 for
 $\xi(x) = r[\overline{F}_X(x)]^{r-1}$
,
 $r > 1$
.
Proposition 4.2. Let X be a nonnegative absolutely continuous random variable. Then
 \begin{equation} \textrm{Cov}(g(X), -\log \overline{F}_X(X)) = \mathbb{E}[g{'}(X_{\tilde{w}})] \, \mathcal{E}(X),\end{equation}
where
 \begin{align*} f_{X_{\tilde{w}}}(x) = \frac{1}{\mathcal{E}(X)} \, \int_x^{\infty} ((-\log \overline{F}_X(t))-1) \, f_X(t) \, \textrm{d} t,\end{align*}
and
 \begin{equation} \textrm{Cov}(g(X), \log F_X(X)) = \mathbb{E}[g{'}(X_{\tilde{\xi}})] \, \mathcal{CE}(X),\end{equation}
where
 \begin{align*} f_{X_{\tilde{\xi}}}(x) = \frac{1}{\mathcal{CE}(X)} \, \int_x^{\infty} (1+\log F_X(t)) \, f_X(t) \, \textrm{d} t .\end{align*}
Proof. The result in (4.8) follows by applying Theorem 2.1 for
 $w(x) = - \log \overline{F}_X(x)$
. The result in (4.9) follows by applying Theorem 2.2 for
 $\xi(x) = - \log F_X(x)$
.
Remark 4.2. For further applications of Stein’s type covariance identities, we suggest referring to [Reference Afendras, Papadatos and Papathanasiou2, Reference Furman and Zitikis21, Reference Kattumannil27, Reference Landsman and Valdez28], and the references therein.
5. The weighted tail conditional expectation in terms of hazard rate
The Pearson family of distributions is the best-known family in which the conditional tail moment
 $\mathbb{E}[X \mid X > x]$
is expressed in terms of the hazard rate; see [Reference Nair and Sankaran31, Reference Ruiz and Navarro38] for more details. Let X be a continuous nonnegative random variable with PDF
 $f_X (x)$
, tail function
 $\overline{F}_X(x)$
, and hazard rate
 $\lambda_X(x) = f_X(x)/\overline{F}_X(x)$
. In the following result we use the weight functions w and
 $\tilde{w}$
(see (2.2)) in order to give two representations analogous to the Pearson family of distributions. The first representation below is an expression of the weighted conditional tail moment
 $\mathbb{E}[w(X) \mid X>x]$
in terms of hazard rate, which is a useful form for studying conditional risk measures. The second representation is an expression of the score function of X.
Proposition 5.1. Let X be a nonnegative absolutely continuous random variable and
 $X_w$
a weighted version, where w is an increasing function. Then,
 \begin{align}\textrm{(i)} & \qquad \mathbb{E}[w(X) \mid X>x] = \tilde{w}(x) \, \lambda_X(x) + \mathbb{E}[w(X)], \end{align}
 \begin{align}\!\!\textrm{(ii)} & \qquad \frac{f^{\prime}_X(x)}{f_X(x)} = \frac{\mathbb{E}[w(X)]-w(x)-\tilde{w}{'}(x)}{\tilde{w}(x)}. \ \ \qquad\end{align}
Proof. (i) Recalling that the tail function of
 $X_w$
can be written as
 \begin{align*} \overline{F}_{X_w}(x) = \frac{ \mathbb{E}[w(X) \mid X>x]}{\mathbb{E}[w(X)]} \, \overline{F}_X(x) \end{align*}
(see, for example, [Reference Gupta and Kirmani23]), it is apparent that
 \begin{equation} \mathbb{E}[w(X) \mid X>x] = \mathbb{E}[w(X)] \, \frac{\overline{F}_{X_w}(x)}{\overline{F}_X(x)}.\end{equation}
Equation (5.3) can be written in the form
 \begin{align*} \mathbb{E}[w(X) \mid X>x] = \mathbb{E}[w(X)] \, \frac{\overline{F}_{X_w}(x)-\overline{F}_X(x)}{f_X(x)} \, \frac{f_X(x)}{\overline{F}_X(x)} + \mathbb{E}[w(X)],\end{align*}
which completes the proof.
(ii) Integrating by parts the left part of (5.1), we have
 \begin{align*} w(x) + \frac{\int_x^{\infty} w{'}(t) \, \overline{F}_X(t) \, \textrm{d} t}{\overline{F}_X(x)} = \tilde{w}(x) \, \lambda_X(x) + \mathbb{E}[w(X)],\end{align*}
or equivalently,
 \begin{align*} w(x) \, \overline{F}_X(x) + \int_x^{\infty} w{'}(t) \, \overline{F}_X(t) \, \textrm{d} t = \tilde{w}(x) \, f_X(x) + \mathbb{E}[w(X)] \, \overline{F}_X(x).\end{align*}
By differentiation in x, the latter formula yields (5.2).
For
 $w(x) = x$
, the left part of (5.1) is a well-known measure in actuarial science. In particular, for
 $q \in (0,1)$
, the moment
 $\mathit{CTE}_q(X) = \mathbb{E}[X \mid X > x_q]$
, where
 $x_q = F^{-1}(q)$
is the value at risk, is a coherent risk measure called conditional tail expectation (CTE); see [Reference Artzner, Delbaen, Eber and Heath3]. Moreover, for
 $w(x)=w_n(x) = x^n$
,
 $n = 1,2,\ldots$
, [Reference Landsman and Valdez28] studied recursive formulas for tail conditional moments
 $\mathbb{E}[X^n \mid X > x_q]$
in terms of the hazard rate by using a ‘tail Stein’s identity’. More applications have been given by [Reference El Methni, Gardes and Girard16], see also the references therein. Next, for
 $w_n(x) = x^n$
, we provide an exact representation for
 $\tilde{w}_n(x)$
and
 $\mathbb{E}[X^n \mid X > x_q]$
for a Gamma and a Pareto distribution; see also Examples 3.2 and 3.5 in [Reference Landsman and Valdez28].
Example 5.1. Suppose that
 $X \sim \textrm{Gamma}(a,b)$
, where
 $a > 0$
and
 $b > 0$
(see Example 4.1). Recalling (3.4), we have
 \begin{align*}\overline{F}_{X_{w_n}}(x) - \overline{F}_X(x)= \sum_{i=1}^n \frac{(bx)^{a+i-1} \, \textrm{e}^{-bx}}{\Gamma(a+i)}= \Gamma(a) \, \sum_{i=1}^n \frac{b^{i-1}x^{i}}{\Gamma(a+i)} \, f_X(x), \end{align*}
and (2.2) yields
 \begin{align*} \tilde{w}_n(x) = \mathbb{E}(X^n) \, \Gamma(a) \, \sum_{i=1}^n \frac{b^{i-1}x^{i}}{\Gamma(a+i)}.\end{align*}
Thus, by (5.1), we obtain
 \begin{align*} \mathbb{E}[X^n \mid X > x_q] = \mathbb{E}(X^n) \, \Gamma(a) \, \sum_{i=1}^n \frac{b^{i-1}x_q^{i}}{\Gamma(a+i)} \, \lambda_X(x_q) + \mathbb{E}(X^n).\end{align*}
Furthermore, for
 $n = 1$
we get
 $\mathbb{E}[X \mid X \gt x_q] = \frac{1}{b} \, x_q \, \lambda_X(x_q) + \frac{a}{b},$
and for
 $n = 2$
we have
 \begin{align*} \mathbb{E}[X^2 \mid X > x_q] = \bigg(\frac{a+1}{b^2} \, x_q + \frac{1}{b} \, x_q^2 \bigg) \, \lambda_X(x_q) + \frac{a(a+1)}{b^2}.\end{align*}
Example 5.2. Suppose that
 $X \sim \textrm{Pareto}(a, k)$
, where
 $a > n$
and
 $k > 0$
(see Example 4.2). Since
 $\mathbb{E}(X^n) = a k^n/(a-n)$
, it follows that
 \begin{align*} \tilde{w}_n(x) = \frac{1}{a-n} \, x \, (x^n - k^n).\end{align*}
Moreover, by (5.1) we have
 \begin{align*} \mathbb{E}[X^n \mid X > x_q] = \frac{1}{a-n} \, x_q \, (x_q^n-k^n) \, \frac{a}{x_q} + \frac{a k^n}{a-n} = \frac{a}{a-n} \, x_q^n.\end{align*}
6. Concluding remarks
This paper is devoted to the construction of Stein-type covariance identities for nonnegative absolutely continuous random variables. The proposed approach is based on the use of weighted distributions and a probabilistic analogue of the mean value theorem. The main results of the paper concern a generalized covariance identity and its applications in actuarial and financial contexts. Characterization results for Gamma and Pareto distributions are obtained. The given results involve identities for the variance of a function of a random variable, and related bounds. Mixtures and generalized mixtures of the above distributions are used in the theoretical results and the illustrative examples. Various identities for risk measures arising from actuarial and financial science are also provided in terms of covariance representation. Based on weight functions, a representation for a conditional risk measure is obtained in terms of hazard rate, and a representation for the score function of X is given. Possible future developments may tackle the more general case of continuous random variables supported on the real line. Another suitable continuation may investigate the construction of Stein-type covariance identities for discrete random variables.
Acknowledgement
Dedicated to the memory of Theophilos Cacoullos.
Funding
Information There are no funding bodies to thank relating to this creation of this article.
Competing Interests
There were no competing interests to declare which arose during the preparation or publication process of this article.


