In quantitative metre, rhythm is instantiated through mapping conventions regulating the distribution of syllable weight in verse constituents (e.g. Halle Reference Halle, Bierwisch and Heidolph1970, Halle & Keyser 1971, Hayes Reference Hayes and Newmeyer1988). Most typically, a distinction between heavy and light syllables is observed, such that certain contexts permit one or the other, but not both. Through corpus studies of four metrical traditions, I demonstrate that the poets' manipulation of phonological material in every one is influenced by sensitivity to additional weight contrasts. These contrasts emerge not as categorical restrictions, but as significant preferences, even while controlling for possible lexical and contextual confounds using mixed effects models.
In particular, I examine the Homeric Greek hexameter, the Finnish Kalevala metre, the Old Norse dróttkvætt and the metre(s) of Kamban's Middle Tamil epic. Each corpus contains between 10,000 and 50,000 metrically parsed lines. In each metre, asymmetries in the metrical distributions of syllable types permit the derivation of a detailed interval scale of weight. For example, the same skeletal hierarchy is observed across languages: C0V<C0VC<C0VV<C0VVC (every link significant at p<0·01 in every language).Footnote 1 Pursued further, this method reveals some of the most articulated syllable-weight scales documented for individual languages, all in metres in which weight is usually assumed to be exclusively binary. That these scales reflect weight is supported by typological parallels with other weight-sensitive systems, including stress. First, the structure of the rhyme takes precedence over that of the onset. Second, more structure (e.g. timing slots) correlates with greater weight. Third, even when complexity is held constant, greater sonority is associated with (if anything) greater weight (e.g. C0V[obstruent]<C0V[sonorant]; though see §4.3 for a caveat concerning the lightness of rhotic-final syllables in Tamil). As another example, among stress systems distinguishing the weights of C0VC and C0VV, the former is almost always the lighter; C0VC<C0VV likewise holds of every metre examined here. Finally, if one defines a heavy syllable in metre as one that is required/preferred in strong metrical positions (or avoided in weak ones), it is sensible to speak of syllables that are progressively more favoured in strong over weak positions (all else being equal) as being progressively heavier.
A generative analysis is proposed in a maximum entropy constraint framework in which gradient/scalar constraints interact with their categorical counterparts to generate the weight-mapping typology. This typology includes quantity-sensitive systems exhibiting incomplete categorisation, i.e. some polarisation towards heavy and light categories (beyond what a purely phonetic model would imply), but with gradient sensitivity to the phonetic interface of weight continuing to leak through within categories.
In sum, although light (C0V) vs. heavy is a prominent weight distinction in all four traditions, rising to the level of categoricality in at least some of them, I show that speakers of these languages were sensitive to various additional contrasts in syllable weight as factors influencing their choices in quantitative versification, a highly conventionalised language game in which syllable weight is manipulated to effect rhythm. Individual languages are like microcosms of the cross-linguistic typology in the gradient realm, in that weight factors that are ignored for categorisation emerge as statistical preferences following the same principles and universals as their categorical counterparts in other languages. These findings are significant for the phonology of weight, for metrical grammar and for modelling the interaction of categoricity and gradience in the treatment of scalar phenomena.
1 The Ancient Greek hexameter
1.1 Metrical and corpus preliminaries
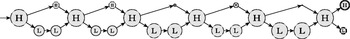
The Ancient Greek hexameter, as employed by poets such as Homer and Hesiod, is schematised in (1) (Maas Reference Maas1962, Raven Reference Raven1962, Halle Reference Halle, Bierwisch and Heidolph1970, West Reference West1982, Prince Reference Prince, Kiparsky and Youmans1989).Footnote 2 Each line comprises six metra (metrical feet), as numbered along the top of the figure. A syllable is light (notated ˘) if it is C0V; otherwise it is heavy (-). Each non-final metron contains a heavy followed by either another heavy or pair of lights. These two halves of the metron are often referred to as the longum (L; obligatory -) and biceps (B; optional ˘ ˘ or -) respectively (West Reference West1982).Footnote 3 The final metron contains a heavy followed by a single syllable of any weight.
(1)


Although the biceps always exhibits an option between - and ˘ ˘, the latter option is increasingly favoured later in the line, to the extent that the fifth (final) biceps is filled by a pair of lights over 95% of the time. To illustrate this preference, the template can be depicted as a weighted directed graph, as in Fig. 1, in which the size of each node is proportional to its likelihood of traversal (the small nodes along the top all being ‘H’).Footnote 4
Directed graph for the Greek hexameter (H=heavy, L=light). Node size is proportional to frequency.

The Ancient Greek corpus employed here consists of 24,677 parsed hexameters extracted from Homer's epics, the Iliad and the Odyssey (ca 750 bce), as available online at the Thesaurus Linguae Graecae.Footnote 5 This corpus, prepared in collaboration with Dieter Gunkel, contains only lines that scan according to the template in (1). A Perl (Wall Reference Wall2010) program was used to automatically syllabify lines (according to standard rules; see Probert Reference Probert and Bakker2010: 100–101)Footnote 6 and assign syllables to metrical positions.Footnote 7 A point of ambiguity in syllabification concerns intervocalic clusters of a stop+liquid or nasal, which can be either heterosyllabic (VC.CV) or, less commonly, compressed into an onset (V.CCV) (see Steriade Reference Steriade1982: 186–208 for details). The parser first attempts to scan the line without compression; that failing, it attempts to compress every combination of eligible clusters (if any) until it finds a scansion or exhausts its options. If no parse is found (due to additional complications), the line is excluded from the present corpus, reducing the size of the corpus by 11% (from 27,758 original lines to the present 24,677 parsed lines).
1.2 Metrical sensitivity to intra-heavy weight
The hexameter templates in (1) and Fig. 1 imply that the metre regulates only binary weight, i.e. heavies and lights. Nevertheless, as some classicists have observed (see below), the poets appear to avoid placing the lightest types of heavies in the biceps (second half of the metron), while no comparable avoidance is observed in the longum (first half of the metron), suggesting that weight-sensitivity is more fine-grained. In the remainder of this section, I support this conclusion, while controlling for possible confounds, and further argue that the poets' choices reveal sensitivity to a continuum of weight within the heavies.
The biceps is sometimes claimed to be a longer position than the longum, such that the poets prefer to fill it with heavier phonological material (e.g. West Reference West1970: 186, Reference West1982: 39, Reference West1987: 7, 22; cf. Maas Reference Maas1962: §51, Irigoin Reference Irigoin1965, Allen Reference Allen1973, Devine & Stephens Reference Devine and Stephens1976, Reference Devine and Stephens1977, Reference Devine and Stephens1994, McLennan Reference McLennan1978). West makes this claim perhaps most explicit, stating in his textbooks that ‘the biceps, being of greater duration [than the longum; KR], requires more stuffing’ (West Reference West1982: 39, Reference West1987: 22). West's evidence for this discrepancy includes the overrepresentation of certain types of heavies in longa relative to bicipitia, including C0Vː in which Vː is the result of lengthening a usually short vowel, C0Vː in which Vː is prevocalic (i.e. stands in hiatus) and C0VC.CV in which C.C is a stop–liquid sequence (1970: 186ff). These types have in common that they are all on the lighter side of heavies; some, in fact, could actually scan as light if deployed in a light metrical position. For example, a short vowel followed by a stop–liquid interlude can scan either as heavy (VC.CV) or as light (V.CCV) (see §1.1). The consistent skews of these lighter types towards the longum suggests that the longum is lighter as a metrical position than the biceps. Indeed, even in the 1st century bce, Dionysius of Halicarnassus (De Compositione Verborum §17 (Aujac & Lebel Reference Aujac and Lebel1981); see Allen Reference Allen1973: 255, West Reference West1982: 18) cited contemporary rhythmicians as holding that the biceps was of longer duration than the longum. This view is corroborated and extended here.
Consider first C0VC vs. C0VV. Both types are categorically heavy, such that either may fill a longum or a biceps. For example, (2) contains two lines from the Iliad, with the second biceps boxed. The first contains C0VC in this position, the second C0VV. (The two syllables also occupy the same position of the word, being the medials of heavy–heavy–heavy trisyllables.)
(2)
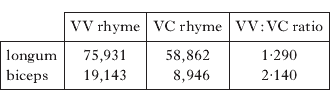
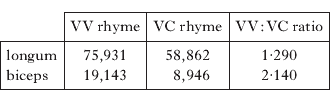
Nevertheless, VV rhymes are significantly skewed towards bicipitia (relative to VC rhymes). In the Homeric corpus, the ratio of VV to VC is 66% greater in bicipitia than it is in longa (p<0·0001), as detailed in Table I. Cross-linguistically, if a language distinguishes between the weights of VC and VV rhymes, it is virtually always the latter that is the heavier (Gordon Reference Gordon2006). These data therefore tentatively support the biceps as being heavier than the longum, though certain confounds are yet to be addressed.
VV:VC ratios in longa vs. bicipitia in Homer.
In particular, while it is possible that the hexameter template is richer than binary, as West (Reference West1970, Reference West1982, Reference West1987) assumes, it is also possible that the different distributions of VC and VV reflect factors unrelated to syllable weight (Devine & Stephens Reference Devine and Stephens1976). First, VV and VC are not identically distributed in words, and different positions of the word might be treated differently by the metre, or subject to different degrees of reduction/fortition (Devine & Stephens Reference Devine and Stephens1994: 74). As hypothetical examples, perhaps word-initial heavies are treated as heavier than word-medial heavies by virtue of, say, initial strengthening (Keating et al. Reference Keating, Cho, Fougeron, Hsu, Local, Ogden and Temple2003) or privilege (Beckman Reference Beckman1998), or perhaps word-final heavies are treated as heavier than word-medial heavies due to final lengthening (Lunden Reference Lunden2006). Thus, VC might appear to be lighter than VV not because of its intrinsic weight as a syllable, but because it is more likely to occupy reduced positions in words or feet. I am not claiming that the metre is necessarily sensitive to these factors, merely that they are logically possible confounds for which one should control. Second, word shapes are distributed unevenly in metre. For example, any heavy preceding a light can only occupy a longum. The initial syllable of a heavy–light disyllable, for instance, is almost four times as likely to be VC as it is to be VV. This sort of discrepancy might explain the higher incidence of VC in longa without any recourse to weight. In sum, even ignoring intrinsic syllable weight, VC might be skewed towards longa due to the way it is distributed within words and the way words are distributed in the line.
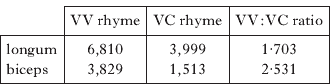
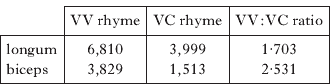
One means of controlling for these confounds is to hold word shape and position in the word constant. Table II is a retabulation of Table I, counting only VC and VV rhymes that are initial in heavy–heavy disyllables. The conclusion is confirmed: even while holding word context constant, the proportion of VV rhymes is significantly greater in bicipitia (p<0·0001).
VV:VC ratios in #_H# context only.
This approach, while simple, has two shortcomings. First, it drastically reduces the quantity of data brought to bear on the question, ignoring in this case over 90% of heavy syllables in the corpus. For less frequent, more specific or more distributionally constrained syllable types, significant trends in the corpus as a whole might be lost on this kind of test. Second, it is unclear from such a test to what extent the same result holds across other positions of the word and other word shapes.
1.3 Controlling for word context with a mixed effects model
These shortcomings can be addressed by scaling up to a statistical approach that takes all the corpus data into account, while still controlling for word shape. One such approach is to enter word context as a random effect in a mixed effects regression model.Footnote 8 Logistic regression assesses the contributions of factors in predicting a binary outcome, in this case, whether a given heavy is placed in a biceps (coded 1) or longum (coded 0). Two conditions are employed in this case to predict this outcome, namely, whether the heavy in question has a VC or VV rhyme (syllables with other rhymes are put aside here). Additionally, each syllable is coded for its word context, i.e. the weight template of its word with its position ‘X-ed out’ (e.g. LXH for the medial of a light-initial and heavy-final trisyllable). Word context is included in the model as a random effect, as it has a very large (in principle infinite) number of levels, of which the hexameter corpus is a sample, if a large one (note that some word shapes, e.g. - ˘ -, are unmetrifiable as such in the hexameter). Each word context is effectively assigned a baseline biceps-likelihood and variance, correcting for the possible positional confounds discussed above without sacrificing generality.Footnote 9
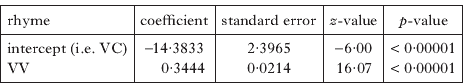
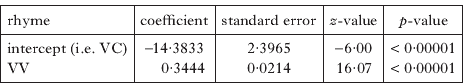
Table III is a simple regression table. VC is treated as the baseline (intercept), while VV is coded as a (binary) factor. The crucial aspect of this table is that, even while the model corrects for word context, VV has a significant (p<0·05) positive (0·34) coefficient, meaning it is significantly more skewed towards bicipitia than the intercept condition, VC.Footnote 10
Logistic model predicting position from rhyme type.
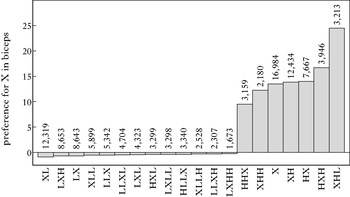
The random effects for word context (n=114) are not shown in Table III. Intercepts for the 20 most frequent word contexts in Homer are depicted as a bar chart in Fig. 2 (as in Levy Reference Levy2010). The y-axis is the likelihood (in logit units) that X in each word context occupies a biceps (considering only words in which X is heavy), ranging from −0·87 (for XL) to 24·50 (for XHL). In the leftmost thirteen word contexts, X is adjacent to a light, entailing that X occupy a longum; these intercepts are therefore uniformly low. The next six word contexts have intermediate intercepts, since X in these contexts can occupy either a longum or a biceps. Finally, in XHL, the rightmost context, X can only occupy a biceps, hence the high intercept. Word contexts are accompanied by their frequencies.
Intercepts of the 20 most frequent word contexts (for X=heavy) in Homer. Bar height indicates skew towards bicipitia (in logit units; see text). The frequency of each context is given at the top of its bar.

The model generates specific predictions as follows. Consider a VC rhyme in the word context XH, whose intercept is 13·92. The sum of the general and word context intercepts (−14·38+13·92=−0·46) is plugged into the logistic function, 1/(1+e −x) (where e ≈ 2·7183), in this case giving 0·387, or a 39% chance that VC in XH is placed in a biceps as opposed to longum. For VV in the same context, the sum also includes the relevant coefficient, giving a biceps likelihood of 47%.
1.4 A more articulated hierarchy of intra-heavy weight
In §1.3, heavies were divided into two types, namely, VC vs. VV rhymes, putting aside heavies falling into neither class. I now further subdivide the heavies, showing that the poets were sensitive to additional grades of weight within the heavies.Footnote 11
First, VC is split into two groups, namely, V[obstruent] and V[sonorant]. Cross-linguistically, the latter is typically the heavier if a distinction is made, as in, for instance, Kwakw'ala (Boas Reference Boas1947, Zec Reference Zec1995) and Lamang (Wolff Reference Wolff1983, Gordon Reference Gordon2002). More generally, sonority is claimed to positively correlate with weight (Zec Reference Zec1988, Reference Zec1995, Reference Zec, Féry and van de Vijver2003, Morén Reference Morén1999, de Lacy Reference de Lacy2002, Reference de Lacy2004, Gordon Reference Gordon2006). I also add to the model the level VVC. If the weights of VV and VVC are distinguished, typologically, the latter is expected to be the heavier, as in Pulaar (Niang Reference Niang1995). More generally, more structure is expected to correlate with (if anything) greater weight (Hyman Reference Hyman1985, Gordon Reference Gordon2002). In sum, four intra-heavy levels are now considered: V[obstruent], V[sonorant], VV and VVC.
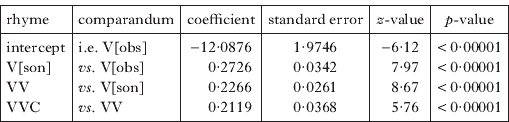
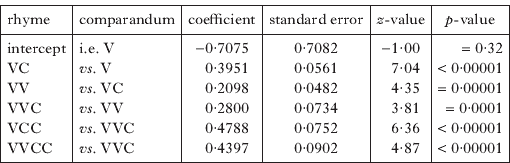
Table IV is the regression table. As in Table III, the model is logistic (binary outcome for placement in biceps), and word context is a random effect (not shown). Each rhyme type is entered as a factor, leaving out V[obstruent] as the intercept. Though one might think of rhyme type as being a single factor with different rhymes being conditions or levels of that factor, in this case each type is treated by the model as a (binary or Boolean) factor, so that the differences between types can be gauged. Factors here are forward-difference coded, meaning that each coefficient and p-value is interpreted not with respect to the general intercept (as with so-called dummy coding) but with respect to the preceding factor in the table (Venables & Ripley Reference Venables and Ripley2002).Footnote 12 The comparandum column makes this coding scheme explicit. The following hierarchy is observed: V[obstruent]<V[sonorant]<VV<VVC (every link p<0·0001), mirroring the typologically inferred hierarchy for weight.
Forward-difference coded regression table for four levels of heavies.
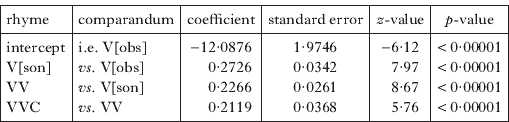
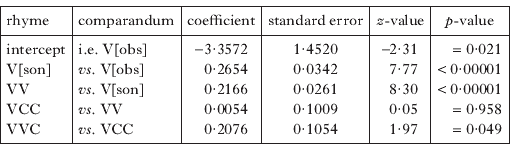
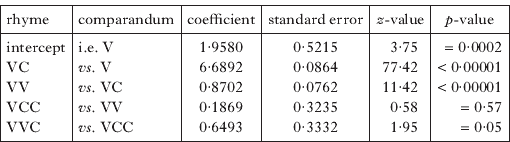
Finally, let us consider one additional level, namely VCC. Numerically, VCC patterns as intermediate between VV and VVC in biceps-skewness, but it is significantly different from neither, as Table V reveals.Footnote 13
Adding VCC to the model.
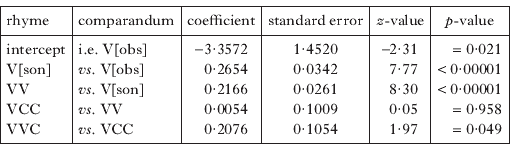
VCC is also not significantly different from V[sonorant] (p=0·02; cf. note 13), but is significantly different from V[obstruent] (p<0·0001).Footnote 14 (A non-significant effect is not positive evidence that the poets failed to distinguish the weights of two types; it merely indicates that the present corpus and methodology provide no evidence that they did.) The place of VCC in the hierarchy can be depicted in two dimensions using a Hasse diagram, as in (3), in which the implicit x-axis is biceps-skewness or weight. Solid lines indicate significant contrasts (in this case all p<0·0001), broken lines near-significant contrasts, as annotated. Contrasts are transitive (e.g. V[son]<VVC is entailed).
(3)
In conclusion, the claim of West and others that the hexameter poets prefer to place heavier heavies in the biceps than in the longum is corroborated here with an extensive parsed corpus and mixed effects modelling that factors out interference from word context and distribution. The poets are shown to be sensitive to a scale of weight within the heavies, as inferred from the relative skews of different rhyme types between longa and bicipitia. This scale aligns with the scale inferred from the cross-linguistic typologies of stress and other weight-sensitive phenomena (Gordon Reference Gordon2002, Reference Gordon2006). Moreover, it aligns with the weight scales established for the other metrical traditions examined in this article.
2 The Finnish Kalevala metre
2.1 Metrical and corpus preliminaries
The Kalevala is a Finnish epic poem based on Karelian folk songs compiled and edited in the nineteenth century by Elias Lönnrot (Lönnrot Reference Lönnrot1849). The metre is trochaic tetrameter, such that each line instantiates the abstract template in (4), which alternates between strong and weak positions. The final position, while in principle weak, can be regarded as anceps (unregulated), as it is in most quantitative metres (cf. §1.1).
(4)
A general rule for mapping syllable weight to metrical positions is given by Kiparsky (Reference Kiparsky and Gribble1968: 138) as: ‘stressed syllables must be long on the downbeat and short on the upbeat’ (for further analysis of the Kalevala metre, see Sadeniemi Reference Sadeniemi1951, Kiparsky Reference Kiparsky and Gribble1968 and Leino Reference Leino1986, Reference Leino, Siikala and Vakimo1994). By stressed syllables, Kiparsky means primary stressed syllables, which are always word-initial in Finnish.Footnote 15 Downbeats are strong; upbeats weak. Orthographic words comprising only one mora are treated as stressless clitics here. Short (i.e. light) syllables end in short vowels (C0V); all other syllables are long (i.e. heavy). Complex onsets are absent from Kalevala Finnish; thus, V(C)V is parsed V.(C)V, VCCV as VC.CV, and so forth. My parser does not resyllabify across words (see Ryan Reference Ryan2011: 71 for justification). (5) contains three sample scansions, with stressed syllables and their positions boxed.
(5)
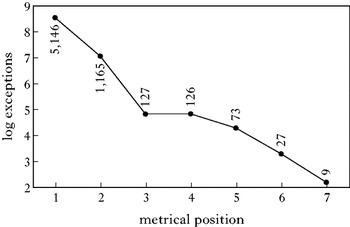
As Kiparsky (Reference Kiparsky and Gribble1968) observes, and as the examples in (5) reinforce, the mapping rule is not entirely strict, especially early in the line. It is enforced increasingly stringently towards the end of the line. Figure 3 gives the number of exceptions in each position (omitting the final position, which is anceps), taking only stressed syllables into account. As the accompanying plot illustrates, the decline in exceptions is almost one-to-one (i.e. slope ≈ −1) if one counts them on a logarithmic scale.
Distribution of exceptions to the Kalevala weight-mapping rule across non-final positions of the line.

My Kalevala corpus comprises 15,846 octosyllabic lines extracted from the text.Footnote 16 A theoretical issue bears on the construction of this corpus: Kiparsky (Reference Kiparsky and Gribble1968) maintains that the Kalevala is metrified according to derivationally intermediate rather than surface phonology. Specifically, he claims that five phonological rules are ordered after the metrically relevant level. I constructed the present corpus so that it is irrelevant for the present purposes whether Kiparsky (Reference Kiparsky and Gribble1968, Reference Kiparsky and Brame1972) is correct in his theory of presurface metrification (cf. Devine & Stephens Reference Devine and Stephens1975, Manaster Ramer Reference Manaster Ramer1981, Reference Manaster Ramer1994; philological issues are also raised: cf. Lauerma Reference Lauerma2001). I accomplished this by retaining only lines whose surface forms either match their alleged metrification forms or else depart from them only in irrelevant ways. First, two of the rules, contraction and apocope, affect syllable count, so by taking only surface octosyllables, there is no possibility that either of these rules applied. If they had, the surface form would have fewer than eight syllables. Two other rules, vowel and consonant gemination, are addressed by excluding all lines whose surface form contains a sequence that might have been an outcome of either rule. These exclusions reduce size of the corpus by 11% (from 17,890 lines to the present 15,846). Finally, the diphthongisation is immaterial for the present purposes, because diphthongs and long vowels are collapsed in the following tests.
2.2 Metrical sensitivity to intra-heavy weight in Finnish
Examining the exceptions to the Kalevala mapping rule more closely, the poets' versification choices are evidently influenced by sensitivity to a scale of weight within the heavies (contraKiparsky Reference Kiparsky and Gribble1968, Hanson & Kiparsky Reference Hanson and Kiparsky1996: 293, 308). In particular, the poets tend to prefer lighter heavies in weak positions rather than in strong ones, an asymmetry from which one can extract an intra-heavy hierarchy.
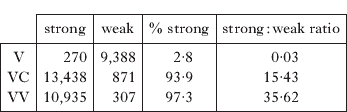
Let us begin with the rhymes VC and VV, as we did in §1.2 with Greek. Table VI gives the incidence of each (as well as V for comparison) in strong vs. weak positions. Counts are based on all stressed syllables from line-medial positions (excluding the two peripheries, which are largely unregulated). Although VC and VV are both found in strong positions over 90% of the time, the strong:weak ratio for VV is over twice as great as that of VC (p<0·0001). Put differently, despite VC and VV being comparably frequent in word-initial, stressed position (counts in Table VI), if the poet places a stressed heavy in a weak position, he or she is over twice as likely to choose a VC rhyme than a VV one (compared to the baseline ratio from strong positions).
Overrepresentations of VC in weak positions.
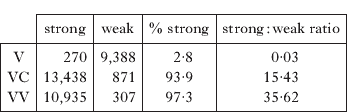
At the same time, however, VC and VV are much closer to each other in weight than either is to V. Weight is therefore being treated as an interval scale (Stevens Reference Stevens1946): multiple levels are distinguished, but they are far from evenly spaced. In this case, the gap between V and VC, straddling the traditional heavy–light cut-off, dwarfs the gap between VC and VV, though both gaps are highly significant.
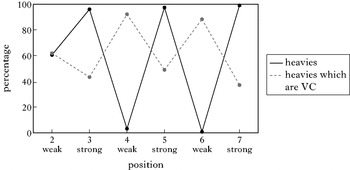
Further support for the poets' treatment of VC heavies as lighter than other heavies across the positions in the line is given by the fact that the percentage of heavies that is VC in each position correlates negatively with the strength of the poets' preference for heavies in that position. The solid line in Fig. 4 represents the latter (i.e. the percentage of stressed syllables in each position that are heavy), with peaks in odd (strong) positions. The broken line represents the VC share (i.e. the percentage of stressed heavies that are VC), which exhibits the converse pattern, i.e. peaks in even (weak) positions. In short, the poets consistently prefer lighter (e.g. VC) heavies in weak positions.
Negative correlation of VC share with position strength. VC is relatively overrepresented in weak positions, which favour lights.

Table VII is a logistic regression table for Finnish rhyme skeletons, including V (i.e. light), VC, VV, VCC and VVC.Footnote 17 The outcome is placement in a strong (1) vs. weak (0) position. Data from line-peripheral positions are once again excluded. As in §1.4, word context is included as a random effect (n=55) and factors are forward-difference coded, to be interpreted in row-wise succession.
Logistic model for skeletal structure in Finnish.
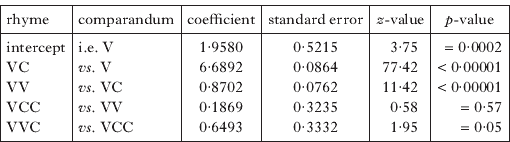
If one puts aside VCC, the hierarchy is V<VC<VV<VVC (for every link p<0·0001).Footnote 18 VCC, for its part, is significantly different from VC (p<0·0001) but not from VV (p=0·57) or VVC (p=0·05; cf. note 13). Note that VCC is relatively rare, comprising 1·7% of heavies. (6) summarises these results as a Hasse diagram.
(6)
In conclusion, as with Homeric Greek, the Kalevala poets are evidently sensitive to a scale of weight. In terms of the skeletal structure of the rhyme, V<VC<VV<VVC and VC<VCC (all p<0·0001) in both languages.
3 Old Norse dróttkvætt metre
Old Norse poetry (ca. 700–1300 ce) comprises two genres, Eddic and skaldic. I focus on the latter here, particularly the Old Icelandic dróttkvætt, the most widely attested skaldic metre. Modal line length is six syllables, though lines can be longer, due to the option of filling certain positions with two syllables. Every line ends with a heavy stressed syllable followed by an unstressed syllable. Because stress is almost uniformly word-initial (unstressed prefixes being relatively marginal; Russom Reference Russom1998: 13ff), it follows that the line typically ends with a disyllabic, heavy-initial content word.
The metrical description of the preceding four positions is more vexed. Perhaps the simplest proposal is that of Craigie (1900: 381), who proposes two metrical templates for the dróttkvætt, SWSWSW (i.e. trochaic trimeter) and SSWWSW (adding an inversion, though see Getty Reference Getty1998 for arguments that inversion does not necessarily implicate multiple templates). To this scheme, Árnason (Reference Árnason1991: 124ff, 1998: 102) adds a third template, WSSWSW. A more elaborate and also more widely employed description (‘still the model most commonly referred to by philologists’; Árnason Reference Árnason1998: 101) is Sievers' (Reference Sievers1893) five-type taxonomy for Germanic verse; cf. Kuhn (Reference Kuhn1983) and Gade (Reference Gade1995) for revisions in this tradition. For the sake of illustration, I employ Árnason's (Reference Árnason1991) system, as exemplified in (7). In this scheme, a strong position can only be filled by a stressed, heavy syllable, whereas weak positions are not as strictly regulated.
(7)
Because syllabification is a vexed issue in Norse metrics, I consider two very distinct approaches, not with a view to arguing for one or the other, nor to suggest that the correct algorithm is necessarily either, but merely to show that even with two opposing extremes (and, by hypothesis, any more nuanced intermediate position), the same general trend in gradient weight is observed. At one extreme, onset maximisation (OM; as in (7)) prioritises building onsets that are as complex as the phonotactics permits, e.g. [hun.drað] (cf. Árnason Reference Árnason1991: 123 for a qualified version of this approach). At the other extreme, coda maximisation (CM) groups all consonants with the preceding vowel, if any, e.g. [hundr.að] (Hoffory Reference Hoffory1889: 91, Beckman Reference Beckman1899: 68, Pipping Reference Pipping1903: 1, 1937, Kuhn Reference Kuhn1983: 53, Gade Reference Gade1995: 30).Footnote 19 Note the asymmetry between these approaches: while OM is reined in by phonotactics ([hun.drað], not *[hu.ndrað]), CM (in the tradition cited) is not.Footnote 20 The criterion for light vs. heavy depends on the algorithm. Under OM, the rhyme V alone is light. Under CM, V, VC and VV are light.
A corpus of 11,832 six-syllable dróttkvætt lines was obtained from the University of Sydney Skaldic Project.Footnote 21 Though the dróttkvætt is not confined to six syllables, retaining only six-syllable lines facilitates metrical parsing. Under Árnason's scheme, position 5 is always strong and positions 4 and 6 are always weak.Footnote 22 Additionally, position 3 is weak if and only if positions 1 and 2 are both strong (filled by stressed heavies). Because positions 1 and 2 are more variable (being SS, SW or WS), I put them aside here. Each syllable from the final four positions is coded for the skeletal structure of its rhyme (e.g. VC), its position type (1 for strong, 0 for weak) and its word context (as in §1.3). A logistic model then predicts metrical placement from rhyme type, factoring out word context as a random effect, as before.
Table VIII is the resulting regression table, at this point considering only stressed, word-initial syllables, as in Finnish (§2), and assuming OM. As always, the table is forward-difference coded, such that a positive coefficient indicates that the given rhyme type exhibits greater bias towards strong positions than the comparandum type. The hierarchy is thus V<VC<VV<VVC<VCC<VVCC (for every link p⩽0·0001).
Logistic model for Old Norse stressed syllable placement.
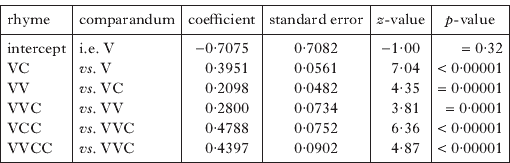
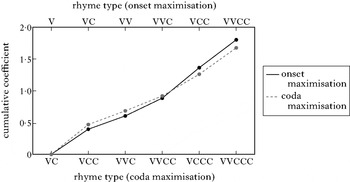
The same basic hierarchy is observed (every link p<0·0001) if CM is instead employed: VC<VCC<VVC<VVCC<VCCC<VVCCC (for every link p<0·0001). An additional consonant is now appended to each rhyme to better align the OM and CM scales. For example, the initial rhyme of [rifu] is V under OM but VC under CM.Footnote 23Figure 5 compares the two hierarchies graphically. To facilitate comparison, the intercepts are normalised to zero. To visualise the global trend, the forward-difference-coded coefficients are presented cumulatively (i.e. as sums of coefficients up to and including the given rhyme). Rhymes on the x-axis are labelled according to both schemes, with OM on top. While it is not surprising that these scales are well correlated, this comparison demonstrates that the choice of syllabification algorithm does not qualitatively alter the conclusion concerning weight.
Weight coefficients under two syllabification algorithms. Larger coefficients indicate a greater skew of stressed syllables containing the given rhyme towards metrically strong positions.

I now turn to unstressed (non-word-initial) syllables. Because they cannot occupy strong positions, strong/weak asymmetries cannot be used as a diagnostic, as they were above for stressed syllables. Instead, I capitalise on the increasing rigidity of the metre towards the end of the line. In particular, I compare unstressed syllables in positions 4 and 6, which are the final two weak positions and also the only two positions that are uniformly weak, to those in all other positions. The former are coded 0 and the latter 1, reflecting the hypothesis that unstressed syllables in uniformly weak cadential positions will tend to be the aggregately lighter set. The logistic model is otherwise set up as above.
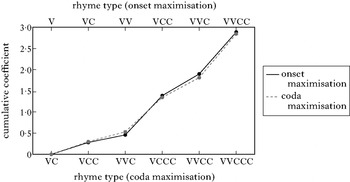
Under OM, the following hierarchy emerges: V<VC<VV<VCC<VVC <VVCC (for every link p<0·0002). Under CM, the same hierarchy emerges (for every link p<0·0001, except VCC<VVC, which is p=0·003). The coefficients under both schemes are plotted in Fig. 6, as they were in Fig. 5.
Weight coefficients under two syllabification algorithms. Larger coefficients indicate a greater avoidance of unstressed syllables containing the given rhyme in cadential weak positions.

In conclusion, two tests reveal sensitivity to a scale of weight in dróttkvætt composition. First, the heavier a stressed syllable is, the more likely it is to be placed in a strong position, giving the scale V<VC<VV<VVC<VCC<VVCC. Second, the heavier an unstressed syllable is, the less likely it is to be placed in a cadential weak position, revealing the scale V<VC<VV<VCC<VVC<VVCC. These tests are independent of each other, relying on completely disjoint sets of data, yet reveal tightly correlated hierarchies. The one exception concerns the rhymes VCC and VVC, which are adjacent under both tests, but in opposite orders. The composite hierarchy is therefore V<VC<VV<{VCC, VVC}<VVCC (where the status of the braced pair is unclear), as in (8), consistent with the V<VC<VV<VVC scales in Ancient Greek and Finnish. Moreover, the present tests cast doubt on whether the dróttkvætt privileges any single binary criterion over the various other weight distinctions in the way that Ancient Greek and Finnish appear to.
(8)
4 Tamil: Kamban's epic metre
4.1 Metrical and corpus preliminaries
The fourth and final language examined in this article is Middle Tamil, specifically Kamban's ca. 1200 ce epic poem, the Irāmāyaṇam (critical edition 1956), a Tamil telling of the South Asian Rāmāyaṇa epic (Hart & Heifetz Reference Hart and Heifetz1988).Footnote 24 A Unicode Tamil-script version of the poem was processed from the Tamil Electronic Library,Footnote 25 losslessly Romanised, and obtained (in part by applying sandhi rules, cf. Rajam Reference Rajam1992, Lehmann Reference Lehmann1994) to be more phonetically transparent. The resulting text comprises 42,128 lines in 10,532 rhyming quatrains.
According to traditional accounts of Tamil prosody (e.g. Niklas Reference Niklas1988, Zvelebil Reference Zvelebil1989, Rajam Reference Rajam1992, Murugan Reference Murugan2000), syllable weight is binary, with C0V being light. Complex onsets are forbidden, giving, for instance, V.V, V.CV, VC.CV, VCC.CV. A word-final consonant is resyllabified with a following vowel-initial word (in some editions, this is made explicit orthographically; Ryan, forthcoming). Diphthongs are treated here as V(ː)C sequences, where C is a glide [j] or [υ]. As such, they always scan as heavy, with two conditional exceptions: [aj] and (rare) [aυ] are claimed to scan as heavy word-initially but light elsewhere (for similar situations in other languages see Miyashita Reference Miyashita2002, Kiparsky Reference Kiparsky, Nelson and Manninen2003). These diphthongs, when light, are notated [ăj] and [ăυ] here.
Kamban's epic comprises an indefinite variety of metres. To begin with two examples, the first and last couplets of the text are given in (9), in IPA transcription and in terms of syllable weight (H=heavy, L=light). Weight templates are spaced at word boundaries, with bullets indicating cæsuras. In these examples, syllable count per line matches within the two couplets but not between them. Furthermore, syllables tend to correspond in weight between lines of the same verse, as indicated by underlining, but across verses, the sequences have little in common.
(9)
Even for a given syllable count, templates vary widely across verses. Modal line length is 16 syllables (though only 15% of lines are of modal length, underscoring the diversity of the corpus). Two 16-syllable verses are exemplified in (10). Position 4, for instance, is consistently heavy in the first, but light in the second. Indeed, the first verse might be characterised as 16 periods (four per line) of LLLH, the second, perhaps, as eight periods of LLLLLLHX. In short, even considering only lines of a certain syllable count, one is hard pressed to define globally applicable strong and weak positions.
(10)
4.2 Scalar weight in Tamil metrics
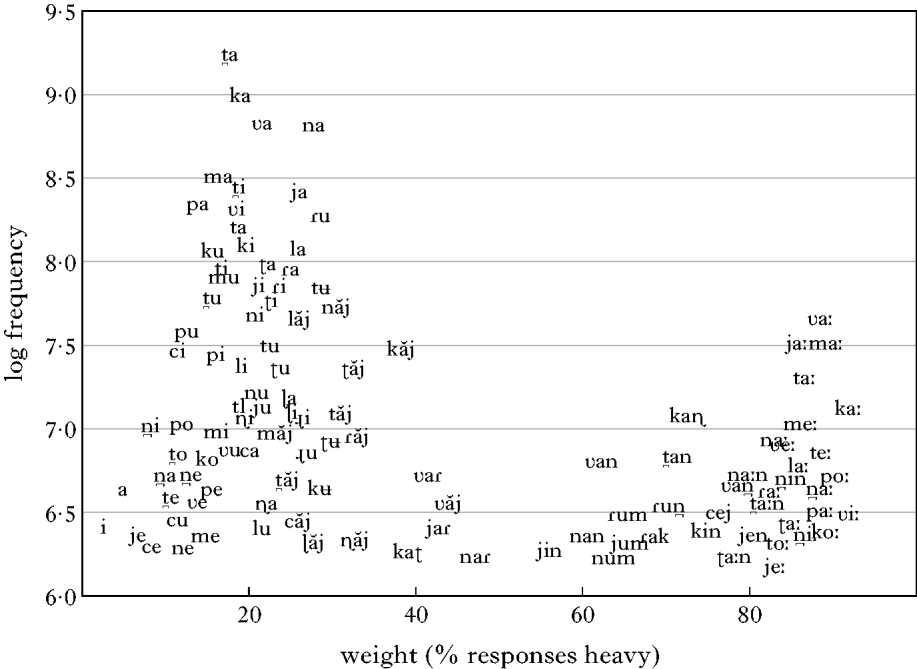
For the present purposes, it is unnecessary to provide a complete model of the metrics in order to gain insight on the treatment of syllable weight. One can capitalise on the templatic parallelism between lines within verses to observe how syllables pattern with respect to each other in terms of weight. As a preliminary illustration, Fig. 7 depicts the estimated weights of syllable types as inferred from their rates of correspondence with heavies in parallel positions of matched-length couplets. For example, in the two verses in (10), the syllable [ka] is found (after resyllabification) four times, couplet-corresponding to [ja], [ji], [ɻe] and [ i] respectively, a heavy response rate of 0%. In Fig. 7, the x-axis is the percentage of the time that each syllable type corresponds to heavies across the whole corpus. Only the 115 most frequent types are shown, corresponding to a frequency cut-off of 500.
Correspondence-estimated weights of 115 Tamil syllables. The x-axis is the percentage of the time that each syllable type is paired with a heavy syllable in the corresponding position of a matched-length couplet.
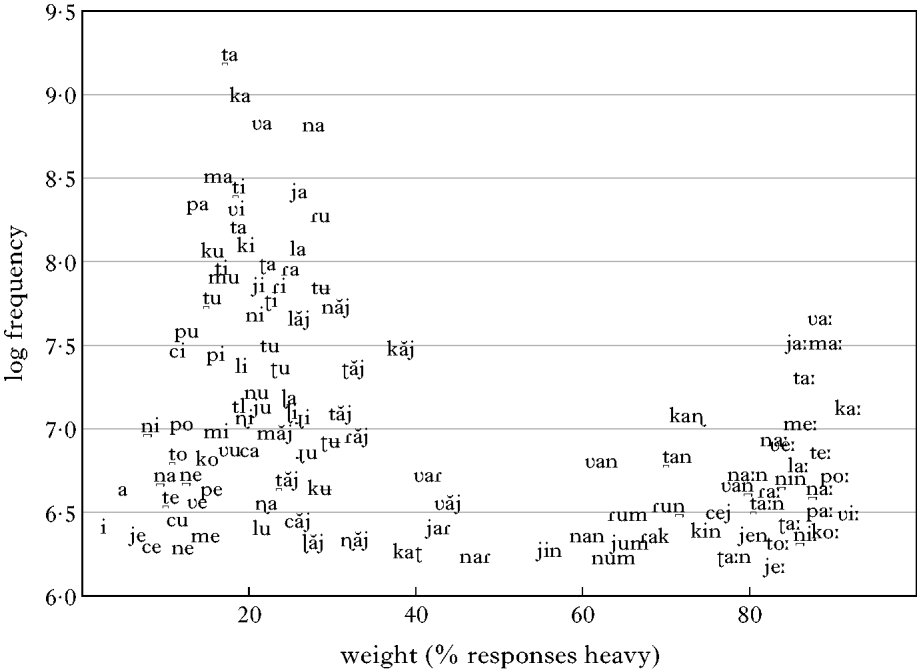
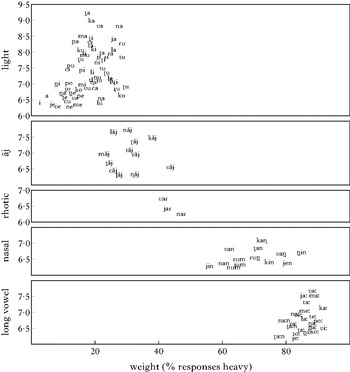
Though one might get an initial impression of light (left) and heavy (right) clouds from Fig. 7, additional stratification is readily observed. Traversing the plot from left to right, syllables can be divided into at least the following relatively coherent (if overlapping) groups: C0V (true lights), C0ăj (light diphthong), C0VR (R=rhotic, i.e. [ɾ] and [ɻ] in this dialect), C0VN (N=nasal) and C0VːC0 (syllables with long vowels).Footnote 26Figure 8 makes this clustering explicit by sorting Fig. 7 into five layers, one for each category, as labelled on the left. The x-axis, which is constant through the subplots, is the same as in Fig. 7. The y-axes of subplots are rescaled to fit their data. For all the corpus data (and not just the smaller set of frequent syllables shown in the figures), the four pairwise comparisons between groups are all significant at (Fisher's) p<0·00001.
Figure 7 filtered into five phonological classes.

Linear regression provides a more controlled means of estimating the effective weights of syllable types from their corpus distributions, corroborating the results above. Most of the model is set up as in previous sections, with rhyme shapes as factors and word contexts as random effects (§1.3). The outcome in this case is a continuous, real-valued variable, reflecting an estimate of the strength of the position in which each syllable token is placed. The general idea is that if one wishes to determine whether a given position in a given line is strong or weak, one can observe to what extent the same context in similar lines is filled by a heavy as opposed to a light syllable.
Given this approach, one must define a metric or criterion for similarity. One simple criterion is templatic identity. For example, the strength of the third (gapped) position of the line LL__HLHLLLH can be estimated from the incidence of heavies in the same position across lines with the same template. Nevertheless, with such a stringent criterion for similarity, the mean for comparanda per datum is only 2·9 lines; the corpus exhibits 14,503 different templates (ignoring boundaries). To increase the number of comparanda per datum, one can restrict one's attention to a more local part of the line, such as, say, a five-syllable window centred on the position of interest. (11) exemplifies two 16-syllable lines with the frame LL__HL at position 7.Footnote 27 Only lines with identical lengths are compared, so that the alignment of windows is commensurate. With five-syllable windows, mean comparanda per datum is 148.
(11)
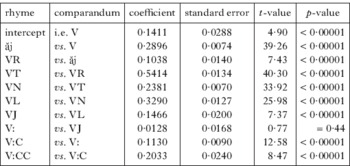
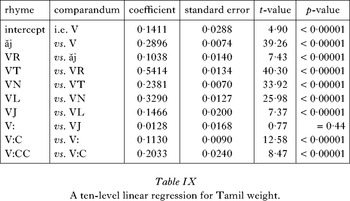
For the present linear model, then, the outcome is the log ratio heavy/light among the set of eligible comparanda, where eligibility is determined by a five-syllable window.Footnote 28 The higher the log ratio, the more often Kamban places a heavy in the given context. Ten rhymal categories are considered in Table IX, forward-difference coded, as before (§1.4). Of these ten levels, nine reach significance: V<ăj<VR<VT<VN<VL<{VJ, Vː}<VːC<VːCC (all p<0·00001). The coefficients are plotted to scale in (12). This scale is consistent with those derived in the previous sections for Ancient Greek, Finnish and Old Norse, all of which exhibit V<VC<VV<VVC.
(12)
A ten-level linear regression for Tamil weight.

4.3 Motivating the Tamil scale
As discussed in §1.4 for Ancient Greek, two general principles of weight are that increasing complexity and increasing sonority are both associated with, if anything, greater weight. These principles jointly motivate most aspects of the Tamil hierarchy in (12). First, in terms of timing slots, the scale reduces to monotonic X<XX<XXX<XXXX (cf. Hayes Reference Hayes1979: 196 on an X<XX<XXX hierarchy in Persian metre).Footnote 29 Second, within XX rhymes, the scale is largely explicable in terms of sonority. (13) uses association lines to show the alignment between a cross-linguistically typical sonority scale (Hogg & McCully Reference Hogg and McCully1987: 33, Parker Reference Parker2002) and the scale inferred from Tamil metrics. With the exception of the rhotics, the two scales align.
(13)
Two details of the Tamil hierarchy remain to be explained. First, the light diphthong [ăj], if segmentally complex, would be expected to be near VJ, not V. Second, and more intriguingly, rhotic codas pattern as unexpectedly light, given their high sonority. I first show that an independent phonological system, prosodic minimality, also treats VR rhymes as light, in opposition to VC≠R and Vː. I then propose that the relatively light weights of VJ and VR are grounded by their short durations.
Like Latin (Mester Reference Mester1994), Tamil exhibits a bimoraic minimum for all word types, as supported by the systematic absence of light words (cf. Ketner Reference Ketner2006), by certain length alternations (e.g. [υa-ɾa] ‘come-inf’ vs. [υaː] ‘come (imp)’; cf. Prince & Smolensky Reference Prince and Smolensky1993, Blumenfeld Reference Blumenfeld2010), and by loanword adaptation. As Ryan (Reference Ryan2011: 107) argues, C0VR (where R∊{ɾ, ɻ}, as above) is subminimal, while C0VC with any other coda is not. In a C0VR monosyllable, V must be long. This restriction is evidently prosodic, given that vowel length is otherwise contrastive in C0VR syllables in all positions of polysyllabic words. At the same time, several phonetic and phonological criteria converge on the rhotics being highly sonorous, and, as typologically expected, intermediate between the laterals and glides; they are also argued to be coda consonants, as opposed to part of the nucleus (2011: 107).Footnote 30
As a preliminary assessment of the correlation between phonetic properties and metrical weight, Ryan (Reference Ryan2011: 119) collected phonetic data on 351 consecutive syllables in a recording of high-register Tamil (the standard acrolect cen-tamil; Tamil is diglossic), specifically, Kausalya Hart reading passages in the audio supplements to her Tamil textbook (Hart Reference Hart1999). Though several centuries separate this recording from Kamban, pronunciation of the acrolect has evidently changed relatively little, as evidenced in part by its faithfulness to the orthography, which was largely settled by Kamban's time (Ryan Reference Ryan2011: 119). To the extent that pronunciation has changed, this comparison is over-conservative: one would expect the correlations reported below to be (if anything) stronger if the phonetic and poetic corpora were more closely aligned.
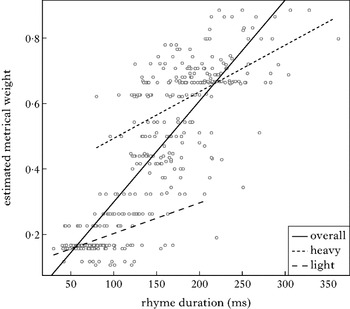
Figure 9 plots the durations of rhyme tokens on the x-axis against their inferred metrical weights on the y-axis (on the connection between duration and syllable weight, see Maddieson Reference Maddieson1993, Hubbard Reference Hubbard1994, Broselow et al. Reference Broselow, Chen and Huffman1997, Gordon Reference Gordon2006). Duration was measured following Gordon (Reference Gordon2002), using discontinuities in the spectrogram and waveform. For syllables closed by a geminate, the midpoint of the geminate was taken to be the endpoint of the rhyme. The weight of each rhyme type was estimated from the metrical corpus using the linear regression model in §4.2, except with individual rhyme types assessed as factors. The range on this axis is close to (0, 1), because the model's log odds estimates are translated into probabilities. The plot contains 351 points, one for each phonetic token. Some horizontal stratification is visible when several phonetic tokens instantiate the same rhyme. Three regression lines are shown. The longest is the overall correlation for all points (Pearson's correlation r=0·840, Spearman's rank correlation ρ=0·847; both p<0·0001). The two shorter regression lines are based on the heavy and light points taken separately, revealing significant correlations even within each of the binary subsets (r, ρ>0·45 for both; all p<0·0001).
Metrical weight (y-axis) as a function of rhyme duration (x-axis).

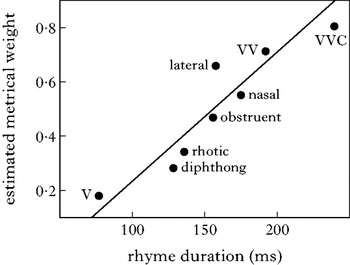
This plot reveals that metrical weight is largely (r=0·84) predictable from rhymal duration.Footnote 31 Moreover, the treatment of [ăj] and VR rhymes as relatively light finds a phonetic motivation. Figure 10 is based on the same data as Fig. 9, but shows category means for the categories from §4.2 for which n>10 in the phonetic data (r=0·929, ρ=0·976; both p<0·001). Crucially, ‘diphthong’ (i.e. [ăj]) and ‘rhotic’ (i.e. VR) are the two categories nearest to V, on both the metrical and phonetic dimensions. Thus, the subhierarchy V<ăj<VR<VT is significant not only in the metrics (§4.2), but also in the phonetics (respective sample sizes of the four categories: 171, 28, 19, 63; respective t-test one-tailed p-values for the three contrasts: p<0·001, p=0·020, p=0·018).
Figure 9 in terms of category means.

In conclusion, Kamban's metrical behaviour suggests sensitivity to a gradient continuum of weight, such that (at least) V<ăj<VR<VT<VN<VL<{VJ, Vː}<VːC<VːCC (for every contrast p<0·00001). In terms of skeletal structure, this is the same scale established for Ancient Greek, Finnish and Old Norse: V<VC<VV<VVC. The subhierarchy within VC in Tamil (R<T<N<L<J) is explicable in terms of sonority, with the exception of the rhotics, which, despite being sonorants, pattern as the lightest codas. Minimality also treats VR as lighter than VC≠R. I propose that the light weights of VR and [ăj] are motivated by their short durations (or energies integrated over duration; note 31).
5 Weight mapping in metre
5.1 Varying categoricity in the treatment of weight
I now turn to the treatment of gradient weight in a generative model of weight mapping. Following work in generative metrics (e.g. Halle Reference Halle, Bierwisch and Heidolph1970, Halle & Keyser 1971, Kiparsky Reference Kiparsky1977, Hayes Reference Hayes and Newmeyer1988, Hanson & Kiparsky Reference Hanson and Kiparsky1996), I assume that metres comprise abstract templates of strong and weak positions (§2.1), among other structure. Constraints indexed to these positions define the sets of syllables permitted in them (e.g. *Heavy/W: ‘penalise a heavy syllable in a weak position’). By weight mapping, I refer to this correspondence relation between metrical positions and syllabic weight.
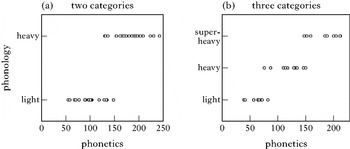
I begin by schematising a space of logical possibilities. At one extreme, weight mapping might be fully categorical. Figure 11 illustrates hypothetical binary (a) and ternary (b) categorisations of dummy data (sampled from normal distributions) on an arbitrary perceptual-phonetic scale (x-axis).Footnote 32 These plots are organised like Fig. 9 above, in which the y-axis is weight (a phonological variable) and the x-axis duration (a phonetic variable). The categories in Fig. 11 overlap somewhat on the phonetic dimension, representing, let us say, a bias for phonological simplicity in categorisation at the expense of fidelity to the phonetic scale (Hayes Reference Hayes, Darnell, Moravcsik, Newmeyer, Noonan and Wheatley1999, Gordon Reference Gordon2002).
Phonetics–phonology interface under total categorisation. (a) two weight categories (light and heavy); (b) three weight categories (light, heavy and superheavy).

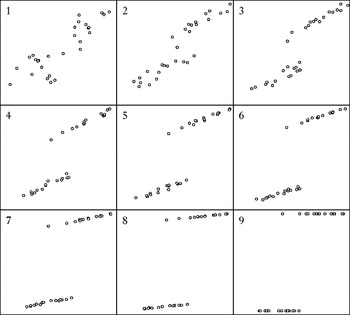
At the other extreme, one can imagine that the phonology (y-axis) might directly reflect the relevant perceptual-phonetic scale without any interference from categorisation (cf. Steriade Reference Steriade, Broe and Pierrehumbert2000, Reference Steriade, Hume and Johnson2001, Flemming Reference Flemming2001, Reference Flemming2003, Reference Flemming, Hayes, Kirchner and Steriade2004), as illustrated by plot 1 of Fig. 12. In this plot, the correlation between phonetics (x-axis) and phonology (y-axis) approximates the diagonal (adding noise for realism). As the other plots in Fig. 12 suggest, one can also imagine situations intermediate between these two extremes, in which the phonology is polarised towards categories, but continues to reflect gradient sensitivity to a phonetic scale within categories. I term this intermediate situation incomplete categorisation (not to be confused with overlapping but complete categorisation, as in Fig. 11). The plots in Fig. 12 are arranged from the least categorical (plot 1) to the most (plot 9); cf. Fig. 11.Footnote 33
A continuum from no (plot 1) to total (plot 9) categorisation. As categoricity increases, the correlation weakens between the phonetic (x-axes) and phonological (y-axes) distributions.

Metres evidently vary in the extent to which they treat weight as binary-categorical as opposed to gradient, instantiating different points along the continuum of categoricity sketched in Fig. 12. Impressionistically, weight appears to be highly (though not exclusively) categorical in Homer's epics (§1) and the Kalevala (§2), but less so in Kamban's epic (§4), in which it is not obvious that categorisation plays any role. More concretely, compare the Tamil (a) and Finnish (b) distributions in Fig. 13. In both plots, the means for V, VC, VV and VVC are superimposed on grey circles representing rhyme tokens. The Tamil data are repeated from Figs 9 and 10, with the same organisation. The Finnish rhyme weights (y-axis) are estimated from the logistic model in §2.2 (see also Table VI), while their durations (x-axis) are based on a small auditory corpus.Footnote 34 In both plots, the data are relatively continuous on the phonetic dimension (as also seen in Gordon's Reference Gordon2006 Finnish data). They differ mainly on the metrical dimension. The Tamil data are continuous, with VC (whether including or excluding VR; §4.3) being approximately halfway between V and VVC. The Finnish data, by contrast, are widely separated, with VC being over ten times as close to VVC as it is to V.Footnote 35 At the same time, weight is not exclusively binary in Finnish, as the contrasts in VC<VV<VVC are significant (§2).
Differing categoricity in Tamil (Kamban) vs. Finnish (Kalevala) metres. Plots arranged as in Fig. 9.

As a constraint framework capable of handling gradient variation, I employ maximum entropy (maxent) grammar (Johnson Reference Johnson, Merlo and Stevenson2002, Goldwater & Johnson Reference Goldwater, Johnson, Spenador, Eriksson and Dahl2003, Wilson Reference Wilson2006, Jäger Reference Jäger, Zaenen, Simpson, King, Grimshaw, Maling and Manning2007, Hayes & Wilson Reference Hayes and Wilson2008, Ryan Reference Ryan2010, Hayes & Moore-Cantwell Reference Hayes and Moore-Cantwell2011; cf. Boersma & Pater Reference Boersma and Pater2008), a type of Harmonic Grammar (Smolensky & Legendre Reference Smolensky and Legendre2006, Pater Reference Pater2009, Potts et al. Reference Potts, Pater, Jesney, Bhatt and Becker2010), but with probabilistic interpretation of candidate harmonies and often a Bayesian approach to constraint weighting. As in all varieties of Harmonic Grammar, the score of each candidate is the sum of its weighted violations. In maxent grammar, rather than treating the candidate with the greatest score as the categorical winner, all scores are transformed into probabilities (though often ones so close to zero or one that the output is effectively categorical). Specifically, if s i is a candidate's non-negative penalty score, p(candidate)=e −si/∑je −sj, where j ranges over all candidates. Constraints are weighted so as to maximise the likelihood of the observed distribution of outputs, possibly with smoothing. See the references above for a more detailed overview.
Incomplete categorisation can be modelled in such a framework by the interaction of categorical and scalar constraints. A fully categorical distribution (as in plot 9 in Fig. 12) is modelled by giving the relevant categorical constraints positive weights and scalar constraints zero weights. A direct interface distribution (as in plot 1) can be achieved by giving scalar constraints positive weights and categorical constraints zero weights. Incomplete categorisation emerges if both categorical and scalar constraints are given positive weights (e.g. plots 2 through 8, according to their relative weights).
A categorical constraint (e.g. *Heavy/W) is either violated or not for each locus of violation; it cannot be violated multiple times (or to some other degree) by a single locus (McCarthy Reference McCarthy2003). A scalar (also known as gradient) constraint, by contrast, is violable to a greater or lesser degree by a single locus (e.g. Flemming Reference Flemming2001, Pater, forthcoming). In the present case, scalar constraints are labelled with the comparative suffix (e.g. *Heavier/W) and violated to a real-valued degree supplied by the phonetics (as in Flemming Reference Flemming2001; cf. the more abstract integer scale for sonority implied by HNuc; Prince & Smolensky Reference Prince and Smolensky1993, McCarthy Reference McCarthy2003, Pater, forthcoming).Footnote 36 For the sake of illustration, the phonetic model here is based on the log mean duration of the rhyme, though a more accurate model would likely be perceptually grounded, integrating loudness, auditory recovery, and so forth (Gordon Reference Gordon2005, Crosswhite Reference Crosswhite2006, Gordon et al. Reference Gordon, Jany, Nash and Takara2008).
(14) is a maxent tableau illustrating four candidate lines for the Kalevala metre. Lines (a) and (b) are actually from the Kalevala, while (c) and (d) are octosyllabic snippets extracted from prose, included for comparison. Four mapping constraints are given in the top row, in decreasing order of weight. For the Kalevala metre, they evaluate only stressed (i.e. word-initial) syllables, excluding those in line-initial position (cf. Sadeniemi Reference Sadeniemi1951, Kiparsky Reference Kiparsky and Gribble1968; see §2.1). The first two constraints, *Heavy/W and *Light/S, are categorical (as above). The final two, *Heavier/W and *Lighter/S, are their scalar counterparts, whose violations are real numbers generated by a phonetic function representing the weight percept. For the present purposes, this function is based solely on the log mean durations of rhyme types, as estimated from the auditory corpus above (note 34). In particular, for each locus of violation, the scalar constraint is violated by the locus's distance from the unmarked end of the scale (cf. McCarthy's Reference McCarthy2003: 82 paraphrase of HNuc). Here, the extrema are taken to be the minimum and maximum log mean durations (log(88 ms)=4·48 and log(408 ms)=6·01).Footnote 37 Consider, for example, the stressed rhyme at in candidate line (a). Because at occupies a weak position, it violates both *Heavy/W (by 1) and *Heavier/W (by log(264 ms)−log(88 ms)=1·099). Note that the violation is the same if seconds or some other unit is used instead of milliseconds: log(0·264 sec)−log(0·088 sec)=1·099. If a rhyme type is absent from the present data, the mean of its skeletal type is substituted.
(14)
Line (a) also contains one stressed syllable in a (non-initial) strong position, namely pór. Although this is a heavy syllable, satisfying *Light/S, it still receives a small penalty from *Lighter/S for its distance from the heavy extremum (log(408 ms)−log(238 ms)=0·539). Constraint weights (computed using the maxent grammar tool (Wilson & George Reference Wilson and George2008), with μ=0 and σ2=1000) are given under their labels. To compute the penalty for line (a), its violation vector <1, 0, 1·1, 0·54> is multiplied by the constraint weight vector <1·348, 1·055, 0·449, 0·252>, and the result <1·348, 0, 0·49, 0·14> is summed, giving 1·98. The given p-value represents in this case the proportion of lines in the corpus with penalties higher than the candidate's. Thus, p=0 for line (c) (from prose) indicates that no line of the Kalevala has that high a penalty. Line (d), while also from prose, is as harmonic as almost 10% of Kalevala lines by this metric. This cline of harmony recalls the notions of complexity (Halle & Keyser Reference Halle and Keyser1971) and gradient metricality (Hayes Reference Hayes, Kiparsky and Youmans1989b, Youmans Reference Youmans, Kiparsky and Youmans1989). Finally, note that this grammar is not a complete model of Kalevala weight mapping. For one, it ignores the fact that violations become increasingly costly towards the end of the line (§2.1); it also sets aside the apparently weaker constraints on unstressed syllables (note 15).Footnote 38
Though constraints such as categorical *Heavy/W and scalar *Heavier/W partially overlap in their workloads, their coexistence generates a typology in which categoricity can vary across systems. An independent argument for the simultaneity of categorical and gradient weight concerns metres such as the Homeric hexameter. Recall from §1.1 that the metre contains two position types, the longum and the biceps, both of which, if filled by a single syllable, permit only a heavy.Footnote 39 In this respect, the metre is categorical in its treatment of lights and heavies, as could be modelled under the present theory by giving constraints such as *Light/Biceps and *Light/Longum sufficiently high weights.Footnote 40 At the same time, however, a clear weight gradient is observed within the heavies, such that the heavier the heavy, the more skewed it is towards the biceps, all else being equal (§1.4). To model this difference, the weight of *Lighter/Biceps can exceed that of *Lighter/Longum, such that lighter heavies incur greater penalties in bicipitia.
(15) is a maxent tableau for the hexameter. Since no phonetic corpus is available, for the sake of exposition, the Finnish data used above are also recruited here (as above, if a rhyme type is absent from the data, the skeletal mean stands in). Even though the categorical constraints are rarely violated, they need not be given the highest weights, since they overlap (‘gang up’) with their scalar counterparts in eliminating lights. Note that the grammar as stated is incomplete; for instance, it ignores the possibility of filling a biceps with a pair of lights, focusing only on the treatment of syllable weight.
(15)
In sum, categorisation and a gradient phonetic interface are argued to interact in weight mapping. First, categorisation can be incomplete, in which case polarisation towards categories is evident, but not so absolute that the grammar is insensitive to the underlying phonetic scale within categories. Second, even if categorisation is complete, it can still be accompanied by intra-categorial gradience, as in the hexameter, which exhibits both a strict binary cut-off and sensitivity to a continuum of weight within the heavies.
5.2 On other possible approaches
As an alternative approach to gradient weight, consider first a theory under which weight is exclusively binary, but syllables are assigned to categories probabilistically, perhaps owing to variable mora projection (on non-variable mora-based weight, see Hyman Reference Hyman1985, Zec Reference Zec1988, Hayes Reference Hayes1989a, Steriade Reference Steriade1991, Gordon Reference Gordon2002). For example, the coda of a VC rhyme might exhibit, say, a 90% chance of projecting a mora, while the second timing slot of VV might exhibit greater odds, such that the latter patterns as slightly heavier. More technically, the question is whether the grammar treats gradient weight as a continuous variable (as proposed in §5.1) or as a discrete (also known as Bernoulli) random variable.
The Greek hexameter furnishes an empirical argument against intra-heavy weight as variable binary weight. As discussed in §5.1, an intra-heavy scale is evident even among positions in which light syllables are categorically forbidden. In the fifth metron, for instance, the VC share of heavies is 69% higher in the longum than in the biceps, even though neither position can be filled by a light (West Reference West1970). For an analysis in terms of variable binary weight, we can assume that progressively lighter heavies are progressively more likely to be categorised as light, while the lighter status of the longum is motivated by its being more tolerant of lights than the biceps. From this analysis, it follows that lighter heavies (e.g. VT and VN) should be found more than occasionally in light positions in the fifth metron, as should true lights (rhyme V) in the fifth longum. Both predictions are incorrect.
Such an approach would likely also treat timing slots individually, which I term atomisation, rather than considering properties of the whole rhyme as an unanalysed unit, as I did in §5.1. Even without reference to moras, one can imagine an atomised version of the approach in §5.1. In Tamil, for example, *Glide-Coda/W could outweigh *Lateral-Coda/W, motivating the lighter treatment of VL vis-à-vis VJ. (For strong positions, in which VJ is the less marked, *Lateral-Coda/S could outweigh *Glide-Coda/S.) The approach in §5.1 is simpler and more restrictive. First, under atomisation, cases like Tamil would require (at least) several constraints to replicate the work done by a single constraint in §5.1, though it is difficult to say precisely how many. Is there a different constraint for each coda consonant? If not, how are consonants grouped? These sorts of questions are moot in §5.1. Indeed, the distributions in §4.3 suggest that Tamil weight is continuous, rather than discretised into even several well-defined levels. One can always approximate a continuous distribution by superimposing increasingly fine-grained categories on it, though if the distribution reflects an intrinsically gradient variable, such an exercise is analytically extravagant.
Moreover, atomisation risks massive overgeneration. For instance, one could generate Tamil′, a language phonetically identical to Tamil, except in that its metrics treats VL as heavier than VJ, reversing the weights of the aforementioned constraints. To avoid this problem, one might (i) stipulate a fixed ordering of constraints, (ii) project constraint weights from a phonetic model or (iii) reformulate the constraints in terms of a stringency hierarchy. I address these three analytical tacks in turn.
First, fixing the ordering amounts to adding a set of stipulations that were unnecessary in §5.1. Furthermore, even with a fixed ordering, metres are generated in which position types exhibit unrelated patterns of conflation, e.g. one in which weight is strictly binary, but the cut-off falls between VL and VJ for weak positions and between VT and VN for strong positions. Such a metre is compatible with the hierarchy T<L<J, etc. In §5.1, by contrast, the binary criterion (if any) is constant (assuming that the shorthand predicates ‘light’ and ‘heavy’ are by definition complementary), and all scalar constraints access the same phonetic scale. (See also de Lacy 2004 contra fixed rankings.)
Second, one might project constraint weights from a phonetic model (cf. Steriade Reference Steriade, Hanson and Inkelas2009a on projection in Optimality Theory), avoiding some of the aforementioned overgeneration problems (e.g. Tamil′), as well as the need for scalar constraints. However, the questions concerning the number and division of categories persist, as do the methodological concerns regarding the explosion of the constraint set in an attempt to simulate a continuous distribution (cf. Zhang Reference Zhang2007). Moreover, even insofar as this approach approximates a notational variant of §5.1, it is more complex on multiple dimensions, in that it requires both many more constraints and an additional grammatical component to project their weights.
Finally, expressing constraints in terms of a universal stringency hierarchy avoids some overgeneration issues (e.g. Tamil′) and arguably possesses theoretical and empirical advantages over fixed rankings (Prince Reference Prince1999, de Lacy Reference de Lacy2002, Reference de Lacy2004). Since heaviness is marked in weak positions, for instance, a stringent weak-indexed constraint would penalise not only a particular rhyme, but any and all heavier rhymes (e.g. *VL-or.heavier/W, *VN-or.heavier/W). Such constraints can be freely ranked, producing various patterns of conflation, but never markedness reversals (as with Tamil′). Several of the problems outlined above also apply to stringency. For one, stringency overgenerates discrepant patterns of conflation for strong vs. weak positions. Further, it requires many more constraints than §5.1, including at least 18 for Tamil (nine levels in §4.2×two position types), though perhaps many more, considering that the hierarchy in principle subsumes any weight distinction significant in any language. The universal hierarchy is itself problematic. Consider, for instance, the fact that VR is lighter than VT in Kamban (§4), but heavier than it in Homer (§1). If this difference is phonetically grounded, the approach in §5.1 gets it for free. A stringency approach, by contrast, can accommodate such superficial reversals only by adding complexity to the universal hierarchy (e.g. distinguishing between shorter and longer rhotics), further recapitulating the phonetics. Finally, the theory in §5.1 predicts that weight should reflect the phonetics not only in terms of the rank order of rhyme types, but also in terms of the magnitudes of various contrasts (e.g. in (12), VR<VT and VT<VN are both significant, though the magnitude of former difference is over twice as great as that of the latter). Because stringency specifies a rank order but is mute on relative differences, it is less restrictive. This final point also applies to any phonetic differences between languages that might be more fine-grained than a given theory of phonological features encodes (e.g. coda singleton [n] being slightly longer in one language than in another). Assuming such differences exist, the proposal here, unlike stringent constraints, predicts them to be relevant to gradient weight.
6 Conclusion
This article challenges the often assumed but rarely tested position that syllable weight is exclusively binary in metrics (see especially Jakobson Reference Jakobson1933 and Devine & Stephens Reference Devine and Stephens1976 for explicit statements of this view). Case studies of four quantitative metres drawn from three language families in every case reveal sensitivity to a continuum of weight within the heavies. Gradient weight in each case characterises an interval scale, in which differences are a matter not just of ranking, but also of relative degree. Furthermore, the scales obtained across traditions are well correlated, not only with each other, but also with the hierarchies inferred from the cross-linguistic typologies of stress and other weight-sensitive phenomena.
In §4.3 and §5.1, it was argued that the features of the gradient scale need not be stipulated, but emerge directly from the perceptual-phonetic interface via constraints whose degrees of violation are phonetically defined (as in Flemming Reference Flemming2001). A maxent constraint grammar approach in which these scalar/gradient constraints coexist with their categorical counterparts generates the attested typology of (i) complete categorisation, (ii) incomplete categorisation, as in the Kalevala metre, in which the phonology is clearly polarised towards categories (vis-à-vis the phonetics), but the phonetic interface continues to leak through within categories, (iii) mixed categorical-gradient systems, as in the Greek hexameter, in which a categorical cut-off is impermeable, but intra-categorial gradience is also observed, and (iv) fully gradient, direct interface systems, of which Kamban's Tamil metre is possibly a case.