





1. Introduction
Embodied approaches to language comprehension propose that conceptual meaning is grounded, at least in part, in perceptual-motor systems (e.g., Fischer & Zwaan, Reference Fischer and Zwaan2008; Gallese & Lakoff, Reference Gallese and Lakoff2005; Glenberg & Kaschak, Reference Glenberg and Kaschak2002; Pulvermüller, Reference Pulvermüller2013). From this perspective, understanding language may involve the partial re-enactment of sensorimotor experiences associated with the described event (Barsalou, Reference Barsalou1999, Reference Barsalou2008), such that perceptual-motor representations contribute to the construction of meaning in language comprehension. This theoretical framework has been particularly influential in explaining action, spatial and motion language, where meaning is closely related to embodied experience (Ahlberg et al., Reference Ahlberg, Bischoff, Kaup, Bryant and Strozyk2018; Kaschak et al., Reference Kaschak, Madden, Therriault, Yaxley, Aveyard, Blanchard and Zwaan2005; Stanfield & Zwaan, Reference Stanfield and Zwaan2001; Zwaan et al., Reference Zwaan, Madden, Yaxley and Aveyard2004). Embodied accounts therefore converge in the argument that perceptual-motor information is activated and contributes to mental simulation in language comprehension (Barsalou, Reference Barsalou1999, Reference Barsalou2008; Bergen & Chang, Reference Bergen, Chang, Östman and Fried2005; Zwaan, Reference Zwaan and Ross2004). Although embodied approaches have motivated extensive language comprehension research, questions remain regarding how observed behavioural evidence should be interpreted and the conditions under which they emerge during sentence processing.
One of the most widely used behavioural indices for investigating mental simulation has been the response time (RT). Across a range of studies (e.g., Chen et al., Reference Chen, de Koning and Zwaan2020; de Koning et al., Reference de Koning, Wassenburg, Bos and van der Schoot2017; Rommers et al., Reference Rommers, Meyer and Huettig2013; Zwaan et al., Reference Zwaan, Stanfield and Yaxley2002; Zwaan & Pecher, Reference Zwaan and Pecher2012), responses are typically faster when linguistic descriptions are paired with semantically congruent rather than incongruent visual stimuli, a phenomenon commonly referred to as the compatibility effect (Bergen, Reference Bergen, Gonzalez-Marquez, Mittelberg, Coulson and Spivey2007). Such effects have often been interpreted as being consistent with embodied accounts because they may indicate that comprehenders construct perceptually grounded representations during language comprehension, facilitating behavioural performance when these representations align with subsequently presented visual information.
However, critics have argued that compatibility effects should be treated as suggestive evidence for the embodied cognition hypothesis rather than unequivocally demonstrate that language comprehension relies on perceptual simulation (Mahon & Caramazza, Reference Mahon and Caramazza2008; Meteyard et al., Reference Meteyard, Cuadrado, Bahrami and Vigliocco2012). This is not only because mental simulation can also be revealed through interference effects (e.g., Bergen et al., Reference Bergen, Narayan and Feldman2003, Reference Bergen, Lau, Narayan, Stojanovic and Wheeler2010; Edmiston & Lupyan, Reference Edmiston and Lupyan2017; Horchak & Garrido, Reference Horchak and Garrido2022; Kaschak et al., Reference Kaschak, Madden, Therriault, Yaxley, Aveyard, Blanchard and Zwaan2005; Ostarek & Huettig, Reference Ostarek and Huettig2017; Richardson et al., Reference Richardson, Spivey, Barsalou and McRae2003), but also because this behavioural pattern may sometimes reflect amodal semantic processing, task-induced mental imagery or decision-related comparison processes between sentence and visual stimuli, rather than mental simulation per se (Weiskopf, Reference Weiskopf2010). Consequently, compatibility effects remain interpretively ambiguous. For terminological clarity, the term congruency effect is used instead throughout the study to refer to the behavioural advantage for semantically congruent over incongruent semantic-visual pairings, which reflects semantic-visual alignment.
Moreover, the magnitude of congruency effects varies substantially across different studies. A growing body of research suggests that their magnitude depends on experimental context, particularly task demands (Bechtold et al., Reference Bechtold, Cosper, Malyshevskaya, Montefinese, Morucci, Niccolai, Repetto, Zappa and Shtyrov2023; Ostarek & Huettig, Reference Ostarek and Huettig2019; Wang, Reference Wang2026). Tasks requiring explicit comparison between visual and linguistic information generally produce stronger congruency effects than tasks that do not require such mapping (Rommers et al., Reference Rommers, Meyer and Huettig2013). In addition, previous studies have suggested that the point at which visual information is encountered during sentence comprehension may modulate the magnitude of congruency effects, with effect sizes increasing as additional semantic information accumulates (Nishide et al., Reference Nishide, Zhao and De Deyne2025; Sato et al., Reference Sato, Schafer and Bergen2013). Together, these findings suggest that the magnitude of congruency effects is not fixed across all contexts but is modulated by the processing goals and the availability of semantic information. However, previous studies have typically examined task demands and visual probe timing separately, making it difficult to determine how these two factors may jointly influence the emergence and magnitude of congruency effects during sentence comprehension.
Accordingly, the present study investigates the conditions under which congruency effects become behaviourally observable during incremental sentence processing. Specifically, the study compares two behavioural paradigms with different processing goals (verification vs. viewing) while systematically manipulating the point at which visual probes are presented. By jointly manipulating task demands and informational availability while holding the linguistic materials constant, the study aims to clarify when congruency effects emerge during incremental sentence comprehension and how they are shaped by task demands. The study contributes to the ongoing debate about the semantic-visual alignment by specifying the conditions under which congruency effects emerge.
1.1 Task demands and congruency effects in semantic-visual alignment
Congruency effects have been reported across a wide range of studies examining semantic-visual alignment in language comprehension (e.g., Redmann et al., Reference Redmann, FitzPatrick and Indefrey2019; Stanfield & Zwaan, Reference Stanfield and Zwaan2001; Yang, Reference Yang2016; Zwaan et al., Reference Zwaan, Stanfield and Yaxley2002; Zwaan & Taylor, Reference Zwaan and Taylor2006), but their magnitude varies considerably across behavioural paradigms (Chen et al., Reference Chen, de Koning and Zwaan2020; Rommers et al., Reference Rommers, Meyer and Huettig2013). One of the influential explanations for the variability in congruency effects concerns task demands. Task demands have been interpreted as reflecting differences in attentional focus and cognitive resource allocation devoted to semantic-visual information alignment during language comprehension (Bechtold et al., Reference Bechtold, Cosper, Malyshevskaya, Montefinese, Morucci, Niccolai, Repetto, Zappa and Shtyrov2023; Ostarek & Huettig, Reference Ostarek and Huettig2017, Reference Ostarek and Huettig2019).
Congruency effects have been widely observed in sentence-picture verification tasks (e.g., de Koning et al., Reference de Koning, Wassenburg, Bos and van der Schoot2017; Stanfield & Zwaan, Reference Stanfield and Zwaan2001; Zwaan et al., Reference Zwaan, Stanfield and Yaxley2002; Zwaan & Pecher, Reference Zwaan and Pecher2012). In this paradigm, participants read or listen to a sentence and judge whether a subsequently presented visual stimulus matches the described event. The task often yields robust congruency effects because it places a strong emphasis on the perceptual-semantic correspondence by demanding explicit judgment on the alignment between the interpreted sentence meaning and the visual stimulus.
In addition, congruency effects have also been investigated in tasks imposing relatively lower demands on explicit semantic-visual alignment, including sensibility judgment tasks (Hu & Zhao, Reference Hu and Zhao2026; Yang, Reference Yang2016; Zwaan & Taylor, Reference Zwaan and Taylor2006), picture-naming tasks (Bub & Masson, Reference Bub and Masson2006; Redmann et al., Reference Redmann, FitzPatrick and Indefrey2019; Rommers et al., Reference Rommers, Meyer and Huettig2013; Zwaan et al., Reference Zwaan, Stanfield and Yaxley2002) and delayed picture-recognition tasks (Pecher et al., Reference Pecher, Zanolie and Zeelenberg2007; Richardson et al., Reference Richardson, Spivey, Barsalou and McRae2003), although these effects are sometimes attenuated or absent in these paradigms (Chen et al., Reference Chen, de Koning and Zwaan2020; Rommers et al., Reference Rommers, Meyer and Huettig2013). This variability suggests that congruency effects reflect not only the correspondence between linguistic and visual information, but also the extent to which such correspondence becomes behaviourally expressed under different attentional focus towards integrating linguistic and visual information. However, task demands have been frequently invoked as a post-hoc explanation for inconsistent magnitude of congruency effects across studies. Given most studies have adopted only a single task while differing substantially in their materials and experimental paradigms (Pecher et al., Reference Pecher, van Dantzig, Zwaan and Zeelenberg2009; Stanfield & Zwaan, Reference Stanfield and Zwaan2001; Yang, Reference Yang2016; Zwaan et al., Reference Zwaan, Madden, Yaxley and Aveyard2004), the specific contribution of task demands remains difficult to isolate.
A few studies have demonstrated that the behavioural detectability of congruency effects is sensitive to task requirements by manipulating task demands while holding visual stimuli constant. Rommers et al. (Reference Rommers, Meyer and Huettig2013) reported stronger effects when participants were instructed to create a visual image of the situation described by the sentence in the picture-naming task, or when they performed a sentence-picture verification task, than when they completed the picture-naming task without any explicit emphasis on semantic-visual correspondence. These findings suggest that the behavioural detectability of semantic-visual alignment is enhanced when tasks direct attention towards the correspondence between linguistic and visual representations and support a goal-adaptive view of congruency effects. More broadly, similar task-sensitive patterns have also been reported in other behavioural congruency paradigms. For example, Bub and Masson (Reference Bub and Masson2006) observed faster gesture initiation only when participants were required to identify and name the object, whereas no reliable congruency effects were found when participants merely viewed the objects. Moreover, existing viewing paradigms have primarily investigated lexical-level processing, leaving it unclear whether semantic-visual alignment can be behaviourally detected during viewing the visual stimuli in sentence comprehension. In addition, although these studies have compared performance across behavioural paradigms while holding the materials constant (Bub & Masson, Reference Bub and Masson2006; Rommers et al., Reference Rommers, Meyer and Huettig2013; Zwaan et al., Reference Zwaan, Stanfield and Yaxley2002), these comparisons have predominantly contrasted processing-based tasks (e.g., sentence-picture verification, viewing) with (speech) production-based tasks (e.g., picture-naming). As a result, it is difficult to determine whether observed differences reflect genuine task modulation or broader differences between responding across processing and (speech) production modalities.
To address these gaps, controlled experimental comparisons are needed, in which task demands are systematically manipulated while linguistic and visual materials, as well as response modality (e.g., button pressing, speech production), are held constant across conditions. Such designs enable a more precise evaluation of how online processing task demands (i.e., whether explicit sentence-visual mapping is required) influence the behavioural expression of semantic-visual alignment during sentence processing. Nevertheless, even under comparable task requirements, the amount of semantic information available at the point of visual presentation may also influence the behavioural detectability of semantic-visual alignment. This factor is referred to here as the informational context of semantic-visual alignment.
1.2 Informational context of semantic-visual alignment in incremental sentence processing
Sentence comprehension can involve constructing situation models – dynamic mental representations that integrate information about entities, actions, spatial relations and temporal structure – which are assumed to be incrementally updated as linguistic input unfolds (Zwaan, Reference Zwaan2008; Zwaan & Radvansky, Reference Zwaan and Radvansky1998). However, much of the existing evidence has relied on probes presented after sentence completion (Bai et al., Reference Bai, Yang and Fan2022; Borreggine & Kaschak, Reference Borreggine and Kaschak2006; Liu et al., Reference Liu, Wang and Han2024). Such designs make it difficult to determine whether semantic-visual alignment emerges immediately upon encountering early diagnostic cues or instead develops gradually as additional linguistic information accumulates across sentence constituents.
Self-paced reading paradigms interleaved with visual probes have been particularly informative in addressing this question because they allow researchers to test the behavioural detectability of semantic-visual alignment at different stages of sentence processing. Sato et al. (Reference Sato, Schafer and Bergen2013), for example, employed a self-paced sentence-picture verification paradigm to examine incremental semantic-visual alignment of object shape information in Japanese. By inserting pictures at different sentence positions, they observed reliable congruency effects at multiple stages of sentence comprehension, with stronger effects when pictures were presented later in the sentence (i.e., after the verb) than at earlier positions. They interpreted this pattern as evidence that mental representations are progressively refined as additional linguistic constraints accumulate, supporting an incremental strengthening account in which early event representations remain underspecified and gradually converge on a more detailed interpretation.
More recently, Nishide et al. (Reference Nishide, Zhao and De Deyne2025) extended this insertion-based logic to motion event comprehension by examining how learners incrementally construct locational versus directional interpretations of English prepositional phrases (e.g., The bird flew in the cage). Critically, they manipulated the informational context by presenting a target video either immediately after the preposition or after sentence completion, thereby testing whether motion construal becomes available as soon as an ambiguous cue is encountered or becomes more behaviourally detectable after later integration. Their results showed that directional interpretations were more difficult than locational ones, and this difference was larger when verification occurred after sentence completion, suggesting that directional construal became increasingly salient as additional linguistic information accumulated.
Additional evidence for the role of informational context comes from Hu and Zhao (Reference Hu and Zhao2026), who used a self-paced sensibility judgment task interleaved with schematic diagrams to examine native English speakers’ processing of English phrasal verbs. They found that diagram congruency facilitated sensibility judgments only when the diagram appeared after sentence completion rather than immediately after the phrasal verb. They therefore argued that congruency effects in first language (L1) processing are sensitive to the amount of linguistic information available, with later probe positions supporting stronger congruency effects when earlier linguistic input is not yet sufficient to support a stable event representation.
Together, these findings indicate that congruency effects can exhibit temporal build-up, consistent with the view that semantic-visual alignment may strengthen as comprehenders accumulate constraining information and progressively commit to a specific event representation (Bergen & Chang, Reference Bergen, Chang, Östman and Fried2005, Reference Bergen, Chang, Hoffmann and Trousdale2013). Under such an account, early representations may remain provisional or underspecified and become increasingly refined as additional cues narrow the space of possible interpretations.
Nevertheless, caution is needed in interpreting these findings. First, larger congruency effects observed at sentence-final probe positions may partially reflect sentence wrap-up processes, during which comprehenders consolidate and integrate information across the entire sentence, making the event representation more stable and easier to align with a visual stimulus. Second, the increasing pattern reported in previous studies has typically been observed in contexts where early linguistic cues provide only partially diagnostic information, requiring later constituents to resolve ambiguity or fully specify event structure. It therefore remains unclear whether congruency effects would necessarily exhibit the same temporal build-up when early cues already provide highly diagnostic information about the event schema. In such contexts, congruency effects may stabilise earlier during processing, resulting in comparable effect magnitude across incremental stages rather than progressively increasing effects. Clarifying how the temporal profile of congruency effects varies as a function of informational context is therefore important for understanding how semantic-visual alignment unfolds during incremental sentence comprehension.
1.3 The present study
Motivated by the above research gaps, the present study examines how semantic-visual alignment is shaped by task demands and the temporal locus of visual probes during incremental processing of Mandarin motion sentences. Motion events provide a suitable domain because spatial relations become available incrementally as linguistic input unfolds. According to image schema accounts, the evolving representation of a motion event is organised around components such as the trajector (TR), landmark (LM), path, source and goal (Johnson, Reference Johnson1987; Talmy, Reference Talmy2000). For example, the spatial relation conveyed by the preposition into can be characterised by a constellation of three schemas including TR-LM, Source-Path-Goal and Container (Bergen & Chang, Reference Bergen, Chang, Östman and Fried2005). In a sentence like ‘A worker walked into the office’, the worker functions as the TR (a movable figure), the office as the LM (a stable reference object) and the motion trajectory progresses towards a goal location (i.e., office) that also functions as a container – a bounded region with an interior and exterior. Therefore, motion language comprehension requires the incremental integration of spatial information into evolving situation models.
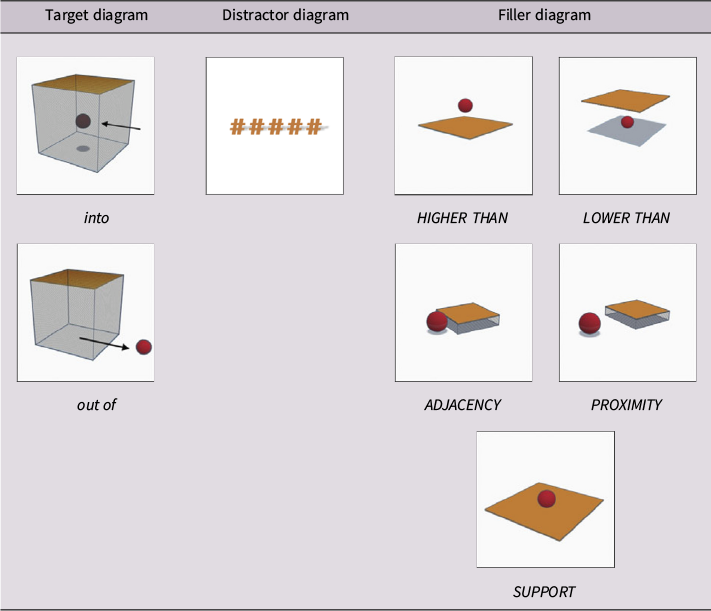
The present study was designed to investigate online semantic-visual alignment of schematic motion representations during incremental sentence comprehension, rather than perceptual inference following sentence completion. Whereas traditional sentence-picture verification tasks often ask participants to verify perceptual properties that are implied (e.g., de Koning et al., Reference de Koning, Wassenburg, Bos and van der Schoot2017; Stanfield & Zwaan, Reference Stanfield and Zwaan2001; Zwaan et al., Reference Zwaan, Stanfield and Yaxley2002), the present diagrams correspond to motion relations that are explicitly encoded by the linguistic input (e.g., into, out of) in the sentence stimuli. Unlike the realistic pictures commonly used in traditional sentence-picture verification tasks, the present study employed schematic diagrams as the visual stimuli presented during sentence processing. Whereas pictures typically preserve rich perceptual features of objects and events, the target diagrams used here are graphic representations composed of simple symbols (see Table 1), such as lines, dots, arrows and geometric shapes (Bryant & Tversky, Reference Bryant and Tversky1999; Tversky et al., Reference Tversky, Zacks, Lee, Heiser, Anderson, Cheng and Haarslev2000), which should not be regarded as pictorial equivalents of the lexical items into or out of. Rather, they were heuristic representations of underlying image-schema relations, abstracting away from object identity and perceptual detail while preserving only the relational structure of the motion event (Wang, Reference Wang2026; Wang & Zhao, Reference Wang and Zhao2024b).
Target, distractor and filler diagrams

Table 1. Long description
The table is organized into four columns: Target diagram, Distractor diagram, and two Filler diagram columns.
Row 1 diagrams:
- Target: A translucent cube with a dark sphere at its center. A black arrow points from the right into the cube toward the sphere. A shadow is cast on the bottom face. Labeled into.
- Distractor: Five orange hash symbols in a horizontal row.
- Filler 1: A red sphere floating above a tilted orange square plane. Labeled Higher than.
- Filler 2: A red sphere resting on a gray plane with an orange rectangular plane floating above it. Labeled Lower than.
Row 2 diagrams:
- Target: A translucent cube with an orange top. A black arrow points from the center of the cube outward toward a red sphere on the right. Labeled out of.
- Filler 1: A red sphere to the left of a rectangular box with an orange top. Labeled ADJACENCY.
- Filler 2: A red sphere on the left and a flat orange rectangular prism on the right. Labeled PROXIMITY.
Row 3 diagram:
- A single filler diagram centered across the last two columns showing a red sphere resting directly on the center of a flat orange square plane. Labeled SUPPORT.
The present study focuses on Mandarin motion expressions, which provides a theoretically informative test case as motion events are typically expressed through resultative verb compounds (RVCs). An RVC consists of two verbal elements (e.g., dǎ pò ‘hit-break’, kàn wán ‘read-finish’), with the second element describing the resulting state or path associated with the event denoted by the first element (Li, Reference Li2013; Wang et al., Reference Wang, Sun, Tham, Wang and Sun2015). The present study focuses on motion-related RVCs (Li & Thompson, Reference Li and Thompson2009; Wang & Zhao, Reference Wang and Zhao2024b), which combine a displacement verb with a directional verb (e.g., zǒu-jìn ‘walk-into’ and bān-chū ‘move-out’). In these constructions, the displacement verb encodes the manner of motion (e.g., zǒu ‘walk’, pǎo ‘run’, bān ‘move’), whereas the directional verb specifies the path of motion (e.g., jìn ‘into’, chū ‘out’). Because the directional verb provides the earliest explicit cue to motion path, this linguistic property enables us to test whether effects emerge once critical path information becomes available and remain stable as subsequent linguistic information unfolds, or whether congruency effects strengthen as additional sentence information accumulates, as suggested by previous studies using self-paced reading paradigms interleaved with visual probes (Hu & Zhao, Reference Hu and Zhao2026; Nishide et al., Reference Nishide, Zhao and De Deyne2025; Sato et al., Reference Sato, Schafer and Bergen2013). Building on the congruency effects observed at the sentence-final diagram region in Mandarin processing (Wang & Zhao, Reference Wang and Zhao2024b), the present study aims to examine whether these effects become behaviourally detectable during incremental comprehension of Mandarin sentences.
To investigate these issues, we adopt a self-paced reading paradigm interleaved with schematic diagrams in which diagrams are inserted at two different regions of segmented sentences. Two factors are manipulated. First, task demands are varied by comparing a sentence-diagram verification task with a sentence-diagram viewing task. Importantly, the two tasks employ identical linguistic and visual stimuli, enabling a controlled comparison of whether congruency effects reflect task-sensitive enhancement of semantic-visual alignment rather than differences in materials and response modes. Second, the informational context of visual probing is manipulated by presenting the diagram either immediately after the directional verb or after the LM noun. These regions are selected because the directional verb provides the earliest reliable cue to the motion path in Mandarin RVCs, whereas the LM noun completes the spatial relation of motion. Comparing these two regions therefore allows us to examine whether semantic-visual alignment is established immediately after path information becomes available, or whether they become stronger as additional spatial information is incrementally integrated. Diagrams are adopted as they provide controlled and effective probes of semantic-visual alignment of schemas during language processing (Wang, Reference Wang2026; Wang & Zhao, Reference Wang and Zhao2024a, Reference Wang and Zhao2024b).
The study addresses two guiding research hypotheses. First, we examine whether congruency effects are task-sensitive and predict stronger effects in the verification task than in the viewing task. Second, we test whether congruency effects vary as a function of diagram insertion region. If early path cues in Mandarin allow rapid establishment of semantic-visual alignment, congruency effects should emerge early and remain relatively stable across regions. The present study therefore provides a stringent assessment of whether congruency effects under different task conditions necessarily strengthen as linguistic input unfolds or instead reflect temporally stable semantic-visual alignment once diagnostic motion information becomes available during incremental Mandarin motion sentence processing.
2. Method
2.1 Participants
149 Chinese adults (48 males and 101 females) were recruited from a WeChat official platform (mean age = 23.64, SD = 5.10). The participants were from different universities in China, including 119 undergraduates and 30 postgraduates. All participants were native Mandarin Chinese speakers with an average self-rated L1 proficiency score of 89.09 (SD = 11.57) out of 100Footnote 1. In addition to Mandarin and English, some participants reported knowledge of other languages, such as Cantonese (n = 17), Japanese (n = 16), Korean (n = 6), Spanish (n = 1) and Thai (n = 1). Written informed consent was obtained from each participant prior to participation. Upon completion of the tasks, participants received monetary compensation for their time. Demographic questionnaire is provided in Supplementary Material 1.
2.2 Materials and design
The study employed a self-paced reading interleaved with diagram paradigm (Sato et al., Reference Sato, Schafer and Bergen2013), using a 2 Task (verification, viewing) × 2 Congruency (congruent, incongruent) × 2 Diagram Region (after directional verb, after LM noun) factorial Latin square design. By manipulating the semantic congruency between sentences and diagrams, the study aimed to examine congruency effects, whereby congruent sentence-diagram pairings were expected to facilitate behavioural responses relative to incongruent pairings in both verification and viewing tasks. RT, defined as the latency from diagram onset to the participant’s key press, served as the dependent measure in both tasks. In the verification task, RT reflected the time participants spent making a diagram verification judgment, whereas in the viewing task it reflected the time they spent viewing the diagram before advancing to the next segment.
The task was manipulated between participants to avoid strategic carry-over effects that might arise if the same participants performed both tasks within a single session. The verification and viewing tasks shared identical sentence and visual stimuli and differed only in task instructions. Experiencing the verification task could encourage participants to actively evaluate diagram-sentence relations even during the viewing task, thereby reducing the intended contrast in task demands. The diagram region was manipulated between participants to minimise the salience of the timing manipulation. A within-participant manipulation would have made variation in diagram position more apparent, potentially encouraging participants to anticipate when the diagrams would appear or adopt task-specific strategies directed at diagram presentation. Such strategic monitoring could have influenced online sentence processing and complicated the interpretation of the observed effects across diagram regions.
2.2.1 Visual stimuli
The visual stimuli were adapted from Wang and Zhao (Reference Wang and Zhao2024b) and consisted of two target diagrams (into diagram, out-of diagram), one distractor diagram (‘######’) and five filler diagrams (See Table 1). The target diagrams represented spatial relations corresponding to the meanings of the directional verb jìn (‘into’) and chū (‘out of’). The into diagram depicted a red ball moving into a box, whereas the out-of diagram depicted a red ball moving out of a box. The distractor diagram, consisting of a string of hashtags (######), was comparable in size and colour to the target diagrams but did not contain spatial information. It was included to reduce the salience and predictability of the target stimuli, thereby discouraging diagram verification strategies.
Five filler diagrams depicted other spatial configurations, including SUPPORT, ADJACENCY, PROXIMITY and VERTICALITY (HIGHER THAN and LOWER THAN). These filler diagrams were crafted based on descriptions of TR-LM relations such as on, close to, near, over/above and under/below, as discussed in previous cognitive linguistic studies (Lindstromberg, Reference Lindstromberg2010; Tyler & Evans, Reference Tyler and Evans2003). The inclusion of filler diagrams was intended to obscure the study focus and minimise strategic responding.
2.2.2 Sentence stimuli
The target Chinese directional verbs were 进 (jìn, ‘into’) and 出 (chū, ‘out of’). A total of 78 sentence stimuli were used (See Supplementary Material 2), including 48 target sentences and 30 filler sentences. All target sentences were divided into ten segments (e.g., 早上九点,/一位/勤奋的/员工/走/进/办公室/然后/开始/工作。English Translation: At 9 a.m., /a/diligent/worker/walked/into/the office/and/started/working.). Target sentences were randomly divided into three subsets, in which 16 were paired with the into diagram, 16 with the out-of diagram and the remaining 16 with the distractor diagram. Sentence-to-diagram assignments were counterbalanced across two diagram regions, resulting in six stimulus lists.
To ensure that the sentence sets were comparable, frequencies of RVCs and RVC-LM collocations were checked using the Centre for Chinese Linguistics (CCL) corpus (Zhan et al., Reference Zhan, Guo and Chen2003, Reference Zhan, Guo, Chang, Chen and Chen2019). After log-transformation, one-way ANOVAs revealed no significant differences across three target sentence subsets for the following measures: RVC frequency (F (2, 21) = 0.07, MSE = 1.68, p = 0.94), RVC-LM collocation frequency (F (2, 21) = 0.03, MSE = 2.56, p = 0.97) and sentence length (F (2, 21) = 2.14, MSE = 0.003, p = 0.14) for jìn; RVC frequency (F (2, 21) = 0.29, MSE = 2.22, p = 0.75), RVC-LM collocation frequency (F (2, 21) = 2.01, MSE = 1.30, p = 0.16) and sentence length (F (2, 21) = 0.35, MSE = 0.003, p = 0.71) for chū.
Filler sentences were adapted from a Chinese grammar book (Ross & Ma, Reference Ross and Ma2014), and did not include the two target Chinese directional verbs. The filler sentences matched in length to target sentences and segmented into ten regions. They were randomly paired with five filler diagrams and were consistent across six stimulus lists.
2.2.3 Sentence-diagram verification task
The sentence-diagram verification task was adapted from the self-paced sentence-picture verification task in Sato et al. (Reference Sato, Schafer and Bergen2013) and implemented using a noncumulative linear (i.e., moving window) display with phrase-by-phrase segmentation. Each trial began with a fixation cross (+) indicating the onset position of the first sentence segment. Subsequently, each segment of the sentence was displayed on the screen one at a time. A diagram was interleaved with the sentence and appeared at one of two diagram regions: after the directional verb (Region 7) or after the LM (Region 8). Table 2 shows the specific regions where diagrams were inserted in a sample sentence stimulus.
Regions of sentence segments and diagrams

Table 2. Long description
The table is organized into eleven numbered columns.
Row 1 is titled After directional verb. It contains the Mandarin sentence segments for nine A M, a, diligent, worker, walk, into, followed by a 3 D diagram, then office, and then, start, work.
Row 2 is titled After L M. It contains the same Mandarin sentence segments but the 3 D diagram is placed after the word office instead of after the word into.
The 3 D diagrams in both rows depict a transparent cube with an orange top face. At the center of the cube is a dark sphere. A black arrow originates from the right side of the frame and points directly toward the sphere. The sphere casts a dark circular shadow on the bottom interior face of the cube.
The note below the table defines L M as landmark and specifies that the English translations are literal word-for-word translations of the Mandarin stimuli.
Note: LM, landmark. The English translations are literal, word-for-word translations of the original Mandarin stimuli.
In each trial, participants pressed the space bar to read the sentence segment by segment. When a diagram appeared, they were asked to make a binary verification judgment on whether the diagram depicted a spatial configuration implied by the sentence. Participants pressed ‘F’ for ‘no’ or ‘J’ for ‘yes’ as quickly as possible within a 5-second time limit. After each trial, including both target and filler trials, participants answered a reading comprehension question presented in Chinese. The questions targeted either information from the sentence (e.g., the adverbial clause, LM or TR) or the accompanying diagram to encourage attention to both linguistic and visual information. For sentence-based questions (e.g., Who went into the office?), two Chinese answer options were presented (e.g., the worker vs. the boss). For diagram-based questions (e.g., Does either of the following diagrams appear in this sentence? or Which of the following diagrams appears in this sentence?), participants responded by selecting between two Chinese options (e.g., yes vs. no; left vs. right) presented together with two of the diagram stimuli (see Table 1). A complete list of comprehension questions and answer options is provided in Supplementary Material 2. Participants responded by pressing the ‘F’ or ‘J’ key within a 10-second time limit. The inclusion of comprehension questions following both target and filler trials was intended to discourage superficial or inattentive responding and enhance the reliability of the RT data.
Diagram verification RTs and accuracy rates (ARs), as well as reading comprehension question ARs, were automatically recorded online. Verification responses were coded as correct if participants responded ‘yes’ to diagrams that were semantically congruent with the Chinese directional verb in the sentence (e.g., into diagram – jìn sentences) or if ‘no’ to diagrams that were semantically inconsistent with the directional verb in the sentence (e.g., into diagram – chū sentences). These criteria were validated by semantic consistency ratings between jìn sentences and into diagrams, as well as chū sentences and out-of diagrams (Wang, Reference Wang2026; Wang & Zhao, Reference Wang and Zhao2024b). Trials involving distractor and filler diagrams were excluded from data analysis because they did not instantiate the motion relations central to the experimental manipulation and served only to reduce stimuli predictability.
2.2.4 Sentence-diagram viewing task
The sentence-diagram viewing task procedure closely resembled the sentence-diagram verification task, adopting a self-paced reading interleaved with diagram paradigm. The diagram regions were the same as the sentence-diagram verification task (see Table 2), appearing after the directional verb (Region 7) or after the LM (Region 8). Participants read each sentence segment-by-segment by pressing the spacebar. The key procedural difference was that, when a diagram appeared, participants were instructed to view it and press the spacebar when they finish, but they were not required to make any explicit verification judgment about the sentence-diagram relationship. To discourage superficial reading and maintain participants’ attention to both the linguistic and visual stimuli during the viewing task, sentence- and diagram-based comprehension questions were randomly interleaved across target and filler trials. The comprehension questions were identical to those used in the verification task, so that the two tasks differed only in whether participants verified the diagram or simply viewed it. Diagram RTs and comprehension ARs in the target trials were automatically recorded online. Only trials involving target diagrams were included in the analysis.
2.3 Procedure
Data were collected online using PsyToolkit (version 3.4.4; Stoet, Reference Stoet2010, Reference Stoet2017). Participants first completed a demographic questionnaire and were then randomly assigned to either the sentence-diagram verification task (n = 82) or the sentence-diagram viewing task (n = 67). Within each task, participants were further randomly assigned to one of six counterbalanced stimulus lists. Consequently, 71 participants were presented with diagrams after the directional verb (verification: n = 40; viewing: n = 31), and 78 were presented with diagrams after the LM (verification: n = 42; viewing: n = 36). In both tasks, participants completed six practice trials before the formal phase. During the practice phase of the verification task, participants received corrective feedback on both diagram verification responses and comprehension question responses. During the practice phase of the viewing task, corrective feedback was provided for comprehension question responses only. In the formal phase of both tasks, participants completed 78 trials without receiving any feedback. Each participant completed the experiment only once and was not allowed to revise previous responses. The entire experimental session lasted approximately 15 to 20 minutes.
2.4 Data analysis
Data analyses were conducted in R (version 4.4.0; R Core Team, 2024). Anonymised data are provided in Supplementary Material 3. Prior to analysis, standard data trimming procedures were applied. Three participants with comprehension ARs below 60% (verification: n = 2; viewing: n = 1) were excluded because such performance suggests insufficient attention to sentence content and approaches chance level on two-choice comprehension questions. In addition, ten participants in the verification task with verification ARs below 60% were excluded because this indicates unreliable engagement with the diagram-sentence relation, making the verification responses unsuitable for analysing congruency effects (Chen et al., Reference Chen, Wang, Zhang and Liu2020). The final sample comprised 136 participants, including 70 in the verification task (diagram after directional verb: n = 33; diagram after LM: n = 37) and 66 in the viewing task (diagram after directional verb: n = 31; diagram after LM: n = 35).
For both tasks, analyses were restricted to trials containing target diagrams from the formal task phase. Trials with incorrect verification responses or incorrect comprehension question responses were excluded (11.7%). RTs exceeding ±3 SDs from each participant’s mean were removed (1.9%) to reduce the influence of extreme outliers while preserving the majority of the response distribution (Chen et al., Reference Chen, Wang, Zhang and Liu2020).
All RTs were log-transformed prior to modelling. Linear mixed-effects models were fitted to the log-transformed RTs using the lme4 package (Bates et al., Reference Bates, Maechler, Bolker, Walker, Christensen, Singmann, Dai, Scheipl, Grothendieck, Green, Fox, Bauer and Krivitsky2022). An initial model was fitted with task, congruency and diagram region as fixed effects (Linck & Cunnings, Reference Linck and Cunnings2015). Random-effects structures were evaluated by comparing the model with random intercepts only and the model including random slopes for congruency by participants and items using likelihood ratio tests. The latter showed improved model fit and was therefore retained for reported analyses. To examine whether the congruency effect changed over the course of the experiment, an additional linear mixed-effects model was fitted including trial order, congruency and their interaction as fixed effects. Statistical significance was assessed using the lmerTest package (Kuznetsova et al., Reference Kuznetsova, Brockhoff and Christensen2017). Model convergence was verified, and statistical assumptions were checked. Pairwise comparisons and estimated marginal means (EMMs) were computed using the emmeans package (Lenth et al., Reference Lenth, Buerkner, Giné-Vázquez, Herve, Jung, Love, Miguez, Riebl and Singmann2023). EMMs were back-transformed to the response scale for reporting and visualisation. In addition, post-hoc simulation-based power analyses were conducted using the simr package (Green & MacLeod, Reference Green and MacLeod2016). Based on 1000 simulations, the estimated power to detect the target fixed effects and interactions reached approximately 80%, indicating adequate sensitivity for the effects of interest. Effect sizes were estimated using Cohen’s d. Following the guideline (Cohen, Reference Cohen1988), values of approximately 0.2, 0.5 and 0.8 were interpreted as small, medium and large effects, respectively. Visualisations were generated using the ggplot2 package (Wickham, Reference Wickham2016). R scripts used for data analysis are provided in Supplementary Material 4.
3. Results
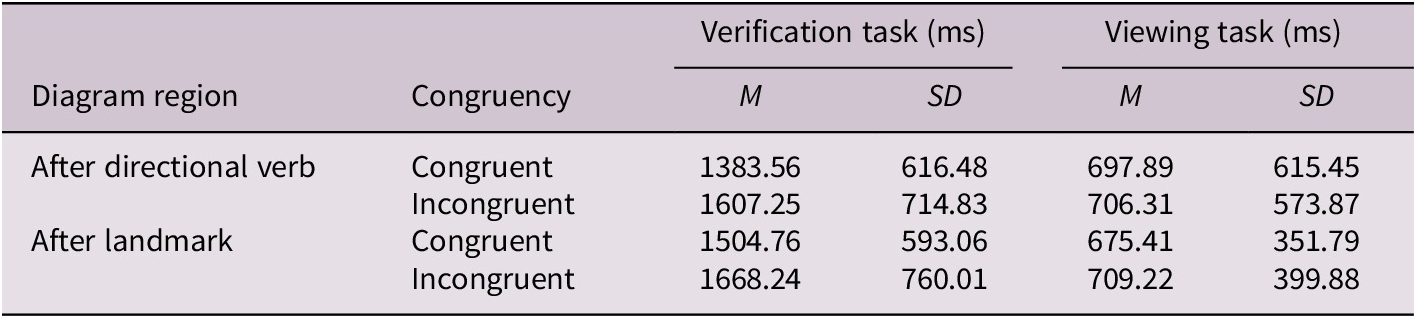
First, descriptive statistical analysis was conducted. Results showed the mean comprehension accuracy was 0.89 (SD = 0.16) in the verification task and 0.92 (SD = 0.12) in the viewing task. The high comprehension ARs across both tasks indicate that participants attended to sentence meaning during the experiment. Descriptive statistical results of RTs by diagram region, congruency and task are reported in Table 3.
Descriptive statistics of response times by diagram region, congruency and task

Table 3. Long description
The table is organized into six columns. The first column is Diagram region, the second is Congruency, followed by two columns for Verification task (M and S D), and two columns for Viewing task (M and S D).
* Row 1: After directional verb, Congruent. Verification task M 1383.56, S D 616.48. Viewing task M 697.89, S D 615.45.
* Row 2: After directional verb, Incongruent. Verification task M 1607.25, S D 714.83. Viewing task M 706.31, S D 573.87.
* Row 3: After landmark, Congruent. Verification task M 1504.76, S D 593.06. Viewing task M 675.41, S D 351.79.
* Row 4: After landmark, Incongruent. Verification task M 1668.24, S D 760.01. Viewing task M 709.22, S D 399.88.
Next, a linear mixed-effects modelFootnote 2 was built to investigate RTs. Results revealed significant fixed effects of task and congruency on RTs, as well as a significant interaction between congruency and task (see Table 4). No significant fixed effect of diagram region was observed; nor did diagram region interact significantly with any other fixed effects.
Linear mixed-effects model results of response times

Table 4. Long description
The table is divided into three main sections: Fixed effects, Random effects, and Model fit.
Fixed effects section columns include beta, S E, 95% C I, t, and p.
* Intercept: beta 7.17, S E 0.06, C I [7.05, 7.29], t 115.27, p less than 0.001.
* Congruency: beta 0.13, S E 0.03, C I [0.08, 0.19], t 4.56, p less than 0.001.
* Diagram region: beta 0.09, S E 0.09, C I [-0.08, 0.25], t 1.01, p 0.312.
* Task: beta -0.84, S E 0.09, C I [-1.014, -0.66], t -9.43, p less than 0.001.
* Congruency times diagram region: beta -0.05, S E 0.04, C I [-0.13, 0.03], t -1.29, p 0.195.
* Congruency times task: beta -0.11, S E 0.04, C I [-0.19, 0.03], t -2.72, p 0.007.
* Diagram region times task: beta -0.02, S E 0.12, C I [-0.26, 0.22], t -0.16, p 0.870.
* Congruency times diagram region times task: beta 0.08, S E 0.06, C I [-0.03, 0.18], t 1.36, p 0.172.
Random effects section columns include Variance, S D, and Correlation.
* Participant (intercept): Variance 0.11, S D 0.35.
* Item (intercept): Variance less than 0.001, S D 0.02.
* Congruency (slope) Participant: Variance 0.01, S D 0.10, Correlation -0.12.
* Congruency (slope) Item: Variance less than 0.001, S D 0.002, Correlation -1.00.
* Residual: Variance 0.10, S D 0.32.
Model fit section for R super 2.
* Marginal: 0.47.
* Conditional: 0.76.
Note: Triple asterisks indicate p less than 0.001, double asterisks indicate 0.001 is less than p which is less than 0.01.
Note: ***p < 0.001, **0.001 < p < 0.01, *0.01 < p < 0.05.
Post-hoc comparisons of the fixed effect of congruency indicated that mean RTs in the congruent condition (EMM = 888, SE = 27.3, df = 133, 95% CI [828, 952]) were estimated to be 68 ms shorter than those in the incongruent condition (EMM = 956, SE = 29.8, df = 132, 95% CI [891, 1026]), with a small congruency effect (t = 5.28, p < 0.001, Cohen’s d = 0.23, SE = 0.04, df = 132, 95% CI [0.15, 0.32]). Post-hoc comparisons of the fixed effect of task showed that mean RTs in the verification task (EMM = 1432, SE = 60.1, df = 134, 95% CI [1302, 1575]) were substantially longer than those in the viewing task (EMM = 593, SE = 25.5, df = 132, 95% CI [538, 653]), with a large effect (t = 14.71, p < 0.001, Cohen’s d = 2.78, SE = 0.19, df = 132, 95% CI [2.40, 3.16]).
To further examine the congruency × task interaction, follow-up analyses were conducted. In the verification task, responses in the congruent condition (EMM = 1357, SE = 58.1, df = 135, 95% CI [1232, 1495]) were estimated to be 155 ms faster than those in the incongruent condition (EMM = 1512, SE = 65.9, df = 135, 95% CI [1370, 1669]), corresponding to a small congruency effect (t = 5.37, p < 0.001, Cohen’s d = 0.34, SE = 0.06, df = 135, 95% CI [0.22, 0.47]). In the viewing task, a smaller congruency effect was observed (t = 2.02, p = 0.046, Cohen’s d = 0.12, SE = 0.06, df = 130, 95% CI [0.002, 0.24]): responses in the congruent condition (EMM = 581, SE = 25.5, df = 132, 95% CI [526, 642]) were estimated to be 23 ms faster than those in the incongruent condition (EMM = 604, SE = 26.8, df = 130, 95% CI [546, 668]). Figure 1 presents the estimated RTs by task, congruency and diagram region.
Estimated response times (ms) for congruent and incongruent diagram conditions across diagram regions in the verification task (left panel) and viewing task (right panel). The x-axis shows the two diagram insertion regions: after the directional verb and after the landmark. Blue symbols and lines represent congruent trials, and red symbols and lines represent incongruent trials. Points indicate model-estimated mean response times, and error bars represent 95% confidence intervals.

Figure 1. Long description
A two-panel line graph. Both panels share a common x-axis labeled Diagram Region with two points: After directional verb and After landmark. The y-axis represents Estimated Response Times in m s. A legend at the bottom indicates blue dots and lines for congruent trials and red dots and lines for incongruent trials.
Left Panel: Verification Task. The y-axis ranges from 1150 to 1750.
* At After directional verb, the congruent mean is approximately 1300 m s and the incongruent mean is approximately 1480 m s.
* At After landmark, the congruent mean increases to approximately 1420 m s and the incongruent mean increases to approximately 1540 m s.
* Vertical error bars indicate 95 percent confidence intervals for each point.
Right Panel: Viewing Task. The y-axis ranges from 450 to 750.
* At After directional verb, the congruent mean is approximately 560 m s and the incongruent mean is approximately 580 m s.
* At After landmark, the congruent mean increases to approximately 600 m s and the incongruent mean increases to approximately 630 m s.
* Vertical error bars indicate 95 percent confidence intervals for each point.
To check whether the congruency effect reflected progressively learned verb-diagram associations over the course of the experiment, an additional linear mixed-effects modelFootnote 3 was fitted. Results showed a significant fixed effect of trial order (β = −0.01, p < 0.001), indicating participants became significantly faster over the course of the tasks. Crucially, the interaction between congruency and trial order was not significant (β = −0.001, p = 0.24), suggesting that the magnitude of the congruency effect remained stable throughout the tasks rather than increasing with repeated exposure.
4. Discussion
The present study examined whether semantic-visual alignment of motion schema during incremental Mandarin sentence processing is modulated by task demands and the informational context in which perceptual probes are encountered. Overall, congruency effects were observed across both tasks and diagram regions, indicating that participants processed the spatial relations conveyed by the sentences in a manner that aligned with the schematic structure represented in the diagrams. Importantly, larger congruency effects were found in the verification task compared to the viewing task, but the congruency effects did not vary regardless of whether the diagram was after the directional verb or the LM noun. These task-sensitive congruency effects provide a behavioural index of how task demands modulate semantic-visual alignment during incremental sentence comprehension.
4.1 Task-sensitive semantic-visual alignment of motion schema
First, we found a significant fixed effect of task, with substantially faster RTs in the viewing task than the verification task. This finding is consistent with the experimental manipulation of different processing demands on the two tasks. In the verification task, RTs reflect not only diagram processing but also the explicit evaluation of the sentence-diagram correspondence, decision formation and response selection. By contrast, participants in the viewing task were required to inspect the diagram. Consequently, the viewing task placed lower immediate cognitive demands on evaluating sentence-diagram correspondence, although the task encouraged participants to maintain attention to both linguistic and visual information throughout the experiment. Therefore, absolute RT differences between tasks should be interpreted as reflecting differences in overall task demands.
The congruency × task interaction provides a more direct index of how specific processing demands modulate the behavioural expression of semantic-visual alignment. Specifically, the larger congruency effect observed in the verification task suggests that requiring participants to explicitly evaluate whether the diagram matched the sentence may strengthen the mapping between linguistic meaning and schematic diagram representations. By contrast, participants in the viewing task could inspect the diagram without being required to explicitly compare it with the preceding sentence, reducing the need for detailed evaluation of the sentence-diagram correspondence. Consequently, a substantially weaker congruency effect was observed in the viewing task, suggesting a modest sensitivity to congruent directional information in sentence-diagram pairings.
Notably, the use of schematic diagrams may have contributed to the stronger congruency effects observed in the verification task by providing a structured basis for mapping linguistic meaning onto visual spatial relations. In the present stimuli, circles represented TRs, boxes represented LMs and arrows encoded motion direction, enabling participants to rapidly align sentence meaning with an abstract spatial event structure. Such alignment may function as an external representational scaffold that facilitates the construction of a coherent situation model (Hu & Zhao, Reference Hu and Zhao2026), particularly when participants are required to verify semantic congruency. In contrast, the viewing task imposed no requirement to establish this mapping, allowing diagrams to be processed more superficially and reducing the behavioural expression of semantic-visual alignment between sentence meaning and spatial structure.
The present findings can further be interpreted from multiple accounts. From the perspective of embodied accounts, the stronger congruency effects observed in the verification task are consistent with the view that language comprehension may involve the partial reactivation of modality-specific sensorimotor traces associated with prior perceptual experience (Barsalou, Reference Barsalou1999, Reference Barsalou2008). Under this interpretation, such traces are not assumed to be obligatorily recruited during comprehension but may be engaged to a greater extent when explicit sentence-diagram verification makes perceptual information task-relevant, while remaining relatively weakly activated under conditions that permit shallower processing (Ostarek et al., Reference Ostarek, Joosen, Ishag, De Nijs and Huettig2019). This interpretation is broadly consistent with previous behavioural studies reporting stronger congruency effects when perceptual or motor information is directly enhanced by task requirements (Bub & Masson, Reference Bub and Masson2006; Chen et al., Reference Chen, de Koning and Zwaan2020; Rommers et al., Reference Rommers, Meyer and Huettig2013; Tomasino et al., Reference Tomasino, Werner, Weiss and Fink2007).
An alternative interpretation is provided by amodal accounts of semantic processing. From this perspective, the stronger congruency effects in the verification task may reflect enhanced semantic comparison between linguistic and visual information, without requiring the recruitment of modality-specific sensorimotor representations (Mahon & Caramazza, Reference Mahon and Caramazza2008; Meteyard et al., Reference Meteyard, Cuadrado, Bahrami and Vigliocco2012; Ostarek et al., Reference Ostarek, Joosen, Ishag, De Nijs and Huettig2019). Explicit verification encourages participants to evaluate the correspondence between sentence meaning and diagrammatic spatial relations, thereby increasing the behavioural expression of semantic-visual alignment.
The present behavioural findings do not allow these interpretations to be distinguished or establish the causal cognitive mechanisms underlying the semantic-visual alignment (Horchak & Garrido, Reference Horchak and Garrido2020; Ostarek et al., Reference Ostarek, Joosen, Ishag, De Nijs and Huettig2019). Rather, they demonstrate that the behavioural expression of such alignment is sensitive to task demands. Future research combining congruency paradigms with more diagnostic approaches such as interference or neurophysiological measures (Horchak & Garrido, Reference Horchak and Garrido2022; Szűcs & Soltész, Reference Szűcs and Soltész2008; Yao & Vanduffel, Reference Yao and Vanduffel2022), will be necessary to determine the representational format and causal mechanisms underlying these task-sensitive congruency effects.
4.2 Congruency effects across incremental sentence regions
A second key finding of the present study is that congruency effects did not differ as a function of diagram region. Specifically, presenting the diagram immediately after the directional verb or after the LM noun yielded comparable congruency effects, and no significant interaction between congruency and diagram region was observed. One interpretation is that Mandarin directional verbs such as jìn (‘into’) and chū (‘out of’) provide sufficiently strong schematic constraints to establish a basic motion representation early in comprehension. Once the directional verb is encountered, comprehenders may already have sufficient information for the level of diagram-sentence alignment measured in the present task, with the LM noun primarily contributing to referential specification rather than altering the core spatial relation.
At the same time, this null interaction should be interpreted cautiously. The present data do not show that processing was identical across the two probe positions; rather, they indicate that the behavioural congruency effect remained stable across the specific within-sentence regions tested here. This contrasts with earlier studies reporting stronger congruency effects at later probe positions (Nishide et al., Reference Nishide, Zhao and De Deyne2025; Sato et al., Reference Sato, Schafer and Bergen2013). One plausible explanation concerns the informational structure of the linguistic input. In those studies, earlier sentence regions provided only partial constraints on the intended interpretation, so additional linguistic material was needed before a stable event representation could be established. By contrast, in the present Mandarin materials, the directional verb may already have supplied the critical schematic information needed to establish a motion representation at an early stage. Because the schematic diagrams transparently encoded the relevant spatial relation, this early representation could be readily aligned with the visual stimulus.
A related methodological consideration is that later congruency effects in some studies may partly reflect wrap-up processes (Hu & Zhao, Reference Hu and Zhao2026; Nishide et al., Reference Nishide, Zhao and De Deyne2025; Sato et al., Reference Sato, Schafer and Bergen2013). That is, integrative processing becomes stronger when comprehenders reach a clause or sentence boundary and consolidate preceding information. In the present design, however, both probe positions occurred within the sentence rather than at sentence-final wrap-up points, which makes a wrap-up-based explanation less likely as the primary source of the observed pattern.
More broadly, the present findings suggest that congruency effects do not necessarily increase across sentence regions during incremental comprehension. Their temporal profile may depend on how strongly early linguistic cues constrain the relevant representation and on how much later information is needed for revision or disambiguation. On this view, increasing congruency effects are more likely when early interpretations remain underspecified, whereas stable effects may arise when key schematic information is available early.
4.3 Limitations and future directions
The present study provides novel evidence regarding the conditions under which congruency effects emerge during incremental sentence comprehension, but several limitations should be acknowledged when interpreting these findings and considering future research. First, although the present study employed only two highly frequent Mandarin directional verbs and two corresponding motion schemas, the trial-order analysis indicated that the congruency effect remained stable across the experiment rather than increasing with repeated exposure, arguing against an explanation based primarily on progressively learned verb-diagram mappings. Nevertheless, future studies should include a broader range of directional verbs, motion schemas and probe locations to further minimise the possibility of strategic mapping and to determine when congruency effects strengthen over time and when they remain stable.
Another methodological consideration concerns the between-participant manipulation of both task and diagram region. This design was adopted to minimise the salience of the experimental manipulations and reduce the likelihood that participants would develop strategic expectations regarding task requirements or the timing of diagram presentation. Nevertheless, manipulating both factors within participants in future research may increase statistical power and provide a more sensitive test of how task demands and informational context jointly modulate semantic-visual alignment. To minimise potential carry-over or strategy effects associated with repeated exposure to different task conditions and diagram positions, future studies could incorporate additional filler items or counterbalancing procedures to reduce the salience of the experimental manipulations while retaining the advantages of a within-participant design.
5. Conclusion
The present study examined how task demands and informational context shape the behavioural detectability of semantic-visual alignment of motion schema during incremental processing of Mandarin motion sentences. Three main conclusions emerge.
First, congruency effects were observed across both tasks, indicating that comprehenders systematically aligned sentence meaning with the motion relations encoded in the diagrams. At the same time, these effects were stronger in the verification task than in the viewing task, showing that congruency effects are not a fixed consequence of sentence comprehension but are modulated by task demands. This finding is consistent with a goal-adaptive account, whereby semantic-visual alignment becomes more behaviourally salient when explicit sentence-diagram mapping is encouraged.
Second, congruency effects remained stable across the two within-sentence probe locations tested in the present design. This pattern suggests that congruency effects do not necessarily strengthen as linguistic input unfolds. Rather, their temporal profile may depend on the informativeness of early linguistic cues and the extent to which subsequent input requires the developing interpretation to be refined.
Third, the study contributes methodologically by demonstrating the value of combining task manipulation with incremental visual probing while holding the linguistic and visual materials constant. By contrasting verification and viewing and by probing semantic-visual alignment at two theoretically motivated regions, the present design offers a more controlled basis for interpreting congruency effects than comparisons across paradigms that differ in response modes or rely solely on sentence-final probes.
Taken together, these findings contribute to a more nuanced understanding of congruency effects during language comprehension. Rather than treating congruency effects as a uniform index of a particular representational mechanism, the present study demonstrates that their behavioural expression is shaped by task demands and linguistic informativeness. Although the present findings can be interpreted from an embodied perspective, they are also compatible with the alternative account of amodal semantic comparison. Future research employing more diagnostic methodologies will be important for distinguishing between these interpretations and clarifying the mechanisms underlying semantic-visual alignment during incremental sentence comprehension.
Data availability statement
Data and supplementary materials are accessible from https://osf.io/5hbjy/
Acknowledgements
We would like to express our gratitude to the editors and anonymous reviewers for their valuable comments and constructive suggestions.
Funding statement
The work is supported by the Fundamental Research Funds for the Central Universities in UIBE (grant number 26QD25).
Ethics statement
The study involving humans was approved by the Office of Research Ethics and Integrity of the University of Melbourne. All participants provided their written informed consent to participate in this study.



 Open access

