




No CrossRef data available.
Article contents
- Abstract
- 1. INTRODUCTION
- 2. IDENTIFICATION OF βα AND qα
- 3. DESCRIPTION OF THE AVERAGE QUANTILE REGRESSION ESTIMATOR
- 4. ASYMPTOTIC PROPERTIES OF THE AVERAGE QUANTILE REGRESSION ESTIMATOR
- 5. THE SEMIPARAMETRIC EFFICIENCY BOUND
- 6. EFFICIENT ESTIMATION OF βα
- 7. MONTE CARLO EXPERIMENTS
- 8. CONCLUSIONS
- APPENDIX
- References
EFFICIENT SEMIPARAMETRIC ESTIMATION OF A PARTIALLY LINEAR QUANTILE REGRESSION MODEL
Published online by Cambridge University Press: 08 January 2003
Article contents
- Abstract
- 1. INTRODUCTION
- 2. IDENTIFICATION OF βα AND qα
- 3. DESCRIPTION OF THE AVERAGE QUANTILE REGRESSION ESTIMATOR
- 4. ASYMPTOTIC PROPERTIES OF THE AVERAGE QUANTILE REGRESSION ESTIMATOR
- 5. THE SEMIPARAMETRIC EFFICIENCY BOUND
- 6. EFFICIENT ESTIMATION OF βα
- 7. MONTE CARLO EXPERIMENTS
- 8. CONCLUSIONS
- APPENDIX
- References
Abstract
This paper is concerned with estimating a conditional quantile function that is assumed to be partially linear. The paper develops a simple estimator of the parametric component of the conditional quantile. The semiparametric efficiency bound for the parametric component is derived, and two types of efficient estimators are considered. Asymptotic properties of the proposed estimators are established under regularity conditions. Some Monte Carlo experiments indicate that the proposed estimators perform well in small samples.This paper is a part of my Ph.D. dissertation submitted to the University of Iowa. I am grateful to my adviser, Joel Horowitz, for his insightful comments, suggestions, guidance, and support. I also thank John Geweke, Gene Savin, two anonymous referees, the co-editor Oliver Linton, and participants at the 2001 Midwest Econometrics Group Annual Meeting in Kansas City for many helpful comments and suggestions. Of course, the responsibility for any errors is mine.
Information
- Type
- Research Article
- Information
- Copyright
- © 2003 Cambridge University Press
1. INTRODUCTION
Many econometrics problems are concerned with estimating a conditional location function such as conditional mean, conditional median, or conditional quantile. Since the seminal work of Koenker and Bassett (1978), there have been many theoretical and applied papers that are related to the estimation of conditional quantiles, including the conditional median as a special case. Most of these papers are based on a priori assumptions about the functional form of the conditional quantile function. The estimation results can be misleading, however, if the model is misspecified. On the other hand, a fully nonparametric method such as the local polynomial estimator in Chaudhuri (1991a, 1991b) could reduce the possibility of misspecification, whereas the curse of dimensionality occurs as the dimension of independent variables increases. Semiparametric methods that can obtain dimension reduction, therefore, are useful because they can avoid the loss of precision due to the curse of dimensionality and they make weaker assumptions about the functional form of the regression model.
In particular, this paper develops an estimation method for a partially linear quantile regression model. The model has the form

where Y is a scalar dependent variable, X is a dx × 1 vector of continuous random variables, Z is a dz × 1 vector of continuous or discrete random variables, qα(·) is an unknown real-valued function, βα is a dz × 1 vector of unknown parameters, and Uα is an unobserved random variable that satisfies Prob(Uα ≤ 0|X = x,Z = z) = α for all x and z, where α indexes the quantile of interest. If α = 0.5, the model reduces to a partially linear median regression model.
There is a growing literature on estimating semi- and nonparametric quantile regression models.1
For semi- and nonparametric mean regression models, see Härdle (1990) and Horowitz (1998b) among many others.
The main purpose of this paper is to develop an asymptotically efficient estimator of βα.2
See Newey and Powell (1990) and Zhao (2001) for asymptotically efficient estimation of linear quantile regression models.
The rest of the paper is organized as follows. Section 2 gives sufficient conditions under which βα and qα are identified. Section 3 describes the AQR estimator of βα. In Section 4, asymptotic properties of the AQR estimator are given under a certain set of regularity conditions. In Section 5, the semiparametric efficiency bound for βα is derived. In Section 6, it is shown that the bound is attainable by constructing efficient estimators of βα. Section 7 presents some Monte Carlo experiments that illustrate the finite sample performance of the proposed estimators. Concluding remarks are given in Section 8. The proofs of theorems are in the Appendix.
2. IDENTIFICATION OF βα AND qα
Before we consider estimation of βα and qα in (1), we have to find conditions under which the partially linear quantile regression model can be identified. The model is identified if βα and qα are uniquely determined by the population distribution of (Y,X,Z). The following result gives sufficient conditions for the identification of the model.
THEOREM 1. Suppose that Prob(Y ≤ qα(X) + Z′βα|X = x,Z = z) = α for all x and z. If
(1) the conditional density of Uα is positive at zero for all x and z, and
(2) var(Z|X = x) is nonsingular at every x,
then qα and βα are identified.
The sufficient conditions can be relaxed but are stated in the form used to derive asymptotic properties of the proposed estimators. Condition (1) is standard but can be relaxed. For example, Knight (1998) derives the asymptotic distributions for linear median regression estimators under a more general assumption than condition (1). See also Smirnov (1952) for limiting distributions of sample quantiles under general assumptions. Condition (2) excludes a constant variable for Z. Furthermore, it requires that no components of Z be perfectly predictable by components of X. A similar but less stringent exclusion restriction is also needed for partially linear mean regression. For example, it is assumed in Robinson (1988) that E [var(Z|X)] is positive definite. See Robinson (1988) for detailed discussion. It is assumed throughout the remainder of this paper that βα and qα are identified.
3. DESCRIPTION OF THE AVERAGE QUANTILE REGRESSION ESTIMATOR
This section presents the main idea behind the estimation method and describes the AQR estimator of βα. The estimation procedure involves two stages: in the first stage, βα is estimated locally at each data point; in the second stage, these local estimates are averaged to obtain an n−1/2-consistent estimator of βα.
To describe the estimation procedure, we need some notation. Let {(Yi,Xi,Zi);1 ≤ i ≤ n} be a random sample of (Y,X,Z) in (1) with size n. Let Cn(Xi) be a cube in Rdx centered at Xi with side length 2δn, where δn is a sequence of positive real numbers such that δn → 0. For u = (u1,…,udx), a dx-dimensional vector of nonnegative integers, let [u] = u1 + ··· + udx. Let Ak be the set of all dx-dimensional vectors u such that [u] ≤ k for some integer k ≥ 0 and let s(Ak) denote the number of elements in Ak. For z ∈ Rdx with u ∈ Ak, let zu =

. In addition, given X1,X2 ∈ Rdx, define

where c = (cu)u∈Ak is a vector of dimension s(Ak). Define ρα(t) = |t| + (2α − 1)t. For each Xi, the first-stage estimator

of βα is defined by

is the solution to the following minimization problem:

where 1(·) is a standard indicator function. Notice that the preliminary estimator defined here is a leave-one-out estimator and a multivariate uniform kernel is used in (2).
It is important to note that only local data points around Xi are used in (2). As a consequence,

converges in probability to βα at a nonparametric rate. A more efficient estimator for βα requires the use of all data points. Because
can be obtained at each data point Xi, the proposed estimation strategy in this paper is to average all

to estimate βα. This averaging method ensures that all data points are used and thus leads to a faster rate of convergence.
In the second stage, the AQR estimator

is now obtained by

where τx(x) is a trimming function such that

with a compact subset

of Rdx. The trimming function is introduced to estimate the parameters βα without being overly influenced by the tail behavior of the distribution of X. It will turn out in Section 4 that this AQR estimator is n−1/2-consistent for βα and asymptotically normal.
The first-stage estimation procedure is a simplified version of the local polynomial estimation procedure developed in Chaudhuri (1991a, 1991b) and Chaudhuri et al. (1997). The estimation method considered here is different from that used in Chaudhuri (1991a, 1991b) and Chaudhuri et al. (1997) in that only a linear term with respect to Z is adopted, no cross products between X and Z are included in (2), and local weighting is carried out in terms of only X, not both X and Z, because the partially linear form of the regression model is assumed in this paper. A similar type of preliminary estimation procedure is also considered in Chen and Khan (2001). The main advantage of using this method is that the Bahadur-type expansion of the estimator is already well established and can be easily specialized for the purpose of this paper.
We conclude this section by mentioning the numerical algorithm of (2). Because the uniform kernel is independent of c and b, the problem (2) can be easily shown to have a linear programming representation. From the perspective of linear quantile regression, problem (2) can be understood as just weighted quantile regression with weight equal to the uniform kernel. All computational algorithms developed for linear quantile regression, therefore, can be used to solve problem (2) (see, e.g., Buchinsky, 1998, and references therein).
4. ASYMPTOTIC PROPERTIES OF THE AVERAGE QUANTILE REGRESSION ESTIMATOR
This section gives regularity conditions under which the AQR estimator of βα is n−1/2-consistent and asymptotically normal. Let ∥·∥ denote the Euclidean norm.
Assumption 1. {(Yi,Xi,Zi);1 ≤ i ≤ n} is a random sample of (Y,X,Z) in (1).
Let Fα(·|x,z) and fα(·|x,z), respectively, denote the cumulative distribution function and the density function of Uα conditional on (X,Z) = (x,z). Moreover, let g(x) denote the density function of X and let gxz(x,z) denote the joint density of X and Z with respect to an appropriate measure. Suppose that Z can be divided into Z = (Z(c),Z(d)), where Z(c) denote the continuous components of Z and Z(d) denote the remaining discrete components. Assume that Z(d) has finitely many mass points. Let

be supports of X and Z = (Z(c),Z(d)) such that

are nonempty convex sets in Rdx and Rdzc.
Assumption 2.
(a) Fα(0|x,z) = α for all (x,z) in

(b) fα(u|x,z) is bounded away from zero and continuously differentiable with respect to u in a neighborhood of zero for all (x,z) in
, and
(c) g is positive on

except on the boundary.
Following the nonparametric estimation literature, a function m: Rd → R will be said to have the order of smoothness p on a convex set

in Rd with p = l + γ, where l ≥ 0 is an integer and 0 < γ ≤ 1, and will be written as

, if (i) partial derivatives

exist and are continuous for all

and [u] ≤ l and (ii) there exists a constant M > 0 such that

In other words, a function m is l-times continuously differentiable and the lth derivative is Hölder continuous with exponent γ. The order of smoothness, if it applies to a vector or matrix-valued function, will be understood componentwise.
Assumption 3. The function qα(·) has the order of smoothness

.
Assumption 4. There exists a γ, 0 < γ ≤ 1 such that

Assumption 5. The distribution of Z has bounded support.
Assumption 6. δn ∝ n−κ, where κ is a positive real number satisfying 1/(2pq) < κ < 1/(3dx).
Assumption 7. The trimming function τx(x) has compact support

, where

has a nonempty interior and

.
Assumption 8. For all

, the matrix Σ(x) is nonsingular, where

Moreover, Σ(x), considered as a function of x, is in

) with some γ, 0 < γ ≤ 1.
3The exponents γ in Assumption 4(a) and (b) and Assumption 8 do not have to be same. For brevity, we assume that γ denotes the minimum of the three γ's.
It is necessary to make some comments regarding regularity conditions. Condition (a) of Assumption 2 imposes the conditional quantile restriction, and condition (b) is important for identification. Condition (c) ensures that there will be sufficiently many Xj's near Xi asymptotically as n → ∞. This condition with Assumption 4(b) guarantees that the marginal density of X is bounded away from zero and infinity on

. As done in Chen and Khan (2001), it is possible to include discrete random variables for X. This, however, is not explicitly done here for the sake of simplicity.
Assumption 3 requires that the order of smoothness pq of qα grow as the dimension of X increases.4
This is common among semiparametric regression estimators. Higher order kernels are often used when the first-stage estimation is based on kernel-type estimators. Assumption 3 is not needed to derive the efficiency bound in Section 5, however.
In particular, Assumption 5 is made to exploit Bernstein's inequality. This assumption can be satisfied by dropping observations with very large values of Z, if necessary.
Assumption 6 restricts the range of the bandwidth.
6Assumption 6 allows for only deterministic bandwidth sequences. It is necessary to use data-based bandwidths in applications; however, it is beyond the scope of this paper to investigate the asymptotic properties of the estimator with data-dependent bandwidth sequences. In simple cases such as nonparametric density and regression estimation, the usual kinds of data-based bandwidth selection do not affect the first-order asymptotics of the estimators (see, e.g., Andrews, 1995).
that is too small can induce the loss of efficiency, whereas a
that is too large allows the estimator to be unduly influenced by the tail behavior of g(x).
Finally, Assumption 8 ensures that the variance of the asymptotic distribution of the estimator is well defined.7
The condition that Σ(x) is nonsingular at every x is stronger than needed to estimate βα. For example, βα can be identified and estimated only using observations for which Σ(x) is nonsingular as long as Prob{Σ(x) is nonsingular} is positive. Assumption 8 is adopted here to minimize the complexity of the proof.
The next theorem establishes the n−1/2-consistency and asymptotic normality of the AQR estimator of βα. Let ez′ be the dz × (dz + 1) matrix such that ez′ = (0,Idz), where 0 denotes the dz-dimensional zero vector and Idz an identity matrix.
THEOREM 2. Suppose that the order of the polynomial in (2) is k = [pq]. Let

denote the AQR estimator of βα. Let Assumptions 1–8 hold. Then as n → ∞,

Although the n−1/2-consistency and asymptotic normality of the AQR estimator are established, the variance V in Theorem 2 is somewhat complicated. It will be shown in Section 5 that in general this variance is different from the efficient variance bound. The variance V in Theorem 2 can be simplified under a stronger condition than in Assumption 2. The following corollary restates Theorem 2 under the assumption of homoskedasticity.
COROLLARY 3. Assume that the conditions in Theorem 2 hold. Furthermore, suppose that the conditional density of Uα given x and z, evaluated at zero, is independent of (x,z), namely, fα(0|x,z) = fα(0) for all (x,z) in

. Then as n → ∞,

The AQR estimator may be compared with other existing estimators in the literature. He and Shi (1996) consider M-type regression splines using bivariate tensor-product B-splines. They establish the asymptotic results under the assumption that Uα is independent of (X,Z). He and Liang (2000) develop estimators for linear and partially linear errors-in-varables models. Their asymptotic results are established under a stringent assumption that E(Z|X = x) = 0 for all x. Chen and Khan (2001) propose an estimation method for a partially linear censored quantile regression. Their estimator uses a two-stage estimation procedure. In the first stage, the conditional quantile function is nonparametrically estimated by the local polynomial method, which is also the case for the AQR estimator. In the second stage, they estimate βα by a least-squares-type estimator using differenced values of the estimated conditional quantiles as dependent variables. The implementation of their estimator requires a kind of tuning parameter that they call a “selection function.” None of the existing estimators in the literature are asymptotically efficient under the conditional heteroskedasticity of Uα. An asymptotically efficient estimator will be constructed in Section 6.
We end this section by considering estimation of the nonparametric component qα(·) of the model (1). Because the parametric component βα can be estimated with an n−1/2 rate, which is faster than the fastest possible rate of convergence for the nonparametric component, it is possible to estimate qα(·) as asymptotically efficiently as if βα were known. The function qα(·) can be estimated by carrying out a local polynomial quantile regression of

on X. See Fan and Gijbels (1996, p. 202) and Yu and Jones (1998) for rule-of-thumb bandwidths.
5. THE SEMIPARAMETRIC EFFICIENCY BOUND
In this section, the semiparametric efficiency bound for βα will be derived by adopting the method used in Newey and Powell (1993). The semiparametric efficiency bound may be viewed as the supremum of the Cramér-Rao-type bounds for regular parametric submodels. This bound can be calculated rigorously by a projection formula. More specifically, the efficiency bound VB for βα is the inverse of the expectation of the outer product of the efficient score for βα, namely, VB = {E [Sα Sα′]}−1, where the efficient score Sα is defined by the projection of the score function for βα onto the orthogonal complement of the tangent space in the nonparametric direction. See, for example, Newey (1990) and Bickel, Klaassen, Ritov, and Wellner (1993) for further discussion.
We consider the following parametric submodel for the nonparametric component qα(·) of the regression function:

where h is an arbitrary function of X that satisfies E∥h∥2 < ∞. As in Newey and Powell (1993), this paper does not attempt to specify an explicit parametric submodel for the distribution of (Uα,X,Z). Instead, we use the existing results of Newey and Powell (1990) to derive the efficient scores (Sβα,Sη) for (βα′,η′)′. Then the efficient score Sα for βα will be calculated by finding the projection of Sβα onto the orthogonal complement of the tangent space for η.
To begin, it is important to notice that the parametric submodel can be written as a linear quantile regression model with parameters (βα′,η′)′. It then follows from Newey and Powell (1990) that the efficient scores for βα and η have the form

By Proposition A.3.5 of Bickel et al. (1993, p. 433), the projection of Sβα onto the tangent space for η can be calculated by

Thus, the efficient score for βα is

This yields the efficiency bound VB

provided that E [Sα Sα′] is nonsingular. This result implies that the AQR estimator is not efficient in general. If the distribution of Uα is homoskedastic and X and Z are jointly normal, then the variance of the AQR estimator is the same as the efficiency bound, ignoring the effect of trimming. This does not necessarily mean that the AQR estimator is efficient in that special case because imposition of the additional restriction could change the efficiency bound.
6. EFFICIENT ESTIMATION OF βα
This section constructs efficient estimators of βα. When Uα is homoskedastic with respect to Z, more precisely if fα(0|x,z) is independent of z, an optimally weighted AQR estimator will deliver asymptotic efficiency; if Uα permits general heteroskedasticity, then a one-step estimator will be constructed.
6.1. Homoskedastic Uα
In this section, we will show that the efficiency bound can be attained by considering a weighted version of the AQR estimator. Because the AQR estimator is just a simple average of the nonparametric estimators, it is plausible to conjecture that a weighted average can improve asymptotic efficiency. Indeed, an efficient estimator of βα can be obtained by choosing a proper weighting function when Uα is homoskedastic. To show this, let w(x) be a dz × dz matrix-valued, weighting function such that E [τx(X)w(X)] is nonsingular and w(x) is in
for some γ, 0 < γ ≤ 1. A weighted AQR estimator
can be defined as

It is straightforward to show that when fα(0|x,z) = fα(0) for all x and z,

Clearly the optimal choice of the weight function is to set w(x) = var(Z|X = x). In practical applications, it is likely that var(Z|X = x) is unknown; however, it can be replaced by its uniformly consistent estimator. For instance, we can use the following weighting function:

where

denotes a kernel estimator of the corresponding expectation. Let

denote the weighted AQR estimator with weight function

. In the following theorems, |·| and op(1) will be understood componentwise.
THEOREM 4. Assume that the conditions in Corollary 3 hold. Moreover, suppose that

Sufficient conditions for uniform consistency of

on a compact set can be easily obtained using the results of the literature, for example, Bierens (1983, 1987) and Andrews (1995). It is easy to see that when fα(0|x,z) = fα(0) for all (x,z), the variance

is the same as the efficiency bound except for the existence of the trimming function. The estimator constructed in this paper is not efficient in a strict sense because it does not use all observations. It is expected that the loss of efficiency due to the existence of the trimming function could be eliminated by letting the support of τx grow very slowly as the sample size increases. For example, Robinson (1988) considers the trimming function

(in his notation), where

is a kernel estimator of the probability density function of Xi and b is a positive constant. The effect of trimming is eliminated in Robinson (1988) by letting b converge to zero very slowly. In addition, Klein and Spady (1993) use elaborate trimming procedures to obtain an efficient semiparametric estimator for binary response models. Details are not worked out here, however.
If Uα permits restricted heteroskedasticity, in other words, Uα is homoskedastic with respect to Z, it is also possible to construct an efficient estimator via optimal weighting. More specifically, if fα(0|x,z) = fα(0|x) for all z, then the asymptotic variance

for the weighted AQR estimator

has the following form:

This reveals that the optimal weighting function is w(x) = fα2(0|x)var(Z|X = x). The efficiency bound, therefore, can be attained by using a consistent estimator of fα2(0|x)var(Z|X = x) as the weighting function. The conditional density fα(0|x) can be consistently estimated using estimated Uα's. On the other hand, if Uα permits general heteroskedasticity, then no weighted AQR estimator can deliver asymptotic efficiency. In the next section, an efficient estimator will be obtained by the one-step method.
6.2. Heteroskedastic Uα
In this section, a one-step asymptotically efficient estimator of βα is constructed by taking one step from the AQR estimator of βα.
8In fact, any n−1/2-consistent estimator of βα can be used as an initial estimator.
denote the AQR estimator defined in Section 3.
If Sα were known except for βα, a one-step asymptotically efficient estimator

would be obtained by

Of course, this estimator is not feasible because Sα contains unknown population quantities such as qα(X),fα(0|X,Z), and T(X). Moreover, as pointed out by Newey and Powell (1990), the score function is not continuous in parameters βα. As a result of this discontinuity, Newey and Powell (1990) make use of a sample splitting method for the efficient estimation of a (censored) linear quantile regression model. The sample splitting method adopted in Newey and Powell (1990) consists of using each half of the observations to estimate the efficient score for the other half. As a result, the ordering of the data may matter for the estimation of βα.
Instead of using the technique of Newey and Powell (1990), this paper smooths the score function. Differentiability of the score function enables us to use standard Taylor series methods to obtain the asymptotic properties of the one-step estimator. The smoothing method requires the introduction of an additional tuning parameter, but we feel that this is acceptable because it is very hard to find any reasonable rule to choose the ordering of the data in practical applications. In addition, it will be shown in Section 7 that the simulation results are somewhat insensitive to the choice of the tuning parameter.9
Another alternative could be to invoke stochastic equicontinuity arguments in Andrews (1994). Unlike the mean regression case,

is a step function and therefore is not smooth enough to apply the existing results in the literature.
Horowitz (1998a) uses a smoothed least-absolute-deviations estimator for a linear median-regression model to obtain asymptotic refinements of bootstrap tests. Following his idea, we replace the indicator function in Sα with a smooth function. Specifically, let J be a bounded, differentiable function satisfying J(t) = 0 if t ≤ −1 and J(t) = 1 if t ≥ 1. The function J can be regarded as the integral of a kernel function. Let {jn} be a sequence of positive real numbers that converges to zero. In addition, let

, where

are some compact subsets of Rdx and Rdzc, respectively. The trimming function τ(x,z) is introduced for the same reason as before. For a given b, a smoothed feasible score function

is then defined as

where

, denote consistent estimators of qα(x),fα(0|x,z), and T(x), respectively. Notice that 1 − J(·/jn) can be arbitrarily close to 1(· ≤ 0) for sufficiently large n. An actual one-step estimator proposed here is

To complete the description of the one-step efficient estimator, we need to specify the nonparametric estimators of qα(Xi),fα(0|Xi,Zi), and T(Xi). First of all, qα(Xi) can be estimated by the first element of

of (2). For fα(0|x,z), a standard kernel density estimator may be used. Observe that fα(0|x,z) can be written as fα(0|x,z) = f1(0,x,z)/f2(x,z), where f1 and f2 are joint densities of (Uα,X,Z) and (X,Z), respectively. This suggests that the conditional density of Uα at zero can be estimated consistently by obtaining the ratio of the kernel estimator of f1 to the kernel estimator of f2. More specifically, the kernel estimator

is defined as

where

kernel function with a bandwidth ν1n, and Kxz is a (dx + dz)-dimensional kernel function with a bandwidth ν2n. Finally, T(Xi) can be estimated by

where Kx is a dx-dimensional kernel function with a bandwidth γn.
The following additional regularity conditions are useful to derive the asymptotic properties of the one-step estimator of βα.
Assumption 9. The trimming function τ(x,z) has compact support

.
Assumption 10. The conditional density fα(u|x,z) is continuously twice differentiable with respect to u in a neighborhood of zero for all (x,z) in
.
Assumption 11. Let J(i)(v) = diJ(v)/dvi.
(a) J(·) is bounded, J(v) = 0 if v ≤ −1, and J(v) = 1 if v ≥ 1.
(b) J is twice differentiable, J(1)(v) is symmetrical about v = 0, J(2) is Lipschitz continuous, and J(i)(v) is bounded for i = 1,2.
(c)

Assumption 12. jn ∝ n−η, where η is a positive real number satisfying ¼ < η < 5/18.
Assumption 13.

Assumptions 10–12 are necessary to make smoothing have no effect on the asymptotic distribution of the one-step estimator. Just like the assumption for
in Theorem 4, Assumption 13 is a high-level assumption that requires that kernel estimators be uniformly consistent on the compact sets. It is easy to obtain sufficient conditions for Assumption 13 using the results of Bierens (1983, 1987) and Andrews (1995). The main result of this paper is as follows.
THEOREM 5. Let
denote the one-step estimator defined in (3). Let Assumptions 1–13 hold. Then as n → ∞ (assuming that V* is well defined),

The variance of Theorem 5 is the same as the efficiency bound except for the effect of the trimming function τ. Just like the case of homoskedastic Uα, the effect of the trimming function is likely to be eliminated by letting the support of τ grow.
For statistical inference, it is necessary to obtain a consistent estimator of the variance V*. There may be several ways to estimate this variance matrix, but a simple consistent estimator of V* that is a by-product of the estimation procedure is

It is shown in the proof of Theorem 5 in the Appendix that

converges to V* in probability. An alternative way to estimate V* is to replace the components of V* with its empirical counterparts. A consistent estimator can be given by

where

denote consistent nonparametric estimators of fα(0|x,z) and E [·|x] .
Adopting the same idea, one can obtain a consistent estimator of the asymptotic variance V of the AQR estimator. Specifically, the consistent estimator

has the form

and

is a nonparametric estimator of Σ(x) using the estimated fα(0|X,Z). It is also straightforward to obtain consistent estimators of the variances of the AQR estimator and the weighted AQR estimator when Uα is homoskedastic.
7. MONTE CARLO EXPERIMENTS
This section presents the results of a Monte Carlo investigation of the finite sample performance of the proposed estimators in the previous sections. In all experiments α = 0.5 and n = 100. Following Robinson (1988) and Chen and Khan (2001), we considered the following model:

where Xi and Zi were drawn from a bivariate standard normal distribution with correlation 0.5 and εi was drawn from the standard normal distribution that is independent of X and Z. Three different functions for q and two different functions for σ were simulated:

where C is a constant that was chosen to make σ(Xi,Zi) have standard deviation 1/3. The function q2, which is taken from Härdle (1990, p. 122), has a bell-shaped hump around zero. The parameter β was set to be 1. The trimming function used in the experiments was τx(x) = 1(|x| ≤ 2).10
If the number of observations that satisfy |Xj − Xi| < δn in (2) is less than 5, which is the number of regressors in the local cubic fitting, then the estimation procedure will break down. Hence, those points were additionally excluded in the experiments.
Computing the AQR estimates requires choosing the order of polynomial k and the bandwidth δn in (2). In the experiments k = 3. The asymptotic results of Section 3 only provide the range of δn in terms of the asymptotic order. A higher order asymptotic theory is required to obtain an asymptotically optimal δn. However, there is a simple, informal selection rule based on the rule-of-thumb bandwidth for the estimation of the nonparametric component qα. Let

be the rule-of-thumb bandwidth for the estimation of q when k = 3, suggested by Fan and Gijbels (1996, p. 202). Specifically,
is of the form

where w0(·) is a weight function,

is obtained from a global polynomial fit,

is a kernel density estimate of the residuals of the global polynomial fit, and

is the αth sample quantile of the residuals. Also,

denotes the fourth derivative of

. The weight function was set to be w0(x) = 1(|x| ≤ 2). The global polynomial fit was obtained by carrying out the median regression of Y on the constant term, X,X2,…,X5, and Z. The bandwidth
converges at rate n−1/9, which is optimal for the estimation of q. Undersmoothing is required for the estimation of β. A simple bandwidth such as

converges at rate n−1/5 and satisfies Assumption 6 when pq ≥ 3. By some preliminary simulations, the averages of ad hoc bandwidths

ranged between 0.7 and 1.1 across the designs considered in the experiments. In the experiments, δn ∈ {0.5, 0.6,…,1.5}, which includes the range of the averages of

. There were 1,000 replications in each experiment. The computations were carried out in GAUSS with GAUSS pseudo-random number generators.
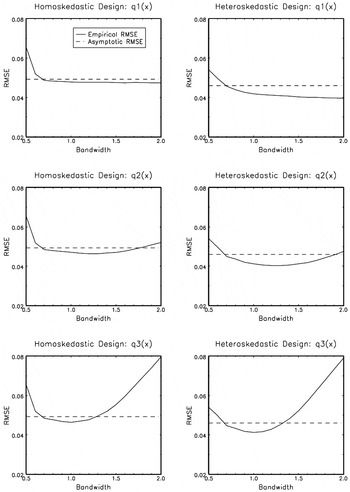
Figure 1 shows the asymptotic (dashed lines) and empirical (solid lines) root mean squared errors (RMSEs) of the AQR estimates of β. The asymptotic RMSEs were calculated (ignoring the effect of trimming) by the formula of the asymptotic variance given in Section 4. For all designs, the empirical RMSEs are quite close to the asymptotic RMSEs over a wide range of bandwidths including the range of the average
. It can be seen that the results for q3 are more sensitive to the bandwidth than those for q1 and q2, but the results for all designs are quite insensitive to the bandwidth in the range of the rule of thumb. The empirical biases of the AQR estimates were also computed and were negligible relative to the empirical standard deviations, so they are not reported here.

Results of the Monte Carlo experiments for the AQR estimates of β.
More tuning parameters are required to compute the one-step efficient estimates. The trimming function was set to be τ(x,z) = 1(|x| ≤ 2, |z| ≤ 2). Gaussian kernels were used to estimate fα(0|Xi,Zi). Bandwidths were ν1n = n−1/7 and ν2n = n−1/6 with respect to standardized designs. For the estimation of T(Xi), γn = sx n−1/5, where sx is the sample standard deviation of X. The smoothing function J is the integral of the quartic kernel such that

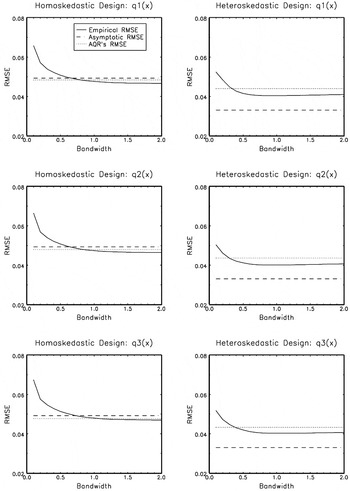
The AQR estimates of β and the estimates of q(·) were computed using bandwidth δn = 0.8 Finally, the bandwidth jn has to be chosen, but the asymptotic theory in Section 5 provides only qualitative restriction for the choice of jn. The experiments focused on the sensitivity to the choice of jn. In the experiments, jn = {0.1, 0.2,…,2.0}.
Figure 2 shows the asymptotic (dashed lines) and empirical (solid lines) RMSEs of the one-step estimates of β. In addition, it also shows the empirical RMSEs (dotted lines) of the AQR estimates. Asymptotic results given in previous sections indicate that the AQR estimator is as efficient as the one-step estimator for homoskedastic designs. Furthermore, the optimally weighted AQR estimator is basically the same as the AQR estimator because var(Z|X) is a constant in the experiments. On the other hand, it can be checked by some calculation that the asymptotic RMSE of the AQR estimator exceeds that of the one-step estimator by a factor of 1.4 for heteroskedastic designs. One noteworthy result is that the empirical RMSEs of the one-step estimates are somewhat larger than asymptotic counterparts for the heteroskedastic designs. This is not too surprising because the one-step estimates use several nonparametric estimates, which can be inaccurate for small sample size such as n = 100. The one-step estimates perform better than the AQR estimates for most of the values of bandwidth jn. It also appears that the results are somewhat insensitive to the choice of the bandwidth jn as long as jn is not too small. In summary, the results of Monte Carlo experiments indicate that our proposed estimators work reasonably well in the finite samples.

Results of the Monte Carlo experiments for the one-step estimates of β.
8. CONCLUSIONS
This paper has developed a new estimation method for the partially linear quantile regression model. It is shown that the parametric component βα can be efficiently estimated. This paper does not investigate methods for optimally choosing the tuning parameters that are required to implement the estimation method. Because the asymptotic distributions of the proposed estimators of βα do not depend on bandwidths, a higher order theory is required to choose optimal bandwidths. There is no theoretical work (that we are aware of) regarding a higher order approximation for semiparametric quantile regression. This is a topic of future research. Another problem that needs to be studied is how to conduct a specification test of the regression model. Although partially linear regression is quite flexible, it still has a possibility of misspecification. It would be also an interesting problem to test a particular parametric quantile regression model against a partially linear alternative.
APPENDIX
A.1. The Proofs of Theorems. This part of the Appendix provides the proofs of theorems. The proofs of Corollary 3 and Theorem 4 are omitted because they are straightforward modifications of the proof of Theorem 2. The stochastic order symbols such as op(1) or Op(1) will be understood componentwise. In addition, |·| is also considered componentwise. Let Uαi = Yi − qα(Xi) − Zi′ βα.
Proof of Theorem 1. Let Fy(·|x,z) denote the conditional distribution of Y given X = x and Z = z. Then we have Fy−1(α|x,z) = qα(x) + z′βα. Notice that Fy−1 is unique given x and z by condition (1). Rewrite this as

Premultiplying both sides by (1 z′)′, we have

for all x and z. Taking expectations on both sides given x, we have

Notice that qα(x) is just a point given x. If condition (2) is satisfied, then the matrix on the left-hand side is invertible. This implies that qα(x) and βα are uniquely determined. Because the choice of x is arbitrary, this completes the proof. █
Proof of Theorem 2. Let

. Write

First notice that Rτx,n results from the replacement of

. It is easy to see that Rτx,n = op(n−1/2) because

is the expectation of τx(X).
To obtain the asymptotic distribution of

, one needs to plug in a Bahadur-type expansion of

. Fortunately this type of expansion has been already well established in Chaudhuri (1991a, 1991b) and Chaudhuri et al. (1997). A modified version of the Bahadur-type linear representation for partially linear quantile regression is given in the second section of this Appendix. To describe the linear representation, we need additional notation. Let b(δn,Xj − Xi,Zj) denote the (s(Ak) + dz)-dimensional vector

and let Gn(Xi) denote the (s(Ak) + dz) × (s(Ak) + dz) matrix

Also, PZ(z|x) denotes a probability measure with respect to Z given X = x. Let e′ denote the dz × (s(Ak) + dz) matrix such that e′ = (0,Idz), where 0 denotes the dz × s(Ak)-dimensional zero matrix and Idz an identity matrix. In addition, let Nn(Xi) denote the number of all j's satisfying |Xj − Xi| ≤ δn for j ≠ i, j = 1,…,n, and let qα*(Xj,Xi) be the k-order Taylor polynomial defined in (A.10), which follows.
It follows from Lemma 1 in the second section of this Appendix that

provided that 1/(2pq + d) < κ < 1/(3dx). It is worth noting that b(δn,Xj − Xi,Zj) and Gn are different from those of Chaudhuri et al. (1997) because a partially linear regression model is considered here.
Now substituting the Bahadur-type expansion of

into Tn and following arguments similar to those in the proof of Theorem 2.1 of Chaudhuri et al. (1997) (in particular, we require 1/(2pq) < κ < 1/(3dx)), we have

where Un is a U-statistic with the kernel dependent on n:


As in the proof of Theorem 2.1 of Chaudhuri et al. (1997), an application of the standard Hoeffding decomposition of Un yields

The next step is to evaluate the limit of the projection Pn. We will show subsequently that

where

Conditioning on (Xi,Zi), we have

As in Lemma 4.2(b) of Chaudhuri et al. (1997), it can be shown that

where OL2(·) denotes a remainder term that is bounded in the L2 norm. By a change of variables, the inner expectation in (A.4) becomes

Using this and a Taylor series expansion, we can show that the outer expectation in (A.4) converges to zero, which proves (A.3). By Chebyshev inequality, (A.3) implies

from which the desired result follows immediately using the multivariate central theorem. █
Proof of Theorem 5. Let I* = V*−1. Write

Let

It will be shown subsequently that


It then follows that

which gives the desired result immediately.
As in Lemma 4.3(a) of Chaudhuri et al. (1997), it can be shown that

In fact, we require that 1/(2pq + dx) < κ < 1/(3dx) in view of Lemma 1 (in particular, see step 3 in the proof). Furthermore, by similar arguments as in the proof of Theorem 2, it can be proved that


where the first equality comes from differentiation, the second equality follows in view of the uniform consistency of

, and the fourth equality can be proved using methods similar to those used to calculate the asymptotic mean of kernel density estimators. To prove the third equality, note that by a Taylor series expansion,

where the remainder term Rn,J is

with the restriction that njn3 → ∞. Now we need to show that Rn,J = op(1). To see this, use the fact that J(2) is Lipschitz continuous to obtain

Using a Taylor series expansion,

where Rn,S is a Taylor series remainder term. As before, the expression in the brackets of the second term is −I* + op(1). Using the same arguments as in (A.9), one can show that the remainder term Rn,S is op(1). As in Lemma 3(k) of Horowitz (1998a), it is not difficult to show that using Chebyshev inequality,

To prove (A.6), it now suffices to show that the third term in the Taylor series expansion is op(1). To see this, note that under Assumption 10,

where the last equality follows from (A.7) and the restriction on jn. █
A.2. Linear Representation for the First-Step Estimators. The result presented here is an extension of the Bahadur-type representation for the local polynomial conditional quantile estimators given in Lemma 4.1 in Chaudhuri et al. (1997). The following lemma assumes partially linear quantile regression and gives a uniform result in the conditional variables Xi.
Define the k-order Taylor polynomial

with the coefficients cn,u(x) = (u!)−1Du(x)δn[u] , where u! = u1!…ud!. Let cα(x) = (cn,u(x))u∈Ak denote the s(Ak)-dimensional vector of Taylor coefficients in (A.10). In addition, let

denote the (s(Ak) + dz)-dimensional vector that minimizes (2) and let aα(Xi) = (cα(Xi)′,βα′)′. Moreover, let b(δn,Xj − Xi,Zj) and Gn(Xi) be defined in (A.1) and (A.2), respectively.
LEMMA 1. Let Assumptions 1–5, 7, and 8 hold. Then we have

where the remainder term Rn(Xi) satisfies

Proof of Lemma 1. We will provide the main ideas and indicate the differences that result from partially linear quantile regression. We will split the proof into several steps.
Step 1. Step 1 of the proof of Lemma 4.1 in Chaudhuri et al. (1997) can be repeated without any modification for our purpose. Specifically, we can choose a pair of positive constants c1 and c2 such that

Step 2. The rate of the uniform convergence can be derived by using arguments similar to those in Chaudhuri et al. (1997). It can be shown that there exists a positive constant K1 such that

provided that κ > 1/(2pq + dx). Under Assumptions 1–5, 7, and 8, Fact 6.5 in Chaudhuri (1991b) and Fact 5.2 in Chaudhuri (1991a) can be easily restated for our purpose. Then (A.12) follows from simple modifications of the arguments used in the proofs of Theorem 3.2 in Chaudhuri (1991b) and Theorems 3.2 and 3.3 in Chaudhuri (1991a).
Step 3. Let

denote the Taylor polynomial with estimated coefficients, which is (A.10) with

. Define

Using the result in step 2 and the continuous differentiability of fα(u|x,z) with respect to u in a neighborhood of zero, we can show that

Step 4. For each Xi, define an (s(Ak) + dz)-dimensional random vector χn(Xi) as

It follows from arguments similar to those used in the proof of Theorem 3.3 in Chaudhuri (1991b) that

almost surely as n → ∞ uniformly in

. To exploit Bernstein's inequality, it is assumed here that Z is bounded.
Step 5. Write

where on the event En. As in step 3 of the proof of Theorem 3.3 in Chaudhuri (1991b), it can be shown that

for some constant M, which is uniform in

. Finally, the desired result of the lemma follows by combining (A.13)–(A.16) and the fact that Gn(Xi) is invertible as n → ∞. █
References
REFERENCES
Andrews, D.W.K.
(1994)
Empirical process methods in econometrics. In
R.F. Engle &
D. McFadden (eds.),
Handbook of Econometrics, vol. IV, pp.
2247–2294.
New York:
North-Holland.
Andrews, D.W.K.
(1995)
Nonparametric kernel estimation for semiparametric models.
Econometric Theory
11,
560–596.Google Scholar
Bickel, P.J.,
C.A.J. Klaassen,
Y. Ritov, &
J.A. Wellner
(1993)
Efficient and Adaptive Estimation for Semiparametric Models.
Baltimore:
Johns Hopkins University Press.
Bierens, H.J.
(1983)
Uniform consistency of kernel estimators of a regression function
under generalized conditions.
Journal of the American Statistical Association
78,
699–707.Google Scholar
Bierens, H.J.
(1987)
Kernel estimators of regression functions. In
T.F. Bewley (ed.),
Advances in Econometrics: Fifth World Congress, vol. I, pp.
99–144.
New York:
Cambridge University Press.
Buchinsky, M.
(1998)
Recent advances in quantile regression models.
Journal of Human Resources
33,
88–126.Google Scholar
Chaudhuri, P.
(1991a)
Global nonparametric estimation of conditional quantile functions
and their derivatives.
Journal of Multivariate Analysis
39,
246–269.Google Scholar
Chaudhuri, P.
(1991b)
Nonparametric estimates of regression quantiles and their local
Bahadur representation.
Annals of Statistics
19,
760–777.Google Scholar
Chaudhuri, P.,
K. Doksum, &
A. Samarov
(1997)
On average derivative quantile regression.
Annals of Statistics
25,
715–744.Google Scholar
Chen, S. &
S. Khan
(2000)
Estimating censored regression models in the presence of
nonparametric multiplicative heteroskedasticity.
Journal of Econometrics
98,
283–316.Google Scholar
Chen, S. &
S. Khan
(2001)
Semiparametric estimation of a partially linear censored regression
model.
Econometric Theory
17,
567–590.Google Scholar
Fan, J. &
I. Gijbels
(1996)
Local Polynomial Modelling and Its Applications.
London:
Chapman and Hall.
Fan, J.,
T.-C. Hu, &
Y.K. Truong
(1994)
Robust nonparametric function estimation.
Scandinavian Journal of Statistics
21,
433–446.Google Scholar
Härdle, W.
(1990)
Applied Nonparametric Regression.
New York:
Cambridge University Press.
He, X. &
H. Liang
(2000)
Quantile regression estimates for a class of linear and partially
linear errors-in-variables models.
Statistica Sinica
10,
129–140.Google Scholar
He, X.,
P. Ng, &
S. Portnoy
(1998)
Bivariate quantile smoothing splines.
Journal of the Royal Statistical Society, Series B
60,
537–550.Google Scholar
He, X. &
P. Shi
(1994)
Convergence rate of B-spline estimators of nonparametric
conditional quantile functions.
Journal of Nonparametric Statistics
3,
299–308.Google Scholar
He, X. &
P. Shi
(1996)
Bivariate tensor-product B-splines in a partly linear model.
Journal of Multivariate Analysis
58,
162–181.Google Scholar
Horowitz, J.L.
(1998a)
Bootstrap methods for median regression models.
Econometrica
66,
1327–1351.Google Scholar
Horowitz, J.L.
(1998b)
Semiparametric Methods in Econometrics.
New York:
Springer-Verlag.
Khan, S.
(2001)
Two stage rank estimation of quantile index models.
Journal of Econometrics
100,
319–355.Google Scholar
Khan, S. &
J.L. Powell
(2001)
Two-step estimation of semiparametric censored regression models.
Journal of Econometrics
103,
73–110.CrossRefGoogle Scholar
Klein, R.W. &
R.H. Spady
(1993)
An efficient semiparametric estimator for binary response models.
Econometrica
61,
387–421.CrossRefGoogle Scholar
Knight, K.
(1998)
Limiting distributions for L1 regression
estimators under general conditions.
Annals of Statistics
26,
755–770.Google Scholar
Koenker, R.,
P. Ng, &
S. Portnoy
(1994)
Quantile smoothing splines
Biometrika
81,
673–680.Google Scholar
Newey, W.K.
(1990)
Semiparametric efficiency bounds.
Journal of Applied Econometrics
5,
99–135.CrossRefGoogle Scholar
Newey, W.K. &
J.L. Powell
(1990)
Efficient estimation of linear and type I censored regression
models under conditional quantile restrictions.
Econometric Theory
6,
295–317.CrossRefGoogle Scholar
Newey, W.K. &
J.L. Powell
(1993)
Efficiency bounds for some semiparametric selection models.
Journal of Econometrics
58,
169–184.CrossRefGoogle Scholar
Robinson, P.M.
(1988)
Root-n-consistent semiparametric regression.
Econometrica
56,
931–954.CrossRefGoogle Scholar
Smirnov, N.V.
(1952)
Limit distributions for the terms of a variational series.
American Mathematical Society Translation, no. 67,
64 pp.
Welsh, A.H.
(1996)
Robust estimation of smooth regression and spread functions and
their derivatives.
Statistica Sinica
6,
347–366.Google Scholar
Yu, K. &
M.C. Jones
(1998)
Local linear quantile regression.
Journal of the American Statistical Association
93,
228–237.Google Scholar
Zhao, Q.
(2001)
Asymptotically efficient median regression in the presence of
heteroskedasticity of unknown form.
Econometric Theory
17,
765–784.Google Scholar
Results of the Monte Carlo experiments for the AQR estimates of β.
Results of the Monte Carlo experiments for the one-step estimates of β.
 You have
Access
- 84
- Cited by