




No CrossRef data available.
COVARIANCE MATRIX ESTIMATION AND THE LIMITING BEHAVIOR OF THE OVERIDENTIFYING RESTRICTIONS TEST IN THE PRESENCE OF NEGLECTED STRUCTURAL INSTABILITY
Published online by Cambridge University Press: 24 September 2003
Abstract
We consider the limiting behavior of the overidentifying restrictions test in the presence of neglected structural instability at a single “break point.” It is shown that the test need not be consistent against this type of misspecification. If it is consistent then it emerges that the limiting behavior of this test statistic depends on the covariance matrix estimator employed. In this paper we consider the case in which a heteroskedasticity autocorrelation covariance (HAC) is used. It is shown that (i) if the HAC estimator is based on uncentered autocovariances then the overidentifying restrictions test diverges at rate T/bT where T is the sample size and bT is the bandwidth; (ii) if the HAC estimator is based on centered autocovariances then the rate of increase of the overidentifying restrictions test is either T/bT or T depending on the form of the instability. These results are used to provide conditions for the consistency of the method of moment selection of Andrews (1999, Econometrica 67, 543–564) when certain elements of the candidate set of moments are misspecified as a result of neglected structural instability.This work was begun while Hall was a Senior Research Fellow and Peixe was a graduate student at the Department of Economics, University of Birmingham, UK, and this support is gratefully acknowledged. Peixe also gratefully acknowledges financial support from FCT under Grant PRAXIS XXI/BD/13453/97. We are very grateful for the very useful comments of Don Andrews and two anonymous referees.
Information
- Type
- Research Article
- Information
- Copyright
- © 2003 Cambridge University Press
1. INTRODUCTION
The overidentifying restriction test is routinely applied in applications of generalized method of moments (GMM) (Hansen, 1982) to assess the adequacy of the model specification. This statistic is particularly convenient because it is a quadratic form in the estimated sample moment evaluated at the second step or iterated estimator and the inverse of the estimated long-run variance of the sample moment. In this paper, we consider the limiting behavior of the overidentifying restrictions test statistic in the presence of misspecification characterized by structural instability at a single “break point.”1
This type of instability is the one most commonly applied in the literature on structural stability testing based on GMM estimators (see inter alia Andrews and Fair, 1988; Ghysels and Hall, 1990; Andrews, 1993; Sowell, 1996; Ghysels, Guay, and Hall, 1997; Hall and Sen, 1999).
The nature of this limiting behavior has important consequences for the construction of moment selection procedures based on the overidentifying restrictions statistic. Andrews (1999) introduces three such methods based, respectively, on an information criterion, an upward testing strategy, and a downward testing strategy. He establishes the consistency of these methods under the assumption that if the moment condition is invalid then the overidentifying restrictions test diverges at rate T. We generalize this analysis to provide conditions under which these methods of moment selection are consistent when members of the candidate set are misspecified as a result of neglected structural instability of the type described previously. Practical implications of these results are also discussed.
The plan of the paper is as follows. Section 2 provides a general result about the inverse of a particular class of matrices that is used in our analysis of the limiting behavior of the HAC estimators. We believe that this inversion result is of interest in its own right and thus present it in a separate section. Section 3 presents our analysis of the overidentifying restrictions test in the presence of neglected structural instability. Section 4 contains an analysis of the moment selection methods when misspecification is due to neglected structural instability. Section 5 presents some concluding remarks. All proofs are relegated to the Appendix.
2. A MATRIX INVERSION RESULT
Consider the matrix

where A is a q × q positive (or negative) definite symmetric matrix of finite, real constants, B is a q × k matrix of finite real constants of rank k, and cT is a scalar sequence of constants that satisfies cT → ∞ as T → ∞.
LEMMA 1. MT has the following properties.
(i) For k ≤ q, limT→∞ cT−k det(MT) = d(A,B), where det(MT) is the determinant of MT and d(A,B) is a finite, nonzero constant that depends on the elements of A and B.
(ii) For k < q, limT→∞ cT−k adj(MT) = a(A,B), where adj(MT) is the adjoint of MT and a(A,B) is a finite, nonzero constant that depends on the elements of A and B. For k = q, limT→∞ cT−k+1 adj(MT) = a(A,B), where a(A,B) is a finite, nonzero constant that depends on the elements of A and B.
(iii) limT→∞ (MT)−1 = N = A−1 − A−1B(B′A−1B)−1B′A−1 for k < q.
(iv) rank(N) = q − k for k < q and the null space of N is spanned by B.
(v) limT→∞ (MT)−1 = 0q where 0q is the q × q null matrix, if k = q.
For brevity, the proof is omitted but is available from the authors upon request. This result generalizes Theorem 1 of Hall (2000), which covers the case in which k = 1. Lemma 1 reveals an interesting relationship between the limiting behavior of MT and that of its inverse. The term MT is the sum of two matrices: A, which is nonsingular and O(1), and cT BB′, which is singular with rank k and O(cT). For finite T, MT is nonsingular, but it is clear that as T → ∞ then cT BB′ dominates in some sense. In the scalar case, the dominant role of the second term is readily apparent in the inverse because limT→∞(a + cT b2)−1 = 0. However, Lemma 1 indicates that the matrix case is far more subtle. As the rank of cT BB′ increases then the rank of limT→∞(MT)−1 = N decreases. Notice that it is only in the case where k = q, and so cT BB′ is nonsingular, that N equals the null matrix.
3. THE LIMITING BEHAVIOR OF THE OVERIDENTIFYING RESTRICTIONS TEST IN THE PRESENCE OF NEGLECTED STRUCTURAL INSTABILITY
In this section, we consider the limiting behavior of the overidentifying restrictions test in the presence of neglected structural instability when the long-run variance is estimated using a HAC matrix. To define this test statistic, we must briefly provide an outline of the GMM estimation framework.
Let

where

, and p ≤ q and let {vt} be a sequence of d-dimensional random vectors in

. We consider the case in which the researcher (mistakenly) assumes that there exists an unknown, but unique, element θ0 ∈ Θ such that

and proceeds to estimate θ0 using GMM based on (2) using the sample {vt; t = 1,2…,T}. Define the first step GMM estimator

by

where

and WT(1) is a q × q positive semidefinite matrix that converges in probability to a positive definite matrix W(1). Because the first step estimator is typically asymptotically inefficient, it is assumed that the researcher undertakes a second step estimation. This second step GMM estimator is defined to be

where the minimand is

and WT(2) is an estimator that is believed to be consistent for the inverse of the long-run variance of the sample moment. In this paper, we consider the case in which WT(2) is either

where

for

and

for

. Subsequently we impose specific assumptions on the scalar function ω(.), known as the kernel, and the bandwidth, bT. Both

fall into the generic class of HAC estimators. The only difference between them is in whether or not the sample autocovariance matrices are centered. For this reason, we refer to

as the uncentered HAC estimator and to

as the centered HAC estimator.
The overidentifying restrictions test statistic associated with second step estimation is given by

This statistic is the focus of our paper. However, we discuss the extension of our results to the overidentifying restrictions test associated with the iterated GMM estimator at the end of the section.
In view of the structure of (3) and (7), the analysis breaks down naturally into three parts. First we derive the limiting behavior of the inverse of a HAC matrix in the presence of neglected structural instability using Lemma 1. Second, we derive the probability limit of the second step GMM estimator. Third, we use aforementioned results to deduce the limiting behavior of the overidentifying restrictions test associated with the second step GMM estimation.
3.1. The Limiting Behavior of the Inverse of the Uncentered and Centered Full Sample HAC Estimators
Given the structure of

, such an analysis requires assumptions about the first step GMM estimator, the kernel and bandwidth used in the HACs, and certain aspects of the data generation process. We now present these assumptions in turn.
The first step estimator is assumed to satisfy the following condition.
Assumption 1. The first step GMM estimator

converges in probability to a well-defined limit denoted θ*(W(1)) where

W(1).
The kernel and bandwidth are restricted to satisfy the following conditions.
Assumption 2. (i) For all

, |ω(x)| ≤ 1, ω(−x) = ω(x), ω(0) = 1, ω(x) is continuous at zero, and for almost all

, ω(x) = 0 for |x| ≥ 1,

for all

where 0 < β < ∞; (ii) bT is a sequence of nonnegative integers such that bT = o(T1/2) and bT → ∞.
It can be verified that Assumption 2(i) restricts attention to truncated kernels such as the Bartlett and Parzen, which were proposed in this context, respectively, by Newey and West (1987) and Gallant (1987). Assumption 2(ii) specifies the rate of increase for bT used by Andrews (1991) in his proof of the consistency of

in correctly specified models.
We now specify certain key aspects of the data generation process. We focus exclusively on the case in which there is instability at a single point in the sample, denoted [πT] , where π ∈ (0,1) and [.] denotes the integer part.
2This scenario is also the primary focus of all the papers on structural stability based on GMM cited in note 1.

and θ* = θ*(W(1)).
Assumption 3. The sample {vt} is a realization from a stochastic process that satisfies the following conditions.
(i) The first moment of f (vt,θ*) satisfies

where μ1 ≠ μ2.
(ii) The autocovariances of f (vt,θ*) satisfy

(iii) The long-run variances for each subsample are given by

, where V1 and V2 are positive definite matrices of constants.
(iv) The long-run variance of the full sample is given by

.

Notice that Assumption 4 is weaker than the requirement that the partial sums satisfy a central limit theorem.
The following theorem characterizes the large sample behavior of the two HAC estimators described previously.
THEOREM 1. Suppose that Assumptions 1–4 hold. Then the HAC estimators in (5) and (6) take the generic form

where A = V, {cT} satisfies limT→∞ bT /cT = β, and (a) for

; (b) for

.
Theorem 1 indicates that neither estimator is consistent in the presence of neglected structural stability.3
However, the centered full sample estimator is consistent if μ1 = μ2. The latter condition implies that the misspecification is not characterized by structural instability but is constant over time, and so under these circumstances this result replicates Theorem 3(i) of Hall (2000).
COROLLARY 1. Suppose that Assumptions 1–4 hold. Then (a)

where NU has rank q − rU where

and has a null space spanned by

; (b)

where NC has rank q − 1 and a null space spanned by (μ1 − μ2).
In most cases rU = 2; however, it is easily verified that rU = 1 under the following circumstances.
Assumption 5. One of the following conditions holds: (i) μ1 = 0, μ2 ≠ 0; (ii) μ1 ≠ 0, μ2 = 0; (iii) μ1 ∝ μ2.
These three cases have an obvious interpretation. Parts (i) and (ii) imply that the population moment condition evaluated at θ* is satisfied in one subsample but not in the other. Part (iii) implies that the instability is purely due to a scale effect, that is, μi = ki μ for some nonzero vector μ and scalars ki for which k1 ≠ k2. Notice that if Assumption 5 holds then the null spaces of both NU and NC are spanned by μ1 − μ2.
3.2. The Limiting Behavior of the Second Step GMM Estimator
Standard proofs of convergence in probability can be divided into two parts.4
For example, see Newey and McFadden (1994).
To characterize the population analog to QT(θ;WT(2)), we introduce the following assumption.
Assumption 6. μ1(θ) = E [f (vt,θ)] for t = 1,2,…[πT] and μ2(θ) = E [f (vt,θ)] for t = [πT] + 1,…T for all θ ∈ Θ. Moreover, supθ∈Θ∥g1,T(θ) − μ1(θ)∥ = op(1) and supθ∈Θ∥g2,T(θ) − μ2(θ)∥ = op(1) where
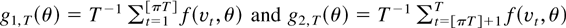
.
Assumption 6 and Corollary 1 imply that5
This follows by the same argument as the proof of Theorem 2.6 in Newey and McFadden (1994).

where

denotes whichever HAC estimator is chosen to estimate the long-run variance. Therefore, we refer to Q0(θ;W(2)) as the population analog to QT(θ;WT(2)).
To derive the probability limit of

, it is necessary to impose an identification condition. It is most convenient to express this condition in the following generic form.
Assumption 7. Q0(θ;W(2)) is minimized at θ = θ**(W(2)), and Q0(θ**(W(2));W(2)) < Q0(θ;W(2)) for all θ ∈ Θ[setmn ]{θ**(W(2))}.
Subsequently we specialize this assumption to the choice of W(2) implied by the particular choice of HAC estimator.6
Assumption 7 is similar to the “identifiable uniqueness” condition that underpins Gallant and White's analysis of misspecified models (see Gallant and White, 1988, p. 19).
The following theorem gives the probability limit of

.
THEOREM 2. Let Assumptions 1–4 and 6 hold.
(a) Let

and Assumption 7 hold for W(2) = NU; then

.
(b) Let

and Assumption 7 hold for W(2) = NC; then

. If, in addition, Assumption 5 holds then θ**(W(2)) = θ*(W1).
Notice that if the uncentered full sample HAC estimator is used then the second step GMM estimator converges to the same probability limit as the first step estimator even though the model is misspecified.
3.3. The Limiting Behavior of the Overidentifying Restrictions Test
To facilitate the analysis, certain additional conditions are required. The first assumption imposes uniform convergence of derivative matrices in each subsample.

The second assumption imposes the uniform boundedness of the partial sums of the sample moment.

Assumption 9 is not commonly used but holds if


where the latter holds in a neighborhood of θ**. For example, (9) and (10) are satisfied if the moment function and its gradient are bounded (in probability) uniformly in t.
The behavior of the overidentifying restrictions test depends crucially on

Note that it is possible for E [f (vt,θ)] ≠ 0 for all t but μ(θ) = 0. In other words, there may be no single value of θ that satisfies the population moment condition for every observation, but there is a value that sets the average of these population moment conditions to zero.
The limiting behavior of the overidentifying restrictions test in the presence of neglected structural instability is given by the following theorem. To facilitate the presentation, we define μ* = μ(θ*), μ** = μ(θ**), θ* = θ*(W(1)), and θ** = θ**(W(2)).
THEOREM 3. If Assumptions 1–4 and 6–9 hold then the large sample properties of the overidentifying restrictions test are as follows.
(a) Put

. If μ* = 0 then JT(WT(2)) = Op(1); otherwise JT(WT(2)) diverges at rate T/bT.
(b) Put

. If μ** = 0 then JT(WT(2)) = Op(1). If μ** ≠ 0 and μ** is in the null space of NC then JT(WT(2)) diverges at rate T/bT. Otherwise JT(WT(2)) diverges at rate T.
Theorem 3 establishes certain important features about the limiting behavior of the overidentifying restrictions in the presence of neglected structural instability. First, the test need not be consistent. Notice that this failure is not specific to the case in which a HAC estimator is used but applies more generally. Second, even if it is consistent then the rate of divergence depends on the choice of covariance matrix. If the uncentered HAC is used and the test is consistent then the overidentifying restrictions test only diverges at rate T/bT. Notice that this behavior conforms with the results presented in Hall (2000) for the case in which the model is misspecified but structurally constant. However, if a centered version of the HAC is used and the test is consistent then the situation is more complicated. If μ** is in the null space of NC then the statistic diverges at rate T/bT and in others at rate T. The vector μ** can lie in the null space either because Assumption 5 holds, and so μ** = μ(θ*), or because it so happens that μ** = b(μ1 − μ2) ≠ 0 for some b.
Throughout the analysis, we have concentrated on the two-step estimator. It is straightforward to show that Theorem 2(a) extends to the iterated estimator and as a consequence that Theorem 3(a) holds for the overidentifying restrictions test based on the iterated estimator. The results in Theorems 2(b) and 3(b) hold if the second step estimator is replaced by the ith step estimator, the first step estimator is replaced by the i − 1th step estimator, and all other definitions are changed appropriately.
4. IMPLICATIONS FOR MOMENT SELECTION
Andrews (1999) proposes methods for moment selection that use either an information criterion or a sequential testing strategy based on the overidentifying restrictions test. He also establishes conditions for their consistency. One of these conditions states that the overidentifying restrictions test diverges at rate T if the moment condition is invalid. It follows from Theorem 3 that the overidentifying restrictions test does not behave in this way under certain conditions when the long-run variance is estimated using a HAC estimator and the moment conditions are invalid due to neglected structural instability. Therefore, in this section, we present an alternative set of conditions for the consistency of the methods of moment selection based on the information criterion and the downward testing strategy.7
We do not consider the third method based on an upward testing strategy because its consistency requires stronger assumptions than the other two. Furthermore, the required modifications to the conditions of Andrews (1999) for consistency of this method are easily deduced from our analysis of the downward testing strategy in Section 4.
To consider the problem of moment selection, it is necessary to introduce some additional notation. It is assumed that the candidate set of scalar functions that can form the basis for the population moment condition is finite. It is convenient to stack these scalar functions into a single vector fmax(.) whose dimension is denoted by qmax. Following Andrews (1999), we use a (qmax × 1) selection vector c to denote which elements of the candidate set are included in a particular moment condition. We therefore now index f (.) by c. If cj = 1 this implies that the jth element of fmax(.) is included in f (.;c), and cj = 0 implies that this element is excluded. Note that |c| = c′c equals the number of elements in f (.;c). The set of all possible selection vectors is denoted by C, that is,

Following Andrews (1999) we also define the sets

as follows:

These sets are used in the statement of an identification condition later.
To present the generic structure of the moment selection methods, we use JT(c) to denote the overidentifying restrictions test associated with the selection vector c. The two moment selection procedures are as follows.
Information criterion.
The selected moment is given by

where

and the information criterion is given by

where −h(|c|)κT is a deterministic bonus term on whose components certain restrictions are placed subsequently.
Downward testing.
The selected moment condition is given by

, any choice of selection vector that satisfies the following conditions.

where γT,|c|−p is the 1 − αT quantile of the χ|c|−p2 distribution. Conditions are placed on αT later.
Given the results in Theorem 3, we consider the case in which the overidentifying restrictions test exhibits the following generic behavior.
Assumption 10. (i) If E [f (vt,θ*;c)] = 0 for some θ* ∈ Θ then

. (ii) If E [f (vt,θ*;c)] ≠ 0 for all θ ∈ Θ then

where a(c) is a finite positive constant that depends on c and τT → ∞ as T → ∞.
The following lemma gives conditions for the consistency of the two methods of moment selection.8
Andrews (1999) also considers the case in which

is not a singleton, but for brevity we do not consider this situation here.
LEMMA 2. Let Assumption 10 hold and assume

. (i) If h(.) is strictly increasing and κT → ∞ as T → ∞ with κT = o(τT) then

. (ii) If αT → 0 as T → ∞ with ln(αT) = o(τT) then

.
This lemma is established using identical arguments to the proofs of Theorems 1 and 2 of Andrews (1999) and so is omitted for brevity. However, there are two important differences between Lemma 2 and this earlier work. Andrews (1999) only considers the case in which a centered covariance matrix estimator is used and τT = T. In contrast, Lemma 2 is valid for cases in which the overidentifying restrictions test diverges at some unspecified rate τT when the moment condition is misspecified. Therefore, it allows for cases in which a centered covariance matrix estimator is used, but the test diverges more slowly than T, and it also covers cases in which an uncentered HAC covariance matrix estimator is used.
We now consider the implications of this result for the case in which a HAC is used to estimate the long-run variance and moments are invalid because of neglected structural instability of the type considered in the previous section. Because Andrews (1999) recommends using the centered covariance matrix estimator for the purposes of model selection, we focus purely on that case for brevity. We split our discussion into two parts depending on whether or not the test is consistent. If the test is not consistent then it does not diverge in cases when E [f (vt,θ**;c)] ≠ 0 for all t, and this inevitably means that neither moment selection method is consistent. Now consider the case in which the test is consistent. Theorem 3 indicates that the rate of divergence can be either T/bT or T. Because in practice it is impossible to know which rate is relevant, we consider the worst case scenario, that is, τ = T/bT. For the information criterion approach, the standard choices for the bonus term are GMM-BIC, for which κT = ln(T), and GMM-HQIC, for which κT = ln[ln(T)] .9
The appropriate choices of h(.) are |c| − p for GMM-BIC and k(|c| − p) where k > 2 for GMM-HQIC. See Andrews (1999) for further discussion.
LEMMA 3. Let Assumption 10 hold. If αT → 0 as T → ∞ with ln(αT) = o(T) but −ln(αT)/τT → ∞ then

where cmax is a qmax × 1 vector of ones.
Therefore, even if the candidate set contains invalid moment conditions—for example,

and |co| < qmax—the downward testing sequence picks all the moment conditions with probability one. The lemma is deduced using Theorem 5.8 of Pötscher (1983), in which it is shown that γ|c|−p,T = o(τT) if and only if ln(αT) = o(τT). Therefore, it follows that if ln(αT)/τT → ∞ then γ|c|−p,T diverges faster than the test statistic.
5. CONCLUDING REMARKS
In this paper, we have analyzed the behavior of the overidentifying restrictions test in the presence of neglected structural instability at a single break point. It is shown that the test need not be consistent against this type of misspecification. However, if it is consistent then the rate of divergence of the statistic depends on the covariance matrix estimator employed. If an uncentered HAC estimator is used then the test diverges at rate T/bT; if a centered HAC estimator is used then the test diverges at either rate T/bT or T depending on the form of the instability. These results are used to explore the properties of certain moment selection procedures when certain elements of the candidate set are misspecified as a result of neglected structural instability. Specifically, conditions are provided for the consistency of both the moment selection criterion of Andrews (1999) and a downward testing strategy based on the overidentifying restrictions test. For the moment selection criterion of Andrews (1999), these conditions exclude certain forms of instability but show that the method is valid with the bonus terms recommended by Andrews (1999). These results apply regardless of whether a centered HAC estimator, as recommended by Andrews (1999), or an uncentered HAC estimator is used to estimate the long-run variance. For the downward testing strategy, these conditions again exclude certain forms of instability and also require that the size of the test be chosen in a way that reflects the true rate of divergence of the test.
We believe that these results have some important practical implications for the use of moment selection procedures. If it is suspected that the candidate set contains moments that are misspecified because of neglected structural instability, then our results suggest that both of the aforementioned moment selection procedures are likely to provide effective methods for excluding a broad class of moments that are invalid in this way, at least asymptotically. However, because the overidentifying restrictions test is not consistent against all possible misspecifications of this type, it is advisable to submit the chosen moment condition to conventional tests for structural instability.
APPENDIX
Proof of Theorem 1.
Part (a). To simplify the notation let

. Consider

. We can divide

into three parts:

where T1 = [πT] . From Assumption 8, it follows that


Therefore, it follows that
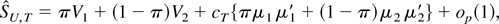
where

by Assumption 2(i). The proof is completed by noting that πμ1μ1′ + (1 − π)μ2 μ2′ = BB′ where

.
Part (b). Let μ* denote the probability limit of

. Assumption 4(i) implies that

By definition,

and so multiplying out the outer product, we obtain

From Assumption 4(i) it follows that

. The latter results combined with (A.1) imply that

where we have used (A.6) to deduce that μ1 − μ* = (1 − π)(μ1 − μ2). Using similar logic, it follows that

Combining these results, we obtain

We can repeat the same sequence of arguments for any i ≤ bT to deduce that

and so from (6) it follows that

The desired result then follows from Assumption 2(i). █
Proof of Theorem 2. For notational convenience we set

. Under our assumptions, it is straightforward to replicate the argument of Wooldridge (1994, (7.1)), which invokes Theorem 2.1 of Newey and McFadden (1994), to prove that

converges in probability to the unique minimizer of Q0(θ;W(2)). Therefore, it only remains to prove the statements in the theorem regarding θ**(W(2)). For part (a), notice that Corollary 1(a) implies that Q0(2)(θ*(W(1)) = 0, and so θ*(W(1)) minimizes Q0(θ;W(2)), which implies θ**(W(2)) = θ*(W(1)) in Assumption 7. For part (b), recall that if Assumption 5 holds then the null spaces of NU and NC are both spanned by μ1 − μ2, and so by the same argument as in part (a) it follows that θ**(W(2)) = θ*(W(1)). █
Proof of Theorem 3. For notational brevity, we set

, θ** = θ**(W(2)), θ* = θ*(W(1)), and JT = JT(WT(2)).
Part (a). An outline of the proof is as follows. We first consider the large sample behavior of

and then consider its implications for JT. We concentrate on the more general case in which μ* ≠ 0. It follows immediately from this analysis that if μ* = 0 then

and so JT = Op(1).
From Theorem 2(a) it follows that

. Using the mean value theorem, it follows that

where

is the q × p matrix with ith row equal to the ith row of GT(θT(i)) for GT(θ) = ∂gT(θ)/∂θ′,

, 0 ≤ λT(i) ≤ 1, and λT = (λT(1),…,λT(q)). Equation (A.11) implies

We now consider each term on the right-hand side of (A.12) in turn. Using (A.6) we have

where


Therefore from Assumption 7, it follows that

. Clearly T1/2μ* is O(T1/2). Assumption 8 implies

From the first-order conditions and (A.11), it follows that

From Theorem 1, Corollary 1, and Assumption 8, it follows that

where NU = V−1 − V−1B(B′V−1B)−1B′V−1 and

. Notice that Assumption 7 that implies G*′NU G* is full rank and so nonsingular. Now consider

. It is convenient to rewrite HT using (A.14) and (A.15) as

The first term on the right-hand side of (A.19) is Op(1) from Corollary 1 and Assumption 7. Now consider the second term on the right-hand side of (A.19), which can be written as


if Assumption 5 is not satisfied and

if Assumption 5 is satisfied.
Now (A.6) implies

where

. The substitution of (A.23) into (A.21) and (A.22) and some reorganization yield

if Assumption 5 is not satisfied and

if Assumption 5 is satisfied, where the last identity follows from Theorem 1. Now consider the second term on the right-hand side of (A.20). Using Lemma A.1 of Hall and Inoue (2003) it follows that

Using (A.24), (A.25), (A.26), and Corollary 1 it follows that

Next we shall show that the third term on the right-hand side of (A.19) is op(T1/2). To this end, consider

. By definition, we have for i > 0,

and so

Using Assumption 9 it then follows that

and so the desired result is established because bT = o(T1/2).
Combining (A.17)–(A.28) we obtain

if Assumption 5 is not satisfied and

if Assumption 5 is satisfied. Notice that either way

. Therefore from (A.12), (A.29), and (A.30), it follows that

if Assumption 5 is not satisfied and

if Assumption 5 is satisfied.
Now consider JT. With a simple rearrangement, it follows that

To analyze the large sample behavior of JT, we substitute (A.31) into (A.33). Because T1/2μ* is the dominant term in (A.31), we begin by considering

Now,

if Assumption 5 is not satisfied and

if Assumption 5 is satisfied. So using (A.23), it follows after some rearrangement that

if Assumption 5 is not satisfied and

if Assumption 5 is satisfied. Because cT = O(bT) we have n1,T = Op(T/bT). Furthermore, it can be shown that (although we omit the details for brevity)

and so this equation plus (A.35) and (A.36) yields JT = Op(T/bT).
From (A.35)–(A.37) it follows that

if Assumption 5 is not satisfied and

if Assumption 5 is satisfied. Therefore

where β = limT→∞(bT /cT). By definition a′a = 1, and from Assumption 4(i) it follows that β > 0, so (A.40) implies limT→∞ P[JT > cq−p,α] = 1.
Finally note that it follows from (A.38) that

if Assumption 5 is not satisfied and

if Assumption 5 is satisfied, where kT(1) = (bT /cT2)a′[cT−1I2 + B′VT−1B]−1a and kT(2) = (bT /cT2)a′[cT−1 + B′VT−1B]−1a. Because cT > 0 and VT is positive semidefinite, kT(1) ≥ 0 and kT(2) ≥ 0. Therefore limT→∞ P[(bT /T)JT ≤ β] = 1.
Part (b). We concentrate on the more general case in which μ** ≠ 0. It follows immediately from this analysis that if μ** = 0 then

, and so JT = Op(1).
The vector μ** lies in the null space if either Assumption 5 holds or Assumption 5 does not hold but μ** = b(μ1 − μ2) ≠ 0 for some b. Therefore, the proof is split into the following three parts: Case (i) Assumption 5 holds; Case (ii) Assumption 5 does not hold but μ** = b(μ1 − μ2) ≠ 0 for some b; Case (iii) neither Case (i) or (ii) holds. As in the proof of part (a), we have


Consider

where DT = VT + cT BB′,

, and VT is defined in the proof of part (a). Because

it follows that


where μ** = Ba in Case (i) and μ** = Bb in Case (ii). It follows from the first-order condition in population: G**′[V−1 − V−1B(B′V−1B)−1BV−1]μ** = 0 that

for Case (iii). Now it can be shown that

where

are defined in Assumption 3. It follows from (A.47), (A.48), and (A.50) that


Combining (A.43)–(A.49), (A.51), and (A.52), we obtain

and

First, consider Cases (i) and (ii). It follows from (A.54) that

Therefore,

It follows from (A.47) that

It follows from (A.51) that

By (A.47) and (A.51) we obtain

Therefore, it follows from (A.56)–(A.59) that

which completes the proof for Cases (i) and (ii).
Next, consider Case (iii). Because

it follows that

By (A.48), (A.52), (A.49), and (A.54), it follows that


Therefore, it follows from (A.61)–(A.65) that

█
References
REFERENCES
Andrews, D.W.K.
(1991)
Heteroscedasticity and autocorrelation consistent covariance matrix
estimation.
Econometrica
59,
817–858.Google Scholar
Andrews, D.W.K.
(1993)
Tests for parameter instability and structural change with unknown
change point.
Econometrica
61,
821–856.Google Scholar
Andrews, D.W.K.
(1999)
Consistent moment selection procedures for generalized method of
moments estimation.
Econometrica
67,
543–564.Google Scholar
Andrews, D.W.K. &
R. Fair
(1988)
Inference in econometric models with structural change.
Review of Economic Studies
55,
615–640.Google Scholar
Gallant, A.R.
(1987)
Nonlinear Statistical Models.
New York:
Wiley.
Gallant, A.R. &
H. White
(1988)
A Unified Theory of Estimation and Inference in Nonlinear Models.
Oxford:
Basil Blackwell.
Ghysels, E.,
A. Guay &
A.R. Hall
(1997)
Predictive test for structural change with unknown breakpoint.
Journal of Econometrics
82,
209–233.Google Scholar
Ghysels, E., &
A.R. Hall
(1990)
A test for structural stability of Euler condition parameters
estimated via the generalized method of moments.
International Economic Review
31,
355–364.Google Scholar
Hall, A.R.
(2000)
Covariance matrix estimation and the power of the overidentifying
restrictions test.
Econometrica
68,
1517–1528.Google Scholar
Hall, A.R., &
A. Inoue
(2003)
The large sample behaviour of the generalized method of moments
estimator in misspelled models.
Journal of Econometrics
114,
361–394.Google Scholar
Hall, A.R., &
A. Sen
(1999)
Structural stability testing in models estimated by generalized
method of moments.
Journal of Business and Economic Statistics
17,
335–348.Google Scholar
Hansen, L.P.
(1982)
Large sample properties of generalized method of moments estimators.
Econometric
50,
1029–1054.Google Scholar
Horn, R.A., &
C.R. Johnson
(1985)
Matrix Analysis.
Cambridge:
Cambridge University Press.
Newey, W.K., &
D.L. McFadden
(1994)
Large sample estimation and hypothesis testing. In
R. Engle and
D.L. McFadden (eds.),
Handbook of Econometrics,
vol. 4, pp.
2113–2247.
Amsterdam:
North-Holland.
Newey, W.K., &
K.D. West
(1987)
A simple positive semi-definite heteroscedasticity and
autocorrelation consistent covariance matrix.
Econometric
55,
703–708.Google Scholar
Pötscher, B.M.
(1983)
Order estimation in ARMA models by Lagrangian multiplier tests.
Annals of Statistics
11,
872–885.Google Scholar
Sowell, F.
(1996)
Optimal tests of parameter variation in the generalized method of
moments framework.
Econometric
64,
1085–1108.Google Scholar
Wooldridge, J.M.
(1994)
Estimation and inference for dependent processes. In
R. Engle and
D.L. McFadden (eds.),
Handbook of Econometrics,
vol. 4, pp.
2641–2739.
Amsterdam:
North-Holland.
 You have
Access
- 7
- Cited by