


1. INTRODUCTION
In this paper we discuss the limiting theory for a novel, unifying class of nonparametric measures of the variation of financial prices. The theory covers commonly used estimators of variation such as realized volatility, but it also encompasses more recently suggested quantities such as realized power variation and realized bipower variation. We considerably strengthen existing results on the latter two quantities, deepening our understanding and unifying their treatment. We will outline the proofs of these theorems, referring for the very technical, detailed formal proofs of the general results to a companion probability theory paper, Barndorff-Nielsen, Graversen, Jacod, Podolskij, and Shephard (2006). Our emphasis is on exposition, explaining where the results come from and how they sit within the econometrics literature.
Our theoretical development is motivated by the advent of complete records of quotes or transaction prices for many financial assets. Although market microstructure effects (e.g., discreteness of prices, bid/ask bounce, irregular trading, etc.) mean that there is a mismatch between asset pricing theory based on semimartingales and the data at very fine time intervals it does suggest the desirability of establishing an asymptotic distribution theory for estimators as we use more and more highly frequent observations. Papers that directly model the impact of market frictions on realized volatility include Zhou (1996), Bandi and Russell (2003), Hansen and Lunde (2006), Zhang, Mykland, and Aït-Sahalia (2005), Barndorff-Nielsen, Hansen, Lunde, and Shephard (2004), and Zhang (2004). Related work in the probability literature on the impact of noise on discretely observed diffusions can be found in Gloter and Jacod (2001a, 2001b), whereas Delattre and Jacod (1997) report results on the impact of rounding on sums of functions of discretely observed diffusions. In this paper we ignore these effects.
Let the d-dimensional vector of the log prices of a set of assets follow the process

At time t ≥ 0 we denote the log prices as Yt. Our aim is to calculate measures of the variation of the price process (e.g., realized volatility) over discrete time intervals (e.g., a day or a month). Without loss of generality we can study the mathematics of this by simply looking at what happens when we have n high-frequency observations on the time interval t = 0 to t = 1 and study our measures of variation as n → ∞. In this case returns will be measured over intervals of length n−1 as

where n is a positive integer.
We will study the behavior of the realized generalized bipower variation process

as n becomes large and where g and h are two given matrix functions of dimensions d1 × d2 and d2 × d3, respectively, whose elements have at most polynomial growth. Here [lfloor ]x[rfloor ] denotes the largest integer less than or equal to x.
Although (2) looks initially rather odd, in fact most of the nonparametric volatility measures used in financial econometrics fall within this class (a measure not included in this setup is the range statistic studied in, e.g., Parkinson, 1980, and its realized version recently introduced by Christensen and Podolskij, 2005, and Martens and van Dijk, 2005). Here we give an extensive list of examples and link them to the existing literature. More detailed discussion of the literature on the properties of these special cases will be given later.
Example 1.
(a) Suppose g(y) = (yj)2 and h(y) = 1; then (2) becomes

which is called the realized quadratic variation process of Yj in econometrics (e.g., Jacod, 1994; Jacod and Protter, 1998; Barndorff-Nielsen and Shephard, 2002, 2004a; Mykland and Zhang, 2006). The increments of this quantity, typically calculated over a day or a week, are often called the realized variances in financial economics. The importance of these increments has been highlighted by Andersen, Bollerslev, Diebold, and Labys (2001) and Andersen, Bollerslev, and Diebold (2006) in the context of volatility measurement and forecasting. See also the survey by Barndorff-Nielsen and Shephard (2006b). Realized variance has a very long history in financial economics. It appears in, for example, Rosenberg (1972), Officer (1973), Merton (1980), French, Schwert, and Stambaugh (1987), Schwert (1989), and Schwert (1998).
(b) Suppose g(y) = yy′ and h(y) = I; then (2) becomes, after some simplification,

This is the realized covariation process. It has been studied by Jacod and Protter (1998), Barndorff-Nielsen and Shephard (2004a), and Mykland and Zhang (2006). Andersen, Bollerslev, Diebold, and Labys (2003) study the increments of this process to produce forecast distributions for vectors of returns.
(c) Suppose g(y) = |yj|r for r > 0 and h(y) = 1; then (2) becomes

which is called the realized rth-order power variation. When r is an integer it has been studied from a probabilistic viewpoint by Jacod (1994), whereas Barndorff-Nielsen and Shephard (2003) look at the econometrics of the case where r > 0. Barndorff-Nielsen and Shephard (2004b) extend this work to the case where there are jumps in Y, showing that the statistic is robust to certain types of jumps when r < 2. Aït-Sahalia and Jacod (2005) have additional insights on that topic. The increments of these types of high-frequency volatility measures have been informally used in the financial econometrics literature for some time when r = 1, but until recently without a strong understanding of their theoretical asymptotic properties. Examples of their use include Schwert (1990), Andersen and Bollerslev (1998), and Andersen and Bollerslev (1997), and they have also been informally discussed by Shiryaev (1999, pp. 349–350) and Maheswaran and Sims (1993). Following the work by Barndorff-Nielsen and Shephard (2003), Ghysels, Santa-Clara, and Valkanov (2004) and Forsberg and Ghysels (2004) have successfully used realized power variation as an input into volatility forecasting competitions.
(d) Suppose g(y) = |yj|r and h(y) = |yj|s for r,s > 0; then (2) becomes
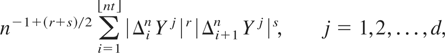
which is called the realized r,sth-order bipower variation process. This measure of variation was introduced by Barndorff-Nielsen and Shephard (2004b), and a more formal discussion of its behavior in the r = s = 1 case was developed by Barndorff-Nielsen and Shephard (2006a). These authors' interest in this quantity was motivated by its virtue of being resistant to finite activity jumps as long as max(r,s) < 2. Recently Barndorff-Nielsen, Shephard, and Winkel (2006) and Woerner (2006) have studied how these results on jumps extend to infinite activity processes, and Corradi and Distaso (2006) have used these statistics to test the specification of parametric volatility models. Here we study these statistics in the case where there are no jumps.
(e) Suppose

Then (2) becomes

Barndorff-Nielsen and Shephard (2006a) used the joint behavior of the increments of these two statistics to test for jumps in price processes. Huang and Tauchen (2005) have empirically studied the finite-sample properties of these types of jump tests. Andersen, Bollerslev, and Diebold (2003) and Forsberg and Ghysels (2004) use bipower variation as an input into volatility forecasting.
We will derive the probability limit of (2) under a general Brownian semimartingale, the workhorse process of modern continuous time asset pricing theory. Only the case of realized quadratic variation (QV), where the limit is the usual QV (defined for general semimartingales), has been previously studied under such wide conditions. Further, under some stronger but realistic conditions, we will derive a limiting distribution theory for (2), thus extending a number of results previously given in the literature on special cases of this framework.
The outline of this paper is as follows. Section 2 contains the main notation used in our analysis. Section 3 gives a statement of a weak law of large numbers for these statistics, and the corresponding central limit theory is presented in Section 4. Extensions of the results to higher order variations are briefly indicated in Sections 5 and 6. Section 7 concludes, and there is an Appendix that provides an outline of the proofs of the results discussed in this paper. For detailed, quite lengthy, and highly technical formal proofs we refer to our companion probability theory paper, Barndorff-Nielsen, Graversen, et al. (2006).
2. NOTATION AND MODELS
We start with Y on some filtered probability space

. In most of our analysis we will assume that Y follows a d-dimensional Brownian semimartingale (written

). It is given in the following statement.
Assumption (H). We have

where W is a d′-dimensional standard Brownian motion, a is a d-dimensional process whose elements are predictable and that has locally bounded sample paths, and the spot covolatility d,d′-dimensional matrix σ has elements that have càdlàg sample paths.
Throughout we will write

the spot covariance matrix. Typically Σt will be full rank, but we do not assume that here. We will write Σtjk to denote the j,kth element of Σt and

Remark 1. Because of the fact that t [map ] σtjk is càdlàg all powers of σtjk are locally integrable with respect to the Lebesgue measure. In particular then

for all t and j.
Remark 2. Both a and σ can have, for example, jumps, intraday seasonality, and long-memory.
Remark 3. The stochastic volatility (e.g., Shephard, 2005) component of Y,

is always a vector of local martingales each with continuous sample paths, as

for all t and j. All continuous local martingales with absolutely continuous quadratic variation can be written in the form of a stochastic volatility process. This result, which is due to Doob (1953), is discussed in, for example, Karatzas and Shreve (1991, pp. 170–172). Using the Dambis–Dubins–Schwartz theorem, we know that the difference between the entire continuous local martingale class and the stochastic volatility class is the local martingales that have only continuous, not absolutely continuous,
1An example of a continuous local martingale that has no SV representation is a time-change Brownian motion where the time change takes the form of the so-called devil's staircase, which is continuous and nondecreasing but not absolutely continuous (see, e.g., Munroe, 1953, Sect. 27). This relates to the work of, for example, Calvet and Fisher (2002) on multifractals.

has elements that are absolutely continuous. This assumption looks ad hoc; however if we impose a lack of arbitrage opportunities and model the local martingale component as a SV process then this property must hold (Karatzas and Shreve, 1998, p. 3; Andersen, Bollerslev, Diebold, and Labys, 2003, p. 583). Hence (3) is a rather canonical model in the finance theory of continuous sample path processes.
3. LAW OF LARGE NUMBERS
To build a weak law of large numbers for Yn(g,h)t we need to make the pair (g,h) satisfy the following assumption.
Assumption (K). All the elements of functions f, g, h, etc. on Rd are continuous with at most polynomial growth.
This amounts to there being suitable constants C > 0 and p ≥ 2 such that

We also need the following notation:

where the expectations are conditional on σ.
Example 2.
(a) Let g(y) = yy′ and h(y) = I; then ρσ(g) = Σ and ρσ(h) = I.
(b) Suppose g(y) = |yj|r; then ρσ(g) = μrσjr, where σj2 is the j,jth element of Σ, μr = E[|u|r], and u ∼ N(0,1).
This setup is sufficient for the proof of Theorem 1.2 of Barndorff-Nielsen, Graversen, et al. (2006), which is restated here.
THEOREM 1. Under Assumption (H) and assuming that g and h satisfy Assumption (K) we have that

where the convergence is also locally uniform in time.
The result is quite clean as it requires no additional assumptions on Y and so is very close to dealing with the whole class of financially coherent continuous sample path processes.
Theorem 1 covers a number of existing setups that are currently receiving a great deal of attention as measures of variation in financial econometrics. Here we briefly discuss some of the work that has studied the limiting behavior of these objects.
Example 3.
(Example 1(a) continued). Then g(y) = (yj)2 and h(y) = 1, so (6) becomes

the QV of Yj. This well-known result in probability theory is behind much of the modern work on realized volatility, which is compactly reviewed in Barndorff-Nielsen and Shephard (2006b).
(Example 1(b) continued). As g(y) = yy′ and h(y) = I, then
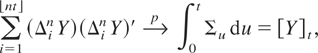
the well-known multivariate version of QV.
(Example 1(c) continued). As g(y) = |yj|r and h(y) = 1 so

This result is due to Jacod (1994) and Barndorff-Nielsen and Shephard (2003).
(Example 1(d) continued). As g(y) = |yj|r and h(y) = |yj|s for r,s > 0, so

a result due to Barndorff-Nielsen and Shephard (2004b), who derived it under stronger conditions than those used here.
(Example 1(e) continued). As

so

Barndorff-Nielsen and Shephard used this type of result to test for jumps as this particular bipower variation is robust to jumps.
4. CENTRAL LIMIT THEOREM
4.1. Further Assumptions on the Process
It is important to be able to quantify the difference between the estimator Yn(g,h) and Y(g,h). In this section we do this by giving a central limit theorem (CLT) for

. We have to make some stronger assumptions both on the process Y and on the pair (g,h) to derive this result.
We start with a variety of assumptions that strengthen Assumptions (H) and (K) given in Sections 2 and 3.
Assumption (H1). We have Assumption (H) with

Here a*, σ*, v* are adapted càdlàg arrays, with a* also being predictable and locally bounded, V is a d′′-dimensional Brownian motion independent of W, μ is a Poisson measure on (0,∞) × E independent of W and V, with intensity measure ν(dt,dx) = dt [otimes ] F(dx), and F is a σ-finite measure on the Polish space

. The term φ is a continuous truncation function on Rdd′ (a function with compact support, which coincides with the identity map on a neighborhood of 0). Finally w(ω,u,x) is a map on Ω × [0,∞) × E into the space of d × d′arrays that is

-measurable in (ω,x) for all u and càdlàg in u, and such that for some sequences (Sk) of stopping times increasing to +∞ we have

Assumption (H2). Σ = σσ′ is everywhere invertible.
Remark 4. If there were no jumps in the volatility then it would be sufficient to employ

which is covered by Assumption (H1). Assumption (H1) is rather general from an econometric viewpoint as it allows for flexible leverage effects, multifactor volatility effects, jumps, nonstationarities, intraday effects, and so on. Indeed we do not know of a continuous time volatility model used in financial economics that is outside this class.
Assumption (H1) looks quite complicated, and one might wonder if a simpler assumption could have been used whose jumps enter through a stochastic integral with a Lévy integrator. However, such a condition is somewhat unsatisfactory because that alternative class of processes is not closed under squaring (further comment on this is given in Section A.2). Hence we have chosen to use Assumption (H1) for it can be applied equally to σ and Σ = σσ′.
4.2. Further Assumptions on g and h
To derive a CLT we need to impose some regularity on g and h.
Assumption (K1). f is even (i.e., f (x) = f (−x) for x ∈ Rd) and continuously differentiable, with derivatives having at most polynomial growth.
To handle some of the most interesting cases of bipower variation, where we are mostly interested in taking low powers of absolute values of returns that may not be differentiable at zero, we sometimes need to relax (K1). The resulting condition is quite technical and is called (K2).
Assumption (K2). f is even and continuously differentiable on the complement Bc of a closed subset

and satisfies

for some constants C, p ≥ 0, and r ∈ (0,1]. Moreover
(a) If r = 1 then B has Lebesgue measure 0.
(b) If r < 1 then B satisfies

and we have

Remark 5. These conditions accommodate the case where f equals |xj|r: this function satisfies Assumption (K1) when r > 1, and Assumption (K2) when r ∈ (0,1] (with the same r of course). When B is a finite union of hyperplanes it satisfies (9). Also, observe that Assumption (K1) implies Assumption (K2) with r = 1 and B = Ø. Assumption (K1) will often be enough to cover many cases of functions with regularly varying properties, as long as they are even, for regularly varying functions are bounded by members of the polynomial at infinity class.
4.3. Main Asymptotic Result
Each of the following assumptions, (J1) and (J2), is sufficient for the statement of Theorem 1.3 of Barndorff-Nielsen, Graversen, et al. (2006) to hold.
Assumption (J1). We have Assumption (H1) and g and h satisfy Assumption (K1).
Assumption (J2). We have Assumptions (H1) and (H2) and g and h satisfy Assumption (K2).
Clearly Assumption (J2) makes stronger assumptions about the volatility process and weaker assumptions about the functions g and h, than Assumption (J1). It is Assumption (J2) that will be used when analyzing the interesting low-power versions of bipower variation.
The result of the theorem is restated in the following.
THEOREM 2. Assume at least one of Assumptions (J1) and (J2) holds; then the process

converges in law stably toward a limiting process U(g,h) having the form

where

Furthermore, B is a standard Wiener process that is defined on an extension of

and is independent of the σ-field

.
Remark 6. The concept and role of stable convergence may be unfamiliar to some readers, and we therefore add some words of explanation. In the simplest case of stable convergence of sequences of random variables, rather than processes, the concise mathematical definition is as follows. Let Xn denote a sequence of random variables defined on a probability space

. Then we say that Xn converges stably in law if there exists a probability measure μ on

(where

denotes the Borel σ-algebra on

) such that for every bounded random variable Z on

and every bounded and continuous function g on

we have that, for n → ∞,

If Xn converges stably in law then, in particular, it converges in distribution (or in law or weak convergence), the limiting law being μ(Ω,·). Accordingly, one says that Xn converges stably to some random variable X if there exists a probability measure μ as before such that X has law μ(Ω,·). This concept and its extension to stable convergence of processes are discussed in Jacod and Shiryaev (2003, pp. 512–518). For earlier expositions, see Hall and Heyde (1980, pp. 56–58) and Jacod (1997). An early use of this concept in econometrics was the work of Phillips and Ouliaris (1990) on the limit distribution of cointegration tests.
However, this formalization does not reveal the key nature of stable convergence, which is that Xn → X stably implies that for any random variable Z, the pair (Z,Xn) converges in law to (Z,X). In the context of the present paper consider the following simple example of the preceding result. Let

Our focus is on

, and our convergence in law stably implies that

Without the convergence in law stably, (12) could not be deduced.
COROLLARY 1. Suppose d3 = 1, which is the situation looked at in Example 1(e). Then Yn(g,h)t is a vector, and so the limiting law of

simplifies. It takes on the form of

where

Here

In particular, for a single point in time t,
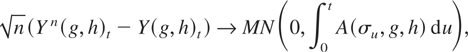
where MN denotes a mixed Gaussian distribution and A(σ,g,h) denotes a matrix whose j,j′th element is A(σ,g,h)j,j′ .
Remark 7. Suppose g(y) = I; then A becomes

Example 4.
Suppose d1 = d2 = d3 = 1; then

where

We consider two concrete examples of this setup.
(i) Power variation. Suppose g(y) = |yj|r and h(y) = 1 where r > 0; then ρσ(h) = 1,

This implies that

where vr = Var(|u|r) and u ∼ N(0,1). When r = 2, this yields a CLT for the realized quadratic variation process, with

a result that appears in Jacod (1994), Mykland and Zhang (2006), and, implicitly, Jacod and Protter (1998), whereas the case of a single value of t appears in Barndorff-Nielsen and Shephard (2002). For the more general case of r > 0 Barndorff-Nielsen and Shephard (2003) derived, under much stronger conditions, a CLT for U(g,h)1. Their result ruled out leverage effects, which are allowed under Theorem 2. The finite-sample behavior of this type of limit theory is studied in, for example, Barndorff-Nielsen and Shephard (2005), Goncalves and Meddahi (2004), and Nielsen and Frederiksen (2005).
(ii) Bipower variation. Suppose g(y) = |yj|r and h(y) = |yj|s where r,s > 0; then

This implies that

In the r = s = 1 case Barndorff-Nielsen and Shephard (2006a) derived, under much stronger conditions, a CLT for U(g,h)1. Their result ruled out leverage effects, which are allowed under Theorem 2. In that special case, writing

we have

In the case where r = ε, s = 2 − ε where 2 > ε > 0 then

, and the statistic is asymptotically robust to finite activity jumps (Barndorff-Nielsen and Shephard, 2004b). For arbitrarily small ε the error process U(g,h)t is close to (15), so this jump robust process is basically as efficient as if there are no jumps in the process.
Example 5.
Suppose g(y) = yy′, h = I. Then we have to calculate

However,

so

This is the result found in Barndorff-Nielsen and Shephard (2004a) but proved there under stronger conditions. The result is, in fact, implicit in the work of Jacod and Protter (1998).
Example 6.
Suppose d1 = d2 = 2, d3 = 1, and g is diagonal. Then

where

Here

Example 7.
Joint behavior of realized QV and realized bipower variation. This sets

The implication is that

Thus

whereas

and

This generalizes the result given in Barndorff-Nielsen and Shephard (2006a) to the leverage case. In particular we have that

5. MULTIPOWER VARIATION
A natural extension of generalized bipower variation is to generalized multipower variation,

where a ∧ b denotes the minimum of a and b. This measure of variation, for the gi′ being absolute powers, was introduced by Barndorff-Nielsen and Shephard (2006a).
We will be interested in studying the properties of Yn(g)t for given functions {gi} with the following properties.
Assumption (K*). All the {gi} are continuous with at most polynomial growth.
The previous results suggest that if Y is a Brownian semimartingale and Assumption (K*) holds, then

See Barndorff-Nielsen, Graversen, et al. (2006) for more details.
Example 8.
(a) Suppose I = 4 and gi(y) = |yj|; then ρσ(gi) = μ1σj so

a scaled version of integrated quarticity.
(b) Suppose I = 3 and gi(y) = |yj|4/3; then

so

Example 9.
Of some importance is the generic case where gi(y) = |yj|2/I, which implies

Thus this class provides an interesting alternative to realized variance as an estimator of integrated variance. Of course it is important to know a central limit theory for these types of quantities. Barndorff-Nielsen, Graverson, et al. (2006) show that when Assumptions (H1) and (H2) hold then

where

with ui ∼ NID(0,1). Thus the asymptotic variance is again a scaled version of integrated quarticity. Clearly ω12 = 2, while recalling that

,

6. SUMS OF REALIZED GENERALIZED BIPOWER
The law of large numbers and the CLT also hold for linear combinations of processes like Y(g) in the preceding discussion.
Example 10.
Let ζin denote the d × d matrix whose (k,l) entry is

. Then

is a linear combination of processes Yn(g) for functions gl being of the form gl(y) = yjyk. It is proved in Jacod, Lejay, and Talay (2005) that under Assumption (H)

whereas under Assumptions (H1) and (H2) the associated CLT is the following convergence in law:

where Γ(σ) denotes the covariance of the variable det(ζ)/d! and ζ is a d × d matrix whose (k,l) entry is

and the Uj's are independent and identically distributed (i.i.d.) centered Gaussian vectors with covariance σσ′.
This kind of result may be used for testing whether the rank of the diffusion coefficient is everywhere smaller than d. In that case one could use a model with a d′ < d for the dimension of the driving Wiener process W.
7. CONCLUSION
This paper provides some rather general limit results for realized generalized bipower variation. In the case of power variation and bipower variation the results are proved under much weaker assumptions than those that have previously appeared in the literature. In particular the no-leverage assumption is removed, which is important in the application of these results to stock data.
There are a number of open questions. It is rather unclear how econometricians might exploit the generality of the g and h functions to learn about interesting features of the variation of price processes. It would be interesting to know what properties g and h must possess for these statistics to be robust to finite activity and infinite activity jumps.
It would be attractive to extend the analysis to allow g and h to depend upon the entire path of Y, not just returns, and to depend upon n. This would allow, respectively, the theory to additionally cover the realized range process studied by Christensen and Podolskij (2005) and the truncated estimator studied by Mancini (2004) and more recently by Aït-Sahalia and Jacod (2005).
A challenging extension is to construct a version of realized generalized bipower variation that is robust to market frictions. Following the work on the realized volatility there are two strategies that may be able to help: the kernel-based approach, studied in detail by Barndorff-Nielsen et al. (2004), and the subsampling approach of Zhang, Mykland, and Aït-Sahalia (2005) and Zhang (2004). In the realized volatility case these methods are basically equivalent; however it is perhaps the case that the subsampling method is easier to extend to the nonquadratic case. Further insights into the choice of n may be possible using mean square error–based optimal sampling developed by Bandi and Russell (2003) and Hansen and Lunde (2006) for realized variance.
APPENDIX: Techniques for the Proof of Theorem 2
A.1. Notational Conventions.
Here we give a fairly detailed account of the basic techniques in the proof of Theorem 2, in the one-dimensional case and under some relatively minor simplifying assumptions. Throughout we set h = 1, for the main difficulty in the proof is being able to deal with the generality in the g function. Once that has been mastered the extension to the bipower measure is not a large obstacle. We refer readers who wish to see the more general case to Barndorff-Nielsen, Graversen, et al. (2006). The outline of this section is as follows. First we introduce our basic notation, and in Section A.2 we set out the model and review the assumptions we use. In Section A.3 we state the theorem we will prove and outline the steps in the proof. Sections A.5, A.6, and A.7 give the proofs of the successive steps.
All processes mentioned in the following discussion are defined on a given filtered probability space

. We shall in general use standard notation and conventions. For instance, given a process (Zt) we write [utri ]inZ := Zi/n − Z(i−1)/n, i,n ≥ 1.
All results will be proved using convergence “stably in law” of sequences of càdlàg processes, which is a slightly stronger notion than convergence in law (cf. Remark 6). For this we shall use the notation

where (Ztn) and (Zt) are given càdlàg processes. Furthermore we shall write

Often

where the ain's are

-measurable. Recall here that given càdlàg processes (Ztn), (Ytn), and (Zt) we have

Moreover, for h : R → R Borel measurable of at most polynomial growth we note that x [map ] ρx(h) is locally bounded and continuous if h is continuous at 0.
In what follows many arguments will consist of a series of estimates of terms indexed by i, n, and t. In these estimates we shall denote by C a finite constant that may vary from place to place. Its value will depend on the constants and quantities appearing in the assumptions of the model, but it is always independent of i, n, and t.
A.2. Model and Basic Assumptions.
Throughout the following discussion (Wt) denotes a

-Wiener process and (σt) a given càdlàg

-adapted process. Define the local martingale

We have deleted the drift of the (Yt) process as taking care of it is a simple technical task, whereas its presence increases the clutter of the notation. Our aim is to study the asymptotic behavior of the processes

where

Here g : R → R is a given continuous function of at most polynomial growth. We are especially interested in g's of the form x [map ] |x|r (r > 0), but we shall keep the general notation because nothing is gained in simplicity by assuming that g is of power form. Throughout the following we shall assume that g furthermore satisfies the following assumptions.
Assumption (Ka). g is an even function and continuously differentiable in Bc where B ⊆ R is a closed Lebesgue null set and ∃ M, p ≥ 1 such that

for all x,y ∈ R.
Remark 8. Assumption (Ka) implies, in particular, that if x ∈ Bc then

Observe that only power functions corresponding to r ≥ 1 do satisfy Assumption (Ka). The remaining case 0 < r < 1 requires special arguments that will be omitted here (for details, see Barndorff-Nielsen, Graversen, et al., 2006).
To prove the central limit theorem we need some additional structure on the volatility process (σt). A natural set of assumptions follows.
Assumption (H0). (σt) can be written as

where (Zt) is a

-Lévy process independent of (Wt) and (σt*) and (vt*) are adapted càdlàg processes and (at*) a predictable locally bounded process.
However, in modeling volatility it is often more natural to define (σt2) as being of the preceding form, that is,

Now this does not in general imply that (σt) has the same form; therefore we shall replace Assumption (H0) by the more general structure given by the following assumption.
Assumption (H1′). (σt) can be written, for t ≥ 0, as

Here (at*),(σt*), and (vt*), are as in Assumption (H0) and (Vt) is another

-Wiener process independent of (Wt), whereas q is a continuous truncation function on R, that is, a function with compact support coinciding with the identity on a neighborhood of 0. Further, μ is a Poisson random measure on (0,∞) × E independent of (Wt) and (Vt) and with intensity measure ν(ds dx) = ds [otimes ] F(dx), F being a σ-finite measure on a measurable space

, and

is a map from Ω × [0,∞) × E into R that is

measurable in (ω,x) for all s and càdlàg in s, satisfying furthermore that for some sequence of stopping times (Sk) increasing to +∞ we have for all k ≥ 1

where

Remark 9. Assumption (H1′) is weaker than Assumption (H0), and if (σt2) satisfies Assumption (H1′) then so does (σt).
Finally we shall also assume nondegeneracy in the model.
Assumption (H2′). (σt) satisfies 0 < σt2(ω) for all (t,ω).
According to general stochastic analysis theory it is known that to prove convergence in law of a sequence (Ztn) of càdlàg processes it suffices to prove the convergence of each of the stopped processes (ZTk∧tn) for at least one sequence of stopping times (Tk) increasing to +∞. Applying this together with standard localization techniques (for details, see Barndorff-Nielsen, Graversen, et al., 2006), we may assume that the following more restrictive assumptions are satisfied.
Assumption (H1a). (σt) can be written as

Here (at*), (σt*), and (vt*) are real valued uniformly bounded càdlàg

-adapted processes; (Vt) is another

-Wiener process independent of (Wt). Further, μ is a Poisson random measure on (0,∞) × E independent of (Wt) and (Vt) with intensity measure ν(ds dx) = ds [otimes ] F(dx), F being a σ-finite measure on a measurable space

, and

is a map from Ω × [0,∞) × E into R that is

measurable in (ω,x) for all s and càdlàg in s, satisfying furthermore

Likewise, by a localization argument, we may make the following assumption.
Assumption (H2a). (σt) satisfies a < σt2(ω) < b for all (t,ω) for some a,b ∈ (0,∞).
Observe that under the more restricted assumptions (Yt) is a continuous martingale having moments of all orders and (σt) is represented as a sum of three square integrable martingales plus a continuous process of bounded variation. Furthermore, the increments of the increasing processes corresponding to the three martingales and of the bounded variation process are dominated by a constant times [utri ]t, implying in particular that

We use ϒ(x) as shorthand for ρx(g). Observe that the assumptions on g imply that x [map ] ϒ(x) is differentiable with a bounded derivative on any bounded interval not including 0; in particular (see Assumption (H2a))
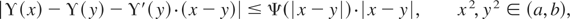
where Ψ : R+ → R+ is continuous and increasing and Ψ(0) = 0.
A.3. Main Result.
As already mentioned, our aim is to show the following special version of the general CLT result given as Theorem 2.
THEOREM 3. Under Assumptions (Ka), (H1a), and (H2a), there exists a Wiener process (Bt) defined on some extension of

and independent of

such that

where B is a Brownian motion independent of the process Y and the convergence is (stably) in law.
The first step is to rewrite the left-hand side of (A.3) as follows:

It is relatively simple to show that the first term of the right-hand side satisfies

Hence what remains is to verify that uniformly

We have

where, uniformly

The first term on the right-hand side of (A.5) is now split into the difference of

where

and

It is rather easy to show that (A.6) tends to 0 in probability uniformly in t. The challenge is thus to show that the same result holds for (A.7).
To handle (A.7) one splits the individual terms in the sum into

plus

where ϒ(x) is shorthand for ρx(g) and ϒ′(x) denotes the derivative with respect to x. That (A.9) tends to 0 may be shown via splitting it into two terms, each of which tends to 0 as is verified by a sequence of inequalities, using in particular Doob's inequality. To prove that (A.8) converges to 0, again one splits, this time into three terms, using the differentiability of g in the relevant regions and the mean value theorem for differentiable functions. The first two of these terms can be handled by relatively simple means; the third poses the most difficult part of the whole proof and is treated via splitting it into seven parts. It is at this stage that the assumption that g is even comes into play and is crucial.
A.4. Details of the Proof.
Introducing the notation

we may reexpress (A.3) as

To prove this, introduce the set of variables {βin|i, n ≥ 1} given by

The βin's should be seen as approximations to

. In fact, because

and (σt) is uniformly bounded, a straightforward application of (A.1) and the Burkholder–Davis–Gundy inequalities (e.g., Revuz and Yor, 1999, pp. 160–171) gives for every p > 0 the following simple estimates:

and

for all i,n ≥ 1. Observe furthermore that

Introduce for convenience, for each t > 0 and n ≥ 1, the shorthand notation

The asymptotic behavior of (Utn(g)) is well known. More precisely under the given assumptions (in fact much less is needed) we have

This result is a rather straightforward consequence of Jacod and Shiryaev (2003, Thm. IX.7.28). Thus, if

we may deduce the following result.
THEOREM 4. Let (Bt) and (Ut(g)) be as before. Then

Proof of Theorem 4. As pointed out just before it is enough to prove that

But for t ≥ 0 and n ≥ 1

where

Thus we have to prove

But, as the left-hand side of this relation is a sum of martingale differences, this is implied by Doob's inequality (e.g., Revuz and Yor, 1999, pp. 54–55) if for all t > 0

Fix t > 0. Using the Cauchy–Schwarz, Burkholder–Davis–Gundy, and Jensen inequalities we have for all i,n ≥ 1.

Thus by means of Jensen inequality and the boundedness of (σt)

which tends to 0 as n → ∞, by Lebesgue's theorem and the boundedness of (σt). █
To prove the convergence (A.10) it suffices, using Theorem 4, to prove that

But as

and, as is easily seen,

the job is to prove that

where for i,n ≥ 1

Fix t > 0 and write, for all i,n ≥ 1,

where

and

We will now separately prove

and

A.5. Some Auxiliary Estimates.
To show (A.15) and (A.16) we need some refinements of the estimate (A.1). To state these we split up

into several terms. By definition

for all i,n ≥ 1. Writing

the difference σu − σ(i−1)/n equals

for i,n ≥ 1 and u ≥ (i − 1)/n where

That is, for i,n ≥ 1,

where

The specific form of the variables implies, using Burkholder–Davis–Gundy inequalities, that for every q ≥ 2 we have

for all i,n ≥ 1 and all j. These terms will now be estimated. This is done in the following series of lemmas where i and n are arbitrary and we use the notation

LEMMA 1.

LEMMA 2.

LEMMA 3.

where

LEMMA 4.

LEMMA 5.

The proofs of these five lemmas rely on straightforward martingale inequalities.
Observe that Lebesgue's theorem ensures, because the processes involved are assumed càdlàg and uniformly bounded, that as n → ∞

Taken together these statements imply the following result.
COROLLARY 2. For all t > 0 as n → ∞

Subsequently we shall invoke this corollary in addition to Lemmas 2 and 5.
A.6. Proof of
 .

Recall that we wish to show that

From now on let t > 0 be fixed. We split the η(2)in's according to

where, writing ϒ(x) for ρx(g),

and

With this notation we shall prove (A.18) by showing

Inserting the description of (σt) (see Assumption (H1a)) we may write

where for all i,n ≥ 1

By Assumption (H2a) and (A.2) and the uniform boundedness of (at*) we have

for all i,n ≥ 1 and thus

Because

are all martingales we have

By Doob's inequality it is therefore feasible to estimate

Inserting again the description of (σt) we find, applying simple inequalities, in particular Jensen's, that

The properties of the Wiener integrals and the uniform boundedness of (σt*) and (vt*) ensure that

and likewise

for all i,n ≥ 1. Likewise for the Poisson part we have

yielding a similar bound. Putting all this together we have for all i,n ≥ 1

Thus as n → ∞ so

and because

we deduce from Doob's inequality that

proving altogether

Applying once more Assumption (H2a) and (A.2) we have for every ε > 0 and every i,n that

Thus from (A.1) and its consequence

we get

for all n and all ε. Letting here first n → ∞ and then ε → 0 we may conclude that as n → ∞

implying the convergence

and thus ending the proof of (A.16). █
A.7. Proof of
.

Recall that we are to show that

Let t > 0 still be fixed. Recall that

Introduce the notation (recall Assumption (K2))

Because B is a Lebesgue null set and βin is absolutely continuous, g′(βin) is defined a.s., and, by assumption, g is differentiable on the interval joining [utri ]inY(ω) and βin(ω) for all ω ∈ Ainc. Thus, using the mean value theorem, we may for all i,n ≥ 1 write

where αin are random points lying in between

, that is,

Thus it suffices to prove

Consider the case k = 1. Using Assumption (Ka) and the fact that βin is absolutely continuous we have a.s.

By Cauchy–Schwarz's inequality E[|δ(1)in|] is therefore for all i,n ≥ 1 less than

implying for fixed t, by means of (A.4), that

For all i,n ≥ 1 we have for every ε > 0

But Assumption (H2a) implies that the densities of βin are pointwise dominated by a Lebesgue integrable function ha,b providing, for all i,n ≥ 1, the estimate

Observe limε→0 αε = 0. Taking now in (A.20) sup over i and then first letting n → ∞ and then ε ↓ 0 we get

proving that

and thus

Consider next the case k = 2. As assumed in Assumption (Ka), g is continuously differentiable outside of B. Thus for each A > 1 and ε > 0 there exists a function GA,ε : (0,1) → R+ such that for given 0 < ε′ < ε/2

Observe that limε′↓0 GA,ε(ε′) = 0 for all A and ε. Fix A > 1 and ε ∈ (0,1). For all i,n ≥ 1 we have

Now writing

for all 0 < ε′ < ε/2 we have

Combining this with the fact that

on Ainc ∩ {|αin| + |βin| ≤ A} we obtain that

Putting this together means that

Exploiting here the inequalities (A.11) and (A.12) we obtain, for all A > 1 and 0 < 2ε′ < ε < 1 and all i,n ≥ 1, using Hölder's inequality, the following estimate:

implying for all n ≥ 1 and t ≥ 0 that

Choosing in this estimate first A sufficiently big, then ε small (recall that limε→0 αε = 0), and finally ε′ small, exploiting that limε′↓0 GA,ε(ε′) = 0 for all A and ε, we may conclude that

and thus

So what remains to be proved is the convergence

As introduced in (A.17)

for all i,n ≥ 1 where

and as

it suffices to prove

The case k = 1 is handled by proving

Using Jensen's inequality it is easily seen that for j = 1,3,4

and so using (A.12)

because almost surely

for all i,n ≥ 1. From here, (A.21) is an immediate consequence of Lemmas 1, 3, and 4.
The remaining case k = 2 is different. The definition of ψ(2)in implies, using basic stochastic calculus, that

, for all i,n ≥ 1, may be written as

where (M(n,i)t) is the martingale defined by M(n,i)t ≡ 0 for t ≤ (i − 1)/n and

otherwise. Thus for fixed i,n ≥ 1

is a linear combination of the following three terms:

But these three terms are all equal to 0 as seen by the following arguments.
The conditional distribution of

is clearly not affected by a change of sign. Thus because g is being assumed even and g′ therefore odd we have

implying the vanishing of the first term.
Second, by assumption, (Wt − W(i−1)/n)t≥(i−1)/n and (M(n,i)t)t≥(i−1)/n are independent given

. Therefore, denoting by

the σ-field generated by

the martingale property of (M(n,i)t) ensures that

Using this the vanishing of

is easily obtained by successive conditioning.
The proof of (A.15) is hereby completed. █


