


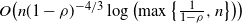

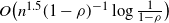
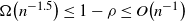

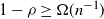

1. Introduction
An  $n\times n$ input-queued switch is a discrete-time queueing network that consists of
 $n^2$ queues, which are arranged in the form of an
 $n\times n$ matrix. Packets arrive to these
 $n^2$ queues exogenously according to independent Bernoulli processes. In each time slot, packets are processed according to schedules, subject to the following constraints: at most one queue can be served from each row and each column, and when a queue is chosen to be served, at most one packet can be processed. After the packets are processed, they immediately depart the system. The main goal is to design a scheduling policy that decides which queues to serve in each time slot, in order to optimize certain performance measures.
The input-queued switch plays a pivotal role in the study of data packet scheduling in an internet router [Reference McKeown, Anantharam and Walrand17] and more recently in a data center network [Reference Alizadeh2, Reference Chowdhury, Zhong and Stoica3, Reference Perry19]. It also serves as a prominent example of a ‘stochastic processing network’ (SPN) [Reference Harrison10], which is a canonical model of dynamic resource allocation problems arising in a wide range of applications. The study of the switch has paved the way towards a better understanding of more general SPNs; indeed, insights generated from policy design and performance analysis in a switch often extend to broader classes of SPNs [Reference Lin and Dai15, Reference McKeown, Anantharam and Walrand17, Reference Shah, Walton and Zhong25, Reference Stolyar28, Reference Tassiulas and Ephremides29].
Even though basic performance measures, such as throughput and stability, are relatively well understood for switches (and for general SPNs) (see e.g. [Reference Dai and Prabhakar6, Reference De Veciana, Lee and Konstantopoulos7, Reference Kelly and Williams12, Reference Keslassy and McKeown13, Reference Lin and Dai15, Reference McKeown, Anantharam and Walrand17, Reference Tassiulas and Ephremides29]), there is a wide gap in our understanding of more refined performance measures, such as moments of queue sizes. In this paper, we reduce this gap by designing new scheduling policies that achieve tighter bounds on the expected total queue size in switches. Our study is motivated by [Reference Shah, Tsitsiklis and Zhong23], which stated the conjecture that the expected total queue size scales as  $\Theta (\frac{n}{1-\rho})$ in an
 $n\times n$ switch, where
 $\rho \in (0,1)$ is the load factor and equals the largest total arrival rate to each row/column of the switch. (This paper makes extensive use of asymptotic notation. For completeness and easy reference, definitions are provided in Section 1.2).
It can be easily seen that  $\Omega (\frac{n}{1-\rho})$ is a lower bound on the expected total queue size, over all n and
 $\rho$ (see e.g. [Reference Shah, Tsitsiklis and Zhong23]). However, matching upper bounds have only been established for restricted parameter regimes. [Reference Neely, Modiano and Cheng18] proposed a batching policy under which the expected total queue size is bounded above by
 $O\Big(\frac{n\log n}{(1-\rho)^2}\Big)$, so that when
 $\rho \in (0, 1)$ is treated as a constant, this upper bound matches the lower bound up to a factor logarithmic in n. [Reference Shah, Walton and Zhong25] proposed a policy under which the switch emulates a product-form queueing network, and established an upper bound of
 $O\Big(\frac{n}{1-\rho}+n^3\Big)$, which matches the lower bound up to a constant factor when
 $1-\rho = O\big(n^{-2}\big)$. More recently, a significant work [Reference Maguluri and Srikant16] shows that the celebrated Max-Weight policy achieves an upper bound of
 $O\Big(\frac{n}{1-\rho} + \frac{n^{5-1/r}}{(1-\rho)^{1/r}}\Big)$ for any integer-valued
 $r \geq 2$, for systems with uniform arrival rates, which matches the lower bound up to a constant factor when
 $1-\rho = O(n^{-a})$ for any
 $a > 4$. Let us also note that using a simple Lyapunov function argument, it can be shown that the Max-Weight policy achieves an upper bound of
 $O\Big(\frac{n^2}{1-\rho}\Big)$ (see e.g. [Reference McKeown, Anantharam and Walrand17, Reference Shah and Kopikare22, Reference Shah, Tsitsiklis and Zhong23, Reference Tassiulas and Ephremides29]).
Observe that when  $1-\rho = \Theta(n^{-1})$, the conjectured scaling is
 $\Theta(n^2)$, whereas all of the aforementioned upper bounds are at least a multiplicative factor O(n) away. Motivated by this observation, [Reference Shah, Tsitsiklis and Zhong24] considered the regime where
 $1-\rho \leq O\big(n^{-1}\big)$, and proposed a scheduling policy that gives an upper bound of
 $O\Big(n^{1.5}(1-\rho)^{-1} \log \frac{1}{1-\rho}\Big)$, for systems with uniform arrival rates. When
 $1-\rho = \Theta(n^{-1})$, this upper bound becomes
 $O\big(n^{2.5}\log n\big)$, a multiplicative factor of
 $O\big(n^{0.5}\log n\big)$ away from the conjectured scaling. While this was a significant improvement, the answer to whether this gap can be further reduced remains elusive.
The main contribution of this paper is a new class of policies that achieves an upper bound of  $O\big(n (1-\rho)^{-4/3} \log (\!\max\{n, 1/(1-\rho)\})\big)$ uniformly over all n and
 $\rho < 1$, when the arrival rates are equal. When
 $\Omega(n^{-1.5}) \le 1-\rho \le O\big(n^{-1}\big)$, this upper bound improves on the best previously known scaling
 $O\big(n^{1.5}(1-\rho)^{-1} \log \frac{1}{1-\rho}\big)$ [Reference Shah, Tsitsiklis and Zhong24]. In particular, when
 $1-\rho = \Theta(n^{-1} )$, our upper bound reduces to
 $O\big(n^{7/3} \log n\big)$, an improvement over the best previously known scaling
 $O\big(n^{2.5}\log n\big)$. When
 $1-\rho \geq \Omega(n^{-1})$, our upper bound improves on the best previously known scaling
 $O\Big(\frac{n\log n}{(1-\rho)^2}\Big)$ [Reference Neely, Modiano and Cheng18]. Finally, we would also like to point out that besides the upper bound
 $O\Big(\frac{n\log n}{(1-\rho)^2}\Big)$ in [Reference Neely, Modiano and Cheng18], ours is the only other upper bound that scales almost linearly in n, the system scale, for any fixed value of
 $\rho \in (0, 1)$. See Table 1 for a summary of the best known scalings on the expected total queue size under various regimes.
Best known scalings of the expected total queue size in various regimes. Here,  $\rho$ is the load factor, and n is the system scale.

Like the policy in [Reference Shah, Tsitsiklis and Zhong24], our policy is a variation of the standard batching policy. In the standard batching policy, time is divided into consecutive intervals (or batches) of equal lengths, and packets that arrive in a given batch are only served after the end of the batch. By optimizing the length of a batch, [Reference Neely, Modiano and Cheng18] proposed a standard batching policy that achieves  $O\Big(\frac{n\log n}{(1-\rho)^2}\Big)$ expected total queue size. Both our policy and the one in [Reference Shah, Tsitsiklis and Zhong24] improved this scaling (in different regimes) by starting to serve packets of a given batch much earlier than the end of that batch. In the regime
 $\Omega(n^{-1.5}) \le 1-\rho \le O\big(n^{-1}\big)$, our policy starts to serve packets even earlier than the policy in [Reference Shah, Tsitsiklis and Zhong24], resulting in improved queue size scaling. For more detailed comparisons of our policy, the one in [Reference Shah, Tsitsiklis and Zhong24], and the standard batching policy in [Reference Neely, Modiano and Cheng18], see Sections 3.2 and 6.
In order to start service early, both our policy and the one in [Reference Shah, Tsitsiklis and Zhong24] need to adapt to changes in system state at a time scale much shorter than the batch length. Since our policy starts service even earlier than the one in [Reference Shah, Tsitsiklis and Zhong24], in the regime  $\Omega(n^{-1.5}) \le 1-\rho \le O\big(n^{-1}\big)$, our policy needs to be more adaptive. This introduces substantial challenges in policy design and analysis. To overcome these challenges, our policy implements an efficient scheduling mechanism which depletes the packets in the
 $n^2$ queues as much as possible without any waste of service opportunities. Mathematically, this can be formulated as an integer linear optimization problem: call a matrix
 $\textbf{\textit{q}}=(q_{ij})_{i,j=1}^n$ with nonnegative integer entries a queue matrix; given
 $\textbf{\textit{q}}$, find the maximum integer k and a queue matrix
 $\textbf{\textit{g}}=(g_{ij})_{i,j=1}^n$ such that
 $\sum_{i} g_{ij}=\sum_{j} g_{ij}=k$ and
 $0 \le g_{ij} \le q_{ij}$. Such
 $\textbf{\textit{g}}$ can then be written as the sum of k maximal schedules, which can be used to deplete the
 $n^2$ queue sizes of
 $\textbf{\textit{q}}$. By representing the rows as left vertices of a bipartite (multi)graph, and the columns as right vertices, the queue size
 $q_{ij}$ can be viewed as the number of edges between left vertex i and right vertex j. From this perspective, the optimization problem is equivalent to finding the largest k-factor (spanning k-regular subgraph) in a bipartite (multi)graph G. Under the Bernoulli arrival assumption, the queue sizes
 $q_{ij}$ are independently and binomially distributed for some common parameters m and p. We show that if
 $pmn \ge 152 \log n$, then G has a k-factor with
 $k=\lfloor pmn- \sqrt{304pmn\log n} \rfloor $ with probability
 $1-n^{-16}$. This result is new, and essentially tight: for example, when G is an Erdős–Rényi bipartite simple graph, i.e., when
 $m=1$, then the condition
 $np=\omega(\!\log n)$ implies that G has a k-factor with
 $k = np - \Theta(\sqrt{np \log n})$, which is asymptotically the best possible, because the minimum degree of G is asymptotically equal to
 $np-\Theta(\sqrt{np \log n})$ with high probability.
We point out that there is a vast literature on graph factors and factorization (see the survey [Reference Plummer20] and the book [Reference Akiyama and Kano1] and the references therein). Most previous work focuses on deriving sufficient conditions for the existence of a k-factor for worst-case possible graphs G. For instance, Csaba [Reference Csaba5] showed that for any bipartite simple graph G with n left and n right vertices, if the minimum degree  $\delta n$ is at least
 $n/2$, then G has a k-factor with
 $k=\lfloor n \frac{\delta+\sqrt{2\delta-1}}{2}\rfloor$. Applying this result to an Erdős–Rényi bipartite simple graph, we can only conclude with high probability the existence of a k-factor with
 $k \sim n \frac{p+\sqrt{2p-1}}{2}$, which is suboptimal when compared to our result.
Random graph factorization was studied earlier in Shamir and Upfal [Reference Shamir and Upfal26]. It was shown that for an Erdős–Rényi random graph G, if the average degree np satisfies  $np-\log n - (k-1) \log \log n \to +\infty$ for a fixed
 $k \ge 1$, then G has a k-factor with probability converging to 1. However, this result only holds for a fixed k and does not provide the largest possible value of k in the dense graph regime where
 $np=\omega(\!\log n)$. A related random capacitated transportation problem was studied in [Reference Hassin and Zemel11], where we observe an
 $n\times n$ capacity matrix
 $C=(c_{ij})$ with random
 $c_{ij}$ and aim to find a matrix
 $X=(x_{ij})$ with the row sums and column sums as large as possible under the constraint that
 $0 \le x_{ij} \le c_{ij}$. The general result of [Reference Hassin and Zemel11] allows for
 $c_{ij}$ not to be independent or identically distributed. In the special case where
 $c_{ij}$ is Bernoulli with the success probability p, their result implies that with high probability an Erdős–Rényi random bipartite graph G has k-factor with
 $k \sim n^{1/3}$, which is much smaller than np for large n and hence highly suboptimal.
Before proceeding, let us make two remarks regarding the proposed policy and its performance scaling. First, our policy and current analysis rely crucially on the assumption of uniform arrival rates, while some existing policies and results, such as the standard batching policy [Reference Neely, Modiano and Cheng18] and the Max-Weight policy [Reference McKeown, Anantharam and Walrand17], apply to heterogeneous arrival rates. Second, our policy requires knowledge of the arrival rates a priori. In contrast, some existing policies, such as the Max-Weight policy, are based solely on the observed queue sizes.
1.1. Organization
The rest of the paper is organized as follows. The model is formally introduced in Section 2. We present our main result and an overview of the policy in Section 3. Section 4 summarizes a few important preliminary results to be used for later parts of the paper. Section 5 introduces the concept of a lower envelope of a queue matrix and provides a characterization of the tightest lower envelope of a random queue matrix, or equivalently, the largest k-factor of a random bipartite multigraph. In Section 6 we formally describe our policy, and in Section 7 we prove the main result. We conclude the paper with some discussion in Section 8.
1.2. Notation
We reserve boldface letters for vectors and matrices, plain and lowercase letters for deterministic scalars, and uppercase letters for random quantities. We also reserve script letters, such as  $\mathcal{S}$,
 $\mathcal{E}$, etc., for sets and/or events. For a set
 $\mathcal{S}$, we use
 $\mathcal{S}^c$ to denote the complement of
 $\mathcal{S}$, and
 $|\mathcal{S}|$ to denote the cardinality of
 $\mathcal{S}$. The indicator function of a set
 $\mathcal{S}$ is denoted by
 $\boldsymbol{1}_{\mathcal{S}}$. We use
 $\mathbb{N}$ to denote the set
 $\{1, 2, \cdots\}$ of natural numbers,
 $\mathbb{Z}$ to denote the set of integers, and
 $\mathbb{Z}_+$ to denote the set
 $\{0, 1, 2, \cdots\}$ of nonnegative integers. For
 $n \in \mathbb{N}$, we use [n] to denote the set
 $\{1, 2, \cdots, n\}$. For two real numbers x and y, we use
 $x \vee y = \max\{x, y\}$ to denote the larger of x and y. For a real number x, we use
 $(x)^+ = x\vee 0$ to denote the nonnegative part of x. The shorthand i.i.d. means ‘independently and identically distributed’, WLOG means ‘without loss of generality’, LHS means ‘left-hand side’, and RHS means ‘right-hand side’. We say a sequence of events
 $\mathcal{E}_n$ indexed by a positive integer n holds with high probability if the probability of
 $\mathcal{E}_n$ converges to 1 as
 $n \to +\infty$. We also note that notation in this paper will be made as consistent with that in [Reference Shah, Tsitsiklis and Zhong24] as possible.
Let us now provide definitions for some asymptotic notation used in this paper. Consider a positive parameter  $r > 0$, and let g(r) and f(r) be two functions of r that take positive real values. Then
 $f(r) = O(g(r))$ if
 $\limsup_{r\to\infty} f(r)/g(r) < \infty$,
 $f(r)=\Omega(g(r))$ if
 $\liminf_{r\to\infty} f(r)/g(r) > 0$,
 $f(r) = \omega(g(r))$ if
 $\liminf_{r\to\infty} f(r)/g(r) = \infty$, and
 $f(r) = \Theta(g(r))$ if
 $f(r) = O(g(r))$ and
 $f(r) = \Omega(g(r))$. In our applications, the asymptotic relations may often appear to involve two parameters, such as the case of
 $O\big(n(1-\rho)^{-1}\big)$, where n and
 $\rho$ are parameters. In these cases, simply treat the function of these two parameters as a single parameter; i.e., let
 $r = n(1-\rho)^{-1}$, and the asymptotic notation is well-defined.
2. Input-queued switch model
Here we only provide a mathematical description of the model; see e.g. [Reference McKeown, Anantharam and Walrand17] for more details on the physical architecture. Abstractly, an  $n\times n$ input-queued switch consists of
 $n^2$ queues, indexed by the pair (i, j), where
 $i, j \in [n]$. In this paper, the first coordinate i of the pair (i, j) is called an input, the second coordinate j an output, and n is often referred to as the system scale of the switch. The system operates in discrete time, indexed by
 $\tau \in \mathbb{N}$. For each i and j, packets arrive in queue (i, j) according to some exogenous process. Let
 $A_{ij}(\tau)$ denote the cumulative number of arrivals to queue (i, j) in time slots 1 through
 $\tau$. Similar to [Reference Shah, Tsitsiklis and Zhong24], we assume that arrivals to each of the
 $n^2$ queues form an independent Bernoulli process with rate
 $\rho/n$, so that
 $A_{ij}(\tau)-A_{ij}(\tau-1)$ are independent Bernoulli random variables with mean
 $\rho/n$, for
 $\tau \in \mathbb{N}$ and
 $i, j \in [n]$, with the convention that
 $A_{ij}(0) = 0$ for all i and j. We are only interested in systems that can be made stable under some scheduling policy, so we assume that
 $\rho < 1$, i.e., the system is underloaded.
In each time slot, the switch can serve a number of packets using a schedule, subject to the following constraints: for each i, at most one packet can be served from any of the n queues  $(i, 1), (i, 2), \cdots, (i, n)$; and for each j, at most one packet can be served from any of the n queues
 $(1, j), (2, j), \cdots, (n, j)$. More precisely, let
 $\boldsymbol{\sigma} = (\sigma_{ij})_{i,j=1}^n$ be a schedule, where
 $\sigma_{ij}$ denotes the number of packets that can be served from queue (i, j) in a time slot. Then the set
 $\mathcal{S}$ of feasible schedules is given by
 \begin{equation}\mathcal{S} = \left\{ \boldsymbol{\sigma} \in \{0, 1\}^{n\times n} \,{:}\, \forall i, \sum_{j^{\prime}=1}^n \sigma_{ij^{\prime}} \leq 1; \ \text{ and } \ \forall j, \sum_{i^{\prime}=1}^n \sigma_{i^{\prime}j} \leq 1 \right\}.\end{equation}
Since the set of schedules  $\mathcal{S}$ corresponds exactly to the set of (partial) matchings between the inputs and outputs, a schedule is sometimes called a matching as well. A schedule
 $\boldsymbol{\sigma} = (\sigma_{ij}) \in \mathcal{S}$ with
 $1 = \sum_{j^{\prime}=1}^n \sigma_{ij^{\prime}} = \sum_{i^{\prime}=1}^n \sigma_{i^{\prime}j}$ for all i and j is also called a full (perfect) matching. A scheduling policy decides, in each time slot, the schedule to use for serving the packets in the system, based on the past history and the current queue sizes.
To specify the dynamics of the model, we adopt the following timing convention. Let  $Q_{ij}(\tau)$ be the size of the queue (i, j) at the beginning of time slot
 $\tau$. In each time slot
 $\tau$, the policy first observes the queue sizes
 $Q_{ij}(\tau)$, and then decides on the schedule
 $\boldsymbol{\sigma}(\tau)$, which is applied in the middle of the time slot. At the end of the time slot, new arrivals take place. Thus, for each i, j, and
 $\tau$, we have
 \begin{equation}Q_{ij}(\tau+1) = \left(Q_{ij}(\tau) - \sigma_{ij}(\tau)\right)^+ + A_{ij}(\tau) - A_{ij}(\tau-1).\end{equation}
Since  $\sigma_{ij}(\tau) \in \{0, 1\}$, Equation (2) can be rewritten as
 \begin{equation}Q_{ij}(\tau+1) = Q_{ij}(\tau) - \sigma_{ij}(\tau)\boldsymbol{1}_{\{Q_{ij}(\tau)>0\}} + A_{ij}(\tau) - A_{ij}(\tau-1).\end{equation}
Throughout the paper, we assume that the system starts empty, i.e.,  $Q_{ij}(1) = 0$ for all i and j. Then, similar to [Reference Shah, Tsitsiklis and Zhong24], we sum Equation (3) over time to get that for
 $\tau \in \mathbb{N}$,
 \begin{equation}Q_{ij}(\tau+1) = A_{ij}(\tau) - S_{ij}(\tau)\end{equation}
for all i and j, where
 \begin{equation}S_{ij}(\tau) = \sum_{t=1}^{\tau} \sigma_{ij}(\tau)\boldsymbol{1}_{\{Q_{ij}(\tau)>0\}}\end{equation}
is the actual service received by queue (i, j) in time slots 1 to  $\tau$. Note
 $S_{ij}(\tau)$ is different from
 $\sum_{t=1}^{\tau} \sigma_{ij}(\tau)$, the cumulative service offered to queue (i, j) in time slots 1 to
 $\tau$. Whenever service is offered for queue (i, j) (i.e.,
 $\sigma_{ij}(\tau) = 1$) but there is no packet to be served (i.e.,
 $Q_{ij}(\tau) = 0$), we called the offered service wasted.
3. Main result and policy overview
In this section, we present the main result of the paper, as well as an overview of our policy.
3.1. Main result
Theorem 1. Let  $n \in \mathbb{N}$, and consider an
 $n\times n$ input-queued switch for which the
 $n^2$ arrival streams form independent Bernoulli processes with a common arrival rate
 $\rho/n$, where
 $\rho \in (0, 1)$. Then there exists a scheduling policy under which the expected total queue size is bounded above by
 $cn (1-\rho)^{-4/3} \log f$ at all times, where
 \begin{equation}f = n \vee \frac{1}{1-\rho},\end{equation}
and c is a constant that does not depend on n or  $\rho$; i.e., for any
 $\tau \in \mathbb{N}$,
 \begin{equation}\mathbb{E}\Bigg[\sum_{i,j=1}^n Q_{ij}(\tau)\Bigg] \leq cn (1-\rho)^{-4/3} \log f.\end{equation}
It is worth noting that the bound in (7) holds uniformly over all n and  $\rho$; this is different from the upper bound in [Reference Shah, Tsitsiklis and Zhong24], for example, which requires a joint scaling of parameters n and
 $\rho$. Let us also note that the upper bound in (7) improves on the best previously known upper bound
 $O\Big(n^{1.5}(1-\rho)^{-1} \log \frac{1}{1-\rho}\Big)$ [Reference Shah, Tsitsiklis and Zhong24] when
 $n \leq \frac{1}{1-\rho} \leq n^{1.5}$, and on the best previously known upper bound
 $O\Big(\frac{n\log n}{(1-\rho)^2}\Big)$ when
 $\frac{1}{1-\rho} < n$. In particular, when
 $\frac{1}{1-\rho} = n$, our upper bound improves the state of the art from
 $O\big(n^{2.5}\log n\big)$ to
 $O\Big(n^{7/3}\log n\Big)$, as shown in the following corollary.
Corollary 1. Let  $n \in \mathbb{N}$, and consider an
 $n\times n$ input-queued switch for which the
 $n^2$ arrival streams form independent Bernoulli processes with a common arrival rate
 $\rho/n$, where
 $\rho = 1-1/n$. Then there exists a scheduling policy under which the total expected queue size is bounded above by
 $c n^{7/3} \log n$ at all times; i.e., for any
 $\tau \in \mathbb{N}$,
 \begin{equation}\mathbb{E}\Bigg[\sum_{i,j=1}^n Q_{ij}(\tau)\Bigg] \leq c n^{\frac{7}{3}} \log n.\end{equation}
We remark that our upper bound is still a multiplicative factor of  $O\big(n^{1/3} \log n\big)$ away from the conjectured scaling
 $\Theta(n^2)$ in [Reference Shah, Tsitsiklis and Zhong23], when
 $1-\rho = \Theta(1/n)$. It is an open question whether this gap can be further reduced. Let us also remark that we will only prove Theorem 1 for n sufficiently large and
 $\rho$ sufficiently close to 1. For smaller n, the theorem remains valid by considering a stabilizing policy such as Max-Weight, and by re-choosing the constant c to be large enough. Similarly, for
 $\rho$ that is strictly bounded away from 1, the theorem remains valid by considering, for example, the batch policy in [Reference Neely, Modiano and Cheng18], and by re-choosing c to be large enough.
3.2. Policy overview and intuition behind improved scaling
We now proceed to describe the high-level ideas underpinning our proposed policy; the formal policy description is deferred to Section 6. The policy proposed in this paper, like the one in [Reference Shah, Tsitsiklis and Zhong24], is of a batching type. In the standard batching policy (see e.g. [Reference Neely, Modiano and Cheng18]), time is divided into consecutive intervals (batches) of equal lengths, and packets that arrive during a given batch are served only in subsequent batches. To guarantee stability, all packets that arrive during one batch should be successfully served during the very next batch, with high probability. By choosing the smallest batch length that guarantees stability, which turns out to be  $O\big(\!\log n/(1-\rho)^2\big)$, the policy in [Reference Neely, Modiano and Cheng18] gives an upper bound of
 $O\big(n\log n/(1-\rho)^2\big)$ on the expected total queue size. See Figure 1b for an illustration.
Comparison between a standard batching policy and our policy. (a) Illustration of a standard batching policy. (b) Illustration of our policy.

Unlike the standard batching policy in [Reference Neely, Modiano and Cheng18], our policy, like the one in [Reference Shah, Tsitsiklis and Zhong24], starts serving packets from a given batch much earlier, before the arrivals of the entire batch. When  $\Omega(n^{-1.5}) \leq 1-\rho \leq O(1/n)$, our policy starts serving packets even earlier than the one in [Reference Shah, Tsitsiklis and Zhong24], resulting in improved queue-size scaling. More specifically, our policy starts serving packets from a given batch of length
 $b = O\big((1-\rho)^{-2} \log f\big)$ (recall the definition of f in Equation (6)) just after the first
 $d = O\big((1-\rho)^{-4/3}\log f\big)$ time slots of that batch, and is still able to finish serving all packets of this batch in b time slots, with high probability. To achieve this, our policy divides a batch into further subintervals of lengths
 $I_0, I_1, \cdots, I_{\ell}$, with
 $I_0 = d$. Then, the uth subinterval is used to serve arrivals from the
 $(u-1)$th subinterval, for
 $u = 1, 2, \cdots, \ell$. See Figure 1a for an illustration.
To guarantee stability, the  $I_u$’s are carefully chosen so that the subintervals are efficiently utilized. More specifically, note that the maximum number of packets that can be served in a period of
 $I_u$ slots is
 $nI_u$, which can be achieved if and only if a full matching is used in each slot, and no offered service is wasted. Thus, the following is required of our policy:
• For each
 $u = 1, 2, \cdots, \ell$, $I_u$ is chosen to be the largest possible, so that the uth subinterval can serve $nI_u$ packets from the $(u-1)$th subinterval, with high probability.


It is by no means obvious that such a requirement can be met. To illustrate the inherent difficulty, consider a  $3\times 3$ switch whose arrivals from a subinterval constitute the following matrix:
 \begin{equation} \textbf{\textit{q}} = \left[ {\begin{array}{c@{\quad}c@{\quad}c} 0 & a & 0 \\ a & 0 & a \\ 0 & a & 0 \end{array} } \right],\end{equation}
where a is some positive integer. Then it is easy to see that for these arrivals, it is impossible to serve 3 packets in one time slot, let alone serve 3t packets in any t time slots.
The fact that the aforementioned requirement can be met has to do with the statistical regularity that originates from the stochastic arrivals with uniform rates. In particular, using the equivalence between queue matrices and bipartite multigraphs described in the introduction, the requirement that  $nI_u$ packets can be served from arrivals of
 $I_{u-1}$ time slots translates into the existence of an
 $I_u$-factor of an Erdős–Rényi random bipartite multigraph, where the number of edges between a pair of left and right nodes is independently and binomially distributed with parameters
 $I_{u-1}$ and
 $\rho/n$. Our characterization of the largest k-factors in an Erdős–Rényi random bipartite multigraph implies that such a requirement can be met with probability
 $1- f^{-16}$, provided that
 \[I_u \le \rho I_{u-1} - \sqrt{ 304 \rho I_{u-1} \log f }.\]
Hence, we choose  $d=I_0 >\cdots >I_\ell = \Theta(d)$ for
 $\ell=\Theta(\sqrt{d/\log f })$. Since
 $\sum_{u=0}^\ell I_u=b$, we get that
 $d=\Theta( b^{2/3} \log^{1/3} f)$, which reduces to
 $d=\Theta( (1-\rho)^{-4/3} \log f)$ when
 $b=\Theta( (1-\rho)^{-2} \log f )$. Thus, the expected number of total arrivals in the first subinterval is
 $n \rho d =\Theta( n (1-\rho)^{-4/3} \log f)$, which will be shown to dictate the order of magnitude of the expected total queue size in Section 7, establishing the upper bound in Theorem 1.
4. Preliminaries
Here we provide some preliminary facts that will be useful for our analysis later on. The same facts were used in [Reference Shah, Tsitsiklis and Zhong24] and we state them here for completeness.
Concentration inequalities. We will use the following concentration bounds on the tail probabilities of binomial random variables (adapted from Theorem 2.4 in [Reference Chung4]).
Theorem 2. Let X be a binomial random variable with parameters m and p, so that  $\mathbb{E}[X] = mp$ and
 $Var(X) = mp(1-p)$. Then, for any
 $x > 0$, we have
 \begin{align}\text{(Lower tail)} \quad \quad {\mathbb P}(X \leq \mathbb{E}[X] - x) & \leq \exp \left\{-\frac{x^2}{2\mathbb{E}[X]}\right\}; \end{align}
 \begin{align}\text{(Upper tail)} \quad \quad {\mathbb P}(X \geq \mathbb{E}[X] + x) & \leq \exp \left\{-\frac{x^2}{2(\mathbb{E}[X]+x/3)}\right\}.\end{align}
Kingman bound for discrete-time G/G/1 queue. Consider the following discrete-time G/G/1 queueing system. For each  $\tau \in \mathbb{N}$,
 $X(\tau)$ denotes the number of packets that arrive during time slot
 $\tau$,
 $Y(\tau)$ denotes the number of packets that can be served during time slot
 $\tau$, and
 $Z(\tau)$ denotes the queue size at the beginning of time slot
 $\tau$. Suppose that
 $X(\tau)$ are i.i.d. across time, so are
 $Y(\tau)$, and
 $\{X(\tau)\,{:}\, \tau \in \mathbb{N}\}$ and
 $\{Y(\tau)\,{:}\,\tau \in \mathbb{N}\}$ are independent. The dynamics of the system are given by
 \begin{equation}Z(\tau+1) = \left(Z(\tau) + X(\tau) - Y(\tau)\right)^+.\end{equation}
The timing convention in Equation (12) is different from that in Equation (2). In Equation (12), arrivals take place before the services in each time slot. This timing convention is used for analyzing the so-called backlogged packets defined in Section 6 (cf. Equation (44)).
Let  $\lambda = \mathbb{E}[X(\tau)]$,
 $m_{2x} = \mathbb{E}[X^2(\tau)]$,
 $\mu = \mathbb{E}[Y(\tau)]$, and
 $m_{2y} = \mathbb{E}[Y^2(\tau)]$. The following theorem is Theorem 4.2 from [Reference Shah, Tsitsiklis and Zhong24], which is a minor adaptation of Theorem 3.4.2 of [Reference Srikant and Ying27].
Theorem 3. (Discrete-time Kingman bound) Consider the aforementioned discrete-time G/G/1 system with  $Z(1) = 0$ and
 $\lambda < \mu$. Then
 \begin{equation}\mathbb{E}[Z(\tau)] \leq \frac{m_{2x} + m_{2y} - 2\lambda \mu}{2(\mu-\lambda)} \quad \text{for all } \tau \in \mathbb{N}.\end{equation}
Optimal clearing policy. A key component in any batching-type policy is to finish serving all packets that arrive during a batch as quickly as possible. Thus, it is important to understand the minimum clearance time of a queue matrix, i.e., the minimum number of slots required to finish serving all packets of a queue matrix using feasible schedules, assuming no new arrivals. The following theorem (also Theorem 4.3 of [Reference Shah, Tsitsiklis and Zhong24]) provides a precise characterization of the minimum clearance time.
Theorem 4. Let  $\textbf{\textit{q}} = (q_{ij})_{i,j=1}^n$ be an
 $n\times n$ queue matrix. Let
 \begin{equation}r_i = \sum_{j^{\prime}=1} q_{ij^{\prime}} \quad \text{and} \quad c_j = \sum_{i^{\prime}=1}^n q_{i^{\prime}j}\end{equation}
be the ith row sum and jth column sum of  $\textbf{\textit{q}}$, respectively. Let
 \begin{equation}\gamma = \max \left\{ \max_i r_i, \; \max_j c_j \right\}.\end{equation}
Then  $\gamma$ is precisely the minimum clearance time of the queue matrix
 $\textbf{\textit{q}}$.
Note that since in each time slot, at most one packet can be cleared from each row or column, each  $r_i$ and each
 $c_j$ will decrease by at most 1. Thus,
 $\gamma$ is clearly a lower bound on the minimum clearance time. Theorem 4 states that there exists an optimal clearing policy that finishes serving all packets of
 $\textbf{\textit{q}}$ in precisely
 $\gamma$ slots.
5. Lower envelopes of queue matrices
As mentioned in the introduction (Section 1) and the policy overview (Section 3), of central importance to our policy is the ability to serve arrivals of a subinterval using full matchings, without any wasted offered services. This motivates us to define the lower envelopes of a queue matrix.
Definition 1. Let  $\textbf{\textit{q}} = (q_{ij})_{i,j=1}^n$ be an
 $n\times n$ queue matrix. A matrix
 $\textbf{\textit{g}} = (g_{ij})_{i,j=1}^n$ is a
 $\beta$-lower envelope of
 $\textbf{\textit{q}}$ if (a) for all i and j,
 $g_{ij} \in \mathbb{Z}_+$ and
 $g_{ij} \leq q_{ij}$; and (b)
 \begin{equation}\beta = \sum_{i^{\prime}=1}^n g_{i^{\prime}j} = \sum_{j^{\prime}=1}^n g_{ij^{\prime}} \quad \text{for all } i, j \in [n].\end{equation}
Remark 1. Let us note that if  $\textbf{\textit{g}}$ is a
 $\beta$-lower envelope of a queue matrix
 $\textbf{\textit{q}}$, then by Theorem 4, packets of
 $\textbf{\textit{g}}$, which also belong to
 $\textbf{\textit{q}}$, can be cleared optimally using
 $\beta$ full matchings, without any wasted service. We call any such
 $\beta$ full matchings the schedules prescribed by the
 $\beta$-lower envelope
 $\textbf{\textit{g}}$ of
 $\textbf{\textit{q}}$.
Recall that a queue matrix  $\textbf{\textit{q}}$ can be viewed equivalently as the biadjacency matrix of a bipartite multigraph G with left vertex set [n] and right vertex set [n], where left vertex i is connected to right vertex j with
 $q_{ij}$ multiple edges if
 $q_{ij}\ge 1$. From this perspective, a
 $\beta$-lower envelope
 $\textbf{\textit{g}}$ of
 $\textbf{\textit{q}}$ can be equivalently viewed as a
 $\beta$-factor of G, i.e., a spanning
 $\beta$-regular subgraph of G. Note that a 1-factor of G is simply a perfect matching of G. Because of this equivalence, we will use the terminologies ‘a
 $\beta$-lower envelope of a queue matrix’ and ‘a
 $\beta$-factor of a bipartite multigraph’ interchangeably, whichever is more convenient.
The next proposition provides a necessary and sufficient condition for the existence of a  $\beta$-lower envelope of any queue matrix, and is a simple adaptation of the Gale–Ryser theorem [Reference Gale9, Reference Ryser21]. Let
 $\mathcal{R}, \mathcal{C} \subseteq [n]$ be nonempty subsets of [n]. For an
 $n\times n$ queue matrix
 $\textbf{\textit{q}} = (q_{ij})_{i,j=1}^n$, we use
 $\textbf{\textit{q}}_{\mathcal{R}, \mathcal{C}}$ to denote the submatrix
 $(q_{ij})_{i \in \mathcal{R}, j \in \mathcal{C}}$.
Proposition 1. Consider an  $n\times n$ queue matrix
 $\textbf{\textit{q}} = (q_{ij})_{i,j=1}^n$. There exists a
 $\beta$-lower envelope of
 $\textbf{\textit{q}}$ if and only if for any
 $k \times \ell$ submatrix
 $\textbf{\textit{q}}_{\mathcal{R}, \mathcal{C}} = (q_{ij})_{i \in \mathcal{R}, j \in \mathcal{C}}$ of
 $\textbf{\textit{q}}$, where
 $\mathcal{R}, \mathcal{C} \subseteq [n]$,
 $|\mathcal{R}| = k$, and
 $|\mathcal{C}| = \ell$, we have
 \begin{equation}\beta (k+\ell-n) \leq \sum_{i\in \mathcal{R}, j \in \mathcal{C}} q_{ij}.\end{equation}
Proof. The proposition follows as a simple corollary of the Feasibility Theorem in [Reference Gale9]. For the sake of completeness and ease of reference, we record here a direct proof based on the max-flow min-cut theorem [Reference Ford and Fulkerson8].
Consider a network  $\bar{G}$ with a source node s, a sink node t, n left vertices corresponding to the rows of
 $\textbf{\textit{q}}$, and n right vertices corresponding to the columns of
 $\textbf{\textit{q}}$. The source node s is connected to every left vertex
 $i \in [n]$ with a directed edge (s, i) of capacity
 $\beta$. The sink node t is connected to every right vertex
 $j \in [n]$ with a directed edge (j, t) of capacity
 $\beta$. Moreover, every left vertex i is connected to every right vertex j with a directed edge (i, j) of capacity
 $q_{ij}$.
We first show (17) is necessary. Suppose there exists a  $\beta$-lower envelope of
 $\textbf{\textit{q}}$, denoted by
 $\textbf{\textit{g}}$. Define
 $f(s,i)=\beta$ for every left vertex
 $i \in [n]$,
 $f(j,t)=\beta$ for every right vertex
 $j \in [n]$, and
 $f(i,j)=g_{ij}$ for every left vertex
 $i \in [n]$ and every right vertex
 $j \in [n]$. Then f is a network flow from s to t on
 $\bar{G}$. Hence, the max flow from s to t on the network
 $\bar{G}$ is at least
 $\beta n$. For any given set
 $\mathcal{R} \subset [n]$ of left vertices and set
 $\mathcal{C} \subset [n]$ of right vertices, consider a cut
 $S=\{s\}\cup \mathcal{R} \cup ([n]-\mathcal{C})$,
 $S^c=\{t\} \cup ([n]-\mathcal{R}) \cup \mathcal{C}$. The capacity of the cut
 $(S,S^c)$ is
 \[c(S, S^c) \triangleq \beta \!\left( n - |\mathcal{R}| \right) + \beta \!\left( n - |\mathcal{C}| \right) + \sum_{i\in \mathcal{R}, j \in \mathcal{C}} q_{ij}.\]
According to the max-flow min-cut theorem, the value of the max flow equals the minimum cut capacity. Thus
 \[\beta n \le \beta \!\left( n - |\mathcal{R}| \right) + \beta \!\left( n - |\mathcal{C}| \right) + \sum_{i\in \mathcal{R}, j \in \mathcal{C}} q_{ij},\]
which is equivalent to (17).
We next show (17) is sufficient. Suppose (17) holds. Let  $(S, S^c)$ be any cut such that
 $s \in S$ and
 $t \in S^c$. Let A denote the set of left vertices and B the set of right vertices. The capacity of cut
 $(S,S^c)$ satisfies
 \begin{align*}c(S, S^c) & = c(S-s, S^c - t) + c(s, S^c-t) + c(S-s, t) \\& = c((S-s) \cap A, (S^c-t) \cap B ) + \\& \quad + \beta \left| (S^c-t) \cap A \right| + \beta \left| (S-s) \cap B \right|,\end{align*}
where we write  $S-s=S\setminus \{s\}$ for ease of notation. Let
 $\mathcal{R}= (S-s) \cap A$ and
 $\mathcal{C}=(S^c-t)\cap B$. Then
 $| (S^c-t) \cap A | = n - |\mathcal{R}|$ and
 $| (S-s) \cap B | = n-|\mathcal{C}|$. It follows that
 \begin{align*}c(S, S^c) & = c(\mathcal{R}, \mathcal{C} ) + \beta \!\left( n - |\mathcal{R}| \right) + \beta ( n - |\mathcal{C}| ) \\&= \sum_{i\in \mathcal{R}, j \in \mathcal{C}} q_{ij} + \beta ( n - |\mathcal{R}| ) + \beta \!\left( n - |\mathcal{C}| \right) \ge \beta n,\end{align*}
where the last inequality holds thanks to (17). Moreover, if  $S=\{s\}$, then the capacity of the cut
 $(S, S^c)$ is equal to
 $\beta n$. Therefore, the minimum cut capacity of network
 $\bar{G}$ with respect to s and t is
 $\beta n$.
Now, from the max-flow min-cut theorem, there is a flow f from s to t on  $\bar{G}$ such that the value of the flow is
 $\beta n$. In particular, for every left vertex
 $i \in [n] $ and right vertex
 $j \in [n]$,
 \[\beta = f(s, i) = \sum_{j^{\prime} \in [n]} f(i, j^{\prime} ) = \sum_{i^{\prime} \in [n]} f(i^{\prime}, j) = f(j,t).\]
Moreover, since the edge capacity is integer-valued, this flow f can further be chosen to be integer-valued. Define an  $n\times n$ matrix
 $\textbf{\textit{g}}$ such that
 $g_{ij}= f(i,j)$ for every left vertex i and every right vertex j. Then
 $g_{ij} \in \mathbb{Z}_+$ and
 \[\beta = \sum_{j^{\prime} \in [n]} g(i, j^{\prime} ) = \sum_{i^{\prime} \in [n]} g(i^{\prime}, j).\]
Therefore,  $\textbf{\textit{g}}$ is a
 $\beta$-lower envelope of
 $\textbf{\textit{q}}$, completing the proof.
The main result of this section is the following tight characterization of the existence of a  $\beta$-lower envelope for a random queue matrix.
Theorem 5. Let  $\textbf{\textit{Q}} = (Q_{ij})_{i,j=1}^n$ be an
 $n\times n$ random queue matrix with i.i.d. entries that are binomially distributed with parameters m and p. Let f be an additional, positive parameter such that
 $f \geq n$. Suppose
 \begin{equation}pmn \geq 152 \log f.\end{equation}
Then, with probability  $1 - 1/f^{16}$,
 $\textbf{\textit{Q}}$ has a
 $\beta_0$-lower envelope with
 \begin{equation}\beta_0 = \lfloor pmn - \sqrt{304 pmn \log f} \rfloor.\end{equation}
Remark 2. Note that for any  $\beta$-lower envelope of
 $\textbf{\textit{Q}}$, it must hold that
 \[\beta \le \min \left\{ \min_i r_i, \; \min_j c_j \right\},\]
where  $r_i$ and
 $c_j$, as given in (14), are respectively the ith row sum and jth column sum of
 $\textbf{\textit{Q}}$. Since both
 $r_i$ and
 $c_j$ are binomially distributed with parameters mn and p, one can show that if
 $mnp \ge \delta_1 \log n$ for a sufficiently large constant
 $\delta_1>0$, then there exists a constant
 $\delta_2>0$ such that with high probability,
 \[ \min_i r_i \le pmn - \delta_2 \sqrt{pmn \log n}\]
and hence  $\beta \le pmn - \delta_2 \sqrt{pmn \log n}.$ Therefore, the lower bound for
 $\beta$ given in (19) with
 $f=n$ is tight up to a constant factor.
Remark 3. Theorem 5 holds for the special case where  $m=1$. In this case,
 $\textbf{\textit{Q}}$ can be viewed as the biadjacency matrix of an Erdős–Rényi bipartite simple graph G with edge probability p. Therefore, our result implies that if
 $np=\omega(\!\log n)$, then with probability converging to 1, G has
 $\beta$-factor with
 $\beta\sim np$.
In comparison, previous work [Reference Csaba5] shows that any simple bipartite graph with n left (right) vertices and minimum degree  $\delta n$, where
 $\delta \geq 1/2$, has a
 $\beta$-factor with
 $\beta =\lfloor n \frac{\delta+\sqrt{2\delta-1}}{2}\rfloor$. Since with high probability the Erdős–Rényi bipartite graph G has minimum degree
 $\sim np$ if
 $p \ge 1/2$, the result in [Reference Csaba5] implies that if
 $p \ge 1/2$, then G has
 $\beta$-factor with
 $\beta\sim n \frac{p+\sqrt{2p-1}}{2}$ with high probability.
Note that  $\frac{p+\sqrt{2p-1}}{2} \le p$, with equality if and only
 $p \in \{0,1\}.$ Therefore, our result improves on the previous result [Reference Csaba5] in the context of Erdős–Rényi bipartite random graphs. As can be seen in the proof, we achieve this improvement by exploiting certain nice random structures in
 $\textbf{\textit{Q}}.$
Proof. By Proposition 1, it suffices to show that with high probability, the inequalities
 \begin{equation}\beta (|\mathcal{R}|+|\mathcal{C}|-n) \leq \sum_{i\in \mathcal{R}, j \in \mathcal{C}} Q_{ij}\end{equation}
hold for any nonempty subsets  $\mathcal{R}$ and
 $\mathcal{C}$ of [n], where
 \begin{equation}\beta = pmn - \sqrt{304 pmn \log f}.\end{equation}
To this end, fix some  $k, \ell \in [n]$, and suppose that
 $k \geq \ell$. WLOG, also suppose that
 $k+\ell > n$, since the inequality (20) is satisfied deterministically for subsets
 $\mathcal{R}$ and
 $\mathcal{C}$ of [n] if
 $|\mathcal{R}| + |\mathcal{C}|\,{\leq}\,n$. There are
 $\Big(\begin{array}{c}n \\[-2pt] k\end{array}\Big) = \Big(\begin{array}{c}n \\[-2pt] n-k\end{array}\Big) \leq n^{n-k}$ subsets of [n] with size k, and
 $\Big(\begin{array}{c}n \\[-2pt] \ell\end{array}\Big) \leq n^{\ell}$ subsets of [n] with size
 $\ell$, so the number of
 $k \times \ell$ submatrices of
 $\textbf{\textit{Q}}$ is no larger than
 $n^{n-k}\cdot n^{\ell} = n^{n-k+\ell}$. Furthermore, for any fixed
 $k\times \ell$ submatrix, say
 $\textbf{\textit{Q}}_{\mathcal{R}, \mathcal{C}}$, of
 $\textbf{\textit{Q}}$, since the entries of
 $\textbf{\textit{Q}}_{\mathcal{R}, \mathcal{C}}$ are i.i.d. binomial random variables with parameters m and p, the sum
 $\sum_{i\in \mathcal{R}, j \in \mathcal{C}} Q_{ij}$ is binomially distributed with parameters
 $k\ell m$ and p. Thus, by Theorem 2, for fixed subsets
 $\mathcal{R}$ and
 $\mathcal{C}$ of [n] with
 $|\mathcal{R}|=k$ and
 $|\mathcal{C}|=\ell$, we have
 \begin{align}&\,{\mathbb P}\Bigg(\sum_{i\in \mathcal{R}, j \in \mathcal{C}} Q_{ij} \leq k\ell mp -\sqrt{38(n-k+\ell) k\ell mp \log f}\Bigg) \nonumber \\
\leq &\,\exp\bigg(-\frac{38(n-k+\ell) k\ell mp \log f}{2k\ell mp}\bigg) = f^{-19(n-k+\ell)}.\end{align}
Let  $\underline{\textbf{\textit{Q}}}(k, \ell)$ denote the minimum value over the sums of entries of all
 $k \times \ell$ submatrices of
 $\textbf{\textit{Q}}$, i.e.,
 \begin{equation}\underline{\textbf{\textit{Q}}}(k, \ell) = \min_{\mathcal{R}, \mathcal{C} \subseteq [n]: |\mathcal{R}|=k, |\mathcal{C}|=\ell} \sum_{i \in \mathcal{R}, j \in \mathcal{C}} Q_{ij}.\end{equation}
Fix subsets  $\mathcal{R}$ and
 $\mathcal{C}$ of [n] with sizes k and
 $\ell$, respectively. Then, by the union bound, we have
 \begin{align}&\,{\mathbb P}\Big(\underline{\textbf{\textit{Q}}}(k, \ell) \leq k\ell mp - \sqrt{38(n-k+\ell) k\ell mp \log f} \Big) \nonumber \\
\leq &\,n^{n-k+\ell} {\mathbb P}\Bigg(\sum_{i\in \mathcal{R}, j \in \mathcal{C}} Q_{ij} \leq k\ell mp - \sqrt{38(n-k+\ell) k\ell mp \log f}\Bigg) \nonumber \\\leq &\,n^{n-k+\ell} \cdot f^{-19(n-k+\ell)} \leq f^{-18(n-k+\ell)} \leq f^{-18},\end{align}
where, for the second-to-last inequality, we used the fact that  $f \geq n$, and for the last inequality, we used the fact that
 $n-k+\ell \geq \ell \geq 1$. Thus, by the union bound again,
 \begin{align}&\,{\mathbb P}\Bigg(\underline{\textbf{\textit{Q}}}(k, \ell) \leq k\ell mp - \sqrt{38(n-k+\ell) k\ell mp \log f} \nonumber \\&\quad \text{ for some } (k, \ell) \text{ with } k \geq \ell, k+\ell >n\Bigg) \nonumber \\\leq &\, \frac{1}{2}n(n+1) f^{-18},\end{align}
since there are at most  $n(n+1)/2$ pairs
 $(k, \ell) \in [n]\times [n]$ with
 $k \geq \ell$. Similarly, we can get
 \begin{align}&\,{\mathbb P}\Bigg(\underline{\textbf{\textit{Q}}}(k, \ell) \leq k\ell mp - \sqrt{38(n-\ell+k) k\ell mp \log f} \nonumber \\&\quad \text{ for some } (k, \ell) \text{ with } k
< \ell, k+\ell >n\Bigg) \nonumber \\ &\quad \leq \frac{1}{2}n(n-1) f^{-18}.\end{align}
Thus, by Inequalities (25) and (26) and the union bound, we have
 \begin{align}&\,{\mathbb P}\Bigg(\underline{\textbf{\textit{Q}}}(k, \ell) \leq k\ell mp - \sqrt{38(n-|k-\ell|) k\ell mp \log f} \nonumber \\&\quad \text{ for some } (k, \ell) \text{ with } k+\ell >n\Bigg) \nonumber \\ &\quad \leq n^2 f^{-18} \leq f^{-16},\end{align}
where for the last inequality we used the fact that  $f\geq n$. We now claim that for all
 $k, \ell \in [n]$ with
 $k+\ell > n$,
 \begin{equation}\beta (k+\ell-n) \leq k\ell mp - \sqrt{38(n - |k-\ell|) k\ell mp \log f},\end{equation}
where  $\beta$ is given by Equation (21).
Proof of the claim. We first prove the claim for the case where  $k \geq \ell$ and
 $k+\ell > n$. In this case,
 $k > n/2$, and
 $n-|k-\ell| = n-k+\ell < 2 \ell$. To prove the claim in this case, it suffices to show that for any
 $k \in [n]$ such that
 $k > n/2$,
 \begin{equation}\beta \!\left(2-\frac{n}{k}\right) \leq kmp - \sqrt{76 kmp \log f}.\end{equation}
To see that Inequality (29) implies Inequality (28), note that because  $k \geq \ell$, we have
 \begin{equation}2-\frac{n}{k} = 1 - \frac{n-k}{k} \geq 1 - \frac{n-k}{\ell} = \frac{k+\ell-n}{\ell}.\end{equation}
Thus, Inequality (29) implies that
 \begin{equation}\beta \cdot \frac{k+\ell-n}{\ell} \leq kmp - \sqrt{76 kmp \log f},\end{equation}
and then
 \begin{align}\beta (k+\ell-n) \leq &\,k\ell mp - \ell \sqrt{76 kmp \log f} \nonumber \\= &\,k\ell mp - \sqrt{38\cdot 2\ell\cdot k \ell mp \log f} \nonumber \\\leq &\,k\ell mp - \sqrt{38(n-k+\ell) k \ell mp \log f},\end{align}
recovering Inequality (28). Here, the last inequality follows from the assumption that  $k+\ell > n$.
Next, we prove Inequality (29). Write  $x = k/n$, and
 $\rho = np$. Then, using the expression (21) for
 $\beta$, we can rewrite Inequality (29) as
 \begin{equation}\left(2-\frac{1}{x}\right) \left(\rho m - \sqrt{304\rho m \log f}\right) \leq x \rho m - \sqrt{x}\cdot \sqrt{76 \rho m \log f}.\end{equation}
Rearranging Inequality (33), we obtain the equivalent expression
 \begin{equation}\left(x+\frac{1}{x}-2\right) \rho m\geq \left(\sqrt{x} + \frac{2}{x} - 4\right) \sqrt{76 \rho m \log f}.\end{equation}
Note that  $x \in (1/2, 1]$, because
 $n/2 < k \leq n$. We will establish next that
 \begin{align}x + \frac{1}{x} - 2 \ge \frac{1}{\sqrt{2}} \left(\sqrt{x} + \frac{2}{x} - 4\right) \quad \forall x \in [1/2,1] ,\end{align}
which together with the condition (18) where  $\rho m \geq 2\cdot 76 \log f$ immediately implies (34).
Note that (35) clearly holds for  $x=1$. For any
 $x \in [1/2, 1)$,
 $x+\frac{1}{x}-2>0$ and moreover
 \[\frac{\sqrt{x} + \frac{2}{x} - 4}{x + \frac{1}{x} - 2} = 2 - \frac{2x - \sqrt{x} }{x + \frac{1}{x} - 2}.\]
Note that  $2x-\sqrt{x}=\sqrt{x} (2\sqrt{x}-1)$ is increasing in
 $x \in [1/2,1)$, while
 $x+1/x$ is decreasing in
 $x \in [1/2,1)$. Hence,
 \[\sup_{x \in [1/2,1)} \frac{\sqrt{x} + \frac{2}{x} - 4}{x + \frac{1}{x} - 2}= \frac{\sqrt{x} + \frac{2}{x} - 4}{x + \frac{1}{x} - 2} \bigg|_{x=1/2} = \sqrt{2},\]
completing the proof of (35).
To summarize, we have established Inequality (34), which is equivalent to Inequality (29), which implies Inequality (28), for the case where  $k \geq \ell$ and
 $k+\ell > n$. By symmetry, the proof of Inequality (28) for the case where
 $k < \ell$ and
 $k+\ell > n$ follows exactly the same line of argument, with the roles of k and
 $\ell$ interchanged. Thus, we have established Inequality (28) and hence the claim.
To complete the proof of the theorem, note that by Inequalities (28) and (27), we have that with probability  $1-f^{-16}$,
 \begin{equation}\beta (k+\ell-n)
< \underline{\textbf{\textit{Q}}}(k, \ell) \qquad \text{ for all } (k, \ell)\text{ with } k+\ell > n,\end{equation}
in which case the matrix  $\textbf{\textit{Q}}$ has a
 $\beta$-lower envelope, by Proposition 1. This completes the proof of the theorem.
6. Policy description
This section contains a detailed description of our proposed scheduling policy. There are similarities between our policy and the one in [Reference Shah, Tsitsiklis and Zhong24], but there are also key differences. Thus, the policy description will be complete and self-contained, with comparisons made to the policy in [Reference Shah, Tsitsiklis and Zhong24] throughout. Let us also note that it suffices for our policy to be well-defined for n sufficiently large and  $\rho$ sufficiently close to 1, since the main result, Theorem 1, will only be proved for n sufficiently large and
 $\rho$ sufficiently close to 1.
Recall that we define  $f = n \vee (1-\rho)^{-1}$ in (6) for notational convenience. We introduce three parameters, b, d, and s. They define the lengths of certain time intervals, which in turn specify different phases of the policy. These parameters are given by
 \begin{align}b &= c_b (1-\rho)^{-2} \log f, \end{align}
 \begin{align}d &= c_d (1-\rho)^{-4/3} \log f, \text{ and } \end{align}
 \begin{align}s &= \rho b + \sqrt{c_s b\log f}.\\[4pt]\nonumber\end{align}
Here,  $c_b$,
 $c_d$, and
 $c_s$ are positive constants that are independent of n and
 $\rho$, and chosen so that
 \begin{equation}c_b - \sqrt{c_s c_b} \geq 1,\quad c_d^{3/2} \geq 76 c_b, \quad c_d \geq c_b, \quad c_s \geq 30.\end{equation}
We also assume that
 \begin{equation}n \geq 4, \quad \rho \geq \frac{1}{2}, \quad \frac{1}{(1-\rho)^{2/3}} \geq \frac{38}{\sqrt{c_d}} \vee \frac{\sqrt{c_d}}{38} \vee c_d.\end{equation}
As is done in [Reference Shah, Tsitsiklis and Zhong24], we will treat the parameters b, d, and s as integers, since doing so will not affect our order-of-magnitude estimates.
Similar to the policy in [Reference Shah, Tsitsiklis and Zhong24], we divide time into consecutive intervals of length b. For  $k = 0, 1, 2, \cdots$, the interval consisting of time slots
 $kb+1, kb+2, \cdots, (k+1)b$ is called the kth arrival period, or the kth batch. The policy intends to complete serving all kth-batch arrivals in the kth service period, which is offset from the kth batch by a delay of d and consists of time slots
 $kb+d+1, \cdots, (k+1)b+d$. All kth-batch packets that are not served during the kth service period are called backlogged and will be served in subsequent service periods. As we will see, the policy is designed in such a way that the number of backlogged packets will be zero with high probability.
We now describe the policy in more detail, by first considering what may happen before the start of the kth service period,  $k \in \mathbb{Z}_+$. There may be backlogged packets from previous service periods, whose number we denote by
 $B_k$. By convention,
 $B_0 = 0$. In addition, time slots
 $kb, kb+1, \cdots, kb+d$ do not belong to the kth service period; arrivals from these d slots do belong to the kth arrival period, however, and they accumulate without being served until slot
 $kb+d+1$, the beginning of the kth service period.
Illustration of the different phases of our policy. (a) Illustration of a typical arrival period and the phases of a service period. The first slot of the arrival period is numbered as slot 1, and subsequent slots are numbered consecutively. The same numbering convention is used in Figure 2b as well. (b) Illustration of the lower envelope phase of the service period. The subinterval I 0 consists of time slots 1 to d. The lower envelope phase is divided into consecutive subintervals  $I_1, I_2, \cdots, I_{\ell}$, with Iu serving arrivals from
 $I_{u-1}$, $u \in \{1, 2, \cdots, \ell\}$.

Next, during the kth service period, scheduling decisions take place in three phases, which are described below and illustrated in Figures 2a and 2b. Note that the scheduling decisions in the first phase, the lower envelope phase, differ substantially from those in the first phase of the policy in [Reference Shah, Tsitsiklis and Zhong24].
1. The kth lower envelope phase consists of the first
$b-d$ time slots of the kth service period, namely, slots $kb+d+1, \cdots, (k+1)b$. This phase is divided further into consecutive subintervals, which we denote by $I_1, I_2, \cdots, I_{\ell}$, where the value of $\ell$ will be specified shortly. Let $I_0$ denote the subinterval consisting of slots $kb, kb+1, \cdots,\break kb+d$. With a slight abuse of notation, we also let $I_u$ denote the length of the subinterval $I_u$, $u \in \{0, 1, \cdots, \ell\}$; these lengths are specified as follows:
(42)Here,\begin{equation}I_u = \left\{\begin{array}{l@{\quad}l}d - 19 u\sqrt{d \log f} & \text{ if } u \in \{0, 1, \cdots, \ell-1\}; \\b - \left(I_0 + I_1 + \cdots + I_{\ell-1}\right) & \text{ if } u = \ell.\end{array}\right.\end{equation}$\ell$ is defined so that $I_{\ell}$ satisfies the condition
(43)In Lemma 2, we will show that\begin{equation}0 \leq I_{\ell} \leq d - 19 \ell \sqrt{d \log f}.\end{equation}$\ell$ is well-defined, i.e., that there exists a unique $\ell \in \mathbb{N}$ such that the condition (43) holds, and we will provide order-of-magnitude estimates for $\ell$.We now proceed to complete the policy description for the lower envelope phase, by describing the scheduling decisions made in each subinterval
$I_1, \cdots, I_{\ell}$. Let $u \in [\ell]$. By the beginning of subinterval $I_u$, all packets from subinterval $I_{u-1}$ have already arrived. During subinterval $I_u$, the policy only handles arrivals from $I_{u-1}$, even though there may be unserved packets from times before $I_{u-1}$. More specifically, let $\textbf{\textit{A}}^{(u-1)} = (A^{(u-1)}_{ij})_{i,j=1}^n$ denote the matrix of the numbers of arrivals to the $n^2$ queues during subinterval $I_{u-1}$. Let $\beta$ be maximal such that $\textbf{\textit{A}}^{(u-1)}$ has a $\beta$-lower envelope. Then $\textbf{\textit{A}}^{(u-1)}$ also has a $\min\{\beta, I_u\}$-lower envelope. During subinterval $I_u$, the policy uses $\min\{\beta, I_u\}$ schedules prescribed by the $\min\{\beta, I_u\}$-lower envelope (recall Remark 1 after Definition 1, and note that all schedules prescribed by the lower envelope are full matchings). If $\beta < I_u$, the policy idles for the remaining $I_u - \beta$ time slots. By the end of the lower envelope phase, there may be kth-batch arrivals that still have not been served; all these arrivals are handled in the normal clearing phase, and possibly the backlog clearing phase and subsequent service periods.2. The kth normal clearing phase consists of the next
$d+s-b$ slots, namely slots $(k+1)b+1, \cdots, kb+d+s$. During this phase, our policy makes the same decisions as that in [Reference Shah, Tsitsiklis and Zhong24]. More specifically, the policy does the following. First, during this phase, the policy does not serve any backlogged packets, or any arrivals from the $(k+1)$th batch (namely, arrivals from the slots $(k+1)b+1, \cdots, kb+d+s$, which take place concurrently with this phase). Next, by slot $(k+1)b+1$, the start of the normal clearing phase, all packets from the kth batch have already arrived. Some of these packets have already been served during the lower envelope phase; the remaining ones will be served using the optimal clearing policy described in Section 5 (cf. the discussion after Theorem 4). It is possible that all kth-batch packets are successfully served before the end of the normal clearing phase, in which case the policy simply idles for the remaining time slots of this phase. On the other hand, it is also possible that by the end of the normal clearing phase, there are still unserved kth-batch packets, whose number we denote by $U_k$. These $U_k$ packets are considered backlogged and then added to the backlog $B_k$ from previous service periods.3. The kth backlog clearing phase consists of the last
$b-s$ slots, namely slots $kb+d+s+1, \cdots, (k+1)b+d$. Again, the scheduling decisions in this phase are the same as those in [Reference Shah, Tsitsiklis and Zhong24]. During this phase, the policy only handles the $B_k+U_k$ backlogged packets accumulated thus far, and it does not serve any arrivals from the $(k+1)$th batch, similar to what happens during the normal clearing phase. We serve the $B_k+U_k$ backlogged packets using some arbitrary policy, the only requirement being that the policy serve one packet in each time slot whenever there are still backlogged packets remaining. Let $B_{k+1}$ denote the number of unserved backlogged packets from the backlog clearing phase, which is also exactly the number of backlogged packets at the beginning of the $(k+1)$th service period. Based on our description, we can see that the numbers of backlogged packets follow the dynamics given by
(44)\begin{equation}B_{k+1} = \left(B_k+U_k - (b-s)\right)^+, \quad k \in \mathbb{Z}_+.\end{equation}


We have now completed the description of the scheduling policy. Note that the total length of the three phases of a service period is  $(b-d) + (d+s-b) + (b-s) = b$, so a service period has the same length as an arrival period. To make sure that the policy is well-defined, we need to verify that the following quantities are nonnegative and well-defined:
 $b-d$, the length of the lower envelope phase;
 $I_1, \cdots, I_{\ell}$, the lengths of the subintervals of the lower envelope phase, and
 $\ell$, the number of these subintervals;
 $d+s-b$, the length of the normal clearing phase; and
 $b-s$, the length of the backlog clearing phase. This is accomplished in the next few lemmas.
Lemma 1. The length  $b-d$ of the lower envelope phase satisfies
 \begin{equation}b-d \geq \frac{1}{2} b \geq 1.\end{equation}
Proof. By (40),  $c_b \geq 30$, and then by (41),
 $(1-\rho)^{-2/3} \geq 2c_d/c_b$. Thus,
 \begin{align*}b-d =&\, c_b (1-\rho)^{-2} \log f - c_d (1-\rho)^{-4/3} \log f \\= &\, \left(c_b (1-\rho)^{-2/3} - c_d\right) (1-\rho)^{-4/3} \log f \\\geq &\,\left(\frac{1}{2} c_b (1-\rho)^{-2/3} + \frac{1}{2}c_b (1-\rho)^{-2/3} - c_d\right) (1-\rho)^{-4/3} \log f \\\geq &\,\left(\frac{1}{2} c_b (1-\rho)^{-4/3}\right) (1-\rho)^{-4/3} \log f \\ = &\,\frac{c_b}{2} (1-\rho)^{-2} \log f = \frac{1}{2} b,\end{align*}
where the last inequality follows from the fact that  $(1-\rho)^{-2/3} \geq 2c_d/c_b$. We also have
 \begin{equation}\frac{1}{2} b = \frac{c_b}{2} (1-\rho)^{-2} \log f \geq \frac{30}{2} \log 3 \geq 1,\end{equation}
by the conditions (40) and (41).
Lemma 2. Recall the description of the scheduling policy in the lower envelope phase, with the subintervals  $I_0, \cdots, I_{\ell}$ defined in Equation (42) and
 $\ell$ defined by Inequality (43). Then
 $\ell$ is well-defined, in that there exists a unique
 $\ell$ that satisfies (43). Furthermore,
 \begin{equation}\ell \leq \frac{\sqrt{c_d}}{38} \cdot \frac{1}{(1-\rho)^{2/3}},\end{equation}
and for  $u \in \{0, 1, 2, \cdots, \ell-1\}$,
 \begin{equation}I_u \geq \frac{1}{2}d.\end{equation}
Proof. Let  $\bar{\ell} = \sqrt{c_d} (1-\rho)^{-2/3}/38$, which, like b, d, and s, we treat as an integer. Let us just note that
 $\bar{\ell}$ is well-defined, in that
 \[\bar{\ell} = \sqrt{c_d} (1-\rho)^{-2/3}/38 \geq \frac{38}{\sqrt{c_d}} \cdot \frac{\sqrt{c_d}}{38} = 1,\]
using the condition  $(1-\rho)^{-2/3} \geq 38/\sqrt{c_d}$ from (41).
For  $u \in \{0, 1, \cdots, \bar{\ell}\}$, let
 \begin{equation}I^{\prime}_u = d - 19 u \sqrt{d \log f}.\end{equation}
We will show that
(a)
$I^{\prime}_u \geq d/2$ for all $u \in \{0, 1, \cdots, \bar{\ell}\}$, and(b)
$I^{\prime}_0 + I^{\prime}_1 + \cdots + I^{\prime}_{\bar{\ell}} \geq b$.


To establish Part (a), note that in view of the definition of  $c_d$ given in (38),
 \begin{equation}\bar{\ell} = \frac{d}{38\sqrt{d\log f}} = \frac{1}{2} \cdot \frac{d}{19\sqrt{d\log f}}.\end{equation}
Thus, for  $u \in \{0, 1, \cdots, \bar{\ell}\}$,
 \begin{align*}I^{\prime}_u \geq I^{\prime}_{\bar{\ell}} & = d - 19\bar{\ell} \sqrt{d\log f} \\& = d - \frac{1}{2} \cdot \frac{d}{19\sqrt{d\log f}} \cdot 19 \sqrt{d\log f} = \frac{1}{2}d.\end{align*}
Next, consider Part (b). We have
 \begin{align*}\sum_{u=0}^{\bar{\ell}} I^{\prime}_u \geq &\, \frac{1}{2}\bar{\ell}d= \frac{\sqrt{c_d}}{38} (1-\rho)^{-2/3} \cdot \frac{c_d}{2} (1-\rho)^{-4/3} \log f \\= &\, \frac{c_d^{3/2}}{76} (1-\rho)^{-2} \log f \\\geq &\,c_b (1-\rho)^{-2} \log f = b,\end{align*}
where the first inequality follows from the fact that the  $I^{\prime}_u \geq d/2$ for all u, and the last inequality follows from the condition (40).
Having established Parts (a) and (b), it is now easy to see that  $\ell$, as characterized by the condition (43), is well-defined and unique, that
 $\ell \leq \bar{\ell} = \frac{\sqrt{c_d}}{38} (1-\rho)^{-2/3}$, and that for
 $u \in \{0, 1, \cdots, \ell-1\}$,
 $I_u = I^{\prime}_u \geq d/2$. This concludes the proof of the lemma.
Lemma 3. The length  $b-s$ of the backlog clearing phase satisfies
 \begin{equation}b-s = c_r (1-\rho)^{-1} \log f,\end{equation}
where  $c_r = c_b - \sqrt{c_s c_b} \geq 1$. In particular,
 $b-s\geq 1$.
Lemma 3 was established in a similar way to Lemma 5.1 in [Reference Shah, Tsitsiklis and Zhong24]; we include its proof here for completeness.
Proof. In view of the definition of b in (37), we have that
 \begin{align*}b-s = &\,b-\rho b - \sqrt{c_s b \log f} \\= &\,c_b (1-\rho)^{-1} \log f - \sqrt{c_s c_b (1-\rho)^{-2} \log^2 f} \\= &\,(c_b - \sqrt{c_s c_b}) (1-\rho)^{-1} \log f = c_r (1-\rho)^{-1} \log f.\end{align*}
The fact that  $c_r \geq 1$ follows from the condition
 $c_b - \sqrt{c_s c_b} \geq 1$ in (40).
Lemma 4. The length  $d+s-b$ of the normal clearing phase satisfies
 \begin{equation}d+s-b \geq c_o (1-\rho)^{-4/3} \log f,\end{equation}
where  $c_o = c_d - c_r \geq 1$. In particular,
 $d+s-b \geq 1$.
Proof. We have
 \begin{align*}d+s-b = &\,d - (b-s) \\= &\,c_d (1-\rho)^{-4/3} \log f - c_r (1-\rho)^{-1} \log f \\\geq &\, (c_d - c_r) (1-\rho)^{-4/3} \log f \\= &\, c_o (1-\rho)^{-4/3} \log f.\end{align*}
By Lemma 3 and the condition  $c_d \geq c_b \geq c_s \geq 30$ in view of (40), we have
 \begin{align*}c_o = c_d - c_r = c_d - c_b+ \sqrt{c_s c_b} \geq \sqrt{c_s c_b} \geq c_s \geq 30.\\[-30pt]\end{align*}
7. Policy analysis
In this section, we provide a thorough analysis of the performance of our policy, and we prove the main result of the paper, Theorem 1. Our goal is to show that at any time, the expected total queue size is bounded above by O(nd), which immediately leads to Theorem 1. To do so, we consider what happens during the kth arrival period and the kth service period, and prove the following:
(i) During the first d slots of the arrival period, the expected total number of arrivals is O(nd).
(ii) With high probability, during the lower envelope phase, the policy uses full matchings for schedules, never idles, and does not waste any offered services (Lemma 5). As a result, the total queue size does not increase in expectation during this phase.
(iii) With high probability, all kth-batch arrivals can be cleared by the end of the normal clearing phase, and the number of new backlogged packets
$U_k$ equals 0 (Lemma 7). Then, by applying Kingman’s bound (Theorem 3) to the number of backlogged packets, $B_k$, we have $\mathbb{E}[B_k]\leq 1$ for all k (Lemma 8).


By properly accounting for different components that contribute to the total queue size at any given time, and using the facts (i)–(iii), we can establish the upper bound O(nd) on the expected total queue size (see Section 7.3).
7.1. No waste or idling during the lower envelope phase
Let  $k \in \mathbb{Z}_+$, and recall from Section 6 the policy description in the kth lower envelope phase. Note that in each time slot of this phase, the policy either uses a full matching or idles. The aim of the policy in this phase is to serve as many packets as possible. Since the phase consists of
 $b-d$ time slots, and at most n packets can be served in each slot, at most
 $n(b-d)$ packets can be served in this phase. There are two ways in which the policy may fail to serve
 $n(b-d)$ packets in this phase:
(i) a service is offered but there is no packet available to serve, in which case the corresponding offered service is wasted; or
(ii) the policy idles for at least one slot.
Let  $\mathcal{W}^k$ be the event that during the kth lower envelope phase, the policy fails to serve
 $n(b-d)$ packets. The following lemma states that with high probability,
 $\mathcal{W}^k$ does not happen.
Lemma 5. We have
 \begin{equation}{\mathbb P}(\mathcal{W}^k) \leq \frac{1}{2f^{13}}, \qquad {for\ all}\ k.\end{equation}
Proof. Let  $k \in \mathbb{Z}_+$. By the discussion preceding Lemma 5, we see that
 $\mathcal{W}^k$ is also precisely the event that there is either waste or idling in the kth lower envelope phase. Recall that the phase is divided into consecutive subintervals
 $I_1, I_2, \cdots, I_{\ell}$. For
 $u \in [\ell]$, let
 $\mathcal{W}^k_u$ denote the event that there is either waste or idling in subinterval
 $I_u$. Then it is easy to see that
 \begin{equation}\mathcal{W}^k = \mathcal{W}^k_1 \cup \mathcal{W}^k_2 \cup \cdots \cup \mathcal{W}^k_{\ell}.\end{equation}
We now claim that for sufficiently large n,
 \begin{equation}{\mathbb P}\Big(\mathcal{W}^k_u\Big) \leq \frac{1}{2f^{15}} \quad \text{for all } u \in [\ell],\end{equation}
from which it follows immediately that, by the union bound,
 \begin{equation}{\mathbb P}\Big(\mathcal{W}^k\Big) \leq \sum_{u=1}^{\ell} {\mathbb P}\Big(\mathcal{W}^k_u\Big)\leq \frac{\ell}{2f^{15}} \leq \frac{f^2}{2f^{15}} = \frac{1}{2f^{13}},\end{equation}
establishing the lemma. Here, the last inequality follows from Inequality (47) in Lemma 2 and the condition  $(1-\rho)^{-2/3} \geq \sqrt{c_d}/38$ in (41), so that
 \[\ell \leq \frac{\sqrt{c_d}}{38} (1-\rho)^{-2/3} \leq (1-\rho)^{-4/3} \leq f^2.\]
The rest of the proof is devoted to the proof of the claim.
By the conditions in (41), it is not difficult to see that
 \begin{equation}\rho d \geq 304 \log f.\end{equation}
Let  $u \in [\ell]$, and recall from Section 6 that
 $\textbf{\textit{A}}^{(u-1)} = (A^{u-1}_{ij})_{i,j=1}^n$ denotes the matrix of arrivals in subinterval
 $I_{u-1}$. Thus,
 $A_{ij}^{(u-1)}$ are i.i.d. binomial random variables with parameters
 $I_{u-1}$ and
 $\rho/n$. By Lemma 2,
 $I_{u-1} \geq d/2$, so
 \begin{equation}\rho I_{u-1} \geq \rho d/2 \geq 152 \log f.\end{equation}
Thus, by Theorem 5, with probability  $1-1/f^{16}$,
 $\textbf{\textit{A}}^{(u-1)}$ has a
 $\beta$-lower envelope with
 \begin{equation}\beta \geq \rho I_{u-1} - \sqrt{304 \rho I_{u-1} \log f} -1.\end{equation}
Then we have
 \begin{align}\beta \geq &\,\rho I_{u-1} - \sqrt{304 \rho I_{u-1} \log f}-1 \nonumber \\= &\,I_{u-1} - (1-\rho) I_{u-1} - \sqrt{304 \rho I_{u-1} \log f}-1 \nonumber \\\geq &\,I_{u-1} - (1-\rho) d - \sqrt{304 d \log f}-1 \nonumber \\= &\,I_{u-1} - c_d (1-\rho)^{-1/3} \log f - \sqrt{304 c_d (1-\rho)^{-4/3} (\!\log f)^2}-1 \nonumber \\= &\,I_{u-1} - c_d(1-\rho)^{-1/3} \log f - \sqrt{304 c_d} (1-\rho)^{-2/3} \log f-1 \nonumber \\\geq &\,I_{u-1} - \sqrt{c_d} (1-\rho)^{-2/3} \log f - 18 \sqrt{c_d} (1-\rho)^{-2/3} \log f \nonumber \\= &\,I_{u-1} - 19 \sqrt{c_d} (1-\rho)^{-2/3} \log f = I_{u-1} - 19 \sqrt{d\log f} \nonumber \\= &\,d - 19 u \sqrt{d\log f} = I_u.\end{align}
Here, the second inequality follows from the fact that  $I_{u-1} \leq d$ and
 $\rho \leq 1$, and the third inequality follows from the condition
 $(1-\rho)^{-2/3} \geq c_d$ of (41), and the condition (40).
So far, we have established that for any  $u \in [\ell]$, with probability
 $1-1/f^{16}$,
 $\textbf{\textit{A}}^{(u-1)}$ has an
 $I_u$-lower envelope. Under this event, during subinterval
 $I_u$, we can find
 $I_u$ full matchings to serve packets from
 $\textbf{\textit{A}}^{(u-1)}$ without any waste; this event is exactly the complement of
 $\mathcal{W}^k_u$. Thus, for sufficiently large n, for any
 $u \in [\ell]$,
 \begin{equation}{\mathbb P}\Big(\!\left(\mathcal{W}^k_u\right)^c\Big) \geq 1 - \frac{1}{f^{16}} \geq 1 - \frac{1}{2f^{15}},\end{equation}
establishing Inequality (55), and hence the claim and the lemma.
7.2. Backlog analysis
Define  $\textbf{\textit{A}}^k(b) = (A^k_{ij}(b))_{i,j=1}^n$, the matrix of kth-batch arrivals, by
 \begin{equation}A^k_{ij}(b) = A_{ij}\left((k+1)b\right) - A_{ij}(kb),\end{equation}
so that  $A^k_{ij}(b)$ is the number of arrivals to queue (i, j) in the kth batch. Let
 \begin{equation}R^k_i = \sum_{j^{\prime}=1}^n A^k_{ij^{\prime}}(b), \qquad C^k_j = \sum_{i^{\prime}=1}^n A^k_{i^{\prime}j}(b)\end{equation}
be the row and column sums for the kth-batch arrivals. Define events
 \begin{equation}\mathcal{R}^k_i = \{R^k_i > s\}, \qquad \mathcal{C}^k_j = \{C^k_j > s\},\end{equation}
and
 \begin{equation}\mathcal{E}^k = \left(\mathcal{R}^k_1 \cup \mathcal{R}^k_2 \cup \cdots \cup \mathcal{R}^k_n \right)\cup \left(\mathcal{C}^k_1 \cup \mathcal{C}^k_2 \cup \cdots \cup \mathcal{C}^k_n \right).\end{equation}
Lemma 6. For sufficiently large n, we have that
 \begin{equation}{\mathbb P}\Big(\mathcal{E}^k\Big) \leq \frac{1}{2f^{13}}, \qquad {for\ all}\ k.\end{equation}
Lemma 6 is similar to Lemma 6.3 of [Reference Shah, Tsitsiklis and Zhong24]; we include its proof here for completeness.
Proof. Consider the event  $\mathcal{R}^k_1 = \{R^k_1 > s\}$. Note that
 $\mathbb{E}[R^k_1] = \rho b$. By Inequality (11) of Theorem 2, we have
 \begin{align*}{\mathbb P}\Big(R^k_1 > s\Big) & = {\mathbb P}\Big(R^k_1 > \rho b + \sqrt{c_s b\log f}\Big) \\
& = {\mathbb P}\Big(R^k_1 > \mathbb{E}\left[R^k_1\right] + \sqrt{c_s b\log f}\Big) \\
& \leq \exp\bigg({-}\frac{c_s b \log f}{2(\rho b+ x/3)}\bigg),\end{align*}
where  $x = \sqrt{c_s b\log f}$. Also note that by Lemma 3,
 \[\rho b+ x/3 \leq \rho b+ x = \rho b + \sqrt{c_s b\log f} = s \leq b.\]
Thus,
 \[{\mathbb P}\Big(R^k_1 > s\Big) \leq \exp\Big({-}\frac{c_s b \log f}{2b}\Big) = \frac{1}{f^{c_s/2}} \leq \frac{1}{4f^{14}},\]
where in the last inequality we used the conditions  $n \geq 4$ of (41) and
 $c_s \geq 30$ of (40). We have similar inequalities for other events
 $\mathcal{R}^k_i$ and
 $\mathcal{C}^k_j$, and by a simple union bound, we have
 \[{\mathbb P}\Big(\mathcal{E}^k \Big) \leq \frac{2n}{4 f^{14}} \leq \frac{1}{2 f^{13}}.\]
Lemma 7. Let  $k \in \mathbb{Z}_+$ be fixed. Then the following hold.
(a)
$U_k = 0$ on any sample path where neither $\mathcal{W}^k$ nor $\mathcal{E}^k$ occurs.(b)
${\mathbb P}(U_k > 0)\leq 1/f^{13}$.(c) On any sample path, we have
$U_k \leq n^2 b$.


Note that Lemma 7 is similar to Lemma 6.4 of [Reference Shah, Tsitsiklis and Zhong24]. We provide the proof of the lemma here for completeness.
Proof. (a) Recall the matrix  $\textbf{\textit{A}}^k(b)$ of kth-batch arrivals defined in Equation (62). Let
 $\hat{\textbf{\textit{Q}}^k} = (\hat{Q^k}_{ij})_{i,j=1}^n$ be the matrix of kth-batch arrivals that remain by the end of the lower envelope phase, and let
 \begin{equation}\hat{R}_i = \sum_{j^{\prime}=1}^n \hat{Q}^k_{ij^{\prime}}, \qquad \hat{C}_j = \sum_{i^{\prime}=1}^n \hat{Q}^k_{i^{\prime}j}\end{equation}
be the row and column sums of  $\hat{\textbf{\textit{Q}}^k}$.
Suppose that  $\mathcal{W}^k$ does not occur. Then, during the lower envelope phase, the policy served
 $n(b-d)$ packets from
 $\textbf{\textit{A}}^k(b)$, and each row/column sum decreases by exactly
 $b-d$ by the end of the phase. More precisely,
 \begin{equation}\hat{R}_i = R_i - (b-d), \text{ and } \hat{C}_j = C_j - (b-d), \text{ for all } i, j \in [n],\end{equation}
where we recall that  $R_i$ and
 $C_j$ are the row and column sums of
 $\textbf{\textit{A}}^k(b)$ (cf. Equation (64)).
Suppose that  $\mathcal{E}^k$ does not occur. Then
 $R_i \leq s$ for all i and
 $C_j \leq s$ for all j. Thus, if neither
 $\mathcal{W}^k$ nor
 $\mathcal{E}^k$ occurs, then
 \begin{equation}\hat{R}_i \leq s-(b-d) = d+s-b, \text{ and } \hat{C}_j \leq d+s-b, \text{ for all } i, j.\end{equation}
But  $d+s-b$ is the length of the normal clearing phase, so all arrivals from the kth batch will be cleared by the end of the normal clearing phase, using the optimal clearing policy described after Theorem 4, and then
 $U_k = 0$.
(b) By part (a), we have
 \[{\mathbb P}(U_k > 0) \leq {\mathbb P}\left(\mathcal{W}^k \cup \mathcal{E}^k \right) \leq \frac{1}{f^{13}}.\]
(c) The number of packets that can get backlogged from any batch cannot be more than the total number of arrivals from that batch, which is bounded above by  $n^2b$.
Lemma 8. Assuming that n is sufficiently large, we have that  $\mathbb{E}[B_k] \leq 1$ for all k.
Lemma 8 is similar to Lemma 6.5 of [Reference Shah, Tsitsiklis and Zhong24], and we only provide a sketch of its proof here. Recall the dynamics of the backlogged packets in Equation (44), so that
 \[B_{k+1} = \left(B_k+U_k - (b-s)\right)^+ \leq \left(B_k+U_k - 1\right)^+,\]
where the inequality follows from Lemma 3. Then, we can bound each  $B_k$ from above sample-path-wise by
 $\hat{B}_k$, where
 $\hat{B}_0 = 0$, and
 \[\hat{B}_{k+1} = \left(\hat{B}_k+U_k - 1\right)^+.\]
Using the notation of Theorem 3 for  $\hat{B}_k$, we have
 $\mu = 1, m_{2y} = 1$. We can also show that
 \begin{align}\lambda = \mathbb{E}\big[U_k\big] \leq f^{-7}, \text{ and } m_{2x} = \mathbb{E}\Big[U_k^2\Big] \leq f^{-1}.\end{align}
Finally, a direct application of Theorem 3 gives
 \[\mathbb{E}\big[B_k\big] \leq \mathbb{E}\Big[\hat{B}_k\Big] \leq 1,\]
for sufficiently large n.
7.3. Queue size analysis
In this subsection, we prove Theorem 1, the main result of this paper. The analysis is similar to the one in [Reference Shah, Tsitsiklis and Zhong24]. We fix a time slot  $\tau$ and consider two cases, depending on whether
 $\tau$ is in a lower envelope phase or not.
To facilitate the analysis, we introduce the following notation; the same notation was also used in [Reference Shah, Tsitsiklis and Zhong24]. Let  $t \in [b+1]$, which will be used to index the b slots of the kth arrival period and the first slot of the kth normal clearing phase. For
 $t \in [b]$, let
 $A^k_{ij}(t)$ denote the number of arrivals to queue (i, j) during the first t slots of the kth arrival period, so
 \begin{equation}A^k_{ij}(t) = A_{ij}(kb+t) - A_{ij}(kb).\end{equation}
Note that this notation is consistent with that introduced earlier, in Equation (62) of Section 7.2. Next, for  $t \in [b]$, let
 $S^k_{ij}(t)$ denote the number of kth-batch packets that arrive in queue (i, j) and get served during the first t slots of the kth batch. Finally, for
 $t \in [b]$ (
 $t = b+1$, respectively), let
 $Q^k_{ij}(t)$ be the number of kth-batch packets in queue (i, j) at the beginning of the tth slot of the kth arrival period (the first slot of the kth normal clearing phase, respectively). Then we have
 \begin{equation}Q^k_{ij}(t+1) = A^k_{ij}(t) - S^k_{ij}(t).\end{equation}
Queue size during the lower envelope phase. Consider a time slot  $\tau$ that belongs to the kth lower envelope phase, so that
 $kb+d+1 \leq \tau \leq (k+1)b$, and consider the total queue size
 $\sum_{i,j=1}^n Q_{ij}(\tau+1)$. This queue size includes two components: backlogged packets from previous service periods, and kth-batch packets.
By Lemma 8, the number  $B_k$ of backlogged packets satisfies
 \begin{equation}\mathbb{E}[B_k]\leq 1.\end{equation}
Next, consider the kth-batch packets that contribute to the queue size  $\sum_{i,j=1}^n Q_{ij}(\tau+1)$. Let
 $t = \tau - kb$, and recall the definition of
 $Q^k_{ij}(t+1)$ from Equation (72). Then,
 \begin{equation}\sum_{i,j=1}^n Q_{ij}(\tau+1) = B_k + \sum_{i,j=1}^n Q^k_{ij}(t+1).\end{equation}
Also recall the definitions of  $A^k_{ij}(t)$ and
 $S^k_{ij}(t)$. First, we have
 \begin{equation}\mathbb{E}\Bigg[\sum_{i,j=1}^n A^k_{ij}(t)\Bigg] = \frac{\rho}{n}\cdot n^2 t = \rho n t.\end{equation}
Second, recall the definition of event  $\mathcal{W}^k$ in Section 7.1. If event
 $\mathcal{W}^k$ does not occur,
 \begin{equation}\sum_{i,j=1}^n S^k_{ij}(t) = n(t-d).\end{equation}
Thus, by Lemma 5,
 \begin{align*}\mathbb{E}\Bigg[\sum_{i,j=1}^n S^k_{ij}(t)\Bigg] & \geq n(t-d) (1-{\mathbb P}(\mathcal{W}^k)) \\& \geq \left(1-\frac{1}{f^{13}}\right) n(t-d)\geq \rho n(t-d).\end{align*}
Thus,
 \begin{align}\mathbb{E}\Bigg[\sum_{i,j=1}^n Q^k_{ij}(t+1) \Bigg] = &\,\mathbb{E}\Bigg[\sum_{i,j=1}^n A^k_{ij}(t)\Bigg] - \mathbb{E}\Bigg[\sum_{i,j=1}^n S^k_{ij}(t)\Bigg] \nonumber \\\leq &\, \rho n t - \rho n(t-d) \nonumber \\= &\, \rho n d \leq nd, \quad t = d+1, \cdots, b.\end{align}
By Equation (74) and Inequalities (73) and (77),
 \begin{equation}\mathbb{E}\Bigg[\sum_{i,j=1}^n Q_{ij}(\tau+1)\Bigg] = \mathbb{E}\Bigg[B_k + \sum_{i,j=1}^n Q^k_{ij}(t+1)\Bigg]\leq 1 + nd \leq 2nd.\end{equation}
Queue size outside the lower envelope phase. This part of the analysis is the same as that in Section 6.4 of [Reference Shah, Tsitsiklis and Zhong24], and is provided here for completeness. Let time slot  $\tau$ belong to either the kth normal clearing phase or the kth backlog clearing phase, so that
 $(k+1)b+1 \leq \tau \leq (k+1)b+d$, and consider the total queue size
 $\sum_{i,j=1}^n Q_{ij}(\tau+1)$. This queue size includes three components: backlogged packets, kth-batch packets, and new arrivals from the
 $(k+1)$th batch.
The backlogged packets may be from previous service periods or from the kth batch; the number of the former is given by  $B_k$, and the number of the latter is bounded above by
 $U_k$. Thus, in view of (70) and (73), the expected total number of backlogged packets is bounded above by
 $\mathbb{E}[B_k + U_k]\leq 2$.
Next, consider the kth-batch packets that contribute to  $\sum_{i,j=1}^n Q_{ij}(\tau+1)$. The number of these packets is largest at the beginning of slot
 $(k+1)b+1$, since there are no kth-batch arrivals from time slot
 $(k+1)b+1$ onwards. Thus, the expected value of the number of these packets is bounded above by
 \[\mathbb{E}\Bigg[\sum_{i,j=1}^n Q^k_{ij}(b+1)\Bigg] \leq nd,\]
where the inequality follows from Inequality (77) for  $t = b$.
Finally, the number of arrivals from the  $(k+1)$th batch is largest at time
 $(k+1)b+d$, and the expectation of this number is bounded above by
 \[\mathbb{E}\Bigg[\sum_{i,j=1}^n A^{k+1}_{ij}(d)\Big] = \frac{\rho}{n}\cdot n^2 d = \rho n d \leq nd.\]
Therefore, the expected total queue size  $\mathbb{E}[\sum_{i,j=1}^n Q_{ij}(\tau+1)]$ is bounded above by
 $2+nd + nd \leq 3nd$.
8. Discussion
In this paper, we proposed a new scheduling policy for input-queued switches when all arrival rates are equal. In the regime  $1-\rho = \Theta(n^{-1})$, our policy gives an upper bound of
 $O\Big(n^{7/3}\log n\Big)$ on the expected total queue size, improving the state-of-the-art bound
 $O\big(n^{2.5}\log n\big)$. Like the policy in [Reference Shah, Tsitsiklis and Zhong24], ours is of the batching type, and it starts serving packets much earlier than the time when a whole batch has arrived. A central component of our policy is the ability to efficiently serve packets without waste, from subintervals that are shorter than a whole batch, which makes crucial use of a novel, tight characterization of the largest k-factor in a random bipartite (multi-)graph, which may be of independent interest. Note that the amount of computation required by our policy at each time slot is at most polynomial in n, as the largest k-lower envelope of a queue matrix, or equivalently the largest k-factor in a bipartite (multi-)graph, can be found via computing the maximum flow in polynomial time.
In the regime  $1-\rho = \Theta(n^{-1})$, while our upper bound on the expected total queue size is
 $O\big(n^{7/3}\log n\big)$, the conjectured scaling is
 $\Theta(n^2)$. It remains an important and interesting challenge to see whether the gap can be closed. Among the class of the batching-type policies considered in our paper and in [Reference Shah, Tsitsiklis and Zhong24], it appears difficult, if not altogether impossible, to reduce the gap, for the following reason. On the one hand, a batching-type policy like ours needs to wait for enough packets to arrive for a certain level of statistical regularity to emerge. On the other hand, the number of arrivals that the policy waits for directly determines the queue-size scaling that can be achieved. The level of regularity required in our policy seems to be the least stringent, given that our characterization of the largest k-factor in a random bipartite multigraph is tight. Thus, we believe that fundamentally new methodological tools and design of much more elaborate policies are required to make further progress on the queue-size scaling, at least in the regime
 $1-\rho = \Theta(n^{-1})$.
Acknowledgement
J. Xu was supported in part by the NSF Grants IIS-1932630, CCF-1850743, and CCF-1856424.



