


1. INTRODUCTION
Let M = [m1,…,mp]′ be an unknown p × q constant matrix, where p ≥ q, that is observed with additive random error. Recorded is the p × q data matrix X = [x1,…,xp]′ modeled by

Here E = [e1,…,ep]′ is a p × q random error matrix that has the following properties: the column vectors {ei : 1 ≤ i ≤ p} are independent, and for every i, E(ei) = 0 and Cov(ei) = σ2Iq. Typically both M and σ2 > 0 are unknown. Equation (1) is a multivariate trend model that relates successive vector observations, the rows of the observed X, to successive vector means, the rows of the unknown M. A basic problem is to estimate M and σ2.
The Frobenius (or euclidean) norm of a matrix B is defined by |B|2 = tr(BB′) = tr(B′B). Let

denote any estimator of M = [m1,…,mp]′. The quality of

is assessed through the quadratic loss

The risk of

is then

the expectation being computed under the model (1).
The risk of the classical unbiased estimator X of M is just σ2. This paper develops better estimators of M that trade off bias against variance so as to reduce quadratic risk. The fundamental idea is to estimate M by shrinking the rank or, more generally, the singular values of the data matrix X. It is important to note that the risk analysis in the basic problem will make no assumption on the rank of M, even though some of the estimators devised for M have less than full rank.
The total least squares (TLS) estimator of order k for M is

Suppose that the singular value decomposition of X is

where

is p × q,

is q × q,

, and

with

. By the Eckart–Young matrix approximation theorem,

Derivations of (6) as solution to the minimization problem (4) are given in Golub and Van Loan (1980, 1996) and in Van Huffel and Vandewalle (1991). Existence of numerically stable algorithms for computing the singular value decomposition is an important advantage of representation (6) for

.
How should we choose k in (6) to minimize the quadratic risk of

as an estimator of M? The answer necessarily takes into account the noise level σ2. Let

be a consistent estimator of σ2. Sections 3 and 4 find an asymptotically best data-based choice

of k:

It is understood that

if

. The corresponding adaptive TLS estimator is then

In notation akin to (5), suppose that the singular value decomposition of M is

where U = [u1,…,uq] is p × q, V = [v1,…,vq] is q × q, U′U = V′V = VV′ = Iq, and L = diag(l1,…,lq) with l1 ≥ ··· ≥ lq ≥ 0. Let

It is shown in Section 4 that the risk of

converges asymptotically, as p tends to infinity, to

Moreover,

also converges to the value (11). In this manner, the adaptive TLS estimator

behaves asymptotically like the best of the competing TLS estimators

. The result makes no assumption on the rank of the unknown M.
It is evident from (8) that

applies a shrinkage factor that is either 1 or 0 to each summand in the singular value decomposition (5) of the unbiased estimator X. Can using other shrinkage factors reduce asymptotic risk below that of

? The answer is yes. It is shown in Sections 3 and 4 that the adaptive total shrinkage (TS) estimator

has smaller risk asymptotically than the adaptive TLS estimator of M. Indeed, the risk of

converges asymptotically, as p tends to infinity, to

which cannot exceed (11) and can be smaller. Section 5.1 extends low risk estimation of M to the more general setting where Cov(ei) = σ2K with K a known positive definite matrix.
A second problem is to estimate M and σ2 under the restriction that rank(M) is q − 1. Model (1) plus this rank restriction defines an errors-in-variables linear regression model in which the columns of M satisfy the linear relation Mvq = 0. The extensive literature on fitting this model uses a variety of other labels, including “total least squares,” “orthogonal regression,” and “measurement error modeling.” For results and further references, see Anderson (1976), Fuller (1987), Gleser (1981), Golub and Van Loan (1980), Van Huffel and Vandewalle (1991), and Van Huffel (2004). This literature develops the estimator

for vp and the TLS estimator

for M. Section 5.2 constructs rank constrained adaptive TLS and TS estimators of M that achieve smaller asymptotic risk than

under the errors-in-variables model. Again, the key is to trade off bias against variance so as to reduce risk.
2. ORACLE ESTIMATORS
This section studies classes of candidate linear estimators for M, constructing within each class an estimator that minimizes the quadratic risk (3). The best such estimators are oracle estimators in that they depend on functions of the unknown parameters M and σ2. The labeling of the oracle estimators foreshadows their linkage, in Sections 3 and 4, with the adaptive TLS and TS estimators described in the Introduction.
2.1. Oracle Linear Estimators
Let A be an arbitrary q × q matrix. This section considers the candidate linear estimator XA for M. The quadratic risk (3) of XA is

where B = A′. This risk is a strictly convex function of B. Expanded algebraically,

We find the matrix

that minimizes (15). Let

The matrix derivatives
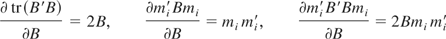
(see Rao and Toutenberg, 1995, Sect. A.15) entail that

Setting this risk derivative equal to zero and simplifying yields the minimizing matrix

Applying (9) to (16) and (19) yields the expressions

with πj as in (10). The matrix

is evidently a symmetric q × q matrix whose eigenvalues all lie in [0,1].
Thus, the linear estimator XA with smallest quadratic risk is

. It is an oracle estimator because its definition involves the unknown parametric function W and σ2. By substitution of

into (14), the risk of the oracle linear estimator is seen to be (13). Section 3 constructs an adaptive estimator whose risk converges asymptotically to this desirable value.
2.2. Oracle Symmetric Affine Shrinkage Estimators
Let

denote the set of all q × q symmetric matrices whose eigenvalues lie in [0,1]. By the analysis of Section 2.1, it is reasonable to limit the search for low risk candidate linear estimators to the symmetric affine shrinkage class

. Let

denote those symmetric matrices whose eigenvalues are either 0 or 1. This is the class of orthogonal projections into Rq. For 0 ≤ k ≤ q, let

denote the orthogonal projections that have eigenvalue 1 with multiplicity k and eigenvalue 0 with multiplicity q − k. Evidently

For every

, the risk (14) of the linear estimator XA simplifies to

where

Of interest for subsequent developments are the following oracle estimators, obtained by minimizing risk over various closed subsets of

:
[bull ] The oracle TS estimator of M is

, where

[bull ] The oracle order k TLS estimator of M is

, where

[bull ] The oracle TLS estimator of M is

, where

The labels given to the oracle estimators are justified by their linkage to adaptive TLS and TS estimators in Sections 3 and 4. The next theorem provides explicit formulas for these oracle estimators and their risks. The following properties of the {πj : 1 ≤ j ≤ q}, defined by (10), assist understanding of this theorem:
- The {πj} are nonincreasing in j and all lie in [0,1].
- pσ2(1 − πj)−1 = pσ2 + lj2.
- p−1|ljujvj′|2/σ2 = (p−1lj2)/σ2 = πj/(1 − πj) is the mean square signal-to-noise ratio of the jth summand in the singular value decomposition of M.
- πj > ½ if and only if the foregoing signal-to-noise ratio exceeds 1.
- πj = 0 if and only if the foregoing signal-to-noise ratio is 0.
THEOREM 2.1. The following expressions hold:

with

defined in (19), and

and

Proof. The first expression in (27) follows from (23) and (20) or from Section 2.1.
Consider symmetric matrices A that take the form

where each fj ∈ [0,1]. For such A, (20) and the second equality of (23) imply

The second expression in (27) follows by applying (31) to the first expression in (27).
For every

, (23) gives

This and (25) entail

In this equation, rank(AW1/2) ≤ k under the constraint rank(A) = k. By the Eckart–Young matrix approximation theorem and (20), the best approximation in norm of rank ≤ k to W1/2 is

This quantity equals

when

is given by the first expression in (29), thereby justifying that formula. The second expression follows from (31) because

has the form (30).
Because

minimizes risk over the matrices

, finding it amounts to minimizing the risk (31) over {fj} values that are either 0 or 1. The minimum risk is achieved by setting fj = 1 when πj > ½ and fj = 0 otherwise. The expressions in (28) follow. In other words, the optimal choice of k in constructing the oracle TLS estimator is

. Note that the first

summands in the singular value decomposition of M are precisely those summands whose signal-to-noise ratio exceeds 1. This makes

an intuitively plausible thresholding estimator. █
3. ADAPTIVE ESTIMATORS
This section devises adaptive estimators that are realizable data-based approximations to the oracle estimators discussed in Section 2. The oracle construction is modified by replacing the risk function r(A,W,σ2), which contains unknown parameters, with an estimated risk function. The resulting adaptive estimators coincide with the TS and TLS estimators described in the Introduction. It will be seen in Section 4 that the risk of each adaptive estimator converges to that of its oracle counterpart as p tends to infinity.
3.1. Estimated Risk and Adaptation
Let

be an L1-consistent estimator of σ2. Two constructions of

are described in Section 4.1. It will be seen in proving Theorem 4.3 that limp→∞supp−1|M|2≤c E|p−1X′X − W − σ2Iq|2 = 0 for every finite c > 0. This suggests estimating W by

Let

Applying singular value decomposition (5) yields

for

as in (7). The estimated risk of the candidate symmetric affine shrinkage estimator XA is defined to be

Corresponding to the oracle estimators discussed in Section 2.2 are the following adaptive estimators, obtained by minimizing estimated risk over various closed subsets of

:
[bull ] The adaptive TS estimator of M is

, where

[bull ] The adaptive order k TLS estimator of M is

, where

[bull ] The adaptive TLS estimator of M is

, where

The next theorem shows that these adaptive estimators coincide with TLS and TS estimators discussed in the Introduction and provides formulas for their estimated risks. The following properties of the

, defined by (7), assist understanding of this theorem:
- The
are nonincreasing in j with values that do not exceed 1 but can be negative, unlike the values of the {πj}.

- .
- is an asymptotically unbiased estimator for p−1lj2 as p tends to infinity (cf. the reasoning for Theorem 4.3 and, more generally, Van Huffel and Vandewalle (1991)).
- Hence,
estimates the mean square signal-to-noise ratio (p−1lj2)/σ2 = p−1|ljujvj′|2 = πj/(1 − πj) of the jth summand in the singular value decomposition of M.
- if and only if the foregoing estimated signal-to-noise exceeds 1.
- if and only if the foregoing estimated signal-to-noise ratio is nonnegative.


Unlike its oracle counterpart

, the matrix

defined in (37) has eigenvalues less than or equal to 1 rather than in [0,1]. Define

Note that

,

, and

. The adaptive TS estimator involves

.
THEOREM 3.1. The following expressions hold:

and

and

Consequently,

Proof. Let

From the second equality in (38),

Observe that

For every

,

because A is positive semidefinite. Similarly,

. Moreover,

. Hence, (49) implies

On the other hand,

From (51) and (52),

, and the minimum is achieved when

. This proves the first expression in (43).
Consider symmetric matrices A that take the form

where each fj ∈ [0,1]. For such A, (37) and the second equality in (38) imply

The second expression in (43) follows by applying (54).
For every

, the first equality in (38) and (47) imply

This and (40) entail

In this equation,

under the constraint rank(A) = k. By the Eckart–Young matrix approximation theorem and (47), the best approximation in norm of rank ≤ k to

is

This quantity equals

when

is given by the first expression in (45), thereby justifying that formula. The second expression in (45) follows from (54) because

has the form (53).
Because

minimizes estimated risk over the matrices
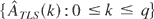
, finding it amounts to minimizing the estimated risk (54) over {fj} values that are either 0 or 1. The minimum risk is achieved by setting fj = 1 when

and fj = 0 otherwise. The expressions in (44) follow. In other words, the optimal choice of k in constructing the adaptive TLS estimator is

. Note that the first

summands in the singular value decomposition of M are precisely those summands whose estimated signal-to-noise ratio exceeds 1. This makes

an intuitively plausible thresholding estimator.
The expressions (46) for

and

follow from their definitions and the already proved parts of Theorem 3.1. █
3.2. Total Shrinkage and the Efron–Morris Estimator
In the case of Gaussian errors, empirical Bayes estimators of M may be constructed as follows. Suppose that the conditional distribution of xi given mi is N(mi,σ2Iq) and that the {xi} are conditionally independent. Suppose that the {mi} are independent and that the distribution of mi is N(0,W). Under quadratic loss, the Bayes estimator of M is then the oracle estimator

.
Because

is a consistent estimator of

in the Bayes model, the adaptive TS estimator

derived in Theorem 3.1, is an empirical Bayes estimator of M. Another consistent estimator of

in the Bayes model is

, which need not belong to

for finite p. This generates the empirical Bayes estimator

Related estimators, albeit more complex, have been used by Green, Berman, Switzer, and Craig (1985) to analyze multiband satellite image data. The Efron and Morris (1976) estimator of M, assuming σ2 known, is

The estimator

generalizes the positive-part James and Stein (1961) estimator to q-dimensional means, and the estimator

in (59) similarly generalizes the James–Stein estimator. The Efron–Morris estimator

is a refinement of

whose efficacy in reducing risk depends on the Gaussian error assumption. Under Assumptions A1 and A2 of Section 4, which do not assume Gaussian errors, the risks of

,

, and

converge as p tends to infinity, as do the estimators themselves in terms of the normalized loss metric. Each of these symmetric affine shrinkage estimators has a computationally stable expression in terms of the singular value decomposition of X. Moreover, the singular value representations reveal the relationship between these shrinkage estimators and the adaptive TLS estimator

.
4. ASYMPTOTIC THEORY
This section develops asymptotic theory in which row dimension q is fixed as column dimension p tends to infinity. First, it is found that the loss of

or

converges to its respective risk. Second, the risk (or loss) of

or

converges to that of its oracle counterpart. Third, the estimated risk of

or

converges to its risk (or loss). The convergences are uniform when the signal-to-noise ratio (pσ2)−1|M|2 and the variance σ2 are both bounded. For simplicity, the notation often omits the dependence of quantities on p.
4.1. Convergence of Loss, Risk, and Estimated Risk
Let

denote the set of all symmetric matrices A = {aij} such that maxi,j|aij| ≤ 1. Evidently

. The following assumptions support the asymptotic results:
A1. The error vectors {ei : 1 ≤ i ≤ p} are independent, identically distributed, such that E(ei) = 0, Cov(ei) = σ2Iq, where σ2 > 0 is unknown.
A2. Under the model of Assumption A1, the variance estimator

satisfies

for every finite c > 0.
THEOREM 4.1. Suppose that Assumptions A1 and A2 hold. Let T(A) denote either the loss L(XA,M) or the estimated risk

of candidate estimator XA. Then, for every finite c > 0 and every finite σ2 > 0,

This theorem shows that the loss, risk, and estimated risk of candidate estimator XA converge asymptotically. The uniformity of this convergence over all

makes estimated risk a trustworthy surrogate for the true loss or risk.
THEOREM 4.2. Suppose that Assumptions A1 and A2 hold. Then, for every finite c > 0 and for every finite σ2 > 0,

Moreover, for S equal to either the loss

or the risk

,

Replacing the subscript TS by TLS in these statements yields valid assertions about

.
By (63), the risk of the adaptive TS estimator

converges to the risk of the oracle TS estimator

, which achieves minimum risk over the class of symmetric affine shrinkage estimators

. By (64), the plug-in estimator

of the risk of

converges to the actual risk or loss of

. In this manner, we can gauge directly from the data how well adaptation has controlled risk. Theorem 3.1 gives a convenient, computationally stable expression for

. Analogous statements hold for the parts of Theorems 4.2 and 3.1 that concern the adaptive TLS estimator

.
Variance Estimation.
It remains to construct suitably consistent estimators of σ2. When enough repeated observations are available on rows of M, the least squares estimator of σ2 satisfies Assumption A2. In the absence of replication, we may consider the smallest singular value estimator

The next theorem shows that

is asymptotically biased upward in general and satisfies Assumption A2 under a restriction on the magnitude of the smallest singular value of M.
THEOREM 4.3. Suppose that Assumption A1 holds and that the q components of each ei have finite fourth moments. Then, for every finite c > 0 and for every finite σ2 > 0,

Let {εp ≥ 0 : p ≥ 1} be any sequence such that limp→∞ εp = 0. Then

Thus,

is a consistent estimator of σ2 provided that lq2/p tends to zero as p tends to infinity. If

is used to construct the adaptive TS and TLS estimators, then Theorems 4.1 and 4.2 continue to hold with one modification: the supremum over all M such that p−1|M|2 ≤ c must be replaced by the supremum over M such that p−1|M|2 ≤ c, p−1lq2 ≤ εp. This recognizes that (67) holds for

rather than Assumption A2.
When σ2 is estimated by

, then the

in (7) that defines the adaptive TLS estimator simplifies elegantly to

. The interpretation of

remains as described in the proof of Theorem 3.1: the first

summands in the singular value decomposition of M are precisely those summands whose estimated signal-to-noise ratio exceeds 1.
4.2. Numerical Experiment
The pertinence of the asymptotic theory to finite sample sizes can be checked on artificial data. We report one experiment with

and

. Let {ui : 1 ≤ i ≤ 4} be independent 100 × 1 random vectors, the elements of each being independent uniform [0,1] random variables. Set

Let M be the result of rounding each entry in the matrix [c1,c2,c3,c4,c5] to the nearest integer. Let E be a 100 × 5 matrix of independent normal(0,σ2) random variables, with σ2 = 25, each rounded to the nearest integer. Set X = M + E. This construction satisfies Assumption A1 with p = 100 and q = 5.
For an instance of such artificial data constructed in S-Plus (code available from the author), the variance estimate

approximates σ2 = 25, the vectors

are close, and

The estimated singular values exhibit an upward bias that is caused by the errors E. Theorem 4.3 explains this for the smallest singular value, and similar analysis is available for the others.
Because the data have been constructed, it is possible to compute oracle estimators and to compare their loss and risk with that of the unbiased estimator X. In particular, using risk expressions in Theorem 2.1,

The rank of the oracle TLS estimator is 3. As expected from limits in Theorem 4.2, the loss and risk are close to one another for each oracle estimator and are smaller for the oracle TS estimator than for the oracle TLS estimator. Both the oracle TLS estimator and the oracle TS estimator dominate the unbiased estimator X substantially.
Using estimated risk expressions in Theorem 3.1, the loss and estimated risk of the adaptive estimators are

The rank of the adaptive TLS estimator is 3, like that of its oracle counterpart. The loss and estimated risk approximate one another for each adaptive estimator and are smaller for the adaptive TS estimator than for the adaptive TLS estimator. Moreover, the loss of the adaptive TS or TLS estimator is only slightly larger than the loss of its oracle counterpart. These findings are again consistent with limits in Theorem 4.2. Both the adaptive TLS estimator and the adaptive TS estimator dominate the unbiased estimator X substantially.
4.3. Proofs
We first state three propositions that will be used in proving Theorem 4.1. Let the {λi(B)} denote the eigenvalues of any symmetric matrix B and let λmax(B) denote the largest eigenvalue. The spectral norm of any matrix B, symmetric or not, is defined by

Let lmax(B) denote the largest singular value of B.
PROPOSITION 4.4.
(i) |·|s is a matrix norm.
(ii) If matrices A and B have compatible dimensions, |AB|s ≤ |A|s|B|s.
(iii) If u is a row or column vector, |u|s = |u|.
(iv) If vectors u, v and matrix A have compatible dimensions, |u′Av| ≤ |u||v||A|s.
(v) |B|s = λmax1/2(B′B) = lmax(B) = lmax(B′) = λmax1/2(BB′) = |B′|s.
(vi) |B|s ≤ |B|.
(vii) If B is symmetric, then |B|s = λmax1/2(B2) = maxi|λi(B)| and |B2|s = |B|s2.
(viii) If B is q × q symmetric, then q−1|tr(B)| ≤ |B|s.
These properties follow readily from the definitions given.
PROPOSITION 4.5. Let {Yp : p ≥ 1} be random elements of C([−1,1]d), the set of all continuous real-valued functions on [−1,1]d. Let plimp→∞ denote the limit in probability as p → ∞. Suppose that

and that

Then

The assumptions of Proposition 4.5 imply the weak convergence in C([−1,1]d) of {Yp : p ≥ 1} to the zero element. From this, (76) follows. See Wichura (1971) for a short proof of the weak convergence.
PROPOSITION 4.6. Suppose that {yp : p ≥ 1}, y, {zp : p ≥ 1}, and z are nonnegative random variables such that plimp→∞yp = y, yp ≤ zp a.s. for every p, Ez < ∞, and limp→∞ E|zp − z| = 0. Then limp→∞ E|yp − y| = 0.
Indeed, the conditions on the {zp} and z imply that the {zp} are uniformly integrable. Hence, so are the {yp}. The result follows (cf. Neveu, 1965, p. 52).
Proof of Theorem 4.1. For any symmetric q × q matrix A = {aij}, let a = {{aij : 1 ≤ i ≤ j},1 ≤ j ≤ q} denote the diagonal and subdiagonal elements of A, organized as a column vector of dimension d = q(q + 1)/2. The function A(a) that maps a ∈ [−1,1]d to

is one-to-one and onto. In the proof, we identify A with A(a) and treat the loss, risk, and estimated risk of a candidate estimator XA as functions of a. For convenient notation, let r(a) = r(A,W,σ2) as defined in (23), let

as defined in (38), and let T(a) = T(A) as in the theorem statement.
The strategy is to show that T(a) − r(a) converges in probability to zero for every a ∈ [−1,1]d, and then use Proposition 4.5 to show that supa∈[−1,1]k|T(a) − r(a)| converges in probability to zero, and finally invoke Proposition 4.6 to establish (62). Repeatedly used are the constraint p−1|M|2 ≤ c and the following properties of B = B(a) = A2 and B = B(a) = (Iq − A)2. For i ≤ j, the operator ∇ij denotes partial differentiation with respect to the element aij of a.


These bounds use Proposition 4.4 and the identity ∇ijB = ∇ijA·A + A·∇ijA.
We first prove the case

of (62). Define

by replacing

with σ2 in the definition (38) of

. Because of the inequality

and Assumption A2, we may replace

by r(a) in the subsequent argument.
Pointwise Consistency. Let

By the law of large numbers,

. Moreover,

and

Thus, for every a ∈ [−1,1]d,

Uniform Consistency. For any a, b in [−1,1]d,

where

for some

on the line segment that joins a and b. Thus

Moreover, using Proposition 4.4,

Applying Markov's inequality and (78) to the right-hand side of (85) establishes existence of a finite constant C, not depending on p, such that

Hence,

Limits (82) and (87) plus Proposition 4.5 yield

L1 Uniform Consistency. Let yp = supa∈[−1,1]d|Yp(a)|. Using (80),

Let

. It follows by the Cauchy–Schwarz inequality and (77) that

By the law of large numbers, wp converges in probability to its expectation qσ2. By Vitali's theorem,

Let z be the constant obtained from zp, the right-hand side of (90), by replacing each instance of wp with qσ2. It follows from (91) that limp→∞ E|zp − z| = 0. This convergence, inequality (90), and Proposition 4.6 imply that (88) can be strengthened to

This completes the proof of (62) when

.
The argument for the case T(A) = L(XA,M) of (62) is similar. The loss of XA is

where D = B − A. Let Yp(a) = L(XA,M) − r(a). Then

Because the right-hand side of (94) has the same structure as the last expression in (80), an argument parallel to the one that follows (80) completes the proof. Indeed, using (77) and (78),

█
Proof of Theorem 4.2. We show that (62) implies

where Z can be

or

or

. The three limits to be proved in (63) and (64) are immediate consequences of (96).
First, (62) with

entails

Hence, (96) holds for

and

Second, (62) with T(A) = L(XA,M) gives

These limits together with (98) establish the remaining two cases of (96). The argument continues to hold when the subscript TS is replaced by TLS. █
Proof of Theorem 4.3. First we show that

Write M = {mij} and E = {eij}. Let δjk denote the Kronecker delta. Then,

Under Assumption A1 and the finite fourth moment condition on the components of each ei,

In addition,

Limit (100) now follows.
Next,

the last inequality using parts (iv) and (vi) of Proposition 4.4. This inequality plus (100) implies limit (66) and hence also (67). █
5. FURTHER RESULTS
Section 5.1 addresses low risk adaptive estimation of M for a more general covariance structure on the rows of the error matrix E. Section 5.2 gives low risk adaptive estimators of M when the rank of M is constrained, as in errors-in-variables linear regression models.
5.1. Generalized TLS and TS Estimators
Suppose that Assumptions A1 and A2 are replaced with the following more general assumptions.
B1. The error vectors {ei : 1 ≤ i ≤ p} are independent, identically distributed, such that E(ei) = 0, Cov(ei) = σ2K, where K is a known, positive definite, q × q matrix and σ2 > 0 is unknown.
B2. Under the model of Assumption B1, the variance estimator

satisfies

for every finite c > 0.
Consider the problem of estimating M under the loss function

To solve this problem, let Y = XK−1/2, N = MK−1/2, and F = EK−1/2. Then F = [f1,…,fp]′ = [K−1/2e1,…,K−1/2ep]′, and

The random vectors {fi} are independent, each having mean vector 0 and covariance matrix σ2Iq.
Estimating M under loss (105) and Assumptions B1 and B2 is thus isomorphic to estimating N under the loss

and Assumptions A1 and A2. To obtain the appropriate adaptive TS estimator, use the following procedure:
- Use the data transformed matrix Y and variance estimator
to construct adaptive estimatorof N as in Section 3.
- Map
into the estimator.


The appropriate TLS estimator is constructed analogously. The theorems in preceding sections map immediately into counterparts that hold for loss (106) under Assumptions B1 and B2. Note that the construction (65) of

is here applied to the transformed data matrix Y.
5.2. Estimating Rank-Constrained M
When rank(M) is q − 1, then lq = 0,

, and the columns of M satisfy the linear constraint Mvq = 0. Assumptions A1 and A2 and the rank condition thus define an errors-in-variables linear regression model. The large literature on this topic, cited in Section 1, provides the estimator

for vp and the estimator

for M. The point of this section is to construct better estimators of M, estimators that have lower risk under the rank constraint.
Let

denote the set of all q × q symmetric matrices whose smallest eigenvalue vanishes and whose other eigenvalues lie in [0,1]. Under the rank constraint on M, πq = 0. Consequently, the oracle TS estimator in (27) now has the form XA with

. Let

denote the set of all q × q symmetric matrices whose smallest eigenvalue vanishes and whose other eigenvalues are either 0 or 1. Under the rank constraint on M, the oracle TLS estimator in (28) has the form XA with

.
Much as in Theorem 3.1, minimizing

over

yields the rank constrained adaptive TS estimator

The estimated risk of

is obtained by deleting the

term in the second expression in (43). On the other hand, minimizing

over

yields the rank constrained adaptive TLS estimator

The estimated risk of

is obtained by deleting the

term in the second expression in (44).
The asymptotic theory of Section 4 carries over to the foregoing rank constrained adaptive and oracle estimators. Under Assumptions A1 and A2 and the condition that rank(M) is q − 1, it is found that the loss of

or

converges to the respective risk. Second, the risk (or loss) of

or

converges to that of its oracle counterpart. Third, the estimated risk of

or

converges to the respective risk (or loss). Moreover, Theorem 4.3 applies with lq2 = 0. Thus,

has the desired L1-consistency property (67).


