


1. INTRODUCTION: BACKGROUND AND MOTIVATION
The consideration of various sequences of random variables and proving or disproving their convergence are one of the main streamlines of modern theoretical probability. In the establishment of the convergence of these sequences, the one-dimensional Chebyshev inequality is an invaluable tool and most frequently used technique. The Chebyshev inequality estimates the probability for exceeding the deviation of a random variable from its mathematical expectation in terms of the variance of the random variable. The mathematical expression of the bound on the probability in the Chebyshev inequality is very simple and can be modified easily for different kinds of sequence of random variables (e.g., for the case of sums of independent random variables). This fact lies behind these frequent applications. In this setting, the Chebyshev inequality has pure theoretical “applications” in probability theory and its role is to provide “a guarantee” of convergence but not to give a bound on concrete probability content.
As is well known, the computing of probabilities in multidimensional spaces is a very hard problem in mathematics, being expressed by multiple integrals. One of the characteristic features of these problems that contributes to its difficulties is the dimensional effect or the “curse” of dimensionality (i.e., any increase in dimension implies substantial computational difficulties). In the light of this phenomenon, any easy–to–compute bound on multivariate probabilities conveys valuable information. In general, bounds on multivariate probability distributions are useful in various areas (Monhor [14]).
Berge [2] initiated the multivariate generalization of the Chebyshev inequality. Considering correlated bivariate random variables, he derived an inequality for the rectangular area with sides whose lengths are the variances multiplied by a positive common factor. After this pioneering work, Lal [12] generalized Berge's result to the case of different factors. Finally, Olkin and Pratt [16] succeeded in deriving Lal's result to arbitrary n-dimensional space. In a theoretical setting, this is a significant result in the studies of multivariate generalization of the Chebyshev inequality. However, the inequality of Olkin and Pratt is too complicated to be applied in practical problems. The above-described background and motivations clarify the mathematical aspects of the topic in question.
The engineering motivation is as follows. The need and importance of bounding the probability content that the multivariate normal random vector falls into an n-dimensional Euclidean ball stemmed from several problems in engineering and informational sciences: GPS ambiguity problems in Hassibi and Boyd [9] and image estimation problems in the context of Gauss–Markov random fields in Jeng [10], Jeng and Woods [11], Molina, Katseggelos, Mateos, Hermoso, and Segall [13].
Consequently, in the present article we address the above problem in terms of the multivariate Chebyshev inequality (i.e., the question of how the one-dimensional Chebyshev inequality can be generalized for estimating the probability content of an n-dimensional Euclidean ball in the case of the multivariate Normal distribution). As a solution to this problem, we derived a new multivariate Chebyshev inequality that gives a lower bound on the probability in question. The bound is given in terms of variances of the random vector in the same way as in the classical one-dimensional Chebyshev inequality. This fact makes the inequality attractive by its being easy to compute and its similarity to the original Chebyshev inequality, in contrast to well-known complicated multivariate Chebyshev inequalities.
The present article also gives some insights into the very origin of the Chebyshev inequality in both one-dimensional and multidimensional settings. This gives the article an expository value and, at the same time, makes it self-contained.
The article is structured as follows. In Sections 2 and 3 we consider brief outlines of the developments in one-dimensional and multidimensional Chebyshev inequalities in an historical setting. Section 4 presents an auxiliary lemma that plays a key role in proving the main result of the article. In Section 5 we prove a new multivariate Chebyshev inequality for multivariate Normal distribution. Section 6 summarizes the results of the article and draws conclusions.
2. ORIGIN OF ONE-DIMENSIONAL CHEBYSHEV INEQUALITY
In any advanced textbook of modern probability theory (e.g., Ross [17]) or a monograph that deals with convergence of sequences of random variables, one inevitably finds the following inequality under the name Chebyshev inequality:

where ε is an arbitrary positive number.
This form of the inequality is suitable for proving the convergence in probability of sequences of random variables in terms of variance. The ε should be chosen as small as possible, in order to prove a convergence of a sequence of random variables. In this situation, inequality (2.1) is not used for a single random variable ξ, but for a sequence of random variables (say, for ξn, n = 1,2,…). This means that the convergence to zero of the sequence of numerators in the right-hand side of inequality (2.1) should be managed. This goal can be achieved in numerous ways, not only for simple sequences of random variables but also for sequences of various functions of random variables. This is an important research area in probability theory and, here, Chebyshev inequality is an extremely flexible tool. However, this is a theoretical issue and going into details further would be a digression from the main line of the article but what we mentioned above is helpful in grasping the very essence of the Chebyshev inequality.
Below, we reformulate inequality (2.1) in the following slightly different form in a precise mathematical setting.
Chebyshev Inequality: If a random variable ξ has finite variance, then, for any r > 0, we have

Chebyshev (1821–1894) [5,6] proved his inequality for the discrete random variables taking a finite number of possible values and the inequality was published in 1867. The proof was based on very long and tedious elementary algebraic calculations. In 1821 (the year of the birth of Chebyshev), the great German mathematician Karl Friedrich Gauss [7,8] proved the following inequality and presented it to the Royal Scientific Society of Göttingen; it appeared in 1823.
Gauss Inequality (Gauss (1821)): If the probability distribution function of a random variable ξ is unimodal, then, for k > 0, we have

where x0 is the mode and τ2 = [(ξ − x0)2].
From this inequality we see that Gauss considered the mode instead of the mathematical expectation for a continuous unimodal probability distribution. In the case of symmetric unimodal distributions, the mode and the mathematical expectation coincide. It is most likely that Gauss had symmetric distributions in mind because, at that time, error distributions were assumed to be symmetric.
Here, we see that precisely comparing the Gauss inequality and the original Chebyshev 1867 inequality is impossible, because Chebyshev proved his inequality for discrete random variables having only a finite number of values, whereas Gauss' statement is valid for continuous distributions, but with the restriction of unimodality. However, from the standpoint of bounding probability content, the Gauss inequality is much better than the Chebyshev inequality; at the same time, the latter is more suitable for the consideration of convergence process related to the law of large numbers. (The law of large numbers with relevance to the assessment of the measurement data quality is discussed in Monhor and Takemoto [15].)
In 1853 (i.e., 14 years after Chebyshev), Irenée-Jules Bienaymé (1796–1878) [4], a French statistician, proved an inequality that is identical with the Chebyshev inequality, but valid for continuous probability distributions without the restriction of unimodality.
We note another form of the Chebyshev inequality.
Chebyshev Inequality: If a random variable ξ has finite variance, then, for any λ > 1, we have

Remark 2.1: In (2.4), Var(ξ) = σ(ξ). If 0 < λ ≤ 1, then we have 1/λ2 ≥ 1; that is, the right-hand side of (2.4) becomes equal to or greater than 1. This means that the case 0 < λ ≤ 1 leads to a trivial inequality. Consequently, the condition that λ > 1 is not a restriction, but avoids the trivial case.
Remark 2.2: Chebyshev originally proved his inequality in the form (2.4), which is more similar to the Gauss inequality.
Bickel and Krieger [3] considered the accuracy of the Chebyshev inequality and, recently, Monhor and Takemoto [15] observed that the increase in λ improves the accuracy of the Chebyshev inequality in comparison with the Normal distribution.
3. CHEBYSHEV INEQUALITY IN MULTIDIMENSIONAL SPACES
Berge [2] generalized inequality (2.4) to the two-dimensional space as follows. If ξ1 and ξ2 are bivariate random variables with zero means, variances σ(ξ1) and σ(ξ2), and correlation coefficient ρ, then we have

It is Berge [2] who first considered the Chebyshev inequality in the multivariate setting. Thus, his result is the first multivariate Chebyshev inequality. After Berge, Lal [12] derived another multivariate Chebyshev inequality considering two different λ's in inequality (3.1). The Lal inequality is as follows:

We see that the Lal inequality is much more complicated, although it establishes mathematically a more general environment.
Olkin and Pratt [16] generalized the above results to the arbitrary n-dimensional space. Let ξ = (ξ1,ξ2,…, ξn) be a random vector with zero mean and with variances σ1,σ2,…, σn. Let ρij be the elements of the correlation matrix of the random vector. Furthermore, we introduce the notations t = [sum ](1/ki), ki > 0, and u = [sum ]ρij /(ki kj). The theorem of Olkin and Pratt then reads as follows:
Theorem (Olkin and Pratt):

We see that the right-hand side of inequality (3.3) is quite complicated and it makes the inequality impractical. However, from the standpoint of pure mathematics, the result of Olkin and Pratt is the culmination point in the multivariate generalization of the classic Chebyshev inequality.
4. CONVENTIONS ON NOTATIONS AND AN AUXILIARY LEMMA
Throughout the article we will denote the complement of a set S in

by Sc and the indicator function of S by IS(x),

; that is, we have

The Euclidean ball with center at x,

and radius r (r > 0) will be denoted by B(x,r):

The determinant of an n × n matrix A = (aij) will be denoted by |A|. In order to simplify and to shorten mathematical technicalities in the proof of the theorem in Section 5, we introduce a function φ(t,A) of real variable t and of matrix parameter A and prove a property of the function φ(t,A) in the form of an independent lemma. The definition of the function φ(t,A) is as follows: φ(t,A) = |I + tA|. Furthermore, in what follows we will also use the standard notation

.
Lemma: Let A be an n × n matrix and I be a unit matrix of the same order. Then we have

Proof: I + tA = (δij + taij), where δij are Kroneker symbols; that is,

By the definition of determinants we have

where the summation is taken over all permutations τ of the numbers 1,2,…, n, and sign(τ) equals 0 or +1 depending on whether τ is even or odd.
Now we write (4.1) in the following form:

where the summation

is taken over all of the permutations for τ except (1,2,…, n).
Differentiating both sides of (4.2), we get the following expression for dφ(t,A)/dt:

In (4.3), each product that is of the type

contains at least two factors of the form

where r ≠ τ(r). This fact implies that

Consequently, we have

This means that

hence, the lemma is proven. █
5. A MULTIVARIATE CHEBYSHEV INEQUALITY
Theorem: Let the random vector ξ = (ξ1,ξ2,…, ξn) have a multivariate Normal distribution with mean vector m = (m1,m2,…, mn). For any r > 0, we then have

Proof: Let

denote the probability density of ξ = (ξ1,ξ2,…, ξn). Also, we designate the inverse of the covariance matrix of ξ by Σ. Here, instead of the covariance matrix itself, we consider its inverse matrix in order to make the mathematical manipulations easier.
Both the summation and the inverse of the covariance matrix were designated by the same capital Greek Σ, which does not cause any ambiguity or confusion; also, we followed the well-established tradition of the use of Σ for both the covariance matrix and its inverse in multivariate statistical analysis (e.g., see Anderson [1]).
In the light of the above notation, we have

where Σ is a symmetric, positive-definite n × n matrix. Hence, it is obvious that if t > 0, then Σ + tI, where I stands for n × n unit matrix, is also symmetric and positive-definite. This means that Σ + tI can be considered as the inverse matrix of covariance of a multivariate Normal distribution. Consequently, for any t > 0, we have

In (5.2), we carry out the following algebraic transformations:
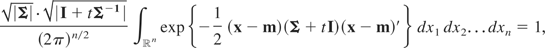
or

Differentiating both sides of (5.3) with respect to t, we obtain

It is easy to see that

. Taking t [nearr ] 0 to both sides of (5.4) and using the lemma, we get

On the other hand,

or

thus, the theorem is proven. █
Jeng [10,11] proved the following inequality, which gives an upper bound on the probability content of a Euclidean ball for a multivariate Normal distribution.
Jeng's Inequality: Assume that B is a n-dimensional positive-definite matrix with eigenvalues ρ1 ≥ ρ2 ≥ ··· ≥ ρn > 0 and B = JDJ, where D is a diagonal matrix that consists of the eigenvalues.
Then, for any r > 0, we have

where q is a constant that does not depend on r.
Remark 5.1: The proof of Jeng's inequality can be found in Jeng and Woods [11]. For computing and approximating the constant q, the reader is referred to Wozencraft and Jacobs [18, p.82]. Note that in Jeng's inequality, B denotes the covariance matrix of the multivariate Normal random vector in question.
Remark 5.2: The bounding method proposed by Hassibi and Boyd [9] is not an explicit inequality, but an algorithmic procedure that is computationally quite complicated.
6. CONCLUDING REMARKS
From inequalites (3.1)–(3.3), we find that the right-hand sides of the inequalities of Lal [12], Berge [2], and Olkin and Pratt [16] are quite different from that of the original Chebyshev inequality. Unlikely as it might seem, the right-hand side of the new multivariate Chebyshev inequality is exactly the same as that of the classic one-dimensional Chebyshev inequality. In this sense, the multivariate generalization of the Chebyshev inequality given in this article can be considered as the most natural variant. This is an interesting fact.
In one-dimensional space, the usual interval that is the complementary event for the classic Chebyshev inequality can be conceived as both a “one-dimensional rectangle” and a “one-dimensional ball” simultaneously. As is well known, this “occasional coincidence” of these two sets (in the language of probability theory, “events”) disappears and they become the sets of different structure in cases when the dimension of the space is higher than one. In multidimensional generalizations of the classic Chebyshev inequality, Berge [2], Lal [12], and Olkin and Pratt [16] followed the line of a rectangle set. However, here we followed the line of a ball, the consideration of which stemmed from the need coming from the engineering problems treated by Hassibi and Boyd [9], Jeng and Woods [11], and Molina et al. [13].
In a practical setting, the most important feature of the new multivariate Chebyshev inequality is its easy-to-compute form. The simultaneous application of the established multivariate Chebyshev inequality and Jeng's inequality is useful in practical problems by providing lower and upper bounds on the probability content. For example, this approach supplies us with an easy-to-compute estimation of the GPS verification probability considered in [9].
Apart from the establishment of the new multivariate Chebyshev inequality, in the present article we traced the very origin of the Chebyshev inequality back to the original source works by Gauss, Bienaymé, and Chebyshev, which is an interesting fact in its own right and adds an expository element to the topic. In addition, these facts make the article self-contained and convey a tutorial value, too.


