



List of symbols
- UAV
-
unmanned aerial vehicle
- SPL
-
sound pressure level
- RL
-
reinforcement learning
- SDG
-
sustainable development goal
- HPM
-
high-priority model
- LPM
-
low-priority model
- DDPG
-
deep deterministic policy gradient
-
 $v$
-
drone velocity
-
${L_0}$
-
noise source
-
${L_{tot}}$
-
total SPL at ground level
-
${L_i}$
-
attenuated SPL of acoustic ray i at ground level
-
${A_{div}}$
-
geometric divergence attenuation
-
${A_{atm}}$
-
atmospheric absorption attenuation
-
$d$
-
distance between noise source and receiver
-
${d_0}$
-
reference distance
- α
-
atmospheric absorption coefficient
- (x,y,z) t
-
vector of UAV coordinates at time instant t
- (x,y,z) dir
-
direction vector of acoustic ray
- (x,y,z) ref
-
direction vector of reflected acoustic ray
- (dx,dy)
-
vector of UAV incremental movements
- T
-
sample time
- N
-
total number of acoustic rays
- I
-
vector of incident acoustic ray
- R
-
vector of reflected acoustic ray
- N
-
normal vector of surface
-
$R\left( t \right)$
-
reward function value of timestep t
-
$\lambda $
-
scaling factor
-
${p_t}$
-
position of the drone at timestep
$t$
-
$P{d_t}$
-
population density of the cell where the drone is located at timestep
$t$
-
${p_{max}}$
-
maximum range of motion of the drone
-
${N_{thr}}$
-
maximum noise peak
-
${L_t}$
-
drone’s noise at timestep
$t$
-
${N_t}$
-
cumulative noise up to timestep
$t$
-
${N_{MAX}}$
-
maximum noise at each timestep
-
${\theta _t}$
-
orientation of (dx,dy) at timestep
$t$
-
${P_j}\left( t \right)$
-
j th penalty function value at timestep
$t$
-
$v\left( t \right)$
-
actions’ additive noise at timestep
$t$
-
${\mathcal N}\left( {0,1} \right)$
-
normal random variable
-
$Mea{n_{ac}}$
-
mean attraction constant
-
$Mean$
-
mean additive noise
-
$std$
-
standard deviation
-
$DeR$
-
decay rate of additive noise
-
$\tau$
-
smoothing factor
-
$\pi$
-
actor policy
- a
-
action
- s
-
state
- S
-
observation
- Q
-
critic network
-
Q
$_{t}$
-
target critic network
- R
-
replay buffer
- m B
-
mini batch size
-
$\pi_t$
-
target actor policy
-
$\theta$
-
actor parameter
-
$\phi$
-
critic parameter
-
$\theta_{t}$
-
target actor parameter
-
$\phi_{t}$
-
target critic parameter
-
$\gamma $
-
discount factor
-
$d$
b
-
binary terminal state variable
- α R
-
learning rate


1.0 Introduction
Drone-based applications in urban air mobility (UAM) have the potential to revolutionise how cities operate, from healthcare to infrastructure management. Drones’ applications in smart city context are many, such as logistics (including delivery of medical samples), infrastructure inspection, surveillance, traffic monitoring, emergency response and air taxi, among others [Reference Straubinger, Rothfeld, Shamiyeh, Büchter, Kaiser and Plötner1–Reference Geronel, Rinaldi, da Silva and Primatesta6]. All these uses of drones in the UAM context can significantly transform urban living, improving efficiency, lowering costs, and delivering faster, safer, and greener services. To fully realise these possibilities, they need to address a range of technological, regulatory, and societal issues. Surmounting those barriers will be critical to their wide adoption and success in the UAM environment [Reference Wang, Liu, Rinaldi and Tsang7]. It is well-known that the social acceptance of UAVs by the public is hindered, mainly, by concerns over privacy, safety, and noise pollution [Reference Eißfeldt and Biella8]. UAVs produce distinct noise signatures characterised by high-frequency tones that can be more annoying and perceptible than other sources of urban noise [Reference Schäffer, Pieren, Heutschi, Wunderli and Becker9]. Also, drones often produce pure tones, which are sounds at specific frequencies that can be particularly irritating. These tones are typically generated by the propeller blades and the motors. This issue is exacerbated in densely populated areas where the ambient noise levels are relatively low, making drone noise more prominent and bothersome. Therefore, addressing the noise impact of drones is crucial for the successful implementation and social acceptance of UAM. The noise generated by low-altitude UAS operations, especially in densely populated areas, can disrupt the tranquility of urban environments and potentially disturb residents and wildlife [Reference Schäffer, Pieren, Heutschi, Wunderli and Becker9]. Urban areas are particularly sensitive to noise pollution, and UAVs contribute significantly to this problem due to their proximity to the ground and the density of human activity. Studies have shown that UAV noise can be more disturbing than ground vehicle noise because of its unique acoustic signature, characterised by higher frequency tones and irregular sound patterns. Research has indicated that prolonged exposure to UAV noise can lead to increased stress levels, sleep disturbances, and adverse effects on cardiovascular health [Reference Schäffer, Pieren, Heutschi, Wunderli and Becker9]. These findings underscore the importance of developing UAV path planning strategies that minimise noise impact, particularly in densely populated areas [Reference Çetin, Cano, Deransy, Tres and Barrado10, Reference Adlakha, Liu, Chowdhury, Zheng and Nouh11]. To address these concerns, it is essential to implement comprehensive and environmentally conscious low-noise flight strategies for UAVs.
This paper is a follow-up to our previous work on noise-aware UAV path planning presented at the 14th EASN International Conference [Reference Sarhan, Rinaldi, Primatesta and Guglieri12]. Such work briefly introduced the noise-aware UAV urban path planning framework (along with the validation results), which is comprehensively presented in this work. Moreover, this paper gives comprehensive insights on the design and implementation of the path planning framework, including environment mapping, noise source modelling, noise propagation, reinforcement learning framework development, model training, model validation and demonstration of model flexibility by training two different models for high- and low-priority drone delivery scenarios. This paper aims therefore to inform future research on context-aware dynamic UAV navigation solutions based on reinforcement learning. By embracing sustainability practices in UAS operations management, we can pave the way for a future where smart cities thrive harmoniously with their surroundings, fostering a greener, quieter and more sustainable urban landscape. In this sense, this work enables context-aware intelligent path planning for reduced noise footprint of the UAV operation towards a seamless integration of the drone technology in society. The contributions of this paper are related to SDG 3,11, and 13 [Reference Varotsos and Cracknell13] as low-noise intelligent UAV path planning can foster sustainability, regulatory compliance and safety of UAM applications. The proposed approach represents a step towards sophisticated progress in terms of public well-being, safety, environmental and social sustainability related to the use of the drone technology in populated urban environments. The original contributions of this work are summarised as follows: (i) conceptualisation of a drone noise footprint evaluation framework for informing noise-aware UAV operations in urban air mobility context; and (ii) development and simulative validation of a low-noise UAV urban path planning solution based on environment mapping, acoustic ray tracing and reinforcement learning.
This paper is organised as follows. A literature review of path planning-based drone noise mitigation approaches is illustrated in Section 1.1. The proposed low-noise UAV path planning framework is presented in Section 2 along with the implementation details. This framework includes environment mapping, acoustic ray tracing and reinforcement learning. Section 3 presents the simulation results that validate the model. Our conclusions and future research directions are drawn in Section 4.
1.1 Related work
Advanced path planning algorithms can minimise UAV noise impact by avoiding densely populated areas and sensitive zones. Although urban locations create limits due to impediments and airspace regulations, operational tactics including raising altitude help reduce ground-level noise through atmospheric absorption and sound dispersion [Reference Kapoor, Kloet, Gardi, Mohamed and Sabatini14]. Noise cost functions can be incorporated into path planning algorithms, particularly heuristic and optimisation-based ones, to steer clear of sensitive or crowded regions, such as hospitals and schools [Reference Adlakha, Liu, Chowdhury, Zheng and Nouh11, Reference Kennedy, Garruccio and Cussen15]. For high-altitude aircraft, there are two primary approaches: reducing noise during crucial stages (such as takeoff and landing), and for low-altitude UAVs, optimising the entire route [Reference Kapoor, Kloet, Gardi, Mohamed and Sabatini14]. For the latter to avoid areas that are sensitive to noise, a thorough understanding of land use is necessary [Reference Kennedy, Garruccio and Cussen15, Reference Šiljak, Einicke, Kennedy and Byrne16]. However, in places like industrial parks or universities, silent zone sites could be changeable, making real-time planning difficult [Reference Šiljak, Einicke, Kennedy and Byrne16]. Numerous research use noise-map or grid-based methodologies. For example Ref. (Reference Adlakha, Liu, Chowdhury, Zheng and Nouh11), applies the A* algorithm for noise-aware routing and overlays a grid to identify barriers and quiet zones, while Ref. (Reference Kennedy, Garruccio and Cussen15) simulates noise over land use data using the ‘iNoise’ software. Similarly Ref. (Reference Šiljak, Einicke, Kennedy and Byrne16), diverts UAVs from crowded paths by using agent-based modeling. Other efforts incorporate sophisticated noise models; for example Ref. (Reference Tan17), embeds a noise objective in A* to balance barriers, distance and noise by combining Gaussian beam tracing (GBT) and heuristic planning. Additionally, machine learning techniques are used: Ref. (Reference Nguyen, Shihua and Liem18) optimises departure paths by employing a soft actor-critic (SAC) reinforcement learning framework with topological and sociological data, exposing trade-offs between noise reduction and fuel efficiency. In Ref. (Reference Tan19), a vehicle routing problem (VRP)-like formulation is expoloited to reduce en-route drone noise impact. This paper introduced a novel hybrid cost function that combines the assessment of the accumulated noise exposure level and path length. Accurate modeling of sound sources and realistic sound propagation computation in urban environments is based on flight simulation. In Ref. (Reference Tan20), high-fidelity simulations are used to assess full-scale UAVs in urban settings by fusing aeroacoustics methods with rotor and fuselage noise models. Heuristic approaches adjust flight trajectories to account for far-field noise propagation, which is supported by a Gaussian beam method. Simpler models, such as the spherical point-source assumption in Ref. (Reference Scozzaro, Delahaye and Ernesto Vela21), permit effective noise estimation. Using simulated annealing, the study changes UAV trajectories to reduce exposure in residential zones while considering energy use. In Ref. (Reference Scott, Manyam, Casbeer, Kumar, Rothenberger and Weintraub22), a power-aware method is introduced, where a mixed integer linear programming (MILP) model with dynamic programming combines energy and noise limitations by alternating between generator and battery modes in places that are sensitive to noise. Lastly, authors in Ref. (Reference Pang, Hu, Dai and Low23) present a cost model that takes into account the dangers of property damage, noise and fatalities. The study uniquely considers the correlation between noise level and cost, setting a threshold at 40 dB to determine when noise impact becomes significant in path planning. The approach is based on the fusion of the estimation of distribution algorithm (EDA) and CostA* algorithm. Using a hybrid optimisation strategy over a noise grid, multi-objective path planning with 3D non-uniform rational B-splines (NURBS)-based trajectories in Ref. (Reference Hohmann, Bujny, Adamy and Olhofer24) takes obstacle avoidance, energy consumption and urban noise into account. The problem of minimising the UAV noise impact near the intersection points of multiple flight trajectories is addressed in Ref. (Reference Tan, Li, Bao, Zhou, Lo, Zhong and Zhang25) by means of a multi-agent Markov decision process framework solved by the Monte Carlo tree search algorithm. The simplified real-time noise prediction method improves scalability and makes it a valuable decentralised intelligent navigation framework. A contribution to assist low-noise flight planning and noise certification has been proposed in Ref. (Reference Bian, Tan, Zhong and Zhang26). From virtual flights, this work evaluates the noise footprint of unmanned aircraft system (UAS) operations using a GBT method implemented in an in-house solver Environmental Acoustic Ray Tracing Code.
2.0 Low-noise UAV path planning framework
2.1 Environment mapping
The city of Turin, Italy, is an ideal study area for evaluating UAV noise impact and path planning due to several compelling reasons. The city’s dense urban core, surrounded by various residential, commercial and industrial zones, presents a realistic scenario for testing UAV operations in different contexts. Additionally, Turin’s diverse population density, with both densely populated neighbourhoods and sparsely inhabited areas, allows for a comprehensive analysis of UAV noise impact across different demographic settings. The architectural landscape of Turin, characterised by a mix of historical buildings, modern skyscrapers and extensive residential complexes, provides a varied environment for testing the noise model, as noise propagation and reflection characteristics differ with building types and materials. Furthermore, Turin’s involvement in smart city initiatives and sustainable urban development projects, coupled with its regulatory support for innovative transportation solutions, makes it a forward-thinking city likely to adopt advanced UAV technologies. These unique characteristics of Turin, combined with its rich data resources and proactive regulatory climate, make it a highly suitable and relevant study area for developing and validating a novel UAV path planning approach aimed at minimising noise impact. The insights gained from this research in Turin can be generalised to other urban areas with similar characteristics, contributing to broader advancements in UAV noise mitigation and urban air mobility. The satellite photo of the study area is depicted in Fig. 1.
Satellite photo of the operational area (Torino, Italy).

To construct the 3D occupancy grid for the study area, building location data was sourced from OpenStreetMap (OSM). The area of interest was defined by the longitude range from 7.6039E to 7.71E and the latitude range from 45.0386N to 45.1094N. Using the Overpass API, building data within these coordinates was downloaded. Once the data was acquired, the geographic coordinates (longitude and latitude) of the buildings were converted into Cartesian coordinates. This step was essential to preserve the relative positions of the buildings accurately on the map, ensuring that the spatial relationships among buildings were maintained. A random height between 12 m and 18 m was assigned to each building, reflecting typical urban building heights in the region. The map was then trimmed to include only a specific portion with the remaining section discarded. This selection ensured that the resulting maps would be uniform in size, specifically 200 × 200 cells, which is crucial for consistency during the training phase. Each cell has a length of 2 m. The entire study area was then represented by a three-dimensional matrix, denoted as R. Each grid point
 $R(i,j,k)$
in this matrix represents an occupancy value, indicating whether the corresponding geographical volume is occupied (value 1) or unoccupied (value 0). Each building’s longitude and latitude were converted to
 $(x,y)$
coordinates which were then mapped to the corresponding
 $(i,j)$
indices in the matrix R. The height of each building was used to determine the k index, representing the vertical dimension. This ensured that the 3D representation accurately reflected the spatial structure of the urban environment. The resulting map is shown in Fig. 2(a). To facilitate efficient path planning and simulation, the large occupancy grid was subdivided into smaller chunks of 200 × 200 × 20 cells, resulting in 456 smaller maps. The uniform size of these chunks ensured consistency in the path planning process.
(a) Obstacle map of the operational area. (b) Population density map of the operational area.

To accurately represent population distribution within the study area, population density data for Italy was sourced from Meta. This data was filtered to include only the regions within the longitude range from 7.6039 E to 7.71 E and the latitude range from 45.0386 N to 45.1094 N, ensuring alignment with the area covered by the obstacles map. The dataset provides the number of individuals in each cell, where each square cell measures 1 arc second, corresponding to approximately 30.87 m at the equator. As latitude increases, the cell width decreases, necessitating adjustments in cell size representation. The dataset includes the longitude and latitude coordinates of each cell’s centre along with the corresponding population count. To process this data, the vertices of each cell were calculated from the centre coordinates based on their latitude, determining the exact boundaries of each cell. The population count assigned to each cell was uniformly distributed across all points within the cell. These geographic coordinates were then converted to Cartesian coordinates to match the coordinate system used for the obstacles map. A 2D grid, mirroring the obstacles map was constructed to represent the study area. Population density values were assigned to each point within this grid based on the processed population data. The resulting population density matrix was then normalised to ensure data consistency across the grid. The map is illustrated in Fig. 2(b). This subdivision ensured uniformity in map sizes and accurate overlap with the obstacles data which is necessary for training the model.
2.2 Noise source and acoustic ray tracing
For this study, a point-source spherical propagation model for the sound generated by the UAV was utilised. This model simplifies the calculations for computational efficiency within a simulation-based optimisation framework while remaining reasonably representative of established findings [Reference Scozzaro, Delahaye and Ernesto Vela21]. Although multi-rotor UAVs produce highly directional noise in their immediate vicinity, it’s assumed that the noise propagates isotropically at the distances considered in this study. Consequently, as the UAVs traverse their routes, the noise pattern generated on the ground does not distort when turning.
Typically, a constant noise source is assumed in such models; however, the velocity of the drone is correlated with its noise level, and since the RL agent can adapt its velocity, it is beneficial to incorporate this variable into the noise model. To achieve this, data from the study in Ref. (Reference Škultéty, Bujna, Janovec and Kandera27) was utilised that recorded noise levels at a fixed distance of 1 m from the ‘DJI Inspire 2’ quadrotor at speeds of 5, 10 and 20 km/h. Measurements were taken across various frequencies, ranging from 20 Hz to 20 kHz, using third-octave bands. For each velocity, the mean SPL across all frequencies was computed to obtain the overall SPL.
Once these three data points were established, an exponential curve was fit to the data, resulting in the SPL-velocity relationship. This results in
 ${L_0} = 60.24 \cdot \exp ( {0.003379 \cdot v})$
, which allows dynamic noise level adjustment based on UAS velocity during flight.
 ${L_0}$
denotes the source SPL in dB, and
 $v$
denotes the velocity in km/h.
The apparently overly simplified drone’s noise model introduced by the relation between
 ${L_0}$
and
 $v$
can be re-addressed easily in the future by interpolating data resulting from extensive experimental results, and/or introducing new parameters and functions for assessing the impact of drone noise on people based on the drone’s characteristics as well as the operating conditions [Reference Kawai, Jäggi, Georgiou, Meister, Pieren and Schäffer28]. The latter is a cutting-edge emerging research topic that is currently being studied by the psychoacoustic UAS scientific community. Also, a monotonic increase of the emitted noise for increasing values of drone’s velocity may not be a high-fidelity noise emission model, and research is currently being carried out about it. On the other hand, it can be seen more generally as a way of accounting for the increase of parasite power consumption with respect to the drone’s operational speed.
In the context of UAV path planning aimed at minimising noise impact, accurately modelling noise propagation is critical. This process involves generating direction vectors from a noise source, which are utilised in ray tracing simulations. The following method was employed to generate these rays using. First, the altitude of the noise source was defined at 40 m. A radius of 10 m was set for generating points within concentric circles around the source at ground level. Four concentric circles were set around the source, each with a radius incrementally larger by 10 m, and each populated with an increasing number of points: 4, 9, 14 and 19 points, respectively, distributed equally on the circle resulting in a total of 46 rays. Subsequently, direction vectors from the source point in the sky to each ground point were computed and normalised to unit vectors. This approach ensured a consistent direction magnitude for the vectors. By employing this method, the noise source is effectively modelled. The generated vectors were visualised in a 3D space to verify accuracy as illustrated in Fig. 3.
The noise source: (a) the acoustic rays emitted from the source at an altitude of 40 m; (b) collision points of the unobstructed rays on the ground; (c) synthetic representation of the scenario with buildings and the interaction of the acoustic rays with the environment.

Accurately modelling the propagation of UAV noise is essential for minimising its impact on the environment. Acoustic ray tracing is a computational technique used to model the propagation of waves through a medium, interaction with obstacles and attenuation over distance. This section details the ray tracing algorithm employed to evaluate the SPL at ground level due to emitted UAV noise. This method involves tracing the path of sound rays emitted from the noise source and calculating their interactions with the environment, considering reflections and atmospheric absorption. The following assumptions are made in the ray tracing model: medium homogeneity, linear propagation, specular reflection, negligible diffraction. The ray tracing algorithm used to evaluate the SPL at ground level involves several key steps: initialisation, propagation, interaction, attenuation and SPL computation.
The algorithm initialises several arrays to store data for each ray, including travelled distance, coordinates along the ray path, attenuation due to geometric divergence and atmospheric absorption and SPL values along the ray path. The source noise magnitude emitted by the UAV is calculated based on its velocity. At the first iteration of a new episode, the minimum noise corresponding to the UAV’s minimum movement ([0,0]) is considered. The velocity,
 $v$
, is computed as
 $v = \left| {\left| {dx,dy} \right|} \right|/T$
, where
 $\left| {\left| {dx,dy} \right|} \right|$
represent the Euclidean norm of the movement vector, and T is the sample time.
For each ray, the initial position is set at the UAV’s current coordinates
 $(x,y,z)$
. The direction of each ray is initialised using pre-calculated direction vectors. The algorithm propagates the ray through the medium by iteratively updating the ray’s position,
 ${x_t}$
,
 $y$
,
 ${z_t}$
, based on the direction,
 ${x_{dir}}$
,
 ${y_{dir}}$
,
 ${z_{dir}}$
, and step length,
 $\alpha $
:
 ${x_{t + 1}} = {x_t} + {x_{dir}} \cdot \alpha $
,
 ${y_{t + 1}} = {y_t} + {y_{dir}} \cdot \alpha $
,
 ${z_{t + 1}} = {z_t} + {z_{dir}} \cdot \alpha $
. The updated coordinates are constrained within the map boundaries to ensure valid indices. The step length was selected to be 0.3 units. This value was determined through iterative ray tracing simulations and visualisation of sound propagation to ensure model fidelity. A larger step length resulted in rays failing to detect obstacles, while a smaller step length significantly increased computational load. This step length struck a balance between accuracy and computational time.
It’s necessary to check for interactions with environmental elements (e.g., ground, buildings). If the ray reaches the map boundary (excluding the ground), the ray tracing for that ray is terminated as it is leaving the area of interest and will no longer have any effect on it. If the ray hits an obstacle, the reflection is handled using the law of reflection, as follows:
 $\boldsymbol{R}=\boldsymbol{I}-\textbf{2}(\boldsymbol{I} \cdot \boldsymbol{N}) \cdot \boldsymbol{N}$
. The updated direction vector of the reflected acoustic ray is expressed as (
 ${x_{ref}} = {x_{dir}} - 2\left( {{x_{dir}} \cdot N} \right) \cdot N$
,
 ${y_{ref}} = {y_{dir}} - 2\left( {{y_{dir}} \cdot N} \right) \cdot N$
,
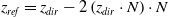 ${z_{ref}} = z_{dir} - 2\left( {{z_{dir}} \cdot N} \right) \cdot N$
).
The SPL loss calculation as described here aligns with the methods prescribed by the ISO 9613-2 standard, which provide guidelines for predicting the attenuation of sound during propagation outdoors. It considers various factors such as geometric divergence, atmospheric absorption, ground effects and barriers. The SPL loss is calculated for each segment of the ray path due to atmospheric absorption and the geometric divergence.
The attenuation from geometric divergence,
 ${A_{div}}$
, accounts for the reduced sound level as the sound propagates over a distance. For a point sound source in a free field, the attenuation in decibels (dB) is given by
 ${A_{div}} = 20\log \left( {d/{d_0}} \right) + 11$
. The attenuation from atmospheric absorption
 ${A_{atm}}$
during propagation over a distance d is given in (dB) by
 ${A_{atm}} = \alpha d/1000$
. d is the distance travelled from source to receiver in (m), d0 is the reference distance (= 1 m); and
 $\alpha$
is the coefficient of atmospheric attenuation in (dB/km) at the nominal median frequency of each third-octave band. Given a temperature of 10 degrees Celsius, relative humidity (RH) of 70%, and assuming a nominal median frequency of 200 Hz (considering drones typically operate between 100 and 300 Hz with an average of 200 Hz), the atmospheric absorption coefficient (α) is set to be 0.76 dB/km as per ISO 9613-2 [29].
The walls are assumed to be solid with no windows, and as per ISO 9,613, they are characterised by a coefficient of 1. This indicates that these walls act as perfect reflectors, meaning they do not allow sound to transmit through them. Consequently, there is no additional attenuation from these walls beyond the reflections they cause. The SPL for each ray is recorded when the ray reaches within a height 2 m above the ground. This is done based on the equation:
 ${L_i} = {L_0} - {A_{div}} - {A_{atm}}$
, where
 $L_i$
is the SPL for each ray in (dB). Once the SPL for each ray is known, the contributions from all
 $N$
rays are summed to determine the overall SPL using the following equation:
 ${L_{tot}} = 10\log \left( {\mathop \sum \nolimits_i^N {{10}^{{\rm{Li}}/10}}} \right)$
, with
 ${L_{tot}}$
denoting the noise impact at the ground level in (dB).
Figure 4 shows the snapshot of the pseudo-code of the ray tracing algorithm proposed in this work.
Snapshot of the pseudo-code of the Ray Tracing algorithm proposed in this work.

2.3 Deep deterministic policy gradient algorithm
The deep deterministic policy gradient (DDPG) algorithm [Reference Silver, Lever, Heess, Degris, Wierstra and Riedmiller30], is a model-free, off-policy RL method. It is an actor-critic RL agent designed to concurrently learn a Q-function and a policy, leveraging off-policy data and the Bellman equation to optimise both. In RL, policy gradient methods are used to find the optimal policy by optimising a parametric policy
 ${\pi _\theta }$
. Traditional policy gradient methods use stochastic policies, where the action is sampled from a probability distribution. Deterministic policy gradient (DPG) methods, however, use a deterministic policy
 ${\pi _\theta }\left( s \right)$
that directly maps states to actions. DDPG agents are suitable for environments with continuous or discrete observation spaces and continuous action spaces. DDPG agents utilise two main components:
-
• Actor: The actor represents a deterministic policy
$\pi(s)$
. A deterministic actor takes an environment observation as input and returns as output an action that is a parametrised deterministic function of the observation, thereby implementing a parametrised deterministic policy. -
• Critic: The critic evaluates the action-value function
$Q(S,A)$
which is a mapping from an environment observation-action pair to the value of a policy.


During training, DDPG agents update both the actor and critic properties at each time step. They store past experiences in a circular experience buffer and update the actor and critic using mini-batches of experiences randomly sampled from this buffer. To ensure stable behaviour, the replay buffer must be sufficiently large to encompass a diverse range of experiences. However, it is not always beneficial to retain all past experiences. Using only the most recent data can lead to overfitting, while using an excessive amount of data can slow down the learning process. Therefore, careful tuning is required to strike the right balance. DDPG trains a deterministic policy using an off-policy approach. DDPG trains a deterministic policy using an off-policy approach (Fig. 5).
Actor-critic agent: representation taken from Ref. (Reference Nguyen, Shihua and Liem18).

Since the policy is deterministic, on-policy exploration at the start may not cover a sufficiently diverse range of actions to obtain useful learning signals. To enhance exploration, noise is added to actions during training using the Ornstein-Uhlenbeck noise model. The noise scale can be reduced over the course of training using a decaying factor to balance the exploration-exploitation tradeoff. The noise value
 $v(t)$
at each time step
 $t$
is updated as
 $v\left( {t + 1} \right) = v\left( t \right) + Mea{n_{ac}} \cdot \left( {Mean - v\left( t \right)} \right) \cdot T + std\left( t \right) \cdot {\mathcal N}\left( {0,1} \right) \cdot \surd T$
, the standard deviation decays at each time step as
 $std\left( {t + 1} \right) = std\left( t \right) \cdot \left( {1 - DecR} \right)$
. It is crucial to set the noise standard deviation appropriately to promote exploration, typically setting
 $std \cdot \surd T$
between 1% and 10% of the action range. DDPG agents maintain four function approximators to estimate the policy and value functions:
-
• Actor
$\boldsymbol{\pi}\!\left({\boldsymbol{S};\,\boldsymbol{\theta} } \right)$
: Takes observation S as input and returns the corresponding action that maximises the long-term reward. -
• Target Actor
${\boldsymbol{\pi}_t}\left( {\boldsymbol{S};\,\boldsymbol{\theta} \boldsymbol{t}} \right)$
: Periodically updated using the latest actor parameters
$\theta$
to improve optimisation stability. The actor policy is updated using the sampled policy as follows:(1)
\begin{align}{1 \over M}\mathop \sum \nolimits_{i = 1}^M {\nabla _a}Q\left( {s,a;\phi } \right){\left| {_{s = {s_1},\;a = \pi \left( {{s_i}} \right)}{\nabla_b}\pi \left( {s;\theta } \right)} \right|_{{s_i}}}\end{align}
-
• Critic
$\boldsymbol{Q}\left({\boldsymbol{S},\boldsymbol{a};\boldsymbol{\phi} } \right)$
: Takes observation S and action a as inputs and returns the expected long-term reward. -
• Target Critic
${\boldsymbol{Q}_t}\left( {\boldsymbol{S},\boldsymbol{a};\,\boldsymbol{\phi} \boldsymbol{t}} \right)$
: Periodically updated using the latest critic parameters
$\theta$
to maintain stability. The update is defined as follows:(2)
\begin{align}\frac{1}{M}\mathop \sum \limits_{i = 1}^M {\left[ {{y_i} - Q\left( {{s_i},{a_i};\phi } \right)} \right]^2}\end{align}


Both the target and main networks (actors and critics) share the same structure and parameterisation. Q-learning algorithms utilise target networks to stabilise training. The expression
 $r + \gamma \left( {1 - d} \right)\max {Q_t}\left( {s',a{\rm{'}}} \right)$
is referred to as the target, as minimising the mean squared Bellman error (MSBE) loss aims to align the Q-function with this target. d represents a binary indicator variable that signifies whether the next state
 $s'$
is terminal or not. Specifically, d=1 if
 $s'$
is a terminal state and d=0 otherwise. However, the target relies on the same parameters
 $\phi$
that are being optimised, leading to instability in MSBE minimisation. To address this, a secondary network called the target network, with parameters
 $\phi_{t}$
is introduced. This target network lags behind the main network, providing more stable target values. DDPG algorithms update the target network more smoothly using Polyak averaging:
 $\phi {\rm{\tau }} + {\phi _{\rm{t}}}\left( {1 - {\rm{\tau }}} \right)$
, where
 $\tau$
is a hyperparameter between 0 and 1, referred to as smoothing factor. This continuous update method helps maintain stability during training.
A snapshot of the pseudo-code of the proposed DDPG algorithm is illustrated in Fig. 6.
Snapshot of the pseudo-code of the DDPG strategy adopted in this work.

2.4 Implementation details
The RL-based low-noise path planning framework proposed in this work requires the definition of UAV state and UAV action space as well as the agent’s reward function. The implementation details are given as follows. The simulation settings are also presented.
2.4.1 State and action space
The input layer’s neuron count is determined by the dimensionality of the state representation. This state representation encapsulates the current condition of the environment, providing a comprehensive snapshot that the RL uses to make informed decisions. The output layer, on the other hand, corresponds to the action space. The number of neurons in this layer should align with the range of possible actions that the agent can take in the environment. The construction and significance of the state representation, which is a critical component of the RL approach is described here. The state representation is a 24-dimensional vector, with the features corresponding to the input layer of the neural network. The vector encapsulates a comprehensive set of features that characterise the current state of the drone and its environment:
-
• Drone Position: The cartesian coordinates of the drone in XY plane.
-
• Target Position: The cartesian coordinates of the target in XY plane.
-
• Distance to Target: The Euclidean distance from the drone to the target.
-
• Target Orientation: The orientation of the target with respect to the drone, represented as an angle in the XY plane.
-
• Local Population Density: The population density at the current drone location.
-
• Mean Population Density: The mean population density across two sub grids of sizes 15 × 15 and 51 × 51, with the drone at the centre of each.
-
• Orientation of Maximum Population Density: The orientation of the point of maximum population density in the sub grid with respect to the drone.
-
• Noise Level: The overall SPL value on the ground.
-
• Obstacle Distance: The distances from the drone to the three closest and three furthest obstacles.
-
• Obstacle Orientation: The orientations of the six obstacles with respect to the drone.
To ensure stability and prevent divergence during the training process, each of these values is normalised to fall within the range [0, 1]. When training a RL agent using techniques like policy gradients or Q-learning, the scale of the input features can affect the scale of the gradients. If the input features have vastly different scales, it can lead to imbalanced gradients and slower convergence. Normalising the input features ensures that the gradients are scaled appropriately, allowing for more stable and efficient learning. Normalising input features helps in improving the generalisation capability of the RL agent. By scaling the features to a similar range, the agent can learn a more generalised policy that performs well across different states or observations.
The agent operates within a fixed height airspace and possesses the capability to navigate in any direction across the continuous space of the XY plane. Such an environment presents unique challenges in terms of decision-making and path planning. To effectively train the agent in this dynamic setting, a critical consideration is the selection of an appropriate sampling time, T, which dictates the frequency at which the agent takes actions. The sampling time chosen for the training phase is 0.3 units. This selection is deliberate, as a smaller T implies that the agent must make decisions more frequently. This characteristic proves advantageous in environments characterised by high dynamism or instances where the drone’s situational awareness is of paramount importance. However, it’s essential to acknowledge that reducing T comes with a computational cost, as the agent must process information and make decisions more rapidly. Thus, there exists a trade-off between the frequency of actions and computational efficiency. The value of T influence both responsiveness and computational feasibility. To further enhance the realism of the simulation, it’s imperative to appropriately define the range of movement available to the agent at each time step. This range directly influences the agent’s velocity and, by extension, its navigational capabilities. To align the simulation with real-world parameters, the range of movement is calibrated to match the velocity of commercial drones, which typically have a maximum speed of 100 km/h. By setting the action range
 $[dx,dy]$
for both the x and y directions to [3,3], corresponding to a movement of 6 meters per time step, the simulated drone achieves a maximum velocity of approximately 101 km/h. This adjustment ensures that the agent’s movement closely mirrors the operational constraints and capabilities of real-world drones, thereby enhancing the fidelity and applicability of the simulation outcomes.
2.4.2 Reward function
The reward function plays a pivotal role in achieving the desired behaviour from the model. At any timestep, if the episode terminates (the agent reaches the target), a reward of 2 is given. Otherwise, the reward is calculated by the weighted sum of the following terms, which are all individually normalised in the range of [0,−1]:
-
1. Idle penalty
${\boldsymbol{P}_1}\left( \boldsymbol{t} \right)$
: penalises the drone for remaining stationary. A penalty of −1 is applied if the drone’s position has not changed in between timesteps.(3)
\begin{align}{P_1}\left( t \right) = \left\{ {\begin{array}{l@{\quad}l} - 1,& if\;{p_t} = {p_{t - 1}} \\[5pt]0,& otherwise\end{array}} \right.\end{align}
-
2. Distance penalty
${\boldsymbol{P}_2}\left( \boldsymbol{t} \right)$
: encourages the drone to reduce the distance to the target. The penalty is based on the change in Euclidean distance to the target.(4)
\begin{align}{P_2}\left( t \right) = - \frac{\|{{p_t} - {p_{target}}\| - \|{p_{t - 1}} - {p_{target}}}\|}{{\|{p_{max}}\|}}\end{align}
-
3. Population density penalty
${\boldsymbol{P}_3}\left( \boldsymbol{t} \right)$
: discourages navigation through high-density areas. A penalty of −1 is applied if the population density increases from the previous timestep; otherwise, a smaller penalty of −0.1 is applied.(5)
\begin{align}{P_3}\left( t \right) = \left\{ {\begin{array}{l@{\quad}l} - 1,& if\;P{d_t} \gt P{d_{t - 1}} \\[5pt] - 0.1,& otherwise\end{array}} \right.\end{align}
-
4. Noise penalty
${\boldsymbol{P}_4}\left( \boldsymbol{t} \right)$
: penalises high noise levels. If the SPL exceeds the threshold (maximum possible SPL on the ground), a penalty of −1 is applied. Below the threshold, the penalty decreases exponentially to 0 as the SPL decreases to 0.(6)
\begin{align}{P_4}\left( t \right) = \left\{ \begin{array}{l@{\quad}l} - 1, & {if\;{L_t} \gt {N_{thr}}} \\[5pt] { - {e^{ - 3 \cdot {\rm{\;}}{{{N_{thr}} - {L_t}} \over {{N_{thr}}}}}},\;} & {otherwise} \end{array} \right.\end{align}
-
5. Cumulative noise penalty
${\boldsymbol{P}_5}\left( \boldsymbol{t} \right)$
: encourages lower cumulative noise and, indirectly, shorter flight time. The penalty increases based on the cumulative noise up to the current timestep.


 \begin{align}{P_5}\left( t \right) = - {{{N_t}} \over {t \cdot {N_{MAX}}}}\end{align}
-
6. Smoothness penalty
${\boldsymbol{P}_6}\left( \boldsymbol{t} \right)$
: prevents erratic behaviour and encourages smooth navigation. The penalty is based on the angular difference in the movement vector between consecutive timesteps.

 \begin{align}{P_6}\left( t \right) = - \frac{{\left| {{\theta _t} - {\theta _{t - 1}}} \right|}}{\pi }\end{align}
The total reward at each timestep,
 $R\left( t \right)$
, is calculated as
 $R\left( t \right) = {\lambda _1}{P_1}\left( t \right) + {\lambda _2}{P_2}\left( t \right) + {\lambda _3}{P_3}\left( t \right) + {\lambda _4}{P_4}\left( t \right) + {\lambda _5}{P_5}\left( t \right) + {\lambda _6}{P_6}\left( t \right)$
, where
 $\lambda $
is the scaling factor.
2.4.3 Simulation settings
To demonstrate the potential of RL-based navigation, two distinct drone delivery scenarios are considered. Therefore, two versions of the RL model are developed:
-
• High-Priority Model (HPM): In scenarios where timely delivery is critical, such as delivering medical supplies to a hospital, the HPM emphasises the reduction of the delivery time over noise minimisation, and optimises the flight path primarily for speed and efficiency, accepting higher noise levels as a trade-off.
-
• Low-Priority Model (LPM): For deliveries that do not require urgency, such as regular postal services, the model focuses on minimising noise impact as much as possible while still ensuring reasonable delivery times. The LPM focuses on optimising flight paths to reduce noise pollution, even if this results in longer delivery times.
For optimisation, the Adam algorithm (adaptive moment estimation) is employed, leveraging adaptive learning rates along with first and second moment estimates to enhance convergence speed and manage sparse gradients effectively. Both networks incorporate a gradient threshold of 1 for gradient clipping, thereby mitigating the exploding gradient problem and ensuring stable updates. Gradient clipping stabilises the training process, particularly at higher learning rates and in the presence of outliers, without typically affecting the accuracy of the learned task. The learning rate, determines the step size for each iteration of gradient descent towards minimising the loss function. The tuned value favours training stability, where higher learning rates might initially accelerate convergence but could result in oscillations or divergence later, and lower learning rates may converge more slowly but with greater robustness. The DDPG agent is then configured, with the first and last layers matching the observation and action space. A smoothing target update method is chosen, and the network is updated at each step. The update rate of the target networks determines how swiftly they track the main networks’ parameters. A higher update rate could lead to faster convergence but might introduce instability or oscillations. Conversely, a lower update rate necessitates more iterations for convergence but offers more stability. The discount factor prioritises long-term rewards over immediate ones, encouraging the agent to develop more far-sighted policies. The replay buffer size affects the diversity of experiences the agent encounters during training. A larger buffer stores more experiences, potentially leading to better policies through diverse training data. However, excessively large buffers may slow down training and increase memory requirements. The batch size determines the number of experiences sampled from the replay buffer for each update step. The main hyperparameters meticulously tuned to optimise the training process are defined as follows: mini batch size: 128, discount factor γ: 0.99, smoothing factor τ: 0.001, Learning rate α: 0.00001, 3 hidden layers, 256 nodes in each hidden layer. Also,
 $Mea{n_{ac}} = 0.15$
,
 $Mean = 0$
,
 $std = 0.85$
, and
 $Decay{\rm{\;}}Rate = {10^{ - 4}}$
. The scaling factors of the reward function are set as
 ${\lambda _1} = 0.02$
,
 ${\lambda _2} = 0.07$
,
 ${\lambda _3} = 0.43$
,
 ${\lambda _4} = 0.01$
,
 ${\lambda _5} = 0.47$
,
 ${\lambda _6} = 1$
. This configuration refers to the HPM. The LPM is defined with a different set of scaling factors, as follows:
 ${\lambda _1} = 0.02$
,
 ${\lambda _2} = 0.06$
,
 ${\lambda _3} = 0.48$
,
 ${\lambda _4} = 0$
,
 ${\lambda _5} = 0.44$
,
 ${\lambda _6} = 1$
.
2.4.4 Model training
To initiate the training process, it is essential to set up the environment and configure both the actor and critic neural networks. The environment encompasses the algorithms previously described and any auxiliary functions necessary for the seamless execution of its operations. The actor and critic networks are each initialised with three hidden layers, each containing 256 nodes. This symmetry ensures consistent parameterisation across both networks. The overall dataset, consisting of 456 obstacle and population density maps, is divided into a training set of 410 maps and a testing set of 46 maps. During the training phase, obstacle and density maps and noise ray direction vectors are imported. At the beginning of each episode, a random obstacle map and its corresponding density map are selected, and the agent’s starting position and target coordinates are specified randomly. Training proceeds by executing actions in the environment, observing the resultant state and reward, and continuing until the episode’s termination condition is met: either the agent reaches within 2 m of the target or the maximum of 280 steps is reached. A new episode begins with another random map and initial coordinates. Throughout training, learning curves such as cumulative reward per episode, moving average of cumulative reward, and initial Q-value of each episode are monitored. These metrics, along with the agent’s success rate, guide the continuation of training until convergence to the optimal policy is achieved. This kind of training process is repeated for both models: HPM and LPM. The evolution of the learning curve throughout the training process of the HPM is illustrated in Fig. 7.
Snapshot of the learning curve throughout the training process of the HPM.

3.0 Simulation results
3.1 Model validation
In order to validate the accuracy of the agent’s learned policy, the trained agent is tested on a map different from the testing dataset. To compare its performance, this trajectory is compared with the direct path to the target and the optimal path found from the A* algorithm. The heuristic function in the A* algorithm is configured to account for both distance (40%) and population density (60%). Since the noise model is velocity-dependent, defining a velocity for the alternative methods is essential to evaluate their noise impact accurately. For a fair comparison, the average velocity of the RL path is used as a constant velocity along the entire path computed by the other methods. The trajectories for the test are depicted in Fig. 8. The heatmap of the noise along the trajectory, the total ground noise impact of the path, and the distribution of the SPL along the trajectory are depicted in Figs 9–11, respectively. The performance metrics of the paths are illustrated in Fig. 12.
UAV flight paths: RL path (red line), A* path (yellow line), and direct path (blue line).

(a) Noise heatmap along the A* path. (b) Noise heatmap along the RL path.

(a) Noise footprint of the A* path. (b) Noise footprint of the RL path.

(a) SPL distribution along the A* path. (b) SPL distribution along the RL path.

Comparison of performance metrics for A*, RL, and direct paths.

The comparative analysis reveals that the RL model, despite generating a longer path and higher overall noise levels, effectively minimises SPL per unit length and achieves lower minimum SPL values. The increased path length and flight time associated with the RL model suggest a deliberate trade-off, where the model prioritises noise reduction over directness of the path. The higher maximum SPL observed in the RL model’s path indicates occasional peaks in noise, which may be a result of the model’s dynamic adjustments to minimise overall noise exposure. The reductions in SPL per unit length achieved by the RL model highlight its potential for applications where minimising noise pollution is critical. These findings suggest that while the RL model may not always produce the shortest or fastest path, it is more effective in reducing noise impact on the ground, which is a key objective for noise-sensitive environments.
To rigorously evaluate the generalisation capability and accuracy of the RL model, extensive testing was conducted on 10 different maps, each featuring random start and target locations. For each map, two separate tests were performed, and the key performance metrics were recorded for the three methods. The statistical analysis, presented as the median and standard deviation (std) for each performance metric, provides a comprehensive view of the model’s efficacy across varied scenarios. The statistical results are reported in Fig. 13. Figure 14 shows the complete set of performance metrics related to the validation results.
Box plot for (a) path length, (b) maximum SPL, (c) minimum SPL, (d) SPL per unit length of the three paths (A*, direct, RL): model validation results.

Comparison of performance metrics for A*, RL, and direct paths: model validation results.

The RL agent exhibited a median path length of 333.18 m with a standard deviation of 138.8 m. This performance closely mirrors the A* path. In contrast, the Direct path demonstrated a shorter median path length of 295.44 m. The relatively longer path lengths of the RL and A* trajectories indicate a prioritisation of navigational strategies beyond mere distance minimisation, aligning with the goal of noise reduction. The higher variability in the RL path length (std = 138.8 m) suggests an adaptive strategy, capable of tailoring paths to specific environmental conditions and noise constraints. The RL agent achieved the lowest median minimum SPL at 45.57 dB, significantly lower than the Direct path and the A* path. The standard deviation for the RL path’s minimum SPL was 3.88 dB, slightly higher than the direct (3.82 dB) and A* (3.65 dB) paths. This notable reduction in minimum SPL highlights the RL agent’s effectiveness in identifying possibilities to minimise the noise impact in sensitive regions. The RL path’s median maximum SPL was 56.61 dB with a standard deviation of 1.91 dB. While this value is slightly higher than the direct and A* paths, the low standard deviation for the RL path suggests a consistent upper bound on noise levels. This consistency is crucial for applications requiring predictable noise management. The slightly higher maximum SPL encountered by the RL path can be attributed to its dynamic velocity adjustments, which allow for brief increases in noise to optimise overall trajectory efficiency. The total SPL for the RL path had a median value of 17625.4 dB with a standard deviation of 7363.5 dB, which is higher than both the A* and the direct paths. The higher total SPL is a consequence of the longer path lengths and the emphasis on reducing noise per unit length rather than total noise. The larger variability in the RL path’s total SPL reflects its adaptive nature, adjusting paths to balance noise distribution effectively. The RL path excelled in minimising noise impact per unit distance, achieving a median SPL per unit length of 51.77 dB/m with a standard deviation of 2.97 dB. This performance surpasses both the direct and A* paths. The lower SPL per unit length indicates a more efficient distribution of noise along the trajectory, reducing the noise impact in noise-sensitive areas despite longer overall paths.
The validation results confirm that the RL model demonstrates strong generalisation capability and accuracy across diverse map layouts. The RL agent consistently achieves lower minimum SPL and SPL per unit length, highlighting its proficiency in managing noise effectively. While the RL paths are generally longer and exhibit higher total SPL, the significant reduction in noise per unit length underscores the agent’s strategic trade-off between path length and noise distribution. For the sake of clarity, it is hereby specified that these results refer to the HPM.
The ray tracing algorithm provides a comprehensive method for evaluating the SPL at ground level due to UAV noise. By accounting for reflections, atmospheric absorption and geometric divergence, the algorithm accurately models noise propagation. This detailed analysis is crucial for optimising UAV flight paths to minimise noise impact on the environment, ensuring compliance with noise regulations and enhancing community acceptance of UAV operations. Given the validation results presented in the manuscript, it is possible to state that future re-implementation of the SPL noise source generation model can be easily addressed; provided that extensive experimental results have been collected. Currently, such results are not present in the literature as this is an emerging research topic with just a few years of publication record. Also, comprehensive experimental results about the perception of drone noise (which may be added as an additional factor in the optimisation process) based on environmental and operating conditions is not present in the literature. This kind of experimental validation can only increase the fidelity and usefulness of the proposed approach.
3.2 Logistics drone mission
To test the effectiveness of the two models (HPM and LPM), a map was selected, and both versions of the RL model were tested under identical conditions, and the performance metrics were recorded for comparison. The high priority model, with its higher average velocity, is more effective in reducing flight time. However, this comes at the cost of a marginally higher total SPL and SPL per unit length. Conversely, the low priority model, with its longer path and flight time, achieves lower total SPL and SPL per unit length, indicating a more efficient noise management relative to the distance traveled. This approach highlights the adaptability of the RL models in handling different delivery scenarios. Integrating RL models into UAV delivery systems offers a robust solution for achieving flexible and optimised drone operations, tailored to the specific needs of different delivery scenarios. By adapting the models for different delivery priorities, we can ensure that drones can operate efficiently in diverse environments, meeting specific operational goals while adhering to noise regulations and reducing environmental impact. The results from these tests are shown in Figs. 15–19.
(a) Satellite photo of the area for testing HPM and LPM. (b) UAV flight paths from HPM and LPM.

(a) Noise heat map of the HPM UAV path. (b) Noise heat map of the LPM UAV path.

(a) Noise footprint of the HPM UAV path. (b) Noise footprint of the LPM UAV path.

(a) SPL distribution along the HPM UAV path. (b) SPL distribution along the LPM UAV path.

Comparison of performance metrics for HPM and LPM paths.

4.0 Conclusion
The results of this study underscore the significant potential of RL for noise-aware navigation of UAVs. Through comprehensive testing on both specific and generalised scenarios, the RL agent demonstrated a sophisticated balance between path length and noise management, outperforming traditional methods such as direct paths and A* algorithms in key aspects of noise control. The RL agent’s ability to follow a longer trajectory, while reducing noise per unit length and achieving lower minimum noise levels, highlights its effectiveness in prioritising noise-sensitive navigation. Despite the longer paths resulting in higher cumulative noise, the RL agent’s capacity to minimise noise impact per distance traveled showcases a nuanced approach to noise distribution. This capability is particularly crucial in environments where minimising noise pollution is essential, such as urban areas or noise-sensitive zones. The comparative analysis revealed that the RL agent’s trajectory, although the longest, effectively managed noise through dynamic adaptation of velocity based on environmental noise sensitivity. This adaptive control allowed the RL agent to reduce noise in critical areas while balancing overall travel efficiency. The lower minimum noise levels and efficient noise per unit length metrics indicate the RL agent’s proficiency in navigating through noise-sensitive environments with minimal disruption. Furthermore, the validation on multiple maps with varying start and target locations affirmed the RL agent’s generalisation capability. The consistent performance in minimising noise and managing maximum noise levels across diverse scenarios underscores the robustness and reliability of the RL model. The adaptability in path length and cumulative noise, driven by context-aware adjustments, demonstrates the RL agent’s potential to operate effectively in dynamic and varied environments. The study also highlighted the inherent trade-off between path length and noise management, a critical consideration for optimising UAV navigation. While the RL agent currently prioritises noise reduction over the shortest distance, ongoing refinements could enhance its overall performance, balancing both path efficiency and noise management. In conclusion, this research validates the efficacy of RL-based strategies for UAV navigation in noise-sensitive applications. The RL agent’s advanced noise management capabilities, combined with its adaptability and generalisation across different scenarios, make it a promising approach for achieving sophisticated environment-aware navigation solutions. Future research directions may include high-fidelity environment mapping including vegetation distribution as well as noise assessment metrics from both acoustics and psycho-acoustics domains.
Acknowledgements
The authors wish to thank the Piedmont Aerospace Cluster (https://www.distrettoaerospazialepiemonte.com/en/) for supporting the PhD activity of Marco Rinaldi.



