


Introduction
Theories and models in materials science and engineering are usually represented by mathematical formulas, which play vital roles in the understanding of materials behavior and performance as well as in the development of advanced materials and technologies. Before machine learning (ML) became available, theories and models were often, and even now continue to be, developed through intuition, derivation, or summarization from the accumulation of experience and knowledge of materials behavior and performance. This model-developing paradigm, however, requires long times and huge effort, as well as the genius of humans.
The rapid development of artificial intelligence (AI) techniques today provides the opportunity for automatic model construction. The new paradigm of data-driven science using AI techniques such as ML to discover knowledge and science from data generated from both experiments and computational simulations has rapidly expanded in the field of materials science and engineering. This paradigm combined with expert domain knowledge yields state-of-the-art methodologies for model development.Reference Goldstein and Coco1
Langley developed an AI program in 1979 with a few simple heuristics to solve a broad range of tasks (e.g., successful rediscovery of the ideal gas law, Kepler’s Third Law, Coulomb’s Law, Ohm’s Law, and Galileo’s Law).Reference Langley2 These models are among the simplest ones. A scientist’s dream is to find natural laws in explicit analytic expressions automatically from data. In 2009, Schmidt and Lipson showed that it was possible to distill underlying physical laws of two conservative systems, air-track oscillators and double pendulums, by employing SR based on genetic programming (GP).Reference Schmidt and Lipson3 An air-track oscillator has fine holes in its surface from which a layer of air is pumped to minimize the friction experienced by a car or several cars gliding on the track. Every car is connected to its nearest neighboring cars or the track end by springs. In these two experiments, they recorded the position of cars on the air track and the position of the pendulums over time by using motion-tracking software and then calculated the velocities and accelerations of the oscillators. They successfully rediscovered the underlying equations describing the designed systems: Hamiltonian or Lagrangian equations were recovered if coordinates and velocities were used as data, and the equation of motion was recovered if coordinates, velocities, and accelerations were all used as data. Besides SR, feature (or descriptor) selection using a ML technique termed the least absolute shrinkage and selection operator (LASSO), where features are scientifically meaningful properties or mathematic operators and the number of features can be reduced to zero by allowing the total magnitude of the summation over the absolute coefficients in a linear least squares fitting to be smaller than an adjustable parameter, was also shown to have the ability to rediscover physical laws from data numerically generated from targeted equations.Reference Schaeffer and McCalla4,Reference Rudy, Brunton, Proctor and Kutz5 Similarly, Ouyang et al. developed a data-driven method called “sure independence screening and sparsifying operator” (SISSO) for identifying interpretable physical descriptors for materials properties.Reference Ghiringhelli, Vybiral, Ahmetcik, Ouyang, Levchenko, Draxl and Scheffler6,Reference Ouyang, Curtarolo, Ahmetcik, Scheffler and Ghiringhelli7
Materials informatics is an emerging and rapidly developing area, particularly after the launch of Materials Genome Initiative (MGI) in 2011 (mgi.gov). Ramakrishna et al.Reference Ramakrishna, Zhang, Lu, Qian, Low, Yune, Tan, Bressan, Sanvito and Kalidindi8 defined materials informatics as that which “employs techniques, tools, and theories drawn from the emerging fields such as data science, internet, computer science and engineering, and digital technologies to the materials science and engineering to accelerate materials, products and manufacturing innovations.” Agrawal and Choudhary suggested that materials informatics has become the “fourth paradigm” in materials science.Reference Agrawal and Choudhary9 Following the guidance of MGI, many free-access and open-to-public materials databases have been built up and materials data are exponentially growing due to the development of high-throughput experiments and high-throughput calculations, as well as data sharing among the materials communities. See Reference Reference Ramakrishna, Zhang, Lu, Qian, Low, Yune, Tan, Bressan, Sanvito and Kalidindi8 for a complete list of available materials databases.
AI and ML-based models can be either explicit or inexplicit. An inexplicit AI and ML-based model function is a “blackbox” (e.g., neural network), which usually involves many flexible mathematical functions containing a number of parameters to fit data. Prediction accuracy is the main goal for such “blackbox” models, and the interpretation of the models is secondary. Although such “blackbox” models are widely applied, they are not the best choice if our goal is to pursue the understanding of underlying mechanisms, in addition to accuracy.
Data to knowledge necessitates models with simple, explicit mathematical expressions. SR is one of the most popular AI and ML methods to obtain explicit models from data for (exactly or approximately) describing target phenomena or mechanisms, and thus can be widely used by materials scientists and engineers to gain knowledge from data.Reference Wang, Wagner and Rondinelli10
SR has been applied in a wide range of application areas (e.g., in the field of fluid mechanicsReference Praks and Brkić11,Reference Goldstein, Coco, Murray and Green12 and dynamical systemsReference Hinchliffe and Willis13–Reference Quade, Abel, Shafi, Niven and Noack17). It is usually performed based on evolutionary computation (EC),Reference De Jong18 such as GPReference Koza19 and its variations, including grammar-guided genetic programming (GGGP),Reference McKay, Hoai, Whigham, Shan and O’Neill20 grammatical evolution (GE)Reference Ryan, Collins and Neill21 and Cartesian genetic programming.Reference Miller22 Inspired by and analogous to Darwin’s theory of evolution by natural selection for excellent offspring, the evolution in GP is realized via iterative selection of optimal candidate solutions. Usually, a candidate solution is called an individual, and the population of individuals after each iteration is named a generation. A new generation is evolved from its parent generation by selecting excellent individuals and adding new individuals. In GP, an individual is expressed in the form of a tree where nonterminal nodes are mathematic operators and terminal nodes are variables or constants and called leaves. Populations are continuously iterated via the process of individual evaluation, selection, and breeding by the operations of crossover and mutation, and eventually evolve to optimal expressions. The general ideas of EC, and the details of the GP, GGGP, and GE methods are presented in ReferencesReference De Jong18–Reference Ryan, Collins and Neill21 and Reference Poli, Langdon, McPhee and Koza23.
There are many publications on SR in the literature. In the following section, we refer to two specific examples of progress in SR research. An overview on SR applications in materials modeling and simulations is also described in a subsequent section. Finally, concluding remarks are provided to highlight our opinions about materials informatics and AI- and ML-based materials discovery and optimization.
Showcase examples of SR applications
Sette and BoullartReference Sette and Boullart24 illustrate how analytic formulas can be discovered via GP. As an example, we show how GP finds a proper mathematical expression to describe or approximate the simple trigonometric function of 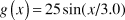 $g\left( x \right) = 25\,sin(x/3.0)$.
 $x$ is sampled as {0, 1, . . . , 9}. If
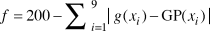 $f = 200 - \mathop \sum \limits_{i = 1}^9 |g({x_i}) - \text{GP}({x_i})|$, then the task of GP is to find a formula
 $\text{GP}(x)$ to minimize the summation term, or to let
 $f$ approach 200. Here, the 200 is used because the summation will always yield values between 0 and 200.Reference Sette and Boullart24 The operators set
 $\{ + , - , \times , \div \}$ and terminals (variables and constants) set
 $\left\{ {x,\left[ {0,...,9} \right]} \right\}$ were used for the construction of expression trees in GP, which was run for 30 generations, with an initial population size of 100. The number of generations and population size are preset parameters in a GP evolution, and their values depend on the complexity of the task, as well as the available computational resources. The evolved best function, considering the balance between fitting quality and formula complexity, is
 $- {x^2} + \frac{{349}}{{36}}x$, which is a good approximation of
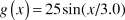 $g\left( x \right) = 25\,sin(x/3.0)$ within
 $x \in [0,9]$ and appears at the 20th generation with the fitted
 $\hat{f}$ value of 190 and a complexity of 19. Here, the complexity is defined as the number of terminals and operators used in the expression. The original trigonometric function was not discovered by GP because the sin operator is not included in the operator set. Clearly, the efficiency of GP and the performance of the created formulas depend critically on what operator sets in addition to the terminal sets are used.
Sette and BoullartReference Sette and Boullart24 also explored the spinning process of yarn in the textile industry and predicted both spinnability and yarn strength deviating from the fiber quality and machine settings. GP was performed on a database of 2160 data points with five machine parameters and five continuous fiber characteristics. The operator set included (1) 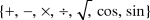 $\[\{ + , - , \times , \div ,\sqrt , \,cos,\,sin\} \]$; (2) a maximum/minimum function; and (3) a step function that groups parameters (0.5, 1.0) to be 1.0 and (0.0, 0.5) to be 0.0. GP evaluations for spinnability and yarn strength yield mathematical expressions that both have prediction accuracy greater than 90%. Partial original features, rather than all of them, appeared in the final expressions, thereby indicating the importance of feature selection.
The dimensional consistency of physical quantities must be maintained in SR for constructing meaningful equations. It was found that the introduction of dimensional analysis (DA) into neural networks could improve prediction performance.Reference Gunaratnam, Degroff and Gero25,Reference Jamadar and Vakharia26 GGGP provides an easy way by using grammar, which imposes a set of semantic constraints on the available forms of mathematical expressions, to incorporate DA, as well as domain knowledge.Reference Angeline and Kinnear27 Ratle and SebagReference Ratle and Sebag28 argued that the integration of DA in grammar might make this more complex and thus lead to poor performance. They proposed that dedicated design of the population initialization step of GGGP might give admissible individuals (i.e., mathematical expressions) sufficient diversity and limited size, where every individual is dimensionally consistent and its size is also limited to preset maximum tree depth without losing diversity. To prove their arguments, they used the proposed approach to rediscover the Kelvin–Voigt model for two viscoelastic systems: (1) parallel connection of a dashpot  ${\text{\eta }_1}$ and a spring
 ${K_1}$ (termed Sys1); and (2) series connection of a spring
 ${K_2}$, a dashpot
 ${\text{\eta }_2}$ and Sys1 (termed Sys2). They generated data by assigning random values to materials parameters in the designed model, representing 20 pseudo-materials. By comparing the results from both common grammar (DA-excluded) and DA-included grammar, they showed that integration of DA significantly accelerated the evolution task.
The proposed method was then applied to find an analytic model for force–displacement curves and force–time curves in indentation tests on various materials. Their results indicate that the DA-included algorithm was able to discover accurate expressions for each of the tested samples, whereas only one unified expression was found for all four tested samples by using the common algorithm, thereby demonstrating the significant advantage of using the DA-included algorithm. More examples of SR applications can be found in recent handbooks of GEReference Ryan, O’Neill and Collins29 and GP.Reference Gandomi, Alavi and Ryan30
SR applications in materials modeling and simulations
Multiscale simulations of materials properties and phenomena are essential in materials research and design. However, the current widely used density functional theory in materials simulations experiences a large gap in time and length scales with respect to real materials. Advanced methods and strategies are urgently needed to bridge this gap. In this regard, trans-scale (crossing scales) simulations are being developed, where GP is utilized to facilitate multiscale and trans-scale simulations.Reference Sastry, Johnson, Goldberg and Bellon31,Reference Sastry, Johnson, Goldberg and Bellon32 Sastry et al. used GP to symbolically regress mapping of saddle point barriers from only a few calculated points via molecular dynamics, thereby avoiding explicit calculation of all barriers.Reference Sastry, Johnson, Goldberg and Bellon31 The GP-regressed barrier function allows one to carry out kinetic Monte Carlo simulations with real-time kinetics based upon realistic atomic interactions. Sastry et al. GP-regressed diffusion energy barriers of a surface atom to its nearby vacancy on the (100) surface of the fcc binary alloy CuxCo1–x and predicted the diffusion barriers within 0.1% error by using 3% or less of the total number of barriers with this approach, leading to a dramatic reduction in CPU time on the order of 4∼7.
Sastry et al. also conducted SR to discover a constitutive model that describes the relationship between flow stress  $\text{\sigma }$ and temperature-dependent strain rate
 $\mathrm{\varepsilon }$ from experimental data for Al-Zn-Mg-Cu aluminum alloy AA7055, a commercially available aluminum alloy with high strength.Reference Sastry, Johnson, Goldberg and Bellon32 The used operator set is
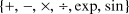 $\{ + , - , \times , \div , exp,sin\}$, and the terminal set is
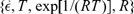 $\{ \mathrm{\varepsilon },T,\,exp[1/(RT)],\mathrm{\mathcal{R}}\}$, where
 $R$ is the ideal gas constant,
 $T$ is temperature, and
 $\mathrm{\mathcal{R}}$ is a random number. The GP, based on experimental data of compression tests at temperatures ranging from 340°C to 520°C at a strain rate of 10−3 s−1, yielded the model:
 $$\mathrm{\varepsilon } = {c_0}exp\left( {\frac{1}{{RT}}} \right){\left( {\frac{\text{\sigma }}{\text{\mu }}} \right)^{4.55}},$$
where  $\text{\mu }$ is viscosity and
 ${c_0}$ is a constant. The formula is nearly the same as that proposed by Padilla et al.,Reference Padilla, Harnish, Gore, Beaudoin, Dantzig, Robertson, Weiland, Tiryakioglu and Lalli33 who used the following law:
 $$\mathrm{\varepsilon } = {c_0}exp\left( {\frac{Q}{{RT}}} \right){\left( {\frac{\text{\sigma }}{\text{\mu }}} \right)^{4.56}}\,,$$
where Q is the activation energy. Furthermore, GP conducted with both low (10−3 s−1) and high strain rate (1 s−1) data gave a unified expression:
 $$\mathrm{\varepsilon } = \frac{{{c_0}exp\left( {1/RT} \right)}}{{g[\mathit{\dot{\varepsilon }},exp\left( {1/RT} \right)]}}{\left( {\frac{\text{\sigma }}{\text{\mu }}} \right)^4}\left( {1 - \frac{\text{\sigma }}{\text{\mu }}} \right),$$
with  $g$ being a complex expression.Reference Sastry, Johnson, Goldberg and Bellon32 This model might imply competition between the fourth-order power law and the fifth-order power law in stress.Reference Sastry, Johnson, Goldberg and Bellon32
The interatomic potential plays a central role in MD and Monte Carlo simulations. Traditionally, potentials are mainly developed based on experience and are thus also called empirical potentials. Recently, data-driven construction of interatomic potentials has become a focus in chemistry and materials science,Reference Behler34 and the commonly used ML methods include artificial neural networks,Reference Li, Ando, Minamitani and Watanabe35–Reference Dolgirev, Kruglov and Oganov39 ridge regression,Reference Fracchia, Del Frate, Mancini, Rocchia and Barone40 Gaussian approximation potential,Reference Deringer and Csányi41 and Gaussian process regression.Reference Glielmo, Sollich and De Vita42,Reference Li, Kermode and De Vita43 GP is also used to construct interatomic potentials.Reference Brown, Thompson and Schultz44–Reference Hernandez, Balasubramanian, Yuan, Mason and Mueller48
In general, data-driven potentials work well within the sampling region, whereas extrapolating to “unseen” (without training data) areas is a challenge. On the other hand, empirical potentials might be widely applicable but usually suffer from insufficient accuracy. These two aspects may complement each other, and their combination could result in potentials with both improved prediction accuracy and transferability.
Hernandez et al.Reference Hernandez, Balasubramanian, Yuan, Mason and Mueller48 summarized the frequently appearing function forms in many empirical potentials, such as Lennard-Jones potential, Morse potential, and many-body potentials, and put them into the function set as expert domain knowledge. First, they tested GP to see if it could construct the pairwise Lennard-Jones potential and the many-body Sutton–Chen embedded atomic potential with the training data, which were generated from MD simulations with the previously mentioned potentials under various simulation ensembles and temperatures. Indeed, GP successfully recovered the original potentials, though the parameters were slightly different. After the validation, they constructed GP copper potentials, considering complexity, computational cost, and fitting quality, from data produced from ab initio MD simulations under different ensembles or temperatures.Reference Hernandez, Balasubramanian, Yuan, Mason and Mueller48 Two GP potentials were applied in MD simulations to predict the elastic constants  ${C_{11}}$,
 ${C_{22}},$ and
 ${C_{44}}$ of fcc copper. Their results showed that the two GP potentials have accuracy comparable to those of the established accurate empirical potentials, while the GP potentials bear the advantages of low complexity.Reference Hernandez, Balasubramanian, Yuan, Mason and Mueller48
In finite element (FE) analysis, modeling nonuniform, nonlinear, and inelastic materials and structures is challenging. Automatic routes and techniques are required for constructing constitutive models from experimental data directly and applying them to FE analysis. GP is powerful in solving this challenging problem, especially when combining with domain knowledge. Javadi and ReezaniaReference Javadi and Rezania49 proposed an intelligent FE method, in which the constitutive equation of 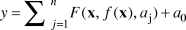 $y = \mathop \sum \limits_{j = 1}^n F(\mathbf{x},f(\mathbf{x}),{a_j}) + {a_0}$ is derived by evolutionary polynomial regression (EPR) from experimental data, where
 $y$ is the predictor output,
 $\mathbf{x}$ are input variables,
 $f$ is some user-provided function, and
 $a$j and
 $a$0 are constants. The function form of
 $F$ is constructed by evolutionary selection of function blocks provided by the user based on their understandings of the physical behaviors. The authors performed EPR on a data set that included 537 items from triaxial tests of a soil and finally obtained the variation of the next state of deviator stress (
 ${^{i + 1}}{\text{\sigma }_\text{d}}$) as a function of the current one (
 ${^i}{\text{\sigma }_\text{d}}$), as well as the confining pressure (
 ${\text{\sigma }_3}$), the current axial strain (
 ${^i}{\text{\varepsilon }_1}$), and the axial strain increment (
 ${^i}(\text{\Delta }{\varepsilon _1})$). For each load increment, the instant modulus was calculated using
 $${E_{\text{EPR}}} = \frac{{{^{i + 1}}({\text{\sigma }_\text{d}}_1) - {^i}({\text{\sigma }_\text{d}}_1)}}{{{^{i + 1}}\left( {{\text{\varepsilon }_1}} \right) - {^i}({\text{\varepsilon }_1})}}$$
and substituted into the constitutive equation of  $\text{\Delta \sigma } = \mathbf{D}\text{\Delta \varepsilon }$, where
 $\mathbf{D}$ is the material stiffness matrix and updated after
 ${E_{\text{EPR}}}$ was recalculated in each step. The FE analysis in conjunction with EPR gave a reliable result, as compared to the traditional elastic–plastic model and nonlinear elastic model. Recently, they extended the EPR method by employing a multi-objective genetic algorithm to reach a tradeoff result between fitness and function complexity,Reference Faramarzi, Alani and Javadi50 which means maximization of fitness and minimization of model complexity.
GandomiReference Gandomi, Sajedi, Kiani and Huang51,Reference Gandomi and Alavi52 employed multi-objective GP, as well as multi-gene genetic programming (MGGP), to find models of concrete strength and creep. For MGGP, they used linear combinations of several GP trees to give a prediction, rather than using only one tree in standard GP. They named a single GP tree as a gene. The MGGP is mathematically expressed by:
 $$\hat{y}(\mathbf{x},\mathbf{d}) = {d_0} + \mathop \sum \limits_{i = 1}^n {d_i}{G_i}(\mathbf{x})\,,$$
where  ${G_i}(\mathbf{x})$ is the output of each GP tree (or each gene),
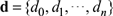 $\mathbf{d} = \{ {d_0},{d_1}, \cdots ,{d_n}\}$ is the gene weight vector,
 $n$ is the number of the gene, and
 $\mathbf{x}$ is the vector of the input variables.
 $\mathbf{d}$ is evaluated by using least squares fitting of the expression to data. Each single GP tree is randomly generated and several GP trees are randomly picked and linearly combined to generate an initial population. Besides crossover and mutation operations in one GP tree as in standard GP, the whole GP trees in MGGP between two expressions are permitted to crossover operations. Their methods presented more accurate predictions for total compliance of concrete than current available models using various statistical indicators.
Versino et al.Reference Versino, Tonda and Bronkhorst53 conducted GP on the deformation behavior of metallic copper to find the expression of strength (represented by flow stress) versus plastic strain ( ${\text{\varepsilon }^p}$), plastic strain rate (
 ${\text{\varepsilon }^p}$), and temperature (
 $T$):
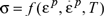 $\text{\sigma } = f({\text{\varepsilon }^p},{\text{\varepsilon }^p},T)$. Four GP models were derived either by using standard GP or GP subjected to expert knowledge constraints. Their data were extracted from the literature. The four GP models as well as two well-established strength models, the Preston–Tonks–Wallace modelReference Preston, Tonks and Wallace54 and the mechanical threshold stress model,Reference Follansbee and Kocks55 were compared by performing a virtual experiment with a classical large-deformation and high strain-rate test—Taylor anvil impact on a copper cylinder under different temperatures from 295 K to 1235 K and different initial velocities from 48.7 to 394 m/s. Comparing the deformed profile and the final length of the simulated cylinder with those of the experimental one indicates the excellent performance of the GP models.Reference Versino, Tonda and Bronkhorst53
Concluding remarks
Recent advancements in data-driven methodology, together with fast-growing materials data, have enabled automatic extraction of knowledge from data and accelerated novel materials discovery, which is becoming a new paradigm in materials research and development. Among the cutting-edge data-driven methods, SR provides regression results in analytic formulas or equations, thereby delivering scientific insights. SR is widely applicable across all areas of materials science and engineering to find explicit formulas, hypotheses, and laws for targeted materials properties and functions.
In particular, when SR is coherently combined with domain knowledge, scientifically meaningful models can be obtained with much less computation power and time. What distinguishes SR from other ML “blackbox” models lies in the analytic outputs, therefore, the significance of integrating domain knowledge into SR has become especially important. In addition to the fitting quality, the low complexity of outcome formulas enable the formulas to be more robust against data noise. When an anticipated formula has only a few coefficients, SR might not require big data for training. Considering the flexibility of incorporating domain knowledge and the large family of genetic programming algorithms, SR is expected to play increasing roles and has broader applications in data-driven knowledge discovery.
Great challenges remain with SR when domain knowledge is not available or insufficient, where SR outcome models may not be physically meaningful and even hard to interpret. One should keep in mind that material data are not perfect; the data may contain noise, and usually, there aren’t enough data points. Since the SR outcome is assessed purely by fitting quality, the SR outcome might have a better fitting quality than the outcome directly from domain knowledge. Under this circumstance, which should we trust, the SR outcome or the outcome directly from domain knowledge? Therefore, it is important in the future to consider how the interpretability of SR outcome models can be improved. At the moment, most terminals in SR are represented by scalar quantities, as overviewed in the present article, and few publications with vector and tensor terminals can be found in the literature. Thus, the development of SR algorithms with mathematical operations on high dimensional terminals might demand more attention from the materials information community.
Acknowledgments
This work was supported by the National Key Research and Development Program of China (No. 2017YFB0702101, 2017YFB0701604 and 2018YFB0704400). S.S. and B.Z. also acknowledge the National Natural Science Foundation of China (No. 11672168).

Sheng Sun is an associate professor at the Materials Genome Institute at Shanghai University, China. He received his BS degree in aircraft design and his MS degree in nanomechanics from the Nanjing University of Aeronautics and Astronautics, China, in 2005 and 2008, respectively. He earned his PhD degree in bioengineering from The Hong Kong University of Science and Technology in 2011. His current research focuses on materials informatics by combining multiscale simulations, mathematical modeling, and machine learning. Sun can be reached by email at mgissh@t.shu.edu.cn.

Runhai Ouyang joined Shanghai University, China, in 2019 as an associate professor at the Materials Genome Institute. He obtained his PhD degree in physical chemistry in 2014 from the Dalian Institute of Chemical Physics, Chinese Academy of Sciences, China. He conducted postdoctoral research at The University of Sydney, Australia, at the University of California, Riverside, and at the Fritz Haber Institute of the Max Planck Society, Germany, He was a co-creator of the SISSO (sure independence screening and sparsifying operator) method. Ouyang can be reached by email at rouyang@shu.edu.cn.

Bochao Zhang is pursuing his MS degree at the Materials Genome Institute at Shanghai University, China. He received his BS degree in mining engineering from the China University of Mining and Technology, China, in 2017. His research focuses on high-throughput materials modeling of electrode/electrolyte interfaces. Zhang can be reached by email at mgizbc@shu.edu.cn.

Tong-Yi Zhang is the founding dean of the Materials Genome Institute at Shanghai University, China. He and was previously at The Hong Kong University of Science and Technology. He is a member of the Chinese Academy of Sciences, China, and the Hong Kong Academy of Engineering Sciences, Hong Kong, and a Fellow of the Hong Kong Institution of Engineers, ASM International, and the International Fracture Congress. His awards include two Second Prizes of the State Natural Science Award of China and the Ho Leung Ho Lee Prize for Scientific and Technological Progress. His current research focuses on materials informatics and mechanoinformatics. Zhang can be reached by email at zhangty@shu.edu.cn.


