INTRODUCTION
Input for learners is a necessary condition for language development (Ellis, Reference Ellis1994; VanPatten, Reference VanPatten2002). Nonetheless, target language input alone may be insufficient for learning to take place (Doughty & Williams, Reference Doughty, Williams, Doughty and Williams1998) because learners may not pay attention to input or might not be able to process it in a way that facilitates their linguistic development. There is an abundance of previous studies in the field of second language acquisition (SLA) that have investigated the various conditions under which the provision of input might assist language learning (for a review see Robinson, Mackey, Gass, & Schmidt, Reference Robinson, Mackey, Gass, Schmidt, Gass and Mackey2012). Yet little is known about the attentional processing involved in learning from different types of input and how attentional processing relates to learning gains in various input conditions. Most studies thus far have focused on attentional processing in conditions where participants were exposed to input flood and where the target structure was textually enhanced (Issa, Morgan-Short, Villegas, & Raney, Reference Issa, Morgan-Short, Villegas, Raney, Roberts, McManus, Vanek and Trenkic2015; Simard & Foucambert, Reference Simard, Foucambert, Bergsleithner, Frota and Yoshioka2013; Winke, Reference Winke2013), but to our knowledge no previous research has examined how an instruction to pay attention to specific aspects of input and explicit metalinguistic explanations facilitate attentional processing.
In this article, we present the findings of a study that investigated how learners pay attention to a target syntactic construction in written L2 input in four different conditions: input flood, input enhancement, instruction to pay attention to the target construction, and explicit metalinguistic explanation. We also examined how the learners’ knowledge of the targeted construction changed in these conditions and how the changes under different conditions were related to attentional processing. First, we will discuss conceptualizations of attention, awareness, and consciousness in cognitive psychology and SLA research. This will be followed by an overview of previous studies on learning under explicit and incidental conditions. Then we will present the methodology we applied in this study to measure attention and the results that we obtained. Finally, we will discuss the findings of the study and their relevance for the field of SLA and language teaching pedagogy.
BACKGROUND
Attention, Consciousness, and Awareness in Cognitive Psychology
To date, ample evidence has been accumulated to indicate that not everything L2 learners are exposed to will be acquired (see, e.g., Sharwood Smith, Reference Sharwood Smith1993). One of the major factors that influences whether or not input will turn into intake is the attention paid to it (Doughty, Reference Doughty and Robinson2001; Robinson et al., Reference Robinson, Mackey, Gass, Schmidt, Gass and Mackey2012; Schmidt, Reference Schmidt1990, Reference Schmidt, Chan, Chi, Cin, Istanto, Nagami, Sew, Suthiwan and Walker2010). Although attention is a key concept in the field of SLA research as well as in cognitive psychology, there is still no consensus as to what attention actually is (Allport, Reference Allport, Meyer and Kornblum1993; Shinn-Cunningham, Reference Shin-Cunningham2008; Wolfe & Horowitz, Reference Wolfe and Horowitz2004). In a recent overview, Chun, Golomb, and Turk-Browne (Reference Chun, Golomb and Turk-Browne2011) define attention as “a core property of all perceptual and cognitive operations. Given limited capacity to process competing options, attentional mechanisms select, modulate, and sustain focus on information most relevant for behavior” (p. 73). Chun et al. (Reference Chun, Golomb and Turk-Browne2011) draw up a useful taxonomy of attentional processing that is particularly relevant for our study. While they acknowledge that attention is not a unitary system, they argue that there are two fundamental ways in which we process attentional targets. On the one hand, we can select and adjust stimuli perceived externally through our senses (e.g., specific information presented on a screen), which they call external attention. External attention can be a stimulus-driven bottom-up process, as well as a goal-directed top-down process. On the other hand, internal attention operates over representations in long-term and working memory (WM), task rules, and responses.
Consciousness, which in simple terms describes the understanding of one’s experiences (Max Velmans, Reference Max Velmans2009; Nagel, Reference Nagel1974), is a concept that is inseparable from attention, yet still needs to be differentiated from it (Bachman, Reference Bachman, Jing, Rosenzweig, d’Ydewalle, Zhang, Chen and Zhang2006; O’Regan & Noe, Reference O’Regan and Noe2001). Koch and Tsuchiya (Reference Koch and Tsuchiya2006) argue that the key function of consciousness is to assist in summarizing information that “pertains to the current state of the organism and its environment and ensuring this compact summary is accessible to the planning areas of the brain” (p. 17). They provide a convincing summary of evidence that there are cases when attentional processing takes place without consciousness. For example, in processes such as priming, adaptation, and visual search, “subjects can attend to a location for many seconds and yet fail to see one or more attributes of an object at that location” (ibid.). This demonstrates the potential lack of consciousness in these cognitive processes. According to Koch and Tsuchiya, however, attention, with consciousness, is necessary for the registration of stimuli in WM, for distinction between stimuli and the provision of a full report of the stimuli attended to.
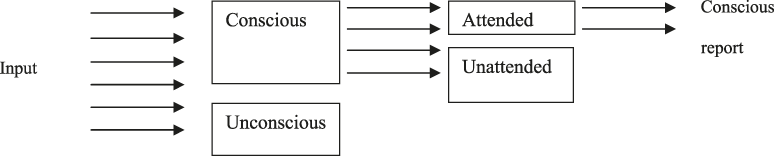
Awareness is another concept that is closely related to attention and consciousness. Lamme’s (Reference Lamme2003) cognitive psychological model is helpful in elucidating how attention can be distinguished from both consciousness and awareness (see Figure 1). Lamme argues that input can be perceived either consciously or unconsciously. Consciously perceived input can either be attended to or remain unattended, highlighting that in his model attention is seen as a phenomenon that is distinct from consciousness. Input that has been consciously perceived and attended to is then available for conscious reporting and can be stored in WM. This final level in the model is regarded as awareness.
Lamme’s (Reference Lamme2003) model of visual awareness and its relation to attention.

Attention, Awareness, and Noticing in Second Language Acquisition
The role of attention, awareness, and consciousness is key to how second language learners process target language input. Existing studies in the field of SLA unequivocally support that paying attention to certain features in the input is necessary for language development (for a review see Robinson et al., Reference Robinson, Mackey, Gass, Schmidt, Gass and Mackey2012). Noticing, according to Schmidt, involves “focal awareness” (Reference Schmidt and Schmidt1995, p. 132), which is necessary for language learning. He further notes that noticing is “nearly ‘isomorphic’ with attention” (ibid., p. 1) and “[what is noticed is] consciously registered” (Schmidt, Reference Schmidt, Chan, Chi, Cin, Istanto, Nagami, Sew, Suthiwan and Walker2010, p. 2). Thus, Schmidt considers noticing to be an attentional process that involves both consciousness and awareness. Schmidt (Reference Schmidt1990) also highlights that noticing is a “private experience, although [it] can be operationally defined as availability for verbal report, subject to certain conditions” (p. 132). According to the definitions in cognitive psychology cited in the preceding text, awareness involves the possibility of offering verbal reports, and therefore what Schmidt calls “noticing” can be equated with “awareness.” Schmidt (Reference Schmidt1990, Reference Schmidt and Schmidt1995, Reference Schmidt, Chan, Chi, Cin, Istanto, Nagami, Sew, Suthiwan and Walker2010) distinguishes between two different levels of awareness: awareness at the level of noticing and awareness at the level of understanding. Noticing can be considered as a surface-level phenomenon, “the conscious registration of the occurrence of certain events” (Schmidt, Reference Schmidt and Schmidt1995, p. 19), whereas understanding represents a deeper level of processing involving pattern and rule recognition. Therefore, understanding is the conscious outcome of a learner’s analysis, comparison, and hypothesis-testing activities. Truscott (Reference Truscott1998) and Truscott and Sharwood Smith (Reference Truscott and Sharwood Smith2011) draw attention to several conceptual problems with the Noticing Hypothesis (NH). They argue that noticing, as Schmidt defines it, is an intermediate level of noticing, because it does not involve rules, generalizations about the language, or form-meaning mapping. They also point out that the NH does not offer a clear explanation of the level of awareness involved in noticing and how noticing is differentiated from either no awareness or a higher level of awareness.
In a more recent discussion, Godfroid, Boers, and Housen (Reference Godfroid, Boers and Housen2013) separate awareness and attention and view them as two sides of the same coin. They do not disregard the possibility of awareness having a role to play in noticing; however, their argument is that a certain level of attention is sufficient for registering new stimuli in long-term memory. This is similar to the view of both Tomlin and Villa (Reference Tomlin and Villa1994) and Robinson (Reference Robinson1995), who argue that awareness is not a necessary condition for language learning. In line with Robinson (Reference Robinson1995), Godfroid et al. (Reference Godfroid, Boers and Housen2013) define noticing as “a cognitive process in which the amount of attention paid to a new language element in the input exceeds a critical threshold, which causes the language element to enter WM and become the object for further processing” (p. 493). Nevertheless, the question remains how to determine the threshold beyond which a stimulus enters WM. In Godfroid et al.’s (Reference Godfroid, Boers and Housen2013) study this threshold is established by comparing processing times spent on real words and pseudowords; however, this might also reflect the different nature of reading involved in reading existing versus nonexisting words (Coltheart, Curtis, Atkins, & Haller, Reference Coltheart, Curtis, Atkins and Haller1993). Therefore processing time differences might not only result from different attentional processing mechanisms but also from different cognitive operations.
As our brief review highlights, there are two key unresolved issues in the investigation of noticing: one concerns the role and degree of awareness involved in noticing and the other the establishment of a critical threshold of processing above which one can claim that noticing took place. Given these theoretical and methodological problems and the fact that the concept of noticing is not present in the psychological literature of awareness, consciousness, and attention, we decided to focus on the construct of attention instead of noticing and investigated L2 learners’ attentional processing under different input conditions. One of the currently available tools that can provide insights into the amount of attention paid to specific features in the input is eye tracking, which we applied in our study to measure attention.
Eye Tracking as a Method of Measuring Attention
The basic assumption underlying eye-tracking studies is that eye movements are to some extent controlled and guided by the attentional system and that eye-fixation durations are indicative of ongoing cognitive processing (Liversedge, Gilchrist, & Everling, Reference Liversedge, Gilchrist and Everling2011; Rayner & Pollatsek, Reference Rayner and Pollatsek1989). It is important to note, however, that not all eye movements are under attentional control and one can attend to a specific visual stimulus without necessarily fixating on it (Hunt & Kingstone, Reference Hunt and Kingstone2003; Juan, Shorter-Jacobi, Schall, & Sperling, Reference Juan, Shorter-Jacobi, Schall and Sperling2004). The eye-tracking measures used to gain insights into attentional processing vary in the field of cognitive psychology (for a review see Reichle, Pollatsek, & Rayner, Reference Reichle, Pollatsek and Rayner2006). In SLA total reading time, which is calculated as the total amount of time that one gazes at an area of interest during reading, has been utilized as one of the main measures (Godfroid et al., Reference Godfroid, Boers and Housen2013; Godfroid & Uggen, Reference Godfroid and Uggen2013; Issa et al., Reference Issa, Morgan-Short, Villegas, Raney, Roberts, McManus, Vanek and Trenkic2015; Smith, Reference Smith and Hult2010, Reference Smith2012; Winke, Gass, & Sydorenko, Reference Winke, Gass and Sydorenko2013).
As pointed out in the preceding text, total fixation duration (TFD) and the total number of eye fixations on a target word/phrase might tell us for how long and how many times participants view a target item, but these might not accurately reflect attentional processing (see also Reichle et al., Reference Reichle, Pollatsek and Rayner2006). In order to overcome this problem, Smith (Reference Smith and Hult2010) considered TFD in excess of 500 milliseconds to be an indication of noticing (attention); however, how this threshold was arrived at is not clear. In other eye-tracking studies the difference in TFD between the experimental condition(s) and the control condition on the target items was regarded as a measure of noticing/attention. This is a more accurate procedure for establishing extra attentional processing load than the use of total fixation time and the total number of eye fixations alone. Nevertheless, the methods of establishing increased attentional processing in these studies still posit several questions. We already highlighted issues relating to the comparison of pseudo- and real-word reading in Godfroid et al.’s (Reference Godfroid, Boers and Housen2013) and Godfroid and Schmidtke’s (Reference Godfroid, Schmidtke, Bergsleithner, Frota and Yoshioka2013) studies. Winke (Reference Winke2013) compared the total reading times in a textually enhanced condition to those in an unenhanced condition. A significant difference between the two groups was taken as an indication of noticing. It is possible, however, that the control group in the unenhanced condition might have also paid attention to the target items, and hence their data might not serve as an accurate baseline. The most precise measure of noticing was devised by Godfroid and Uggen (Reference Godfroid and Uggen2013), who subtracted the fixation duration on two different forms of the same verb and then compared these subtracted values for regular and irregular verbs.
Given the problems with treating the TFDs of the control group as base line, we decided to use two eye-tracking measurements in this study to investigate the amount of attention paid to the target items: TFD on areas of interest (AOI) and the difference between observed TFD and expected TFD on AOIs (ΔOE). As described in the preceding text, the first of these measures, TFD, has been widely applied in previous studies. The second measure, which is in certain ways similar to the subtracted measure used by Godfroid and Uggen (Reference Godfroid and Uggen2013) and to residual reading times in sentence processing studies (Trueswell, Tanenhaus, & Garnsey, Reference Trueswell, Tanenhaus and Garnsey1994; Wilson & Garnsey, Reference Wilson and Garnsey2009), was developed to take into consideration participants’ reading speed when determining extra attentional processing load. The expected TFD was the average reading time that the participants spent on each word/phrase presented on the screen. Observed time was the actual time that the participants spent on target constructions. If a participant spent more time on a word/phrase than the expected reading time (difference between observed fixation duration and expected fixation duration), we considered it as a measure of additional attentional processing (for more details on the actual calculation of this measure see the methodology and data analysis sections).
Attentional Processing and Learning Outcomes in Different Instructional Conditions
Recent eye-tracking studies (e.g., Issa et al., Reference Issa, Morgan-Short, Villegas, Raney, Roberts, McManus, Vanek and Trenkic2015; Winke, Reference Winke2013) have investigated cognitive and attentional processing in different instructional conditions. In these studies, input salience was enhanced implicitly by means of input flood and textual enhancement (TE). In conditions of input flood, the frequency of the target construction is increased in the input. Another commonly applied input enhancement technique involves making target language constructions visually salient. Salience can also be increased externally with the help of explicit focus on form (FonF) techniques (Doughty & Williams, Reference Doughty, Williams, Doughty and Williams1998), such as the discussion of target forms, metalinguistic explanations, negative evidence through overt error correction, processing instructions, and garden-path techniques (Gascoigne, Reference Gascoigne2006; Nassaji & Fotos, Reference Nassaji and Fotos2011).
The findings with regard to the potential role of input flood in enhancing learners’ L2 competence are mixed. Reinders and Ellis (Reference Reinders, Ellis, Ellis, Loewen, Elder, Erlam, Philp and Reinders2009) report similar posttest gains in both input enhancement and input flood groups in their study of English negative adverbs. Trahey and White (Reference Trahey and White1993) found that input flood had a significant effect on learning word order in English. Hernández’s (Reference Hernández2008) study, however, indicated that input flood combined with explicit instruction is more effective than input flood alone for learning discourse markers in Spanish.
The findings of previous research on TE are also contradictory. Alanen (Reference Alanen and Schmidt1995), Jourdenais, Ota, Stauffer, Boyson, and Doughty (Reference Jourdenais, Ota, Stauffer, Boyson, Doughty and Schmidt1995), and Shook (Reference Shook1994) found TE to have a positive impact on L2 learners’ grammatical development. The results of Leow (Reference Leow2001), Leow, Egi, Nuevo and Tsai (Reference Leow, Egi, Nuevo and Tsai2003), White (Reference White, Doughty and Williams1998), Wong (Reference Wong2003), Overstreet (Reference Overstreet1998), and Simard (Reference Simard2009) showed no effect of TE. Overall, Lee and Huang’s (Reference Lee and Huang2008) meta-analysis concluded that TE has a small-sized effect (d = .22) on the acquisition of grammatical constructions in L2 learning. Two recent eye-tracking studies by Winke (Reference Winke2013) and Simard and Foucambert (Reference Simard, Foucambert, Bergsleithner, Frota and Yoshioka2013) indicate increased attentional processing of input under enhanced conditions when attentional processing is operationalized as total fixation time, whereas in Issa et al.’s (Reference Issa, Morgan-Short, Villegas, Raney, Roberts, McManus, Vanek and Trenkic2015) research, TE had no effect on total fixation time but resulted in lower skipping rates. Neither Winke (Reference Winke2013) nor Issa et al. (Reference Issa, Morgan-Short, Villegas, Raney, Roberts, McManus, Vanek and Trenkic2015) found a significant relationship between total fixation time and gain scores.
There seems to be stronger evidence for the beneficial effects of explicit instruction in second language learning. In Goo, Grañena, Yilmaz, and Novella’s (Reference Goo, Grañena, Yilmaz, Novella and Rebuschat2015), Norris and Ortega’s (Reference Norris and Ortega2000), and Spada and Tomita’s (Reference Spada and Tomita2010) meta-analyses of previous studies, explicit instruction was found to result in substantially greater improvement in various posttest scores than implicit instruction, in which no explicit explanation of the grammatical construction or instruction to pay attention to specific constructions in the input was offered. In line with the findings of these meta-analyses, studies where implicit and explicit FonF techniques were jointly investigated also show the advantage of explicit instruction (see e.g., Radwan, Reference Radwan2005; Robinson, Reference Robinson1997; Rosa & O’Neill, Reference Rosa and O’Neill1999; Tode, Reference Tode2007) (for a critical analysis see also Andringa, De Glopper, and Hacquebord, Reference Andringa, De Glopper and Hacquebord2011).
Recent advances in eye-tracking technology allow us to investigate how successful explicit and implicit instruction is at directing learners’ attention to the target linguistic features and how the amount of attention paid to the target constructions is associated with learning gains under different instructional conditions. In our research we examined how attention to input facilitates language development under four instructional conditions: input flood, TE, instruction to pay attention to a grammatical construction, and explicit metalinguistic explanation of the target language construction. The chosen syntactic construction was causative had. The choice of this construction was motivated by the assumption that the selected preintermediate learner sample would have no or very little preexisting knowledge of this construction. Another important consideration was that the construction should form an easily identifiable area of interest for eye-tracking research. Furthermore, because we used implicit instructional techniques and the intervention was relatively short, we needed to select a construction whose meaning could be inferred from the context and for which there is a one-to-one form-to-meaning mapping. Our research questions were as follows:
Research question 1: How does knowledge of the form and meaning of the target syntactic construction causative had as measured by a production and a comprehension task change under explicit and implicit instructional conditions in the case of Sri Lankan preintermediate-/intermediate-level English language learners?
Research question 2: How does attention paid to examples of the causative had construction in the input texts differ under explicit and implicit instructional conditions?
Research question 3: How is the change in knowledge of the target construction under explicit and implicit instructional conditions related to the attention paid to examples of the causative had construction in the input texts?
THE STUDY
Context
The data for this study was collected at a state university in Sri Lanka. The student population of the university consists of students from all parts of the country and almost all of them belong to the first language Sinhala or Tamil communities. The university receives the majority of its students from schools where the medium of instruction is Sinhala. In such schools, English is taught as a compulsory subject from Grade 1. Therefore, these students will have learned English for nearly 13 years at school by the time they enter university. The university administers both undergraduate and postgraduate degree courses, and all the courses are run with English as the medium of instruction. In addition, English language is taught as a credit-bearing course at the university for all undergraduate students.
Participants
The participants in this study were 100 first-language Sinhala speakers who were first-year undergraduate students in the bachelor of commerce degree program at the university. Eighty students formed part of the experimental condition and 20 students took part as members of the control group. As we explain in the following text, high-quality eye-tracking data was available for 45 out of the 80 experimental group participants. The control group students did not participate in the eye-tracking phase of the study.
The participants had been attending university for five months when the data collection for this study took place. The participants were 19 to 21 years old, 29 of them were female and 71 male. The participants in this study were either at a B1 or low B2 level of English language proficiency in the Common European Framework of Reference (Council of Europe, 2011) based on scores on the university admission language test. As mentioned in the preceding text, all the participants had experience of learning English for more than 10 years. None of the 100 participants were bilingual speakers of other languages or had learned another foreign language in addition to English.
MATERIALS
Input Texts
Three short stories written by the researchers were used as input texts (see IRIS repository for experimental materials: https://www.iris-database.org/). In order to verify whether the vocabulary used was appropriate for the participants, we checked the texts for lexical complexity by using Vocabprofile (Heatley, Nation, & Coxhead, Reference Heatley, Nation and Coxhead2002). All three texts contained more K1 words (most frequent 1,000 words in English) than K2 words (the second most frequent 1,000 words in English). Text 1 contained a total of 93.56% K1 and K2 words, Text 2 a total of 91.74% of K1 and K2 words, and Text 3 a total of 91.84% of K1 and K2 words. Most of the off-list words in the texts were proper nouns. Because more than 90% of the words in the texts belonged to the K1 and K2 bands, it was assumed that the texts were within the lexical competence of the participants. This lexical analysis also allowed us to control for word-frequency effects that might potentially impact fixation durations and overall reading speed. Each text contained seven examples of the target construction causative had, that is, 21 in total over the three texts. The items for target construction were taken from the British National Corpus to ensure that the main verb in the target construction would be representative of the most frequent verbs used in this construction. The verbs used in the target construction also belonged to the K1 and K2 bands. Slight alterations were made to nouns (e.g., had the tools delivered instead of had the letters delivered) to make the examples compatible with the overall story line. The target items, which consisted of had + article + noun + main verb, contained four to eight syllables.
In order to ensure that the participants had a purpose for reading, each reading text contained four multiple-choice reading comprehension questions that were included after the text. Two of the four comprehension questions for each text were based on general understanding of the text and the other two were aimed at assessing whether the participants understood the meaning of the target construction.
Pretest and Posttest
In the pre- and posttests, two tasks were used so that we could assess both the production and comprehension of the target construction. In the sentence reconstruction (SR) task, the participants had to rewrite given sentences starting with the word(s) provided so that the new sentences meant exactly the same as the given ones. This task, which meant to tap into participants’ explicit knowledge gained in the experiment, contained 20 items in total: six critical items requiring causative had and 14 fillers.
In the grammaticality judgment (GJ) task, which consisted of a total of 40 items, the participants had to decide whether sentences were grammatically correct or incorrect. There were ten target GJ items (five correct and five incorrect) in the pre-/ posttests. The rest were distractor items. The ungrammatical items included two items where the –ed suffix was omitted, three word-order errors, and one instance of the use of the wrong suffix –ing. In order to minimize the effect of sentence length, all target SR items and eight target GJ items contained 10 words each. The remaining two target GJ items consisted of 11 words. The SR task was administered in written mode, whereas the GJ task was presented aurally. For the GJ task the first author, who shared the same first language as the participants, was recorded reading out loud 40 sentences with a five-second interval between each of them. The participants listened to the recording and made their judgments about the correctness of the sentences during these intervals. This procedure ensured that the participants completed the GJ task under some degree of time pressure and that they would primarily rely on their implicit knowledge of the target construction.
The proper nouns and some other nouns in subject or object positions in the SR and GJ items were changed in the posttest to prevent that the participants remember the answers that they provided in the pretest. All the target examples (in the SR and GJ items) used in the pre- and posttests were taken from the British National Corpus; however, the nouns were altered and phrases were added to the sentences in order to maintain the length of sentences across two testing occasions. The reliability of the posttest SR task as measured by Cronbach alpha was 0.681 and that of the posttest GJ task .447. The lower value of for the GJ task might indicate a higher level of guessing.
Procedures
The 100 participants were randomly assigned to five groups of 20 participants each: Groups A, B, C, D, and E. Group E was the control group and the rest were experimental groups. All the participants signed a consent form, filled in a background questionnaire, and took a pretest on the first day of the experiment, that is, five days before the first eye-tracking session. The participants in the experimental groups met with the first author individually three times (every other day) between the pretest and posttest for individual eye-tracking sessions. Immediately after the third eye-tracking session, the participants took a posttest. The control group completed the pretest and posttest only.
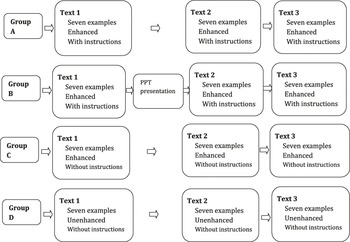
Following the pretest, the four experimental groups were provided with input on the target construction in three consecutive sessions in four different ways (see Figure 2 for an illustration of the experimental design of the study). Group A received enhanced input, and at the beginning of each eye-tracking session, the participants were asked to pay attention to highlighted phrases. Group B was exposed to similar input to that of Group A in the first eye-tracking session. Immediately before the second eye-tracking session, however, the participants in this group viewed a PowerPoint presentation that explained the form and meaning of the target construction in writing. The presentation consisted of six slides and included four examples from Text 1. Thereafter, the participants were exposed to the second input, that is, enhanced text with an instruction asking them to pay attention to highlighted phrases. Input session 3 for Group B was similar to their first input session. Group C received enhanced input, that is, all examples of the target construction were highlighted in bold in the texts that they read. The participants in Group C were not informed that there was a specific target construction highlighted in the text, and they were not asked to pay attention to highlighted phrases. To Group D we administered unenhanced input, that is, examples of the target construction were not highlighted in their texts nor were they told that there was a specific target construction in the texts.
Experimental design.

Eye-Tracking Procedures
For the collection of eye-tracking data, a Tobii X2-60 portable eye-tracker was used. It was connected to a laptop computer and placed in a quiet room. At the beginning of the first session, the participants were informed about the function of the eye-tracker and a trial slide was used to provide them with an overview of the eye-tracking procedure. At the beginning of each reading session, a nine-point calibration was performed. Participants sat approximately 67 centimeters away from the screen.
In preparation for the eye-tracking experiment, the three input texts were placed on PowerPoint slides. After piloting different fonts, font sizes, and spacing, 24-point, double-spaced Calibri was used. This font was selected because it is considered to be suitable for screen display (Erickson, Reference Erickson2013).
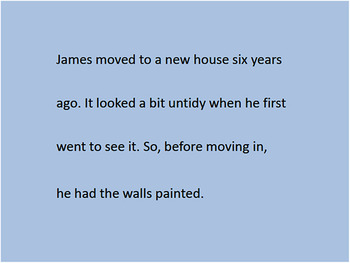
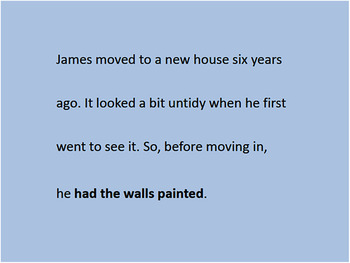
All the words belonging to a particular example of the target structure, that is, AOI (e.g., had the walls painted), were placed on the same line in order to facilitate the measurement of fixation duration on AOIs (see Figure 3 for an example of an unenhanced input slides and Figure 4 for an example of an enhanced input slide). The position of the AOIs within the lines could not be controlled because the targets formed part of a coherent story line. As the targets and the texts were identical in all experimental conditions, variations in the position of AOIs were not expected to influence the findings. Each slide contained four to five double-spaced lines. The PowerPoint slides were transferred to the Tobii eye-tracking software.
Example of the unenhanced input slides.

Example of the enhanced input slides.

In the eye-tracking phase of the study, the participants were told that they were going to read a story on the computer screen. They were informed that they could proceed to the next slide when they finished reading; however, they were not allowed to go back to previous slides. No specific time was allocated for reading, the participants could spend as much time on a slide, reading and rereading the text, as they felt necessary.
DATA ANALYSIS
Analysis of the Eye-Tracking Data
As already mentioned, we used two eye-tracking measurements to infer the amount of attention paid to the target items. First, the TFD of each participant on each AOI was measured and the mean TFD for each participant for all AOIs was calculated. This calculation was done for each text separately and resulted in a measure called the mean TFD. For the second eye-tracking measurement, the TFD for each participant for the text on the whole page was measured. Then, the expected TFD on each AOI was calculated based on the proportion of the number of syllables that the AOI had in relation to the number of syllables on the whole page where the particular AOI occurred. Footnote 1 We used syllables, because Trueswell et al. (Reference Trueswell, Tanenhaus and Garnsey1994) argue that letter-based standardizations are inaccurate. Furthermore, in English there is no one-to-one correspondence between letters and sounds and often letter combinations rather than individual letters denote phonemes. This results in the fact that beyond initial stages of learning to read, not letters but larger grain-sized units such as onsets and rimes and ultimately syllables constitute the basic units of word-level decoding in English (Ziegler & Goswami, Reference Ziegler and Goswami2005).
 $${\rm{Expected\ fixation\ duration\ of\ an\ AOI\ for\ a\ participant}} = {{{\rm{no}}{\rm{.\ of\ syllables\ of\ the\ AOI}}\, \times \,{\rm{TFD - whole\ page}}} \over {{\rm{no}}{\rm{.\ of\ syllables\ of\ the\ whole\ page}}}}$$
Then, the difference between the observed and expected TFD was calculated again for each participant for each AOI.
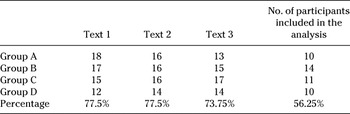
Unfortunately, on each testing occasion approximately 13 to 15% participants’ data had to be discarded because their eye fixations went beyond the screen for a considerable amount of time. As we needed information for all the three text-reading sessions, only those participants whose data were of appropriate quality for all three texts were included in the eye-tracking data analysis for research questions 2 and 3 (see Table 1). This resulted in the loss of data for 35 participants out of the 80 whose eye-tracking measures were taken in the experimental conditions.
Number of participants whose eye-tracking data was of sufficiently good quality in each stage and the overall number of participants included in the eye-tracking data analyses

PRETEST AND POSTTEST RESULTS
In both the SR and GJ tasks, correct answers received one mark and incorrect answers were scored as zero. Half marks were not allocated and spelling mistakes were ignored. The maximum score on the SR task was six points and on the GJ task 10 points. First, the total for both SR and GJ items was computed. Then, the gain score was calculated separately for the SR and GJ target items by calculating the difference between the total score of the posttest and the total score of the pretest.
Statistical Analyses
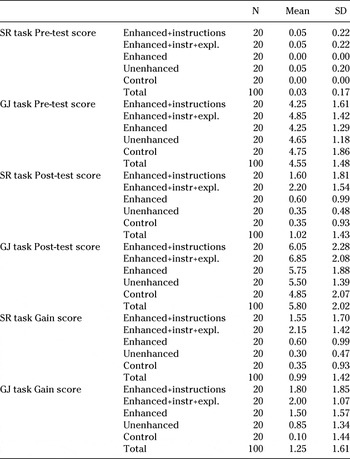
First, the normality of the distribution of all variables was checked by means of a Shapiro-Wilks test. Except for the SR task, all the variables were normally distributed (see Tables 2 and 3 for the descriptive statistics). For the SR task we calculated the standardized residuals and Cook’s distances. The Normal P-P plot of the standardized residuals indicated no deviation from normality and none of the residuals fell outside the +2/-2 range. All Cook’s distance values were well below the critical threshold of 1 (Tabachnick & Fidell, Reference Tabachnick and Fidell2007). Therefore, we decided to use parametric analyses for the study. In order to answer our first research question, we analyzed change in knowledge over time with repeated measures MANOVA. For this analysis data for all participants (N = 100) was included. In the analyses pertaining to our second research question, we compared the eye-tracking measures of the treatment groups by means of one-way analysis of variance. As for the third research question, the relationship between the gain scores and eye-tracking measures was examined with the help of Spearman-rank order correlations. The level of significance was set at p < .05 and in the case of multiple tests Bonferroni correction was applied to adjust the significance level and avoid inflated Type I error. Effect sizes were calculated using partial eta square values. Based on Cohen (Reference Cohen1988), partial eta square values above .06 were taken as indications of medium and above .138 as large effect size.
Descriptive statistics for the sentence reconstruction and grammaticality judgement tasks (N = 100)

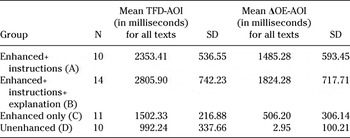
Descriptive statistics of TFD-AOI and ΔOE-AOI for the groups (N = 45)

RESULTS
Changes in Receptive and Productive Knowledge of the Target Syntactic Constructions under Different Input Conditions
In our first research question we asked how knowledge of the form and meaning of the target syntactic construction causative had changes under different input conditions. In order to answer this question, we conducted a repeated measures MANOVA analysis to find out whether there was an improvement in the SR and GJ task scores for the overall study sample, and whether an interaction between the effect of instructional conditions and the rate of improvement in the two tasks could be observed. This was followed by post hoc Scheffe comparisons across the groups to detect where the differences between them lay.
For the SR task, we found a statistically significant increase in the scores from pretest (M = 0.03, SD = 0.17) to posttest (M = 1.02, SD = 1.43), Wilks’s Lambda = 0.57, F(4, 95) = 69.81, p < .001, partial eta squared = .42. The mean increase was .99 with a 95% confidence interval ranging from 0.72 to 1.26. For the GJ items, there was also a statistically significant difference between the total scores of the pretest (M = 4.55, SD = 1.48) and the posttest (M = 5.80, SD = 2.02), Wilks’s Lambda = 0.57, F(4, 95) = 71.17, p < .001, partial eta squared = .42. The mean increase in this task was 1.25 with a 95% confidence interval ranging from .93 to 1.57. The mean values in the pretest SR task indicated no existing knowledge of the target construction, whereas the mean for the GJ task was significantly below the 50% guessing range, t(96) = -3.17, p = .002.
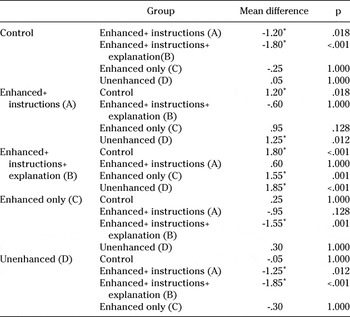
In the case of the SR task, the repeated measures MANOVA analysis showed a significant between-subjects (i.e., treatment) effect with a large effect size, F(4, 95) = 8.22, p < .001, partial eta squared = .25, and a significant interaction between treatment conditions and improvement in this task also with a large effect size, Wilks’s Lambda = 0.71, F(4, 95) = 9.62, p < .001, partial eta squared = .288. A follow-up ANOVA with the gain score as the dependent variable and the post hoc Bonferroni analysis showed that there is a significant mean difference in the gain scores for posttest SR items between the control group and the enhanced+ instructions (A) group (p = .018) and between the control group and the enhanced+ instructions+ explanation (B) group (p < .001). A significant mean difference was also found between the unenhanced (D) group and the enhanced+ instructions (A) group (p = .012) and the enhanced+ instructions+ explanation (B) group (p < .001). Moreover, the enhanced+ instructions+ explanation (B) group showed a significant improvement (p = .001) compared to the enhanced only (C) group (see Table 4).
Between-subject effects in the sentence reconstruction task (N = 100)

* p < .05.
The repeated MANOVA analysis for the GJ task indicated no significant between group effect, Wilks’s Lambda = 0.57, F(4, 95) = 1.28, p = .281, partial eta squared = .051. However, a significant interaction between treatment conditions and improvement over time, Wilks’s Lambda = 0.81, F(4, 95) = 5.48, p = .001, partial eta squared = .188 was found. The comparison of the gain scores of the groups by means of ANOVA and post hoc Bonferroni tests showed that the enhanced+ instructions (A) group (p = .005), the enhanced+ instructions+ explanation (B) group (p = .001), and the enhanced (C) group (p = .036) achieved significantly higher gains than the control group. The pair-wise t-tests comparing the pre- and posttest GJ task scores revealed that the control group, t(19) = 0.30, p = 0.761, did not improve its scores over time. The enhanced (C) group, t(19) = 4.26, p = < 0.001, enhanced+ instructions (A) group, t(19) = 4.34, p < 0.001, and the enhanced+ instructions+ explanation group (B), t(19) = 8.35, p < 0.001, made significant gains. The improvement of the unenhanced (D) group did not reach the level of significance once Bonferroni correction was applied, t(19) = 2.81, p = 0.011.
Attentional Processing under Different Input Conditions
In our study we also aimed to answer the question of whether the attention that participants pay to the target grammatical construction differs under different treatment conditions (see research question 2). First, mean scores for both variables, that is, TFD for all AOIs (TFD) and the difference between the observed and expected TFD for all AOIs (ΔOE), were computed. The descriptive statistics presented in Table 3 show that the enhanced+ instructions+ explanation (B) group had the highest TFD and ΔOE values. This group is followed by the enhanced+ instructions (A) group, while the lowest values were recorded for the participants in the unenhanced (D) group. ΔOE values indicate that the enhanced+ instructions (A), enhanced+ instructions+ explanation (B), and enhanced only (C) groups spent more time than expected gazing at examples of the target construction. The ΔOE value was around zero in the unenhanced (D) group.
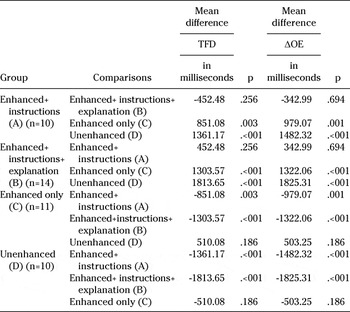
In order to answer our second research question, an ANOVA analysis was conducted to assess the impact of the treatment conditions on the TFD and ΔOE values averaged for the three texts. The type of input was found to have an overall significant effect on TFD, F(3,41) = 27.06, p < .001, partial eta squared = .67, and ΔOE, F(3,41) = 28.42, p < .001, partial eta squared = .68. The effect size can be considered large for both variables. As can be seen in Table 5, the post hoc Scheffe-procedure revealed that there was a significant mean difference in both the TFD and ΔOE values between the enhanced+ instructions (A) group, on the one hand, and the enhanced only (C) and unenhanced (D) groups, on the other. Similarly, the enhanced+ instructions+ explanation (B) group demonstrated significantly higher TFD and ΔOE values than the enhanced only (C) and unenhanced (D) groups. No significant difference could be detected between the enhanced only (C) and unenhanced (D) groups or between the enhanced+ instructions (A) and enhanced+ instructions+ explanation (B) groups, respectively.
Differences in eye-tracking measures across groups (N = 45)

Relationship between Change in Knowledge and Attention Paid to Target Items
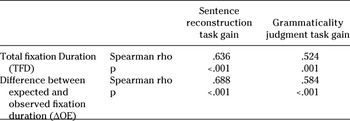
In our study we were also interested in exploring the relationship between the attention paid to the targeted grammatical construction and changes in knowledge in the different instructional conditions (see research question 3). For this purpose, we first computed Spearman rank-order correlations between the eye-tracking measures and the gain scores of the SR items and GJ items for the whole sample. As can be seen in Table 6, there are strong positive correlations between the gain scores of the SR and GJ items and the eye-tracking variables.
Correlations between eye-tracking measures and gain score of the whole sample (N = 45)

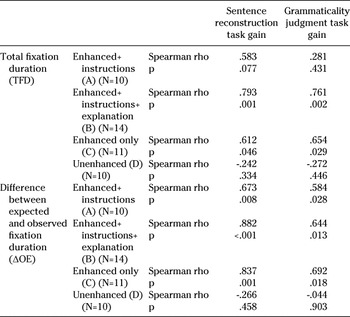
Although the sample size in the experimental groups was relatively small, we computed nonparametric Spearman rho correlations to investigate the relationship between the gain scores and eye-tracking measures in different input conditions (see Table 7). In the unenhanced (D) group, no significant correlations were found, whereas for the other three groups the correlations between gain scores in both tasks and the ΔOE value were all statistically significant and strong. The TFD was also strongly associated with the improvement participants made in both of the tasks in the enhanced+ instructions+ explanation (B) and the enhanced only (C) conditions, but not in the enhanced+ instructions (A) group.
Correlations between eye-tracking data and gain scores in the experimental groups (N = 45)

DISCUSSION
Attentional Processing under Different Input Conditions
In our study we examined how attentional processing of the target grammatical construction causative had varies under four different input conditions (see research question 2). The results of the eye-tracking phase of our study reveal that, under the input flood condition, the participants’ attention did not seem to be drawn to examples of the target construction, and this was apparent in the fluctuations of the observed and expected TFD (ΔOE) around and below the value of zero. This suggests that the participants in this condition may not have performed additional attentional processing of the target examples besides decoding them as part of the text. They might neither have exercised goal-directed top-down control over the allocation of their attention to this feature of the input (Shiffrin, Reference Shiffrin, Atkinson, Herrnstein, Lindzey and Luce1988; Styles, Reference Styles2006) nor did they engage in additional bottom-up attentional processing (Chun et al., Reference Chun, Golomb and Turk-Browne2011).
The attentional processing of the participants in the enhanced-only condition did not seem to differ considerably from that of the participants in the unenhanced condition. These findings align with those of Issa et al. (Reference Issa, Morgan-Short, Villegas, Raney, Roberts, McManus, Vanek and Trenkic2015), but are different from the results obtained by Winke (Reference Winke2013) and Simard and Foucambert (Reference Simard, Foucambert, Bergsleithner, Frota and Yoshioka2013). The reason for this difference might lie in the nature of the enhancement. In our study we highlighted the target items in bold, and in Issa et al.’s (Reference Issa, Morgan-Short, Villegas, Raney, Roberts, McManus, Vanek and Trenkic2015) study different color font was used. Winke (Reference Winke2013) and Simard and Foucambert (Reference Simard, Foucambert, Bergsleithner, Frota and Yoshioka2013) enhanced the text by underlining. Underlining might have been more effective in creating an isolation effect (Reference von Restorffvon Restorff, 1933), and consequently it might have more successfully drawn learners’ attention to the target items than boldfacing or different color fonts. This indicates that boldfacing as a form of TE in this experimental condition was not successful in inducing additional attentional processing. It is also possible that the externally induced salience in our study might not have corresponded with learners’ internally generated salience (Sharwood Smith, Reference Sharwood Smith1991, Reference Sharwood Smith1993). Furthermore, Lavie, Hirst, De Fockert, and Viding’s (Reference Lavie, Hirst, De Fockert and Viding2004) research in the field of cognitive psychology also suggests that increasing perceptual load, such as the visual enhancement of a section of text, results in early exclusion of the stimulus from further cognitive processing unless the stimulus is deemed to be relevant to the task. It can thus be hypothesized that the participants in the TE condition did not consider the visually enhanced constructions essential for comprehension of the text, and consequently did not engage in subsequent active attentional processing.
Based on the results of our study, one of the most effective experimental manipulations in our study seems to be the instruction to pay attention to the grammatical construction embedded in the text. Explicit rule presentation can provide an additional boost to the learning process, which is attested to by the facts that the enhanced+ instructions+ explanation (B) group demonstrated the highest level of correlations between eye-tracking measures and learning gains and the largest improvement in the SR task. Wickens’s (Reference Wickens, Kramer, Wiegmann and Kirlik2007) SEEV (salience effort expectancy value) model of attention can offer a possible explanation for these results. Wickens argues that four factors are important in determining what aspects of incoming stimuli one attends to: salience, effort, expectancy, and value. The model predicts that when different pieces of information compete for attentional resources, information will be heeded that is salient, requires less effort to process, is expected in a given situation, and has high value in terms of the task to be solved. It can be hypothesized that by informing learners that a novel grammatical construction is embedded in the text, the expectancy value of the targeted structure was increased, and concomitantly its salience became relevant to the task at hand. Therefore, in the two experimental conditions where participants were asked to pay attention to the specific construction in the input, the participants can be assumed to have exercised both top-down attention control to search for the relevant feature in the input text and bottom-up control to select the necessary information among other stimuli (Chun et al., Reference Chun, Golomb and Turk-Browne2011; Koch & Tsuchiya, Reference Koch and Tsuchiya2006).
ATTENTION AND PERFORMANCE
In our research we also aimed to answer the questions of how L2 learners’ knowledge of the targeted syntactic construction causative had changes under different input conditions and how these changes in knowledge are related to the amount of attention paid to the target construction (see research questions 1 and 3). With regard to the changes in participants’ performance in the SR task, the findings mirror those obtained when we examined differences in the eye-fixation measures. The main difference in learning gains seems to lie between the explicit FonF conditions (enhanced+ instruction and enhanced+ instructions+ explanation) and the implicit FonF treatments (input flood and input enhancement), with the two explicit FonF groups making significantly greater improvements in the posttest than the other groups. The mean value of the change in scores is higher than 1.5 points for these groups for both tests, which signals more than 25% improvement in the SR task and 15% in the GJ task. Our findings also reveal that, in the SR task, the two implicit FonF groups did not score significantly higher than the control group that received no exposure to the target construction at all. In the GJ task, the effect size for the treatment was small and the post hoc procedures did not show significant group differences in learning gains.
The different pattern of improvement in the two tasks might be explained by making reference to the kind of knowledge and conditions under which this knowledge had to be applied in these tasks. Although the SR task required participants to use their knowledge of the target construction productively, it was not performed under time pressure. This might have allowed learners to apply their explicit knowledge of the target construction (N. Ellis, Reference Ellis2005). The GJ task, which was presented to the participants in auditory mode, was carried out under some degree of time pressure. It is still a matter of debate whether a GJ task performed under time pressure assesses L2 learners’ explicit or implicit knowledge (e.g., R. Ellis, Reference Ellis2005; Gutiérrez, Reference Gutiérrez2013; Zhang, Reference Zhang2014). Nevertheless, recent evidence from an eye-tracking study by Godfroid et al. (Reference Godfroid, Loewen, Jung, Park, Gass and Ellis2015) seems to suggest that, under timed conditions, L2 learners tend to apply their implicit knowledge. Taking this together with Bialystok’s (Reference Bialystok1979) finding that, under auditory conditions, a GJ task encourages learners to rely on their implicit knowledge, we can hypothesize that, in our study, the participants primarily used implicit knowledge when making their GJ. Based on this reasoning, it can be assumed that our experimental manipulations were more effective in developing explicit knowledge representations than participants’ implicit knowledge. Another possible explanation is that learners need more time for implicit knowledge to develop, and our study was not conducted on a timescale that would have allowed for this development.
The results of our study with regard to the differential effect of explicit and implicit learning conditions are in line with the outcomes of Spada and Tomita’s (Reference Spada and Tomita2010) and Goo et al.’s (Reference Goo, Grañena, Yilmaz, Novella and Rebuschat2015) meta-analysis, which showed that explicit FonF conditions have a greater impact on L2 development than implicit ones. Both an instruction to pay attention to a specific grammatical construction, which is similar to the rule-search condition in Robinson’s (Reference Robinson1997) study, and explicit metalinguistic explanation resulted in a significantly larger improvement in the SR task than input flood and input enhancement. As shown in the preceding text, both of these input conditions were seen to be effective means of directing L2 learners’ attention to the target feature, and this increased attentional processing was also strongly associated with learning gains in the SR task. The findings with regard to the differential effects of the explicit and implicit FonF techniques seem to lend support to the argument that minimally guided instruction, such as input flood and TE, might not be beneficial if learners do not have previous familiarity with the target construction (Jahan & Kormos, Reference Jahan and Kormos2015).
The results of the correlational analyses point to a strong relationship between the eye-tracking variables and the learning gains made by our participants. The correlations are particularly high in the case of the ΔOE measures and the improvement in the SR task. In line with our hypothesis that the difference between the observed and expected eye-fixation duration would be reflective of additional attentional processing, this value accounts for a somewhat larger proportion of variance in gain scores than the TFD value. As already argued, the increased fixation duration and the difference between the observed and expected eye-fixation durations can be seen as indications of top-down and bottom-up attention control processes (Chun et al., Reference Chun, Golomb and Turk-Browne2011; Koch & Tsuchiya, Reference Koch and Tsuchiya2006). Attentional processing of the target construction is very strongly related to learning gains, especially in the SR task, which assessed the establishment of explicit knowledge representations.
CONCLUSION
The study presented in this article demonstrates that learning gains on a target L2 grammatical construction are very strongly associated with the attention learners pay to it in the input. Using eye-tracking methodology, we have also shown that explicit FonF techniques, most importantly the instruction to pay attention to a grammatical structure in the text, seem to be more efficient in directing learners’ attention to the targeted construction than implicit FonF techniques. An important pedagogical implication of our study is that if learners are given limited support in what to pay attention to in the input, their attentional processes may not be directed to the target feature even if there are abundant examples of it in the text or if they are visually enhanced.
In our article we also make a theoretical contribution by clearly delineating the differences between attention, consciousness, and awareness based on literature in the field of cognitive psychology. In addition, we devised a new eye-tracking measure, the difference between observed and expected eye-fixation durations, which we assume operationalizes selective attention better than the total eye-fixation duration value. In our study, the calculations of expected and observed values are based on word length measured in syllables, but this operationalization can be refined further to take various lexical characteristics into account, such as word frequency, concreteness, and imageability, that potentially influence how long a word is fixated on (Reichle et al., Reference Reichle, Pollatsek and Rayner2006).
Our study is not without limitations, one of the most important of which is the fact that a large portion of participants’ eye-tracking data had to be excluded from the analyses. This was partly because a portable eye-tracker was used to access a sufficiently large number of participants from a homogenous language learning background and because measurements were taken at three occasions. In future studies, more sensitive equipment and a larger number of learners will be needed to gain more nuanced insights into differences in attentional processing under different experimental conditions and to examine the relationship between eye-tracking measures and learning gains. Due to data collection constraints, no delayed posttests could be administered, and hence we have little knowledge about how enduring the learning gains were. Although we originally administered a productive test that would have required the participants to apply the target grammatical construction in a meaningful context in a written text, so few learners actually used the construction that the analysis of these data was not possible. Therefore, in future studies, other means for eliciting the productive use of the target construction will be needed. Furthermore, in our study we could only hypothesize about the kind of knowledge our test-tasks assessed. Using confidence ratings or tracking the eye movements of the participants while performing a GJ task might yield more reliable information about whether learners rely on explicit or implicit knowledge in this task. Finally, our study involved only brief and short-term treatment sessions that might have constrained the gains students made under the implicit learning conditions.