Introduction
Consumers purchasing gambling and alcohol products receive similar advice. ‘Please gamble responsibly’ is seen perhaps as frequently as advice to ‘please drink responsibly’. But how should this advice be followed? With alcohol, the familiar alcohol by volume percentage (ABV%) tells consumers about product strength, and this information is further broken down into the number of units of alcohol per serving on the majority of alcohol sold in the UK (Portman Group, 2017). In gambling, a similar percentage determines product strength in terms of statistical risk, but this advice is given to consumers more inconsistently. Electronic gambling machines represent one UK gambling product that comes with product risk information, where by law statistical risks are presented as (Parke et al., Reference Parke, Parke and Blaszczynski2016):
 $${\hbox '}{\rm return}{\hbox -}{\rm to}{\hbox -}{\rm player}{\hbox ' }\% = {\rm 100} \; \ndash \; {\rm house \; edge}$$
And the return-to-player percentage is described in practice as, for example, ‘This game has an average percentage payout of 97.3%’. The return-to-player corresponds to the long-run proportion of every £100 wagered that gets returned to gamblers as prize money. The gambling operator keeps the remainder as the ‘house edge’. House edge will be used here in contrast to return-to-player, as a higher house edge represents a higher average risk (Woolley et al., Reference Woolley, Livingstone, Harrigan and Rintoul2013), mirroring the risks of high-ABV% alcohol. In European roulette, for example, the house edge on all bets is 2.7% (return-to-player of 97.3%), and this forms the basis for many roulette-based electronic gambling machine games. Qualitative research suggests that many regular gamblers fail to see UK electronic gambling machine return-to-player warning labels (Collins et al., Reference Collins, Green, d'Ardenne, Wardle and Williams2014), and that some gamblers do not understand the return-to-player percentage (Collins et al., Reference Collins, Green, d'Ardenne, Wardle and Williams2014; Harrigan et al., Reference Harrigan, Brown and Barton2017; Rowe et al., Reference Rowe, De Ionno, Holland, Flude, Brodrick, Vinay and Moutos2017). Despite these current failings, evidence from the behavioural risk communication literature suggests that this information could be communicated to more people through the use of graphical risk representations (Garcia-Retamero & Cokely, Reference Garcia-Retamero and Cokely2017), while the tobacco literature suggests that making these warning labels more prominent should also boost effectiveness (Hammond, Reference Hammond2011) . But despite these significant failings, many UK gambling products are marketed with even less product risk information than is currently given on return-to-player warning labels.
Soccer is the UK's national sport, and soccer betting is now the most popular form of gambling with British problem gamblers (Gambleaware, 2017). The most common advice featuring on soccer bets, either at point of purchase or on marketing communications, is currently the generic, ‘When the fun stops, stop’. Absolutely no advice is given on relative product risk, even as these risks may vary substantially, in contrast to return-to-player or ABV% labels. When consumers see a soccer bet, either in a physical bookmaker, on a bookmaker's website or in a marketing communication, they typically receive only one piece of risk information: the betting odds. For example, a bet on the correct score in soccer such as ‘Arsenal to win by three goals to one, 25-to-1’ means that gamblers will win £25 of profit for every £1 bet if the team Arsenal wins by three goals to one (Cortis, Reference Cortis2015). But each potential payout must be multiplied by its probability of happening in order to calculate a gambler's long-term returns. In European roulette, potential payout and event probability happen to be perfectly negatively correlated, so that the house edge is a constant 2.7%. Some psychologists have recently proposed that payout and probability are in fact negatively correlated in many real-world environments, resulting in roughly constant average expected returns (Pleskac & Hertwig, Reference Pleskac and Hertwig2014). However, as we show next, the house edge can fluctuate wildly across different bet types in soccer betting.
Bookmakers rarely share past betting data with researchers (Chagas & Gomes, Reference Chagas and Gomes2017). But the average house edge can be estimated indirectly in sports betting, based on bookmakers’ odds (Cortis, Reference Cortis2015), under the assumption that bookmakers offset the risks of different bets (Stark & Cortis, Reference Stark and Cortis2017). Each soccer match ends in one of three salient outcomes: home win, draw or away win. Bets on these outcomes are the oldest bets that can be made in soccer (Forrest, Reference Forrest, Hausch and Ziemba2008) and will be called ‘home–draw–away’ bets here. These events are high-profile and are relatively few, so it should be easy for gamblers to shop around and find the bookmaker with the best home–draw–away odds, especially with odds comparison sites such as oddschecker.com. In addition, the house edge on home–draw–away bets has decreased in recent years (Constantinou & Fenton, Reference Constantinou and Fenton2013; Buhagiar et al., Reference Buhagiar, Cortis and Newall2018). For example, a study found home–draw–away edges of 4.5% on average over the 2014 World Cup (Newall, Reference Newall2015), compared to an average house edge of 10.3% in data from the 1990s (Kuypers, Reference Kuypers2000). But bookmakers are increasingly innovating new bet types (Newall, Reference Newall2015, Reference Newall2017; Newall et al., Reference Newall, Thobhani, Walasek and Meyer2018). Correct score bets, for example, pay off if a gambler can predict the more specific final scoreline. The same 2014 World Cup study found a far higher house edge of 21.9% on correct score bets (Newall, Reference Newall2015), which is proportionally not much lower than the 26% house edge found on correct score bets from a study in the 1990s (Dixon & Pope, Reference Dixon and Pope2004). The house edge in soccer depends a lot on the type of bet chosen and can be more than eight times the 2.7% European roulette house edge on a per-bet basis. This is important for gamblers, as a lower house edge allows gamblers to benefit from a lower ‘price’ of gambling, and thereby to be able to afford a higher number of gambling experiences from some fixed budget allocated for gambling (Woolley et al., Reference Woolley, Livingstone, Harrigan and Rintoul2013).
Perhaps one of the unique attractions of sports betting is that ‘skilful’ bettors can beat these average house edges (Kaunitz et al., Reference Kaunitz, Zhong and Kreiner2017). Sports betting is a skill-based form of gambling, whereas roulette is luck-based as there is nothing that can be legally done to beat the 2.7% house edge (Thorp, Reference Thorp1998). The reality, however, is that many sports fans are not especially skilled at predicting sports outcomes. Sports fans are overconfident, even when the financial stakes are high (Simmons & Massey, Reference Simmons and Massey2012), and they are subject to wishful thinking (Babad, Reference Babad1987). In addition, soccer experts are not necessarily better than non-experts at predicting outcomes (Andersson et al., Reference Andersson, Edman and Ekman2005, Reference Andersson, Memmert and Popowicz2009). Prediction skill means that soccer bettors can plausibly receive returns that are both better and worse than the averages summarised in the previous paragraph. This paper will therefore use machine learning to investigate the total potential impact of prediction skill across four soccer betting types. Although it could be difficult to directly make sports bettors more skilful, it might be easier to alert sports bettors to observable product features, such as the level of betting odds, which are correlated with product risk. For example, with alcohol, it is reasonable to guess that the ABV% of a bottle of whiskey is higher than that of a bottle of wine, which is higher than that of a bottle of beer. Any salient attribute of sports bets that is correlated with the returns that gamblers receive could similarly be used to communicate product risk non-numerically.
Risks are relatively easy to estimate in electronic machine gambling, where the chance of each outcome is predetermined. This makes the house edge fixed and the winning probabilities and payoffs for gamblers easy to calculate via probability theory and Monte Carlo simulation. It is harder to calculate event probabilities in sports betting, where each match is unique and the outcomes are governed partly by chance and partly by skill (Hill, Reference Hill1974). This is one potential reason for the inconsistent labelling of product risk on UK gambling products. But consider what could happen if a gambler sees a warning label on an electronic gambling machine, but not on a soccer bet. It is possible the gambler might assume that the unlabelled soccer bet poses less risk, while actually, soccer bets can be over eight times riskier on a per-bet basis. But while it is harder to calculate product risk for sports bets, the variable nature of sports betting risks also provides a unique opportunity to reduce the harms associated with sports betting.
Gambling-related harm increases as gamblers’ total losses increase (Markham et al., Reference Markham, Young and Doran2014, Reference Markham, Young and Doran2016). But gamblers’ losses are not fixed in sports betting, and they depend on the relative skill levels across gamblers and bookmakers. At present, British bookmakers are creating soccer bets with ever-increasing potential payoffs, which is the only piece of risk information currently communicated to gamblers (Newall, Reference Newall2015, Reference Newall2017; Newall et al., Reference Newall, Thobhani, Walasek and Meyer2018). This matters because these high-potential-payoff bets have higher house edges than traditional home–draw–away bets. But changing the behaviour of even a small number of gamblers, such as by making them more aware of how potential payoff combines with event probability to determine the house edge, could incentivise bookmakers to compete on ‘price’ – the house edge (Woolley et al., Reference Woolley, Livingstone, Harrigan and Rintoul2013). House edges have decreased for home–draw–away bets since the late 1990s (Kuypers, Reference Kuypers2000; Constantinou & Fenton, Reference Constantinou and Fenton2013; Buhagiar et al., Reference Buhagiar, Cortis and Newall2018), demonstrating that bookmakers can compete on price. Any decreases in the house edge mean then even gamblers who do not change their behaviour in any way can also benefit from resulting decreases in their gambling losses.
Gambling-related harm is seen as a public health problem by many researchers (Korn & Shaffer, Reference Korn and Shaffer1999; Livingstone & Woolley, Reference Livingstone and Woolley2007; Orford, Reference Orford2010; Markham & Young, Reference Markham and Young2015; Lopez-Gonzalez et al., Reference Lopez-Gonzalez, Estévez and Griffiths2017). Any intervention to reduce gambling's public health costs must consider the trade-off between individual freedom and protecting vulnerable consumers. At one end of the trade-off spectrum is the freedom-preserving choice to ‘do nothing’, while stronger interventions such as ‘change the default’ and ‘use tax incentives’ lie increasingly towards the other end (Nuffield Council on Bioethics, 2007). Providing information on product risk, such as via warning labels, is the first and most freedom-preserving public health intervention on this spectrum. We have used the examples of alcohol and electronic gambling machine warning labels to highlight an omission of product risk information for sports bets. However, any new warning label should be trialled experimentally and in field trials before being rolled out at a population level to ensure consumer understanding and to mitigate the risk of any behavioural backfiring (Stibe & Cugelman, Reference Stibe, Cugelman, Meschtscherjakov, De Ruyter, Fuchsberger, Murer and Tscheligi2016). Any gambling warning label should also ideally leverage insights from the behavioural risk communication literature (Garcia-Retamero & Cokely, Reference Garcia-Retamero and Cokely2017), which current UK electronic gambling machine labels do not (Collins et al., Reference Collins, Green, d'Ardenne, Wardle and Williams2014; Rowe et al., Reference Rowe, De Ionno, Holland, Flude, Brodrick, Vinay and Moutos2017). In addition, if warning labels are not effective at protecting consumers, then stronger public health interventions should also be considered (Nuffield Council on Bioethics, 2007). These are all important goals for future research. This paper tackles a more fundamental issue in soccer betting: risks must be understood before they can be communicated.
This paper will use machine learning to investigate how product risk varies across the largest dataset of past betting odds and results available to us. The aim is to uncover information relevant to the concept of ‘responsible gambling’: “If gambling is to be conceptualized as a leisure activity to be engaged in as an individual choice … then it is fundamental that the individual is presented with all relevant information, in a timely fashion, in order to make an informed choice” (Parke et al., Reference Parke, Harris, Parke, Rigbye and Blaszczynski2015, p. 31). This will be operationalised through three research questions:
RQ1 What is the variation in prediction skill across four key soccer bet types?
Prediction skill matters to the extent that some gamblers can achieve better returns than others. Our machine learning model will make bets across different soccer matches and bet types. We have data for home–draw–away, correct score and two other bet types (explained in the ‘Data’ section below). The model will do this with three strategies in order to mimic the variability across human sports bettors. Model performance will then be compared across bet types and strategies using the strategies’ arithmetic average returns for comparison. If a gambler approaches a given bet type with a given strategy, this percentage gives the amount of staked money lost on average per bet.
Some human sports bettors try to get the highest return possible by inspecting recent performance and developing knowledge about the sport. This strategy will be mimicked by a strategy we call ‘Most-skilled’. The existence of skill can be demonstrated via showing an improvement in performance over a strategy that requires no skill (or knowledge). Therefore, to check the validity of our machine learning model, a second strategy called ‘Random’ will be generated. For RQ1, Random places a bet on every available outcome within a bet type. For RQ1, this generates more precise estimates of what a truly random betting strategy will return than just selecting one bet at random. It should be the case that the Most-skilled strategy yields higher returns than Random. However, if it is possible to beat a random strategy, then it is also possible to do worse than a random strategy. But there should be limits to how bad a strategy can do, as even the most unlikely events do eventually happen in sports betting (such as Leicester FC winning the 2015/2016 English Premier League). Our machine learning model will mimic the worst returns a human might get via the ‘Least-skilled’ strategy. For RQ1, we hypothesise that the returns will be distributed within each bet type as: Most-skilled > Random > Least-skilled. Prediction skill likely matters more for some bet types than others, and this will also be investigated in RQ1.
RQ2 A gambler starts with £100 and bets 10% of their ‘bankroll’ on each game. How long will their stake take on average to fall to £50 (the ‘half-life’)?
RQ1 provides the best estimates of the returns from placing a single bet under the three strategies previously discussed. But many gamblers place sequences of bets from a given starting amount of dedicated gambling money, called a ‘bankroll’. Average arithmetic returns provide an incomplete picture for such sequences of gambles (Chen & Ankenman, Reference Chen and Ankenman2006). RQ2 attempts to mirror the returns of the three strategies (Most-skilled, Random and Least-skilled), as measured by the number of bets before half an initial amount of money is lost, on average. This should provide a more accurate measure of what repeat gamblers could experience. This research question is motivated by the statistical concept of the ‘gambler's ruin’, which shows how a gambler with negative expected returns will eventually lose all of their money (Mohan, Reference Mohan1955; Harik et al., Reference Harik, Cantú-Paz, Goldberg and Miller1999). The 10% proportion was chosen heuristically by us, in the absence of us having any human betting data to compare against (Chagas & Gomes, Reference Chagas and Gomes2017). Larger-percentage bet sizes can compress the differences between betting strategies; for example, with a bet of 50%, one losing bet hits the ‘half-life’ definition. Smaller bet sizes can do the opposite, as gamblers’ bankrolls asymptote towards lasting forever.
As with RQ1, it should be the case that, within each bet type, the strategies have half-lives of: Most-skilled > Random > Least-skilled. For RQ2, Random involves randomly picking one bet per bet type. This is because betting on every outcome, as in RQ1, creates a portfolio of offsetting bets that loses a small amount of money with certainty, due to the house edge, leading to an artificial boost in the bankroll half-life (and no gambler would enjoy losing a small amount of money with certainty). RQ2 therefore investigates how gamblers’ bankrolls evolve across different betting strategies and bet types.
RQ3 Which specific outcomes within each bet type do the Most-skilled and Least-skilled prediction strategies tend to choose?
Machine learning should ideally provide insights to help human decision-makers. Humans often overestimate the likelihood of low-probability events (Kahneman & Tversky, Reference Kahneman and Tversky1979). This tendency has been reflected in sports betting via the ‘favourite–longshot’ bias, where longshots with low winning chances yield higher than average losses for gamblers than bets on favourites (Vaughan Williams, Reference Vaughan Williams1999). The favourite–longshot bias has been observed in large-dataset investigations of home–draw–away soccer odds (Constantinou & Fenton, Reference Constantinou and Fenton2013; Buhagiar et al., Reference Buhagiar, Cortis and Newall2018). Ideally, the Least-skilled strategy will look like a biased human sports bettor, while the Most-skilled strategy will bet differently. Looking at recurring features of the specific bets chosen by the Most-skilled and Least-skilled strategies could also help inform strategies intended to educate gamblers about observable bet attributes that are correlated with product risk.
Model
Machine learning models come in varying degrees of complexity. Innovations in machine learning research often focus on new techniques for processing large amounts of data. Our intention with this paper was not to innovate new machine learning techniques, but to apply established prediction models from the operations research literature to the topic of responsible gambling. Better machine learning models will always be possible. However, any improvement in prediction should not necessarily bias our estimates of different betting strategies’ relative risks. Our key innovations are to consider the total impact of skill via comparing the Most-skilled and Least-skilled strategies and to use the most extensive, freely available dataset of soccer betting odds (four bet types over eight seasons). We encourage other researchers to attempt to replicate these results with different datasets and models.
Data
We wanted to train the model on as many bet types as possible, given the ever-increasing number of ways to bet on soccer. However, long-running, freely available datasets were required, limiting the number of bet types that could be studied. Historical odds were available for the following four betting types: correct score, home–draw–away, over/under and Asian handicap. Data for eight seasons of English Premier League soccer (the highest English club competition) betting odds and results from 2010/2011–2017/2018 were taken from oddsportal.com.
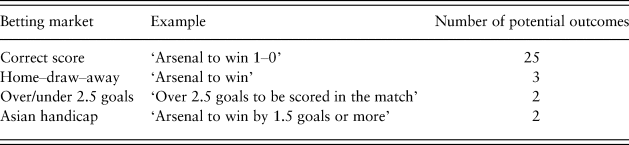
Summary information is provided in Table 1. Of the four bet types, correct score bets stand out as an outlier in Table 1 with 25 potential outcomes. Although there is in theory no limit on the number of goals scored by both teams in a soccer match, reliable data were available only on the 24 most common scorelines. All other potential scorelines were included as a 25th catch-all outcome in the model. Home–draw–away bets have three potential outcomes (home win, draw and away win). The over/under is a bet on the number of goals scored: to be either between zero and two goals or to be three or more goals (two potential outcomes). The Asian handicap performs a skill adjustment on the two teams, effectively removing the potential of a draw (e.g., Arsenal to win by 1.5 goals or more, therefore giving two potential outcomes).Footnote 1 ‘Complex’ bet types with many potential outcomes, such as correct score bets, have previously been associated with high house edges (Ayton, Reference Ayton1997) and an overestimation by soccer fans of average event probability (Newall, Reference Newall2017).
Example of betting odds data

Note: Although there is potentially an infinite number of potential correct scores, reliable betting odds were only available for the 24 most-likely scorelines. Therefore, we include these 24 scorelines (either team scoring up to four goals, excluding 4–4) while adding a 25th catch-all outcome for any other scoreline.
The model was also given in-game statistics of recent team performance (explained at greater length in the ‘Inputs’ section below). These data were downloaded from football-data.co.uk.
Model specifications
Machine learning models approach new datasets like a cautious gambler, learning patterns between current data and future outcomes before making any predictions (the learning phase). The first three seasons were solely used to learn from the data.Footnote 2 Prediction quality on these learned associations was then assessed only in a new, unseen part of the data (the prediction phase). From the fourth season on, the model strategies placed (simulated) bets and received hypothetical returns. Because old data become gradually less informative, each season of prediction was based only on the previous three seasons of learning.
An emphasis on predicting new data is a hallmark of the machine learning approach to statistical testing. Less emphasis is placed on interpreting p-values, as in traditional null hypothesis statistical testing. The main check on model validity is that the Most-skilled and Least-skilled model strategies should respectively perform better and worse than Random in the prediction phase. Some researchers have argued that the social sciences could benefit from placing greater emphasis on predicting new data and less on explaining past data, as is currently done via null hypothesis statistical testing (Yarkoni & Westfall, Reference Yarkoni and Westfall2017).
Prediction-phase performance was available for five seasons in total: 2013/2014–2017/2018. Prior to running any analyses, a decision was made to discard the first five games of each season due to potentially large between-season variations in team performance. This leaves a total sample size of 1650 matches to compare model performance on (330 matches per season). Each prediction is based on 990 learning-phase observations (three seasons). The required number of learning-phase observations to obtain 95% statistical power is 380 for the low-complexity bet types (home–draw–away, over/under 2.5 goals and Asian handicap) and 950 for the high-complexity correct score bet type (Hsieh et al., Reference Hsieh, Bloch and Larsen1998).
Appropriate machine learning model choice depends on the underlying data's statistical properties. Some soccer forecasting models were developed for individual matches, which is typically accounted for by multinomial logistic regression models, given the three main outcomes of a soccer match (e.g., Koning, Reference Koning2000; Willoughby, Reference Willoughby2002; Khazaal et al., Reference Khazaal, Chatton, Billieux, Bizzini, Monney, Fresard, Thorens, Bondolfi, El-Guebaly and Zullino2012). But the present model also forecasts bet outcomes, which depend on the specific teams’ characteristics, where a conditional logistic regression is more appropriate (Smith et al., Reference Smith, Paton and Vaughan Williams2009). Each of these features needs to be accounted for separately. Therefore, we used a combination of multinomial and conditional (mixed) logistic regression to capture the full scope of the data (McFadden, Reference McFadden and Zarembka1974; McFadden & Train, Reference McFadden and Train2000; Lessmann et al., Reference Lessmann, Sung, Johnson and Ma2012).
Inputs
The machine learning model, like an expert gambler, learns associations between publicly available information (predictors) and soccer outcomes. Given the applied nature of our research questions, our aim was not to test the predictive power of previously unexplored inputs, but to only use inputs established in the previous literature to have positive predictive performance. While better models could always be designed, our relatively simple approach should not necessarily bias our estimates of different betting strategies’ relative risks. It might seem that adding more inputs should boost predictive power. However, adding more inputs can increase the risk of ‘overfitting’, where chance random associations are discovered and erroneously predicted to recur in the prediction phase, hence leading to poor prediction-phase performance (Yarkoni & Westfall, Reference Yarkoni and Westfall2017).
Our first model input was an average of relevant match betting odds, using an average of around 30 bookmakers per data point. Betting odds have been shown to successfully predict outcomes in the soccer forecasting literature (Goddard & Asimakopoulos, Reference Goddard and Asimakopoulos2004; Štrumbelj & Šikonja, Reference Štrumbelj and Šikonja2010; Štrumbelj, Reference Štrumbelj2014). Betting odds tend to fare even better than other prediction methods, such as Elo rating systems, which were originally designed for chess ratings (Hvattum & Arntzen, Reference Hvattum and Arntzen2010; Leitner et al., Reference Leitner, Zeileis and Hornik2010). As is the standard in the literature, these odds were averaged to reduce random forecast error, and they were normalised to remove the effect of the house edgeFootnote 3 (Hvattum & Arntzen, Reference Hvattum and Arntzen2010; Leitner et al., Reference Leitner, Zeileis and Hornik2010).
Gamblers will often factor in recent performance. Therefore, the model was provided with in-game statistics summarising each team's performance over the previous five matches. Based on successful in-game predictors from the previous literature, we chose the cumulative number of points earned – three for a win, one for a draw and zero for a loss (Goddard & Asimakopoulos, Reference Goddard and Asimakopoulos2004; Goddard, Reference Goddard2005) – and the number of goals scored and conceded (Dixon & Robinson, Reference Dixon and Robinson1998; Oberstone, Reference Oberstone2009; Baio & Blangiardo, Reference Baio and Blangiardo2010; Angelini & De Angelis, Reference Angelini and De Angelis2017). Predictors that have been used in the previous literature but were not included here include the number of corners won (Andersson et al., Reference Andersson, Memmert and Popowicz2009), shots on target (Oberstone, Reference Oberstone2009), recent injuries (Constantinou & Fenton, Reference Constantinou and & Fenton2017) and disciplinary bookings (Titman et al., Reference Titman, Costain, Ridall and Gregory2015).
We combined the estimate of the likelihood of each event happening from the machine learning model with the potential payoff size to create an estimate of the expected return from each bet with different strategies. The Most-skilled strategy chose the bet with the highest long-run expected return within each bet type for each match, while the Least-skilled strategy chose the bet with the lowest long-run expected return.
Results
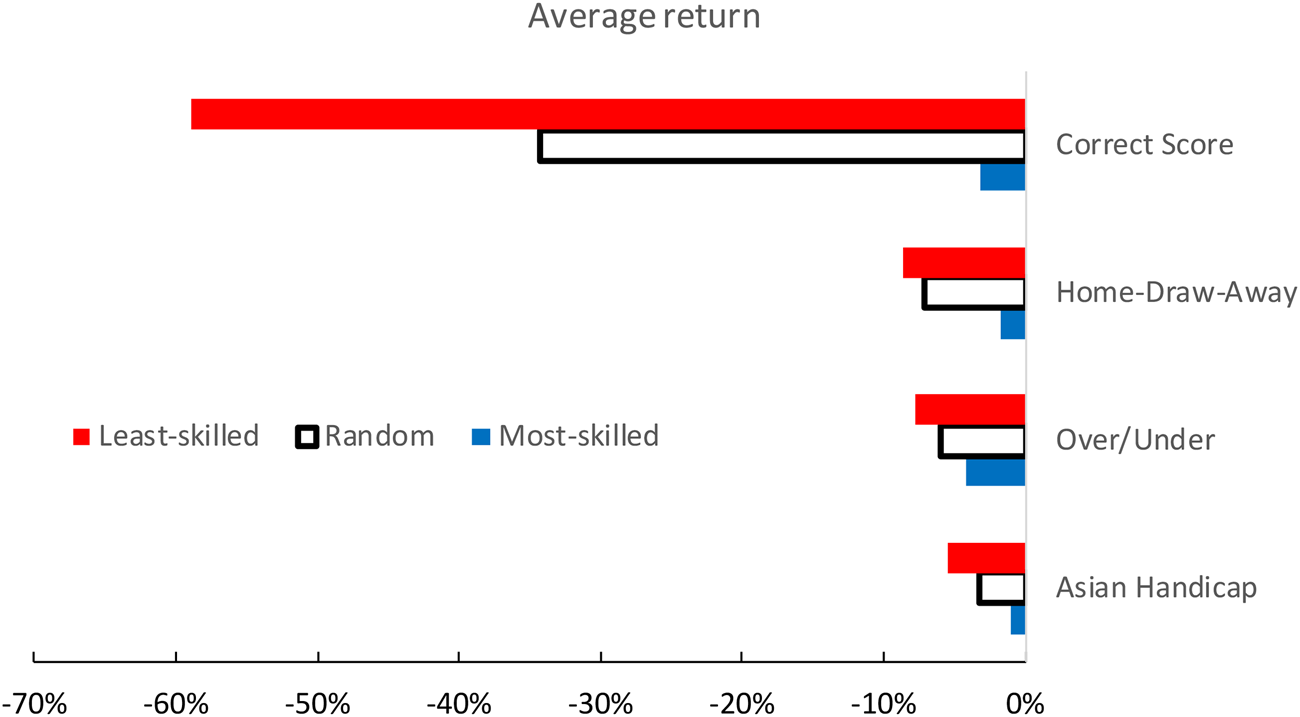
In response to RQ1, the arithmetic average percentage returns varied over both the four bet types and the three betting strategies used, as summarised in Figure 1. Figure 1 presents the results of different hypothetical bettors, so it is more accurate to present the returns as experienced by each betting strategy, rather than as the bookmaker's overall house edge. The negative returns experienced by each strategy in Figure 1 can be interpreted as showing that predictions were never able to overcome the bookmaker's house edge. A return of –3.3% is equivalent to a house edge of 3.3%, or equivalently a return-to-player of 96.7%. In each bet type, it can be seen that the Most-skilled prediction performed best, the Least-skilled strategy performed worst and Random was in the middle. Therefore, in each bet type, (positive) betting skill improved performance, while (negative) betting skill worsened performance. Prediction skill mattered most in with correct score bets. With correct score bets, the Least-skilled strategy returned –58.9% on average, Random –34.3% and the Most-skilled strategy –3.3% (returns as experienced by the model). No other betting strategy experienced returns worse than –10% per bet (even the Least-skilled strategies). Additionally, in the other three bet types, the per-bet difference in returns across the three betting strategies was 7% or under. Prediction skill always mattered, but especially with correct score bets (where there were many potential outcomes).
Prediction skill variability over each bet type and strategy

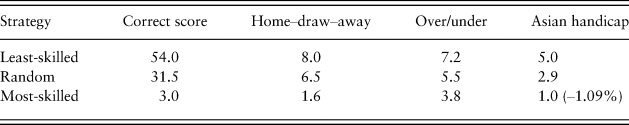
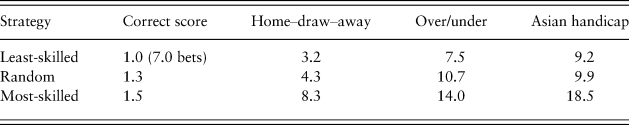
Next, we investigated the variation in relative betting performance. Comparing the relative losses can indicate the potential magnitude of savings a gambler could make by shifting towards lower-‘price’ bets. Table 2 shows each loss as a multiple of the lowest-loss performance, which was Most-skilled Asian handicap, at –1.1%. The variation in relative performance was large. The Least-skilled correct score strategy lost 54.0 times more per bet than the lowest-loss performance. High relative losses were not unique to correct score bets, with, for example, the Least-skilled home–draw–away strategy losing 8.0 times more per bet than the lowest-loss performance.
Relative per-bet losses (in percentages) standardised so that the lowest loss strategy (Asian handicap, Most-skilled) = 1

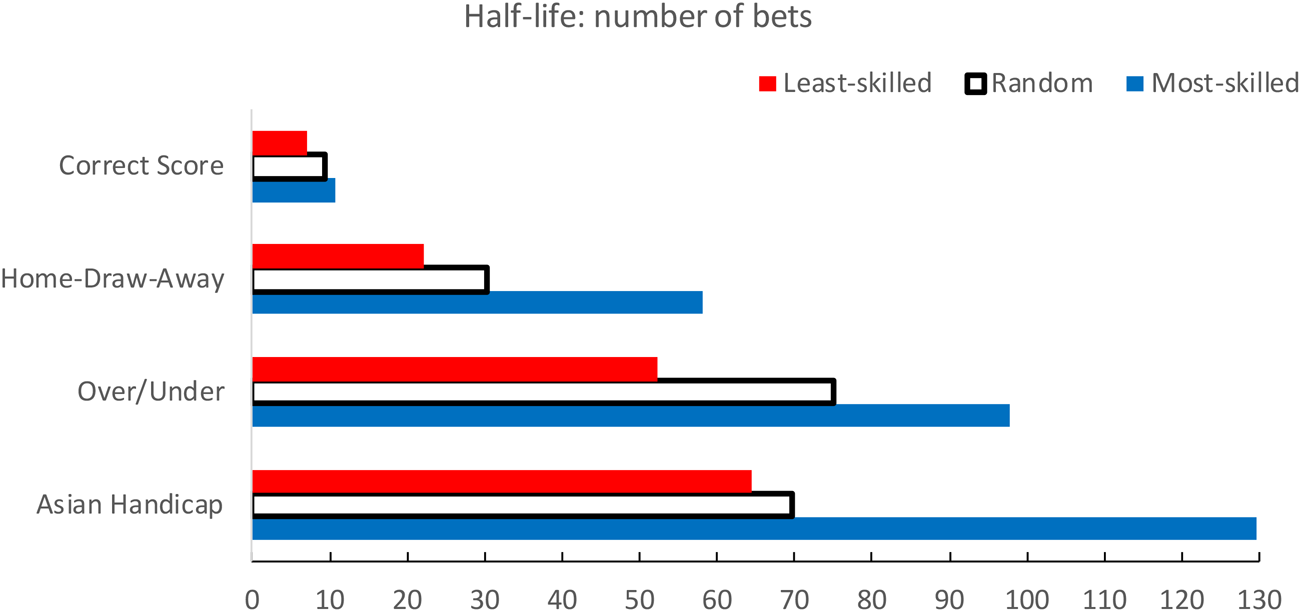
The half-life measured the number of bets before an average of 50% of starting wealth was lost (betting 10% of remaining wealth per match). Half-life variation is summarised in Figure 2, in response to RQ2. Similarly to Figure 1, the Most-skilled strategy had the longest half-life across each of the four bet types and the Least-skilled strategy had the shortest half-life. Correct score bets had half-lives of 10.8 to 7.0 bets, making it an outlier compared to the other three bet types. The other three bet types had Least-skilled half-lives of 22.2 (home–draw–away), 52.2 (over/under) and 64.4 bets (Asian handicap), all lasting longer than the Most-skilled correct score strategy. A comparison of relative half-lives in Table 3 highlights the large differences. The longest half-life strategy (Asian handicap, Most-skilled, 129.6 bets) lasted 18.5 times longer than the shortest half-life strategy (correct score, Least-skilled, 7.0 bets). There was again a large spread in betting outcomes, as measured by the half-life. All correct score betting strategies had short half-lives because this is the most volatile bet type.
Half-life variability over each bet type and strategy

Relative half-lives (in number of bets) standardised so that the lowest half-life strategy (correct score, Least-skilled) = 1

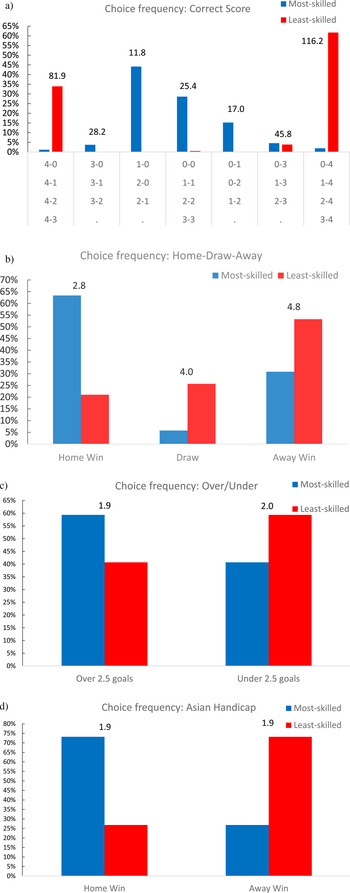
Next, we investigated the outcomes chosen by the Most-skilled and Least-skilled prediction strategies across each bet type. Figure 3 provides an answer to RQ3. There are clear differences, as the Most-skilled strategy preferred low-scoring home wins with correct score bets (Figure 3(a)) and home wins with home–draw–away bets (Figure 3(b)). Figure 3 also provides the average decimal odds across each outcome shown on the x-axis. The decimal odds represent the total payoff from a successful bet of $1 (Cortis, Reference Cortis2015). The higher the decimal odds, the more extreme a longshot the bet is. In soccer, the team playing at home is usually the favourite to win (due to home advantage). By convention, the home team's score is written first, so a scoreline of 2–0 translates to the home team scoring twice and not conceding.
Most- and Least-skilled specific choice frequencies across each bet type: (a) correct score; (b) home–draw–away; (c) over/under; and (d) Asian handicap. The decimal odds are shown above each x-axis category, showing the total average payoff from a successful bet of $1. Similar scorelines were grouped together in (a), although the model estimates frequencies for each scoreline separately. By convention, scorelines are written as ‘home team score–away team score’

Across each bet type, the Most-skilled strategy usually chose likely outcomes with low decimal odds. For example, the home team winning 1–0, 2–0 or 2–1 with correct score bets was chosen 44.1% of the time (average decimal odds = 11.8), and the home team winning in home–draw–away was chosen 63.4% of the time (average decimal odds = 2.8). The Most-skilled strategy also favoured the home team winning in the Asian handicap and over 2.5 goals in the over/under. By contrast, the Least-skilled strategy chose the most extreme outcomes. This is demonstrated best with correct score bets, where the Least-skilled strategy places more than 95% of its bets across either the away team winning and scoring four goals (61.7%, average decimal odds = 116.2) or the home team winning and scoring four goals (33.9%, average decimal odds = 81.9). (Each scoreline is estimated separately by the models; we have grouped similar scorelines together for simplicity.) The Most-skilled strategy tended to bet on favourites, while the Least-skilled strategy tended to bet on lower-probability longshots, reflecting the established human bias of overweighting small probabilities (Kahneman & Tversky, Reference Kahneman and Tversky1979).
Discussion
The ‘Introduction’ section called soccer betting a “skill-based gambling form.” In support of this claim, it was found that prediction skill mattered in each of the four soccer bet types. Most strikingly, it was found that gamblers’ losses varied by a factor of 54 (from 1.1% to 58.9%). To return to the ABV% comparison from the ‘Introduction’ section, this is like the difference between a reduced-alcohol lager and a strong whiskey. Meanwhile, the ‘half-life’ number of bets before a starting bankroll was reduced by half varied by a factor of 18.5 (from 7.0 to 129.6 bets). The large number of outcomes makes every correct score bet a longshot compared to the three other bet types. Usually starving but occasionally feasting is a poor way to maintain wealth on average over time. This suggests that responsible gamblers should limit their exposure to volatile bet types such as correct score bets. The Least-skilled strategy tended to bet on lower-probability longshots, reflecting the established human bias of overweighting small probabilities (Kahneman & Tversky, Reference Kahneman and Tversky1979). But how else might these results be relevant to the topic of responsible gambling in humans?
The wide variation in gamblers’ losses here contrasts with European roulette, where each possible bet has a constant house edge of 2.7%. This variability in soccer betting only increases the amount of information that should be given to gamblers, in keeping with responsible gambling principles (Parke et al., Reference Parke, Harris, Parke, Rigbye and Blaszczynski2015). But at present, UK soccer bets are marketed with only the betting odds and generic advice such as ‘When the fun stops, stop’. By contrast, the more informative house edge is currently communicated to electronic machine gamblers as the ‘return-to-player’ percentage (Parke et al., Reference Parke, Parke and Blaszczynski2016). In addition, from April 2019, a £2 wagering limit will be placed on UK electronic gambling machines (Casey, Reference Casey2018). By comparison, soccer betting, which is the most popular form of gambling with British problem gamblers (Gambleaware, 2017), has seen neither element of consumer protection.
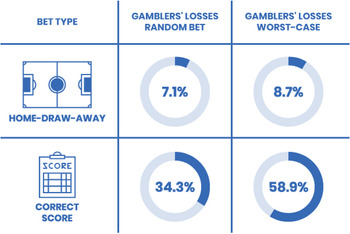
Providing more information to soccer bettors could be seen as an informational ‘nudge’ (Thaler & Sunstein, Reference Thaler and Sunstein2008), as an example of ‘boosting’ (Hertwig, Reference Hertwig2017) or as an example of consumer education (Peters, Reference Peters2017). Figure 4 provides an example of how more information could be given for home–draw–away and correct score bets – the two bet types from this paper that have been seen in observational studies of UK gambling advertising (Newall, Reference Newall2015, Reference Newall2017; Newall et al., Reference Newall, Thobhani, Walasek and Meyer2018). Figure 4 provides a prototype example of how gamblers’ losses when using the Random and Least-skilled strategies could be communicated to soccer bettors. In keeping with the spirit of ABV% labels, it might be wise not to present too much information to consumers, such as the Most-skilled strategy returns, which could plausibly cause confusion given that sports fans are prone to wishful thinking (Babad, Reference Babad1987).
Example of warning labels for home–draw–away and correct score bet types. The ‘worst-case’ column corresponds to the returns of the Least-skilled prediction strategy

However, Figure 4 presents only estimates based on our historical simulation of eight seasons of data, the largest dataset available to us. Because the risks of sports betting are not fixed, it is important to present gamblers with the most up-to-date information. We did not have access to actual past betting data for this paper, and so we were forced to use the Random strategy as a proxy for gamblers’ average losses. Replacing this figure with gamblers’ past average losses for a given bet type over some recent time horizon is one way in which Figure 4 could be improved upon. The timely communication of gamblers’ past losses could also help bookmakers who plan to increase their customer base by competing on price. By comparison, some British bookmakers appear to be currently competing to create new bets with high betting odds, which consumers observe, but high hidden house edges (Newall, Reference Newall2018).
There are many aspects of any new warning label that should first be empirically tested. Any new warning label should ideally be trialled in both the laboratory and in the field before being introduced into the population in order to mitigate the risk of any behavioural backfiring (Stibe & Cugelman, Reference Stibe, Cugelman, Meschtscherjakov, De Ruyter, Fuchsberger, Murer and Tscheligi2016). For example, qualitative research suggests that some young drinkers use ABV% information to find cost-effective ways of maximising their alcohol consumption (Jones & Gregory, Reference Jones and Gregory2009; Maynard et al., Reference Maynard, Langfield, Attwood, Allen, Drew, Votier and Munafò2017). While we think that few gamblers will want to purposively maximise their gambling losses, there are other issues from other public health domains of potential relevance to gambling risk communication. Any warning label should ideally be as attention grabbing as other product features. One eye-tracking study of alcohol warning labels showed that participants spent only 7% of their time looking at current UK alcohol warning labels (Kersbergen & Field, Reference Kersbergen and Field2017). The tobacco literature demonstrates that larger warning labels are the most effective (Hammond, Reference Hammond2011), which is relevant to any new warning label and to present return-to-player warning labels. Previous gambling research showed that many regular electronic machine gamblers had not even seen return-to-player warning labels before (Collins et al., Reference Collins, Green, d'Ardenne, Wardle and Williams2014), and that many gamblers find return-to-player warning labels confusing (Collins et al., Reference Collins, Green, d'Ardenne, Wardle and Williams2014; Harrigan et al., Reference Harrigan, Brown and Barton2017; Rowe et al., Reference Rowe, De Ionno, Holland, Flude, Brodrick, Vinay and Moutos2017). For example, the behavioural risk communication literature suggests that visual aids could boost gamblers’ risk understanding (Garcia-Retamero & Cokely, Reference Garcia-Retamero and Cokely2017).
Another approach is to educate gamblers not about statistical risks, but about observable features that are correlated with these risks. For example, with alcohol, there are many salient product features such as alcohol type and bottle size that are correlated with ABV%. This paper found that gamblers’ losses increased as the potential payoff implied by the betting odds increased, and this occurred both within and between bet types. Bets on longshots have higher average losses than bets on favourites. This is unlike European roulette, where the potential payoff and event probability are perfectly negatively correlated to create a constant average loss of 2.7%. A public health awareness campaign could therefore seek to warn gamblers about the above-average risks of longshot soccer bets. There is some evidence that sports bettors do learn to improve their returns over time, partly by avoiding longshots (Feess et al., Reference Feess, Müller and Schumacher2014). This natural learning process could be enhanced with more explicit advice.
It could be the case that warning labels and education campaigns are an insufficient intervention to debias consumers about the complex statistical information underlying modern soccer bets (Weiss-Cohen et al., Reference Weiss-Cohen, Konstantinidis, Speekenbrink and Harvey2018) and given the messages in gambling marketing prompting more frequent and riskier gambling (Hing et al., Reference Hing, Russell, Li and Vitartas2018, Reference Hing, Russell, Thomas and Jenkinson2019). This may particularly be the case in soccer betting, given evidence that sports fans are prone to wishful thinking (Babad, Reference Babad1987) and are overconfident even when the financial stakes are high (Simmons & Massey, Reference Simmons and Massey2012). If this is the case, than less freedom-preserving public health interventions should also be considered (Nuffield Council on Bioethics, 2007). For example, a stronger intervention is to ‘restrict choice’, which is already being used for UK electronic gambling machines, where the maximum bet size will be reduced from £100 to £2 from April 2019 (Casey, Reference Casey2018). Tax incentives are also being used in UK alcohol policy, with stronger forms of alcohol being subject to different rates of tax duty than lower-strength alcohol. Any public health intervention should be informed by the fundamental data on product risk that this paper attempts to uncover for soccer betting.
Gambling-related harm increases as gamblers’ total losses increase (Markham et al., Reference Markham, Young and Doran2014, Reference Markham, Young and Doran2016). However, gamblers’ average losses must be combined with betting volume to determine gamblers’ total losses. But the betting volume of human sports bettors constitutes data that we did not have access to for this paper. Data on human betting volume could plausibly highlight a different set of high-loss soccer bets that are important for the promotion of responsible gambling. We hope that gambling operators will share more data on gamblers’ actual behaviour (Cassidy et al., Reference Cassidy, Loussouarn and Pisac2013) in order to determine the extent to which these machine learning strategies reflect actual differences in human betting skill and to enable further research on responsible gambling in humans.
Questions might also be asked as to what machine learning can do to help inform soccer bettors. Although better predictive models than those used in the current paper could always be designed, this should not disqualify our inferences on different betting strategies’ relative risks. Machine learning has progressed recently in relatively constrained skill-based decision-making domains. Chess champion Garry Kasparov lost to Deep Blue in 1997. Go champion Lee Sedol lost to AlphaGo in 2016. And various top poker professionals have lost special matches to machines (Brown & Sandholm, Reference Brown and Sandholm2017; Moravčík et al., Reference Moravčík, Schmid, Burch, Lisý, Morrill, Bard, Davis, Waugh, Johanson and Bowling2017), with poker being a skill-based gambling form (Potter van Loon et al., Reference van Loon Potter, van den Assem and van Dolder2015). Although machine play is still imperfect for all but the simplest games, machines have attained a high enough level that experts in chess (Kasparov, Reference Kasparov2017), go (Metz, Reference Metz2016) and poker (Newall, Reference Newall2013) now routinely train with machines. This suggests that machine intelligence should be good enough to inform non-expert soccer bettors as well. Using machine intelligence to inform responsible gambling strategies in humans could well become more internationally relevant over time as the USA moves towards widespread legalised sports betting (Purdum, Reference Purdum2018).
Acknowledgements
Thanks to Tadgh Hegarty and Lukasz Walasek for their useful feedback.
Funding
The authors received no funding for this research.