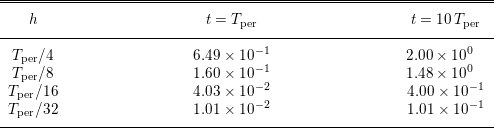1 Introduction
This paper surveys the relations between numerical integration and the Hamiltonian (or hybrid) Monte Carlo method (HMC), an important and widely used Markov chain Monte Carlo algorithm (Diaconis Reference Diaconis2009) for sampling from probability distributions. It is written for a general audience and requires no background on numerical algorithms for solving differential equations. We hope that it will be useful to mathematicians, statisticians and scientists, especially because the efficiency of HMC is largely dependent on the performance of the numerical integrator used in the algorithm.
Named one of the top ten algorithms of the twentieth century (Cipra Reference Cipra2000), MCMC originated in statistical mechanics (Allen and Tildesley Reference Allen and Tildesley1987, Frenkel and Smit Reference Frenkel and Smit2002, Krauth Reference Krauth2006, Lelièvre, Rousset and Stoltz Reference Lelièvre, Rousset and Stoltz2010, Tuckerman Reference Tuckerman2010, Landau and Binder Reference Landau and Binder2014) and is now a cornerstone in statistics (Geman and Geman Reference Geman and Geman1984, Gelfand and Smith Reference Gelfand and Smith1990, Geyer Reference Geyer1992, Tierney Reference Tierney1994); in fact Bayesian approaches only became widespread once MCMC made it possible to sample from completely arbitrary distributions. In conjunction with Bayesian methodologies, MCMC has enabled applications of statistical inference to biostatistics (Jensen, Liu, Zhou and Liu Reference Jensen, Liu, Zhou and Liu2004), population modelling (Link and Barker Reference Link and Barker2009), reliability/risk assessment/uncertainty quantification (Sullivan Reference Sullivan2015), machine learning (Andrieu, de Freitas, Doucet and Jordan Reference Andrieu, de Freitas, Doucet and Jordan2003), inverse problems (Stuart Reference Stuart2010), data assimilation (Chen Reference Chen2003, Evensen Reference Evensen2009), pattern recognition (Webb Reference Webb2003, Bishop Reference Bishop2006), artificial intelligence (Ghahramani Reference Ghahramani2015), and probabilistic robots (Thrun, Burgard and Fox Reference Thrun, Burgard and Fox2005). In these applications, MCMC is used to evaluate the expected values necessary for Bayesian statistical inference, in situations where other methods such as numerical quadrature, Laplace approximation and Monte Carlo importance sampling are impractical or inaccurate. Moreover, MCMC is used as a tool to set the invariant distribution of numerical methods for first- and second-order Langevin stochastic differential equations (Kikuchi, Yoshida, Maekawa and Watanabe Reference Kikuchi, Yoshida, Maekawa and Watanabe1991, Roberts and Tweedie Reference Roberts and Tweedie1996b , Roberts and Tweedie Reference Roberts and Tweedie1996a , Bou-Rabee and Vanden-Eijnden Reference Bou-Rabee and Vanden-Eijnden2010, Bou-Rabee and Vanden-Eijnden Reference Bou-Rabee and Vanden-Eijnden2012, Bou-Rabee and Hairer Reference Bou-Rabee and Hairer2013, Bou-Rabee, Donev and Vanden-Eijnden Reference Bou-Rabee, Donev and Vanden-Eijnden2014, Bou-Rabee Reference Bou-Rabee2014, Fathi Reference Fathi2014, Fathi, Homman and Stoltz Reference Fathi, Homman and Stoltz2015) and stochastic partial differential equations (Beskos, Roberts, Stuart and Voss Reference Beskos, Roberts, Stuart and Voss2008, Bou-Rabee Reference Bou-Rabee2017). Even though MCMC algorithms are often straightforward to program, there are numerous user-friendly, general-purpose software packages available to carry out statistical analysis, including BUGS (Lunn, Thomas, Best and Spiegelhalter Reference Lunn, Thomas, Best and Spiegelhalter2000, Lunn, Spiegelhalter, Thomas and Best Reference Lunn, Spiegelhalter, Thomas and Best2009, Lunn et al. Reference Lunn, Jackson, Best, Thomas and Spiegelhalter2012), Stan (Carpenter et al. Reference Carpenter, Gelman, Hoffman, Lee, Goodrich, Betancourt, Brubaker, Guo, Li and Riddell2016), MCMCpack (Martin, Quinn and Park Reference Martin, Quinn and Park2011), MCMCglmm (Hadfield Reference Hadfield2010) and PyMC (Patil, Huard and Fonnesbeck Reference Patil, Huard and Fonnesbeck2010).
HMC itself was invented in 1987 (Duane, Kennedy, Pendleton and Roweth Reference Duane, Kennedy, Pendleton and Roweth1987) to study lattice models of quantum field theory, and about a decade later popularized in data science (Liu Reference Liu2008, Neal Reference Neal and Brooks2011). A simple introduction to this algorithm may be found in Sanz-Serna (Reference Sanz-Serna, Dieci and Guglielmi2014). A key feature of HMC is that it offers the possibility of generating proposal moves that, while being far away from the current state of the Markov chain, may be accepted with high probability, thus avoiding random walk behaviour and reducing the correlation between samples. Such a possibility exists because proposals are generated by numerically integrating a system of Hamiltonian differential equations. The distance between the proposal and the current state may in principle be large if the differential equations are integrated over a suitably long time interval; the acceptance probability of the proposals may be made arbitrarily close to
 $100\%$
by carrying out the integration with sufficient accuracy. Of particular significance for us is the fact that HMC requires that the numerical integration be performed with a volume-preserving reversible method.
Since the computational cost of HMC mainly lies in the numerical integrations, it is of much interest to perform these as efficiently as possible. At present, the well-known velocity Verlet algorithm is the method of choice, but, as will be apparent, Verlet may not be the most efficient integrator one could use. What does it take to design a good integrator for HMC? A key point of this paper is that, due to the specificities of the situation, a number of concepts traditionally used to analyse numerical integrators (including the notions of order of consistency/convergence, error constants, and others) are of limited value in our context. On the one hand and as we have already mentioned, HMC requires methods that have the geometric properties of being volume-preserving and reversible, and this limits the number of integrators that may be applied. It is fortunate that, in the last twenty-five years, the literature on the numerical solution of differential equations has given much attention to the construction of integrators with relevant geometric properties, to the point that geometric integration (a term introduced in Sanz-Serna Reference Sanz-Serna, Duff and Watson1997) is now a well-established subfield of numerical analysis (Iserles and Quispel Reference Iserles and Quispel2017). On the other hand, the properties of preservation of volume and reversibility have important quantitative implications on the integration error (Theorem 6.2), which in turn have an impact on the acceptance rate of proposals. As a consequence, it turns out that, for HMC purposes, the order of the integrator is effectively twice its nominal order; for instance the Verlet algorithm behaves, within HMC, as a fourth-order integrator. In addition, in HMC, integrators are likely to be operated with large values of the step size, with the implication that analyses that are only valid in the limit of vanishing step size may not be very informative. One has rather to turn to studying the performance of the integrator in well-chosen model problems.
Sections 2–5 provide the necessary background on differential equations, numerical methods, geometric integration and Monte Carlo methods respectively. The heart of the paper is in Section 6. Among the topics considered there, we mention the investigation of the impact on the energy error of the properties of preservation of volume and reversibility (Theorem 6.2) and a detailed study of the behaviour of the integrators in the Gaussian model. Also presented in Section 6 is the construction of integrators more efficient than the Verlet algorithm. Sections 7 and 8 consider, in two different scenarios, the behaviour of HMC as the dimensionality of the target distribution increases. Section 7, based on Beskos et al. (Reference Beskos, Pillai, Roberts, Sanz-Serna and Stuart2013), studies the model problem where the target is a product of many independent, identical copies. The case where the target arises from discretization of an infinite-dimensional distribution is addressed in Section 8; our treatment, while related to the material in Beskos, Pinski, Sanz-Serna and Stuart (Reference Beskos, Pinski, Sanz-Serna and Stuart2011), has some novel features because we have avoided the functional analytic language employed in that reference. Finally, Section 9 contains supplementary material.
2 Differential equations and their flows
In this section we introduce some notation and review background material on differential equations, with special emphasis on the Hamiltonian and reversible systems at the basis of HMC algorithms. The section ends with a description of the Lie bracket, which appears in the analysis of the integrators to be used later.
2.1 Preliminaries
We are concerned with autonomous systems of differential equations in
 $\mathbb{R}^{D}$
,
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}x=f(x);\end{eqnarray}$$
the function (vector field)
 $f$
is assumed throughout to be defined in the whole of
 $\mathbb{R}^{D}$
and to be sufficiently smooth. An important role is played by the particular case
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}q=M^{-1}p,\quad \displaystyle \frac{\text{d}}{\text{d}t}p=F(q),\end{eqnarray}$$
where
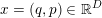 $x=(q,p)\in \mathbb{R}^{D}$
,
 $D=2d$
,
 $q\in \mathbb{R}^{d}$
,
 $p\in \mathbb{R}^{d}$
and
 $M$
is a constant, invertible matrix, so that
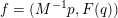 $f=(M^{-1}p,F(q))$
. By eliminating
 $p$
, (2.2) is seen to be equivalent to
 $$\begin{eqnarray}M\displaystyle \frac{\text{d}^{2}}{\text{d}t^{2}}q=F(q);\end{eqnarray}$$
this is not the most general autonomous system of second-order differential equations in
 $\mathbb{R}^{d}$
because the derivative
 $(\text{d}/\text{d}t)q$
does not appear on the right-hand side. When the forces depend only on the positions, Newton’s second law for a mechanical system gives rise to differential equations of the form (2.2); then
 $q$
,
 $(\text{d}/\text{d}t)q$
,
 $p$
and
 $F$
are respectively the vectors of coordinates, velocities, momenta and forces, and
 $M$
is the matrix of masses.
We let
 $\unicode[STIX]{x1D711}_{t}$
denote the
 $t$
-flow of the system (2.1) under consideration. By definition, for fixed real
 $t$
,
 $\unicode[STIX]{x1D711}_{t}:\mathbb{R}^{D}\rightarrow \mathbb{R}^{D}$
is the map that associates with each
 $\unicode[STIX]{x1D6FC}\in \mathbb{R}^{D}$
the value at time
 $t$
of the solution of (2.1) that at the initial time 0 takes the initial value
 $\unicode[STIX]{x1D6FC}$
.
Example 2.1. As a very simple but important example, we consider the standard harmonic oscillator, the system in
 $\mathbb{R}^{2}$
of the special form (2.2) given by
 $$\begin{eqnarray}\displaystyle \frac{\text{d}q}{\text{d}t}=p,\quad \displaystyle \frac{\text{d}p}{\text{d}t}=-q.\end{eqnarray}$$
For future reference, we note that, with matrix notation, the solutions satisfy
 $$\begin{eqnarray}\left[\begin{array}{@{}c@{}}q(t)\\ p(t)\end{array}\right]=M_{t}\left[\begin{array}{@{}c@{}}q(0)\\ p(0)\end{array}\right]\!,\quad M_{t}=\left[\begin{array}{@{}cc@{}}\phantom{-}\cos t & \sin t\\ -\sin t & \cos t\end{array}\right]\!.\end{eqnarray}$$
Thus the flow has the expression
 $$\begin{eqnarray}\unicode[STIX]{x1D711}_{t}(\unicode[STIX]{x1D709},\hspace{2.22198pt}\unicode[STIX]{x1D702})=(\unicode[STIX]{x1D709}\cos t+\unicode[STIX]{x1D702}\sin t,\hspace{2.22198pt}-\unicode[STIX]{x1D709}\sin t+\unicode[STIX]{x1D702}\cos t).\end{eqnarray}$$
When
 $\unicode[STIX]{x1D6FC}=(\unicode[STIX]{x1D709},\unicode[STIX]{x1D702})\in \mathbb{R}^{2}$
is fixed and
 $t$
varies, the right-hand side of (2.5) yields the solution that at
 $t=0$
takes the initial value
 $(\unicode[STIX]{x1D709},\unicode[STIX]{x1D702})$
. The notation
 $\unicode[STIX]{x1D711}_{t}(\unicode[STIX]{x1D709},\hspace{2.22198pt}\unicode[STIX]{x1D702})$
emphasizes that, in the flow, it is the parameter
 $t$
that is seen as fixed, while
 $(\unicode[STIX]{x1D709},\unicode[STIX]{x1D702})\in \mathbb{R}^{2}$
is regarded as a variable. Geometrically,
 $\unicode[STIX]{x1D711}_{t}$
is the clockwise rotation of angle
 $t$
around the origin of the
 $(q,p)$
-plane.
For a given system (2.1), it is well possible that for some choices of
 $\unicode[STIX]{x1D6FC}$
and
 $t$
, the vector
 $\unicode[STIX]{x1D711}_{t}(\unicode[STIX]{x1D6FC})\in \mathbb{R}^{D}$
is not defined; this will happen if
 $t$
is outside the interval in which the solution of (2.1) with initial value
 $\unicode[STIX]{x1D6FC}$
exists. For simplicity in the statements, we shall assume hereafter that
 $\unicode[STIX]{x1D711}_{t}(\unicode[STIX]{x1D6FC})$
is always defined.
Flows possess the group property:
 $\unicode[STIX]{x1D711}_{0}$
is the identity map in
 $\mathbb{R}^{D}$
and, for arbitrary real
 $s$
and
 $t$
,
 $$\begin{eqnarray}\unicode[STIX]{x1D711}_{t}\circ \unicode[STIX]{x1D711}_{s}=\unicode[STIX]{x1D711}_{s+t}.\end{eqnarray}$$
In particular, for each
 $t$
,
 $$\begin{eqnarray}(\unicode[STIX]{x1D711}_{t})^{-1}=\unicode[STIX]{x1D711}_{-t},\end{eqnarray}$$
that is,
 $\unicode[STIX]{x1D711}_{-t}$
is the inverse of the map
 $\unicode[STIX]{x1D711}_{t}$
. For the harmonic oscillator example, the group property simply states that a rotation of angle
 $s$
followed by a rotation of angle
 $t$
has the same effect as a rotation of angle
 $s+t$
.
2.2 Hamiltonian systems
The Hamiltonian formalism (Marsden and Ratiu Reference Marsden and Ratiu1999, Arnol’d Reference Arnol’d1989) is essential for understanding HMC algorithms.
2.2.1 Hamiltonian vector fields
Assume that the dimension
 $D$
of (2.1) is even,
 $D=2d$
, and write
 $x=(q,p)$
with
 $q,p\in \mathbb{R}^{d}$
. Then the system (2.1) is said to be Hamiltonian if there is a function
 $H:\mathbb{R}^{2d}\rightarrow \mathbb{R}$
such that, for
 $i=1,\ldots ,d$
, the scalar components
 $f^{i}$
of
 $f$
are given by
 $$\begin{eqnarray}f^{i}(q,p)=+\displaystyle \frac{\unicode[STIX]{x2202}H}{\unicode[STIX]{x2202}q^{i}}(q,p),\quad f^{d+i}(q,p)=-\displaystyle \frac{\unicode[STIX]{x2202}H}{\unicode[STIX]{x2202}p^{i}}(q,p).\end{eqnarray}$$
Thus, the system is
 $$\begin{eqnarray}\displaystyle \frac{\text{d}q^{i}}{\text{d}t}=+\displaystyle \frac{\unicode[STIX]{x2202}H}{\unicode[STIX]{x2202}q^{i}}(q,p),\quad \displaystyle \frac{\text{d}p^{i}}{\text{d}t}=-\displaystyle \frac{\unicode[STIX]{x2202}H}{\unicode[STIX]{x2202}p^{i}}(q,p),\end{eqnarray}$$
or, in vector notation (Sanz-Serna and Calvo Reference Sanz-Serna and Calvo1994),
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}\left[\begin{array}{@{}c@{}}q\\ p\end{array}\right]=J^{-1}\unicode[STIX]{x1D6FB}H(q,p),\end{eqnarray}$$
where
 $$\begin{eqnarray}\unicode[STIX]{x1D6FB}H=\biggl[\displaystyle \frac{\unicode[STIX]{x2202}H}{\unicode[STIX]{x2202}q^{1}},\ldots ,\displaystyle \frac{\unicode[STIX]{x2202}H}{\unicode[STIX]{x2202}q^{d}},\displaystyle \frac{\unicode[STIX]{x2202}H}{\unicode[STIX]{x2202}p^{1}},\ldots ,\displaystyle \frac{\unicode[STIX]{x2202}H}{\unicode[STIX]{x2202}p^{d}}\biggr]^{T}\end{eqnarray}$$
and
 $$\begin{eqnarray}J=\left[\begin{array}{@{}cc@{}}0_{d\times d} & -I_{d\times d}\\ I_{d\times d} & \phantom{-}0_{d\times d}\end{array}\right]\!.\end{eqnarray}$$
The function
 $H$
is called the Hamiltonian,
 $\mathbb{R}^{2d}$
is the phase space, and
 $d$
is the number of degrees of freedom.
A system of the special form (2.2) is Hamiltonian if and only if
 $F=-\unicode[STIX]{x1D6FB}{\mathcal{U}}(q)$
for a suitable real-valued function
 ${\mathcal{U}}$
, that is,
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}q=M^{-1}p,\quad \displaystyle \frac{\text{d}}{\text{d}t}p=-\unicode[STIX]{x1D6FB}{\mathcal{U}}(q);\end{eqnarray}$$
when that is the case,
 $$\begin{eqnarray}H(q,p)={\mathcal{T}}(p)+{\mathcal{U}}(q),\quad \text{with }{\mathcal{T}}(p)=\displaystyle \frac{1}{2}p^{T}M^{-1}p.\end{eqnarray}$$
In applications to mechanics,
 ${\mathcal{T}}$
and
 ${\mathcal{U}}$
are respectively the potential and kinetic energy and
 $H$
represents the total energy in the system. The harmonic oscillator (2.3) provides the simplest example; there
 ${\mathcal{T}}=(1/2)p^{2}$
,
 ${\mathcal{U}}=(1/2)q^{2}$
.
2.2.2 Symplecticness and preservation of oriented volume
A mapping
 $\unicode[STIX]{x1D6F7}:\mathbb{R}^{2d}\rightarrow \mathbb{R}^{2d}$
is said to be symplectic or canonical if, at each point
 $(q,p)\in \mathbb{R}^{2d}$
,
 $$\begin{eqnarray}\unicode[STIX]{x1D6F7}^{\prime }(q,p)^{T}J\unicode[STIX]{x1D6F7}^{\prime }(q,p)=J\end{eqnarray}$$
(
 $\unicode[STIX]{x1D6F7}^{\prime }(q,p)$
denotes the
 $2d\times 2d$
Jacobian matrix of
 $\unicode[STIX]{x1D6F7}$
). The (analytic) condition (2.11) has a geometric interpretation in terms of preservation of two-dimensional areas (Arnol’d Reference Arnol’d1989); this interpretation is not required to understand the rest of the paper.
When
 $d=1$
, if we set
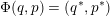 $\unicode[STIX]{x1D6F7}(q,p)=(q^{\ast },p^{\ast })$
, the condition (2.11), after multiplying the matrices on the left-hand side, is seen to be equivalent to
 $$\begin{eqnarray}\displaystyle \frac{\unicode[STIX]{x2202}q^{\ast }}{\unicode[STIX]{x2202}q}\displaystyle \frac{\unicode[STIX]{x2202}p^{\ast }}{\unicode[STIX]{x2202}p}-\displaystyle \frac{\unicode[STIX]{x2202}q^{\ast }}{\unicode[STIX]{x2202}p}\displaystyle \frac{\unicode[STIX]{x2202}p^{\ast }}{\unicode[STIX]{x2202}q}=1.\end{eqnarray}$$
The left-hand side is the Jacobian determinant of
 $\unicode[STIX]{x1D6F7}$
and therefore the transformation
 $\unicode[STIX]{x1D6F7}$
is symplectic if and only if the mapping
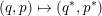 $(q,p)\mapsto (q^{\ast },p^{\ast })$
preserves oriented area in the
 $(q,p)$
-plane, that is, for any domain
 $D$
the oriented area of the image
 $\unicode[STIX]{x1D6F7}(D)\subset \mathbb{R}^{2}$
coincides with the oriented area of
 $D$
.Footnote
1
For instance, for each
 $t$
, the rotation in (2.5) is a symplectic transformation in
 $\mathbb{R}^{2}$
.
For general
 $d$
the following result holds (Arnol’d Reference Arnol’d1989, Section 38).
Proposition 2.2. For a symplectic transformation the determinant of
 $\unicode[STIX]{x1D6F7}^{\prime }$
equals 1. Therefore symplectic transformations preserve the oriented volume in
 $\mathbb{R}^{2d}$
, that is,
 $\unicode[STIX]{x1D6F7}(D)$
and
 $D$
have the same oriented volume for each domain
 $D\subset \mathbb{R}^{2d}$
.
For
 $d>1$
, preservation of oriented volume is a strictly weaker property than symplecticness.
The proof of the following two results is easy using (2.11).
Proposition 2.3. The composition
 $\unicode[STIX]{x1D6F7}_{1}\circ \unicode[STIX]{x1D6F7}_{2}$
of two symplectic mappings is itself symplectic.
Proposition 2.4. The change of variables
 $(q,p)=\unicode[STIX]{x1D6F7}(\bar{q},\bar{p})$
with
 $\unicode[STIX]{x1D6F7}$
symplectic transforms the Hamiltonian system of differential equations (2.8) into a system for
 $(\bar{q},\bar{p})$
that is also Hamiltonian. Moreover, the Hamiltonian function
 $\bar{H}$
of the transformed system is the result of changing variables in
 $H$
, that is,
 $\bar{H}=H\circ \unicode[STIX]{x1D6F7}$
.
In view of the following important general result (Marsden and Ratiu Reference Marsden and Ratiu1999, Proposition 2.6.2), the symplecticness of the rotation (2.5) noted above is a manifestation of the Hamiltonian character of the harmonic oscillator.
Theorem 2.5. Let
 $D=2d$
. The system (2.1) with flow
 $\unicode[STIX]{x1D711}_{t}$
is Hamiltonian if and only if, for each real
 $t$
,
 $\unicode[STIX]{x1D711}_{t}$
is a symplectic mapping.
Thus symplecticness is a characteristic property that allows us to decide whether a differential system is Hamiltonian or otherwise in terms of its flow, without knowing the vector field (right-hand side)
 $f$
of the equation.
We recall that a flow preserves oriented volume if and only if the corresponding vector field
 $f$
is divergence-free (
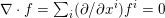 $\unicode[STIX]{x1D6FB}\cdot f=\sum _{i}(\unicode[STIX]{x2202}/\unicode[STIX]{x2202}x^{i})f^{i}=0$
). If
 $d>1$
, there are divergence-free differential systems in
 $\mathbb{R}^{2d}$
that are not Hamiltonian; their flows preserve oriented volume but are not symplectic.
The behaviour of the solutions of Hamiltonian problems is very different from that encountered in ‘general’ systems; some features that are ‘the rule’ in Hamiltonian systems are exceptional in non-Hamiltonian systems. Such special behaviour of Hamiltonian solutions may always be traced back to the symplecticness of the flow. As a very simple example, we consider once more the harmonic oscillator (2.3). The origin is a centre: a neutrally stable equilibrium surrounded by periodic trajectories. Small perturbations of the right-hand side of (2.3) generically destroy the centre; after perturbation the trajectories become spirals and the origin becomes either an asymptotically stable node (trajectories spiral in) or an unstable node (trajectories spiral out). However, if the perturbation is such that the perturbed system is also Hamiltonian, then the centre will not disappear under small perturbations.
2.2.3 Preservation of energy
If
 $(q(t),p(t))$
is a solution of (2.8), then
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}H(q(t),p(t))=\unicode[STIX]{x1D6FB}H(q(t),p(t))^{T}J^{-1}\unicode[STIX]{x1D6FB}H(q(t),p(t))=0,\end{eqnarray}$$
because
 $J^{-1}$
is skew-symmetric. Therefore we may state the following.
Theorem 2.6. The value of the Hamiltonian function is preserved by the flow of the corresponding Hamiltonian system, that is,
 $H\circ \unicode[STIX]{x1D711}_{t}=H$
for each real
 $t$
.
In applications to the physical sciences, this result is usually the mathematical expression of the principle of conservation of energy. Unlike symplecticness, which is a characteristic property, conservation of energy on its own does not ensure that the underlying system is Hamiltonian. There are many examples of non-Hamiltonian systems whose solutions preserve the value of a suitable energy function.
2.2.4 Preservation of the canonical probability measure
Let
 $\unicode[STIX]{x1D6FD}$
denote a positive constant and assume that
 $H$
is such that
 $$\begin{eqnarray}Z=\int _{\mathbb{R}^{2d}}\exp (-\unicode[STIX]{x1D6FD}H(q,p))\,\text{d}q\,\text{d}p<\infty .\end{eqnarray}$$
Then we have the following result, which is a direct consequence of the fact that
 $\unicode[STIX]{x1D711}_{t}$
preserves both the volume element
 $\text{d}q\,\text{d}p$
(Proposition 2.2) and the value of
 $\exp (-\unicode[STIX]{x1D6FD}H)$
(because, according to Theorem 2.6, it preserves the value of
 $H$
).
Theorem 2.7. The probability measure
 $\unicode[STIX]{x1D707}$
in
 $\mathbb{R}^{2d}$
with density (with respect to the ordinary Lebesgue measure)
 $Z^{-1}\exp (-\unicode[STIX]{x1D6FD}H(q,p))$
is preserved by the flow of the Hamiltonian system (2.8), that is,
 $\unicode[STIX]{x1D707}(\unicode[STIX]{x1D711}_{t}(D))=\unicode[STIX]{x1D707}(D)$
for each domain
 $D\subset \mathbb{R}^{2d}$
and each real
 $t$
.
In statistical mechanics (Allen and Tildesley Reference Allen and Tildesley1987, Frenkel and Smit Reference Frenkel and Smit2002, Tuckerman Reference Tuckerman2010), if (2.8) describes the dynamics of a physical system and
 $\unicode[STIX]{x1D6FD}$
is the inverse of the absolute temperature, then
 $\unicode[STIX]{x1D707}$
is the canonical measure that governs the distribution of
 $(q,p)$
over an ensemble of many copies of the given system when the system is in contact with a heat bath at constant temperature, that is,
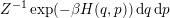 $Z^{-1}\exp (-\unicode[STIX]{x1D6FD}H(q,p))\,\text{d}q\,\text{d}p$
represents the fraction of copies with momenta between
 $p$
and
 $p+\text{d}p$
, and configuration between
 $q$
and
 $q+\,\text{d}q$
. Note that under the canonical distribution, (local) minima of the energy
 $H$
correspond to (local) maxima of the probability density function, that is, to modes of the distribution. Also, if the temperature decreases (
 $\unicode[STIX]{x1D6FD}$
increases), it is less likely to find the system at a location
 $(q,p)$
with high energy.
For Hamiltonian functions of the particular form in (2.10), we may factorize
 $$\begin{eqnarray}\exp (-\unicode[STIX]{x1D6FD}H(q,p))=\exp \biggl(-\displaystyle \frac{1}{2}\unicode[STIX]{x1D6FD}\,p^{T}M^{-1}p\biggr)\times \exp (-\unicode[STIX]{x1D6FD}\,{\mathcal{U}}(q))\end{eqnarray}$$
and therefore, under the canonical distribution,
 $q$
and
 $p$
are stochastically independent. The (marginal) distribution of the configuration variables
 $q$
has probability density function proportional to
 $\exp (-\unicode[STIX]{x1D6FD}\,{\mathcal{U}}(q))$
. The momenta
 $p$
possess a Gaussian distribution with zero mean and covariance matrix equal to
 $M$
. These distributions are associated with the names of Boltzmann, Gibbs and Maxwell. Hereafter we refer to the canonical measure as the Boltzmann–Gibbs distribution.
2.3 Reversible systems
Assume now that
 $S$
is a linear involution in
 $\mathbb{R}^{D}$
, that is, a linear map such that
 $S(S(x))=x$
for each
 $x$
. A mapping
 $\unicode[STIX]{x1D6F7}:\mathbb{R}^{D}\rightarrow \mathbb{R}^{D}$
is said to be reversible (with respect to
 $S$
) if, for each
 $x$
,
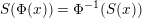 $S(\unicode[STIX]{x1D6F7}(x))=\unicode[STIX]{x1D6F7}^{-1}(S(x))$
or, more compactly,
 $$\begin{eqnarray}S\circ \unicode[STIX]{x1D6F7}=\unicode[STIX]{x1D6F7}^{-1}\circ S.\end{eqnarray}$$
The following results have easy proofs.
Proposition 2.8. If
 $\unicode[STIX]{x1D6F7}$
is
 $S$
reversible, then
 $$\begin{eqnarray}|\text{det}\,\unicode[STIX]{x1D6F7}^{\prime }(S(\unicode[STIX]{x1D6F7}(x)))|=|\text{det}\,\unicode[STIX]{x1D6F7}^{\prime }(x)|^{-1},\end{eqnarray}$$
for each
 $x$
.
Proposition 2.9. If
 $\unicode[STIX]{x1D6F7}_{1}$
is
 $S$
-reversible, then
 $\unicode[STIX]{x1D6F7}_{1}\circ \unicode[STIX]{x1D6F7}_{1}$
is
 $S$
-reversible. If
 $\unicode[STIX]{x1D6F7}_{1}$
and
 $\unicode[STIX]{x1D6F7}_{2}$
are
 $S$
-reversible, then the symmetric composition
 $\unicode[STIX]{x1D6F7}_{1}\circ \unicode[STIX]{x1D6F7}_{2}\circ \unicode[STIX]{x1D6F7}_{1}$
is
 $S$
-reversible.
Theorem 2.10. Consider the system (2.1) with flow
 $\unicode[STIX]{x1D711}_{t}$
. The following statements are equivalent.
∙ For each
 $t$
,
$\unicode[STIX]{x1D711}_{t}$
is an
$S$
-reversible mapping.
∙ For each
$x\in \mathbb{R}^{D}$
,
$S(f(x))=-f(S(x))$
, that is,
$S\circ f=-f\circ S$
.


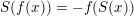

Systems of differential equations that satisfy the conditions in the theorem are said to be reversible (with respect to
 $S$
). Systems of the particular form (2.2) are reversible with respect to the momentum flip involution
 $$\begin{eqnarray}S(q,p)=(q,-p).\end{eqnarray}$$
If (2.2) describes a mechanical system, then (2.12) expresses the well-known time-reversibility of mechanics: if
 $(q_{in},p_{in})$
is the initial state of a system and
 $(q_{f},p_{f})$
the final state after
 $t$
units of time have elapsed, then the state
 $(q_{f},-p_{f})$
evolves in
 $t$
units of time to the state
 $(q_{in},-p_{in})$
.
Proposition 2.11. The Hamiltonian system (2.8) is reversible with respect to the momentum flip involution (2.13) if and only if
 $H$
is an even function of
 $p$
, that is,
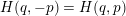 $H(q,-p)=H(q,p)$
for all
 $q$
and
 $p$
.
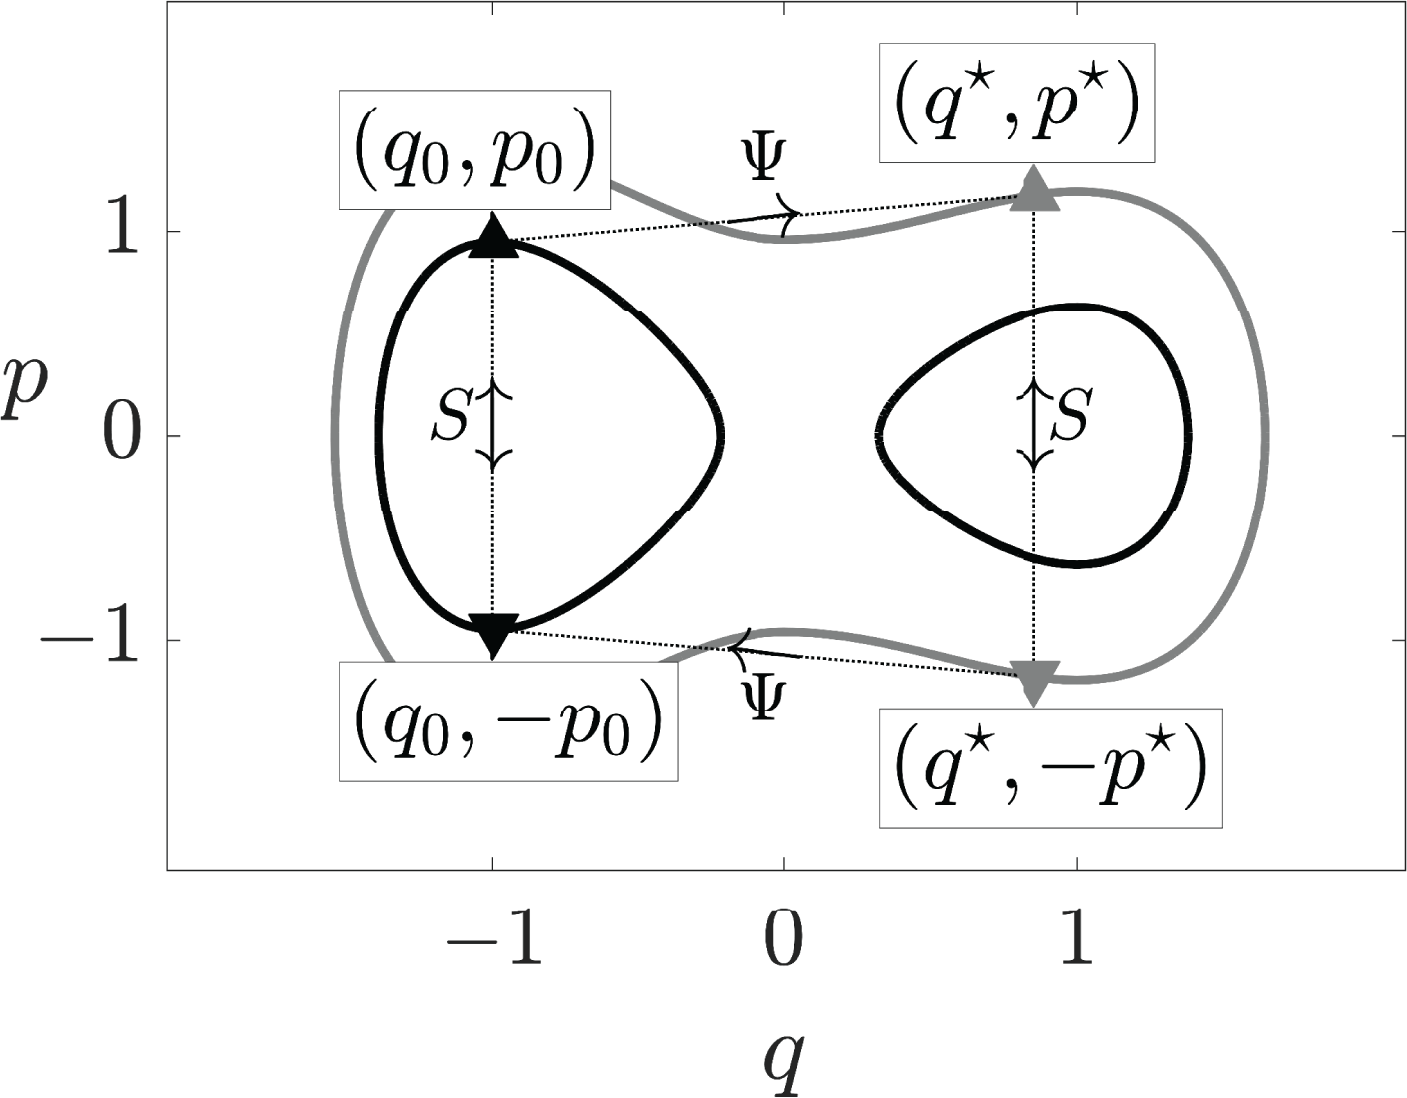
Figure 6.1 (see page 160) illustrates the reversibility of the Hamiltonian flow corresponding to a one-degree-of-freedom double-well potential.
As is the case for Hamiltonian systems, reversible systems have flows with special geometric properties, not shared by ‘general’ systems (Lamb and Roberts Reference Lamb and Roberts1998).
2.4 The Lie bracket
If
 $\unicode[STIX]{x1D711}_{t}^{(f)}$
and
 $\unicode[STIX]{x1D711}_{t}^{(g)}$
denote respectively the flows of the
 $D$
-dimensional systems
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}x=f(x),\quad \displaystyle \frac{\text{d}}{\text{d}t}x=g(x),\end{eqnarray}$$
in general
 $\unicode[STIX]{x1D711}_{s}^{(g)}\circ \unicode[STIX]{x1D711}_{t}^{(f)}\neq \unicode[STIX]{x1D711}_{t}^{(f)}\circ \unicode[STIX]{x1D711}_{s}^{(g)}$
; in fact, a Taylor expansion shows that, as
 $t$
,
 $s$
approach
 $0$
,
 $$\begin{eqnarray}\unicode[STIX]{x1D711}_{s}^{(g)}(\unicode[STIX]{x1D711}_{t}^{(f)}(x))-\unicode[STIX]{x1D711}_{t}^{(f)}(\unicode[STIX]{x1D711}_{s}^{(g)}(x))=st\,[f,g](x)+O(t^{3}+s^{3}),\end{eqnarray}$$
where the Lie bracket (or Lie–Jacobi bracket or commutator)
 $[f,g]$
of
 $f$
and
 $g$
(Arnol’d Reference Arnol’d1989, Section 39) is the mapping
 $\mathbb{R}^{D}\rightarrow \mathbb{R}^{D}$
that at
 $x\in \mathbb{R}^{D}$
takes the value
 $$\begin{eqnarray}[f,g](x)=g^{\prime }(x)f(x)-f^{\prime }(x)g(x).\end{eqnarray}$$
Thus the magnitude of
 $[f,g]$
measures the lack of commutativity of the corresponding flows. The following result holds.
Theorem 2.12. With the preceding notation,
 $\unicode[STIX]{x1D711}_{s}^{(g)}\circ \unicode[STIX]{x1D711}_{t}^{(f)}=\unicode[STIX]{x1D711}_{t}^{(f)}\circ \unicode[STIX]{x1D711}_{s}^{(g)}$
for arbitrary
 $t$
and
 $s$
if and only if the Lie bracket
 $[f,g](x)$
vanishes at each
 $x\in \mathbb{R}^{D}$
. When these conditions hold, we say that
 $f$
and
 $g$
commute.
For commuting
 $f$
and
 $g$
,
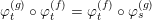 $\unicode[STIX]{x1D711}_{t}^{(g)}\circ \unicode[STIX]{x1D711}_{t}^{(f)}=\unicode[STIX]{x1D711}_{t}^{(f)}\circ \unicode[STIX]{x1D711}_{s}^{(g)}$
provides the
 $t$
flow of the system
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}x=f(x)+g(x).\end{eqnarray}$$
The Lie bracket is skew-symmetric:
 $[f,g]=-[g,f]$
for arbitrary
 $f$
and
 $g$
. In addition, it satisfies the Jacobi identity,
 $$\begin{eqnarray}[f_{1},[f_{2},f_{3}]]+[f_{2},[f_{3},f_{1}]]+[f_{3},[f_{1},f_{2}]]=0,\end{eqnarray}$$
for any
 $f_{1}$
,
 $f_{2}$
,
 $f_{3}$
. In this way the vector space of all vector fields together with the operation
 $[\cdot ,\cdot ]$
is a Lie algebra.
For Hamiltonian systems it is possible to work in terms of the so-called Poisson bracket of the Hamiltonian functions (Arnol’d Reference Arnol’d1989, Section 40), rather than in terms of the Lie bracket of the fields.
Theorem 2.13. If the fields
 $f$
and
 $g$
are Hamiltonian with Hamiltonian functions
 $H$
and
 $K$
respectively, that is,
 $f=J^{-1}\unicode[STIX]{x1D6FB}H$
,
 $g=J^{-1}\unicode[STIX]{x1D6FB}K$
, then
 $[f,g]$
is also a Hamiltonian vector field. Moreover, the Hamiltonian function of
 $[f,g]$
is given by
 $-\{H,K\}$
,Footnote
2
where
 $\{H,K\}$
is the Poisson bracket of the functions
 $H$
and
 $K$
, defined as
 $$\begin{eqnarray}\{H,K\}=(\unicode[STIX]{x1D6FB}H)^{T}J^{-1}\unicode[STIX]{x1D6FB}K.\end{eqnarray}$$
For real-valued functions in
 $\mathbb{R}^{2d}$
, the Poisson bracket operation is skew-symmetric, that is,
 $\{H,K\}=-\{K,H\}$
, and satisfies the Jacobi identity
 $$\begin{eqnarray}\{H_{1},\{H_{2},H_{3}\}\}+\{H_{2},\{H_{3},H_{1}\}\}+\{H_{3},\{H_{1},H_{2}\}\}=0.\end{eqnarray}$$
Let
 $f$
and
 $g$
be reversible vector fields. Differentiation in
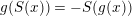 $g(S(x))=-S(g(x))$
implies for the Jacobian that
 $g^{\prime }(S(x))S=-S(g^{\prime }(x))$
, and it follows that
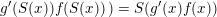 $g^{\prime }(S(x))f(S(x)))=S(g^{\prime }(x)f(x))$
(no minus sign!). Then the Lie bracket of two reversible fields is not reversible, but rather satisfies the following property.
Proposition 2.14. If two vector fields
 $f$
and
 $g$
are
 $S$
-reversible, then
 $$\begin{eqnarray}[f,g](S(x))=S([f,g](x)).\end{eqnarray}$$
For three
 $S$
-reversible vector fields, the iterated commutator
 $[f_{1},[f_{2},f_{3}]]$
is
 $S$
-reversible.
3 Integrators
In the sampling algorithms studied later, differential systems like (2.1) or (2.2) have to be numerically integrated. In this section we review the required material. Hairer, Nørsett and Wanner (Reference Hairer, Nørsett and Wanner1993), Hairer and Wanner (Reference Hairer and Wanner2010) and Butcher (Reference Butcher2016) provide extensive, authoritative treatises on the subject. A more concise introduction is given by Griffiths and Higham (Reference Griffiths and Higham2010). We begin by recalling some basic definitions, and later focus on splitting integrators and fixed
 $h$
stability, as both play important roles in the implementation of HMC algorithms.
3.1 Preliminaries
Each one-step numerical method or one-step integrator for (2.1) is described by a map
 $\unicode[STIX]{x1D713}_{h}:\mathbb{R}^{D}\rightarrow \mathbb{R}^{D}$
that depends on a real parameter
 $h$
, the step size. Given the initial value
 $\unicode[STIX]{x1D6FC}$
, and a value of
 $h$
(
 $h\neq 0$
), the integrator generates a numerical trajectory,
 $x_{0},x_{1},x_{2},\ldots ,$
defined by
 $x_{0}=\unicode[STIX]{x1D6FC}$
and, iteratively,
 $$\begin{eqnarray}x_{n+1}=\unicode[STIX]{x1D713}_{h}(x_{n}),\quad n=0,1,2,\ldots .\end{eqnarray}$$
To compute
 $x_{n+1}$
when
 $x_{n}$
has already been found is to perform a (time) step. For each
 $n$
, the vector
 $x_{n}$
is an approximation to the value at time
 $t_{n}=nh$
of the solution
 $x(t)$
of (2.1) with initial condition
 $x(0)=\unicode[STIX]{x1D6FC}$
, i.e. to
 $\unicode[STIX]{x1D711}_{t_{n}}(\unicode[STIX]{x1D6FC})$
. Typically
 $h$
is positive and then the integration is forward in time
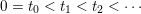 $0=t_{0}<t_{1}<t_{2}<\cdots \,$
, but in some applications it may be of interest to use
 $h<0$
so as to get
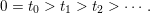 $0=t_{0}>t_{1}>t_{2}>\cdots \,.$
The simplest and best known integrator, Euler’s rule, with
 $$\begin{eqnarray}x_{n+1}=x_{n}+hf(x_{n}),\end{eqnarray}$$
corresponds to the mapping
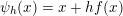 $\unicode[STIX]{x1D713}_{h}(x)=x+hf(x)$
. It uses one evaluation of
 $f$
per step. Explicit
 $s$
-stage Runge–Kutta formulas use
 $s$
evaluations of
 $f$
per step,
 $s=1,2,\ldots ,$
and are therefore
 $s$
times more expensive per step than Euler’s rule; examples include Runge’s method
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}(x)=x+hf\biggl(x+\displaystyle \frac{h}{2}f(x)\biggr)\end{eqnarray}$$
(with two stages), several well-known formulas of Kutta with four stagesFootnote
3
and the formulas within the popular MATLAB function ode45. A method with
 $s$
stages will be competitive with Euler’s rule only if it gives more accurate approximations than Euler’s rule when this is operated with a step size
 $s$
times shorter, so as to equalize computational costs.
Implicit Runge–Kutta integrators are also used in practice, and then
 $\unicode[STIX]{x1D713}_{h}$
is defined by means of algebraic equations. For instance, the midpoint rule has
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}(x)=x+hf\biggl(\displaystyle \frac{1}{2}(x+\unicode[STIX]{x1D713}_{h}(x))\biggr),\end{eqnarray}$$
that is,
 $$\begin{eqnarray}x_{n+1}=x_{n}+hf\biggl(\displaystyle \frac{1}{2}(x_{n}+x_{n+1})\biggr).\end{eqnarray}$$
Here, computing
 $x_{n+1}$
when
 $x_{n}$
is already known requires us to solve a system of algebraic equations in
 $\mathbb{R}^{D}$
. There are many more useful examples of implicit Runge–Kutta methods, including the so-called Gauss methods.
Remark 3.1. Note that in the formulas displayed above
 $h$
and
 $f$
do not appear separately, but always in the combination
 $hf$
. This clearly implies that, if, for a given method,
 $x_{n}$
,
 $n=0,1,2\ldots$
is a numerical trajectory with step size
 $h$
corresponding to the system (2.1), it is also a numerical trajectory with step size
 $\unicode[STIX]{x1D706}h$
for the system
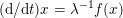 $(\text{d}/\text{d}t)x=\unicode[STIX]{x1D706}^{-1}f(x)$
(
 $\unicode[STIX]{x1D706}\neq 0$
denotes a constant). We shall always assume that we deal with integrators having this property.
A one-step integrator is called symmetric or self-adjoint Footnote 4 if
 $$\begin{eqnarray}(\unicode[STIX]{x1D713}_{h})^{-1}=\unicode[STIX]{x1D713}_{-h},\end{eqnarray}$$
so as to mimic the property (2.7) of the exact solution flow. The midpoint rule (3.3) provides an example. Explicit Runge–Kutta methods are never symmetric.
Multistep integrators, including the well-known Adams formulas, where the computation of
 $x_{n+1}$
requires knowledge of
 $k\geq 2$
past values
 $x_{n},x_{n-1},$
 $\ldots ,x_{n-k+1}$
, may be very efficient, but will not be considered in this paper; they have seldom been applied in the context of sampling algorithms.
3.2 Order
Since, for the exact solution, the sequence
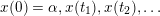 $x(0)=\unicode[STIX]{x1D6FC},x(t_{1}),x(t_{2}),\ldots$
satisfies
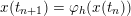 $x(t_{n+1})=\unicode[STIX]{x1D711}_{h}(x(t_{n}))$
,
 $n=0,1,\ldots ,$
rather than (3.1), for the numerical integrator to make sense it is necessary that
 $\unicode[STIX]{x1D713}_{h}$
be an approximation to
 $\unicode[STIX]{x1D711}_{h}$
. The integrator is said to be consistent if, at each fixed
 $x\in \mathbb{R}^{D}$
,
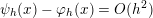 $\unicode[STIX]{x1D713}_{h}(x)-\unicode[STIX]{x1D711}_{h}(x)=O(h^{2})$
as
 $h\rightarrow 0$
. If
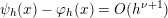 $\unicode[STIX]{x1D713}_{h}(x)-\unicode[STIX]{x1D711}_{h}(x)=O(h^{\unicode[STIX]{x1D708}+1})$
,
 $\unicode[STIX]{x1D708}$
a positive integer, then the integrator is (consistent) of order
 $\geq \unicode[STIX]{x1D708}$
. A method of order
 $\geq \unicode[STIX]{x1D708}$
that is not of order
 $\geq \unicode[STIX]{x1D708}+1$
is said to have order
 $\unicode[STIX]{x1D708}$
. Euler’s rule (3.2) has order 1, the four-stage formulas of Kutta have order 4 and the midpoint rule (3.3) has order 2. We shall see later (Theorem 4.7) that the order of a symmetric integrator is an even integer. All integrators to be considered hereafter are assumed to be consistent.
The vector
 $\unicode[STIX]{x1D713}_{h}(x)-\unicode[STIX]{x1D711}_{h}(x)$
is called the local error at
 $x$
: it is the difference between the result of a single time-step of the numerical method starting from
 $x$
and the result of the application of the
 $h$
-flow to the same point
 $x$
. For future reference, we note that the expansion of the local error for Euler’s method is given by
 $$\begin{eqnarray}\displaystyle \unicode[STIX]{x1D713}_{h}(x)-\unicode[STIX]{x1D711}_{h}(x) & = & \displaystyle (x+hf(x))-\biggl(x+hf(x)+\displaystyle \frac{h^{2}}{2}f^{\prime }(x)f(x)+O(h^{3})\biggr)\nonumber\\ \displaystyle & = & \displaystyle -\displaystyle \frac{h^{2}}{2}f^{\prime }(x)f(x)+O(h^{3}).\end{eqnarray}$$
In the expansion of the true solution flow we have used that
 $(\text{d}/\text{d}t)x=f(x)$
and
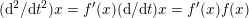 $(\text{d}^{2}/\text{d}t^{2})x=f^{\prime }(x)(\text{d}/\text{d}t)x=f^{\prime }(x)f(x)$
.
The local error does not per se give information on the global error at
 $t_{n}$
, i.e. on the difference
 $x_{n}-x(t_{n})$
. This is because
 $x_{n}=\unicode[STIX]{x1D713}_{h}(x_{n-1})$
while
 $x(t_{n})$
is the result of the application of the
 $h$
-flow to
 $x(t_{n-1})$
:
 $\unicode[STIX]{x1D713}_{h}$
and
 $\unicode[STIX]{x1D711}_{h}$
are not applied to the same point.Footnote
5
However, the following result holds.
Theorem 3.2. If the (one-step) integrator is consistent of order
 $\unicode[STIX]{x1D708}$
, then, for each fixed initial value
 $x_{0}=x(0)$
and
 $T>0$
,
 $$\begin{eqnarray}\max _{0\leq t_{n}\leq T}|x_{n}-x(t_{n})|=O(h^{\unicode[STIX]{x1D708}}),\quad h\rightarrow 0+.\end{eqnarray}$$
This expresses the fact that the integrator is convergent of order
 $\unicode[STIX]{x1D708}$
. Of course, the corresponding result holds if the integration is carried out backward in time over
 $-T\leq t\leq 0$
.
Remark 3.3. The global errors
 $x_{n}-x(t_{n})$
, in addition to possessing an
 $O(h^{\unicode[STIX]{x1D708}})$
bound as above, have an asymptotic expansion in powers of
 $h$
. For instance, if we restrict the attention to the leading
 $h^{\unicode[STIX]{x1D708}}$
-term in the expansion, we have
 $$\begin{eqnarray}x_{n}-x(t_{n})=h^{\unicode[STIX]{x1D708}}a(x(0),t_{n})+h^{\unicode[STIX]{x1D708}}r(x(0),t_{n};h),\end{eqnarray}$$
where the function
 $a$
is independent of
 $h$
and, for each fixed initial value
 $x(0)$
,
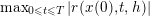 $\max _{0\leq t\leq T}|r(x(0),t,h)|$
tends to
 $0$
as
 $h\rightarrow 0\!+$
. Thus, for
 $h$
sufficiently small, the global error is approximately equal to
 $h^{\unicode[STIX]{x1D708}}a(x(0),t_{n})$
: halving
 $h$
divides the error by a factor
 $2^{\unicode[STIX]{x1D708}}$
.
Remark 3.4. In the description above, the step points
 $t_{n}$
are uniformly spaced. General-purpose software uses variable time-steps:
 $t_{n+1}=t_{n}+h_{n}$
where
 $h_{n}$
changes with
 $n$
. For each
 $n$
, the value of
 $h_{n}$
is chosen by the algorithm to ensure that the local error at
 $x_{n}$
is below a user-prescribed tolerance. Since, for reasons to be explained in Section 4, HMC integrations are carried out with constant step size, we shall not concern ourselves with variable step sizes.
3.3 Splitting methods
Euler’s method and the other integrators mentioned above may be applied to any given system (2.1). Other techniques only make sense for particular classes of systems and cannot therefore be incorporated into general-purpose software; however, they have gained much popularity in recent decades due, among other things, to their role in geometric integration (see Section 4). Of special importance to us is the class of splitting integrators that we consider next. Blanes and Casas (Reference Blanes and Casas2016) provide a very good source of information.
3.3.1 The Lie–Trotter formula
Splitting methods are applicable to cases where the right-hand side of (2.1) may be split into two parts,
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}x=f(x)=f^{(\text{A})}(x)+f^{(\text{B})}(x),\end{eqnarray}$$
in such a way that the flows
 $\unicode[STIX]{x1D711}_{t}^{(\text{A})}$
and
 $\unicode[STIX]{x1D711}_{t}^{(\text{B})}$
of the split systems
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}x=f^{(\text{A})}(x),\quad \displaystyle \frac{\text{d}}{\text{d}t}x=f^{(\text{B})}(x),\end{eqnarray}$$
are available analytically. To avoid trivial cases, we shall hereafter assume that the Lie bracket
 $[f^{(\text{A})},f^{(\text{B})}]$
does not vanish identically, because otherwise Theorem 2.12 shows that (3.7) may also be solved analytically without resorting to numerical approximations.
Systems of the particular form (2.2) provide an important example. When they are split by taking
 $$\begin{eqnarray}\displaystyle (\text{A})\qquad \displaystyle \frac{\text{d}}{\text{d}t}q & = & \displaystyle M^{-1}p,\quad \displaystyle \frac{\text{d}}{\text{d}t}p=0\end{eqnarray}$$
and
 $$\begin{eqnarray}\displaystyle (\text{B})\qquad \displaystyle \frac{\text{d}}{\text{d}t}q & =0,\quad \displaystyle \frac{\text{d}}{\text{d}t}p=F(q), & \displaystyle\end{eqnarray}$$
the flows are explicitly given by
 $$\begin{eqnarray}\unicode[STIX]{x1D711}_{t}^{(\text{A})}(q,p)=(q+tM^{-1}p,p)\end{eqnarray}$$
and
 $$\begin{eqnarray}\unicode[STIX]{x1D711}_{t}^{(\text{B})}(q,p)=(q,p+tF(q)).\end{eqnarray}$$
In molecular dynamics (Schlick Reference Schlick2002) these mappings are respectively called a drift (
 $q$
advances with constant speed and the momentum
 $p$
remains constant) and a kick (the system stays in its current configuration, and the momentum is incremented by the action of the force). A direct computation of the Lie bracket shows that, except in the trivial case where
 $F$
vanishes identically, the vector fields in (3.9)–(3.10) do not commute.
A simple Taylor expansion proves that the Lie–Trotter formula
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}=\unicode[STIX]{x1D711}_{h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{A})}\end{eqnarray}$$
defines a first-order integrator for (3.7):
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}(x)-\unicode[STIX]{x1D711}_{h}(x)=\displaystyle \frac{h^{2}}{2}[f^{(\text{A})},f^{(\text{B})}](x)+O(h^{3}).\end{eqnarray}$$
(Observe that, not unexpectedly, the coefficient of the leading power of
 $h$
is proportional to the Lie bracket.) While
 $f^{(\text{A})}$
and
 $f^{(\text{B})}$
contribute simultaneously to the change of
 $x$
in (3.7), they do so successively in the Lie–Trotter integrator. By swapping the roles of
 $\text{A}$
and
 $\text{B}$
, we have the alternative integrator
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}=\unicode[STIX]{x1D711}_{h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{B})}.\end{eqnarray}$$
3.3.2 Strang’s formula
The most popular splitting integrator for (3.7) corresponds to Strang’s formula (Strang Reference Strang1963)
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}=\unicode[STIX]{x1D711}_{(1/2)h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{(1/2)h}^{(\text{B})}\end{eqnarray}$$
and, as a Taylor expansion shows, has second-order accuracy,
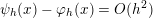 $\unicode[STIX]{x1D713}_{h}(x)-\unicode[STIX]{x1D711}_{h}(x)=O(h^{2})$
as
 $h\rightarrow 0$
. More precisely,
 $$\begin{eqnarray}\displaystyle \unicode[STIX]{x1D713}_{h}(x)-\unicode[STIX]{x1D711}_{h}(x) & = & \displaystyle \displaystyle \frac{h^{3}}{12}[f^{(\text{A})},[f^{(\text{A})},f^{(\text{B})}]](x)\nonumber\\ \displaystyle & & \displaystyle \quad +\,\displaystyle \frac{h^{3}}{24}[f^{(\text{B})},[f^{(\text{A})},f^{(\text{B})}]](x)+O(h^{4}),\end{eqnarray}$$
so that the leading term of the local error is a linear combination of two so-called iterated Lie brackets.
When applied to the particular case (2.2), the formula (3.13) yields the well-known velocity Verlet integrator, the method of choice in molecular dynamics; the step
 $n\rightarrow n+1$
comprises two kicks of duration
 $h/2$
separated by a drift of duration
 $h$
:
 $$\begin{eqnarray}\displaystyle p_{n+1/2} & = & \displaystyle p_{n}+\displaystyle \frac{h}{2}F(q_{n}),\nonumber\\ \displaystyle q_{n+1} & = & \displaystyle q_{n}+hM^{-1}p_{n+1/2},\nonumber\\ \displaystyle p_{n+1} & = & \displaystyle p_{n+1/2}+\displaystyle \frac{h}{2}F(q_{n+1}).\nonumber\end{eqnarray}$$
The evaluations of
 $F$
represent the bulk of the computational cost of the algorithm. The value
 $F(q_{n+1})$
to be used in the first kick of the next step,
 $n+1\rightarrow n+2$
, is the same used in the second kick of the current step. In this way, while the very first step requires two evaluations of
 $F$
, subsequent steps only need one.
When
 $N$
steps of the method (3.13) are taken, the map that advances the numerical solution from
 $x_{0}$
to
 $x_{N}$
, that is,
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}^{N}=\overbrace{(\unicode[STIX]{x1D711}_{(1/2)h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{(1/2)h}^{(\text{B})})\circ \cdots \circ (\unicode[STIX]{x1D711}_{(1/2)h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{(1/2)h}^{(\text{B})})}^{N\text{ times}},\end{eqnarray}$$
may be rewritten with the help of the group property (2.6) in the leapfrog form
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}^{N}=\unicode[STIX]{x1D711}_{(1/2)h}^{(\text{B})}\circ \overbrace{(\unicode[STIX]{x1D711}_{h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{B})})\circ \cdots \circ (\unicode[STIX]{x1D711}_{h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{B})})}^{N-1\text{ times}}\circ \,\unicode[STIX]{x1D711}_{h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{(1/2)h}^{(\text{B})};\end{eqnarray}$$
now the right-hand side only uses
 $N+1$
times the flow
 $\unicode[STIX]{x1D711}_{t}^{(\text{B})}$
. In the particular case (3.9)–(3.10), the combination
 $\unicode[STIX]{x1D711}_{h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{B})}$
corresponds to the following formulas to advance the numerical solution,
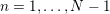 $n=1,\ldots ,N-1$
:
 $$\begin{eqnarray}\displaystyle p_{n+1/2} & =p_{n-1/2}+hF(q_{n}), & \displaystyle \nonumber\\ \displaystyle q_{n+1} & =q_{n}+hM^{-1}p_{n+1/2}; & \displaystyle \nonumber\end{eqnarray}$$
 $p$
jumps over
 $q$
and then
 $q$
jumps over
 $p$
like children playing leapfrog. The leapfrog implementation makes apparent the truth of an earlier observation:
 $N$
steps of the velocity Verlet integrator may be implemented with
 $N+1$
evaluations of
 $F$
.
Strang’s method is symmetric:
 $$\begin{eqnarray}\displaystyle (\unicode[STIX]{x1D713}_{h})^{-1} & = & \displaystyle (\unicode[STIX]{x1D711}_{(1/2)h}^{(\text{B})})^{-1}\!\circ (\unicode[STIX]{x1D711}_{h}^{(\text{A})})^{-1}\!\circ (\unicode[STIX]{x1D711}_{(1/2)h}^{(\text{B})})^{-1}\nonumber\\ \displaystyle & = & \displaystyle \unicode[STIX]{x1D711}_{-(1/2)h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{-h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{-(1/2)h}^{(\text{B})}\nonumber\\ \displaystyle & = & \displaystyle \unicode[STIX]{x1D713}_{-h}.\nonumber\end{eqnarray}$$
It is clear that the symmetry is a consequence of the palindromic structure of (3.13), that is, the formula reads the same from left to right as from right to left.
The roles of
 $\text{A}$
and
 $\text{B}$
in (3.13) may be interchanged:
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}=\unicode[STIX]{x1D711}_{(1/2)h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{(1/2)h}^{(\text{A})}.\end{eqnarray}$$
For (3.9)–(3.10) one then obtains the position Verlet integrator: one step comprises two drifts of duration
 $h/2$
and one kick of duration
 $h$
.
3.3.3 Splitting formulas with more stages
It is of course possible to use splitting formulas more sophisticated than Strang’s. For instance, for any choice of the real parameter
 $b$
, we may consider the integrator
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}=\unicode[STIX]{x1D711}_{bh}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{(1/2)h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{(1-2b)h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{(1/2)h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{bh}^{(\text{B})},\end{eqnarray}$$
where we observe that, in one step, the
 $\text{A}$
and
 $\text{B}$
flows of the systems (3.8) act for a total duration of
 $h$
units of time each to ensure consistency. Due to its palindromic structure, this integrator is symmetric, and from Theorem 4.7 its order is at least two. It turns out that the order is exactly two for all choices of
 $b$
(Blanes, Casas and Sanz-Serna Reference Blanes, Casas and Sanz-Serna2014). The order of splitting integrators is discussed later in relation to the concept of modified equations.
Even though three
 $\text{B}$
flows and two
 $\text{A}$
flows feature in (3.16),
 $N$
steps of the integrator only require the computation of
 $2N+1$
 $\text{B}$
flows and
 $2N$
 $\text{A}$
flows; this is seen by combining flows as we did above for the Strang case. We say that (3.16) is a palindromic two-stage integrator.Footnote
6
The method (3.16) may be denoted by
 $$\begin{eqnarray}(b,1/2,(1-2b),1/2,b).\end{eqnarray}$$
Similarly, one may consider the two-parameter family of palindromic three-stage splittings
 $$\begin{eqnarray}(b,a,1/2-b,1-2a,1/2-b,a,b).\end{eqnarray}$$
A full description of this family is given by Campos and Sanz-Serna (Reference Campos and Sanz-Serna2017), who suggest parameter choices for various applications. There is a unique choice of
 $a$
and
 $b$
resulting in a fourth-order method often associated with Yoshida’s name (Yoshida Reference Yoshida1990); for all other choices, the order is
 $\unicode[STIX]{x1D708}=2$
.
The family of palindromic
 $s$
-stage splitting formulas is given by
 $$\begin{eqnarray}(b_{1},a_{1},b_{2},a_{2},\ldots ,a_{s^{\prime }},b_{s^{\prime }+1},a_{s^{\prime }},\ldots ,a_{2},b_{2},a_{1},b_{1})\end{eqnarray}$$
if
 $s=2s^{\prime }$
is even, and by
 $$\begin{eqnarray}(b_{1},a_{1},b_{2},a_{2},\ldots ,b_{s^{\prime }},a_{s^{\prime }},b_{s^{\prime }},\ldots ,a_{2},b_{2},a_{1},b_{1})\end{eqnarray}$$
if
 $s=2s^{\prime }-1$
. After imposing the consistency requirement that at each step the
 $\text{A}$
and
 $\text{B}$
flows act during
 $h$
units of time each, the family has
 $s-1$
parameters left. By taking
 $s$
sufficiently high it is possible to achieve any desired order (Sanz-Serna and Calvo Reference Sanz-Serna and Calvo1994, Section 13.1). Clearly, increasing the number of stages does not lead to integrators with more complicated implementation; regardless of the value of
 $s$
, numerical integrations only consist of a sequence of flows of the split systems.
It is not necessary to add that to each of the integrators just described there corresponds a second integrator found by swapping the roles of the systems
 $\text{A}$
and
 $\text{B}$
, just as (3.15) corresponds to (3.13).
So far our attention has focused on palindromic formulas as these will be important later in connection with the property of reversibility (Theorem 4.2). It is also possible to consider splittings of the form
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}=\unicode[STIX]{x1D711}_{b_{r}h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{a_{r}h}^{(\text{A})}\circ \cdots \circ \unicode[STIX]{x1D711}_{b_{2}h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{a_{2}h}^{(\text{A})}\circ \unicode[STIX]{x1D711}_{b_{1}h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{a_{1}h}^{(\text{A})},\end{eqnarray}$$
which we denote as
 $$\begin{eqnarray}(b_{r},a_{r},\ldots ,b_{2},a_{2},b_{1},a_{1})\end{eqnarray}$$
(
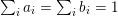 $\sum _{i}a_{i}=\sum _{i}b_{i}=1$
). The palindromic formulas in (3.19)–(3.20) are particular instances of this general format because it is always possible to set
 $a_{1}=0$
in (3.21).
Remark 3.5. When a splitting integrator of the general form (3.21) is applied to the splitting (3.9)–(3.10) of the system (2.2), the result coincides with the application of a so-called symplectic, explicit Runge–Kutta–Nyström (RKN) method. The properties (order, stability, etc.) of such an integrator may therefore be studied either by using techniques pertaining to splitting integrators (as is done in this paper) or by employing an RKN approach. The second methodology was favoured in the early years of geometric integration (Sanz-Serna Reference Sanz-Serna1992, Sanz-Serna and Calvo Reference Sanz-Serna and Calvo1994).
3.4 Fixed
$h$
stability

If two numerical schemes are candidates to integrate an initial value problem for a given system (2.1), then the scheme that leads to smaller global errors for a given computational cost may seem more desirable (but, in the context of geometric integration, the geometric properties may play a role when choosing the integrator: see Section 4 below). Even though global errors may be bounded as in (3.6), in practice it is almost always impossible, for the problem at hand, to estimate realistically the error constant implied in the
 $O(h^{\unicode[STIX]{x1D708}})$
notation in the bound. For this reason, the literature on numerical integrators has traditionally resorted to well-chosen model problems where both the numerical and true solutions,
 $x_{n}$
and
 $x(t_{n})$
, may be written down in closed form; the performance of the various integrators on the model problem may then be investigated analytically and is taken as an indication of their performance when applied to realistic problems. Note that the actual numerical solution of the model problem cannot be expected to be of real practical interest, since in that problem the true solution is available analytically.
3.4.1 One degree of freedom
For our purposes, the model problem of choice is the harmonic oscillator (2.3). For Runge–Kutta methods, for the splitting algorithms in Section 3.3 (and in fact for all one-step integrators of practical interest) a time-step
 $(q_{n+1},p_{n+1})=\unicode[STIX]{x1D713}_{h}(q_{n},p_{n})$
may be expressed as
 $$\begin{eqnarray}\left[\begin{array}{@{}c@{}}q_{n+1}\\ p_{n+1}\end{array}\right]=\tilde{M}_{h}\left[\begin{array}{@{}c@{}}q_{n}\\ p_{n}\end{array}\right]\!,\quad \tilde{M}_{h}=\left[\begin{array}{@{}cc@{}}A_{h} & B_{h}\\ C_{h} & D_{h}\end{array}\right]\end{eqnarray}$$
for suitable method-dependent coefficients
 $A_{h}$
,
 $B_{h}$
,
 $C_{h}$
,
 $D_{h}$
. The evolution over
 $n$
time-steps is then given by
 $$\begin{eqnarray}\left[\begin{array}{@{}c@{}}q_{n}\\ p_{n}\end{array}\right]=\tilde{M}_{h}^{n}\left[\begin{array}{@{}c@{}}q_{0}\\ p_{0}\end{array}\right]\!,\end{eqnarray}$$
an expression to be compared with (2.4).
If a given
 $h>0$
is such that
 $|\tilde{M}_{h}^{n}|\rightarrow \infty$
as
 $n\rightarrow \infty$
, the magnitude of numerical solution
 $(q_{n},p_{n})$
will grow unboundedly, while the true solution of course remains bounded as
 $t\rightarrow \infty$
. Necessarily, global errors will be large for large
 $n$
. Then the integrator is said to be unstable for that particular choice of
 $h$
.
Example 3.6. For Euler’s rule (3.2) we find
 $$\begin{eqnarray}A_{h}=D_{h}=1,\quad B_{h}=-C_{h}=h.\end{eqnarray}$$
The eigenvalues of
 $\tilde{M}_{h}$
are
 $1\pm \text{i}h$
with modulus
 $(1+h^{2})^{1/2}$
and, therefore, for any fixed
 $h>0$
, the powers
 $\tilde{M}_{h}^{n}$
grow exponentially as
 $n$
increases. Due to this numerical instability, Euler’s rule is completely unsuitable for integrating the harmonic oscillator, and this rules it out as a method to integrate more complicated oscillatory problems.
More precisely, in the step
 $n\rightarrow n+1$
, the radius
 $r=(q^{2}+p^{2})^{1/2}$
, which remains constant for the true solution, grows like
 $$\begin{eqnarray}r_{n+1}=(1+h^{2})^{1/2}r_{n}=\biggl(1+\displaystyle \frac{h^{2}}{2}+O(h^{4})\biggr)r_{n}\end{eqnarray}$$
for the Euler solution, so that
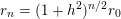 $r_{n}=(1+h^{2})^{n/2}r_{0}$
. Note that, taking limits as
 $n\rightarrow \infty$
,
 $h\rightarrow 0$
, with fixed
 $nh$
, we find
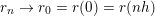 $r_{n}\rightarrow r_{0}=r(0)=r(nh)$
, as it corresponds to a convergent method.
Example 3.7. The midpoint rule (3.3) has
 $$\begin{eqnarray}A_{h}=D_{h}=\displaystyle \frac{1-h^{2}/4}{1+h^{2}/4},\quad B_{h}=-C_{h}=\displaystyle \frac{h}{1+h^{2}/4}.\end{eqnarray}$$
The characteristic equation of
 $\tilde{M}_{h}$
is
 $$\begin{eqnarray}\unicode[STIX]{x1D706}^{2}-2A_{h}\unicode[STIX]{x1D706}+1,\end{eqnarray}$$
and therefore the product of the eigenvalues is 1. For
 $h\neq 0$
,
 $|A_{h}|<1$
and the matrix has a pair of complex conjugate eigenvalues of unit modulus. Then the powers
 $\tilde{M}_{h}^{n}$
remain bounded as
 $n$
increases and the method is stable for any
 $h$
.
Example 3.8. Let us next consider Strang’s splitting (3.13), applied with the splitting (3.9)–(3.10), which yields the velocity Verlet algorithm. This has
 $$\begin{eqnarray}A_{h}=D_{h}=1-h^{2}/2,\quad B_{h}=h,\quad C_{h}=-h+h^{3}/4;\end{eqnarray}$$
the characteristic equation is again of the form (3.25). For
 $h>2$
,
 $A_{h}<-1$
and the eigenvalues are real and distinct, so that one of them has modulus
 ${>}1$
, and therefore the powers
 $\tilde{M}_{h}^{n}$
grow exponentially. For
 $h<2$
the eigenvalues are complex of unit modulus and the powers
 $\tilde{M}_{h}^{n}$
remain bounded. For
 $h=2$
,
 $\tilde{M}_{h}$
is a non-trivial Jordan block whose powers grow linearly (weak instability). To summarize, the integrator is unstable for
 $h\geq 2$
and has the stability interval
 $0<h<2$
. Integrations with
 $h>2$
lead to extremely large global errors, as we shall see below.
Example 3.9. For the alternative Strang formula (3.15), which yields the position Verlet algorithm, the coefficients are
 $$\begin{eqnarray}A_{h}=D_{h}=1-h^{2}/2,\quad B_{h}=h-h^{3}/4,\quad C_{h}=-h.\end{eqnarray}$$
The discussion is almost identical to the one in the preceding example. The stability interval is also
 $0<h<2$
, as one may have guessed from the equal role that
 $q$
and
 $-p$
play in the harmonic oscillator (2.3).
Velocity Verlet integration of the harmonic oscillator. Relative errors after one or ten oscillation periods.

Example 3.10. In the situation of Example 3.8, are values of
 $h$
below the upper limit 2 satisfactory? The answer of course depends on the accuracy required. For the initial condition
 $q=1$
,
 $p=0$
, and different stable values of
 $h$
, Table 3.1 gives the relative error in the Euclidean norm
 $$\begin{eqnarray}\displaystyle \frac{|(q_{n}-q(t_{n}),p_{n}-p(t_{n}))|}{|(q(t_{n}),p(t_{n}))|}\end{eqnarray}$$
at the final integration time, when the integration is carried out over an interval of length either one oscillation period (second column) or ten oscillation periods (third column). Columns are consistent with the order of convergence as in (3.6). The last rows reveal that the error increases linearly with
 $t$
(this will not be true when integrating other differential systems). In the first row the error grows more slowly than
 $t$
: the numerical solution
 $(q_{n},p_{n})$
remains close to the unit circle for all values of
 $n$
and therefore errors cannot be substantially larger than the diameter of the circle. From the table we see that if we are interested in errors below
 $10\%$
over an interval of length equal to ten oscillation periods, then
 $h$
has to be taken below
 $2\unicode[STIX]{x1D70B}/32\approx 0.20$
, that is, well below the upper end,
 $h=2$
, of the stability interval. To provide an indication of the effect of using unstable values of
 $h$
, we mention that with
 $h=\unicode[STIX]{x1D70B}$
the error after one period is
 ${\approx}46.4$
and after ten periods
 ${\approx}4.68\times 10^{17}$
.
Before we move to more complicated models, let us make two observations, valid for Runge–Kutta, splitting integrators and any other method of practical interest.
Remark 3.11. Because the problem is linear and rotationally invariant, the magnitude of the relative errors is independent of the initial condition
 $(q_{0},p_{0})\neq (0,0)$
.
Remark 3.12. Replacing the model (2.3) with the apparently more general system
 $$\begin{eqnarray}\displaystyle \frac{\text{d}q}{\text{d}t}=\unicode[STIX]{x1D714}p,\quad \displaystyle \frac{\text{d}p}{\text{d}t}=-\unicode[STIX]{x1D714}q,\quad \unicode[STIX]{x1D714}>0,\end{eqnarray}$$
with oscillation period
 $2\unicode[STIX]{x1D70B}/\unicode[STIX]{x1D714}$
, does not really change things: in view of Remark 3.1, integrating (3.26) with step size
 $h$
is equivalent to integrating (2.3) with step size
 $h/\unicode[STIX]{x1D714}$
. Because the length of the integration interval and the step size in Table 3.1 are given in terms of the oscillation period, the results displayed are valid for (3.26) for any choice of the value of
 $\unicode[STIX]{x1D714}$
. Regardless of the initial condition, if we are interested in relative errors below
 $10\%$
over an interval of length
 $20\unicode[STIX]{x1D70B}/\unicode[STIX]{x1D714}$
(equal to ten oscillation periods), then
 $h$
has to be taken below
 $2\unicode[STIX]{x1D70B}/(32\unicode[STIX]{x1D714})$
. Of course, for (3.26), stability requires that
 $h<2/\unicode[STIX]{x1D714}$
.
3.4.2 Several degrees of freedom; stability restrictions on
$h$

Let us now move to the model with
 $d$
degrees of freedom,
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}q=M^{-1}p,\quad \displaystyle \frac{\text{d}}{\text{d}t}p=-Kq,\end{eqnarray}$$
where
 $M$
and
 $K$
are
 $d\times d$
, symmetric positive-definite matrices. This is the Hamiltonian system with
 $$\begin{eqnarray}H=\displaystyle \frac{1}{2}p^{T}M^{-1}p+\displaystyle \frac{1}{2}q^{T}Kq.\end{eqnarray}$$
In mechanics,
 $M$
and
 $K$
are the mass and stiffness matrices respectively.
This model may transformed into
 $d$
uncoupled one-degree-of-freedom oscillators. In fact, factor
 $M=LL^{T}$
(which may be done in infinitely many ways) and diagonalize the symmetric positive-definite matrix
 $L^{-1}KL^{-T}$
as
 $U^{T}L^{-1}KL^{-T}U=\unicode[STIX]{x1D6FA}^{2}$
, with
 $U$
orthogonal and
 $\unicode[STIX]{x1D6FA}$
diagonal with diagonal entries
 $\unicode[STIX]{x1D714}_{i}$
,
 $i=1,\ldots ,d$
. A simple computation yields the next result.
Proposition 3.13. With the notation above, the (non-canonical) change of dependent variables,
 $q=L^{-T}U\bar{q}$
,
 $p=LU\unicode[STIX]{x1D6FA}\bar{p}$
, decouples the system into a collection of
 $d$
harmonic oscillators:
 $$\begin{eqnarray}\displaystyle \frac{\text{d}\bar{q}^{i}}{\text{d}t}=\unicode[STIX]{x1D714}_{i}\bar{p}^{i},\quad \displaystyle \frac{\text{d}\bar{p}^{i}}{\text{d}t}=-\unicode[STIX]{x1D714}_{i}\bar{q}^{i},\quad i=1,\ldots ,d\end{eqnarray}$$
(superscripts denote components).
Now, for all integrators of practical interest, decoupling and numerical integration commute: carrying out the integration in the old variables
 $(q,p)$
yields the same result as successively (i) changing variables in the system, (ii) integrating each of the uncoupled oscillators, and (iii) translating the result to the old variables. Therefore stability may be analysed under the assumption that the integration is performed in the uncoupled version.
Example 3.14. Consider a particular case with
 $d=2$
,
 $M=L=I$
,
 $\unicode[STIX]{x1D714}_{1}=1$
and
 $\unicode[STIX]{x1D714}_{2}=100$
and the initial condition
 $$\begin{eqnarray}\bar{q}^{1}(0)=1,\quad \bar{p}^{1}(0)=0,\quad \bar{q}^{2}(0)=0.01,\quad \bar{p}^{2}(0)=0.\end{eqnarray}$$
We wish to integrate with the velocity Verlet algorithm over
 $0\leq t\leq 20\unicode[STIX]{x1D70B}$
(ten periods of the slower oscillation) and aim at absolute errors of magnitude
 ${\approx}0.1$
in the Euclidean norm in the
 $\mathbb{R}^{4}$
space of the variables
 $(q^{1},q^{2},p^{1},p^{2})$
or, equivalently, because here
 $q=U\bar{q}$
with
 $U$
orthogonal, in the Euclidean norm of the variables
 $(\bar{q}^{1},\bar{q}^{2},\bar{p}^{1},\bar{p}^{2})$
. On accuracy grounds it would be sufficient to take
 $h\approx 0.2$
: from Example 3.10 we know this is enough to integrate the first uncoupled oscillator with the desired accuracy, and the second oscillator should not contribute significantly to the error, due to the smallness of
 $\bar{q}^{2}(t)$
and
 $\bar{p}^{2}(t)$
for all
 $t$
. However, unless we take
 $h\unicode[STIX]{x1D714}_{2}<2$
, i.e.
 $h<0.02$
, the errors in
 $\bar{q}^{2}(t)$
and
 $\bar{p}^{2}(t)$
will grow exponentially due to instability. In this example, and in many situations arising in practice, to avoid instabilities, the value of
 $h$
has to be chosen much smaller than accuracy would require. As a result the computational effort to span the time interval of interest would be much higher than might be expected on accuracy grounds. These situations are called stiff. To deal with stiffness one may resort to suitable implicit integrators such as the midpoint rule, or explicit integrators with large stability intervals.
Remark 3.15. It may seem that the initial condition in the preceding example is somewhat contrived, as the sizes of two components of
 $\bar{q}$
are so unbalanced. This is not so: it is easily checked that, in terms of the original energy in (3.27), the contributions to
 $H$
of the
 $\unicode[STIX]{x1D714}_{1}$
and
 $\unicode[STIX]{x1D714}_{2}$
oscillations are both equal to
 $1/2$
. Those oscillations are called normal modes in mechanics.
The present discussion is continued in Section 4.4.
We emphasize that, while the preceding material refers to the quadratic Hamiltonian (3.27), one may expect that it has some relevance for Hamiltonians close to that model. However, there are cases where the behaviour of a numerical integrator departs considerably from its behaviour when applied to (3.27). This point is discussed in Section 9.2.
4 Geometric integration
Classically, the development of numerical integrators for ordinary differential equations focused on general-purpose methods (such as linear multistep or Runge–Kutta formulas) that were selected after analysing their local error and fixed
 $h$
stability properties. Geometric integration (Sanz-Serna Reference Sanz-Serna, Duff and Watson1997) is a newer paradigm of numerical integration, where the interest lies in methods tailored to the problem at hand with a view to preserving some of its geometric features. The development of geometric integration started in the 1980s with the study of symplectic integrators for Hamiltonian systems by Feng Kang and others (Sanz-Serna Reference Sanz-Serna1992, Sanz-Serna and Calvo Reference Sanz-Serna and Calvo1994). Useful monographs are those by Leimkuhler and Reich (Reference Leimkuhler and Reich2004), Hairer et al. (Reference Hairer, Lubich and Wanner2010), Feng and Qin (Reference Feng and Qin2010) and Blanes and Casas (Reference Blanes and Casas2016). We review the geometric integration of Hamiltonian and reversible systems and study the use of modified equations, a key tool for our purposes. We also examine the behaviour of geometric integrators in the harmonic model problem. The section concludes by showing the optimality of the stability interval of the Strang/Verlet integrator.
4.1 Hamiltonian problems
Splitting integrators are symplectic in the following sense. Assume that the system (3.7) is Hamiltonian and that it is split in such a way that both split systems (3.8) are also Hamiltonian. Then the splitting integrator mapping
 $\unicode[STIX]{x1D713}_{h}$
is symplectic, as a composition (Proposition 2.3) of flows that are individually symplectic (Theorem 2.5). This ensures that the numerical solution shares the specific properties of Hamiltonian flows that derive from symplecticness. Note that for
 $\unicode[STIX]{x1D713}_{h}$
to be symplectic it is not enough that the system being integrated is Hamiltonian; if the split vector fields
 $f^{(\text{A})}$
and
 $f^{(\text{B})}$
are not Hamiltonian themselves, then
 $\unicode[STIX]{x1D713}_{h}$
cannot be expected to be symplectic. Of course, all possible splittings of a Hamiltonian vector field as a sum of Hamiltonian vector fields,
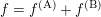 $f=f^{(\text{A})}+f^{(\text{B})}$
, may be obtained by splitting the Hamiltonian
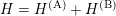 $H=H^{(\text{A})}+H^{(\text{B})}$
in an arbitrary way and then setting
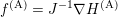 $f^{(\text{A})}=J^{-1}\unicode[STIX]{x1D6FB}H^{(\text{A})}$
,
 $f^{(\text{B})}=J^{-1}\unicode[STIX]{x1D6FB}H^{(\text{B})}$
. We sum up as follows.
Theorem 4.1. Assume that the Hamiltonian of the system (2.8) is written as
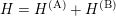 $H=H^{(\text{A})}+H^{(\text{B})}$
and, correspondingly, split
 $f=J^{-1}\unicode[STIX]{x1D6FB}H$
into
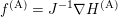 $f^{(\text{A})}=J^{-1}\unicode[STIX]{x1D6FB}H^{(\text{A})}$
and
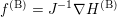 $f^{(\text{B})}=J^{-1}\unicode[STIX]{x1D6FB}H^{(\text{B})}$
. For any splitting integrator (3.21) and any
 $h$
, the mapping
 $\unicode[STIX]{x1D713}_{h}$
is symplectic. In particular,
 $\unicode[STIX]{x1D713}_{h}$
conserves oriented volume.
Note that the
 $n$
-fold composition
 $\unicode[STIX]{x1D713}_{h}^{n}$
that advances the numerical solution over
 $n$
time-steps is then also symplectic (Proposition 2.3).
Some implicit Runge–Kutta methods, including the midpoint rule and Gauss methods, are also symplectic:
 $\unicode[STIX]{x1D713}_{h}$
is a symplectic map whenever the system (2.1) being integrated is Hamiltonian as in (2.8). No explicit Runge–Kutta method is symplectic. In particular, Euler’s rule is not symplectic; according to Example 3.6 the Euler discretization of the harmonic oscillator increases area, as
 $\tilde{M}_{h}$
has determinant
 $1+h^{2}$
. This increase in area is related to the estimate (3.24) that shows that the Euler solution spirals outward, a non-Hamiltonian behaviour.
In the particular case of the Hamiltonian in (2.10), taking
 ${\mathcal{T}}$
and
 ${\mathcal{U}}$
to play the roles of
 $H^{(\text{A})}$
and
 $H^{(\text{B})}$
respectively leads to the splitting of the differential system given in (3.9)–(3.10) with
 $F=-\unicode[STIX]{x1D6FB}{\mathcal{U}}$
.
It would also be desirable to have integrators that preserved energy when applied to the Hamiltonian system (2.8), that is,
 $H\circ \unicode[STIX]{x1D713}_{h}=H$
. Unfortunately, for realistic problems such a requirement is incompatible with
 $\unicode[STIX]{x1D713}_{h}$
being symplectic (Sanz-Serna and Calvo Reference Sanz-Serna and Calvo1994, Section 10.3). It is then standard practice to insist on symplecticness and sacrifice conservation of energy. There are several reasons for this. Symplecticness plays a key role in the Hamiltonian formalism (see Theorem 2.5). In addition, while, as we have seen, it is not difficult to find symplectic formulas, standard classes of integrators do not include energy-preserving schemes unless the energy is assumed to have particular forms. Finally, as we shall discuss below, symplectic schemes have small energy errors even when the integration interval is very long.
4.2 Reversible problems
For reversible systems we have, from Proposition 2.9 and Theorem 2.10, the following theorem.
Theorem 4.2. Assume that (3.7), and the split systems (3.8) are reversible with respect to the same involution
 $S$
. If the system is integrated by means of a palindromic splitting integrator (3.19) or (3.20), then, for any
 $h$
, the mapping
 $\unicode[STIX]{x1D713}_{h}$
will also be reversible.
The midpoint rule and Gauss Runge–Kutta formulas also generate reversible mappings
 $\unicode[STIX]{x1D713}_{h}$
whenever they are applied to a reversible system. No explicit Runge–Kutta method is reversible.
The
 $n$
-fold composition
 $\unicode[STIX]{x1D713}_{h}^{n}$
that advances the numerical solution over
 $n$
time-steps is then also reversible (Proposition 2.9). However, note that if variable time-steps were taken, then the mapping
 $\unicode[STIX]{x1D713}_{h_{n}}\circ \cdots \circ \unicode[STIX]{x1D713}_{h_{1}}$
, which advances the solution from
 $t_{0}$
to
 $t_{n+1}$
, would not be reversible. This is one of the reasons for not considering variable time-steps here; see Remark 3.4.
The use of reversible integrators (with constant step sizes) ensures that the numerical solution inherits relevant geometric properties of the true solution of the differential system (Cano and Sanz-Serna Reference Cano and Sanz-Serna1997, Cano and Sanz-Serna Reference Cano and Sanz-Serna1998).
4.3 Modified equations
Modified equations are rather old (see references in Griffiths and Sanz-Serna Reference Griffiths and Sanz-Serna1986); however, their use as a means to analyse numerical integrators has only become popular in the past twenty years, since the emergence of geometric integration (Sanz-Serna Reference Sanz-Serna and Marsden1996).
4.3.1 Motivation
Let us first look at some examples.
Example 4.3. Suppose that the system (2.1) is solved with Euler’s rule (3.2) and let
 $\unicode[STIX]{x1D713}_{h}$
denote the corresponding map
 $x+hf(x)$
. Consider the new system, parametrized by
 $h$
,
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}x=\tilde{f}_{h}(x),\quad \tilde{f}_{h}(x)=f(x)-\displaystyle \frac{h}{2}f^{\prime }(x)f(x),\end{eqnarray}$$
with flow
 $\tilde{\unicode[STIX]{x1D711}}_{t}$
(for simplicity, the dependence of this flow on the parameter
 $h$
is not incorporated in the notation). By proceeding as in the derivation of (3.5), we find that the Taylor expansion of
 $\tilde{\unicode[STIX]{x1D711}}_{h}$
in powers of
 $h$
is
 $$\begin{eqnarray}\displaystyle \tilde{\unicode[STIX]{x1D711}}_{h}(x) & = & \displaystyle x+h\tilde{f}_{h}(x)+\displaystyle \frac{h^{2}}{2}\tilde{f}_{h}^{\prime }(x)\tilde{f}_{h}(x)+O(h^{3})\nonumber\\ \displaystyle & = & \displaystyle x+h\biggl(f(x)-\displaystyle \frac{h}{2}f^{\prime }(x)f(x)\biggr)+\displaystyle \frac{h^{2}}{2}f_{h}^{\prime }(x)f_{h}(x)+O(h^{3})\nonumber\\ \displaystyle & = & \displaystyle x+hf(x)+O(h^{3}).\nonumber\end{eqnarray}$$
Thus, the Euler mapping
 $\unicode[STIX]{x1D713}_{h}(x)$
, which differs from the flow of the system (2.1) being solved in
 $O(h^{2})$
terms (first-order consistency), differs from the flow
 $\tilde{\unicode[STIX]{x1D711}}_{h}$
of the so-called modified or shadow system (4.1) in
 $O(h^{3})$
terms (second-order consistency). According to Theorem 3.2 (see Griffiths and Sanz-Serna Reference Griffiths and Sanz-Serna1986 for details), over bounded time intervals, the Euler solution differs from the corresponding solution of the modified system in
 $O(h^{2})$
terms. Therefore we may expect that the properties of the Euler solutions for (2.1) will resemble the properties of the solutions of (4.1) more than they resemble the properties of solutions of (2.1) itself. When studying the properties of Euler’s rule, working with (4.1) rather than with
 $\unicode[STIX]{x1D713}_{h}$
should be advantageous, because differential equations are simpler to analyse than maps. An illustration is provided next.
Example 4.4. Let us particularize the preceding example to the case of the harmonic oscillator (2.3). The modified system (4.1) is found to be
 $$\begin{eqnarray}\displaystyle \frac{\text{d}q}{\text{d}t}=p+\displaystyle \frac{h}{2}q,\quad \displaystyle \frac{\text{d}p}{\text{d}t}=-q+\displaystyle \frac{h}{2}p,\end{eqnarray}$$
and from here a simple computation yields for the radius
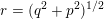 $r=(q^{2}+p^{2})^{1/2}$
 $$\begin{eqnarray}\displaystyle \frac{\text{d}r}{\text{d}t}=\displaystyle \frac{h}{2}r,\end{eqnarray}$$
so that, over a time interval of length
 $h$
,
 $r$
is multiplied by the factor
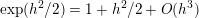 $\exp (h^{2}/2)=1+h^{2}/2+O(h^{3})$
. This is precisely what we found in (3.24) for the Euler solution of the harmonic oscillator (but the
 $O(h^{3})$
remainder here will not coincide with the one in (3.24), because there is an
 $O(h^{3})$
difference between
 $\unicode[STIX]{x1D713}_{h}$
and
 $\tilde{\unicode[STIX]{x1D711}}_{h}$
).
Example 4.5. In (4.1),
 $\tilde{f}_{h}(x)$
is a first-degree polynomial in
 $h$
. If
 $\tilde{f}_{h}(x)$
is chosen to be quadratic in
 $h$
, that is,
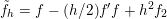 $\tilde{f}_{h}=f-(h/2)f^{\prime }f+h^{2}f_{2}$
, it is possible to determine
 $f_{2}$
so as to achieve
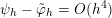 $\unicode[STIX]{x1D713}_{h}-\tilde{\unicode[STIX]{x1D711}}_{h}=O(h^{4})$
for the Euler map
 $\unicode[STIX]{x1D713}_{h}(x)=x+hf(x)$
. Similarly, taking
 $\tilde{f}_{h}(x)$
as a suitable chosen polynomial in
 $h$
with degree
 $\unicode[STIX]{x1D707}=3,4,\ldots ,$
it is possible to achieve
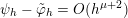 $\unicode[STIX]{x1D713}_{h}-\tilde{\unicode[STIX]{x1D711}}_{h}=O(h^{\unicode[STIX]{x1D707}+2})$
.
4.3.2 Definition
Given a (consistent) integrator
 $\unicode[STIX]{x1D713}_{h}$
for system (2.1), there exists a (unique) formal series in powers of
 $h$
,
 $$\begin{eqnarray}\tilde{f}_{h}^{\infty }(x)=f(x)+hg^{[1]}(x)+h^{2}g^{[2]}(x)+\cdots\end{eqnarray}$$
(the
 $g^{[\unicode[STIX]{x1D707}]}$
map the space
 $\mathbb{R}^{D}$
into itself), with the property that, for each
 $\unicode[STIX]{x1D707}=0,1,\ldots ,$
the flow
 $\tilde{\unicode[STIX]{x1D711}}_{h}^{[\unicode[STIX]{x1D707}]}$
of the modified system
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}x=\tilde{f}_{h}^{[\unicode[STIX]{x1D707}]}(x),\quad \tilde{f}_{h}^{[\unicode[STIX]{x1D707}]}(x)=f(x)+hg^{[1]}(x)+\cdots +h^{\unicode[STIX]{x1D707}}g^{[\unicode[STIX]{x1D707}]}(x),\end{eqnarray}$$
satisfies
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}(x)-\tilde{\unicode[STIX]{x1D711}}_{h}^{[\unicode[STIX]{x1D707}]}(x)=O(h^{\unicode[STIX]{x1D707}+2}).\end{eqnarray}$$
Furthermore, for a symmetric method, the odd-numbered
 $g^{[\unicode[STIX]{x1D707}]}(x)$
are identically zero:
 $$\begin{eqnarray}g^{[1]}(x)=g^{[3]}(x)=g^{[5]}(x)=\cdots =0.\end{eqnarray}$$
As
 $\unicode[STIX]{x1D707}$
increases, the solutions of the modified system (4.3) provide better and better approximations to
 $\unicode[STIX]{x1D713}_{h}$
. For some vector fields
 $f$
and some integrators (see an example in Proposition 4.9 below), it may happen that the formal series (4.2) converges for each
 $x$
(so that
 $\tilde{f}_{h}^{\infty }$
is a well-defined mapping
 $\mathbb{R}^{D}:\rightarrow \mathbb{R}^{D}$
) and that furthermore the flow
 $\tilde{\unicode[STIX]{x1D711}}_{h}^{[\infty ]}$
of
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}x=\tilde{f}_{h}^{\infty }(x)\end{eqnarray}$$
coincides with
 $\unicode[STIX]{x1D713}_{h}$
. In those cases, (4.6) provides an exact modified system to study
 $\unicode[STIX]{x1D713}_{h}$
. However, such situations are exceptional, because, in general, discrete dynamical systems (such as the one generated by
 $\unicode[STIX]{x1D713}_{h}$
) possess features that cannot appear in flows of autonomous differential systems. It is the lack of convergence of (4.2) that makes it necessary to consider the truncations in (4.3) which do not exactly reproduce
 $\unicode[STIX]{x1D713}_{h}$
but approximate it with an error as in (4.4). It is possible, by increasing
 $\unicode[STIX]{x1D707}$
as
 $h$
becomes smaller and smaller, to render the discrepancy
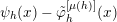 $\unicode[STIX]{x1D713}_{h}(x)-\tilde{\unicode[STIX]{x1D711}}_{h}^{[\unicode[STIX]{x1D707}(h)]}(x)$
exponentially small with respect to
 $h$
, as first proved by Neishtadt (Sanz-Serna and Calvo Reference Sanz-Serna and Calvo1994, Section 10.1).
4.3.3 Finding explicitly the modified equations
For splitting integrators, the terms of the series (4.2) may be found explicitly by using the Baker–Campbell–Hausdorff formula. The next theorem provides a summary of some key points; a more detailed description is given in Section 9.1.
Theorem 4.6. Assume that system (3.7) is integrated by means of a (consistent) splitting algorithm of the general format (3.21). The series (4.2) is of the form
 $$\begin{eqnarray}\displaystyle & & \displaystyle (f^{(\text{A})}+f^{(\text{B})})+hC_{1,1}[f^{(\text{A})},f^{(\text{B})}]\nonumber\\ \displaystyle & & \displaystyle \qquad +h^{2}(C_{2,1}[f^{(\text{A})},[f^{(\text{A})},f^{(\text{B})}]]+C_{2,2}[f^{(\text{B})},[f^{(\text{A})},f^{(\text{B})}]])+\cdots \nonumber\end{eqnarray}$$
where, for each
 $\unicode[STIX]{x1D707}=1,2\ldots ,$
the coefficient of
 $h^{\unicode[STIX]{x1D707}}$
is a linear combination of linearly independent iterated commutators involving
 $\unicode[STIX]{x1D707}+1$
fields
 $f^{(\text{A})}$
,
 $f^{(\text{B})}$
. The coefficients
 $C_{i,j}$
that appear in the linear combinations are known polynomials on the coefficients
 $a_{k}$
and
 $b_{\ell }$
that appear in the formula (3.21).
If the splitting is palindromic then all the coefficients
 $C_{2i+1,j}$
corresponding to odd powers of
 $h$
vanish.
For Runge–Kutta methods it is also possible to give expressions for the terms in the series (4.2): see Calvo, Murua and Sanz-Serna (Reference Calvo, Murua, Sanz-Serna, Kloeden and Palmer1994) or Sanz-Serna (Reference Sanz-Serna and Marsden1996).
4.3.4 Modified equations and order
If in (4.2) the functions
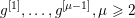 $g^{[1]},\ldots ,g^{[\unicode[STIX]{x1D707}-1]},\unicode[STIX]{x1D707}\geq 2$
, vanish so that
 $$\begin{eqnarray}\tilde{f}_{h}^{[\unicode[STIX]{x1D707}]}(x)-f(x)=h^{\unicode[STIX]{x1D707}}g^{[\unicode[STIX]{x1D707}]}(x)+O(h^{\unicode[STIX]{x1D707}+1}),\end{eqnarray}$$
then the flow
 $\tilde{\unicode[STIX]{x1D711}}_{h}^{[\unicode[STIX]{x1D707}]}$
of (4.3) and the flow
 $\unicode[STIX]{x1D711}_{h}$
of (2.1) will satisfy
 $$\begin{eqnarray}\tilde{\unicode[STIX]{x1D711}}_{h}^{[\unicode[STIX]{x1D707}]}(x)-\unicode[STIX]{x1D711}_{h}(x)=h^{\unicode[STIX]{x1D707}+1}g^{[\unicode[STIX]{x1D707}]}(x)+O(h^{\unicode[STIX]{x1D707}+2}),\end{eqnarray}$$
which in view of (4.4) implies that
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}(x)-\unicode[STIX]{x1D711}_{h}(x)=h^{\unicode[STIX]{x1D707}+1}g^{[\unicode[STIX]{x1D707}]}(x)+O(h^{\unicode[STIX]{x1D707}+2}),\end{eqnarray}$$
that is, the integrator
 $\unicode[STIX]{x1D713}_{h}(x)$
has order
 $\unicode[STIX]{x1D707}$
(or higher). The converse is also true, because the argument may be reversed: order
 $\geq \unicode[STIX]{x1D707}$
implies that
 $g^{[1]},\ldots ,g^{[\unicode[STIX]{x1D707}-1]}$
must vanish. From (4.5), the order of a symmetric method must be an even integer. To sum up, we have the following result, which makes it possible to use the series (4.2) rather than the mapping
 $\unicode[STIX]{x1D713}_{h}$
to study the order of a given integrator.
Theorem 4.7. A (consistent) integrator has order
 $\geq \unicode[STIX]{x1D708}$
,
 $\unicode[STIX]{x1D708}\geq 2$
, if and only if the functions
 $g^{[1]},\ldots ,g^{[\unicode[STIX]{x1D708}-1]}$
appearing in (4.2) are identically zero.
When the order is exactly
 $\unicode[STIX]{x1D708}$
,
 $\unicode[STIX]{x1D708}=1,2,\ldots ,$
the leading term of the truncation error is
 $h^{\unicode[STIX]{x1D708}+1}g^{[\unicode[STIX]{x1D708}]}(x)$
.
A (consistent) symmetric integrator has even order.
This theorem, in tandem with Theorem 4.6, provides the standard way to write down the order conditions for splitting methods, that is, the relations on the coefficients
 $a_{k}$
,
 $b_{\ell }$
that are necessary and sufficient for an integrator to have order
 $\unicode[STIX]{x1D708}$
. Specifically, order
 $\geq \unicode[STIX]{x1D708}$
is equivalent to
 $C_{i,j}=0$
whenever
 $i<\unicode[STIX]{x1D708}$
. Here are the simplest illustrations.
∙ The Lie–Trotter formula (3.11) has
$\unicode[STIX]{x1D708}=1$
, and, according to Theorems 4.6 and 4.7, the leading term of the local error is a constant multiple of
$h^{2}[f^{(\text{A})},f^{(\text{B})}]$
, which matches our earlier finding in (3.12).∙ The condition
$C_{1,1}=0$
is necessary and sufficient for an integrator to have order
$\unicode[STIX]{x1D708}\geq 2$
. It is automatically satisfied for palindromic formulas.∙ Strang’s formula (3.13) has order exactly 2. The coefficient of
$h^{3}$
in the expansion of the local error is a combination of iterated commutators with three fields. This was already found in (3.14).∙ To have order
$\unicode[STIX]{x1D708}\geq 3$
we have to impose the order conditions
$C_{1,1}=0$
,
$C_{2,1}=0$
,
$C_{2,2}=0$
.


4.3.5 Modified equations and geometric integrators
The geometric properties of integrators have a clear impact on their modified systems.
Let us begin with the Hamiltonian case. If the split fields in (3.8) are Hamiltonian with Hamiltonian functions
 $H^{(\text{A})}$
and
 $H^{(\text{B})}$
, then by invoking Theorem 2.13 it is feasible to work with iterated Poisson brackets of
 $H^{(\text{A})}$
and
 $H^{(\text{B})}$
rather than with the iterated Lie brackets of
 $f^{(\text{A})}$
and
 $f^{(\text{B})}$
. Then the expansion in Theorem 4.6 is replaced by
 $$\begin{eqnarray}\displaystyle & & \displaystyle (H^{(\text{A})}+H^{(\text{B})})-hC_{1,1}\{H^{(\text{A})},H^{(\text{B})}\}\nonumber\\ \displaystyle & & \displaystyle \qquad +h^{2}(C_{2,1}\{H^{(\text{A})},\{H^{(\text{A})},H^{(\text{B})}\}\}+C_{2,2}\{H^{(\text{B})},\{H^{(\text{A})},H^{(\text{B})}\}\})+\cdots \,.\nonumber\end{eqnarray}$$
For each
 $\unicode[STIX]{x1D707}$
, the modified system (4.3) is a Hamiltonian system. This is a reflection of the fact that, according to Theorem 4.1, splitting integrators give rise to mappings
 $\unicode[STIX]{x1D713}_{h}$
that are symplectic. In the class of Runge–Kutta methods it is also true that symplectic integrators have modified systems that are Hamiltonian.
Speaking informally, we may say that all integrators change the system being integrated into a modified system; in non-symplectic methods the (perhaps small) change is such that the modified system is no longer Hamiltonian. Symplectic methods are those that change Hamiltonian systems into Hamiltonian systems. This heuristic description cannot be made entirely rigorous because, as pointed out above, the exact modified system (4.6) only exists in a formal sense due to the lack of convergence of the series in (4.2). The existence of a Hamiltonian modified system is at the basis of many favourable properties of symplectic integrators.
Remark 4.8. The considerations above only make sense if the step size
 $h$
is held constant along the integration interval. Since the modified system changes with
 $h$
, variable step size implementations of symplectic integrators do not have well-defined modified systems and in fact their behaviour is closer to that of non-symplectic integrators than to that of symplectic integrators used with constant step sizes (Calvo and Sanz-Serna Reference Calvo and Sanz-Serna1993).
For the reversible case, consider the situation of Theorem 4.2. From Proposition 2.14 all iterated commutators involving an odd number of fields are themselves
 $S$
-reversible. Since, according to Theorem 4.6, for palindromic splitting integrators the iterated commutators with an even number of fields enter the expansion (4.2) with null coefficients, then the modified systems (4.3) are reversible.
4.3.6 Conservation of energy by symplectic integrators
As noted above, Neishtadt proved that, under suitable regularity assumptions, the modified system may be chosen so as to ensure that its
 $h$
-flow is exponentially close to the mapping
 $\unicode[STIX]{x1D713}_{h}$
. For symplectic integrators, the modified system is Hamiltonian and therefore exactly preserves its own Hamiltonian function that we denote by
 $\tilde{H}_{h}$
. It follows that, except for exponentially small errors,
 $\unicode[STIX]{x1D713}_{h}$
preserves
 $\tilde{H}_{h}$
. On the other hand, for a symplectic integrator of order
 $\unicode[STIX]{x1D708}$
, the difference between
 $\tilde{H}_{h}$
and
 $H$
is
 $O(h^{\unicode[STIX]{x1D708}})$
(Theorem 4.7). These considerations make it possible to prove that symplectic integrators preserve the value of the Hamiltonian
 $H$
of the system being integrated with error
 $O(h^{\unicode[STIX]{x1D708}})$
over time intervals
 $0\leq t\leq T_{h}$
whose length
 $T_{h}$
increases exponentially as
 $h\rightarrow 0$
(Hairer et al.
Reference Hairer, Lubich and Wanner2010).
For linear problems an exact modified system exists, and using the same argument, we may conclude that the error in energy of a symplectic integrator has an
 $O(h^{\unicode[STIX]{x1D708}})$
bound over the infinite interval
 $0\leq t<\infty$
, or in other words the energy error may be bounded independently of the number of step taken. For the case of the harmonic oscillator, this will be illustrated presently.
4.4 Geometric integrators and the harmonic model problem
We take again the integration of the harmonic oscillator as a model problem (see (3.22)–(3.23)); now our interest is in studying in detail the behaviour of geometric integrators.
We focus on (consistent) integrators that are both symplectic and reversible. In terms of the matrix
 $\tilde{M}_{h}$
, the first of these properties corresponds to
 $A_{h}D_{h}-B_{h}C_{h}=1$
and, when this condition holds, reversibility is equivalent to
 $A_{h}=D_{h}$
. Our treatment follows that of Blanes et al. (Reference Blanes, Casas and Sanz-Serna2014).
The characteristic polynomial of
 $\tilde{M}_{h}$
is of the form (3.25) and there are four possibilities, the first two corresponding to unstable simulations and the last two corresponding to stable simulations.
(1)
$h$
is such that
$|A_{h}|>1$
. In that case
$\tilde{M}_{h}$
has spectral radius
${>}1$
and therefore the powers
$\tilde{M}_{h}^{n}$
grow exponentially with
$n$
.(2)
$A_{h}=\pm 1$
and
$|B_{h}|+|C_{h}|>0$
. The powers
$\tilde{M}_{h}^{n}$
grow linearly with
$n$
.(3)
$A_{h}=\pm 1$
,
$B_{h}=C_{h}=0$
, that is,
$\tilde{M}_{h}=\pm I$
,
$\tilde{M}_{h}^{n}=(\pm I)^{n}$
.(4)
$h$
is such that
$|A_{h}|<1$
. In that case,
$\tilde{M}_{h}$
has complex conjugate eigenvalues of unit modulus and the powers
$\tilde{M}_{h}^{n}$
,
$n=0,1,\ldots ,$
remain bounded.


Comparing (3.22) with the result of setting
 $t=h$
in (2.4), we see that, by consistency,
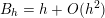 $B_{h}=h+O(h^{2})$
and
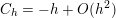 $C_{h}=-h+O(h^{2})$
, and therefore
 $A_{h}=(1+B_{h}C_{h})^{1/2}=1-h^{2}/2+O(h^{3})$
. Thus, for
 $h>0$
sufficiently small,
 $A_{h}<1$
and the integration will be stable. The stability interval of the integrator is the longest interval
 $(0,h_{\max })$
such that integrations with
 $h\in (0,h_{\max })$
are stable. For reasons discussed in Example 3.14, methods with long stability intervals are often to be favoured. From Example 3.7, the midpoint rule has stability interval
 $(0,\infty )$
. Explicit integrators have stability intervals of finite length.
For each
 $h$
such that
 $|A_{h}|\leq 1$
, it is expedient to introduce
 $\unicode[STIX]{x1D703}_{h}\in \mathbb{R}$
such that
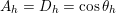 $A_{h}=D_{h}=\cos \unicode[STIX]{x1D703}_{h}$
. For
 $|A_{h}|<1$
, we have
 $\sin \unicode[STIX]{x1D703}_{h}\neq 0$
and we may define
 $$\begin{eqnarray}\unicode[STIX]{x1D712}_{h}=B_{h}/\sin \unicode[STIX]{x1D703}_{h}.\end{eqnarray}$$
In terms of
 $\unicode[STIX]{x1D703}_{h}$
and
 $\unicode[STIX]{x1D712}_{h}$
, the matrices in (3.22) and (3.23) are then
 $$\begin{eqnarray}\tilde{M}_{h}=\left[\begin{array}{@{}cc@{}}\cos \unicode[STIX]{x1D703}_{h} & \unicode[STIX]{x1D712}_{h}\sin \unicode[STIX]{x1D703}_{h}\\ -\unicode[STIX]{x1D712}_{h}^{-1}\sin \unicode[STIX]{x1D703}_{h} & \cos \unicode[STIX]{x1D703}_{h}\end{array}\right]\end{eqnarray}$$
and
 $$\begin{eqnarray}\tilde{M}_{h}^{n}=\left[\begin{array}{@{}cc@{}}\cos (n\unicode[STIX]{x1D703}_{h}) & \unicode[STIX]{x1D712}_{h}\sin (n\unicode[STIX]{x1D703}_{h})\\ -\unicode[STIX]{x1D712}_{h}^{-1}\sin (n\unicode[STIX]{x1D703}_{h}) & \cos (n\unicode[STIX]{x1D703}_{h})\end{array}\right]\!.\end{eqnarray}$$
For a value of
 $h$
in the (stable) case
 $A_{h}=\pm 1$
,
 $B_{h}=C_{h}=0$
, we have
 $\sin \unicode[STIX]{x1D703}_{h}=0$
, so (4.7) does not make sense. However, the matrix
 $\tilde{M}_{h}$
is of the form (4.8) for any choice of
 $\unicode[STIX]{x1D712}_{h}$
. (Typically, for such a value of
 $h$
, one may avoid the indeterminacy in the value of
 $\unicode[STIX]{x1D712}_{h}$
by taking limits as
 $\unicode[STIX]{x1D716}\rightarrow 0$
in
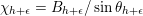 $\unicode[STIX]{x1D712}_{h+\unicode[STIX]{x1D716}}=B_{h+\unicode[STIX]{x1D716}}/\sin \unicode[STIX]{x1D703}_{h+\unicode[STIX]{x1D716}}$
.)
For a method of order
 $\unicode[STIX]{x1D708}$
,
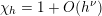 $\unicode[STIX]{x1D712}_{h}=1+O(h^{\unicode[STIX]{x1D708}})$
,
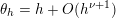 $\unicode[STIX]{x1D703}_{h}=h+O(h^{\unicode[STIX]{x1D708}+1})$
as
 $h\rightarrow 0$
. By comparing the numerical
 $\tilde{M}_{h}^{n}$
in (4.9) with the true
 $M_{nh}$
in (2.4), one sees that a method with
 $\unicode[STIX]{x1D703}_{h}=h$
would have no phase error: the angular frequency of the rotation of the numerical solution would coincide with the true angular frequency of the harmonic oscillator. More generally, the difference
 $\unicode[STIX]{x1D703}_{h}-h$
governs the phase error. According to (4.9), this phase error grows linearly with
 $n$
(recall Table 3.1). On the other hand, a method with
 $\unicode[STIX]{x1D712}_{h}=1$
would have no energy error: the numerical solution would remain on the correct level curve of the Hamiltonian, i.e. on the circle
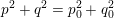 $p^{2}+q^{2}=p_{0}^{2}+q_{0}^{2}$
. The discrepancy between
 $\unicode[STIX]{x1D712}_{h}$
and
 $1$
governs the energy errors. In (4.9) we see that these are bounded as
 $n$
grows.
The preceding considerations may alternatively be understood by considering the modified Hamiltonian given in the next result.
Proposition 4.9. Consider the application to the harmonic oscillator (2.3) of a (consistent) reversible volume-preserving integrator (3.22), and assume that the step size
 $h$
is stable, so that
 $\tilde{M}_{h}$
may be written in the form (4.8). Then
 $\unicode[STIX]{x1D713}_{h}$
exactly coincides with the
 $h$
flow of the modified Hamiltonian
 $$\begin{eqnarray}\tilde{H}_{h}=\displaystyle \frac{\unicode[STIX]{x1D703}_{h}}{2h}\biggl(\unicode[STIX]{x1D712}_{h}p^{2}+\displaystyle \frac{1}{\unicode[STIX]{x1D712}_{h}}q^{2}\biggr).\end{eqnarray}$$
Modified Hamiltonian for (a) velocity and (b) position Verlet. The dots are the first five points along a discrete orbit of the velocity/position Verlet integrator initiated at
 $(q,p)=(1,0)$
and the grey line provides the associated level set of the modified Hamiltonian. For comparison, the black contour line shows the corresponding level set of the true Hamiltonian.

In particular, numerical trajectories are contained in ellipses,
 $$\begin{eqnarray}\unicode[STIX]{x1D712}_{h}p^{2}+\displaystyle \frac{1}{\unicode[STIX]{x1D712}_{h}}q^{2}=\unicode[STIX]{x1D712}_{h}p_{0}^{2}+\displaystyle \frac{1}{\unicode[STIX]{x1D712}_{h}}q_{0}^{2},\end{eqnarray}$$
rather than in circles (Figure 4.1).
Remark 4.10. A comparison of a given integrator (3.22) with (2.4) shows that
 $$\begin{eqnarray}\left[\begin{array}{@{}c@{}}q_{n+1}\\ p_{n+1}\end{array}\right]=\tilde{M}_{h}\left[\begin{array}{@{}c@{}}q_{n}\\ p_{n}\end{array}\right]\!,\quad \tilde{M}_{h}=\left[\begin{array}{@{}cc@{}}A_{h} & -C_{h}\\ -B_{h} & D_{h}\end{array}\right]\end{eqnarray}$$
is a second integrator of the same order of accuracy. We might think that (4.11) arises from (3.22) by changing the roles of the variables
 $q$
and
 $p$
. In the particular case of splitting integrators, (4.11) arises from (3.22) after swapping the roles of the split systems
 $\text{A}$
and
 $\text{B}$
. The integrators (3.22) and (4.11) share the same interval of stability and the same
 $\unicode[STIX]{x1D703}_{h}$
. The function
 $\unicode[STIX]{x1D712}_{h}$
of (4.11) is obtained by changing the sign of the reciprocal of the function
 $\unicode[STIX]{x1D712}_{h}$
of (3.22). The important function
 $\unicode[STIX]{x1D70C}(h)$
to be introduced in Proposition 6.4 is also the same for (3.22) and (4.11). The velocity Verlet algorithm and the position Verlet algorithm provide an example of this kind of pair of integrators (see Examples 3.8 and 3.9).
The results we have just presented may be extended to quadratic Hamiltonians with
 $d$
degrees of freedom (3.27): it is sufficient to use diagonalization as in Proposition 3.13. In particular, for stability we require that the stability interval of the integrator contains all products
 $h\unicode[STIX]{x1D714}_{i}$
, where the frequencies
 $\unicode[STIX]{x1D714}_{i}$
are the square roots of the eigenvalues of
 $L^{-1}KL^{-T}$
, with
 $LL^{T}=M$
.
4.5 Optimal stability of Strang’s method
Let us fix an integer
 $N$
and consider consistent palindromic splitting integrators (3.19)–(3.20) with
 $s=N$
; these use
 $N$
evaluations of
 $F$
per step when applied to problems of the form (3.9)–(3.10). The corresponding coefficient
 $A_{h}$
in (3.22) is a polynomial of degree
 $N$
in the variable
 $z=h^{2}$
(for obvious reasons
 $A_{h}$
is often called the stability polynomial of the integrator). We pointed out above that consistency imposes the relation
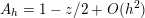 $A_{h}=1-z/2+O(h^{2})$
. Our aim is to identify, among the class just described, the polynomial
 $A_{h}(z)$
that satisfies
 $|A_{h}(z)|<1$
for
 $0<h<h_{\text{max}}$
with
 $h_{\text{max}}$
as large as possible. As we shall show presently, the
 $A_{h}(z)$
sought corresponds to the integrator
 $$\begin{eqnarray}\unicode[STIX]{x1D713}_{h}=\overbrace{\unicode[STIX]{x1D713}_{h/N}^{V}\circ \cdots \circ \unicode[STIX]{x1D713}_{h/N}^{V}}^{N\text{ times}},\end{eqnarray}$$
where
 $\unicode[STIX]{x1D713}_{h}^{V}$
is the mapping associated with the Strang/Verlet formula (3.13).Footnote
7
Note that to carry out a step of length
 $h$
with the method in (4.12), one just has to take
 $N$
consecutive steps of length
 $h/N$
of standard velocity Verlet. In other words, subject to stability, if one wishes to take as long a step as possible with a budget of
 $N$
evaluations of the force per step, the best choice is to concatenate
 $N$
steps of Strang/Verlet.
Footnote
8
To see the optimality of
 $\unicode[STIX]{x1D713}_{h}$
in (4.12), we first note that, after expressing
 $\unicode[STIX]{x1D713}_{h/N}^{V}$
in terms of the
 $\text{A}$
and
 $\text{B}$
flows and merging consecutive
 $\text{B}$
flows, the mapping (4.12) corresponds indeed to a palindromic splitting with
 $N$
stages. Then, from Example 3.8 we know that Verlet is stable for
 $0<h<2$
and this implies that (4.12) is stable for
 $0<h/N<2$
(for (4.12) the powers of
 $\tilde{M}_{h}$
are powers of the Verlet matrix
 $\tilde{M}_{h/N}^{V}$
). In this way (4.12) has stability interval
 $(0,2N)$
and we shall prove next that this is the longest possible. From Example ?? 3.8, Verlet with step size
 $h/N$
has
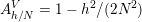 $A_{h/N}^{V}=1-h^{2}/(2N^{2})$
, which, in view of (4.8)–(4.9), implies that for (4.12) the coefficient
 $A_{h}$
has the expression
 $$\begin{eqnarray}\cos \unicode[STIX]{x1D703}_{h}=\cos (N\unicode[STIX]{x1D703}_{h/N}^{V}).\end{eqnarray}$$
Recalling the definition
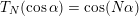 $T_{N}(\cos \unicode[STIX]{x1D6FC})=\cos (N\unicode[STIX]{x1D6FC})$
of the Chebyshev polynomial
 $T_{N}$
, we observe that for (4.12)
 $$\begin{eqnarray}A_{h}(z)=T_{N}\biggl(1-\displaystyle \frac{z}{2N^{2}}\biggr).\end{eqnarray}$$
Well-known properties of
 $T_{N}$
imply that no other polynomial
 $A_{h}(z)$
of degree
 $\leq N$
with
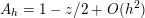 $A_{h}=1-z/2+O(h^{2})$
has modulus
 $\leq 1$
in the interval
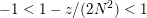 $-1<1-z/(2N^{2})<1$
, that is, when
 $0<h<2N$
.
5 Monte Carlo methods
In this section we review some basic concepts and principles of Monte Carlo methods aimed at computing integrals with respect to a given probability distribution (Sokal Reference Sokal, Dewitt-Morette and Folacci1997, Asmussen and Glynn Reference Asmussen and Glynn2007, Liu Reference Liu2008, Diaconis Reference Diaconis2009). We also describe the Hamiltonian or hybrid Monte Carlo (HMC) method and some of its variants.
5.1 Simple Monte Carlo methods
Given a probability distribution
 $\unicode[STIX]{x1D707}$
in
 $\mathbb{R}^{D}$
(the target distribution) and a function
 $F:\mathbb{R}^{D}\rightarrow \mathbb{R}$
, the problem addressed by the algorithms considered here is to numerically estimate the following
 $D$
-dimensional integral with respect to
 $\unicode[STIX]{x1D707}$
:
 $$\begin{eqnarray}\unicode[STIX]{x1D707}(F)=\int _{\mathbb{R}^{D}}F(x)\unicode[STIX]{x1D707}(\text{d}x).\end{eqnarray}$$
In general,
 $\unicode[STIX]{x1D707}(F)$
cannot be determined analytically. Moreover, since the dimension
 $D$
might not be small, conventional numerical quadrature is likely not to be practical or even feasible.
The simple Monte Carlo method approximately computes
 $\unicode[STIX]{x1D707}(F)$
in (5.1) by generating
 $N$
independent and identically distributed (i.i.d.) samples
 $X_{1},\ldots ,X_{N}$
from
 $\unicode[STIX]{x1D707}$
, evaluating the function
 $F$
at these samples and using the estimator
 $$\begin{eqnarray}\bar{F}_{N}=\displaystyle \frac{1}{N}\mathop{\sum }_{i=1}^{N}F(X_{i}).\end{eqnarray}$$
Assuming that
 $\unicode[STIX]{x1D707}(F)<\infty$
, the law of large numbers states that
 $$\begin{eqnarray}\lim _{N\rightarrow \infty }\bar{F}_{N}=\unicode[STIX]{x1D707}(F)\quad \text{as }N\rightarrow \infty ,\end{eqnarray}$$
almost surely. If, in addition, the standard deviation
 $\unicode[STIX]{x1D70E}_{0}(F)$
of the random variable
 $F(X)$
,
 $X\sim \unicode[STIX]{x1D707}$
, defined by
 $$\begin{eqnarray}\unicode[STIX]{x1D70E}_{0}(F)^{2}=\int _{\mathbb{ R}^{D}}(F(x)-\unicode[STIX]{x1D707}(F))^{2}\unicode[STIX]{x1D707}(\text{d}x)\end{eqnarray}$$
is finite, the central limit theorem ensures the following distributional limit:
 $$\begin{eqnarray}N^{1/2}(\bar{F}_{N}-\unicode[STIX]{x1D707}(F))\overset{d}{\rightarrow }{\mathcal{N}}(0,\unicode[STIX]{x1D70E}_{0}(F)^{2})\quad \text{as }N\rightarrow \infty .\end{eqnarray}$$
Loosely speaking, this may be interpreted as stating that the distribution of
 $\bar{F}_{N}$
is approximately
 ${\mathcal{N}}(0,\unicode[STIX]{x1D70E}_{0}(F)^{2}/N)$
. Hence, the standard deviation of the error
 $\bar{F}_{N}-\unicode[STIX]{x1D707}(F)$
decreases like the inverse square root of the number of samples. Often this standard deviation is referred to as Monte Carlo error. Thus, to halve the Monte Carlo error the number of i.i.d. samples needs to be quadrupled.
In most cases of practical interest, we cannot directly generate i.i.d. samples
 $X_{i}$
from
 $\unicode[STIX]{x1D707}$
and must therefore resort to Markov chain Monte Carlo methods.
5.2 Markov chain Monte Carlo methods
Recall that a Markov chain with state space
 $\mathbb{R}^{D}$
is a sequence of random
 $D$
-vectors
 $\{X_{i}\}_{i\in \mathbb{N}}$
that satisfies the Markov property
 $$\begin{eqnarray}\mathbb{P}(X_{i+1}\in A\mid X_{1},\ldots ,X_{i})=\mathbb{P}(X_{i+1}\in A\mid X_{i})\end{eqnarray}$$
for all measurable sets
 $A$
. In other words, given the past history of the chain
 $X_{1},\ldots ,X_{i}$
, the only information required to update the state of the chain is the current state
 $X_{i}$
. Here our interest is restricted to (time-) homogeneous chains, that is, to cases where
 $\mathbb{P}(X_{i+1}\in A\mid X_{i})$
is independent of
 $i$
.
Typically one constructs a homogeneous Markov chain in terms of its transition probabilities
 $\unicode[STIX]{x1D6F1}_{x}$
,
 $x\in \mathbb{R}^{D}$
. These are the probabilities
 $$\begin{eqnarray}\unicode[STIX]{x1D6F1}_{x}(A)=\mathbb{P}(X_{i+1}\in A\mid X_{i}=x),\end{eqnarray}$$
with
 $i\in \mathbb{N}$
and
 $A$
measurable. Often
 $\unicode[STIX]{x1D6F1}_{x}$
may be computed as
 $$\begin{eqnarray}\unicode[STIX]{x1D6F1}_{x}(A)=\int _{A}\unicode[STIX]{x1D6F1}_{x}(\text{d}x^{\prime }),\end{eqnarray}$$
for a suitable kernel
 $\unicode[STIX]{x1D6F1}_{x}(\text{d}x^{\prime })$
. Clearly the chain is determined once the transition probabilities and the distribution of
 $X_{1}$
are known. In practice, the term ‘chain’ is used in a wide sense to refer to the transition probabilities without specifying the distribution of
 $X_{1}$
.
A probability distribution
 $\unicode[STIX]{x1D708}$
is an invariant or stationary distribution of a Markov chain with transition probabilities
 $\unicode[STIX]{x1D6F1}_{x}$
if
 $$\begin{eqnarray}\int _{\mathbb{R}^{D}}\unicode[STIX]{x1D6F1}_{x}(A)\unicode[STIX]{x1D708}(\text{d}x)=\int _{A}\unicode[STIX]{x1D708}(\text{d}x)\end{eqnarray}$$
holds for all measurable sets
 $A$
. We also say that
 $\unicode[STIX]{x1D6F1}_{x}$
preserves
 $\unicode[STIX]{x1D708}$
. In the situations we are interested in, a Markov chain will have a unique invariant distribution. If
 $\unicode[STIX]{x1D708}$
is the invariant distribution of the chain and in addition
 $X_{1}\sim \unicode[STIX]{x1D708}$
, one says that the chain is at stationarity.
Markov chain Monte Carlo (MCMC) methods generate a Markov chain
 $\{X_{i}\}_{i\in \mathbb{N}}$
that has the target
 $\unicode[STIX]{x1D707}$
as an invariant distribution and estimate
 $\unicode[STIX]{x1D707}(F)$
by the average (5.2). By analogy to the simple i.i.d. situation described above, one would like to have MCMC methods that meet two basic requirements.
∙ For each
$F:\mathbb{R}^{D}\rightarrow \mathbb{R}$
such that
$\unicode[STIX]{x1D707}(F)<\infty$
, (5.4)This is the MCMC analogue of the law of large numbers.$$\begin{eqnarray}\bar{F}_{N}\overset{\text{a.s.}}{\rightarrow }\unicode[STIX]{x1D707}(F)\quad \text{as }N\rightarrow \infty .\end{eqnarray}$$
∙ For each
$F:\mathbb{R}^{D}\rightarrow \mathbb{R}$
such that
$\unicode[STIX]{x1D707}(F)<\infty$
and
$\unicode[STIX]{x1D70E}_{0}(F)<\infty$
, (5.5)for some$$\begin{eqnarray}N^{1/2}(\bar{F}_{N}-\unicode[STIX]{x1D707}(F))\overset{d}{\rightarrow }{\mathcal{N}}(0,\unicode[STIX]{x1D70E}(F)^{2})\quad \text{as }N\rightarrow \infty ,\end{eqnarray}$$
$\unicode[STIX]{x1D70E}(F)$
. This is the MCMC analogue of the central limit theorem.


For each fixed function
 $F$
and Markov chain
 $\{X_{i}\}_{i\in \mathbb{N}}$
, the constant
 $\unicode[STIX]{x1D70E}(F)^{2}$
appearing in (5.5) is called the asymptotic variance of the MCMC estimator
 $\bar{F}_{N}$
. A straightforward calculation shows that this asymptotic variance satisfies
 $$\begin{eqnarray}\unicode[STIX]{x1D70E}(F)^{2}=\unicode[STIX]{x1D70E}_{0}(F)^{2}+2\mathop{\sum }_{i>1}\operatorname{cov}_{\unicode[STIX]{x1D707}}(F(X_{1}),F(X_{i})),\end{eqnarray}$$
where
 $\unicode[STIX]{x1D70E}_{0}(F)$
is defined in (5.3) and the covariances are computed assuming that the chain is at stationarity. If the
 $X_{i}$
were independent, all the covariances
 $\operatorname{cov}_{\unicode[STIX]{x1D707}}(F(X_{1}),F(X_{i}))$
would vanish and we would recover the standard central limit theorem. Since, in most interesting cases, the
 $X_{i}$
in the Markov chain are not mutually independent,
 $\unicode[STIX]{x1D70E}(F)$
is often larger than
 $\unicode[STIX]{x1D70E}_{0}(F)$
. Generally speaking it is desirable to have low values of
 $\operatorname{cov}_{\unicode[STIX]{x1D707}}(X_{1},X_{i})$
so that
 $\unicode[STIX]{x1D70E}(F)$
is not far away from
 $\unicode[STIX]{x1D70E}_{0}(F)$
for each
 $F$
.
In practice, the inputs that the user has to supply to an MCMC algorithm include the following.
∙ A sample of the initial state
$X_{1}$
. Ideally, this sample should be taken in a domain of state space of high probability. Otherwise the chain may need many steps to start generating useful samples. A discussion of this issue is beyond the scope of this paper.∙ A possibly non-normalized density function
$\unicode[STIX]{x1D70C}$
of the target
$\unicode[STIX]{x1D707}$
, that is, the probability density function is
$Z^{-1}\unicode[STIX]{x1D70C}(x)$
, where
$Z=\int _{\mathbb{R}^{D}}\unicode[STIX]{x1D70C}(x)\,\text{d}x$
is not assumed to be
$1$
; the value of
$Z$
is not required to run the algorithms.


5.3 Metropolis method for reversible maps
The replacement of the i.i.d. variables that simple Monte Carlo uses in the estimator (5.2) with variables of a Markov chain is of interest because it is not difficult to construct a chain that has a given target
 $\unicode[STIX]{x1D707}$
as an invariant distribution. The key to this construction is the Metropolis–Hastings accept/reject mechanism, which turns a given proposal chain (for which
 $\unicode[STIX]{x1D707}$
is not invariant) into a Metropolized chain, which leaves
 $\unicode[STIX]{x1D707}$
invariant. The simplest Metropolis rule was introduced in 1953 in a landmark paper (Metropolis et al.
Reference Metropolis, Rosenbluth, Rosenbluth, Teller and Teller1953); later, Hastings provided an important generalization (Hastings Reference Hastings1970).
A review of the Metropolis–Hastings rule is not required for our purposes. However, we shall present a trimmed-down variant of Metropolis–Hastings that we will use to define HMC. This variant works in the special case where the target
 $\unicode[STIX]{x1D707}$
is invariant with respect to a linear involution, takes as input a reversible deterministic map, and manufactures a Markov chain that preserves
 $\unicode[STIX]{x1D707}$
. While the chain that we construct is not expected to satisfy a law of large numbers and therefore has no practical merit, Proposition 5.2 will be used later to analyse HMC methods.
The technique, patterned after Fang, Sanz-Serna and Skeel (Reference Fang, Sanz-Serna and Skeel2014), requires a non-normalized density function
 $\unicode[STIX]{x1D70C}:\mathbb{R}^{D}\rightarrow \mathbb{R}$
of the target, and, as pointed out above, a map
 $\unicode[STIX]{x1D6F7}:\mathbb{R}^{D}\rightarrow \mathbb{R}^{D}$
that is reversible with respect to a linear involution
 $S$
that preserves probability, that is,
 $\unicode[STIX]{x1D70C}\circ S=\unicode[STIX]{x1D70C}$
. The accept/reject mechanism is based on the acceptance probability
 $\unicode[STIX]{x1D6FC}:\mathbb{R}^{D}\rightarrow [0,1]$
defined as
 $$\begin{eqnarray}\unicode[STIX]{x1D6FC}(x)=\min \biggl\{1,\displaystyle \frac{\unicode[STIX]{x1D70C}(\unicode[STIX]{x1D6F7}(x))}{\unicode[STIX]{x1D70C}(x)}|\text{det}\,\unicode[STIX]{x1D6F7}^{\prime }(x)|\biggr\}\end{eqnarray}$$
(
 $\unicode[STIX]{x1D6F7}^{\prime }$
is the Jacobian matrix of
 $\unicode[STIX]{x1D6F7}$
).
We consider the following algorithm.
Algorithm 5.1 (Metropolized reversible map).
Given
 $X_{0}\in \mathbb{R}^{D}$
(the input state), the method outputs a state
 $X_{1}$
as follows.
- Step 1.
Generate a proposal move
$\tilde{X}_{1}=\unicode[STIX]{x1D6F7}(X_{0})$
.- Step 2.
Output
$X_{1}=\unicode[STIX]{x1D6FE}\tilde{X}_{1}+(1-\unicode[STIX]{x1D6FE})S(X_{0})$
, where
$\unicode[STIX]{x1D6FE}$
is a Bernoulli random variable with parameter
$\unicode[STIX]{x1D6FC}(X_{0})$
(i.e.
$\unicode[STIX]{x1D6FE}$
is
$1$
with probability
$\unicode[STIX]{x1D6FC}(X_{0})$
and
$0$
with probability
$1-\unicode[STIX]{x1D6FC}(X_{0})$
).


Step 2 contains the accept/reject mechanism. In the case of acceptance the updated state coincides with the state proposed
 $\tilde{X}_{1}$
from Step 1; in the case of rejection the updated state is
 $S(X_{0})$
. Note that for rejection, conventional Metropolis mechanisms set the updated state of the chain to be
 $X_{0}$
.
Proposition 5.2. In the situation described above, let
 $\{X_{i}\}_{i\in \mathbb{N}}$
be the Markov chain defined by iterating Algorithm 5.1. Then the target distribution is an invariant distribution of this chain.
Proof. The transition kernel of
 $\{X_{i}\}_{i\in \mathbb{N}}$
is given by
 $$\begin{eqnarray}\unicode[STIX]{x1D6F1}_{x}(\text{d}x^{\prime })=\unicode[STIX]{x1D6FC}(x)\unicode[STIX]{x1D6FF}(x^{\prime }-\unicode[STIX]{x1D6F7}(x))\,\text{d}x^{\prime }+(1-\unicode[STIX]{x1D6FC}(x))\unicode[STIX]{x1D6FF}(x^{\prime }-S(x))\,\text{d}x^{\prime },\end{eqnarray}$$
where
 $\unicode[STIX]{x1D6FF}(\cdot )$
is the Dirac-delta function. Hence, for any measurable set
 $A$
, if
 $1_{A}(x)$
denotes the corresponding indicator function,
 $$\begin{eqnarray}\displaystyle & & \displaystyle \int _{\mathbb{R}^{D}}\unicode[STIX]{x1D6F1}_{x}(A)\unicode[STIX]{x1D70C}(x)\,\text{d}x=\int _{A}\unicode[STIX]{x1D70C}(x)\,\text{d}x\nonumber\\ \displaystyle & & \displaystyle \qquad +\int _{\mathbb{R}^{D}}\unicode[STIX]{x1D6FC}(x)\unicode[STIX]{x1D70C}(x)1_{A}(\unicode[STIX]{x1D6F7}(x))\,\text{d}x-\int _{\mathbb{R}^{D}}\unicode[STIX]{x1D6FC}(x)\unicode[STIX]{x1D70C}(x)1_{A}(S(x))\,\text{d}x.\nonumber\end{eqnarray}$$
By change of variables in the third integral,
 $$\begin{eqnarray}\displaystyle & & \displaystyle \int _{\mathbb{R}^{D}}\unicode[STIX]{x1D6F1}_{x}(A)\unicode[STIX]{x1D70C}(x)\,\text{d}x=\int _{A}\unicode[STIX]{x1D70C}(x)\,\text{d}x\nonumber\\ \displaystyle & & \displaystyle \qquad +\int _{\mathbb{R}^{D}}\unicode[STIX]{x1D6FC}(x)\unicode[STIX]{x1D70C}(x)1_{A}(\unicode[STIX]{x1D6F7}(x))\,\text{d}x\nonumber\\ \displaystyle & & \displaystyle \qquad -\int _{\mathbb{R}^{D}}\unicode[STIX]{x1D6FC}(S(\unicode[STIX]{x1D6F7}(x)))|\text{det}\,\unicode[STIX]{x1D6F7}^{\prime }(x)|\unicode[STIX]{x1D70C}(\unicode[STIX]{x1D6F7}(x))1_{A}(\unicode[STIX]{x1D6F7}(x))\,\text{d}x,\nonumber\end{eqnarray}$$
where we used the hypothesis that
 $\unicode[STIX]{x1D70C}\circ S=\unicode[STIX]{x1D70C}$
. The last two terms on the right-hand side of this equation cancel because
 $$\begin{eqnarray}\displaystyle \unicode[STIX]{x1D6FC}(S(\unicode[STIX]{x1D6F7}(x))) & = & \displaystyle \min \biggl\{1,\displaystyle \frac{\unicode[STIX]{x1D70C}(x)}{\unicode[STIX]{x1D70C}(\unicode[STIX]{x1D6F7}(x))}|\text{det}\,\unicode[STIX]{x1D6F7}^{\prime }(x)|^{-1}\biggr\}\nonumber\\ \displaystyle & = & \displaystyle \unicode[STIX]{x1D6FC}(x)\unicode[STIX]{x1D70C}(x)\displaystyle \frac{1}{\unicode[STIX]{x1D70C}(\unicode[STIX]{x1D6F7}(x))}|\text{det}\,\unicode[STIX]{x1D6F7}^{\prime }(x)|^{-1},\nonumber\end{eqnarray}$$
which follows from the reversibility of
 $\unicode[STIX]{x1D6F7}$
, the hypothesis
 $\unicode[STIX]{x1D70C}\circ S=\unicode[STIX]{x1D70C}$
and Proposition 2.8.☐
5.4 The HMC method: basic idea
We consider a target distribution
 $\unicode[STIX]{x1D6F1}$
in
 $\mathbb{R}^{d}$
. If
 ${\mathcal{U}}:\mathbb{R}^{d}\rightarrow \mathbb{R}$
denotes the negative logarithm of the (not necessarily normalized) probability density function of the target, then
 $$\begin{eqnarray}\unicode[STIX]{x1D6F1}(\text{d}q)=Z_{q}^{-1}\exp (-{\mathcal{U}}(q))\,\text{d}q,\quad \text{where }Z_{q}=\int _{\mathbb{R}^{d}}\exp (-{\mathcal{U}}(q))\,\text{d}q.\end{eqnarray}$$
The Monte Carlo algorithms studied here use
 ${\mathcal{U}}$
but do not require knowledge of the normalization factor
 $Z_{q}$
. In HMC, regardless of the application in mind,
 ${\mathcal{U}}$
is seen as the potential energy of a mechanical system with coordinates
 $q$
. Then auxiliary momenta
 $p\in \mathbb{R}^{d}$
and a quadratic kinetic energy function
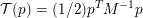 ${\mathcal{T}}(p)=(1/2)p^{T}M^{-1}p$
are introduced as in (2.10) (
 $M$
is a positive-definite symmetric matrix chosen by the user).Footnote
9
The total energy of this fictitious mechanical system is
 $H={\mathcal{T}}+{\mathcal{U}}$
and the equations of motion are given in (2.9).
Example 5.3. In the particular case where the target
 $\unicode[STIX]{x1D707}$
is Gaussian with non-normalized density
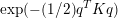 $\exp (-(1/2)q^{T}Kq)$
,
 $q\in \mathbb{R}^{d}$
, we have
 $$\begin{eqnarray}{\mathcal{U}}(q)=(1/2)q^{T}Kq,\end{eqnarray}$$
which leads to the Hamiltonian (3.27) discussed above. For a univariate standard normal target,
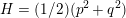 $H=(1/2)(p^{2}+q^{2})$
and Hamilton’s equations reduce to those of harmonic oscillator (2.3).
The Boltzmann–Gibbs distribution in
 $\mathbb{R}^{2d}$
corresponding to
 $H$
was discussed earlier in connection with Theorem 2.7. This distribution is defined as
 $$\begin{eqnarray}\displaystyle \unicode[STIX]{x1D6F1}_{BG}(\text{d}q,\text{d}p) & = & \displaystyle (2\unicode[STIX]{x1D70B})^{-d/2}|\text{det}\,M|^{-1/2}\exp \biggl(-\displaystyle \frac{1}{2}p^{T}M^{-1}p\biggr)\nonumber\\ \displaystyle & & \displaystyle \quad \times \,Z_{q}^{-1}\exp (-{\mathcal{U}}(q))\,\text{d}q\,\text{d}p\end{eqnarray}$$
(for simplicity the inverse temperature is taken here to be
 $\unicode[STIX]{x1D6FD}=1$
). Clearly the target
 $\unicode[STIX]{x1D6F1}$
is the
 $q$
-marginal of
 $\unicode[STIX]{x1D6F1}_{BG}$
. The
 $p$
-marginal is Gaussian with zero mean and covariance matrix
 $M$
; therefore samples from this marginal are easily available (and will be put to use in the algorithms below). A key fact for our purposes: Hamilton’s equations of motion (2.9) preserve
 $\unicode[STIX]{x1D6F1}_{BG}$
(Theorem 2.7).
HMC generates (correlated) samples
 $(q_{i},p_{i})\in \mathbb{R}^{2d}$
by means of a Markov chain that leaves
 $\unicode[STIX]{x1D6F1}_{BG}$
invariant; the corresponding marginal
 $q_{i}\in \mathbb{R}^{d}$
chain then leaves invariant the target distribution
 $\unicode[STIX]{x1D6F1}$
. The basic idea of HMC is encapsulated in the following algorithm (the duration
 $\unicode[STIX]{x1D706}>0$
is a – deterministic – parameter, whose value is specified by the user).
Algorithm 5.4 (exact HMC).
Let
 $\unicode[STIX]{x1D706}>0$
denote the duration parameter.
Given the current state of the chain
 $(q_{0},p_{0})\in \mathbb{R}^{2d}$
, the method outputs a state
 $(q_{1},p_{1})\in \mathbb{R}^{2d}$
as follows.
- Step 1.
Generate a
$d$
-dimensional random vector
$\unicode[STIX]{x1D709}_{0}\sim {\mathcal{N}}(0,M)$
.- Step 2.
Evolve over the time interval
$[0,\unicode[STIX]{x1D706}]$
Hamilton’s equations (2.9) with initial condition
$(q(0),p(0))=(q_{0},\unicode[STIX]{x1D709}_{0})$
.- Step 3.
Output
$(q_{1},p_{1})=(q(\unicode[STIX]{x1D706}),p(\unicode[STIX]{x1D706}))$
.


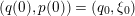
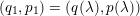
Note that
 $p_{0}$
plays no role, since the initial condition starts from
 $\unicode[STIX]{x1D709}_{0}$
. Step 1 is referred to as momentum refreshment or momentum randomization.
It is easy to see that this algorithm succeeds in preserving the distribution
 $\unicode[STIX]{x1D6F1}_{BG}$
.
Theorem 5.5. Consider the Markov chain
 $\{(q_{i},p_{i})\}_{i\in \mathbb{N}}$
defined by iterating Algorithm 5.4. The probability distribution
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
in (5.7) is an invariant distribution of this chain.
Proof. The transformation
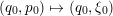 $(q_{0},p_{0})\mapsto (q_{0},\unicode[STIX]{x1D709}_{0})$
obviously preserves the Boltzmann–Gibbs distribution. The same is true for the transformation
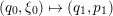 $(q_{0},\unicode[STIX]{x1D709}_{0})\mapsto (q_{1},p_{1})$
, as we saw in Theorem 2.7.☐
The transition kernel of this chain is given by
 $$\begin{eqnarray}\unicode[STIX]{x1D6F1}_{(q,p)}(\text{d}q^{\prime },\text{d}p^{\prime })=\mathbb{E}\{\unicode[STIX]{x1D6FF}((q^{\prime },p^{\prime })-\unicode[STIX]{x1D711}_{\unicode[STIX]{x1D706}}(q,\unicode[STIX]{x1D709}))\}\,\text{d}q^{\prime }\,\text{d}p^{\prime },\end{eqnarray}$$
where the expected value is over
 $\unicode[STIX]{x1D709}\sim {\mathcal{N}}(0,M)$
.
The most appealing feature of the algorithm is that if
 $\unicode[STIX]{x1D706}$
is sufficiently large, we may hope that the Markov transitions
 $i\rightarrow i+1$
produce values
 $q_{i+1}$
far away from
 $q_{i}$
, thus reducing the correlations in the chain and facilitating the exploration of the target distribution.
5.5 Numerical HMC
Algorithm 5.4 cannot be used in practice because in the cases of interest the exact solution flow
 $\unicode[STIX]{x1D711}_{\unicode[STIX]{x1D706}}$
of Hamilton’s equations is not available. It is then necessary to resort to numerical approximations to
 $\unicode[STIX]{x1D711}_{\unicode[STIX]{x1D706}}$
, but, as pointed out in Section 4, numerical methods cannot preserve volume in phase space and energy and therefore do not preserve exactly the Boltzmann–Gibbs distribution. To correct the bias introduced by the time discretization error, the numerical solution is Metropolized using Algorithm 5.1. However, this requires the numerical integrator to be reversible.
Let
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}$
denote a numerical approximation of
 $\unicode[STIX]{x1D711}_{\unicode[STIX]{x1D706}}$
(more precisely, if the step size is
 $h$
and
 $n=\lfloor \unicode[STIX]{x1D706}/h\rfloor$
is the number of steps required to integrate up to
 $t=\unicode[STIX]{x1D706}$
, then
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}=\unicode[STIX]{x1D713}_{h}^{n}$
). In order to use Algorithm 5.1 with
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}$
playing the role of
 $\unicode[STIX]{x1D6F7}$
and the momentum flip involution (2.13) playing the role of
 $S$
, we first note (Proposition 2.11) that the momentum flip involution preserves
 $H$
in (2.10) and, as a consequence, it preserves the Boltzmann–Gibbs distribution. In addition Theorem 2.10 ensures that the Hamiltonian flow is reversible with respect to this involution; it then makes sense (Theorem 4.2) to assume that the integrator chosen is such that
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}$
is also reversible. The acceptance probability in (5.6) now reads
 $$\begin{eqnarray}\unicode[STIX]{x1D6FC}(q,p)=\min \{1,\text{e}^{-\unicode[STIX]{x1D6E5}H(q,p)}|\text{det}\,\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}^{\prime }(q,p)|\},\end{eqnarray}$$
where
 $$\begin{eqnarray}\unicode[STIX]{x1D6E5}H(q,p)=H(\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}(q,p))-H(q,p)\end{eqnarray}$$
is the energy error (recall that if the integrator were exact
 $H(\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}(q,p))$
would coincide with
 $H(q,p)$
by conservation of energy, Theorem 2.6).
Algorithm 5.6 (numerical HMC).
Let
 $\unicode[STIX]{x1D706}>0$
denote the duration parameter and let
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}$
be a reversible numerical approximation to the Hamiltonian flow
 $\unicode[STIX]{x1D711}_{\unicode[STIX]{x1D706}}$
.
Given the current state of the chain
 $(q_{0},p_{0})\in \mathbb{R}^{2d}$
; the method outputs a state
 $(q_{1},p_{1})\in \mathbb{R}^{2d}$
as follows.
- Step 1.
Generate a
$d$
-dimensional random vector
$\unicode[STIX]{x1D709}_{0}\sim {\mathcal{N}}(0,M)$
.- Step 2.
Find
$\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}(q_{0},\unicode[STIX]{x1D709}_{0})$
by evolving Hamilton’s equations (2.9) with a reversible integrator over the time interval
$[0,\unicode[STIX]{x1D706}]$
with initial condition
$(q_{0},\unicode[STIX]{x1D709}_{0})$
.- Step 3.
Output
$(q_{1},p_{1})=\unicode[STIX]{x1D6FE}\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}(q_{0},\unicode[STIX]{x1D709}_{0})+(1-\unicode[STIX]{x1D6FE})(q_{0},-\unicode[STIX]{x1D709}_{0})$
, where
$\unicode[STIX]{x1D6FE}$
is a Bernoulli random variable with parameter
$\unicode[STIX]{x1D6FC}(q_{0},\unicode[STIX]{x1D709}_{0})$
with
$\unicode[STIX]{x1D6FC}$
as in (5.8).


Theorem 5.7. Consider the Markov chain
 $\{(q_{i},p_{i})\}_{i\in \mathbb{N}}$
defined by iterating Algorithm 5.6. The probability distribution
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
in (5.7) is an invariant distribution of this chain.
Proof. As in the preceding theorem, the transformation
 $(q_{0},p_{0})\mapsto (q_{0},\unicode[STIX]{x1D709}_{0})$
preserves the Boltzmann–Gibbs distribution. The same is true for the transformation
 $(q_{0},\unicode[STIX]{x1D709}_{0})\mapsto (q_{1},p_{1})$
according to Proposition 5.2.☐
The transition kernel of the chain is given by
 $$\begin{eqnarray}\displaystyle \unicode[STIX]{x1D6F1}_{(q,p)}(\text{d}q^{\prime },\text{d}p^{\prime }) & = & \displaystyle \mathbb{E}\{\unicode[STIX]{x1D6FC}(q,\unicode[STIX]{x1D709})\unicode[STIX]{x1D6FF}((q^{\prime },p^{\prime })-\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}(q,\unicode[STIX]{x1D709}))\}\,\text{d}q^{\prime }\,\text{d}p^{\prime }\nonumber\\ \displaystyle & & \displaystyle \quad +\,\mathbb{E}\{(1-\unicode[STIX]{x1D6FC}(q,\unicode[STIX]{x1D709}))\unicode[STIX]{x1D6FF}((q^{\prime },p^{\prime })-S(q,\unicode[STIX]{x1D709}))\}\,\text{d}q^{\prime }\,\text{d}p^{\prime }.\nonumber\end{eqnarray}$$
In practice, the acceptance probability (5.8) may not be readily available due to the need to compute
 $\det \unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}^{\prime }(q,p)$
. If the numerical approximation
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}$
, in addition to being assumed reversible, is also volume-preserving (as it would be for splitting integrators according to Theorem 4.1), then the determinant drops from the formula, and then the acceptance probability
 $$\begin{eqnarray}\unicode[STIX]{x1D6FC}(q,p)=\min \{1,\text{e}^{-\unicode[STIX]{x1D6E5}H(q,p)}\}\end{eqnarray}$$
becomes easily computable. Variants where preservation of volume does not take place are studied by Fang et al. (Reference Fang, Sanz-Serna and Skeel2014).
Remark 5.8. The states of the Markov chain
 $\{(q_{i},p_{i})\}_{i\in \mathbb{N}}$
are not to be confused with the intermediate values of
 $q$
and
 $p$
that the numerical integrator generates while transitioning the chain from one state of the chain to the next. Those intermediate values were denoted by
 $(q_{n},p_{n})$
in the preceding sections and we have preferred not to introduce additional notation to describe the Markov chain.
Remark 5.9. Theorems 5.5 and 5.7 show that
 $\unicode[STIX]{x1D6F1}_{\text{BG}}$
is an invariant distribution for the chains generated by Algorithms 5.4 and 5.6 respectively. However, they do not guarantee that those chains meet the two basic requirements in (5.4) and (5.5), and indeed a simple example will be presented below where the sequence of values of
 $q$
generated by those algorithms is
 $q_{0},-q_{0},q_{0},-q_{0},\ldots$
so that the requirements are not met. A detailed study of the convergence properties of HMC is beyond the scope of this paper and we limit ourselves to some remarks in Section 9.5.
5.6 Exact randomized HMC
The Hamiltonian flow in Step 2 of Algorithm 5.4 is what, in principle, enables HMC to make large moves in state space that reduce correlations in the Markov chain
 $\{q_{i}\}_{i\in \mathbb{N}}$
. Roughly speaking, one may hope that by increasing the duration
 $\unicode[STIX]{x1D706}$
,
 $q_{1}$
moves away from
 $q_{0}$
, thus reducing correlation. However, simple examples show that this outcome is far from assured.
Indeed, for the univariate standard normal target distribution in Example 5.3, the Hamiltonian flow is a rotation in the
 $(q,p)$
-plane with period
 $2\unicode[STIX]{x1D70B}$
. It is easy to see that if
 $q_{0}$
is taken from the target distribution, as
 $\unicode[STIX]{x1D706}$
increases from
 $0$
to
 $\unicode[STIX]{x1D70B}/2$
, the correlation between
 $q_{1}$
and
 $q_{0}$
decreases and for
 $\unicode[STIX]{x1D706}=\unicode[STIX]{x1D70B}/2$
,
 $q_{1}$
and
 $q_{0}$
are independent. However, increasing
 $\unicode[STIX]{x1D706}$
beyond
 $\unicode[STIX]{x1D70B}/2$
will cause an increase in the correlation, and for
 $\unicode[STIX]{x1D706}=\unicode[STIX]{x1D70B}$
,
 $q_{1}=-q_{0}$
and the chain is not ergodic. For general distributions, it is likely that a small
 $\unicode[STIX]{x1D706}$
will lead to a highly correlated chain, while choosing
 $\unicode[STIX]{x1D706}$
too large may cause the Hamiltonian trajectory to make a U-turn and fold back on itself, thus increasing correlation (Homan and Gelman Reference Homan and Gelman2014). Generally speaking, the performance of HMC may be very sensitive to changes in
 $\unicode[STIX]{x1D706}$
, as first noted by Mackenzie (Reference Mackenzie1989). In order to increase the robustness of the algorithm, Mackenzie suggested randomly varying
 $\unicode[STIX]{x1D706}$
from one Markov transition to the next, and for that purpose he used a uniform distribution in the interval
 $[\unicode[STIX]{x1D706}_{\text{min}},\unicode[STIX]{x1D706}_{\text{max}}]$
.
Recently Bou-Rabee and Sanz-Serna (Reference Bou-Rabee and Sanz-Serna2017) have studied an algorithm where the lengths of the time intervals of integration of the Hamiltonian dynamics at the different transitions of the Markov chain are independent and identically distributed exponential random variables with mean
 $\unicode[STIX]{x1D706}$
; these durations are of course taken to be independent of the state of the chain. The algorithm is then as follows.
Algorithm 5.10 (exact RHMC).
Given the current state of the chain
 $(q_{0},p_{0})\in \mathbb{R}^{2d}$
, the algorithm outputs the state
 $(q_{1},p_{1})\in \mathbb{R}^{2d}$
as follows.
- Step 1.
Generate a
$d$
-dimensional random vector
$\unicode[STIX]{x1D709}_{0}\sim {\mathcal{N}}(0,M)$
.- Step 2.
Generate a random duration
$t\sim \operatorname{Exp}(1/\unicode[STIX]{x1D706})$
.- Step 3.
Evolve Hamilton’s equations (2.2) over the time interval
$[0,t]$
with initial condition
$(q(0),p(0))=(q_{0},\unicode[STIX]{x1D709}_{0})$
.- Step 4.
Output
$(q_{1},p_{1})=(q(t),p(t))$
.


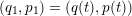
Analogous to Theorem 5.5, the probability distribution
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
in (5.7) is an invariant distribution of the Markov chain
 $\{(q_{i},p_{i})\}_{i\in \mathbb{N}}$
defined by iterating Algorithm 5.10. Analytical results and numerical experiments (Bou-Rabee and Sanz-Serna Reference Bou-Rabee and Sanz-Serna2017, §4–5) show that the dependence of the performance of Algorithm 5.10 on the mean duration parameter
 $\unicode[STIX]{x1D706}$
is simpler than the dependence of the performance of Algorithm 5.4 on its constant duration parameter.
5.7 Numerical randomized HMC
Unfortunately, the complex dependence of correlation on the duration parameter
 $\unicode[STIX]{x1D706}$
of Algorithm 5.4 is not removed by time discretization and is therefore inherited by Algorithm 5.6. For instance, for the univariate standard normal target, it is easy to check that if
 $\unicode[STIX]{x1D706}$
is close to an integer multiple of
 $\unicode[STIX]{x1D70B}$
and
 $h>0$
is suitably chosen, then a Verlet numerical integration will result, for each
 $q_{0}$
, in
 $q_{1}=-q_{0}$
(a move that will be accepted by the Metropolis–Hastings step).
To improve its performance, Algorithm 5.6 is typically operated with values of
 $h$
that are randomized (Neal Reference Neal and Brooks2011). Since, due to stability restrictions, explicit integrators cannot be used with arbitrarily large values of the time-step,
 $h$
is typically chosen from a uniform distribution in an (often narrow) interval
 $(\unicode[STIX]{x1D6E5}t_{\text{min}},\unicode[STIX]{x1D6E5}t_{\text{max}})$
. The number of time-steps
 $N$
in each integration leg is kept constant, and therefore the length of the integration intervals is random with a uniform distribution in
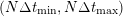 $(N\unicode[STIX]{x1D6E5}t_{\text{min}},N\unicode[STIX]{x1D6E5}t_{\text{max}})$
. Even after such a randomization, the fact remains that increasing the duration parameter will increase the computational cost of each integration leg and may impair the quality of the sampling.
Several modifications of Algorithm 5.10 that use numerical integration are suggested in Bou-Rabee and Sanz-Serna (Reference Bou-Rabee and Sanz-Serna2017). The most obvious of them approximates the Hamiltonian flow in Step 3 by a volume-preserving reversible integrator (such as Verlet) operated with a fixed step size
 $h$
and with the number of integration steps
 $m$
at the different transitions of the Markov chain being independent and identically distributed geometric random variables with mean
 $\unicode[STIX]{x1D706}/h$
. These random numbers are of course taken to be independent of the state of the chain. As in Algorithm 5.6, one needs an accept/reject mechanism to remove the bias due to the energy errors introduced by this integrator.
Algorithm 5.11 (numerical RHMC).
Let
 $\unicode[STIX]{x1D706}>0$
denote the duration parameter and let
 $\unicode[STIX]{x1D713}_{h}$
be a reversible numerical approximation of the Hamiltonian flow
 $\unicode[STIX]{x1D711}_{h}$
.
Given the current state of the chain
 $(q_{0},p_{0})\in \mathbb{R}^{2d}$
, the algorithm outputs the state
 $(q_{1},p_{1})\in \mathbb{R}^{2d}$
as follows.
- Step 1.
Generate a
$d$
-dimensional random vector
$\unicode[STIX]{x1D709}_{0}\sim {\mathcal{N}}(0,M)$
.- Step 2.
Generate a geometric random variable
$m$
supported on the set
$\{1,2,3,\ldots \}$
and with mean
$\unicode[STIX]{x1D706}/h$
.- Step 3.
Output
$(q_{1},p_{1})=\unicode[STIX]{x1D6FE}\unicode[STIX]{x1D713}_{h}^{m}(q_{0},\unicode[STIX]{x1D709}_{0})+(1-\unicode[STIX]{x1D6FE})(q_{0},-\unicode[STIX]{x1D709}_{0})$
, where
$\unicode[STIX]{x1D6FE}$
is a Bernoulli random variable with parameter
$\unicode[STIX]{x1D6FC}$
defined as in (5.9).


Analogous to Theorem 5.7, the probability distribution
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
in (5.7) is an invariant distribution of the Markov chain
 $\{(q_{i},p_{i})\}_{i\in \mathbb{N}}$
defined by iterating Algorithm 5.11.
In the remainder of this paper our attention is focused on Algorithm 5.6. Experiments based on Algorithm 5.11 are reported in Section 8.2 and an example that illustrates the effects of randomization of
 $h$
and
 $\unicode[STIX]{x1D706}$
is presented in Section 9.3.
6 Numerical integration and HMC
The computational work in HMC stems mainly from the cost of the evaluations of the force
 $-\unicode[STIX]{x1D6FB}{\mathcal{U}}$
that are required in the numerical integration to be carried out at each transition of the Markov chain (Step 2 of Algorithm 5.6). If the dimension
 $d$
of
 $q$
is high, those evaluations are likely to be expensive; for instance, in a molecular dynamics study of a macromolecule with
 $N\gg 1$
atoms,
 $d=3N$
and each atom typically interacts with all others, so that the complexity of evaluating
 $-\unicode[STIX]{x1D6FB}{\mathcal{U}}$
grows like
 $N^{2}$
. As in any other numerical integration, the aim is to reach a target accuracy with the minimum possible complexity. Specific to the HMC scenario is the fact that, in the event of rejection in Step 3, the algorithm wastes all of the force evaluations used to compute
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}(q,\unicode[STIX]{x1D709})$
. In addition, when a rejection occurs at a transition
 $i\rightarrow i+1$
of the Markov chain, the new value
 $q_{i+1}$
coincides with the old
 $q_{i}$
, and this contributes to an increase in the correlations along the chain, which degrades the quality of sampling as pointed out when discussing the central limit theorem in (5.5). Since low acceptance rates are unwelcome and the acceptance probability (5.9) is a function of the energy error
 $\unicode[STIX]{x1D6E5}H(q,p)=H(\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}(q,p))-H(q,p)$
, it is important to perform the integration so as to have small energy errors. In this connection we recall from Section 4 that symplectic integrators conserve energy with errors that are
 $O(h^{\unicode[STIX]{x1D708}})$
over exponentially long time intervals. In this way, the symplecticness of the integrator plays a dual role in HMC. On the one hand, it ensures conservation of volume, thereby making it possible to have the simple expression (5.9) for the acceptance probability. On the other hand, it ensures favourable energy errors even if the integration legs are very long.
An additional point: the sign of the error matters. Formula (5.9) shows that, if the integration starts from a point
 $(q,p)$
for which
 $\unicode[STIX]{x1D6E5}<0$
, then
 $\unicode[STIX]{x1D6FC}=1$
, leading to acceptance.
This section begins with a key result, Theorem 6.2, which shows that for reversible volume-preserving integrators the energy error is on average much smaller than one may have anticipated. After that we study in detail the model case of Gaussian targets and discuss the construction of integrators more efficient than Verlet.
6.1 Mean energy error
Step 2 in Algorithm 5.6 requires a volume-preserving reversible integrator if (5.9) is to be used. As we shall discuss now, those geometric properties have a direct impact on the mean energy error. We begin with an auxiliary result (Beskos et al. Reference Beskos, Pillai, Roberts, Sanz-Serna and Stuart2013, Lemma 3.3) that holds for any volume-preserving reversible map.
Proposition 6.1. Let
 $\unicode[STIX]{x1D6F9}:\mathbb{R}^{2d}\rightarrow \mathbb{R}^{2d}$
be a volume-preserving bijection that is reversible with respect to the momentum flip involution (2.13), and set
 $\unicode[STIX]{x1D6E5}(q,p)=H(\unicode[STIX]{x1D6F9}(q,p))-H(q,p)$
. If
 $g$
is an odd real function of a real variable, then
 $$\begin{eqnarray}\int _{\mathbb{R}^{2d}}g(\unicode[STIX]{x1D6E5}(q,p))\,\text{e}^{-H(q,p)}\,\text{d}q\,\text{d}p=-\int _{\mathbb{ R}^{2d}}g(\unicode[STIX]{x1D6E5}(q,p))\,\text{e}^{-H(\unicode[STIX]{x1D6F9}(q,p))}\,\text{d}q\,\text{d}p,\end{eqnarray}$$
provided that one of the integrals exists. If
 $g$
is even, then
 $$\begin{eqnarray}\int _{\mathbb{R}^{2d}}g(\unicode[STIX]{x1D6E5}(q,p))\,\text{e}^{-H(q,p)}\,\text{d}q\,\text{d}p=\int _{\mathbb{ R}^{2d}}g(\unicode[STIX]{x1D6E5}(q,p))\,\text{e}^{-H(\unicode[STIX]{x1D6F9}(q,p))}\,\text{d}q\,\text{d}p,\end{eqnarray}$$
provided that one of the integrals exists.
Proof. By a change of variables under the map
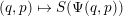 $(q,p)\mapsto S(\unicode[STIX]{x1D6F9}(q,p))$
,
 $$\begin{eqnarray}\displaystyle \int _{\mathbb{R}^{2d}}g(\unicode[STIX]{x1D6E5}(q,p))\,\text{e}^{-H(q,p)}\,\text{d}q\,\text{d}p & = & \displaystyle \int _{\mathbb{R}^{2d}}g(\unicode[STIX]{x1D6E5}(S(\unicode[STIX]{x1D6F9}(q,p))))\,\text{e}^{-H(S(\unicode[STIX]{x1D6F9}(q,p)))}\,\text{d}q\,\text{d}p\nonumber\\ \displaystyle & = & \displaystyle \int _{\mathbb{R}^{2d}}g(-\unicode[STIX]{x1D6E5}(q,p))\,\text{e}^{-H(\unicode[STIX]{x1D6F9}(q,p))}\,\text{d}q\,\text{d}p,\nonumber\end{eqnarray}$$
where in the first step we used that both
 $S$
and
 $\unicode[STIX]{x1D6F9}$
preserve volume and in the second we took into account that
 $S$
leaves
 $H$
invariant and that the reversibility of
 $\unicode[STIX]{x1D6F9}$
implies
 $$\begin{eqnarray}\unicode[STIX]{x1D6E5}(q,p)=-\unicode[STIX]{x1D6E5}(S(\unicode[STIX]{x1D6F9}(q,p))).\end{eqnarray}$$
☐
A univariate target with probability modes at
 $q=\pm 1$
, leading to a double-well potential
 ${\mathcal{U}}$
. The continuous lines are contours of constant
 $H$
. The symmetry of the contours with respect to the axis
 $p=0$
is a consequence of the reversibility of the Hamiltonian flow. The solutions of Hamilton’s equations move from left to right when
 $p>0$
and from right to left when
 $p<0$
, so when contours are reflected over the horizontal axis the arrow of time is reversed. If a reversible
 $\unicode[STIX]{x1D6F9}$
maps
 $(q_{0},p_{0})$
into
 $(q^{\ast },p^{\ast })$
, it has to map
 $(q^{\ast },-p^{\ast })$
into
 $(q_{0},p_{0})$
, so as to preserve the symmetry of the figure. The transition
 $(q_{0},p_{0})\mapsto (q^{\ast },p^{\ast })$
has an increase in energy and
 $(q^{\ast },-p^{\ast })\mapsto (q_{0},p_{0})$
decreases energy in exactly the same amount; this is the content of formula (6.1).

We now use the proposition to bound the average of
 $\unicode[STIX]{x1D6E5}$
.
Theorem 6.2. Let
 $\unicode[STIX]{x1D6F9}:\mathbb{R}^{2d}\rightarrow \mathbb{R}^{2d}$
be a bijection that is volume-preserving and reversible with respect to the momentum flip involution (2.13). If the integral
 $$\begin{eqnarray}m_{\unicode[STIX]{x1D6E5}}=\int _{\mathbb{R}^{2d}}\unicode[STIX]{x1D6E5}(q,p)\,\text{e}^{-H(q,p)}\,\text{d}q\,\text{d}p,\end{eqnarray}$$
with
 $\unicode[STIX]{x1D6E5}(q,p)=H(\unicode[STIX]{x1D6F9}(q,p))-H(q,p)$
, exists, then
 $$\begin{eqnarray}0\leq m_{\unicode[STIX]{x1D6E5}}\leq \int _{\mathbb{R}^{2d}}\unicode[STIX]{x1D6E5}(q,p)^{2}\,\text{e}^{-H(q,p)}\,\text{d}q\,\text{d}p.\end{eqnarray}$$
Furthermore the first inequality is strict except in the trivial case where
 $\unicode[STIX]{x1D6E5}(q,p)$
vanishes for each
 $(q,p)$
.
Proof. By using the preceding proposition with
 $g(x)=x$
, we get
 $$\begin{eqnarray}m_{\unicode[STIX]{x1D6E5}}=\displaystyle \frac{1}{2}\int _{\mathbb{R}^{2d}}\unicode[STIX]{x1D6E5}(q,p)(1-\text{e}^{-\unicode[STIX]{x1D6E5}(q,p)})\,\text{e}^{-H(q,p)}\,\text{d}q\,\text{d}p.\end{eqnarray}$$
The inequality
 $x(1-\text{e}^{-x})>0$
, valid for all real
 $x\neq 0$
, yields the lower bound in (6.3).
For the upper bound, we apply the inequality
 $|\text{e}^{x}-1|\leq |x|(\text{e}^{x}+1)$
, valid for all
 $x\in \mathbb{R}$
, to obtain
 $$\begin{eqnarray}\displaystyle m_{\unicode[STIX]{x1D6E5}} & \leq & \displaystyle \displaystyle \frac{1}{2}\int _{\mathbb{R}^{2d}}|\unicode[STIX]{x1D6E5}(q,p)|\,|1-\text{e}^{-\unicode[STIX]{x1D6E5}(q,p)}|\,\text{e}^{-H(q,p)}\,\text{d}q\,\text{d}p\nonumber\\ \displaystyle & \leq & \displaystyle \displaystyle \frac{1}{2}\int _{\mathbb{R}^{2d}}\unicode[STIX]{x1D6E5}(q,p)^{2}(1+\text{e}^{-\unicode[STIX]{x1D6E5}(q,p)})\,\text{e}^{-H(q,p)}\,\text{d}q\,\text{d}p\nonumber\\ \displaystyle & \leq & \displaystyle \int _{\mathbb{R}^{2d}}\unicode[STIX]{x1D6E5}(q,p)^{2}\,\text{e}^{-H(q,p)}\,\text{d}q\,\text{d}p.\nonumber\end{eqnarray}$$
In the last step we used Proposition 6.1 with
 $g(x)=x^{2}$
.☐
Figure 6.1 illustrates the geometry behind formula (6.1). The figure makes clear that to each initial condition
 $(q_{0},p_{0})$
with an energy increase
 $\unicode[STIX]{x1D6E5}\geq 0$
there corresponds an initial condition
 $(q^{\ast },-p^{\ast })$
with an energy decrease of the same magnitude. In the integrand in (6.2) the energy increase at
 $(q_{0},p_{0})$
is weighed by
 $\exp (-H(q_{0},p_{0}))$
, a larger factor than the weight
 $\exp (-H(q^{\ast },-p^{\ast }))$
of the corresponding energy decrease. In addition, by conservation of volume, if
 $(q_{0},p_{0})$
ranges in a small domain, then the corresponding points
 $(q^{\ast },-p^{\ast })$
range in a small domain of the same measure. This explains why the integral (6.2) is positive.
We are of course interested in applying Theorem 6.2 to the case where
 $\unicode[STIX]{x1D6F9}$
is the map
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}$
in Step 2 of Algorithm 5.6 (numerical HMC). Assume for simplicity that
 $\unicode[STIX]{x1D706}/h$
is an integer, so that
 $t=\unicode[STIX]{x1D706}$
coincides with one of the step points of the numerical integration. Then the energy error satisfies pointwise, that is, at each fixed
 $(q,p)$
,
 $$\begin{eqnarray}\unicode[STIX]{x1D6E5}(p,q)=H(\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}(q,p))-H(q,p)=[H(\unicode[STIX]{x1D711}_{\unicode[STIX]{x1D706}}(q,p))+O(h^{\unicode[STIX]{x1D708}})]-H(q,p)=O(h^{\unicode[STIX]{x1D708}}),\end{eqnarray}$$
where
 $\unicode[STIX]{x1D708}$
is the order of the integrator and we have successively used the convergence result in Theorem 3.2 and conservation of energy (Theorem 2.6). The bounds in Theorem 6.2 have important implications.
∙ The upper bound. Even though pointwise the energy error
$\unicode[STIX]{x1D6E5}$
is of size
$O(h^{\unicode[STIX]{x1D708}})$
, on average (with respect to the Boltzmann–Gibbs distribution)
$m_{\unicode[STIX]{x1D6E5}}$
is, at least formally, of size
$O(\unicode[STIX]{x1D6E5}^{2})=O(h^{2\unicode[STIX]{x1D708}})$
. The order of the average energy error is automatically twice the anticipated order. This is clearly an advantage of using a volume-preserving reversible integrator.∙ The lower bound. This is a disadvantage. Imagine a case where two uncoupled systems with Hamiltonian functions
$H_{1}$
and
$H_{2}$
are juxtaposed. The aggregate is a new Hamiltonian system with Hamiltonian
$H_{1}+H_{2}$
. The mean energy error for the aggregate is
$\mathbb{E}(\unicode[STIX]{x1D6E5}_{1}+\unicode[STIX]{x1D6E5}_{2})=\mathbb{E}(\unicode[STIX]{x1D6E5}_{1})+\mathbb{E}(\unicode[STIX]{x1D6E5}_{2})$
, and because both terms being added are
$\geq 0$
there is no room for cancellation. In general, the value of the energy and therefore the value of the energy error may be expected to increase as the number of degrees of freedom increases, in agreement with the fact that in physics, energy is an extensive quantity.


This discussion will be continued in Section 7.
6.2 Energy error in the standard Gaussian target
Sections 3.4 and 4.4 were devoted to investigating the behaviour of different integrators when applied to the harmonic oscillator. We take up this theme once more, this time in the HMC context. The aim is then to study what happens when HMC is used to sample from the univariate standard normal, hoping that any findings will be relevant to more complex distributions. (Of course, in practice there is no interest in using an MCMC algorithm to sample from a normal distribution. See the discussion on model problems at the beginning of Section 3.4.)
6.2.1 Pointwise energy error bounds
We return to the situation in Proposition 4.9 and now study the energy error after
 $n$
time-steps
 $\unicode[STIX]{x1D6E5}(q_{0},p_{0})=H(p_{n},q_{n})-H(q_{0},p_{0})$
, where
 $H=(1/2)(p^{2}+q^{2})$
. The following result (Blanes et al.
Reference Blanes, Casas and Sanz-Serna2014, Proposition 4.2) provides an upper bound for
 $\unicode[STIX]{x1D6E5}(q_{0},p_{0})$
uniform in
 $n$
.
Proposition 6.3. The energy error,
 $\unicode[STIX]{x1D6E5}(q_{0},p_{0})$
, may be bounded as
 $$\begin{eqnarray}\unicode[STIX]{x1D6E5}(q_{0},p_{0})\leq \displaystyle \frac{1}{2}(\unicode[STIX]{x1D712}_{h}^{2}-1)p_{0}^{2}\end{eqnarray}$$
if
 $\unicode[STIX]{x1D712}_{h}^{2}\geq 1$
, or as
 $$\begin{eqnarray}\unicode[STIX]{x1D6E5}(q_{0},p_{0})\leq \displaystyle \frac{1}{2}\biggl(\displaystyle \frac{1}{\unicode[STIX]{x1D712}_{h}^{2}}-1\biggr)q_{0}^{2}\end{eqnarray}$$
if
 $\unicode[STIX]{x1D712}_{h}^{2}\leq 1$
.
Proof. We only prove the first item; the other is similar. The ellipse (4.10) has its major axis along the co-ordinate axis
 $p=0$
of the
 $(q,p)$
-plane, as in Figure 4.1(a). Hence
 $2H(q,p)=p^{2}+q^{2}$
attains its maximum on that ellipse if
 $p=0$
which implies
 $q^{2}=q_{0}^{2}+\unicode[STIX]{x1D712}_{h}^{2}p_{0}^{2}$
. If the final point
 $(q_{n},p_{n})$
of the numerical trajectory happens to be at that maximum,
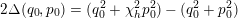 $2\unicode[STIX]{x1D6E5}(q_{0},p_{0})=(q_{0}^{2}+\unicode[STIX]{x1D712}_{h}^{2}p_{0}^{2})-(q_{0}^{2}+p_{0}^{2})$
.☐
6.2.2 Average energy error bounds
We estimate next the average energy error (Blanes et al.
Reference Blanes, Casas and Sanz-Serna2014, Proposition 4.3). Note that the bound provided is once more uniform in
 $n$
.
Proposition 6.4. In the situation described above, assume that
 $(q_{0},p_{0})$
is a Gaussian random vector with non-normalized probability density function
 $\exp (-H(q,p))$
, where
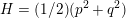 $H=(1/2)(p^{2}+q^{2})$
. Then the expectation of the random variable
 $\unicode[STIX]{x1D6E5}(q_{0},p_{0})\in \mathbb{R}^{2}$
is given by
 $$\begin{eqnarray}\mathbb{E}(\unicode[STIX]{x1D6E5})=\sin ^{2}(n\unicode[STIX]{x1D703}_{h})\hspace{2.22198pt}\unicode[STIX]{x1D70C}(h),\end{eqnarray}$$
where
 $$\begin{eqnarray}\unicode[STIX]{x1D70C}(h)=\displaystyle \frac{1}{2}\biggl(\unicode[STIX]{x1D712}_{h}^{2}+\displaystyle \frac{1}{\unicode[STIX]{x1D712}_{h}^{2}}-2\biggr)=\displaystyle \frac{1}{2}\biggl(\unicode[STIX]{x1D712}_{h}-\displaystyle \frac{1}{\unicode[STIX]{x1D712}_{h}}\biggr)^{2}\geq 0,\end{eqnarray}$$
and accordingly
 $$\begin{eqnarray}0\leq \mathbb{E}(\unicode[STIX]{x1D6E5})\leq \unicode[STIX]{x1D70C}(h).\end{eqnarray}$$
Proof. With the shorthand
 $c=\cos (n\unicode[STIX]{x1D703}_{h})$
,
 $s=\sin (n\unicode[STIX]{x1D703}_{h})$
, we may write
 $$\begin{eqnarray}2\unicode[STIX]{x1D6E5}(q_{0},p_{0})=\biggl(-\displaystyle \frac{1}{\unicode[STIX]{x1D712}_{h}}sq_{0}+cp_{0}\biggr)^{2}+(cq_{0}+\unicode[STIX]{x1D712}_{h}sp_{0})^{2}-(p_{0}^{2}+q_{0}^{2})\end{eqnarray}$$
or
 $$\begin{eqnarray}2\unicode[STIX]{x1D6E5}(q_{0},p_{0})=s^{2}\biggl(\displaystyle \frac{1}{\unicode[STIX]{x1D712}_{h}^{2}}-1\biggr)q_{0}^{2}+2cs\biggl(\unicode[STIX]{x1D712}_{h}-\displaystyle \frac{1}{\unicode[STIX]{x1D712}_{h}}\biggr)q_{0}p_{0}+s^{2}(\unicode[STIX]{x1D712}_{h}^{2}-1)p_{0}^{2}.\end{eqnarray}$$
Since
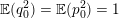 $\mathbb{E}(q_{0}^{2})=\mathbb{E}(p_{0}^{2})=1$
and
 $\mathbb{E}(q_{0}p_{0})=0$
, the proof is complete.☐
6.2.3 Energy error bounds for Verlet
Let us illustrate the preceding results in the case of the Verlet integrator. For the velocity version, we find from Example 3.8 and (4.7), for
 $0<h<2$
,
 $$\begin{eqnarray}\unicode[STIX]{x1D712}_{h}^{2}=\displaystyle \frac{h^{2}}{1-(1-h^{2}/2)^{2}}=\displaystyle \frac{1}{1-h^{2}/4}>1.\end{eqnarray}$$
The bound in Proposition 6.3 reads
 $$\begin{eqnarray}\unicode[STIX]{x1D6E5}(q_{0},p_{0})\leq \displaystyle \frac{h^{2}}{8(1-h^{2}/4)}\,p_{0}^{2}.\end{eqnarray}$$
For
 $h=1$
,
 $\unicode[STIX]{x1D6E5}(q_{0},p_{0})\leq p_{0}^{2}/6$
; therefore, if
 $-2<p_{0}<2$
(an event that for a standard normal distribution has probability
 ${>}95\%$
), then
 $\unicode[STIX]{x1D6E5}(q_{0},p_{0})<2/3$
, which results in a probability of acceptance
 $\geq 51\%$
, regardless of the number
 $n$
of time-steps.
The position Verlet integrator (Example 3.9 and Remark 4.10) has
 $\unicode[STIX]{x1D712}_{h}^{2}=1-h^{2}/4<1$
provided that
 $0<h<2$
. Proposition 6.3 yields
 $$\begin{eqnarray}\unicode[STIX]{x1D6E5}(q_{0},p_{0})\leq \displaystyle \frac{h^{2}}{8(1-h^{2}/4)}\,q_{0}^{2}\end{eqnarray}$$
(as one may have guessed from (6.5) by symmetry).
From Proposition 6.4, for both the velocity and the position versions,
 $$\begin{eqnarray}0\leq \mathbb{E}(\unicode[STIX]{x1D6E5})\leq \unicode[STIX]{x1D70C}(h)=\displaystyle \frac{h^{4}}{32(1-h^{2}/4)}.\end{eqnarray}$$
We draw attention to the exponent of
 $h$
in the numerator: even though, pointwise, for the harmonic oscillator, energy errors for the Verlet integrator are
 $O(h^{2})$
, they are
 $O(h^{4})$
on average, which of course matches our earlier finding in Theorem 6.2. For
 $h=1$
the expected energy error is
 $\leq 1/24$
. Halving
 $h$
to
 $h=1/2$
leads to an expected energy error
 $\leq 1/480$
. The conclusion of the examples above is that acceptance rates for Verlet are likely to be high even if the step size
 $h$
is not small.
6.3 Velocity Verlet or position Verlet?
Discrete trajectories of the Markov chain when HMC for the standard Gaussian target is operated with (a) velocity and (b) position Verlet. Each marker is a state of the Markov chain (intermediate values of
 $(q,p)$
along the numerical trajectories are not depicted). The size of the markers is related to the index
 $i$
in the chain: states corresponding to larger values of
 $i$
have smaller markers. The chains start at
 $q=10$
. In (b), all chain transitions result in rejection, so that
 $q_{i}=10$
for all values of
 $i$
; position Verlet gets stuck. In (a), the velocity chain quickly identifies the interval around
 $q=0$
where the target distribution is concentrated.

The symmetry between the velocity and position Verlet integrators may lead to the conclusion that their performances in the HMC scenario are equivalent. This is not the case, because in Algorithm 5.6 (for a general target distribution) the
 $q$
and
 $p$
variables do not play a symmetric role at all. In particular, samples of
 $p$
from the correct marginal distribution (Step 1) are used as initial conditions for the integration legs in Step 2. On the contrary, when the Markov chain is initialized, the user has to guess a suitable starting value for
 $q$
(see the end of Section 5.2). In some applications, the chosen starting value may actually correspond to a location of low probability, and we now study the difficulties that may arise in that case.
Figure 6.2 corresponds to the standard Gaussian/harmonic oscillator target and compares the performance of the velocity and position algorithms when the chain is initialized with
 $q$
at a location of very low probability,
 $q_{0}=10$
, ten standard deviations away from the mean (the initialization of
 $p$
is of no consequence since momenta are discarded in the momentum-refreshment Step 1 of Algorithm 5.6). The position integrator gets stuck where its velocity counterpart succeeds without problems.
Insight into the different behaviours of velocity and position Verlet may be gained from Figure 6.3, which corresponds to integrations with the large value
 $h=1.85$
carried out in the interval
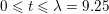 $0\leq t\leq \unicode[STIX]{x1D706}=9.25$
(five time-steps). Regardless of the choice of
 $|q_{0}|$
, velocity Verlet will result in an energy decrease (and therefore acceptance) if the initial sample
 $\unicode[STIX]{x1D709}_{0}$
of the momentum is such that
 $(q_{0},\unicode[STIX]{x1D709}_{0})$
lands in the grey area of panel (a), which will happen with large probability because small values of
 $|\unicode[STIX]{x1D709}_{0}|$
are likely to occur. On the contrary, in the position algorithm energy decreases only occur if very large values of
 $\unicode[STIX]{x1D709}_{0}$
are drawn. Certainly, there is symmetry between the grey areas of both panels; however, in HMC, having energy decreases near the
 $q$
-axis is helpful, and having them near the
 $p$
-axis is not. It may help to go back to the bound (6.5) which shows that, for velocity Verlet,
 $p_{0}=0$
ensures an energy decrease; compare both panels in Figure 4.1 as well.
Regions where the energy error
 $\unicode[STIX]{x1D6E5}(q,p)$
is positive/negative for (a) velocity and (b) position Verlet. In the grey-shaded regions
 $\unicode[STIX]{x1D6E5}(q,p)$
is negative, ensuring acceptance of the Markov transition. The contour lines in the background show level sets of
 $H(q,p)$
.

To conclude this discussion we emphasize that if the chains were initialized by drawing samples from the marginal distribution of
 $q$
(i.e. started at stationarity), then the behaviour of velocity and position Verlet would be the same due to the
 $q/p$
symmetry.
6.4 Multivariate Gaussian model
We study once more the quadratic Hamiltonian (3.27) and note that the covariance matrix
 $\unicode[STIX]{x1D6F4}$
of the target is the inverse of the stiffness matrix
 $K$
. As discussed in Proposition 3.13, in the particular case where
 $M=I$
, the square roots of the eigenvalues of
 $K$
are the angular frequencies of the dynamics; the eigenvalues of
 $\unicode[STIX]{x1D6F4}$
are of course the variances of the target along the directions of the eigenvectors. Thus small variance implies high frequency.
6.4.1 Average energy error in the multivariate case
Proposition 6.4 may be extended to the multivariate Gaussian case. We begin by providing a variant of Proposition 3.13.
Proposition 6.5. The change of dependent variables,
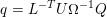 $q=L^{-T}U\unicode[STIX]{x1D6FA}^{-1}Q$
,
 $p=LUP$
, decouples the system into a collection of
 $d$
harmonic oscillators:
 $$\begin{eqnarray}\displaystyle \frac{\text{d}Q^{i}}{\text{d}t}=\unicode[STIX]{x1D714}_{i}P^{i},\quad \displaystyle \frac{\text{d}P^{i}}{\text{d}t}=-\unicode[STIX]{x1D714}_{i}Q^{i},\quad i=1,\ldots ,d\end{eqnarray}$$
(superscripts denote components).
In terms of the new variables, the function in (3.27) is given by
 $$\begin{eqnarray}\displaystyle \frac{1}{2}P^{T}P+\displaystyle \frac{1}{2}Q^{T}Q=\displaystyle \frac{1}{2}\mathop{\sum }_{i}((P^{i})^{2}+(Q^{i})^{2}).\end{eqnarray}$$
Therefore the
 $2d$
variables
 $Q^{i}$
and
 $P^{i}$
are independent standard Gaussian.Footnote
10
As discussed in connection with Proposition 3.13, we may assume that the numerical method is applied to each of the uncoupled oscillators. After recalling Remark 3.12, the following result is easily proved.
Theorem 6.6. Consider a stable integration of (3.27) with a (consistent), reversible volume-preserving integrator applied with a stable value of
 $h$
. If
 $(q_{0},p_{0})$
are random variables with probability density function (proportional to)
 $\exp (-H)$
, then for each
 $n$
the expectation of the energy error
 $\unicode[STIX]{x1D6E5}(q_{0},p_{0})=H(q_{n},p_{n})-H(q_{0},p_{0})$
may be bounded as
 $$\begin{eqnarray}0\leq \mathbb{E}(\unicode[STIX]{x1D6E5})\leq \mathop{\sum }_{j=1}^{d}\unicode[STIX]{x1D70C}(\unicode[STIX]{x1D714}_{j}h),\end{eqnarray}$$
where
 $\unicode[STIX]{x1D70C}$
is the function defined in Proposition 6.4.
6.4.2 An illustration
Bivariate Gaussian distribution,
 $(q^{1},q^{2})$
-plane; the ellipse is a contour of constant probability density. HMC operated with (a) velocity Verlet and (b) MALA. The size of the markers is related to
 $i$
: points along the Markov trajectory corresponding to larger values of
 $i$
have smaller markers. The computational budget for both algorithms is fixed at 100 force evaluations. Along these trajectories, the average acceptance probability for HMC and MALA is 93% and 82%, respectively. The stability requirement for Verlet is
 $h<0.2$
, which is set by the component of the target distribution with the smallest variance. In relation to MALA, note that HMC relaxes more rapidly to a region of high probability.

As an example, we consider a two-dimensional target where
 $$\begin{eqnarray}K=\unicode[STIX]{x1D6F4}^{-1}=\displaystyle \frac{1}{2}\left[\begin{array}{@{}cc@{}}101 & -99\\ -99 & 101\end{array}\right]\!.\end{eqnarray}$$
This matrix has eigenvalues
 $\unicode[STIX]{x1D714}_{1}^{2}=1$
(with eigenspace
 $q^{1}=q^{2}$
) and
 $\unicode[STIX]{x1D714}_{2}^{2}=100$
(with eigenspace
 $q^{1}=-q^{2}$
). The mass matrix is chosen to be
 $M=I$
. We use HMC with velocity Verlet; stability requires
 $h\unicode[STIX]{x1D714}_{2}<2$
or
 $h<0.2$
and we set
 $h=0.15$
. The chain is started at
 $(q^{1},q^{2})=(9,9)$
where
 ${\mathcal{U}}(9,9)=81$
, that is, about nine standard deviations in the direction of largest variance. The duration parameter
 $\unicode[STIX]{x1D706}$
is set to be equal to 1.35 (i.e. there are nine time-steps in each numerical integration leg) and the number of transitions in the chain was the maximum attainable with a computational budget of 100 force evaluations. Figure 6.4(a) shows that HMC rapidly relaxes to a region of high probability.
Remark 6.7. It may be of interest to relate this experiment to the discussion of stiffness in Example 3.14. Here it is the oscillation with frequency
 $\unicode[STIX]{x1D714}_{1}$
(i.e. the evolution along the diagonal
 $q^{1}=q^{2}$
) that matters most; however,
 $h$
has to be chosen in terms of the oscillation with frequency
 $\unicode[STIX]{x1D714}^{2}$
.Footnote
11
Nevertheless, HMC succeeds because, at each Markov transition, several time-steps are taken.
As a comparison we have also implemented the well-known algorithm MALA, with the same initial state and same computational budget. MALA may be described as the algorithm that results when, in HMC operated with velocity Verlet, the duration parameter
 $\unicode[STIX]{x1D706}$
is chosen to coincide with
 $h$
, that is, each integration leg only takes one time-step. In this way the accept/reject mechanism operates after each individual time-step in MALA (but only after
 $\unicode[STIX]{x1D706}/h$
successive time-steps in HMC). Figure 6.4(b) shows MALA zigzags in a region of low probability.
Remark 6.8. In connection with the preceding remark, we note that for MALA the progress of the Markov chain along the
 $q^{1}=q^{2}$
diagonal is slow. Each time-step moves the state by a small amount, because
 $h$
was chosen by taking into account the behaviour of the problem along the
 $q^{1}=-q^{2}$
diagonal. The momentum refreshments, which in MALA take place after every individual time-step, change the direction of motion in the
 $(q^{1},q^{2})$
-plane, thus inducing a random walk behaviour. HMC avoids this random walk behaviour by taking sufficiently many time-steps between consecutive accept/reject steps so that integration legs make substantial strides in the solution components with high variance.
6.5 Can Verlet be beaten?
Currently, velocity Verlet is the integrator of choice within HMC algorithms. Is this the best possibility? In this subsection we will discuss whether it is possible to construct a palindromic splitting formula with
 $s>1$
stages (3.19)–(3.20) that improves on the velocity Verlet algorithm in the sense that, when operated with a step size
 $h$
, leads to smaller energy errors – higher acceptance probabilities – than velocity Verlet with step size
 $h/s$
. Because, as illustrated above, Verlet is often very successful for large values of the step size, such a construction has to be based on investigating the behaviour of the integrators for finite
 $h$
and therefore cannot be guided by information (such as the expansion in Theorem 4.6) which corresponds to the behaviour as
 $h\rightarrow 0$
. We therefore resort to Gaussian models with Hamiltonian of the form (3.27). In the remainder of this subsection we shall use the symbol
 $\unicode[STIX]{x1D70F}$
to refer to the actual value of the step size implemented in the algorithm and keep the letter
 $h$
for the (non-dimensional) product
 $\unicode[STIX]{x1D714}\unicode[STIX]{x1D70F}$
, where
 $\unicode[STIX]{x1D714}$
represents one of the frequencies present in the problem. With this notation, Verlet is stable for
 $0<h<2$
or
 $0<\unicode[STIX]{x1D70F}<2/\unicode[STIX]{x1D714}_{\text{max}}$
.
When the number
 $d$
of degrees of freedom equals 1, velocity Verlet is indeed the best choice. We know from Section 6.2 that Verlet will deliver high acceptance rates for
 $h$
just below its stability limit and, from Section 4.5, that Verlet has the longest stability interval. So Verlet performs well for HMC for values of
 $\unicode[STIX]{x1D70F}$
where other integrators are not even stable. Essentially the same is true for
 $d$
small, as one sees by decoupling the problem into
 $d$
one-degree-of-freedom oscillators as we did in Section 6.4. However, as
 $d$
increases, Verlet is not likely to keep high acceptance rates if
 $\unicode[STIX]{x1D70F}$
is just below
 $2/\unicode[STIX]{x1D714}_{\text{max}}$
: in fact the additive character of the energy, noted in the discussion of Theorem 6.2, implies that, even if the energy error in each of the one-dimensional oscillators in the problem is small, the energy error for the overall system will likely be large. In that scenario, where, on accuracy grounds, Verlet has to be operated with
 $\unicode[STIX]{x1D70F}$
significantly smaller than the stability limit
 $2/\unicode[STIX]{x1D714}_{\text{max}}$
, there is room for improvements in efficiency by resorting to more sophisticated integrators, as we discuss next.
6.5.1 Two stages
Two-stage palindromic integrators (3.17) corresponding to
 $b=1/4$
or
 $b$
given by (6.8). (a) Stability polynomial
 $A_{h}$
. For
 $b=1/4$
(which provides two steps of velocity Verlet of step length
 $\unicode[STIX]{x1D70F}/2$
) stability is lost at
 $h=4$
and there is a double root of the equation
 $A_{h}=-1$
. The method (6.8) has a significantly shorter stability interval because under perturbation the double root of
 $A_{h}=-1$
splits into two real roots. (b) The quantity
 $\unicode[STIX]{x1D70C}=\unicode[STIX]{x1D70C}(h)$
that governs the expected energy error for Gaussian problems (see (6.7)). When the methods are operated with
 $0<h<2$
, i.e.
 $0<\unicode[STIX]{x1D70F}<2/\unicode[STIX]{x1D714}_{\text{max}}$
, the choice (6.8) yields values of
 $\unicode[STIX]{x1D70C}$
much smaller than those corresponding to
 $b=1/4$
.

We begin by studying the one-parameter family (3.17) of methods with two stages (i.e. essentially two force evaluations per step). For the choice
 $b=1/4$
, one step of length
 $\unicode[STIX]{x1D70F}$
of the two-stage method is equivalent to two steps of length
 $\unicode[STIX]{x1D70F}/2$
of velocity Verlet (see equation (4.12) with
 $N=2$
). The stability polynomial
 $A_{h}$
was described in terms of the Chebyshev polynomial
 $T_{2}$
in Section 4.5 and its graph may be seen in Figure 6.5(a). Stability is lost at
 $h=4$
when
 $A_{h}=1$
; at
 $h=2\sqrt{2}\approx 2.82$
, there is a double root of the equation
 $A_{h}=-1$
(corresponding to the double root at
 $\unicode[STIX]{x1D701}=0$
of the equation
 $T_{2}(\unicode[STIX]{x1D701})=2\unicode[STIX]{x1D701}^{2}-1=-1$
). Small perturbations of
 $b=1/4$
turn the double root of the equation
 $A_{h}=-1$
into two real roots in the neighbourhood of
 $h=2\sqrt{2}$
; after such perturbation the length of the stability interval drops from 4 to
 ${\approx}2\sqrt{2}$
. Accordingly, in problems where
 $d$
is small enough for standard velocity Verlet to work well with
 $\unicode[STIX]{x1D70F}\unicode[STIX]{x1D714}_{\text{max}}$
in the interval
 $(\sqrt{2},2)$
, no two-stage formula with
 $b\neq 1/4$
can improve upon Verlet. However, if, when applying Verlet,
 $\unicode[STIX]{x1D70F}\unicode[STIX]{x1D714}_{\text{max}}$
has to be chosen below
 $\sqrt{2}$
on accuracy grounds, then, as we will see now, efficiency may be improved by choosing
 $b$
in (3.17) different from
 $1/4$
.
Blanes et al. (Reference Blanes, Casas and Sanz-Serna2014) suggest the following procedure to find the value of
 $b$
. Their numerical experiments show that, for Gaussian problems with
 $d\leq 1000$
, (one-stage) velocity Verlet achieves acceptance rates
 $\geq 20\hspace{2.22198pt}\%$
when
 $\unicode[STIX]{x1D70F}\unicode[STIX]{x1D714}_{\text{max}}\leq 1$
(i.e. when
 $\unicode[STIX]{x1D70F}$
is less than half of the maximum allowed by stability). They then assume that two-stage integrators should be required to perform well when
 $\unicode[STIX]{x1D70F}\unicode[STIX]{x1D714}_{\text{max}}\leq 2$
. On the other hand, in view of (6.7), for Gaussian models performance is governed by the quantity
 $\unicode[STIX]{x1D70C}$
defined in Proposition 6.4, which for the one-parameter family (3.17) is found to be
 $$\begin{eqnarray}\unicode[STIX]{x1D70C}(h;b)=\displaystyle \frac{h^{4}(2b^{2}(1/2-b)h^{2}+4b^{2}-6b+1)^{2}}{8(2-bh^{2})(2-(1/2-b)h^{2})(1-b(1/2-b)h^{2})}.\end{eqnarray}$$
Then
 $b$
is chosen by minimizing
 $$\begin{eqnarray}\Vert \unicode[STIX]{x1D70C}\Vert _{(2)}=\max _{0\leq h\leq 2}\unicode[STIX]{x1D70C}(h;b),\end{eqnarray}$$
which yields
 $b=0.21178\ldots .$
To avoid cumbersome decimal expressions, Blanes et al. (Reference Blanes, Casas and Sanz-Serna2014) instead use the approximate value
 $$\begin{eqnarray}b=\displaystyle \frac{3-\sqrt{3}}{6}\approx 0.21132,\end{eqnarray}$$
which gives
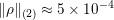 $\Vert \unicode[STIX]{x1D70C}\Vert _{(2)}\approx 5\times 10^{-4}$
. For comparison,
 $b=1/4$
has a substantially larger
 $\Vert \unicode[STIX]{x1D70C}\Vert _{(2)}\approx 4\times 10^{-2}$
. Numerical experiments reported by Blanes et al. (Reference Blanes, Casas and Sanz-Serna2014) confirm that when
 $d$
is not small the method (6.8) is a clear improvement on Verlet in an example where the target is not Gaussian. See also Mannseth, Kleppe and Skaug (Reference Mannseth, Kleppe and Skaug2018).
6.5.2 Three stages
A similar study may be undertaken for the three-stage family (3.18) with two parameters
 $a$
and
 $b$
. The choice
 $a=1/3$
,
 $b=1/6$
yields a method consisting of the concatenation of three successive steps of length
 $\unicode[STIX]{x1D70F}/3$
of velocity Verlet (see equation (4.12) with
 $N=3$
). The graphs of the stability polynomial
 $A_{h}$
may be seen in Figure 6.6(a). Stability is lost at
 $h=6$
when
 $A_{h}=-1$
. The double root of
 $T_{3}(\unicode[STIX]{x1D701})=4\unicode[STIX]{x1D701}^{3}-4\unicode[STIX]{x1D701}=1$
at
 $\unicode[STIX]{x1D701}=-1/2$
gives rise to a double root of
 $A_{h}=1$
at
 $h=3\sqrt{3}\approx 5.19$
. The double root of
 $T_{3}(\unicode[STIX]{x1D701})=-1$
gives rise to a double root of
 $A_{h}=-1$
at
 $h=3$
. Perturbing the values
 $a=1/3$
,
 $b=1/6$
leads in general to methods with (short) stability intervals of length
 ${\approx}3$
, because typically the double root of
 $A_{h}=-1$
splits into two single roots. However, it is possible to perturb
 $a$
and
 $b$
in such a way that, after perturbation,
 $A_{h}=-1$
has a double root close to
 $h=3$
as analysed in Campos and Sanz-Serna (Reference Campos and Sanz-Serna2017). For such particular perturbations, stability is lost by crossing the line
 $A_{h}=1$
. This is what happens for the choice
 $$\begin{eqnarray}a=0.29619504261126,\quad b=0.11888010966548,\end{eqnarray}$$
found in Blanes et al. (Reference Blanes, Casas and Sanz-Serna2014) by minimizing
 $$\begin{eqnarray}\Vert \unicode[STIX]{x1D70C}\Vert _{(3)}=\max _{0\leq h\leq 3}\unicode[STIX]{x1D70C}(h;b).\end{eqnarray}$$
Note that the range of the maximum is now
 $0\leq h\leq 3$
to account for the fact that, when using three force evaluations per step, we aim at integrations with
 $\unicode[STIX]{x1D70F}\unicode[STIX]{x1D714}_{\text{max}}\leq 3$
to be competitive with Verlet. The choice (6.9) results in
 $\Vert \unicode[STIX]{x1D70C}\Vert _{(3)}\approx 7\times 10^{-5}$
and a stability interval of length
 ${\approx}4.67\ldots .$
Blanes et al. (Reference Blanes, Casas and Sanz-Serna2014) report experiments showing the superiority of (6.9) over standard velocity Verlet and also describe the construction of optimized four-stage integrators.
Three-stage palindromic integrators (3.18) for
 $a=1/3$
,
 $b=1/6$
or
 $a$
,
 $b$
given by (6.9). (a) Stability polynomial
 $A_{h}$
. (b) The quantity
 $\unicode[STIX]{x1D70C}=\unicode[STIX]{x1D70C}(h)$
, which governs the expected energy error for Gaussian problems (see (6.7)). When the methods are operated with
 $0<h<3$
, the choice (6.9) yields values of
 $\unicode[STIX]{x1D70C}$
much smaller than those corresponding to
 $a=1/3$
,
 $b=1/6$
.

6.5.3 The AIA approach
Let us go back to the one-parameter family (3.17) of methods with two stages. The choice (6.8) is based on the assumption that with
 $b=1/4$
the integrator (equivalent to velocity Verlet) would be used with
 $\unicode[STIX]{x1D70F}\unicode[STIX]{x1D714}_{\max }$
in the interval
 $(0,2)$
. There is of course a degree of arbitrariness in the choice of this interval. When an interval
 $(0,c)$
with
 $c$
slightly above
 $2$
is considered, then minimization of
 $$\begin{eqnarray}\max _{0\leq h\leq c}\unicode[STIX]{x1D70C}(h;b)\end{eqnarray}$$
results in a value of
 $b$
slightly above that corresponding to
 $(0,2)$
. This improves the length of the stability interval, but, with the notation in Theorem 4.6, increases the quantity
 $C_{2,1}^{2}+C_{2,2}^{2}$
, so that the integrator becomes less accurate in the limit
 $h\rightarrow 0$
(note that
 $C_{1,1}=0$
because we are dealing with methods of order 2). As
 $c$
is increased further, the value of
 $b$
that minimizes (6.10) increases towards
 $b=1/4$
; the stability interval improves and accuracy worsens. For
 $c\geq 2\sqrt{2}$
the optimization procedure leads to
 $b=1/4$
because, as pointed out earlier, then
 $b=1/4$
is the only value for which the maximum in (6.10) is finite. On the other hand, as
 $c$
decreases from
 $2$
, the optimal value of
 $b$
decreases, accuracy in the limit
 $h\rightarrow 0$
improves and the stability interval becomes shorter. In the limit
 $c\downarrow 0$
,
 $b$
approaches
 $b\approx 0.1932$
, the value that minimizes
 $C_{2,1}^{2}+C_{2,2}^{2}$
(McLachlan Reference Mclachlan1995).
In the adaptive integration approach (AIA) suggested by Fernández-Pendás, Akhmatskaya and Sanz-Serna (Reference Fernández-Pendás, Akhmatskaya and Sanz-Serna2016) and Akhmatskaya, Fernández-Pendás, Radivojević and Sanz-Serna (Reference Akhmatskaya, Fernández-Pendás, Radivojević and Sanz-Serna2017) for molecular dynamics problems, the value of
 $b$
in (3.17) is chosen by minimizing (6.10) with the parameter
 $c$
adapted to the problem being solved, rather than being kept at the somewhat arbitrary value
 $c=2$
. The procedure is as follows. In molecular dynamics packages such as GROMACS (Hess, Kutzner, van der Spoel and Lindahl Reference Hess, Kutzner, van der Spoel and Lindahl2008), the user is prompted to specify her choice of the value of
 $\unicode[STIX]{x1D70F}$
; of course, smaller values of
 $\unicode[STIX]{x1D70F}$
lead to more expensive simulations. The package estimates the values of the frequencies of all harmonic forces present in the problem and will not run if
 $\unicode[STIX]{x1D70F}\tilde{\unicode[STIX]{x1D714}}_{\text{max}}$
is close to the Verlet stability limit (
 $\tilde{\unicode[STIX]{x1D714}}_{\text{max}}$
is the maximum of the estimated frequencies). AIA sets
 $c=\sqrt{2}\tilde{\unicode[STIX]{x1D714}}_{\max }\unicode[STIX]{x1D70F}$
(
 $\sqrt{2}$
is a safety factor), so that in (6.10)
 $h$
ranges in the shortest interval that contains all products
 $\sqrt{2}\unicode[STIX]{x1D70F}\tilde{\unicode[STIX]{x1D714}}_{i}$
, where
 $\tilde{\unicode[STIX]{x1D714}}_{i}$
are the estimated frequencies. (If
 $c\geq 4$
, the user is asked to reduce
 $\unicode[STIX]{x1D70F}$
.) In this way, whenever the user is prepared to operate with a value of
 $\unicode[STIX]{x1D70F}$
that is ‘small’ for the problem being tackled, AIA chooses a more accurate integrator; as
 $\unicode[STIX]{x1D70F}$
increases, AIA will pick up a value of
 $b$
leading to a more stable, less accurate integrator. This strategy has been successfully implemented in an in-house version of GROMACS. The computational overheads are negligible as they only stem from finding the value of
 $b$
for the problem at hand and the value of
 $\unicode[STIX]{x1D70F}$
chosen by the user. Numerical experiments show that AIA is a clear improvement on Verlet.
7 HMC in high dimension: tuning the step size
We now follow Beskos et al. (Reference Beskos, Pillai, Roberts, Sanz-Serna and Stuart2013) and study the behaviour of HMC as the dimensionality increases. As a by-product we obtain a general rule for tuning the value of
 $h$
when running HMC with a chosen value of the duration
 $\unicode[STIX]{x1D706}$
of the integration legs. The analysis uses a model situation similar to that employed in Roberts, Gelman and Gilks (Reference Roberts, Gelman and Gilks1997) and Roberts and Rosenthal (Reference Roberts and Rosenthal1998) to analyse other sampling techniques. High-dimensionality in a different setting is the object of the next section.
7.1 The set-up
We consider a high-dimensional Hamiltonian system in
 $(\mathbb{R}^{2d})^{m}$
,
 $m\gg 1$
, obtained by juxtaposing without coupling
 $m$
copies of a fixed Hamiltonian system in
 $\mathbb{R}^{2d}$
. If we write a point
 $(q,p)\in (\mathbb{R}^{2d})^{m}$
in components as
 $$\begin{eqnarray}q=(q_{1},\ldots ,q_{m})\in (\mathbb{R}^{d})^{m}\quad \text{and}\quad p=(p_{1},\ldots ,p_{m})\in (\mathbb{R}^{d})^{m},\end{eqnarray}$$
then the Hamiltonian of the system in
 $(\mathbb{R}^{2d})^{m}$
is
 $$\begin{eqnarray}H_{m}(q,p)=\mathop{\sum }_{j=1}^{m}H(q_{j},p_{j}),\end{eqnarray}$$
with
 $$\begin{eqnarray}H(q_{j},p_{j})=\displaystyle \frac{1}{2}p_{j}^{T}M^{-1}p_{j}+{\mathcal{U}}(q_{j})-\log (Z).\end{eqnarray}$$
Here
 ${\mathcal{U}}:\mathbb{R}^{d}\rightarrow \mathbb{R}$
is the potential energy function for each component and
 $Z$
is the normalizing factor for the one-component Boltzmann–Gibbs distribution, so that
 $\exp (-H(q_{j},p_{j}))$
is a (normalized) probability density function in
 $\mathbb{R}^{2d}$
.Footnote
12
In this way
 $\exp (-H_{m}(q,p))$
is the (normalized) probability density function of the Boltzmann–Gibbs distribution in
 $(\mathbb{R}^{2d})^{m}$
; clearly the
 $2m$
random vectors
 $q_{j}$
,
 $p_{j}$
are stochastically independent for this distribution.
From a sampling viewpoint, the target
 $\unicode[STIX]{x1D6F1}$
is the distribution in
 $(\mathbb{R}^{d})^{m}$
with non-normalized density
 $\exp (-\sum _{j=1}^{m}{\mathcal{U}}(q_{j}))$
; under this target the
 $q_{j}$
are independent and identically distributed. We sample from
 $\unicode[STIX]{x1D6F1}$
by using Algorithm 5.6 (HMC), evolving
 $(q,p)$
by integrating numerically the dynamics associated with
 $H_{m}$
. Since there is no coupling between components, in Step 2 of the algorithm each pair
 $(q_{j},p_{j})$
moves independently of all the others. In particular, the step size stability restriction for the whole system will coincide with the restriction for the one-component Hamiltonian and will therefore be independent of
 $m$
. Similarly, in Step 1 randomizing the momentum
 $p$
in
 $(\mathbb{R}^{d})^{m}$
is equivalent to randomizing each
 $p_{j}$
. However, in Step 3, the different components come together: acceptance depends on the error in
 $H_{m}$
and this is obtained by adding the errors in the energies of the individual components. As a consequence of Theorem 6.2, for a fixed value of
 $h$
and a fixed integration interval
 $0\leq t\leq \unicode[STIX]{x1D706}$
, the mean energy error in one component is positive and therefore the mean energy error for
 $H_{m}$
will grow linearly with
 $m$
; as a result, the acceptance rate will decrease as the dimensionality increases. Therefore, for
 $m$
large with
 $\unicode[STIX]{x1D706}$
fixed, the value of
 $h$
will have to be decreased to ensure a satisfactory acceptance rate; note that this restriction on
 $h$
is due to accuracy considerations and has no relation to the stability limit of the integrator being used, which, as we just pointed out, is independent of
 $m$
in our setting.
7.2 Decreasing
$h$
as the dimensionality increases

In what follows we fix the duration
 $\unicode[STIX]{x1D706}$
of the integration leg, assume that
 $\unicode[STIX]{x1D706}/h$
is an integer and study the way in which
 $h$
has to be decreased if we wish to ensure that the acceptance rate remains bounded away from
 $0$
as
 $m\uparrow \infty$
. We let
 $\unicode[STIX]{x1D6E5}(q_{j},p_{j};h)$
denote the one component energy error at
 $t=\unicode[STIX]{x1D706}$
for an integration started from the initial state
 $(q_{j},p_{j})$
; this initial state is regarded as a random variable distributed according to the Boltzmann–Gibbs associated with
 $H$
. Thus
 $(q,p)$
will be distributed according to the Boltzmann–Gibbs distribution with density
 $\exp (-H_{m})$
; in other words the chain is assumed to be at stationarity.
7.2.1 The mean energy error for one component
We shall be concerned with the first and second moments
 $$\begin{eqnarray}\displaystyle \unicode[STIX]{x1D707}(h) & = & \displaystyle \int _{\mathbb{R}^{2d}}\unicode[STIX]{x1D6E5}(q_{j},p_{j};h)\,\text{e}^{-H(q_{j},p_{j})}\,\text{d}q_{j}\,\text{d}p_{j},\nonumber\\ \displaystyle s^{2}(h) & = & \displaystyle \int _{\mathbb{R}^{2d}}\unicode[STIX]{x1D6E5}(q_{j},p_{j};h)^{2}\,\text{e}^{-H(q_{j},p_{j})}\,\text{d}q_{j}\,\text{d}p_{j},\nonumber\end{eqnarray}$$
and the corresponding variance
 $\unicode[STIX]{x1D70E}^{2}(h)=s^{2}(h)-\unicode[STIX]{x1D707}(h)^{2}$
.
The following important result rounds out Theorem 6.2. We now assume that
 $\unicode[STIX]{x1D6E5}(q_{j},p_{j};h)$
behaves asymptotically as
 $h^{\unicode[STIX]{x1D708}}a(p_{j},q_{j})$
for a suitable function
 $a$
(cf. Remark 3.3 where global errors rather than energy errors were considered). In this way, smaller values of
 $|a|$
correspond to more accurate integrators and/or ‘easier’ Hamiltonians. The theorem below ensures that the expectation
 $\unicode[STIX]{x1D707}(h)$
of
 $\unicode[STIX]{x1D6E5}$
is
 ${\approx}(\unicode[STIX]{x1D6F4}/2)h^{2\unicode[STIX]{x1D708}}$
, where we emphasize that the exponent of
 $h$
is twice the order of the method and that the proportionality constant
 $\unicode[STIX]{x1D6F4}$
is the average of
 $a^{2}$
. The hypotheses in the theorem will hold in practice under reasonable hypotheses on the integrator and the target distribution; the reader is referred to Beskos et al. (Reference Beskos, Pillai, Roberts, Sanz-Serna and Stuart2013) for a complete study in the case of the velocity Verlet scheme.
Theorem 7.1. Assume the following.
∙ There exist functions
$a(p_{j},q_{j})$
and
$r(q_{j},p_{j};h)$
such that with$$\begin{eqnarray}\unicode[STIX]{x1D6E5}(q_{j},p_{j};h)=h^{\unicode[STIX]{x1D708}}a(p_{j},q_{j})+h^{\unicode[STIX]{x1D708}}r(q_{j},p_{j};h),\end{eqnarray}$$
$\lim _{h\rightarrow 0}r(q_{j},p_{j};h)=0$
for each
$(q_{j},p_{j})$
.∙ There exists a real-valued function
$D(q_{j},p_{j})$
, integrable with respect to the Boltzmann–Gibbs distribution, such that, for a suitable
$h_{0}>0$
, $$\begin{eqnarray}\sup _{0<h<h_{0}}\displaystyle \frac{\unicode[STIX]{x1D6E5}(q_{j},p_{j};h)^{2}}{h^{2\unicode[STIX]{x1D708}}}\leq D(q_{j},p_{j}).\end{eqnarray}$$


Then
 $$\begin{eqnarray}\lim _{h\rightarrow 0}\displaystyle \frac{\unicode[STIX]{x1D707}(h)}{h^{2\unicode[STIX]{x1D708}}}=\displaystyle \frac{\unicode[STIX]{x1D6F4}}{2},\quad \lim _{h\rightarrow 0}\displaystyle \frac{\unicode[STIX]{x1D70E}^{2}(h)}{h^{2\unicode[STIX]{x1D708}}}=\unicode[STIX]{x1D6F4},\end{eqnarray}$$
with
 $$\begin{eqnarray}\unicode[STIX]{x1D6F4}=\int _{\mathbb{R}^{2d}}a(q_{j},p_{j})^{2}\,\text{e}^{-H(q_{j},p_{j})}\,\text{d}q_{j}\,\text{d}p_{j}.\end{eqnarray}$$
Proof. We first establish the second limit. For fixed
 $(q_{j},p_{j})$
, the first hypothesis implies that
 $\unicode[STIX]{x1D6E5}(q_{j},p_{j};h)/h^{2\unicode[STIX]{x1D708}}\rightarrow a(q_{j},p_{j})$
and then, by dominated convergence,
 $$\begin{eqnarray}\lim _{h\rightarrow 0}\displaystyle \frac{s^{2}(h)}{h^{2\unicode[STIX]{x1D708}}}=\int _{\mathbb{R}^{2d}}a(q_{j},p_{j})^{2}\,\text{e}^{-H(q_{j},p_{j})}\,\text{d}q_{j}\,\text{d}p_{j}=\unicode[STIX]{x1D6F4}.\end{eqnarray}$$
In addition, the bound (6.3) shows that
 $$\begin{eqnarray}\lim _{h\rightarrow 0}\displaystyle \frac{\unicode[STIX]{x1D707}(h)^{2}}{h^{2\unicode[STIX]{x1D708}}}=0\end{eqnarray}$$
and the limit for
 $\unicode[STIX]{x1D70E}^{2}(h)/h^{2\unicode[STIX]{x1D708}}$
follows.
From (6.4), with the shorthand
 $\unicode[STIX]{x1D6E5}=\unicode[STIX]{x1D6E5}(q_{j},p_{j};h)$
,
 $$\begin{eqnarray}\displaystyle & & \displaystyle \displaystyle \frac{2\unicode[STIX]{x1D707}(h)-\unicode[STIX]{x1D70E}^{2}(h)}{h^{2\unicode[STIX]{x1D708}}}-\displaystyle \frac{\unicode[STIX]{x1D707}(h)^{2}}{h^{2\unicode[STIX]{x1D708}}}\nonumber\\ \displaystyle & & \displaystyle \qquad =-\int _{\mathbb{R}^{2d}}\displaystyle \frac{\unicode[STIX]{x1D6E5}}{h^{\unicode[STIX]{x1D708}}}\,\displaystyle \frac{\exp (-\unicode[STIX]{x1D6E5})-1+\unicode[STIX]{x1D6E5}}{h^{\unicode[STIX]{x1D708}}}\,\text{e}^{-H(q_{j},p_{j})}\,\text{d}q_{j}\,\text{d}p_{j}.\nonumber\end{eqnarray}$$
We note that the second fraction in the integral approaches
 $0$
as
 $h\rightarrow 0$
for fixed
 $(q_{j},p_{j})$
, because the numerator is
 $O(\unicode[STIX]{x1D6E5}^{2})$
. A dominated convergence argument (see Beskos et al.
Reference Beskos, Pillai, Roberts, Sanz-Serna and Stuart2013 for details) shows that the integral also approaches 0 and the proof is complete.☐
7.2.2 The mean energy error for
$m$
components

For the Hamiltonian
 $H_{m}$
the energy error
 $\unicode[STIX]{x1D6E5}_{m}(q,p;h)$
is given by the sum
 $\sum _{j=1}^{m}\unicode[STIX]{x1D6E5}(q_{j},p_{j};h)$
. Under our hypotheses, the random variables being added are independent and identically distributed and therefore
 $\unicode[STIX]{x1D6E5}_{m}(q,p;h)$
has expectation
 $m\unicode[STIX]{x1D707}(h)\approx m\unicode[STIX]{x1D6F4}h^{2\unicode[STIX]{x1D708}}/2$
and variance
 $m\unicode[STIX]{x1D70E}^{2}(h)\approx m\unicode[STIX]{x1D6F4}h^{2\unicode[STIX]{x1D708}}$
; thus to ensure that
 $\unicode[STIX]{x1D6E5}_{m}(q,p;h)$
has a distributional limit as
 $m\uparrow \infty$
, it is reasonable to impose a relation
 $$\begin{eqnarray}h=\ell m^{-1/(2\unicode[STIX]{x1D708})},\end{eqnarray}$$
with
 $\ell >0$
a constant. Under this relation, a central limit theorem (see Beskos et al.
Reference Beskos, Pillai, Roberts, Sanz-Serna and Stuart2013 for details) ensures that, as
 $m\uparrow \infty$
, the distribution of the random variable
 $\unicode[STIX]{x1D6E5}_{m}(q,p;h)$
converges to the distribution of a random variable
 $\unicode[STIX]{x1D6E5}_{\infty }\sim N(\ell ^{2\unicode[STIX]{x1D708}}\unicode[STIX]{x1D6F4}/2,\ell ^{2\unicode[STIX]{x1D708}}\unicode[STIX]{x1D6F4})$
. It then follows that the expectation of the acceptance probability
 $\min \{1,\exp (-\unicode[STIX]{x1D6E5}_{m})\}$
converges to
 $$\begin{eqnarray}\mathbb{E}(\min \{1,\text{e}^{-\unicode[STIX]{x1D6E5}_{\infty }}\}).\end{eqnarray}$$
The last expectation may be found analytically and turns out to be
 $$\begin{eqnarray}A(\ell )=2\unicode[STIX]{x1D6F7}(-\ell ^{\unicode[STIX]{x1D708}}\sqrt{\unicode[STIX]{x1D6F4}}/2),\end{eqnarray}$$
where
 $\unicode[STIX]{x1D6F7}$
is the standard normal cumulative distribution function
 $$\begin{eqnarray}\unicode[STIX]{x1D6F7}(x)=\displaystyle \frac{1}{\sqrt{2\unicode[STIX]{x1D70B}}}\int _{-\infty }^{x}\exp \biggl(-\displaystyle \frac{\unicode[STIX]{x1D709}^{2}}{2}\biggr)\,\text{d}\unicode[STIX]{x1D709}.\end{eqnarray}$$
We then conclude the following.
Theorem 7.2. Assume that the hypotheses of Theorem 7.1 are fulfilled. If in the scenario above the number of copies
 $m$
and the step size
 $h$
are related as in (7.1), then, at stationarity, the expectation of the acceptance probability of the HMC algorithm converges to (7.2) as
 $m\uparrow \infty$
.
For Verlet, with
 $\unicode[STIX]{x1D708}=2$
, the scaling (7.1) entails that halving
 $h$
compensates for a multiplication of
 $m$
by a factor of
 $16$
. This scaling in high dimension is very favourable when compared with the situation for other sampling techniques (Roberts et al.
Reference Roberts, Gelman and Gilks1997, Roberts and Rosenthal Reference Roberts and Rosenthal1998).
7.3 Optimal tuning
In Theorem 7.1, a lower value of
 $\unicode[STIX]{x1D6F4}$
, i.e. a lower mean value of the function
 $a^{2}$
, indicates a more accurate integrator and/or an ‘easier’ Hamiltonian. Correspondingly, formula (7.2) is such that lowering the value of
 $\unicode[STIX]{x1D6F4}$
increases the expected acceptance probability
 $A$
(
 $\unicode[STIX]{x1D6F7}(x)$
is an increasing function of
 $x$
). In practice the function
 $a$
and the constant
 $\unicode[STIX]{x1D6F4}$
are unknown, and this would seem to imply that (7.2) is of no practical value. We shall now show that, on the contrary, this relation provides a way to tune the parameter
 $h$
in the HMC algorithm.
Increasing the value of
 $\ell$
in (7.1) leads to a larger step size and therefore lowers the computational cost of each integration leg over the fixed interval
 $[0,\unicode[STIX]{x1D706}]$
but typically increases the energy error. Note in this connection that in (7.2),
 $A$
decreases as
 $\ell$
increases. What is the best choice of
 $\ell$
? Beskos et al. (Reference Beskos, Pillai, Roberts, Sanz-Serna and Stuart2013) argue that the function
 $E(\ell )=\ell A(\ell )$
is a sensible indicator of the efficiency of the algorithm, as its reciprocal measures the amount of work necessary to generate an accepted proposal. With this metric,
 $\ell$
should be determined to maximize
 $\ell A(\ell )$
: a direct maximization is not feasible because, as we just noted, we cannot compute
 $A(\ell )$
. This difficulty may be circumvented by treating
 $A$
as an independent variable and expressing
 $\ell$
as a function of
 $A$
: then
 $$\begin{eqnarray}E(A)=\displaystyle \frac{2^{1/\unicode[STIX]{x1D708}}}{\unicode[STIX]{x1D6F4}^{1/(2\unicode[STIX]{x1D708})}}A(\unicode[STIX]{x1D6F7}^{-1}(1-A/2))^{1/\unicode[STIX]{x1D708}}.\end{eqnarray}$$
Clearly the value of
 $A$
that maximizes
 $E$
is independent of
 $\unicode[STIX]{x1D6F4}$
and is therefore independent of the target. In addition the optimal
 $A$
is the same for all integrators sharing the same value of
 $\unicode[STIX]{x1D708}$
. For the case
 $\unicode[STIX]{x1D708}=2$
, it is found numerically that
 $$\begin{eqnarray}A(\unicode[STIX]{x1D6F7}^{-1}(1-A/2))^{1/2}\end{eqnarray}$$
is maximized when
 $$\begin{eqnarray}A\approx 0.651.\end{eqnarray}$$
This analysis suggests that, for an integrator of order
 $\unicode[STIX]{x1D708}=2$
and once the integration interval has been chosen, if
 $m$
is large,
 $h$
should be selected in such a way that, in the simulations, the acceptance rate is observed to be close to
 $65\%$
. If the observed acceptance rate is larger, one would do better with a larger value of
 $h$
. That would imply more rejections, but the waste caused by the rejections would be offset by the larger number of proposals that may be generated with a fixed budget of force evaluations. Conversely, acceptance rates significantly below
 $65\%$
indicate that one would do better by working more to generate each single proposal. While our analysis has been performed in the case where the target is a product of
 $m$
independent identical distributions, practical experience shows that this rule works more generally (Beskos et al.
Reference Beskos, Pillai, Roberts, Sanz-Serna and Stuart2013).
8 HMC for path sampling: sampling from a perturbed Gaussian distribution
So far the samples generated by the HMC algorithm have been vectors
 $q\in \mathbb{R}^{d}$
. In some applications the samples needed are paths. In this section we discuss the use of HMC in those situations. As will be made clear, the material is directly relevant to the problem of sampling from targets that are perturbations of Gaussian distributions.
8.1 A model problem
In order to keep the presentation as simple as possible, we shall initially limit our attention to a model situation; the general case is discussed at the end of the section.
We consider paths
 $u(s)$
, where
 $u$
is a real-valued function of the variable
 $s\in [0,S]$
. The paths are constrained by the homogeneous Dirichlet conditions
 $u(0)=u(S)=0$
and, formally, their distribution is governed by the ‘potential energy’ functional
 $$\begin{eqnarray}{\mathcal{U}}(u)=\int _{0}^{S}\biggl[\displaystyle \frac{1}{2}(\unicode[STIX]{x2202}_{s}u(s))^{2}+g(s,u(s))\biggr]\,\text{d}s.\end{eqnarray}$$
If the function
 $u(s)$
is smooth, then after integration by parts,
 $$\begin{eqnarray}{\mathcal{U}}(u)=\int _{0}^{S}\biggl[-\displaystyle \frac{1}{2}u(s)\unicode[STIX]{x2202}_{ss}u(s)+g(s,u(s))\biggr]\,\text{d}s.\end{eqnarray}$$
Distributions of this form arise when studying diffusion bridge problems (Reznikoff and Vanden-Eijnden Reference Reznikoff and Vanden-Eijnden2005, Beskos et al. Reference Beskos, Roberts, Stuart and Voss2008, Hairer, Stuart and Voss Reference Hairer, Stuart and Voss2009).
Example 8.1. Fix a timeFootnote
13
horizon
 $S>0$
and consider the process
 $\mathsf{X}:[0,S]\rightarrow \mathbb{R}$
that solves the Ornstein–Uhlenbeck equation
 $$\begin{eqnarray}\,\text{d}\mathsf{X}(s)=-\mathsf{X}(s)\,\text{d}s+\,\text{d}\mathsf{B}(s),\end{eqnarray}$$
conditioned on both initial and final conditions
 $\mathsf{X}(0)=0$
,
 $\mathsf{X}(S)=0$
. Here
 $\mathsf{B}$
is a standard Brownian motion. The law of this diffusion bridge is a probability measure
 $\unicode[STIX]{x1D6F1}$
on paths
 $u$
satisfying the boundary conditions that is associated with the functional
 $$\begin{eqnarray}\displaystyle \frac{1}{2}\int _{0}^{S}[(\unicode[STIX]{x2202}_{s}u(s))^{2}+u(s)^{2}]\,\text{d}s.\end{eqnarray}$$
Remark 8.2. The case where the process is conditioned on
 $\mathsf{X}(0)=x^{-}$
,
 $\mathsf{X}(S)=x^{+}$
may be reduced to the case with homogeneous boundary conditions, by writing
 $u(s)=\bar{u}(s)+\ell (s)$
, where
 $\ell (s)$
is a smooth function of
 $s$
with
 $\ell (0)=x^{-}$
,
 $\ell (S)=x^{+}$
. After this transformation, the new paths
 $\bar{u}(s)$
satisfy homogeneous boundary conditions and their distribution corresponds to a functional of the form (8.1).
A precise mathematical description of the meaning of (8.1) and of the associated probability distribution on paths
 $\unicode[STIX]{x1D6F1}$
will be given later. For the time being, we note that to study the infinite-dimensional problem on a computer it is necessary to introduce a finite-dimensional discretized version, and we turn to presenting a way of performing the discretization.
We use a uniform grid consisting of
 $d+2$
grid points:
 $$\begin{eqnarray}\{s_{j}=j\unicode[STIX]{x1D6E5}s\mid j=0,\ldots ,d+1\},\quad \unicode[STIX]{x1D6E5}s=S/(d+1).\end{eqnarray}$$
The space of paths is then replaced by the finite-dimensional state space
 $\mathbb{R}^{d}$
; the
 $j$
th component
 $u_{j}$
of an element
 $\mathbf{u}\in \mathbb{R}^{d}$
is seen as an approximation to
 $u(s_{j})$
,
 $j=1,\ldots ,d$
. The functional (8.1) is discretized as
 $$\begin{eqnarray}{\mathcal{U}}_{d}(\mathbf{u})=\unicode[STIX]{x1D6E5}s\biggl(-\displaystyle \frac{1}{2}\mathbf{u}^{T}\mathbf{L}\mathbf{u}+G_{d}(\mathbf{u})\biggr),\quad G_{d}(\mathbf{u})=\mathop{\sum }_{j=1}^{d}g(u_{j})\end{eqnarray}$$
(cf. (8.2)), where the matrix
 $\mathbf{L}$
corresponds to the standard central difference approximation to
 $\unicode[STIX]{x2202}_{ss}$
with homogeneous Dirichlet boundary conditions:
 $$\begin{eqnarray}\mathbf{L}=\displaystyle \frac{1}{\unicode[STIX]{x1D6E5}s^{2}}\left[\begin{array}{@{}cccc@{}}-2 & 1 & & \\ 1 & \ddots & \ddots & \\ & \ddots & \ddots & 1\\ & & 1 & -2\end{array}\right]\!.\end{eqnarray}$$
Note that if the vector
 $\mathbf{u}$
contains the grid values of a smooth path
 $u$
, then
 ${\mathcal{U}}_{d}(\mathbf{u})\rightarrow {\mathcal{U}}(u)$
as
 $\unicode[STIX]{x1D6E5}s\rightarrow 0$
.
Our task is then to sample from the target
 $\unicode[STIX]{x1D6F1}_{d}$
in
 $\mathbb{R}^{d}$
with non-normalized density
 $\exp (-{\mathcal{U}}_{d}(\mathbf{u}))$
. Special attention has to be paid to the increase in dimension
 $d$
as the discretization becomes more accurate.
8.2 Preconditioned HMC for path sampling
We now set up an HMC algorithm, called preconditioned HMC (PHMC), to sample from our target
 $\unicode[STIX]{x1D6F1}_{d}$
.
8.2.1 Algorithm description
As expected, we introduce an auxiliary variable
 $\mathbf{p}\in \mathbb{R}^{d}$
and a Boltzmann–Gibbs distribution
 $\unicode[STIX]{x1D6F1}_{BGd}$
in
 $\mathbb{R}^{d}\times \mathbb{R}^{d}$
with non-normalized density
 $\exp (-{\mathcal{H}}_{d}(\mathbf{u},\mathbf{p}))$
. The Hamiltonian
 ${\mathcal{H}}_{d}$
is given by
 $\unicode[STIX]{x1D6E5}sH_{d}(\mathbf{u},\mathbf{p})$
, with
 $$\begin{eqnarray}H_{d}(\mathbf{u},\mathbf{p})=\displaystyle \frac{1}{2}\mathbf{p}^{T}\mathbf{M}^{-1}\mathbf{p}-\displaystyle \frac{1}{2}\mathbf{u}^{T}\mathbf{L}\mathbf{u}+G_{d}(\mathbf{u})\end{eqnarray}$$
(where
 $\mathbf{M}$
is a mass matrix). Of course, the target
 $\unicode[STIX]{x1D6F1}_{d}$
is the
 $\mathbf{u}$
-marginal of
 $\unicode[STIX]{x1D6F1}_{BGd}$
, while the
 $\mathbf{p}$
-marginal is Gaussian
 $N(\mathbf{0},(\unicode[STIX]{x1D6E5}s)^{-1}\mathbf{M})$
.
The pair
 $(\mathbf{u},\mathbf{p})$
is evolved by means of the Hamiltonian dynamics associated with
 $H_{d}$
:
 $$\begin{eqnarray}\left[\begin{array}{@{}c@{}}\mathbf{\errMathOverAccent{}{u}}(t)\\ \boldsymbol{{\dot{p}}}(t)\end{array}\right]=\left[\begin{array}{@{}c@{}}\mathbf{M}^{-1}\mathbf{p}(t)\\ \mathbf{L}\mathbf{u}(t)-\unicode[STIX]{x1D6FB}G_{d}(\mathbf{u}(t))\end{array}\right]\!.\end{eqnarray}$$
Clearly, this dynamics preserves the value of
 ${\mathcal{H}}_{d}$
and therefore the distribution
 $\unicode[STIX]{x1D6F1}_{BGd}$
.
Remark 8.3. Instead of (8.6), one could use the dynamics corresponding to the Hamiltonian
 ${\mathcal{H}}_{d}$
that features in the non-normalized density
 $\exp (-{\mathcal{H}}_{d}(\mathbf{u},\mathbf{p}))$
of
 $\unicode[STIX]{x1D6F1}_{BGd}$
. This alternative dynamics differs from that of (8.6) by a change in scale of
 $t$
. However, (8.6) is more natural in our context, where there is an infinite-dimensional problem in the background. We illustrate this as follows. Assume that
 $\mathbf{M}$
is taken to be the identity and
 $g=0$
. Then (8.6), after eliminating
 $\mathbf{p}$
, implies
 $\boldsymbol{\ddot{u} }=\mathbf{L}\mathbf{u}$
, so that
 $\mathbf{u}(t)$
satisfies the standard semidiscrete wave equation. This matches the fact that as
 $\unicode[STIX]{x1D6E5}s\rightarrow 0$
,
 ${\mathcal{H}}_{d}$
approaches
 $$\begin{eqnarray}\int _{0}^{S}\displaystyle \frac{1}{2}(p(s)^{2}+(\unicode[STIX]{x2202}_{s}u(s))^{2})\,\text{d}s,\end{eqnarray}$$
which provides the Hamiltonian functional (total energy) for the Hamiltonian partial differential equations
 $\unicode[STIX]{x2202}_{t}u=p$
,
 $\unicode[STIX]{x2202}_{t}p=\unicode[STIX]{x2202}_{ss}u$
which, after elimination of
 $p$
, yield the wave equation
 $\unicode[STIX]{x2202}_{tt}u=\unicode[STIX]{x2202}_{ss}u$
.
A challenge with numerically solving (8.6) using an explicit symplectic integrator (like Verlet) is that the spectral radius of
 $\mathbf{L}$
grows with
 $d$
. Consequently, as the number of grid points increases, the dynamics may become highly oscillatory due to the presence of fast frequencies, and stably approximating this type of dynamics may be difficult (Calvo and Sanz-Serna Reference Calvo and Sanz-Serna2009). For example, numerical stability of a Verlet integrator applied to (8.6) with
 $G_{d}=0$
and
 $\mathbf{M}=\mathbf{I}$
requires that its time-step size
 $h$
be inversely proportional to
 $d$
.
To avoid this type of restrictive dependence, we precondition the dynamics by choosing the mass matrix
 $\mathbf{M}=-\mathbf{L}$
:
 $$\begin{eqnarray}\left[\begin{array}{@{}c@{}}\mathbf{\errMathOverAccent{}{u}}(t)\\ \boldsymbol{{\dot{p}}}(t)\end{array}\right]=\left[\begin{array}{@{}c@{}}-\mathbf{L}^{-1}\mathbf{p}(t)\\ \mathbf{L}\mathbf{u}(t)-\unicode[STIX]{x1D6FB}G_{d}(\mathbf{u}(t))\end{array}\right]\!.\end{eqnarray}$$
In the particular case where
 $g$
vanishes, we have
 $\boldsymbol{\ddot{u} }=-\mathbf{u}$
; all the
 $d$
frequencies of the preconditioned problem are
 $1$
and Verlet has a step size restriction
 $h<2$
, independently of
 $d$
.
Remark 8.4. Consider for the moment a dynamics of the form (8.6) where
 $\mathbf{L}$
is an arbitrary negative-definite matrix and
 $\unicode[STIX]{x1D6FB}G_{d}(\mathbf{u})$
is small with respect to
 $\mathbf{L}\mathbf{u}$
. From a sampling viewpoint, this situation would arise if standard HMC were applied to sampling from a perturbation of the centred Gaussian distribution with covariance matrix
 $-\mathbf{L}^{-1}$
. The preconditioning
 $\mathbf{M}=-\mathbf{L}$
makes sense in that setting. Large eigenvalues of
 $-\mathbf{L}$
correspond to directions in state space with small variances/large forces; the mass in those direction is then chosen to be large so as to ensure small displacements and avoid fast frequencies. This idea may be extended: general targets may be locally approximated by a state-dependent Gaussian model, and one may then choose a state-dependent
 $M$
as the inverse of the covariance matrix of the Gaussian approximation (Girolami and Calderhead Reference Girolami and Calderhead2011). Unfortunately the state dependence of the mass matrix introduces additional terms in Hamilton’s equations, which are no longer of the form (2.9), with the unwelcome consequence that explicit volume-preserving reversible integrators do not exist.
Ornstein–Uhlenbeck bridge. Mean acceptance probability as a function of
 $h$
for the PRHMC algorithm for three choices of the splitting parameter
 $c$
and the three values of
 $\unicode[STIX]{x1D6E5}s$
. The number of time-steps
 $n$
at each integration leg is random with a geometric distribution chosen in such a way that the average length
 $\unicode[STIX]{x1D706}=nh$
of the integration interval is 20. The number of samples is
 $10^{4}$
. For
 $c=1$
the acceptance probability does not decrease as the grid is refined.

In the PHMC algorithm, the system (8.7) is integrated by means of a symplectic reversible scheme with second-order accuracy. We use the Strang splitting (3.13) with
 $$\begin{eqnarray}\displaystyle & & \displaystyle (\text{A})\qquad \left[\begin{array}{@{}c@{}}\mathbf{\errMathOverAccent{}{u}}(t)\\ \boldsymbol{ ṗ }(t)\end{array}\right]=\left[\begin{array}{@{}c@{}}-\mathbf{L}^{-1}\mathbf{p}(t)\\ c^{2}\mathbf{L}\mathbf{u}(t)\end{array}\right]\nonumber\end{eqnarray}$$
and
 $$\begin{eqnarray}\displaystyle & & \displaystyle (\text{B})\qquad \left[\begin{array}{@{}c@{}}\mathbf{\errMathOverAccent{}{u}}(t)\\ \boldsymbol{ ṗ }(t)\end{array}\right]=\left[\begin{array}{@{}c@{}}\mathbf{0}\\ (1-c^{2})\mathbf{L}\boldsymbol{ u}(t)-\unicode[STIX]{x1D6FB}G_{d}(\mathbf{u}(t))\end{array}\right]\!,\nonumber\end{eqnarray}$$
where
 $c\in [0,1]$
is a parameter. The choice
 $c=0$
leads to the velocity Verlet method.
Thus, in PHMC, a transition of the HMC Markov chain starts by drawing a new value of the momentum from the marginal distribution
 $$\begin{eqnarray}N(\mathbf{0},(\unicode[STIX]{x1D6E5}s)^{-1}\mathbf{M})=N(\mathbf{0},-(\unicode[STIX]{x1D6E5}s)^{-1}\mathbf{L}),\end{eqnarray}$$
takes
 $m=\lfloor \unicode[STIX]{x1D706}/h\rfloor$
steps of the splitting integrator, and accepts/rejects with acceptance probability
 $\min \{1,\text{e}^{-\unicode[STIX]{x1D6E5}{\mathcal{H}}_{d}}\}$
(see Algorithm 5.6). A variant called PRMHC, with randomized duration as in Algorithm 5.11, is clearly possible; in that variant the number of steps is chosen to be geometrically distributed with mean
 $\unicode[STIX]{x1D706}/h$
.
Remark 8.5. For implementation purposes, it is advisable to use the variable
 $\mathbf{v}=-\mathbf{L}^{-1}\mathbf{p}$
rather than
 $\mathbf{p}$
. In the variables
 $(\mathbf{u},\mathbf{v})$
, the split system
 $(\text{A})$
takes the trivial form
 $\mathbf{\errMathOverAccent{}{u}}(t)=\mathbf{v}(t)$
,
 $\mathbf{\errMathOverAccent{}{v}}(t)=-c^{2}\mathbf{u}(t)$
. Before beginning an integration leg, the fresh value of
 $\mathbf{v}$
is drawn from the corresponding distribution
 $N(\mathbf{0},(\unicode[STIX]{x1D6E5}s)^{-1}\mathbf{L}^{-1})$
. When computing the acceptance probability, the Hamiltonian
 ${\mathcal{H}}_{d}$
is correspondingly expressed in terms of
 $(\mathbf{u},\mathbf{v})$
.
8.2.2 Numerical illustration
Ornstein–Uhlenbeck bridge. This figure assesses the sampling accuracy of the PRHMC algorithm. For the distribution
 $\unicode[STIX]{x1D6F1}_{d}$
, the plot graphs the exact and empirical values of the variance of
 $\mathbf{u}_{i}$
when
 $\unicode[STIX]{x1D6E5}s=0.02$
corresponding to
 $d=49$
interior grid points (the horizontal axis labels the components). The time-step size is
 $h=2.0$
. The number of time-steps
 $n$
at each integration leg is random with a geometric distribution chosen in such a way that the average length
 $\unicode[STIX]{x1D706}=nh$
of the integration interval is 20. The number of samples is
 $10^{6}$
. The acceptance rate was
 $95\%$
. When measured in the
 $L^{2}$
-norm of
 $\mathbb{R}^{49}$
, the relative error of the vector of empirical variances is
 $0.36\%$
. The values
 $c=0$
,
 $c=0.5$
were also tested but the acceptance rates were virtually zero.

We have implemented the randomized duration PRHMC algorithm in the particular case of the Ornstein–Uhlenbeck bridge in Example 8.1, with
 $S=1$
and homogeneous Dirichlet boundary conditions (see Section 9.3 for the case of constant duration PHMC). Note that due to the linearity of the Ornstein–Uhlenbeck process, the target
 $\unicode[STIX]{x1D6F1}_{d}$
is Gaussian and there is no need to use MCMC techniques to sample from it; however, using this target provides a convenient test problem. Figure 8.1 plots the mean acceptance probability of PRHMC as a function of
 $h$
for three values of the parameter
 $c$
in the integrator and three choices of
 $\unicode[STIX]{x1D6E5}s$
. Clearly
 $c=1$
provides the best performance. Note in particular that for
 $c=1$
the acceptance probability is independent of
 $\unicode[STIX]{x1D6E5}s$
; for the other values of
 $c$
and fixed
 $h$
the acceptance probability decreases with
 $\unicode[STIX]{x1D6E5}s$
. Figure 8.2 shows that the use of
 $c=1$
leads to accurate sampling even with
 $h$
large. The theory in what follows clarifies these numerical results.
8.2.3 Analysis
The results that follow are concerned with the application of PHMC and PRHMC to targets associated with (8.1) in the particular case of the Ornstein–Uhlenbeck bridge (8.3). The proofs are given in Section 9.4.
In the following stability theorem we require the lowest eigenvalue
 $$\begin{eqnarray}\unicode[STIX]{x1D714}_{1}^{2}=\displaystyle \frac{4}{\unicode[STIX]{x1D6E5}s^{2}}\sin ^{2}\biggl(\displaystyle \frac{\unicode[STIX]{x1D70B}}{2(d+1)}\biggr)\end{eqnarray}$$
of
 $-\mathbf{L}$
. It is trivial to show that
 $2/S\leq \unicode[STIX]{x1D714}_{1}$
; therefore the stability requirements do not become more stringent as
 $\unicode[STIX]{x1D6E5}s\rightarrow 0$
. This is a consequence of the preconditioning of the dynamics.
Theorem 8.6. If
 $h>0$
satisfies
 $$\begin{eqnarray}\left\{\begin{array}{@{}ll@{}}ch+2\arctan \biggl(\displaystyle \frac{h(1+(1-c^{2})\unicode[STIX]{x1D714}_{1}^{2})}{2c\unicode[STIX]{x1D714}_{1}^{2}}\biggr)<\unicode[STIX]{x1D70B}\quad & \text{if }c\in (0,1],\\ h<\displaystyle \frac{2\unicode[STIX]{x1D714}_{1}}{\sqrt{1+\unicode[STIX]{x1D714}_{1}^{2}}}\quad & \text{if }c=0,\end{array}\right.\end{eqnarray}$$
then the splitting integrator used in the PHMC and PRMHC algorithms is stable.
We now turn to the mean energy error after an integration leg.
Theorem 8.7. Choose
 $\unicode[STIX]{x1D702}\in (0,\unicode[STIX]{x1D70B})$
and restrict the attention to step sizes such that
 $ch\leq \unicode[STIX]{x1D702}$
and the stability requirement (8.9) is satisfied.
∙ For
$c\in [0,1)$
, there exist positive constants
$h_{0}=h_{0}(c,\unicode[STIX]{x1D702})$
and
$C=C(c,\unicode[STIX]{x1D702})$
, such that for
$h<h_{0}$
, the mean energy error after
$n$
time-steps has the bounds $$\begin{eqnarray}0\leq \mathbb{E}(\unicode[STIX]{x1D6E5}{\mathcal{H}}_{d})\leq Cdh^{4}.\end{eqnarray}$$
∙ In the case
$c=1$
, there exist positive constants
$h_{0}=h_{0}(\unicode[STIX]{x1D702})$
and
$C^{\prime }=C^{\prime }(\unicode[STIX]{x1D702})$
, such that for
$h<h_{0}$
, $$\begin{eqnarray}0\leq \mathbb{E}(\unicode[STIX]{x1D6E5}{\mathcal{H}}_{d})\leq C^{\prime }h^{4}.\end{eqnarray}$$


Here, the expected value is over random initial conditions with non-normalized density
 $\exp (-{\mathcal{H}}_{d}(\mathbf{u},\mathbf{p}))$
.
The exponent of
 $h$
in the bounds should not be surprising by now. We emphasize that the bounds are independent of the number of steps in the integration leg. They therefore apply to the PHMC case where the duration of the integration leg is fixed and to cases where that duration is randomized as in the PRHMC algorithm in the experiments above. For
 $c\neq 1$
the energy error grows linearly with the number of degrees of freedom. This is the behaviour we found in the scenario studied in Section 7, but we note that here the different components
 $\mathbf{u}_{j}$
are not independent nor are they identically distributed (this point is discussed further in Section 9.4). On the other hand, for
 $c=1$
the energy error bound is uniform in
 $\unicode[STIX]{x1D6E5}s$
.
Even though full details will not be given, we mention that the bounds in Theorem 8.7 may be used to derive results on the acceptance rate, in analogy to what we did in Section 7. If
 $c=1$
, the mean acceptance rate for fixed
 $h$
is independent of
 $\unicode[STIX]{x1D6E5}s$
. However, for
 $c\neq 1$
,
 $h$
has to be scaled as
 $(\unicode[STIX]{x1D6E5}s)^{1/4}$
to ensure that the mean acceptance rate is bounded away from 0 as
 $\unicode[STIX]{x1D6E5}s\rightarrow 0$
. This agrees with the experiments in Figure 8.1. Note that the scaling
 $h\sim (\unicode[STIX]{x1D6E5}s)^{1/4}$
arises from accuracy considerations rather than from stability restrictions.
8.3 Hilbert space HMC
The non-normalized density
 $\propto \exp (-{\mathcal{U}}_{d}(\mathbf{u}))$
of the target
 $\unicode[STIX]{x1D6F1}_{d}$
associated with
 ${\mathcal{U}}_{d}(\mathbf{u})$
in (8.4) may be factored as
 $$\begin{eqnarray}\exp (-\unicode[STIX]{x1D6E5}sG_{d}(\mathbf{u}))\times \exp \biggl(-\displaystyle \frac{\unicode[STIX]{x1D6E5}s}{2}\mathbf{u}^{T}\mathbf{L}\mathbf{u}\biggr).\end{eqnarray}$$
Thus
 $\unicode[STIX]{x1D6F1}_{d}$
has non-normalized density
 $$\begin{eqnarray}\exp (-\unicode[STIX]{x1D6E5}sG_{d}(\mathbf{u}))\end{eqnarray}$$
with respect to the Gaussian distribution
 $\unicode[STIX]{x1D6F1}_{d}^{0}$
in
 $\mathbb{R}^{d}$
with mean
 $\mathbf{0}$
and covariance matrix
 $(\unicode[STIX]{x1D6E5}s)^{-1}\mathbf{L}^{-1}$
. This observation is useful because as
 $d\uparrow \infty$
,
 $\unicode[STIX]{x1D6F1}_{d}^{0}$
approaches the centred Gaussian distribution
 $\unicode[STIX]{x1D6F1}^{0}$
in the Hilbert space
 $L^{2}(0,S)$
with covariance operator
 $(-\unicode[STIX]{x2202}_{ss})^{-1}$
, where the differential operator
 $-\unicode[STIX]{x2202}_{ss}$
has homogeneous boundary conditions (Da Prato and Zabczyk Reference Da Prato and Zabczyk2014). It is well known that
 $\unicode[STIX]{x1D6F1}^{0}$
is the distribution of the Brownian bridge in
 $[0,S]$
with homogeneous boundary conditions. On the other hand, the first factor in (8.10) is a discretization of
 $$\begin{eqnarray}\exp \biggl(-\int _{0}^{S}g(s,u(s))\,\text{d}s\biggr).\end{eqnarray}$$
In this way the path distribution
 $\unicode[STIX]{x1D6F1}$
may be described as the measure whose density with respect to the Gaussian
 $\unicode[STIX]{x1D6F1}^{0}$
is given by the last display. There is an important difference between the finite- and infinite-dimensional cases. The finite-dimensional
 $\unicode[STIX]{x1D6F1}_{d}$
may described in two equivalent ways: (i) as having non-normalized density
 $\exp (-{\mathcal{U}}_{d}(\mathbf{u}))$
with respect to the standard Lebesgue measure
 $\text{d}q$
or (ii) as having non-normalized density (8.11) with respect to the Gaussian
 $\unicode[STIX]{x1D6F1}_{d}^{0}$
. The infinite-dimensional
 $\unicode[STIX]{x1D6F1}$
cannot be defined by a density with respect to the standard Lebesgue measure in
 $L^{2}$
, simply because that measure does not exist. Thus, necessarily
 $\unicode[STIX]{x1D6F1}$
has to be defined by its density with respect to
 $\unicode[STIX]{x1D6F1}^{0}$
.
These considerations lead to studying the general problem of sampling from a target
 $\unicode[STIX]{x1D6F1}$
defined by a density
 $\exp (-\unicode[STIX]{x1D6F7}(u))$
with respect to a given centred Gaussian reference measure
 $\unicode[STIX]{x1D6F1}_{0}$
in a Hilbert space. The PHMC and PRHMC algorithms described above in the restricted scenario of (8.1) may be extended without difficulty to that general problem. In the extension, the matrix
 $\mathbf{L}$
in (8.5) is replaced by a discretization of the inverse of the covariance operator of
 $\unicode[STIX]{x1D6F1}_{0}$
and the function
 $G_{d}$
arises from discretizing
 $\unicode[STIX]{x1D6F7}$
. Again the key point in the preconditioned algorithms is to choose the mass matrix
 $\mathbf{M}$
to coincide with
 $-\mathbf{L}$
; this ensures that if
 $\unicode[STIX]{x1D6F7}=0$
, the dynamics is given by
 $\boldsymbol{\ddot{u} }=-\mathbf{u}$
where all frequencies are
 $1$
.
The general problem just described has been addressed by Beskos et al. (Reference Beskos, Pinski, Sanz-Serna and Stuart2011), who introduced an HMC algorithm that is formulated in the Hilbert space itself. Of course, in practice that algorithm can only be implemented after a suitable discretization and, once the discretization has been performed, it coincides with PHMC with
 $c=1$
implemented as in Remark 8.5. We emphasize that in PHMC we first discretized the target and then formulated the sampling method. In contrast, Beskos et al. (Reference Beskos, Pinski, Sanz-Serna and Stuart2011) proceed in reverse order: discretization comes after formulating the sampling method. The route in Beskos et al. (Reference Beskos, Pinski, Sanz-Serna and Stuart2011), which requires non-trivial use of functional-analytic techniques, is mathematically more sophisticated than the approach we have followed here. What is then the advantage of formulating the algorithm in the infinite-dimensional scenario? A sampling method that works in the Hilbert space itself may be expected to work uniformly well as the dimension
 $d$
of the discretization tends to
 $\infty$
. This is what happens to the algorithm in Beskos et al. (Reference Beskos, Pinski, Sanz-Serna and Stuart2011) in view of Theorem 8.7. On the other hand, for
 $c\neq 1$
, PHMC cannot arise from discretizing a Hilbert space algorithm, because we know that its performance becomes worse and worse as
 $d\uparrow \infty$
with
 $h$
fixed.
To finish this section, we remark that for MALA preconditioned and non-preconditioned versions are available (Beskos et al. Reference Beskos, Roberts, Stuart and Voss2008), and analogous to the latter, there is a non-preconditioned version of HMC (Bou-Rabee Reference Bou-Rabee2017).
9 Supplementary material
The paper concludes with material that complements a number of points considered in the preceding sections.
9.1 Finding the modified equation of a splitting integrator
We now show how to obtain the expansion in Theorem 4.6. Full details will be given for the particular case of the Lie–Trotter splitting algorithm (3.11); but the method is the same for more involved integrators. There are two steps. In the first, flows are represented as exponentials. In the second, exponentials are combined by means of the Baker–Campbell–Hausdorff (BCH) formula.
9.1.1 Lie derivatives
Associated with the vector field
 $f(x)$
in the differential system (2.1) with flow
 $\unicode[STIX]{x1D711}_{t}$
, there is a Lie derivative
 $D_{f}$
. This is the first-order differential operator that maps each smooth function
 $\unicode[STIX]{x1D712}:\mathbb{R}^{D}\rightarrow \mathbb{R}$
into a new function
 $D_{f}\unicode[STIX]{x1D712}:\mathbb{R}^{D}\rightarrow \mathbb{R}$
defined as
 $$\begin{eqnarray}(D_{f}\unicode[STIX]{x1D712})(x)=\mathop{\sum }_{i=1}^{D}f^{i}(x)\displaystyle \frac{\unicode[STIX]{x2202}}{\unicode[STIX]{x2202}x^{i}}\unicode[STIX]{x1D712}(x)\end{eqnarray}$$
(superscripts denote components of vectors). The chain rule leads to the formula
 $$\begin{eqnarray}\displaystyle \frac{\text{d}}{\text{d}t}\unicode[STIX]{x1D712}(\unicode[STIX]{x1D711}_{t}(x))\biggr|_{t=0}=(D_{f}\unicode[STIX]{x1D712})(x),\end{eqnarray}$$
which shows the meaning of
 $(D_{f}\unicode[STIX]{x1D712})(x)$
as a rate of change of
 $\unicode[STIX]{x1D712}$
along the solution
 $t\mapsto \unicode[STIX]{x1D711}_{t}(x)$
of (2.1). By successively applying this formula to the functions
 $D_{f}\unicode[STIX]{x1D712},D_{f}(D_{f}\unicode[STIX]{x1D712}),\ldots ,$
we find
 $$\begin{eqnarray}\displaystyle \frac{\text{d}^{k}}{\text{d}t^{k}}\unicode[STIX]{x1D712}(\unicode[STIX]{x1D711}_{t}(x))\biggr|_{t=0}=(D_{f}^{k}\unicode[STIX]{x1D712})(x),\quad k=2,3,\ldots ,\end{eqnarray}$$
where
 $D_{f}^{k}$
is the
 $k$
th-order differential operator defined inductively as
 $$\begin{eqnarray}(D_{f}^{k}\unicode[STIX]{x1D712})(x)=(D_{f}(D_{f}^{k-1}\unicode[STIX]{x1D712}))(x),\quad k=2,3,\ldots .\end{eqnarray}$$
Therefore the Taylor expansion of
 $\unicode[STIX]{x1D712}(\unicode[STIX]{x1D711}_{t}(x))$
at
 $t=0$
reads
 $$\begin{eqnarray}\unicode[STIX]{x1D712}(\unicode[STIX]{x1D711}_{t}(x))=\mathop{\sum }_{k=0}^{\infty }\displaystyle \frac{t^{k}}{k!}(D_{f}^{k}\unicode[STIX]{x1D712})(x)\end{eqnarray}$$
or
 $$\begin{eqnarray}\unicode[STIX]{x1D712}(\unicode[STIX]{x1D711}_{t}(x))=(\exp (tD_{f})\unicode[STIX]{x1D712})(x),\end{eqnarray}$$
a formula that may be used to retrieve, at least formally,
 $\unicode[STIX]{x1D711}_{t}$
: its application with
 $\unicode[STIX]{x1D712}$
equal to the coordinate function
 $\unicode[STIX]{x1D712}(x)=x^{i}$
,
 $i=1,\ldots ,D$
, yields the
 $i$
th component of the vector
 $\unicode[STIX]{x1D711}_{t}(x)$
. In conclusion, the equality
 $$\begin{eqnarray}\unicode[STIX]{x1D712}\circ \unicode[STIX]{x1D711}_{t}=\exp (tD_{f})\unicode[STIX]{x1D712}\end{eqnarray}$$
may be understood as a representation of the flow of a differential system as the exponential of the Lie operator of its vector field.
If
 $f^{(\text{A})}$
and
 $f^{(\text{B})}$
are vector fields, then the compositions
 $D_{f^{(\text{A})}}D_{f^{(\text{B})}}$
and
 $D_{f^{(\text{B})}}D_{f^{(\text{A})}}$
are second-order differential operators. However, it is easily checked that
 $D_{f^{(\text{A})}}D_{f^{(\text{B})}}-D_{f^{(\text{B})}}D_{f^{(\text{A})}}$
is a first-order differential operator. In fact the following result holds (Arnol’d Reference Arnol’d1989, Section 39).
Proposition 9.1.
 $D_{f^{(\text{A})}}D_{f^{(\text{B})}}-D_{f^{(\text{B})}}D_{f^{(\text{A})}}$
is the Lie operator corresponding to the vector field
 $[f^{(\text{A})},f^{(\text{B})}]$
, that is, to the Lie bracket of
 $f^{(\text{A})}$
and
 $f^{(\text{B})}$
defined in (2.14).
If now
 $\unicode[STIX]{x1D711}_{t}^{(\text{A})},\unicode[STIX]{x1D711}_{s}^{(\text{B})}$
are the flows corresponding to the vector fields
 $f^{(\text{A})}$
and
 $f^{(\text{B})}$
respectively, two applications of (9.1) give
 $$\begin{eqnarray}\displaystyle \unicode[STIX]{x1D712}\circ (\unicode[STIX]{x1D711}_{s}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{t}^{(\text{A})}) & = & \displaystyle (\unicode[STIX]{x1D712}\circ \unicode[STIX]{x1D711}_{s}^{(\text{B})})\circ \unicode[STIX]{x1D711}_{t}^{(\text{A})}=\exp (tD_{f^{(\text{A})}})(\unicode[STIX]{x1D712}\circ \unicode[STIX]{x1D711}_{s}^{(\text{B})})\nonumber\\ \displaystyle \phantom{\unicode[STIX]{x1D712}\circ (\unicode[STIX]{x1D711}_{s}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{t}^{(\text{A})})} & = & \displaystyle \exp (tD_{f^{(\text{A})}})(\exp (sD_{f^{(\text{B})}})\unicode[STIX]{x1D712})\nonumber\\ \displaystyle \phantom{\unicode[STIX]{x1D712}\circ (\unicode[STIX]{x1D711}_{s}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{t}^{(\text{A})})} & = & \displaystyle (\exp (tD_{f^{(\text{A})}})\exp (sD_{f^{(\text{B})}}))\unicode[STIX]{x1D712}.\end{eqnarray}$$
Thus the operator
 $\exp (tD_{f^{(\text{A})}})\exp (sD_{f^{(\text{B})}})$
represents the composition
 $\unicode[STIX]{x1D711}_{s}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{t}^{(\text{A})}$
in analogy with (9.1). Note that the
 $\text{A}$
-flow acts first in the composition
 $\unicode[STIX]{x1D711}_{s}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{t}^{(\text{A})}$
while
 $\exp (tD_{f^{(\text{A})}})$
acts second in the product of operators
 $\exp (tD_{f^{(\text{A})}})\exp (sD_{f^{(\text{B})}})$
. Our task now is to write
 $\exp (tD_{f^{(\text{A})}})\exp (sD_{f^{(\text{B})}})$
as a single exponential.
9.1.2 The Baker–Campbell–Hausdorff formula
Assume for the time being that
 $X$
and
 $Y$
are square matrices of the same dimension. It is well known that the product
 $\exp (X)\exp (Y)$
of their exponentials only coincides with
 $\exp (X+Y)$
if
 $X$
and
 $Y$
commute. In fact, by multiplying out
 $$\begin{eqnarray}\exp (X)=I+X+\displaystyle \frac{1}{2}X^{2}+\displaystyle \frac{1}{6}X^{3}+\cdots\end{eqnarray}$$
and
 $$\begin{eqnarray}\exp (Y)=I+Y+\displaystyle \frac{1}{2}Y^{2}+\displaystyle \frac{1}{6}Y^{3}+\cdots \,,\end{eqnarray}$$
we find
 $$\begin{eqnarray}\displaystyle \exp (X)\exp (Y) & = & \displaystyle I+X+Y+\displaystyle \frac{1}{2}X^{2}+XY+\displaystyle \frac{1}{2}Y^{2}\nonumber\\ \displaystyle & & \displaystyle \qquad \displaystyle \frac{1}{6}X^{3}+\displaystyle \frac{1}{2}X^{2}Y+\displaystyle \frac{1}{2}XY^{2}+\displaystyle \frac{1}{6}X^{3}+\cdots \,.\nonumber\end{eqnarray}$$
The products on the right-hand side are all of the form
 $X^{k}Y^{\ell }$
, while the expansion of
 $\exp (X+Y)$
gives rise to products such as
 $YX$
,
 $Y^{2}X$
,
 $YX^{2}$
,
 $XYX$
,
 $YXY$
. The BCH formula (Sanz-Serna and Calvo Reference Sanz-Serna and Calvo1994, Hairer et al.
Reference Hairer, Lubich and Wanner2010) writes
 $\exp (X)\exp (Y)$
as the exponential
 $\exp (Z)$
of a matrix
 $$\begin{eqnarray}\displaystyle Z & = & \displaystyle X+Y+\displaystyle \frac{1}{2}[X,Y]+\displaystyle \frac{1}{12}[X,[X,Y]]+\displaystyle \frac{1}{12}[Y,[Y,X]]\nonumber\\ \displaystyle & & \displaystyle \quad +\displaystyle \frac{1}{24}[X,[Y,[Y,X]]]-\displaystyle \frac{1}{720}[Y,[Y,[Y,[Y,X]]]]+\cdots \,,\nonumber\end{eqnarray}$$
where
 $[\cdot ,\cdot ]$
denotes the commutator, for example
 $[X,Y]=XY-YX$
. The recipe to write down the terms on the right-hand side is of no consequence for our purposes; what is remarkable is that this right-hand side is a combination of
 $X$
,
 $Y$
and iterated commutators.
Now the BCH is valid, at least formally (i.e. disregarding the convergence of the series involved), if
 $X$
and
 $Y$
, instead of matrices, are elements of any associative, non-commutative algebra. In particular it may be applied to the case where
 $X$
and
 $Y$
are first-order differential operators, such as those considered above. Going back to (9.2) and recalling that the commutator of the Lie derivatives corresponds to the Lie bracket of the vector fields (Proposition 9.1), the BCH formula with
 $s=t=h$
then yields
 $$\begin{eqnarray}\unicode[STIX]{x1D711}_{h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{A})}=\exp (hD_{\tilde{f}_{h}^{\infty }}),\end{eqnarray}$$
where
 $f_{h}^{\infty }$
is the vector field
 $$\begin{eqnarray}f_{h}^{\infty }=f^{(\text{A})}+f^{(\text{B})}+\displaystyle \frac{h}{2}[f^{(\text{A})},f^{(\text{B})}]+\displaystyle \frac{h^{2}}{12}[f^{(\text{A})},[f^{(\text{A})},f^{(\text{B})}]]+\cdots \,.\end{eqnarray}$$
Now a comparison with (9.1) shows that
 $\unicode[STIX]{x1D711}_{h}^{(\text{B})}\circ \unicode[STIX]{x1D711}_{h}^{(\text{A})}$
is formally the
 $h$
-flow of
 $f_{h}^{\infty }$
, or, in other words, that
 $f_{h}^{\infty }$
is the modified vector-field for the Lie–Trotter splitting algorithm (3.11).
For Strang’s method and for more involved splitting integrators the methodology is the same: each of the individual flows whose composition yields
 $\unicode[STIX]{x1D713}_{h}$
is written as an exponential and then the exponentials are combined via the BCH formula. For an integrator where
 $\unicode[STIX]{x1D713}_{h}$
is the composition of
 $m$
flows,
 $m-1$
applications of the BCH are required. The task may be demanding due to the combinatorial intricacies of the BCH formula.
Remark 9.2. As noted in Section 4, finding the modified vector field as above and then resorting to Theorem 4.7 is the most common way of investigating the consistency of splitting algorithms. An alternative direct technique, not based on modified equations, was suggested by Murua and Sanz-Serna (Reference Murua and Sanz-Serna1999). More recently, word series (Alamo and Sanz-Serna Reference Alamo and Sanz-Serna2016, Murua and Sanz-Serna Reference Murua and Sanz-Serna2017) have been introduced as a simpler means to deal with this kind of question. A survey of the combinatorial techniques used to analyse integrators is provided by Sanz-Serna and Murua (Reference Sanz-Serna and Murua2015).
9.2 Distributions with light tails
Verlet scheme for time-step (a)
 $h=1$
and (b)
 $h=1/2$
applied to
 $H(q,p)=(1/2)p^{2}+(1/4)q^{4}$
. The numerical solutions mimic the behaviour of the exact solution only for initial conditions close to the origin. Decreasing
 $h$
enlarges the region where the integrator performs satisfactorily, but does not eliminate the problem.

The numerical integration of Hamiltonian systems with a quadratic Hamiltonian (3.27) (which corresponds to HMC sampling of Gaussian distributions) was discussed in Section 3. For distributions whose tails are lighter than those of a Gaussian, the potential energy
 ${\mathcal{U}}(q)$
grows more rapidly than quadratically as
 $|q|\rightarrow \infty$
and this causes difficulties when integrating numerically the Hamiltonian dynamics.
We illustrate this for the univariate distribution with non-normalized density
 $\exp (-q^{3})$
. Figure 9.1 shows, for two values of
 $h$
, nine velocity Verlet trajectories corresponding to initial conditions with
 $p=0$
and
 $q\in (0,2]$
. Whereas for smaller values of the initial
 $q$
the numerical trajectory mimics the behaviour of the true solution, large initial values of
 $q$
lead to trajectories that quickly escape to infinity. Reducing the value of
 $h$
enlarges the size of the domain where Verlet performs satisfactorily. However, no matter how small
 $h$
is chosen, there will be an outer region where the performance is bad. This is easily understood. The kicks of the Verlet algorithm update
 $p$
by using the formula
 $p\mapsto p-(h/2)q^{3}$
. For this update to be a reasonable approximation to the true dynamics, it is obvious that the magnitude of
 $(h/2)q^{3}$
should be small when compared with the magnitude of
 $p$
; a requirement that does not hold for any fixed
 $h$
and
 $p$
if
 $|q|$
is sufficiently large. The problem is the same for other explicit integrators. For implicit integrators, such as the midpoint rule, the solution of the algebraic equations to be solved at each step also demands smaller values of
 $h$
for larger values of
 $q$
as discussed in Sanz-Serna and Calvo (Reference Sanz-Serna and Calvo1994, Section 3.3.3).
The conclusion is that, when using an integrator with fixed
 $h$
, one’s attention has to be restricted to a bounded subset
 $D$
of the phase space
 $\mathbb{R}^{2d}$
chosen to guarantee that the complement
 $\mathbb{R}^{2d}\backslash D$
has negligible probability with respect to
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
. After fixing
 $D$
, a suitably small value of
 $h$
has to be chosen. While the situation is well understood for the sampling algorithm MALA (Bou-Rabee and Hairer Reference Bou-Rabee and Hairer2013), the corresponding analysis for HMC has not yet been carried out.
9.3 Randomizing the time-step and the duration
Time-step or duration randomization for the Ornstein–Uhlenbeck bridge. Mean acceptance probability as a function of
 $h$
for (a) PHMC operated with constant step sizes, (b) PHMC operated with randomized step sizes of average
 $h$
, and (c) PRHMC, for
 $c=0$
and three values of
 $\unicode[STIX]{x1D6E5}s$
. In all three cases the duration parameter is
 $\unicode[STIX]{x1D706}=20$
. The number of samples is
 $10^{4}$
. The PRHMC algorithm is the least susceptible to periodicities in the underlying Hamiltonian dynamics.

The exact RHMC algorithm, where the length of the integration leg is a random variable with exponential distribution, was discussed at the end of Section 5 along with its numerical counterpart. We also discussed there an alternative procedure, based on randomizing the step length. We now illustrate the performance of these randomized algorithms in the case of the Ornstein–Uhlenbeck bridge example considered in Section 8. With the notation employed there, we set
 $c=0$
, which leads to the standard Verlet integrator. We have implemented three algorithms: (i) PHMC operated with (constant) step sizes of length
 $h$
, (ii) PHMC operated with step sizes of length
 $\unicode[STIX]{x1D6E5}t$
uniformly distributed in the interval
 $[0.9h,1.1h]$
and (iii) PRHMC. The results are given in Figure 9.2 (panel (c) is the same as Figure 8.1(a)). As
 $h$
varies, the behaviour of the non-randomized algorithm (i) is very irregular due to resonances between the step size and the periods of the dynamics (see Section 5.2). Randomizing
 $h$
regularizes the behaviour, but not as successfully as PRMHC does. This is consistent with the study carried out in Bou-Rabee and Sanz-Serna (Reference Bou-Rabee and Sanz-Serna2017, §4–5).
The results of experiments with
 $c=0.5$
and
 $c=1$
, not reported here, show the same patterns.
9.4 PHMC for the Ornstein–Uhlenbeck bridge: proofs
We now prove Theorems 8.6 and 8.7.
9.4.1 One degree of freedom
We begin by studying the application of the integrator used in PHMC to a one-degree-of-freedom, linear analogue of the dynamics in (8.7) given by the Hamiltonian function
 $$\begin{eqnarray}H(q,p)=\displaystyle \frac{1}{2}\unicode[STIX]{x1D714}^{-2}p^{2}+\displaystyle \frac{1}{2}(\unicode[STIX]{x1D714}^{2}+1)q^{2}.\end{eqnarray}$$
If
 $\unicode[STIX]{x1D714}\gg 1$
, this corresponds to the motion of a particle with large mass
 $\unicode[STIX]{x1D714}^{2}$
attached to a stiff spring of constant
 $1+\unicode[STIX]{x1D714}^{2}$
. The solutions are periodic with a frequency
 $1+1/\unicode[STIX]{x1D714}^{2}$
that decreases as
 $\unicode[STIX]{x1D714}$
increases.
The one-step propagation matrix (cf. (3.22)) is given explicitly by
 $$\begin{eqnarray}\tilde{M}_{h,c}=\left[\begin{array}{@{}cc@{}}\cos (ch)-{\displaystyle \frac{h\tilde{\unicode[STIX]{x1D714}}^{2}}{2c\unicode[STIX]{x1D714}^{2}}}\sin (ch) & {\displaystyle \frac{\sin (ch)}{c\unicode[STIX]{x1D714}^{2}}}\\ -h\tilde{\unicode[STIX]{x1D714}}^{2}\cos (ch)-{\displaystyle \frac{4c^{2}\unicode[STIX]{x1D714}^{4}-h^{2}\tilde{\unicode[STIX]{x1D714}}^{4}}{4c\unicode[STIX]{x1D714}^{2}}}\sin (ch) & \cos (ch)-{\displaystyle \frac{h\tilde{\unicode[STIX]{x1D714}}^{2}}{2c\unicode[STIX]{x1D714}^{2}}}\sin (ch)\end{array}\right]\!,\end{eqnarray}$$
with
 $\tilde{\unicode[STIX]{x1D714}}^{2}=1+(1-c^{2})\unicode[STIX]{x1D714}^{2}$
, if
 $c\in (0,1]$
, or
 $$\begin{eqnarray}\tilde{M}_{h,c}=\left[\begin{array}{@{}cc@{}}1-{\displaystyle \frac{h^{2}}{2\unicode[STIX]{x1D714}^{2}}}(1+\unicode[STIX]{x1D714}^{2}) & {\displaystyle \frac{h}{\unicode[STIX]{x1D714}^{2}}}\\ {\displaystyle \frac{h(1+\unicode[STIX]{x1D714}^{2})(h^{2}-(4-h^{2})\unicode[STIX]{x1D714}^{2})}{4\unicode[STIX]{x1D714}^{2}}} & 1-{\displaystyle \frac{h^{2}}{2\unicode[STIX]{x1D714}^{2}}}(1+\unicode[STIX]{x1D714}^{2})\end{array}\right]\end{eqnarray}$$
if
 $c=0$
.
The following result is concerned with the stability of the integrator. Note that the stability restriction on
 $h$
weakens as
 $\unicode[STIX]{x1D714}$
gets larger.
Proposition 9.3. If
 $\unicode[STIX]{x1D714}>0$
,
 $c\in [0,1]$
, and
 $h>0$
satisfies
 $$\begin{eqnarray}\left\{\begin{array}{@{}ll@{}}ch+2\arctan \biggl(\displaystyle \frac{h(1+(1-c^{2})\unicode[STIX]{x1D714}^{2})}{2c\unicode[STIX]{x1D714}^{2}}\biggr)<\unicode[STIX]{x1D70B}\quad & \text{if }c\in (0,1],\\ h<\displaystyle \frac{2\unicode[STIX]{x1D714}}{\sqrt{1+\unicode[STIX]{x1D714}^{2}}}\quad & \text{if }c=0,\end{array}\right.\end{eqnarray}$$
then the splitting integrator is stable.
Proof. Since the integrator is symplectic,
 $\det (\tilde{M}_{h,c})=1$
and stability is ensured if the magnitude of the trace is
 ${<}2$
. The case
 $c=0$
is trivial. For the case
 $c\in (0,1]$
, by means of elementary trigonometric formulas we find
 $$\begin{eqnarray}\displaystyle \frac{1}{2}\operatorname{trace}(\tilde{M}_{h,c})=\frac{\cos (ch+\arctan ({\textstyle \frac{h\tilde{\unicode[STIX]{x1D714}}^{2}}{2c\unicode[STIX]{x1D714}^{2}}}))}{\cos (\arctan ({\textstyle \frac{h\tilde{\unicode[STIX]{x1D714}}^{2}}{2c\unicode[STIX]{x1D714}^{2}}}))}.\end{eqnarray}$$
As
 $h$
increases from 0, stability is lost when
 $h$
is such that the sum of the arguments in the cosine functions reaches
 $\unicode[STIX]{x1D70B}$
, so that the numerator and the denominator are opposite.☐
As in Section 4.4, for stable integrations,
 $\tilde{M}_{h,c}$
may be written in the form (4.8), with
 $\cos (\unicode[STIX]{x1D703}_{h})=\operatorname{trace}(\tilde{M}_{h,c})/2$
and
 $$\begin{eqnarray}\unicode[STIX]{x1D712}_{h}=\left\{\begin{array}{@{}ll@{}}{\displaystyle \frac{\sin (ch)}{c\unicode[STIX]{x1D714}^{2}\sin (\unicode[STIX]{x1D703}_{h})}}\quad & \text{if }c\in (0,1],\\ {\displaystyle \frac{h}{\unicode[STIX]{x1D714}^{2}\sin (\unicode[STIX]{x1D703}_{h})}}\quad & \text{if }c=0.\end{array}\right.\end{eqnarray}$$
For the error
 $\unicode[STIX]{x1D6E5}$
in
 $H$
after an integration leg, by proceeding as in the proof of Proposition 6.4, we may show the following.
Proposition 9.4. For any positive integer
 $n$
,
 $\unicode[STIX]{x1D714}>0$
,
 $c\in [0,1]$
,
 $\unicode[STIX]{x1D6FD}>0$
and
 $h>0$
satisfying the stability requirement (9.3), the energy error after
 $n$
steps satisfies
 $$\begin{eqnarray}\mathbb{E}(\unicode[STIX]{x1D6E5})=\unicode[STIX]{x1D6FD}^{-1}\sin ^{2}(n\unicode[STIX]{x1D703}_{h})\unicode[STIX]{x1D70C}(c,\unicode[STIX]{x1D714},h),\end{eqnarray}$$
where the expectation is over random initial conditions with non-normalized density
 $\text{e}^{-\unicode[STIX]{x1D6FD}H(q,p)}$
and
 $$\begin{eqnarray}\unicode[STIX]{x1D70C}(c,\unicode[STIX]{x1D714},h)=\displaystyle \frac{1}{2}\biggl(\widehat{\unicode[STIX]{x1D712}}_{h}^{2}+\displaystyle \frac{1}{\widehat{\unicode[STIX]{x1D712}}_{h}^{2}}-2\biggr)=\displaystyle \frac{1}{2}\biggl(\widehat{\unicode[STIX]{x1D712}}_{h}-\displaystyle \frac{1}{\widehat{\unicode[STIX]{x1D712}}_{h}}\biggr)^{2}\geq 0\end{eqnarray}$$
with
 $$\begin{eqnarray}\widehat{\unicode[STIX]{x1D712}}_{h}^{2}=(\unicode[STIX]{x1D714}^{2}+\unicode[STIX]{x1D714}^{4})\unicode[STIX]{x1D712}_{h}^{2}.\end{eqnarray}$$
Accordingly
 $$\begin{eqnarray}0\leq \mathbb{E}(\unicode[STIX]{x1D6E5})\leq \unicode[STIX]{x1D70C}(c,\unicode[STIX]{x1D714},h).\end{eqnarray}$$
Our next result gives a representation for
 $\unicode[STIX]{x1D70C}$
. The proof is a tedious exercise in algebra and will not be given.
Proposition 9.5. For
 $\unicode[STIX]{x1D714}>0$
,
 $c\in [0,1]$
, and
 $h>0$
satisfying the stability requirement (9.3), we have
 $$\begin{eqnarray}\unicode[STIX]{x1D70C}(c,\unicode[STIX]{x1D714},h)=\displaystyle \frac{1}{2}\displaystyle \frac{h^{4}r^{2}}{(1+\unicode[STIX]{x1D714}^{-2})(1+\unicode[STIX]{x1D714}^{-2}-h^{2}r)},\end{eqnarray}$$
where
 $r$
is the function
 $$\begin{eqnarray}r(c,\unicode[STIX]{x1D714},h)=\displaystyle \frac{1}{4}(1-c^{2}+\unicode[STIX]{x1D714}^{-2})^{2}+c^{2}(1-c^{2}+\unicode[STIX]{x1D714}^{-2})R(ch),\end{eqnarray}$$
with
 $$\begin{eqnarray}R(ch)=\displaystyle \frac{1-ch\cot (ch)}{(ch)^{2}}.\end{eqnarray}$$
The function
 $R(\unicode[STIX]{x1D701})$
has the finite limit
 $1/3$
as
 $\unicode[STIX]{x1D701}\rightarrow 0$
. If
 $c>0$
,
 $R(ch)$
is positive and increases monotonically in the interval
 $0<ch<\unicode[STIX]{x1D70B}$
, with
 $R(ch)\uparrow \infty$
as
 $ch\uparrow \unicode[STIX]{x1D70B}$
. As a consequence,
 $r$
is an increasing function of
 $h\in (0,\unicode[STIX]{x1D70B})$
; the term
 $1+\unicode[STIX]{x1D714}^{-2}-h^{2}r$
in (9.4) approaches
 $0$
as
 $h$
approaches the upper limit of the stability interval. The preceding propositions imply that the mean energy error has an
 $O(h^{4})$
bound. By now this result is hardly a surprise, because we are dealing with an integrator of order
 $\unicode[STIX]{x1D708}=2$
.
9.4.2
$d$
degrees of freedom

We now address the application of PHMC to the target associated with (8.1) when
 $g(u)=(1/2)u^{2}$
. Theorems 8.6 and 8.7 are proved by using in
 $\mathbb{R}^{d}$
an orthonormal basis of eigenvectors of
 $-\mathbf{L}$
(cf. the proof of (6.7)). In the basis of eigenvectors the different components are stochastically independent but not identically distributed.
For Theorem 8.6 it is enough to recall that in Proposition 9.3 larger values of
 $\unicode[STIX]{x1D714}$
lead to less stringent stability requirements. Therefore stability is limited by the smallest eigenvalue of
 $-\mathbf{L}$
given in (8.8).
Turning to the proof of Theorem 8.7, by using the spectral decomposition and Proposition 9.4 with
 $\unicode[STIX]{x1D6FD}=\unicode[STIX]{x1D6E5}s$
, we may write
 $$\begin{eqnarray}0\leq \mathbb{E}(\unicode[STIX]{x1D6E5}{\mathcal{H}}_{d})\leq \mathop{\sum }_{j=1}^{d}\unicode[STIX]{x1D70C}(c,\unicode[STIX]{x1D714}_{j},h),\end{eqnarray}$$
with
 $\unicode[STIX]{x1D714}_{j}^{2}$
equal to the
 $j$
th eigenvalue of
 $-\mathbf{L}$
,
 $$\begin{eqnarray}\unicode[STIX]{x1D714}_{j}^{2}=\displaystyle \frac{4}{\unicode[STIX]{x1D6E5}s^{2}}\sin ^{2}\biggl(\displaystyle \frac{j\unicode[STIX]{x1D70B}}{2(d+1)}\biggr)\geq \displaystyle \frac{4j^{2}}{S^{2}}.\end{eqnarray}$$
We now use (9.4) to obtain the bound
 $$\begin{eqnarray}0\leq \mathbb{E}(\unicode[STIX]{x1D6E5}{\mathcal{H}}_{d})\leq \displaystyle \frac{h^{4}}{2}\mathop{\sum }_{j=1}^{d}\displaystyle \frac{r(c,\unicode[STIX]{x1D714}_{j},h)^{2}}{1-h^{2}r(c,\unicode[STIX]{x1D714}_{j},h)},\end{eqnarray}$$
and, since
 $r$
is a decreasing function of
 $\unicode[STIX]{x1D714}$
,
 $$\begin{eqnarray}0\leq \mathbb{E}(\unicode[STIX]{x1D6E5}{\mathcal{H}}_{d})\leq d\displaystyle \frac{h^{4}}{2}\displaystyle \frac{r(c,\unicode[STIX]{x1D714}_{1},h)^{2}}{1-h^{2}r(c,\unicode[STIX]{x1D714}_{1},h)}.\end{eqnarray}$$
The first bound in the theorem now follows easily: for
 $h$
bounded away from
 $\unicode[STIX]{x1D70B}$
,
 $r$
is bounded, and then
 $h$
may be reduced further to ensure that
 $1-h^{2}r(c,\unicode[STIX]{x1D714}_{1},h)$
is bounded away from 0.
When
 $c=1$
,
 $$\begin{eqnarray}r(1,\unicode[STIX]{x1D714}_{j},h)=\displaystyle \frac{1}{4}\unicode[STIX]{x1D714}_{j}^{-4}+\unicode[STIX]{x1D714}_{j}^{-2}R(h)\leq \displaystyle \frac{S^{4}}{64j^{4}}+\displaystyle \frac{S^{2}}{4j^{2}}R(h),\end{eqnarray}$$
and therefore for
 $h$
bounded away from
 $\unicode[STIX]{x1D70B}$
,
 $r(1,\unicode[STIX]{x1D714}_{j},h)=O(j^{-2})$
. Thus, if we write
 $$\begin{eqnarray}0\leq \mathbb{E}(\unicode[STIX]{x1D6E5}{\mathcal{H}}_{d})\leq \displaystyle \frac{h^{4}}{2}\mathop{\sum }_{j=1}^{d}\displaystyle \frac{r(1,\unicode[STIX]{x1D714}_{j},h)^{2}}{1-h^{2}r(1,\unicode[STIX]{x1D714}_{1},h)},\end{eqnarray}$$
the sum on the right-hand side may be bounded independently of
 $d$
.
9.5 Convergence
Here is a brief discussion of the sampling properties of HMC.
Intuitively speaking, the point of using HMC is that its Hamiltonian dynamics breaks the random walk behaviour that impairs the convergence of simple MCMC methods like the random walk Metropolis or the MALA algorithm (Gustafson Reference Gustafson1998, Diaconis, Holmes and Neal Reference Diaconis, Holmes and Neal2000). This slow convergence can be understood by using a diffusion approximation of these simple MCMC methods. In particular, the processes associated with simple MCMC methods are often well approximated (in a weak sense) by overdamped Langevin dynamics (Bou-Rabee et al. Reference Bou-Rabee, Donev and Vanden-Eijnden2014: see their Theorem 5.1 for a precise mathematical statement), also called Brownian dynamics. This may be seen as a consequence of the detailed balance property of the algorithms. As a result, the corresponding paths meander around state space and explore the target distribution mainly by diffusion. Qualitatively speaking, this is random walk behaviour. The basic idea in HMC is to replace the first-order Langevin dynamics in order to avoid this random walk behaviour.
Unfortunately, beyond this intuition, the improvement in convergence afforded by HMC is not well understood. Under certain conditions on the time-step and target distribution, it has been known for a while that numerical HMC converges to the right distribution asymptotically (Schütte Reference Schütte1999, Stoltz Reference Stoltz2007, Cancès, Legoll and Stoltz Reference Cancès, Legoll and Stoltz2007). More recently, the piecewise deterministic process associated with Algorithm 5.10 (exact RHMC) was shown to be geometrically ergodic, that is, its transition probabilities converge to the target distribution in the total variation metric at an exponential rate (Bou-Rabee and Sanz-Serna Reference Bou-Rabee and Sanz-Serna2017, Theorem 3.9). The proof of geometric ergodicity of RHMC relies on Harris’s theorem, which requires a (local) version of Doeblin’s condition: a minorization condition for the transition probabilities at a finite time and in a compact set. Unfortunately, given the complicated form of these transition probabilities, the minorization condition involves non-explicit constants, and in particular, the dependence of the resulting convergence rate on the mean duration parameter is not clear.
Using a coupling approach, a contraction rate for exact RHMC in a Wasserstein distance has been derived (Bou-Rabee and Eberle 2018). The dependence of the contraction rate on the mean duration parameter is explicit. It follows from this rate that, if the mean duration parameter is proportional to the standard deviation of the target distribution, then the algorithm converges at a kinetic speed (as opposed to a diffusive speed). The main tools used in the proof are a Markovian coupling and a coupling distance that are both tailored to the structure of exact RHMC. The coupling is based on the framework introduced in Eberle (Reference Eberle2016), and is related to a recently developed coupling for second-order Langevin dynamics (Eberle Reference Eberle2018, Eberle, Guillin and Zimmer Reference Eberle, Guillin and Zimmer2016).
9.6 Related algorithms
We finally discuss generalizations of Algorithm 5.6 (numerical HMC). The corresponding literature is extensive and rapidly growing; we limit ourselves to a few of the many available techniques.
9.6.1 Generalized HMC
Generalized HMC (GHMC) allows the possibility of partial randomization of momentum at every step of the HMC algorithm (Horowitz Reference Horowitz1991, Kennedy and Pendleton Reference Kennedy and Pendleton2001). Specifically, in GHMC, one introduces a so-called Horowitz angle
 $\unicode[STIX]{x1D719}\in (0,\unicode[STIX]{x1D70B}/2]$
and replaces the randomized momentum
 $\unicode[STIX]{x1D709}_{0}$
in Step 1 of Algorithm 5.6 with
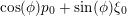 $\cos (\unicode[STIX]{x1D719})p_{0}+\sin (\unicode[STIX]{x1D719})\unicode[STIX]{x1D709}_{0}$
. This partial momentum randomization preserves the
 $p$
-marginal of
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
, and hence GHMC leaves
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
invariant. When
 $\unicode[STIX]{x1D719}=\unicode[STIX]{x1D70B}/2$
, the initial momentum
 $p_{0}$
is fully randomized and we recover HMC. If
 $\unicode[STIX]{x1D719}\in (0,\unicode[STIX]{x1D70B}/2)$
, then
 $p_{0}$
is only partially randomized; this may be of interest in molecular dynamics applications because then the samples may give more information on the Hamiltonian dynamics than when each integration leg starts with a completely new momentum. The case
 $\unicode[STIX]{x1D719}=0$
is excluded, since then there is no momentum randomization, and consequently, the GHMC chain is confined to a single level set of
 $H$
, and in general, is not ergodic with respect to
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
. Since the momentum randomizations are the source of dissipation in HMC (Bou-Rabee and Sanz-Serna Reference Bou-Rabee and Sanz-Serna2017), partial momentum randomization makes the algorithm less dissipative and less diffusive, as discussed in Neal (Reference Neal and Brooks2011, §5.5.3). One can similarly introduce a partial momentum randomization to Algorithm 5.11 (numerical RHMC).
9.6.2 Extra chance HMC
As mentioned earlier, rejections increase correlations along the HMC chain and waste computational effort. Extra chance HMC (XHMC) (Campos and Sanz-Serna Reference Campos and Sanz-Serna2015) provides a simple way for HMC to get extra chances to obtain acceptance, and hence delay or even avert rejection as in Mira (Reference Mira2001) and Green and Mira (Reference Green and Mira2001). To describe the XHMC algorithm, it suffices to describe its accept/reject mechanism, which we state in terms of a symplectic and reversible integrator
 $\unicode[STIX]{x1D713}_{h}$
, and its
 $n$
-step map,
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}=\unicode[STIX]{x1D713}_{h}^{n}$
where
 $n=\lfloor \unicode[STIX]{x1D706}/h\rfloor$
. Given a user-prescribed number of extra chances
 $K$
and
 $(q,p)\in \mathbb{R}^{2d}$
, define
 $\unicode[STIX]{x1D6E4}^{0}(q,p)=0$
,
 $\unicode[STIX]{x1D6E4}^{K+1}(q,p)=1$
, and
 $$\begin{eqnarray}\unicode[STIX]{x1D6E4}^{j}(q,p)=\unicode[STIX]{x1D6FC}(q,p)\vee \cdots \vee \unicode[STIX]{x1D6FC}^{j}(q,p),\quad 1\leq j\leq K,\end{eqnarray}$$
where
 $$\begin{eqnarray}\unicode[STIX]{x1D6FC}^{j}(q,p)=\min \{1,\text{e}^{-(H(\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}^{j}(q,p))-H(q,p))}\}.\end{eqnarray}$$
Note that
 $\unicode[STIX]{x1D6E4}^{j}$
is monotonically increasing with
 $j$
. Instead of flipping a coin at every step as in Algorithm 5.6, XHMC rolls a
 $(K+1)$
-sided die with probabilities
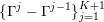 $\{\unicode[STIX]{x1D6E4}^{j}-\unicode[STIX]{x1D6E4}^{j-1}\}_{j=1}^{K+1}$
. Given the current state of the chain
 $(q_{0},p_{0})\in \mathbb{R}^{2d}$
, the transition in Step 3 of Algorithm 5.6 is accordingly replaced by
 $$\begin{eqnarray}(q_{1},p_{1})=\left\{\begin{array}{@{}ll@{}}\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}^{j}(q_{0},\unicode[STIX]{x1D709}_{0})\quad & \text{if the }j\text{th side of the die comes up},\\ (q_{0},-\unicode[STIX]{x1D709}_{0})\quad & \text{if the }(K+1)\text{th side of the die comes up},\end{array}\right.\end{eqnarray}$$
where
 $\unicode[STIX]{x1D709}_{0}\sim {\mathcal{N}}(0,M)$
. It is straightforward to show that XHMC leaves
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
invariant (Campos and Sanz-Serna Reference Campos and Sanz-Serna2015, Appendix A). Moreover, thanks to the possibility of extra chances, the probability of rejection at every step drops from
 $\unicode[STIX]{x1D6FC}(q_{0},p_{0})$
to
 $1-\unicode[STIX]{x1D6E4}^{K}(q_{0},p_{0})$
. As its name suggests, the accept/reject mechanism in XHMC can be implemented recursively, so that the proposal move
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}^{j}(q_{0},p_{0})$
and its associated transition probability
 $\unicode[STIX]{x1D6E4}^{j}-\unicode[STIX]{x1D6E4}^{j-1}$
are only computed if
 $\unicode[STIX]{x1D6F9}_{\unicode[STIX]{x1D706}}^{j-1}(q_{0},p_{0})$
is not accepted. One can also easily incorporate a partial momentum randomization into XHMC.
9.6.3 Tempering techniques
Probability distributions with multiple modes arise frequently in practice. Different modes may represent metastable conformations of a large molecular system (Frantz, Freeman and Doll Reference Frantz, Freeman and Doll1990, Hansmann and Okamoto Reference Hansmann and Okamoto1993, Hansmann Reference Hansmann1997, Sugita and Okamoto Reference Sugita and Okamoto1999, Wales Reference Wales2003) or important features of posterior distributions in Bayesian inference problems (Geyer and Thompson Reference Geyer and Thompson1995, Neal Reference Neal1996, Liang and Wong Reference Liang and Wong2001, Ji and Wong Reference Ji and Wong2006, Kou, Zhou and Wong Reference Kou, Zhou and Wong2006). Unfortunately, HMC may not converge well in situations where the potential energy has multiple minima separated by large barriers. This is a well-known limitation of HMC. It may be due to the low probability of the momentum randomizations in HMC to produce an initial condition whose kinetic energy is sufficiently high that the corresponding solution to Hamilton’s equations crosses the potential energy barriers. Also, the momentum randomization may have difficulties producing an initial momentum
 $\unicode[STIX]{x1D709}_{0}$
with the right direction for the solution to Hamilton’s equation to exit the current potential well. For such multimodal target distributions, it is advantageous to use HMC in conjunction with a tempering technique such as parallel tempering, simulated tempering, and tempered transition methods (Geyer Reference Geyer and Keramides1991, Marinari and Parisi Reference Marinari and Parisi1992, Geyer and Thompson Reference Geyer and Thompson1995, Neal Reference Neal1996). Tempering methods typically introduce an artificial inverse temperature parameter
 $\unicode[STIX]{x1D6FD}$
and apply HMC to the Boltzmann–Gibbs distribution at multiple values of this parameter. The basic idea is that at sufficiently high temperature, the tempered Boltzmann–Gibbs distribution becomes flat enough that barrier crossings in the Hamiltonian integration legs become more likely. Of course, the states of the tempered chains cannot be directly used to compute sample averages with respect to
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
, which emphasizes that the computational cost of these tempering techniques is by no means negligible.
9.6.4 No U-turns
A practical difficulty with HMC is tuning the durations of the Hamiltonian integration legs. The No-U-Turn Sampler (NUTS) adaptively chooses this parameter by increasing the length of the numerical orbit until the distance between the endpoints of the orbit stops increasing. Unfortunately this procedure breaks reversibility, since, roughly speaking, if this criterion is applied in the reverse direction starting from the end of a trajectory, one does not expect to land at the start of the trajectory. Since reversibility is a key ingredient to the accept/reject mechanism in Algorithm 5.1, and the proof of the associated Theorem 5.7, NUTS uses a different approach: it applies the criterion to the discrete trajectory obtained by integrating the Hamiltonian dynamics in the forward and backward directions. Starting with a single step, the number of forward and backward integration steps is doubled until a U-turn first occurs. NUTS then ends the simulation and samples from all of these points in a way that ensures that the algorithm leaves
 $\unicode[STIX]{x1D6F1}_{\operatorname{BG}}$
invariant. The procedure does not use the Metropolis–Hastings method but rather a variant of the slice sampling method (Neal Reference Neal2003). Since this sampling step involves all of the states produced by this procedure, the algorithm is thought to have some of the appealing properties of the windowed HMC method, which employs an accept/reject mechanism based on windows of states (Neal Reference Neal1994, Neal Reference Neal and Brooks2011).
9.6.5 Shadow HMC
Given a symplectic and reversible integrator
 $\unicode[STIX]{x1D713}_{h}$
for the Hamiltonian dynamics, shadow HMC is an importance sampling technique that replaces the Boltzmann–Gibbs density
 $\exp (-H)$
with a shadow density
 $\exp (-\tilde{H}_{h}^{[\unicode[STIX]{x1D707}]})$
where
 $\tilde{H}_{h}^{[\unicode[STIX]{x1D707}]}$
is the modified (or shadow) Hamiltonian of
 $\unicode[STIX]{x1D713}_{h}$
up to order
 $\unicode[STIX]{x1D707}$
(Izaguirre and Hampton Reference Izaguirre and Hampton2004, Sweet, Hampton, Skeel and Izaguirre Reference Sweet, Hampton, Skeel and Izaguirre2009, Akhmatskaya and Reich Reference Akhmatskaya and Reich2008). In so doing, shadow HMC samples from a different target density and the samples have to be reweighed in order to compute averages with respect to the target distribution. This method is not to be confused with the so-called surrogate transition method (Liu Reference Liu2008), since in shadow HMC the target density is altered. The rationale for shadow HMC is that
 $\exp (-\tilde{H}_{h})$
is easy to sample from, in the sense that
 $\unicode[STIX]{x1D713}_{h}$
preserves
 $\tilde{H}_{h}$
much more accurately than
 $H$
, and hence, for a given duration parameter, shadow HMC increases the acceptance probability without having to reduce the time-step
 $h$
. There is also a shadow generalized HMC method, which similarly replaces the target density in GHMC with
 $\exp (-\tilde{H}_{h})$
. Several aspects of shadow HMC have not been sufficiently analysed from a mathematical viewpoint. For instance the integrability of
 $\exp (-\tilde{H}_{h}^{[\unicode[STIX]{x1D707}]})$
has not been studied in depth. Moreover, shadow HMC requires estimating the modified Hamiltonian to order
 $\unicode[STIX]{x1D707}$
, which is non-trivial since it requires computing (or estimating) higher derivatives of
 ${\mathcal{U}}$
(Skeel and Hardy Reference Skeel and Hardy2001). The momentum randomization step in Algorithm 5.6 must be modified, since the
 $p$
-marginal of
 $\exp (-\tilde{H}_{h}^{[\unicode[STIX]{x1D707}]})$
is no longer a Gaussian distribution.
Acknowledgements
This work was supported in part by a Catalyst Grant to N. B-R. from the Provost’s Fund for Research at Rutgers University–Camden under project no. 205536, and also in part by the NSF Research Network in Mathematical Sciences: ‘Kinetic description of emerging challenges in multiscale problems of natural sciences’ (PI, Eitan Tadmor; NSF grant no. 11-07444). J.M.S. has been supported by project MTM2016-77660-P(AEI/FEDER, UE) funded by MINECO (Spain).