





1. Introduction
The rate of data acquisition in contemporary astronomy surpasses the capacity of human astronomers to process these data using conventional approaches. Just the Nancy Grace Roman Space Telescope and the Vera C. Rubin Observatory are expected to generate approximately 500 petabytes of scientific data, which is ‘many orders of magnitude greater than the cumulative astronomical data collected throughout human history’Footnote 1 . Similar considerations hold for the Square Kilometer Array Observatory in the radio range.
The adoption and implementation of big-data methodologies within the field of astronomy are of paramount importance to the sustained success of astronomical research teams in the face of this data deluge. This is widely acknowledged within the astronomical community, as evident from the Astro2020 Decadal Survey and its associated white papers. Applying big-data techniques in astronomy can facilitate tasks such as analysing vast datasets, optimising data processing pipelines, and managing archival data. Anomaly detection is a fundamental challenge in contemporary data science, particularly when applied to large-scale datasets. This paper addresses the identification of outliers within given data populations, aiming to direct focus towards a reduced subset of observations due to their deviation from established distributional patterns characteristic of the underlying population.
2. The dataset
For our study we have used a subset of 35,358 sources of the Chandra Source Catalogue v.2.0 (CSC Evans et al. Reference Evans, Evans, Martínez-Galarza, Miller, Primini, Azadi, Burke, Civano, D’Abrusco, Fabbiano, Graessle, Grier, Houck, Lauer, McCollough, Nowak, Plummer, Rots, Siemiginowska and Tibbetts2024) that was used in the previous outlier search of Swarm et al. (Reference Swarm, DeRoo, Liu and Watkins2022, S22 thereafter). The total CSC contains more than 300,000 X-ray sources, but most of them have a hardness ratio (X-ray colour) of null or
 $\pm1$
. Following S22, we excluded these sources from our study and used 27 (out of the more than 500) relevant summary properties (location, significance, instrument usage data, colour, best-fit spectral models) of the CSC. About 50% of the sources in our sample lack values for features of automatic model fits. We address this issue by using “dummy-variable imputation” for missing models, meaning that the missing values are set to 0, while a flag is set to keep track of the imputation. Missing error ellipses, and missing ACIS exposure are treated in the same way.
2.1. A previous study
Swarm et al. (Reference Swarm, DeRoo, Liu and Watkins2022, S22) used a principal component analysis (PCA) and an unsupervised random forest algorithm (uRF) to identify outliers in the CSC. While this approach is effective for the CSC, it is not scalable to larger datasets. As S22 mention in their paper, the current approach is limited by the memory capacity of the machine on which it is run. For their analysis they needed to chunked the data into smaller pieces to process them. This is suboptimal for mainly two reasons: (i) Working with chunks of data means the algorithm does not have access to the full dataset, which can lead to some outliers being missed; (ii) The chunking process can be time-consuming, and is hard to reproduce.
3. Our approach
In this work, we present an alternative approach to the problem of outlier detection in large datasets. Our approach is based on the k-nearest neighbours and spectral clustering algorithms, which are well-known machine learning algorithms that can be used for a variety of tasks, including outlier detection. We follow the algorithm, proposed in chapter 6 of Wang et al. (Reference Wang, Wang and Wilkes2020) which consists of the following five steps:
-
(1) Compute the k-nearest neighbours of each point in the dataset, and create a dataset for each point with its k-nearest neighbours
-
(2) Perform spectral clustering on each of the datasets created in step 1, and collect all the second-smallest eigenvalues
-
(3) Compute the frequency of each eigenvalue, and select the top P percent data points corresponding to eigenvalues with the lowest frequency
-
(4) For each of the data points selected in step 3, compute the distance to its k-nearest neighbours and sort them by it
-
(5) Select the top M data points with the largest distance to their k-nearest neighbours data points
The algorithm relies on the following hyperparameters. The number of nearest neighbours (k) to be considered when computing the k-nearest neighbours of each point. We set
 $k=7$
. The percentage of data points to select in step 3, which we set to
 $P=0.2$
. Another hyperparameter is the number of outliers (M).
3.1. The Heat library
We implemented our approach using the Heat libraryFootnote 2 , which is a distributed tensor framework for high performance data analytics created by Helmholtz Analytics. It serves as a Python toolset and its goal is to fill the gap between machine learning libraries with strong focus on exploiting GPU performance and traditional, distributed high-performance computing. The basic idea behind Heat is to provide a dtype, distributed tensor library with machine learning methods based on it. Among its notable characteristics, ‘heat‘ optimally utilises parallel and distributed computing resources, enabling rapid processing and examination of extensive datasets. It also equips users with diverse data manipulation and analysis tools, making it well-suited for activities like data cleansing, filtering, transformation, and aggregation.
4. Results & Discussion
As mentioned in Sect. 2 we use a combination of 27 relevant summary properties of the sources in the CSC, including the position, spectral properties, exposure, etc. to determine how “outlierish” a source is using an approach based on the k-nearest neighbours and spectral clustering algorithms and implemented with Heat (Sect. 3). Our approach gives a list of all the sources sorted by how “outlierish” they are. We take a look at the top 120 sources of this list, the numbers of outliers given in S22. We find that of the 120 sources 88 sources (73.3%) are flagged due to some observational issue (the pile-up fraction exceeds 10% in all observations, the source is located on an ACIS readout streak in all observations, the source is saturated in all observations, the source and/or background regions overlap in one or more contributing stacked observations, the source region parameters were manually modified via human review, the best fit source position was manually modified via human review, the source was manually added in the catalog via human review). Of the remaining 32 source 20 sources are variable. This result shows that our approach is sensitive in identifying outliers, as it picks up sources that stand out from the bulk of sources for some reason. However, the identified outliers are special because of some observational issue and not because they show special, interesting physical properties. The discrimination between outliers due to observational issues and those that stand out because of their physical properties is a general problem in outlier detection.
To exclude outliers due to some observational issue, we remove all sources from our sample that are flagged. This results in a cleaned data set of a remaining 24 225 sources. We conduct five independent outlier detection runs. Comparing the top 1061 sources (which corresponds to three per cent of all sources, including flagged ones) of these runs, we identify 31 outliers. Of these 24 are variable (77%).
In another step we also exclude the variable sources from our sample. Repeating our analysis with this sample we obtain the same 1061 sources in five independent runs and regard again the top 120 of them as outliers. We verified that this sample of outliers is identified as outliers because of their combination of properties and that they do not stand out in a single parameter (examples of distribution for some parameters are show in Fig. 1). A detailed analysis of the selected sources will be presented in a further paper.
Distribution of the galactic absorption, the hard-to-soft hardness, the ACIS exposure, and the powerlaw photon index for the sources of the sample (open diamonds) and for our outliers (filled circles).

If you wonder, why we did not include a direct comparison to the results of S22, we would like to mention that during our analysis we realised that about a quarter of the outliers detected by S22 cluster at a certain galactic absorption (
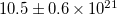 $10.5\pm0.6\times10^{21}$
cm
 $^{-2}$
) and at a certain ACIS exposure time (
 $1792\pm20$
ks; Fig. 2). We cannot explain where this preference comes from.
Distribution of galactic absorption and ACIS exposure for the sources of the sample and those identified as outliers by S22.

In the current implementation of the algorithm we did not need to exploit Heat’s full data parallelism capabilities yet. However, we plan as a follow-up project to scale our approach to larger datasets, like those of the Zwicky Transient Facility or those expected form LSST of the Vera Rubin Observatory.
Acknowledgement
We thank Dustin Swarm from the University of Iowa for providing the clean data set. HS acknowledge funding by the project “NRW-Cluster for data intensive radio astronomy: Big Bang to Big Data (B
 $^3$
D)” funded through the programme “Profilbildung 2020", an initiative of the Ministry of Culture and Science of the State of North Rhine-Westphalia. SM and TM visited JSC as summer students within the Helmholtz Information and Data Science Academy (HIDA) trilateral exchange programme.


 Open access

