


1. Introduction
The U.S. government issues thousands of regulations each year. Some of these respond to crises, such as the COVID-19 pandemic, while others develop over time to address longer-term goals. Regulations can address market failures by reducing or eliminating negative externalities and improve the efficiency of resource allocation. However, poorly designed or excessive regulations may impose a “regulatory burden” on the economy. How regulation affects the economy is thus an important question for both researchers and policymakers and is particularly relevant today. Efforts to answer this question are often hindered by the difficulty of measuring regulation. Existing research has mostly focused on measuring the quantity of regulation. However, the regulatory environment for economic activities depends not only on how many regulations there are but also on their types, the enforcement of specific regulatory requirements, the particular policy instrument used to achieve regulatory goals, and the subjective perception of regulation.
To study the relationship between regulation and economic outcomes through a holistic lens, we construct news-based, time-series measures of sentiment and uncertainty about the U.S. regulatory environment using natural language processing (NLP) applied to newspaper articles from 1985 through 2021. We show a simple economic application of these measures by examining the relationship between regulatory sentiment, regulatory uncertainty, and macroeconomic performance. The findings contribute to the understanding of the economic implications of regulation by documenting that changes in the regulatory environment that induce negative perceptions or higher uncertainty are associated with changes in aggregate economic activity. Moreover, regulatory sentiment, as defined in our study, may be a more appropriate measure for reflecting the connection between regulation and macroeconomic outcomes than regulatory uncertainty.
Our text analysis covers 608,172 news articles related to regulation from seven leading U.S. newspapers from January 1985 through December 2021. The normalized volume of these articles suggests increasing news attention to regulatory policy in the U.S. over time, stressing the need to investigate the content of regulation-related news. We then use an NLP technique, lexicon-based sentiment analysis, to evaluate two dimensions of the news corpus: the average sentiment (i.e., positive and negative tone) and the degree of uncertainty expressed in the news about regulation. Based on the estimated sentiment and uncertainty, we build monthly indexes of regulatory sentiment and regulatory uncertainty, respectively, from 1985 through 2021. In addition to the aggregate measures, we further categorize relevant news articles into 14 regulatory policy areas and construct categorical indexes that measure regulatory sentiment and uncertainty in specific policy areas.
To examine the empirical relationship, we estimate impulse responses of key macroeconomic variables to shocks in regulatory sentiment and regulatory uncertainty. A negative shock to the regulatory sentiment measure represents an unexpected change in the overall regulatory environment that is perceived negatively by stakeholders and reflected in the media, while a positive shock to regulatory uncertainty indicates a change in the regulatory environment that imposes high uncertainty. Hypothetically, when firms view regulatory changes negatively or become uncertain about them, they may withdraw or postpone their hiring and investment activities, thereby affecting aggregate economic outcomes.
The empirical results are largely consistent with the hypothesis. The impulse response functions suggest that a negative shock to aggregate regulatory sentiment is associated with large, persistent declines in future output and employment. In particular, regulatory sentiment shocks related to transportation and consumer safety and health are associated with negative, long-lasting responses in future output. These responses remain after various model modifications and upon controlling for existing measures of general economic sentiment or policy uncertainty, implying that our regulatory sentiment measure contains some unique information that is not captured by other related measures.
The estimated impulse responses to a regulatory uncertainty shock are more nuanced. The output and employment responses to an increase in aggregate regulatory uncertainty are not statistically significant in the baseline analysis and are at most transitory in an alternative model. However, increased uncertainty about business and trade regulation and energy regulation is associated with declines in aggregate output and appears to have a stronger linkage with economic outcomes compared to other areas.
Economic theory suggests that regulation can have a negative or positive impact on the economy. On one hand, regulation generally imposes restrictions on firm behavior and thus diverts resources that otherwise might be used for production and innovation (Coffey et al. Reference Coffey, McLaughlin and Peretto2020; Eads, Reference Eads1980). Regulation may also change a firm’s ability to calculate the payoffs of investments (Eads, Reference Eads1980). Uncertainty can exacerbate this effect, since it hampers firms’ ability to form a probability distribution of payoffs, making firms more cautious about their investment and hiring decisions (Bloom, Reference Bloom2009, Reference Bloom2014). On the other hand, regulation can generate positive economic impacts by changing the nature and the optimal institutional patterns of research that a firm undertakes Eads (Reference Eads1980). A well-known example is the “Porter hypothesis,” which argues that properly designed environmental regulations can stimulate innovation that may partially offset or even exceed their compliance costs (Porter and Van der Linde Reference Porter and Van der Linde1995).
The relationship between regulation and aggregate economic outcomes thus becomes an empirical question. Existing approaches to measuring regulation primarily focus on the quantity of regulation, such as the number of rules published by federal agencies, and the number of pages, total words, or command words in the regulatory code (e.g., the Code of Federal Regulations) (Coffey et al. Reference Coffey, McLaughlin and Peretto2020; Dawson and Seater, Reference Dawson and Seater2013; Mulligan and Shleifer, Reference Mulligan and Shleifer2005). Others use government spending and staffing devoted to regulatory activity as a proxy for regulation (Beard et al. Reference Beard, Ford, Kim and Spiwak2011; Sinclair and Vesey, Reference Sinclair and Vesey2012). These studies generally find a negative or statistically insignificant relationship between regulation and macroeconomic outcomes.
However, existing empirical measures do not provide complete information about the aggregate effects of regulation. The quantity of regulation or regulators’ spending is far from a perfect measure of regulation itself (Calomiris et al. Reference Calomiris, Mamaysky and Yang2020; Simkovic and Zhang, Reference Simkovic and Zhang2019). Moreover, these measures typically track a single aspect of regulation at a relatively low frequency (mostly annually) due to the prolonged rulemaking or budget process. Our news-based measures of regulatory sentiment and regulatory uncertainty capture real-time fluctuations in the outlook for the overall regulatory environment at a much higher frequency. These fluctuations can be caused by various types of regulatory events, such as the promulgation of a new regulation, a company’s regulatory compliance or violation, a regulatory investigation, or a lawsuit challenging agency regulatory actions. Therefore, our study presents a holistic view of the relationship between regulation and economic outcomes.
Sentiment and uncertainty around the regulatory environment are important because firm decisions are subject to these subjective perceptions. Firms’ anticipation of payoffs may depend on whether they hold a positive or negative view of the current and future regulatory environment, which captures the idea of “animal spirits” that influence household and business behavior (Keynes, Reference Keynes1936; Shiller, Reference Shiller2017). An analogy is consumer sentiment measuring subjective attitudes toward current and future economic conditions. Survey-based measures, such as the Michigan Consumer Sentiment Index, have been widely examined in economic studies and found to have incremental predictive power for consumption expenditures and other economic activity (Benhabib and Spiegel, Reference Benhabib and Spiegel2019; Bram and Ludvigson, Reference Bram and Ludvigson1998; Carroll et al. Reference Carroll, Fuhrer and Wilcox1994). Closely related to sentiment, uncertainty can postpone firm actions like investment and hiring (Bachmann and Bayer, Reference Bachmann and Bayer2013; Bloom, Reference Bloom2014). For example, a pharmaceutical company may have the option to invest in the development of a new drug; however, if the company is uncertain about whether the drug will be approved to enter the market by regulators, it may prefer to wait until some certainty is achieved.
Recent developments in NLP have introduced economists to using unstructured text as data and to building novel text-based measures of sentiment and uncertainty (Gentzkow et al. Reference Gentzkow, Kelly and Taddy2019). Newspapers are a popular source of text data, as they provide high-frequency information and can work as ”information intermediaries” with an effect of influencing and shaping public opinions (Ter Ellen et al. Reference Ter Ellen, Larsen and Thorsrud2022). Examples include news-based economic sentiment measures, which are found to be strongly correlated with survey-based consumer sentiment measures and help explain aggregate economic fluctuations (Fraiberger, Reference Fraiberger2016; Shapiro et al. Reference Shapiro, Sudhof and Wilson2022). Another seminal contribution comes from the news-based economic policy uncertainty (EPU) index developed by Baker et al. (Reference Baker, Bloom and Davis2016). Numerous studies have subsequently developed similar uncertainty measures for other countries (Arbatli Saxegaard et al. Reference Arbatli Saxegaard, Davis, Ito and Miake2022; Cerda et al. Reference Cerda, Silva and Valente2016) and specific policy areas such as trade policy and monetary policy (Caldara et al. Reference Caldara, Iacoviello, Molligo, Prestipino and Raffo2020; Husted et al. Reference Husted, Rogers and Sun2019). This research generally finds that increased policy uncertainty reduces business investment and employment growth, raises precautionary savings, and increases stock price volatility (Baker et al. Reference Baker, Bloom and Davis2016; Bloom et al. Reference Bloom, Floetotto, Jaimovich, Saporta-Eksten and Terry2018; Caldara et al. Reference Caldara, Iacoviello, Molligo, Prestipino and Raffo2020; Gulen and Ion, Reference Gulen and Ion2016; Julio and Yook, Reference Julio and Yook2016).
We contribute to this literature by developing sentiment and uncertainty measures specifically related to regulation as well as studying both across different regulatory areas. Few studies have examined sentiment or uncertainty around regulation. An exception is Baker et al. (Reference Baker, Bloom and Davis2016)’s categorical EPU index on regulation, which measures economic uncertainty around regulatory policy. They use a pre-defined set of terms related to regulation, in addition to their economic, uncertainty, and policy terms, to identify news articles that reflect regulatory policy uncertainty and construct the index based on the volume of those articles. Our regulatory uncertainty measure differs from the regulatory EPU index in several ways, both conceptually and methodologically. We discuss this in more detail in Section 4.3.
Our study has several practical implications. First, the dynamic relationships we show in this paper suggest that an improvement in the regulatory system that improves public perceptions of government interventions may help minimize unnecessary regulatory burden on the economy. Second, news sentiment and uncertainty around certain regulatory policy areas appear to have particularly strong links with macroeconomic performance. Policymakers in those areas should take into account the indirect macroeconomic effects that their regulations may entail and should increase transparency and clarity in the regulations. Third, up-to-date measures of regulatory sentiment and uncertainty can provide forward-looking information about economic conditions. This information may help firms better anticipate payoffs and make optimal hiring and investment decisions.
In the next section, we describe the data we use in this study, including text data from news articles and economic data used in the estimation of impulse response functions. In Section 3, we describe our approach to identifying the news content related to regulation and the evidence of increasing media attention to regulation over time. Section 4 presents the aggregate regulatory sentiment and regulatory uncertainty indexes, including the sentiment analysis method we use to construct the indexes, some descriptive analysis, and the validation of the indexes. Section 5 shows the impulse responses of macroeconomic variables to regulatory sentiment and uncertainty shocks. In Section 6, we describe the categorical indexes that measure regulatory sentiment and regulatory uncertainty across 14 policy areas and their varied roles in the impulse responses of macroeconomic outcomes. Section 7 concludes the study.
2. Data
Our initial news corpus includes over one million news articles that contain keywords beginning with “regulat” or “deregulat”Footnote 1 (e.g., “regulation,” “regulator,” “deregulation”) from seven U.S. newspapers published between January 1985 and December 2021. The seven newspapers are the Boston Globe, Chicago Tribune, Los Angeles Times, New York Times, USA Today, Wall Street Journal, and the Washington Post.Footnote 2 We access the full texts and metadata of the news articles through ProQuest’s TDM Studio, which provides a comprehensive collection of historical and current newspapers in a machine-readable format (ProQuest, 2022). We remove articles with identical full texts to a previous article, leaving 990,262 articles in the corpus.
Since the keyword “regulation” and its variants can be used in many contexts other than referring to government regulatory policy,Footnote 3 we conduct further analysis to refine the corpus by defining a dictionary of regulatory noun chunks (i.e., certain noun phrases extracted from the text) from the titles of all rules considered by federal agencies from 1995 to 2019. The rule title data are obtained from the federal government’s semiannual Unified Agenda of Regulatory and Deregulatory Actions reports (Office of Information and Regulatory Affairs, 2020). The reports provide uniform data on regulatory and deregulatory actions that agencies plan to issue in the near and long-term future. The Unified Agenda reports published over 190,000 actions between 1995 and 2019, which correspond to 38,868 unique rules (as identified by Regulation Identifier Numbers). Section 3 details our approach for defining the dictionary and identifying the news content related to regulatory policy. As a result, our final news corpus includes 608,172 regulation-related news articles. Table 1 shows the number of articles from each newspaper.
Article counts by newspaper

Table 1. Long description
A table titled Article counts by newspaper. The table has 8 rows and 6 columns. The columns are labeled All articles, Unique articles, Regulatory articles, First regulatory article, and Last regulatory article. The row labels are Wall Street Journal, New York Times, Los Angeles Times, The Washington Post, Chicago Tribune, Boston Globe, USA Today, and Total. The values in the table are as follows: Row 1: Wall Street Journal, 259714, 253862, 168874, 1985-01-02, 2021-12-31. Row 2: New York Times, 283773, 273223, 164626, 1985-01-01, 2021-12-31. Row 3: Los Angeles Times, 130697, 129998, 78438, 1985-01-01, 2021-12-31. Row 4: The Washington Post, 120506, 117519, 72705, 1987-01-01, 2021-12-31. Row 5: Chicago Tribune, 100049, 99327, 56154, 1985-01-01, 2021-12-31. Row 6: Boston Globe, 77358, 75946, 44862, 1985-01-01, 2021-12-31. Row 7: USA Today, 40951, 40387, 22513, 1987-04-01, 2021-12-30. Row 8: Total, 1013048, 990262, 608172, 1985-01-01, 2021-12-31.
For estimating impulse responses, we use monthly data on employment (Bureau of Labor Statistics, 2022), the effective federal funds rate, and industrial production (Board of Governors of the Federal Reserve System, 2022a,b), as well as monthly averages of the S&P 500 index (S&P Dow Jones Indices LLC, 2022). In robustness checks, we also use the Michigan Consumer Sentiment Index (University of Michigan, 2022), the economic sentiment index (Shapiro et al. Reference Shapiro, Sudhof and Wilson2022), the VIX (Cboe Exchange, Inc., 2022), and the EPU index (Baker et al. Reference Baker, Bloom and Davis2016). The economic data cover the period from January 1985 through December 2021 to match our regulatory measures.
3. News attention to regulation
In this section, we describe the approach we use to identify regulation-related news articles from the initial news corpus. Controlling for the total number of news articles published in each newspaper, we show evidence that news attention to regulation has been increasing over time.
3.1 Identifying regulation-related news
Identifying regulation-related news is challenging for several reasons. While some newspaper databases label news articles by subject categories such as finance, politics, and health care, news articles are rarely labeled as regulatory policy. Also, while regulation may be the main theme of an article, it may also be mentioned only in certain sections of an article that primarily discusses economic or political issues. This makes a standard article-level analysis inappropriate for identifying news content related to regulation. A simple search of a limited set of keywords like “regulation” or “regulator” would also yield inaccurate results because those words can be used in various contexts.
To identify news content specifically related to regulation, we define a dictionary of regulatory noun chunks to assess the context in which the keyword “regulation” or its variants are mentioned in an article. Specifically, we examine the sentence that mentions “regulat*” or “deregulat*” and its neighboring sentences (i.e., a sentence before and after the regulatory sentence). If any of the three sentences contain one or more regulatory noun chunks from our dictionary, then we consider these sentences to be regulation-related news. An article may have multiple regulatory sentences, depending on the extent to which regulation is the focus of the article, and all such sentences and their neighboring sentences constitute the regulatory section of the article. Specifically, we conduct this assessment in a three-step process.
First, we obtain noun chunks from the titles of all unique rules published in the Unified Agenda reports from 1985 to 2019. Noun chunks are “base noun phrases” identified using the NLP library spaCy. For example, the rule title “Test Procedures for the Analysis of Trace Metals Under the Clean Water Act” contains four noun chunks: [“Test Procedures,” “the Analysis,” “Trace Metals,” “the Clean Water Act”]. We then clean the noun chunks by eliminating special characters, removing leading articles (i.e., “the,” “a,” and “an” at the beginning of a noun chunk), and lemmatizing the tokens within the noun chunks. The above example thus becomes [“test procedure,” “analysis,” “trace metal,” “clean water act”]. We retain only the cleaned noun chunks with two or more tokens, because a single-token noun chunk such as “analysis” is too broad in meaning to suggest any information specific to regulation. We iterate this process over all unique rule titles and eventually generate a list of unique n-token noun chunks (
 $n\geq 2$
). This list includes over 37,000 noun chunks and serves as the base for our dictionary.
Next, we preprocess the texts of all news articles in our initial data set. This process includes segmenting sentences within an article, extracting the sentence that mentions “regulat*” or “deregulat*” (indexed
 $i$
) and its neighboring sentences (indexed
 $i-1$
and
 $i+1$
), and lemmatizing the tokens within the sentences. We then search each of the n-token noun chunks generated in the first step within the extracted sentences using regular expression operations. If the three consecutive sentences (
 $i-1$
to
 $i+1$
) contain one or more of the noun chunks, then these sentences are included in the regulatory section of the article.
As a third step, we conduct human checking and correction of the noun chunks that occur in the articles. Because the list of the n-token noun chunks automatically generated from the rule titles still includes some general terms frequently mentioned in news articles but not specifically related to government regulation (e.g., “same time,” “first quarter,” and “other country”), we read through the noun chunks appearing in all the news articles and manually filter out these general terms.Footnote 4 After removing these general terms from the results, there remain 10,458 unique noun chunks that appear in 608,172 news articles, meaning that each of these articles contains a regulatory section. These noun chunks form our dictionary of regulatory noun chunks, which are also used to construct our categorical indexes discussed in Section 6. Appendix A lists the 100 regulatory noun chunks that occur most frequently in the news articles.
Our sentiment analyses presented in the remainder of the paper are based on the corpus of the regulatory sections in the 608,172 news articles.
3.2 Increasing news attention to regulation
Tracking the relative frequency of articles discussing regulatory issues over time can suggest trends in news attention to regulation. We investigate this by building a monthly index of news attention to regulation using an approach similar to Baker et al. (Reference Baker, Bloom and Davis2016)’s method for building their EPU index. That is, we scale the monthly count of news articles that contain regulatory sections by dividing this count by the total number of news articles published in the newspaper that month, and then standardize the scaled monthly counts and normalize the time series to a mean of 100 from 1985 to 2009. Specifically, the monthly news attention index
 $NA_t$
is calculated as:
 \begin{equation} NA_t=z_t\frac {100}{\frac {1}{\widetilde {T}}\sum _{t=1}^{\widetilde {T}}z_t}, \end{equation}
where
 $z_t$
is the mean of standardized monthly counts across newspapers:
 \begin{equation} z_t=\frac {1}{K}\sum _{i=1}^{K}\frac {x_{it}}{N_{it}\delta _{i,\widetilde {T}}}, \end{equation}
where
 $i=\left \{1,2,\ldots ,K\right \}$
denotes the newspaper,
 $t=\left \{1,2,\ldots ,T\right \}$
denotes the month,
 $x_{it}$
is the raw count of articles related to regulation in newspaper
 $i$
in month
 $t$
,
 $N_{it}$
is the total number of news articles published in newspaper
 $i$
in month
 $t$
, and
 $\delta _{i,\widetilde {T}}$
is the standard deviation of the scaled count
 $\frac {x_{it}}{N_{it}}$
over the time interval
 $\widetilde {T}$
for standardization and normalization (i.e., January 1985–December 2009).
Monthly index of news attention to regulation (January 1985–December 2021).
Notes: The index is constructed by standardizing the monthly counts of regulation-related news articles scaled by the monthly counts of all news articles in each newspaper and normalizing the time series to a mean of 100 from January 1985 to December 2009. The index is calculated using data from seven U.S. newspapers including Boston Globe, Chicago Tribune, Los Angeles Times, New York Times, USA Today, Wall Street Journal, and the Washington Post.

Figure 1 plots the monthly index of news attention to regulation. The overall pattern suggests that regulation has attracted increasing media attention in recent years, particularly since the Great Recession. News attention to regulation tends to rise during months marked by major regulatory developments or historical events that prompted massive regulatory responses. For example, the index shows spikes around the Lehman Brothers bankruptcy in 2008, the passage of Obamacare and the Dodd-Frank Act in 2010, and the 2016 and 2020 presidential elections, as well as a substantial drop during the month of the 9/11 attacks in 2001.
The recent increase in media focus on regulation not only suggests that regulatory policy has become an increasingly popular topic among journalists, but also implies that regulation has become more relevant to their audiences, potentially including consumers, workers, and business leaders. This observation further motivates an investigation of the related news content and its implications for the macroeconomy.
4. Measuring regulatory sentiment and regulatory uncertainty
This section starts with a description of the sentiment analysis method we use to estimate the sentiment and uncertainty scores of regulation-related news articles in our corpus. Using the estimated scores, we compute the monthly indexes of regulatory sentiment and regulatory uncertainty from 1985 through 2021. We also present some evidence supporting the validity of these indexes.
4.1 Sentiment analysis
As a popular field of NLP, sentiment analysis is used to extract, quantify, and analyze the semantic orientation of a document, such as customer reviews, social media posts, survey responses, and news articles. In addition to a mere polar view of sentiment (i.e., positive or negative), sentiment analysis methods can be applied to classify other subjective information in source material, such as emotional states (e.g., happiness, fear, and anger), subjectivity, confidence, and uncertainty. We use a lexicon-based approach for sentiment analysis. This approach assesses the semantic orientation of a document based on the frequency of words or phrases with a specific semantic orientation appearing in the document. It relies on predefined dictionaries of opinionated words, such as a list of positive or negative words. There are many available sentiment dictionaries, designed for general purposes and some for specific domains.
We use the 2018 version of the Loughran and McDonald (LM) dictionary (originally developed in Loughran and McDonald (Reference Loughran and McDonald2011)) to assess the sentiment and uncertainty in the regulatory sections of news articles in the baseline analysis. The LM dictionary was specifically constructed for the domain of finance, using a corpus of corporate 10-K reports (Loughran and McDonald, Reference Loughran and McDonald2011). Because of its domain relevance, the LM dictionary has been frequently used in economic research (for example, Fraiberger (Reference Fraiberger2016); Calomiris et al. (Reference Calomiris, Mamaysky and Yang2020); Ostapenko (Reference Ostapenko2020)). The 2018 version of the dictionary comprises sentiment word lists in several categories, including 2,355 words in the negative category, 354 words in the positive category, and 297 words in the uncertainty category.
However, we also notice that the LM positive and negative word lists are highly unbalanced, with substantially more negative words than positive words. One reason is that Loughran and McDonald (Reference Loughran and McDonald2011) focuses on the proportion of negative words in 10-K reports for detecting the association between tone and excess returns. They note that finance and accounting research generally finds little incremental information in positive words, and the LM positive word list was created more for completeness than for “discerning an impact on tone identification” (Loughran and McDonald, Reference Loughran and McDonald2011, p. 45). While an unbalanced dictionary may not affect our interpretation of changes in sentiment over time, it can bias our sentiment assessment toward a disproportionately negative tone. For this reason, we also use two other dictionaries to construct the sentiment measure for comparison: the Harvard General Inquirer (GI) dictionary and the Lexicoder Sentiment Dictionary (LSD). The GI dictionary is a general-purpose lexicon originally developed in the 1960s that has been widely used in various disciplines (Stone et al. Reference Stone, Dunphy, Smith and Ogilvie1966). It covers several broad valence categories, including lists of 2,005 negative words and 1,637 positive words. The LSD is a comprehensive sentiment lexicon that combines three pre-existing dictionaries and tailored primarily to political news (Young and Soroka, Reference Young and Soroka2012).Footnote 5 The LSD comprises 2,857 negative words and 1,709 positive words.
Similar to our search of regulatory noun chunks, we use regular expressions to count occurrences of each sentiment word in the preprocessed regulatory section of an article. We incorporate a negation rule to account for negated positive and negative words. That is, if an English negation word, such as “not,” “don’t,” or “cannot,” occurs within three tokens before an opinionated word, then the opinionated word is assigned the opposite orientation. For example, the following regulatory section contains two occurrences of negative words from the LM dictionary: “hazard” and “violation,” and three occurrences of positive words: “boost,” “fear” (with the negation word “without”), and “boost.”
So, the department’s Occupational Safety and Health Administration in recent years has boosted spending on its consultation program, which allows little companies to ask for an OSHA visit to look for workplace hazards without fear of being cited for violations as a result of that visit. The idea is to boost voluntary compliance with safety regulations. The program’s funding rose 50% between fiscal 1996 and fiscal 2001, to $48.8 million, equal to about 11% of OSHA’s total budget.Footnote 6
We use a standard formula to calculate sentiment scores. The regulatory sentiment score of an article is the difference between the proportion of positive words and the proportion of negative words in the regulatory section of the article. Thus, a positive sentiment score indicates an overall positive tone in news coverage of regulation, and a negative score means an overall negative tone. The example above has a sentiment score of 1.22, suggesting a slightly positive tone toward OSHA’s regulatory consultation program.
We use a similar approach to assess uncertainty in regulation-related news content. The uncertainty category of the LM dictionary covers a broad range of terms beyond “uncertainty” and “uncertain,” such as “ambiguity,” “confusion,” “doubt,” and “vague.” The regulatory uncertainty score of an article is the proportion of uncertainty words in the regulatory section of the article. A higher uncertainty score suggests a higher level of uncertainty expressed in regulation-related news. Below is an example of a regulatory section with a relatively high uncertainty score (7.02). The uncertainty words “confusion,” “preliminary,” “vagueness,” and “confusing” all indicate considerable uncertainty around a regulation banning smoking in restaurants in New York City.
Still, the law has clearly produced confusion. Dr. Hamburg, whose staff has so far issued only preliminary regulations for enforcing the smoking ban, said that final regulations would be published within two weeks, to “clarify some areas of vagueness.” Many restaurant owners said the most confusing part of the law governs smoking in bar areas and gardens.Footnote 7
4.2 Regulatory sentiment and uncertainty indexes
Table 2 shows the descriptive statistics of the sentiment scores estimated with the LM, GI, and LSD dictionaries and the uncertainty scores using the LM dictionary. The absolute sentiment score that measures the polarity of a document is clearly dependent on the scope of opinionated words defined in the dictionary. Unsurprisingly, the sentiment measured using the LM dictionary tends to be more negative compared to the GI and LSD. The LSD produces the most balanced result, with an approximately equal number of articles estimated to be negative and positive. To illustrate how the three dictionaries assess a document differently, Appendix B shows examples of regulatory sections with negative and positive words identified from each dictionary. As shown in Table 2, the uncertainty scores indicate that approximately half of the articles expressed a degree of uncertainty in the sections that discuss regulation. Appendix B also lists the uncertainty words and estimated uncertainty scores for the examples.
Descriptive statistics of estimated sentiment and uncertainty scores

Table 2. Long description
A table with descriptive statistics of estimated sentiment and uncertainty scores. The table has four columns: Sentiment score with LM, GI, LSD, and Uncertainty score with LM. It includes rows for Mean, Std. Dev., Minimum, Maximum, Articles with negative scores, Articles with positive scores, and N. Each row provides values for each column. For example, the Mean row shows LM: -2.06, GI: 1.06, LSD: -0.05, LM: 0.75. The table compares the sentiment scores estimated using different dictionaries and the uncertainty scores using the LM dictionary.
To construct the monthly sentiment and uncertainty indexes, we use a fixed effects regression model following Shapiro et al. (Reference Shapiro, Sudhof and Wilson2022). The specification is:
 \begin{equation} s_j=u_{t(j)}+v_{i(j)}+\epsilon _j , \end{equation}
where
 $s_j$
is the estimated regulatory sentiment or uncertainty score for article
 $j$
,
 $u_{t(j)}$
is a year-month fixed effect, and
 $v_{i(j)}$
is a newspaper fixed effect. The estimated coefficients on the year-month fixed effects
 $u_t$
from Eq. (3) constitute the monthly sentiment or uncertainty index, depending on the dependent variable. One advantage of this approach is that the newspaper fixed effects control for time-invariant heterogeneities across newspapers, which helps address concerns about ideological differences among news sources. This is particularly important for our measures, because news sentiment toward government regulation may be significantly influenced by the political stance of the newspaper.
Monthly index of regulatory sentiment (January 1985–December 2021).
Notes: The figure plots three regulatory sentiment indexes estimated using the LM dictionary, the GI dictionary, and the LSD, respectively, and the first principal component of the three indexes. All indexes are normalized to have mean equal to zero and standard deviation equal to one.

Figure 2. Long description
A line graph titled Monthly index of regulatory sentiment (January 1985-December 2021). The horizontal axis represents the years from 1985 to 2021, and the vertical axis represents the standardized regulatory sentiment index ranging from -6 to 6. The graph includes four lines representing different sentiment indexes: LM Sentiment Index, GI Sentiment Index, LSD Sentiment Index, and the First Principal Component. Key events such as the Savings and Loan Crisis, Clinton Health Care Plan, 9/11, Lehman Brothers, Obamacare, Deepwater Horizon Oil Spill, Libor Scandal, Dodd-Frank, Bush Midterm Election, 2016 Presidential Election, 2020 Presidential Election, Coronavirus Outbreak, and COVID-19 Vaccine are annotated on the graph. The lines show fluctuations in regulatory sentiment over time, with notable peaks and troughs corresponding to these events.
Figure 2 plots the regulatory sentiment indexes estimated using different dictionaries between January 1985 and December 2021. To focus on changes over time rather than absolute differences in polarity across indexes, we normalize the indexes by their means and standard deviations. The three time series demonstrate similar patterns over time and are strongly correlated with one another. The correlation between the LM and LSD indexes is 0.81; the correlation between the LM and GI indexes is 0.58; and the correlation between the LSD and GI indexes is 0.73. We also plot the first principal component of the three standardized sentiment indexes in Figure 2, which explains 81% of the variance. All three indexes and the principal component suggest that regulatory sentiment has changed over time. For example, newspapers in the late 1980s and early 1990s appear to have adopted a relatively negative tone when discussing regulation, while sentiment became more positive around the mid-1990s and remained stable and higher until the early 2000s. In the following impulse response estimates, we present the results using the LM sentiment index but also include results based on the GI and LSD indexes and the principal component to demonstrate robustness.
Monthly index of regulatory uncertainty (January 1985–December 2021).
Notes: The figure plots the regulatory uncertainty index estimated using the uncertainty category of the LM dictionary.

Figure 3 plots the regulatory uncertainty index. Notably, we see more frequent spikes in regulatory uncertainty during recent years. The index elevated during the Great Recession and reached its historical peak in 2010, a year marked by several important events in the regulatory history, including the enactment of Obamacare in March, the Deepwater Horizon oil spill in April, and the passage of the Dodd-Frank Act in July. Since then, regulatory uncertainty has remained at a relatively high level, suggesting a potential structural break around the 2010 peak. Other large spikes occurred around the Lehman Brothers bankruptcy in September 2008, the election of Donald Trump in November 2016, and the onset of the COVID-19 pandemic in the U.S. in April 2020.
4.3 Validation
Since there are no established measures that capture regulatory sentiment or uncertainty as defined in our study, it is not feasible to validate our measures based on any “gold standard.” However, we assess the validity of our measures indirectly in several ways.
First, we examine the news articles with extreme sentiment or uncertainty estimates. Appendix C lists ten articles with the lowest sentiment scores, ten articles with the highest sentiment scores, and ten articles with the highest uncertainty scores. Many articles with negative sentiment discuss firms’ violations of certain regulations, while articles with positive sentiment praise the effectiveness of some regulations or reflect positive expectations for regulatory changes. Articles with high uncertainty generally comment on confusion about existing regulations or uncertainty about future regulatory actions. Although these examples do not capture the whole picture, a human review of these articles suggests that the measures are consistent with qualitative interpretations of regulatory sentiment and uncertainty. That is, the measures capture shifts in sentiment or uncertainty around the regulatory environment, which may be driven by a broad range of regulation-related events such as the promulgation of a new regulation, a company’s regulatory compliance or violation, a regulatory investigation, and a lawsuit challenging agency regulatory actions.
Second, to verify that our measures indeed capture relevant regulatory events, we study the word clouds of articles published during months associated with regulatory sentiment or uncertainty shocks. As shown in Appendix D, the word cloud for each month displays common noun chunks found in the regulatory sections from that month, which can be used to extrapolate the major events that caused the regulatory sentiment or uncertainty shock. For example, the increase in regulatory sentiment in November 2016 largely reflected optimism about the incoming Trump administration’s movements on financial regulation; the controversy around the London Inter-bank Offered Rate (LIBOR) in July 2012 caused a substantial decrease in regulatory sentiment; in September 2008, it was announced that Fannie Mae and Freddie Mac were being placed under the direct supervision of the federal government, which triggered an increase in regulatory uncertainty; in April 2020, the coronavirus outbreak was associated with another spike in regulatory uncertainty. The word clouds illustrate key terms that align with the possible events associated with large regulatory sentiment or uncertainty fluctuations highlighted in Figures 2 and 3.
Third, we compare our measures with several related sentiment and uncertainty measures. Appendix E.1 plots our regulatory sentiment index with the economic sentiment index of Shapiro et al. (Reference Shapiro, Sudhof and Wilson2022). The correlation between the regulatory sentiment index and economic sentiment index is 0.29 and statistically significant. While the two time series comove in some time periods, they do not always coincide with each other. For example, during the early 1990s recession, both economic sentiment and regulatory sentiment declined substantially. During the 2007–2008 financial crisis, however, regulatory sentiment did not decline as sharply as economic sentiment. Also, regulatory sentiment seems to react more strongly to political events such as the Clinton health care reform and 2016 presidential election.
Appendices E.2 and E.3 plot our regulatory uncertainty index alongside the aggregate EPU index and the categorical EPU index on regulation from Baker et al. (Reference Baker, Bloom and Davis2016). The regulatory uncertainty index has a statistically significant correlation of 0.34 with the aggregate EPU index and 0.43 with the regulatory EPU index. Although the correlations between regulatory uncertainty and EPU measures are only moderate, the measures demonstrate several spikes around the same time periods, such as those around Black Monday, the Lehman Brothers bankruptcy, the 2016 presidential election, and the coronavirus outbreak. Nevertheless, these measures also capture some different historical events. For example, EPU surged during the first and second Gulf wars, the 9/11 attacks, and the debt ceiling dispute in 2011, whereas regulatory uncertainty remained relatively stable during these periods. Instead, a large increase in regulatory uncertainty occurred during January–April 2010, coinciding with the enactment of Obamacare and the Deepwater Horizon oil spill.
The comparisons suggest both similarities and differences between our regulatory measures and other sentiment or uncertainty metrics. The differences likely arise from the fact that they capture different types of perceptions. The economic sentiment measure tracks news sentiment about economic conditions which may or may not concern government regulation. The aggregate EPU index measures economic uncertainty induced by a broad range of policy issues, including regulatory, trade, fiscal, and monetary policies. The regulatory EPU index is more closely linked to our regulatory uncertainty measure because of the same focus on regulation. Still, the regulatory EPU index puts a particular emphasis on financial regulation given how Baker et al. (Reference Baker, Bloom and Davis2016) identify regulation-specific text, while our measures reflect a broader definition of regulation and a wider range of regulatory issues. It is not surprising that our measures did not spike during historical events less related to regulation, such as the Gulf wars, but rather exhibited stronger responses to regulatory developments in healthcare and the environment. These comparisons suggest that our regulatory sentiment and uncertainty measures, while sharing some overlapping information with other economic sentiment or policy uncertainty measures, contain unique information about regulation and potentially different economic implications.
5. Macroeconomic implications of regulatory sentiment and uncertainty
The newly developed measures of regulatory sentiment and regulatory uncertainty can be used in various economic analyses. In this section, we apply them to studying macroeconomic implications of regulatory sentiment and uncertainty by examining impulse responses of macroeconomic variables. We discuss a baseline analysis and a series of robustness checks.
5.1 Impulse responses
For the baseline analysis, we use the local projection method of Jordà (Reference Jordà2005) to estimate the impulse responses of aggregate output and employment to a regulatory sentiment or uncertainty shock.Footnote 8 Local projections rely on single-equation methods which do not require specifying the full multivariate system and provide intuitive regression interpretation (Jordà and Taylor, Reference Jordà and Taylor2025). This method has been widely used for estimating impulse response functions in the context of text-based sentiment and uncertainty measures (Ahir et al. Reference Ahir, Bloom and Furceri2022; Caldara et al. Reference Caldara, Iacoviello, Molligo, Prestipino and Raffo2020; Shapiro et al. Reference Shapiro, Sudhof and Wilson2022).
The estimation entails a distinct linear regression for each forecast horizon
 $h$
with the following specification:
 \begin{equation} y_{i,t+h}=\alpha _i^h+\beta _i^{h}reg_t+\sum _{\tau =1}^{3}\gamma _{i,\tau }^{h}reg_{t-\tau }+\sum _{\tau =0}^{3}\theta _{i,\tau }^{h}Y_{t-\tau }+\varepsilon _{i,t+h}, \end{equation}
where
 $y_i$
is log industrial production or log employment,
 $reg$
is the regulatory sentiment or regulatory uncertainty index, the matrix
 $Y$
includes contemporaneous and lagged values of economic variables including log S&P 500, the federal funds rate, log employment, and log industrial production,
 $\beta _i^{h}$
and
 $\gamma _{i,\tau }^{h}$
are the estimated coefficients on the contemporaneous and lagged regulatory index, respectively,
 $\theta _{i,\tau }^{h}$
are the estimated coefficients on the contemporaneous and lagged control variables in
 $Y$
, and
 $\varepsilon _{i,t+h}$
is the error term.Footnote
9
Based on multiple information criteria, we choose three lags of the variables.Footnote
10
The impulse response from a shock to regulatory sentiment or uncertainty on economic variable
 $y_i$
is given by the estimates of
 $\beta _i^{h}$
. We consider horizons ranging up to 12 months after the shock (
 $h=\{0,1,\ldots ,12\}$
).Footnote
11
The baseline specification includes both contemporaneous and lagged controls to ensure that the regulatory shock is conditionally exogenous given the information available at time
 $t$
(Jordà, Reference Jordà2023). Consistent with recent guidance in the local projection literature, we control for variables central to the identification strategy, the outcome and impulse variables, and additional macroeconomic variables that strongly predict either the outcome or the regulatory measures (Montiel Olea et al. Reference Montiel Olea, Plagborg-Moller, Qian and Wolf2025). This approach corresponds to a recursive identification in which the regulatory measure is ordered last (Jordà and Mertens, Reference Jordà and Mertens2023). Accordingly, the resulting impulse responses should be interpreted as responses conditional on current macroeconomic conditions.
Impulse responses.
Notes: The figures plot impulse response functions for industrial production and employment to: (a) a one-standard-deviation negative shock to regulatory sentiment, and (b) a one-standard-deviation upward shock to regulatory uncertainty. The regulatory sentiment index is estimated using the LM dictionary. The impulse response functions are estimated from local projections using monthly data from January 1985 through December 2021. Shaded areas show 90% (light gray) and 95% (dark gray) confidence bands.

Figure 4. Long description
The image contains four line graphs showing impulse responses to regulatory sentiment and uncertainty shocks. Panel A: Impulse Responses to a Regulatory Sentiment Shock. The top-left graph shows the industrial production response. The x-axis represents months from 0 to 12, and the y-axis represents the industrial production response in percent, ranging from -1.0 to 0.2. The graph shows statistically significant declines in industrial production after the shock. The top-right graph shows the employment response. The x-axis represents months from 0 to 12, and the y-axis represents the employment response in percent, ranging from -1.0 to 0.2. The graph shows statistically significant declines in employment after the shock. Panel B: Impulse Responses to a Regulatory Uncertainty Shock. The bottom-left graph shows the industrial production response. The x-axis represents months from 0 to 12, and the y-axis represents the industrial production response in percent, ranging from -1.0 to 0.2. The graph shows statistically insignificant changes in industrial production after the shock. The bottom-right graph shows the employment response. The x-axis represents months from 0 to 12, and the y-axis represents the employment response in percent, ranging from -1.0 to 0.2. The graph shows statistically insignificant changes in employment after the shock. Shaded areas in all graphs represent 90% (light gray) and 95% (dark gray) confidence bands.
Figure 4 presents the impulse responses estimated from local projections. Panel (a) plots the impulse responses of industrial production and employment to a one-standard-deviation negative shock to the regulatory sentiment index, with point estimates and 90% and 95% confidence bands. The estimates show that a negative sentiment shock is associated with declines in industrial production and employment. The responses of industrial production are statistically significant at the 5% level beginning six months after the shock and gradually rise up to a 0.61% drop by the 12th month following the shock. The shock is also associated with a statistically significant reduction in employment starting eight months after the shock, with a maximum estimated drop of 0.28%. These baseline results are based on the LM-based regulatory sentiment index. Using the alternative sentiment indexes (i.e., the GI-based index, the LSD-based index, and the first principal component), we obtain similar impulse responses, as shown in Appendix F.
Panel (b) of Figure 4 shows the impulse responses to an upward regulatory uncertainty shock. The estimated responses associated with a one-standard-deviation increase in regulatory uncertainty are not statistically significant at the 5% or 10% level. This result differs from Baker et al. (Reference Baker, Bloom and Davis2016)’s findings on their EPU index, which suggest that an upward EPU shock leads to statistically significant declines in industrial production and employment. This difference confirms that our regulatory uncertainty measure captures a different type of uncertainty than the EPU index, as discussed in Section 4.3. Uncertainty specific to regulatory policy is likely to affect firm behavior and thus the macroeconomy in distinct ways compared to other types of policy. One possibility is that, since regulations typically go through prolonged notice-and-comment processes before being finalized, regulatory uncertainty may reflect fewer unanticipated changes in future policies and instead indicate greater confusion, ambiguity, and imprecision in the interpretation and implementation of promulgated regulations. To further compare regulatory uncertainty with EPU and check the robustness of the baseline results, we re-estimate impulse response functions using vector autoregressions (VARs) in Section 5.2.1.Footnote 12
To summarize the baseline results, the impulse response estimates suggest that regulatory sentiment has a larger and more robust relationship with aggregate economic activity than regulatory uncertainty. A decline in regulatory sentiment is associated with statistically significant, persistent drops in future output and employment, whereas an increase in regulatory uncertainty is not associated with statistically significant responses in output or employment.
5.2 Robustness and extensions
5.2.1 VAR-estimated impulse responses
As a robustness exercise, we estimate impulse responses using a VAR identified via a recursive (Cholesky) ordering. In our main VAR specification, we follow the monthly VAR model of Baker et al. (Reference Baker, Bloom and Davis2016) and order the regulatory measure first, allowing it to affect macroeconomic variables contemporaneously. Specifically, the VAR uses the following ordering of variables: the regulatory sentiment or uncertainty index, the log S&P 500 index, the federal funds rate, log employment, and log industrial production. The VAR includes three lags of all variables, and we report impulse responses for up to 36 months after the shock. We also estimate an alternative VAR that reverses the ordering of the variables, which corresponds more closely to the recursive interpretation of our baseline local projection specification. We therefore view the VAR analysis as a robustness exercise that assesses the sensitivity of the results to alternative implementations of recursive identification rather than as an alternative baseline specification.
Appendix H.1 plots the impulse response functions estimated from our main VAR specification. A regulatory sentiment shock is associated with statistically significant, persistent reductions in both industrial production and employment. There are also statistically significant declines in industrial production and employment following an increase in regulatory uncertainty, although these responses wane quickly after one period, suggesting that they are at most transitory. Overall, the impulse responses estimated from the VAR are largely consistent with those from the baseline local projections. Any differences in the impulse responses reflect differences in the identifying restrictions imposed by the two specifications and, where those restrictions are comparable, the distinct finite-sample properties of the VAR and local projection estimators (Plagborg-Møller and Wolf, Reference Plagborg-Møller and Wolf2021).
Results remain unchanged when we make several modifications to the VAR specification following Baker et al. (Reference Baker, Bloom and Davis2016). These include reversing the ordering of variables in the VAR, a bivariate VAR, a bivariate VAR with reverse ordering, dropping the S&P index, including the VIX, and adding time trends. As shown in Appendix H.2, the impulse response patterns remain very similar to the baseline estimates, particularly for a regulatory sentiment shock.
As Plagborg-Møller and Wolf (Reference Plagborg-Møller and Wolf2021) discuss, local projections and VARs asymptotically estimate the same impulse responses, provided that the lag length used for estimation tends to infinity. However, the two methods can disagree substantially at intermediate and long horizons (i.e., exceeding the lag length used for estimation), where local projection estimators exhibit lower bias than VAR estimators but substantially higher variance (Li et al. Reference Li, Plagborg-Møller and Wolf2024; Plagborg-Møller and Wolf, Reference Plagborg-Møller and Wolf2021). Therefore, in Appendix I, we plot the impulse responses from local projections up to 36 horizons to examine whether this bias-variance trade-off affects our results. As shown, the impulse response estimation at a longer horizon suggests persistent responses associated with a regulatory sentiment shock and statistically insignificant responses associated with a regulatory uncertainty shock, consistent with the conclusions drawn from the baseline and VAR results.
5.2.2 General economic sentiment and policy uncertainty
While we show in Section 4.3 that there are variations between our regulatory measures and general economic sentiment or policy uncertainty measures, it is still possible that the estimated responses to regulatory sentiment or uncertainty shocks are picking up information about effects of general economic sentiment or policy uncertainty embedded in the news. To investigate this issue further, we add measures of economic sentiment and uncertainty to the matrix
 $Y$
in Eq. (4), including the Michigan Consumer Sentiment Index, the news-based economic sentiment index of Shapiro et al. (Reference Shapiro, Sudhof and Wilson2022), the VIX, and the EPU index of Baker et al. (Reference Baker, Bloom and Davis2016). As shown in Appendix J, the impulse response estimates are nearly unaffected after controlling for any of these measures. In particular, the robustness of the estimates bolsters our findings regarding the relationship between regulatory sentiment and macroeconomic outcomes, suggesting that our measure of regulatory sentiment captures at least some unique information about economic activity that is not reflected in general economic sentiment or policy uncertainty.
5.2.3 Interactions between regulatory sentiment and uncertainty
Given that sentiment and uncertainty are sometimes viewed as related concepts, it is possible that the effects of regulatory sentiment and uncertainty shocks are conditional on each other. Leveraging the flexibility of the local projection method, we extend the linear model to account for potential interactions between regulatory sentiment and regulatory uncertainty. We estimate impulse response functions to examine whether the responses to a regulatory sentiment (uncertainty) shock are different when regulatory uncertainty (sentiment) is particularly high or low. For each forecast horizon
 $h$
, we run the following regression:
 \begin{equation} y_{i,t+h}=a_i^h+\sum _{\tau =0}^{3}{\beta _{i,\tau }^{h}}{X_{t-\tau }}+\sum _{\tau =0}^{3}{\gamma _{i,\tau }^{h}}({sent_{t-\tau }}\times {unc_{t-\tau }})+u_{i,t+h}, \end{equation}
where
 ${sent_{t}}\times {unc_{t}}$
is an interaction term of regulatory sentiment and regulatory uncertainty, the matrix
 $X$
includes the contemporaneous and lagged values of regulatory sentiment, regulatory uncertainty, and the same set of economic variables included in the baseline Eq. (4),
 $\beta _{i,\tau }^{h}$
are the estimated coefficients on the contemporaneous and lagged regressors in
 $X$
,
 $\gamma _{i,\tau }^{h}$
are the estimated coefficients on the contemporaneous and lagged interaction term, and
 $u_{i,t+h}$
is the error term.
Panel (a) of Appendix K plots the impulse responses to a regulatory sentiment shock conditional on different levels of regulatory uncertainty. Specifically, we compare impulse responses originating from levels of regulatory uncertainty at one standard deviation above and below its mean. There are some signals suggesting that the estimated responses to regulatory sentiment shocks vary with the level of regulatory uncertainty: the estimated declines in industrial production and employment after a regulatory sentiment shock tend to be larger when regulatory uncertainty is high. However, the impulse response functions exhibit similar overall trajectories under high and low uncertainty, and the differences are not statistically significant. Therefore, the results do not provide strong evidence that the relationship between regulatory sentiment shocks and macroeconomic outcomes depends on the level of regulatory uncertainty. Similar results are observed for impulse responses to regulatory uncertainty shocks when regulatory sentiment is high versus low (Panel (b) of Appendix K).
5.2.4 Regulation or deregulation
When we generate our initial news corpus, we search for articles that contain terms starting with “regulat” or “deregulat.” One potential concern is that the economic impact of sentiment or uncertainty about regulation that imposes restrictions may be different from that of sentiment or uncertainty about deregulation (i.e., the reduction or elimination of regulations). To investigate whether that influences our results, we remove articles that contain “deregulat” and re-run the analyses. Among the 608,172 articles covered in the baseline analysis, 31,265 articles contain terms starting with “deregulat.” The revised regulatory sentiment and uncertainty indexes based on the remaining 576,907 articles are highly correlated with the baseline indexes, with both correlations exceeding 0.97.
Appendix L shows the impulse responses to a regulatory sentiment or uncertainty shock using the revised indexes. Compared to the baseline estimates, the output and employment responses to a regulatory sentiment or uncertainty shock remain nearly unchanged. This robustness check is only to show that removing news content potentially associated with deregulation does not change our results substantially. Further analysis is needed to examine whether and how the effects of perceptions about regulation and deregulation differ, but this is beyond the scope of this paper.
5.2.5 Variance decomposition
Another interesting question is how much these regulatory shocks contribute to fluctuations in aggregate economic outcomes. To explore this, we estimate the forecast error variance decomposition (FEVD) from a regulatory sentiment shock and a regulatory uncertainty shock, respectively, using both the local projection and VAR models.Footnote
13
Appendix M plots the FEVDs for industrial production and employment. Using the
 $R^2$
method with a VAR-based bootstrap from Gorodnichenko and Lee (Reference Gorodnichenko and Lee2020), the local projection-based FEVDs suggest that a regulatory sentiment shock explains up to 4.6% of the forecast error variance of output and 4% of the forecast error variance of employment over a 12-month horizon, while a regulatory uncertainty shock explains at most 1% of the corresponding forecast error variance (Appendix M.1).Footnote
14
The VAR-based FEVDs also suggest similar results (Appendix M.2).
Taken together with the main analysis, these results indicate that regulatory sentiment shocks not only are associated with larger and more statistically significant responses in aggregate output and employment but also appear to be more important determinants of fluctuations in these variables than regulatory uncertainty shocks.
6. Sentiment and uncertainty by regulatory policy area
While the application of our regulatory sentiment and uncertainty indexes suggests some interesting macroeconomic implications, these measures capture information in the news about regulation in general. However, regulation is diverse, spanning various policy areas and segments of the economy. To discover how regulatory sentiment and uncertainty vary across policy areas and how they connect to economic activity, we build categorical indexes of regulatory sentiment and uncertainty for 14 policy areas. This section presents the indexes and their corresponding impulse response estimates.
6.1 Categorizing news articles
To categorize relevant news content by regulatory area, we use the dictionary of regulatory noun chunks described in Section 3.1. Specifically, we leverage the fact that these regulatory noun chunks originate from rule titles and that rules are issued by agencies with domain-specific regulatory authorities. For example, the Environmental Protection Agency primarily issues environmental regulations, the Food and Drug Administration issues regulations to protect food safety and health, and the Commodity Futures Trading Commission regulates segments of the financial market. Therefore, we categorize agencies by regulatory area according to their jurisdictions and assume that the noun chunks extracted from rules issued by a given agency correspond to that agency’s regulatory area.
We define 14 regulatory areas for classifying the agencies in our sample, including the following: consumer safety and health; national and homeland security; transportation; labor and workplace; environment and natural resources; energy; finance and banking; general business and trade; agriculture and rural development; education and culture; communications; criminal justice; housing, urban development, and social security; and international relations. Appendix N provides examples of agencies, their designated regulatory areas, and associated rule titles. After linking regulatory noun chunks back to their respective agencies, the vast majority of the noun chunks (8,750 out of 10,458) in our dictionary are assigned to a single regulatory area, while a small portion of noun chunks appear in rules issued by multiple agencies and thus correspond to multiple regulatory areas (e.g., “final rule,” “administrative requirement,” and “technical amendment”). We use only the area-specific noun chunks (i.e., terms associated with a single regulatory area) for classifying the news articles.
To verify the relevance of these noun chunks, we conduct human auditing on the area-specific noun chunks. Among the regulatory noun chunks associated with each regulatory area, we manually review the 100 most frequently occurring noun chunks in our regulation-related corpus to remove or correct their assigned areas. For example, the terms “federal law,” “public hearing,” and “government agency” were originally linked to the area of consumer safety and health before human auditing, because they appeared only in rule titles related to this area. However, since these terms do not contain information specific to consumer safety and health, they are excluded from classification. Following this auditing process, the dictionary is refined to include 8,293 area-specific noun chunks.
Since the regulatory section of a news article in our corpus typically contains one or more of the noun chunks, articles are classified into regulatory areas based on the presence of area-specific noun chunks. The following is an example of a regulatory section:
Automobile manufacturers are financing a multimillion dollar lobbying campaign aimed at persuading state legislatures to require motorists to buckle up their seat belts, a move designed to kill a federal regulation requiring the industry to equip vehicles with more expensive air bags by 1989. Last year, legislatures in New York, New Jersey and Illinois adopted mandatory seat belt laws and legislation already has been filed on Beacon Hill to bring about the same end.Footnote 15
This regulatory section contains four regulatory noun chunks: “seat belt,” “federal regulation,” “air bag,” and “seat belt” (with “seat belt” occurring twice). Among these terms, “federal regulation” is a general phrase used in rule titles and is therefore excluded from classification. In contrast, “seat belt” and “air bag” are noun chunks uniquely associated with the area of transportation in our dictionary, allowing the article to be classified in this category.
In longer regulatory sections, news articles often contain multiple regulatory noun chunks corresponding to different regulatory areas. To address this, we define the dominant area of an article as the most common area across all the area-specific noun chunks in the regulatory section. This approach intends to capture the primary regulatory focus of the relevant content in a news article. Mathematically, suppose there are
 $n$
occurrences of area-specific noun chunks in the regulatory section (duplicated noun chunks are counted multiple times), and
 $\mathbf{a}_{m\times 1}^{p}$
denotes an
 $m\times 1$
vector for the
 $p$
th occurrence of noun chunks, where the
 $q$
th element of the vector
 $a_{q}^{p}=1$
if the
 $p$
th noun chunk is associated with the
 $q$
th area (
 $q=\left \{1,2,\ldots ,m\right \}$
), and otherwise
 $a_{q}^{p}=0$
. We sum these vectors across all noun chunks:
 \begin{equation} \sum _{p=1}^{n}\mathbf{a}_{m\times 1}^{p}=\mathbf{b}_{m\times 1}. \end{equation}
Then the dominant area is
 $q_{max}$
such that
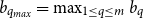 $b_{q_{max}}=\max _{1\leq q \leq m} b_q$
. In some cases, an article may have multiple dominant areas.
Following this classification process, 305,367 articles are classified into one or more regulatory areas. Appendix O shows word clouds of the top 50 area-specific noun chunks for each area. Appendix P plots article counts by area, showing that finance and banking is the regulatory area that has drawn the most news attention, followed by environment and natural resources, consumer safety and health, and general business and trade.
6.2 Categorical indexes
We use the same approach to construct the categorical indexes as we do for the aggregate regulatory sentiment and uncertainty indexes. Namely, for a given regulatory area, we create the indexes by fitting a fixed effects regression to the estimated sentiment or uncertainty scores of the articles classified into the area. The specification is:
 \begin{equation} s_{j, q}=u_{t(j, q)}+v_{i(j, q)}+\epsilon _{j, q} , \end{equation}
where
 $s_{j, q}$
is the estimated sentiment or uncertainty score for article
 $j$
in area
 $q$
,
 $u_{t(j, q)}$
is a year-month fixed effect, and
 $v_{i(j, q)}$
is a newspaper fixed effect. The estimated coefficients on the year-month fixed effects
 $u_{t(j, q)}$
from the regression form the monthly sentiment or uncertainty index for regulatory area
 $q$
.
Appendix Q plots the categorical sentiment and uncertainty indexes over time, including their 12-month rolling means highlighting general patterns over time. There are substantial variations in the measured sentiment and uncertainty across different regulatory areas. For example, sentiment toward environment and natural resources regulation largely improved from the late 1980s through the 1990s, a decade with many significant changes in environmental regulations such as the passage of the 1990 Clean Air Act amendments.
Regulatory sentiment and uncertainty around finance and banking regulation (January 1985–December 2021).
Notes: The figures plot the LM-based regulatory sentiment index (panel (a)) and regulatory uncertainty index (panel (b)) for finance and banking regulation. Dashed red lines show 12-month rolling means.

Taking finance and banking as a case study, Figure 5 shows how sentiment and uncertainty around finance and banking regulation evolved over time and fluctuated around relevant financial and economic events. Several dips in sentiment around finance and banking regulation are notable during this time period. The biggest dip occurred in the late 80s and early 90s, coinciding with the savings and loan crisis. Sentiment also declined during periods linked to Fannie Mae’s violation of accounting rules in 2004, the bankruptcy of MF Global in 2011, the LIBOR scandal in 2012, and the coronavirus outbreak in 2020. Interestingly, regulatory sentiment toward finance and banking did not decline significantly during the 2007–08 financial crisis. In contrast, regulatory uncertainty rose sharply starting the financial crisis and reached a peak in 2010, as the Dodd-Frank Act was passed in response to the crisis. These contrasting patterns suggest that our measures do not capture perceptions of the market but rather the regulatory environment concerning the market.
Although uncertainty is usually perceived negatively, comparing the two measures indicates that higher uncertainty is not always accompanied by more negative sentiment. This is also manifested in our aggregate measures. A prominent example is the 2016 presidential election, which coincided with a spike in both regulatory sentiment and uncertainty. These changes are likely to reflect positive yet uncertain prospects for curbs on Dodd-Frank financial regulations, as asserted during Trump’s presidential campaign.
6.3 Impulse responses
We estimate impulse responses to a regulatory sentiment or uncertainty shock for each regulatory area by replacing the aggregate index with a categorical index in Eq. (4). The analysis suggests a particularly strong linkage between sentiment and uncertainty in certain regulatory areas and economic activity.
Impulse responses for selected regulatory areas.
Notes: The figures plot impulse responses for selected regulatory areas. For all areas, refer to Appendix R. The regulatory sentiment indexes are estimated using the LM dictionary. The impulse response functions are estimated from local projections using monthly data from January 1985 through December 2021. Shaded areas show 90% (light gray) and 95% (dark gray) confidence bands.

Figure 6 shows the impulse responses for selected regulatory areas, and the figures for all areas are available in Appendix R. Negative regulatory sentiment shocks related to consumer safety and health and transportation are associated with statistically significant reductions in future output. The responses to a transportation-related regulatory sentiment shock are particularly large and persistent, with an estimated drop of 0.6% in output at the 12th month after a one-standard-deviation shock. As illustrated in the word clouds in Appendix O, major regulatory issues covered by the news content on transportation regulation include traffic speeds, airbag requirements, interstate commerce, electric vehicles, and traffic safety. The news content concerning consumer safety and health regulation discusses issues such as public health, the Food and Drug Administration, child care, and new drugs. By contrast, the impulse responses of employment to sentiment shocks in these areas are relatively nuanced: the response to a sentiment shock around consumer safety and health regulation is significant only over a transitory period, and the response to a sentiment shock around transportation regulation is not statistically significant. The estimated responses to a sentiment shock related to finance and banking regulation are not statistically significant for output and are only marginally significant for employment.
While we do not observe statistically significant responses to an aggregate regulatory uncertainty shock (as discussed in Section 5.1), uncertainty shocks about energy regulation and business and trade regulation appear to have a stronger linkage with economic outcomes. As shown in Panel (c) of Figure 6, increased regulatory uncertainty around general business and trade is associated with a statistically significant reduction in future output, and this response is large and persistent. News on regulatory issues in general business and trade focuses on initial public offerings, self-regulation, and startups. A relatively transitory drop in output follows an uncertainty shock around energy regulation. Energy-related regulatory issues are relatively dispersed, with nuclear power and crude oil drawing a substantial amount of news attention. Similar to regulatory sentiment, the employment responses to regulatory uncertainty shocks in these areas are less prominent (Panel (d)).
Similar to the analysis for aggregate measures, we test the robustness of the impulse response functions using an alternative VAR model from Baker et al. (Reference Baker, Bloom and Davis2016). Although we observe some significant responses associated with regulatory sentiment shocks around national and homeland security, environmental and natural resources, and criminal justice using local projections, those responses are not robust when applying the VAR model for estimation. This may be partially due to the limited number of articles in some areas. Therefore, we do not draw conclusions about those areas.
Overall, we find that economic outcomes, particularly aggregate output, are more sensitive to changes in sentiment related to consumer safety and health regulation and transportation regulation as well as uncertainty around energy regulation and business and trade regulation, compared to other regulatory areas.
While sentiment and uncertainty related to many regulatory areas do not exhibit statistically significant relationships with aggregate economic outcomes, this does not imply that they have no economic impact. Instead, regulations in specific domains may exert stronger effects at the sectoral level. For example, Ma and Xie (Reference Ma and Xie2025) find that increased regulatory uncertainty related to oil and gas production reduces both oil output and drilling activity, while Gavriilidis (Reference Gavriilidis2021) shows that climate policy uncertainty negatively affects
 $\textrm {CO}_{2}$
emissions. The categorical indexes developed in this study provide a useful tool for examining how public perceptions in particular regulatory areas influence sector-specific economic outcomes. We leave such inquiries to future research.
7. Conclusion
In this study, we measure how regulatory sentiment and regulatory uncertainty expressed in the news have changed over time and examine their relationship with aggregate economic activity. We identify an original corpus of regulation-related news from seven leading U.S. newspapers, which shows that news attention to regulation has been increasing since the Great Recession. We then employ lexicon-based sentiment analysis of the relevant news text to construct monthly indexes of regulatory sentiment and regulatory uncertainty from 1985 to 2021.
Our regulatory measures capture public perceptions of the current and future regulatory environment. Text analysis suggests that these perceptions are affected not only by the addition or reduction of regulations but also by a broad range of regulation-related events at both the macro and micro levels, such as a presidential transition, the passage of an influential bill, a large company’s regulatory compliance or violation, and an important regulatory investigation. Shifts in regulatory sentiment or uncertainty, such as shocks to the regulatory environment that trigger negative perceptions or higher uncertainty, can affect aggregate economic outcomes.
We apply the news-based measures of regulatory sentiment and regulatory uncertainty to studying their macroeconomic implications. Using local projections, we estimate the impulse responses of aggregate output and employment associated with regulatory sentiment and uncertainty shocks. The impulse response functions suggest that a negative regulatory sentiment shock is associated with large, persistent drops in future output and employment, while the responses to a regulatory uncertainty shock overall are statistically insignificant or transitory. The impulse response estimates are robust to various modifications of the empirical model and data. In particular, the estimated responses to regulatory sentiment shocks largely remain after controlling for existing measures of general economic sentiment and policy uncertainty, suggesting that our measure of regulatory sentiment captures some unique information about the economy. Additionally, these estimated responses do not vary systematically with the degree of regulatory uncertainty present in the economy.
To further explore which types of regulatory policy drive the connection between regulation and macroeconomic outcomes, we construct categorical indexes of sentiment and uncertainty for 14 regulatory policy areas. The impulse response estimates suggest that negative regulatory sentiment shocks related to consumer safety and health and transportation are associated with particularly persistent, large drops in future output. Despite the lack of evidence for persistent responses to aggregate regulatory uncertainty shocks in our analysis, aggregate output appears to be more sensitive to increased uncertainty around business and trade regulation and energy regulation than in the other areas.
While this study highlights the adverse macroeconomic responses associated with negative perceptions and elevated uncertainty surrounding regulatory changes, it is important to acknowledge the societal benefits that regulation can provide. The societal benefits of regulation, such as reducing pollution and ensuring safe products and workplaces, are not formally considered in this study. In some circumstances, negative reactions from stakeholders or a certain degree of uncertainty may be inevitable in order to achieve the intended social objectives of regulation. Future research could aim to quantify the trade-offs between the potential economic costs associated with negative regulatory sentiment or elevated regulatory uncertainty and the societal benefits that regulations are designed to produce.
Building on our findings, future research could further investigate the mechanisms through which regulatory sentiment influences macroeconomic outcomes, as our analysis suggests it may play a more important role than regulatory uncertainty. In addition, sentiment and uncertainty related to specific regulatory areas may have larger effects on particular sectors than on the aggregate economy. Our categorical indexes can be used to explore these heterogeneous effects at the sector, industry, or firm level. The text-based methodology developed in this study could also be adapted to construct industry- or topic-specific regulatory measures.
Supplementary material
The supplementary material for this article can be found at https://doi.org/10.1017/S1365100526101394.
Acknowledgements
The authors gratefully acknowledge the GW Regulatory Studies Center for support for this project and ProQuest for providing access to TDM Studio. The authors thank Steve Balla, Leah Brooks, Bentley Coffey, Bridget Dooling, Susan Dudley, Jerry Ellig, Federico M. Ferrara, Xiaohan Ma, Brian Mannix, Roberto Samaniego, Arthur Turrell, and Simon van Norden for their insightful comments and suggestions. The authors are also grateful to the participants at the 2020 Banca d’Italia and Federal Reserve Board Joint Conference, the Southern Economic Association 90th and 91st Annual Meetings, the GW H. O. Stekler Research Program on Forecasting seminar, the 2021 Federal Forecasters Conference, the 2021 ESCoE Conference on Economic Measurement, the Pennsylvania State University Macro Seminar, and the 2022 Conference on Real-Time Data Analysis, Methods, and Applications for their helpful comments. John Bertino and Neha Mathur provided excellent research assistance. Disclaimer: The views expressed herein are the authors’ own and do not necessarily reflect the views of any employer or other entity with which they may be associated.


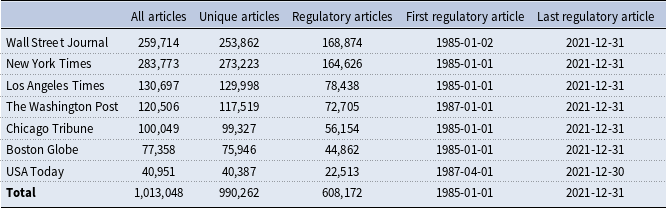

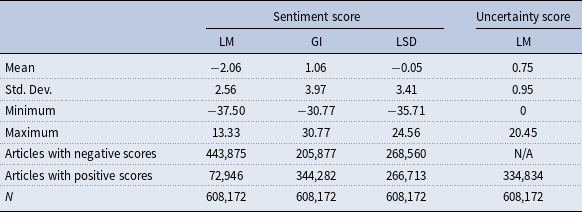


 Open access

