


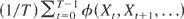
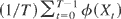
1. MOTIVATION
In the analysis of nonlinear, and also linear, time series models for processes (Xt,t ≥ 0) it is of key interest to derive conditions for which a law of large numbers (LLN) applies for the empirical average of functions of (Xt,t ≥ 0) as given by

Here φ(.) is some well defined measurable function with finite expectation as specified in Theorem 1 in Section 2. A simple example is the empirical autocovariance of order h, which in the univariate mean-zero case can be written as

. Irrespective of the initial value X0, this should converge to the theoretical covariance under suitable regularity conditions on the process (Xt,t ≥ 0).
We show in Theorem 1 that indeed the strong, and hence also weak, LLN applies to empirical averages of the general form in (1) independently of the initial distribution of a (geometrically) ergodic Markov chain (Xt,t ≥ 0).
In recent econometric nonlinear time series analysis of nondiscrete observations, such as exchange rates and interest rates, often the concept of geometric ergodicity from Markov chain theory is used as a way to classify stationarity and ergodic properties of (Xt,t ≥ 0). It follows by Meyn and Tweedie (1993, Thm. 17.0.1) that the strong LLN applies to empirical averages of the form

independently of the initial distribution. However, here

is a function of Xt alone, and hence this is a restricted version of the case in (1). In particular, it does not cover the mentioned simple example of the empirical covariance of order h.
Typically, geometric ergodicity of a nonlinear times series process is verified by using a drift criterion from Markov chain theory; see, for example, the general discussions with many examples in Carrasco and Chen (2002), Meitz and Saikkonen (2004), Tjøstheim (1990), and, recently, Kristensen (2005) and Liebscher (2005) and the references therein. Geometric ergodicity implies that there exists an initial distribution of X0, the invariant distribution, such that the process (Xt,t ≥ 0) is stationary, and, moreover, the drift criterion implies that suitable moments of the stationary version of the process exist and are finite.
Note also that it is a direct consequence of geometric ergodicity that the stationary version is β-mixing and therefore that a LLN applies to the stationary version as emphasized in, for example, Doukhan (1995) and Carrasco and Chen (2002). The contribution here is to relax the condition of stationarity or, equivalently, that the process is initiated from the invariant distribution.
As is well known, convergence of terms such as (1) are in particular needed when deriving asymptotic theory for parameter estimators, where the LLN plays a key role when establishing both consistency and asymptotic distribution theory. Many references exist—a much applied classic reference is Billingsley (1961) with focus on general inference in Markovian models, where the general regularity condition (1.11) to be verified therein is a specific example of (1); see also Tjøstheim (1990, Sect. 6). In fact, virtually any econometric time series study on asymptotic inference applies some version of the LLN. For studies with a focus on inference in autoregressive conditional heteroskedastic (ARCH) type models, see, for example, Jeantheau (1998), Jensen and Rahbek (2004a, 2004b), Kristensen and Rahbek (2005a), Lee and Hansen (1994), Ling and McAleer (2003), and also Masry and Tjøstheim (1995) for the nonparametric case. Also, see, for example, Saikkonen and Choi (2004) and Caner and Hansen (2004), where key assumptions imply that the LLN applies to other nonlinear time series. In particular, Kristensen and Rahbek (2005a, 2005b) emphasize results for asymptotic inference in nonlinear ARCH models that hold independently of the initial value.
2. THE LLN
Consider a time homogenous Markov chain (Xt,t ≥ 0) with state space

and transition probabilities Px,

and initial distribution μ, that is,

. Typically,

and

, the Borel σ-algebra on

, where p ≥ 1. Denote by Pμ the distribution of the process (Xt,t ≥ 0) on

. For n ≥ 2, denote further the n-step transition probabilities of the Markov chain by

and set Px1(A) = Px(A).
The Markov chain (Xt,t ≥ 0) is ergodic if there exists a distribution μ0 such that

holds for all

and where ∥·∥ denotes the total variation norm; see Meyn and Tweedie (1993). If such a μ0 exists, it is the unique invariant distribution, and the process (Xt,t ≥ 0) is stationary with distribution Pμ0 when X0 is initiated with μ0,

.
The stronger notion of geometric ergodicity is given by

for some ρ, 0 < ρ < 1.
If an ergodic Markov chain (Xt,t ≥ 0) is initiated by the stationary distribution μ0, then the ergodic theorem for stationary processes in, for example, Stout (1974, Thms. 3.5.7 and 3.5.8) states that for any measurable

, with Eμ0|φ(Xt,Xt+1,…)| < ∞, the average

converges almost surely to Eμ0φ(Xt,Xt+1,…) with respect to Pμ0.
Theorem 1, which follows, establishes that the LLN applies to ergodic Markov chains that are not initiated by the stationary distribution.
THEOREM 1. Assume that (Xt,t ≥ 0) on

is a time homogenous Markov chain that is ergodic and is not necessarily initiated from the stationary distribution μ0. Assume further that

is measurable and Eμ0|φ(Xt,Xt+1,…)| < ∞.
Then for any choice of initial distribution μ,

The proof is given later in this section.
Remarks
(a) As already emphasized, typically geometric ergodicity of Markov chains is verified using a drift criterion from Markov chain theory. Likewise, as discussed in, for example, Tjøstheim (1990), drift criteria can be used for verification of ergodicity.
(b) Often Xt in applied econometric time series analysis is not a Markov chain as it depends on k-lags of the process. That is, Xt depends on Xt−1,Xt−2,…, Xt−k and is therefore not a Markov chain for k ≥ 2. In this case, ergodicity can be established for the Markov chain

as defined by

The emphasis here is on Markovian processes, or processes that can be embedded in a Markov chain. Convergence for other types of dependent processes has been discussed extensively in the literature: see, for example, Andrews (1988), Davidson (1994), Doukhan (1995), McLeish (1975), and White (2000).
Proof of Theorem 1. Define the set H by

By assumption

is measurable and Eμ0|φ(Xt,Xt+1,…)| < ∞. Hence

and

by the ergodic theorem in Stout (1974, Thms. 3.5.7 and 3.5.8). It remains to show that Pμ((Xt,t ≥ 0) ∈ H) = 1, but this follows by Lemma 2, which is given next, noting that by definition H in (6) belongs to the tail σ-algebra. █
LEMMA 2. Under the assumptions of Theorem 1, then for any set H in the tail σ-algebra,

Proof of Lemma 2. Note first that for any set H in the tail σ-algebra, then H for any n ≥ 1 can be written as

with

.
Next, with X0 initiated by μ, define similar to the n-step transition probabilities in (3)

In particular, with μ0 the invariant distribution,

Using these definitions and (8), (7) follows by

where (i) and (ii) hold by definition. The inequality in (iii) holds by noting that

and using (10). Next, the equality in (iii) holds by the definition of Pμn in (9) and from using that μ0(A) = ∫μ0(A) dμ(x). Finally, the inequality in (iv) holds by the triangle-inequality for norms, and the convergence in (iv) is implied by ergodicity of the Markov chain and by dominated convergence, because ∥Pxn − μ0∥ ≤ 2. █


