


1. INTRODUCTION
Most commonly employed econometric models rely on the assumption of stationarity of the sequence of observations. Statistical inference involving this dependence structure should feature good asymptotic properties, and, among these, consistency plays a major role. From a classical point of view, there is a wealth of literature on the topic providing consistency results in specific situations. From a Bayesian point of view, no Doob-type results are available beyond the exchangeable case. However, because Bayesian methods are now routinely applied to problems in which the dependence structure for the observations is more complicated than exchangeability, there is a need for the extension of Doob's theorem to these cases.
Here we will deal with stationary sequences of observations collected in time whose probability distribution is representable as a mixture of conditionally stationary and ergodic laws. In other words we suppose that, conditionally on some random element, the observations are stationary, with sample means obeying the ergodic theorem. The representation theorem we will need is given in Maitra (1977) and further analyzed in Aldous (1985).
Consider a stationary sequence of random variables (Xn)n≥1 defined on some probability space

and taking values in a Polish space

, endowed with the Borel σ-algebra

. Conditionally on a random element, say, θ, the sequence is stationary and ergodic and its law is characterized by the family (Pn(·;θ))n≥1 of one-step transition distributions, that is,

with

. The random parameter θ taking values in the parameter space can be either finite- or infinite-dimensional, and one is typically interested in estimating θ or a functional of θ, given an n-sample of observation (X1,…, Xn). Such estimates are known as a posterior estimates. Here we will deal with asymptotic properties of the sequence of predictive distributions (Pn)n≥1. The models we will consider are characterized by the fact that the probability distribution of the vector (X1,…, Xn) admits a mixture representation of the type

for any set A in

and for some probability distribution Π on the parameter space Θ, with p(dx1|x0;θ) = p(dx1|θ). Using the terminology commonly employed in Bayesian statistics, Π acts as a prior distribution for θ. Moreover, for any θ,

is a probability distribution on

that can be seen as the distribution of (X1,…, Xn) given θ. If we let P∞(·|θ) denote the distribution of the whole sequence (Xn)n≥1 this means that, for any n ≥ 1,

Suppose that each p(dx|x1,…, xi−1;θ) admits a density with respect to some σ-finite measure λ on

, that is, p(dx|x1,…, xi−1;θ) = f (x|x1,…, xi−1;θ)λ(dx). With respect to these transition densities, we ask for an identifiability condition to hold true. This implies that f (· |x1,…, xi−1;θ) ≠ f (· |x1,…, xi−1;θ′) for any θ ≠ θ′,

and i ≥ 1. This is a fundamental requirement for all statistical models. Hence it should be always satisfied, and it will be valid in all the examples we are going to list in the following sections.
As one can see, a number of processes of common use in applications may play the role of the mixing model in the representation theorem for the sequence of observations. Here we highlight some interesting and useful examples.
1.1. Exchangeable Sequences
A noteworthy special example is represented by a sequence of exchangeable observations. In this case, the de Finetti representation theorem states that the distribution of a vector of n of those random variables can be represented as a mixture of independent and identically distributed (i.i.d.) random variables, that is,

Hence

This describes the common setting for Bayesian applications, which parallels the classical assumption of i.i.d. observations. The first Bayesian study of consistency for this class of models dates back to the paper by Doob (1949). More recent work has been done by Lijoi, Prünster, and Walker (2004) that inspires the proof to the much more general theorem in the present paper.
1.2. Discretely Observed Diffusion Processes
Let the stochastic process X = {Xt : t ≥ 0} be a diffusion process that is the solution of the following stochastic differential equation:

where {Bt : t ≥ 0} is a standard Brownian motion and b and σ satisfy suitable conditions ensuring existence and uniqueness of the solution to (2). More specifically, introduce the scale density

, for some x* in the interior of the domain, I, of Xt. We suppose I = [l,r], where −∞ ≤ l < r ≤ +∞. If the following conditions are satisfied:

then X is strongly stationary (see, e.g., Karatzas and Shreve, 1991, Sect. 5.5) and ergodic.
Take, now, an increasing sequence of positive numbers (tn)n≥1 with tn → +∞ as n → +∞ and set Yn = Xtn. The interest of a discretely observed diffusion process is crucial to a number of problems in economics and finance. Indeed, models of the type (2) are routinely used to describe the behavior of stock prices, exchange rates, and interest rates, among other interesting economic phenomena. In all these applications, data are recorded at discrete time points (e.g., monthly, weekly, daily), and then it is important to study properties of estimation procedures that involve the sequence (Yn)n≥1. Within the frequentist setting, an area of research has focused on methods of estimation based on the use of contrast functions or approximate likelihood functions, and remarkable papers are those by Dacunha-Castelle and Florens-Zmirou (1986), Bibby and Sørensen (1995), Gourieroux, Monfort, and Renault (1993), Pedersen (1995), and Aït-Sahalia (2002). Some of these papers also consider the consistency of the suggested estimation methods. Techniques for Bayesian inference in this context have been developed in Elerian, Chib, and Shephard (2001), Eraker (2001), Beskos, Papaspiliopoulos, Roberts, and Fernhead (2006), and Roberts and Stramer (2001).
1.3. Markov Processes
Another noteworthy example that falls within the class of models we deal with is represented by stationary Markov processes. Hence, we let (Xn)n≥1 be a stationary Markov process taking values in a general state space

, and we denote its one-step transition density by p(·,·). If the process is aperiodic and irreducible, it is also ergodic. Thus our result includes such a model. Note that the parameter θ might in this case coincide with the transition density itself, thus being infinite-dimensional. Classical approaches typically involve maximum likelihood procedures. See, for example, Billingsley (1961). As far as the Bayesian approach is concerned, interest in inference for stationary and ergodic Markov chains has grown in a variety of settings and applied problems.
Here we consider a Markovian state space model based on a time series {Yt : t = 1,…, n} whose observations are conditionally independent given an unobserved sufficient state {Xt : t = 1,…, n}, assumed to be Markovian. The aim is to learn about the state Xt, given contemporaneously available information. See, for example, Pitt and Shephard (1999). Moreover, and still in a Bayesian setting, popular Markov chain Monte Carlo (MCMC) techniques are based on the simulation of stationary and ergodic Markov chains. See, for example, Chib (1996) and Chib and Greenberg (1996).
More recently an interesting approach for constructing strictly stationary AR(1) models has been introduced by Mena and Walker (2005). The idea is to use one-step Bayesian nonparametric predictive distributions to define the transition density of the process.
1.4. ARCH(1) Models
Suppose (Xn)n≥1 is a sequence of random variables defined by

where σn2 = θ1 + θ2 Xn−12 and the Zn's are i.i.d. with a zero mean and unit variance. If θ2 < exp{−ψ(0.5)}, where ψ is the so-called ψ-function, then the process (Xn)n≥1 is stationary ergodic. The parameter is, in this case, the vector θ = (θ1,θ2). Both a classical likelihood-based approach and Bayesian techniques are considered, for instance, in Fiorentini, Sentana, and Shephard (2004).
1.5. Linear Processes
Let (an(θ))n≥1 be a sequence of real numbers that is squared-summable, that is,
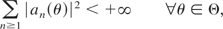
where Θ is possibly an infinite-dimensional space. Denote by {εn(θ) : n = −∞,…,+∞} a stochastic process such that

where δi,j = 1 if i = j and it is zero otherwise. Then the process (Xn)n≥1 defined by

is stationary and ergodic. Classical inferential procedures for these processes are accounted for in Brockwell and Davis (1996). A description of Bayesian solutions to problem estimation can be found in West and Harrison (1997) and Huerta and West (1999a, 1999b).
2. CONSISTENCY FOR STATIONARY MODELS
Here we wish to prove an asymptotic result that is known to hold in the exchangeable case. Let us first set the parameter space Θ to be complete and separable with respect to some suitable metric and indicate with σ(Θ) the corresponding Borel σ-algebra. According to the assumptions outlined in Section 1, for any n ≥ 1 and θ ∈ Θ, the probability distribution

admits a density with respect to the product measure λn on

, and we denote such a density by hn(·|θ), that is,

and

. To evaluate distance between any two densities on

, we consider the Hellinger distance, which is well known to be equivalent to the L1-metric, defined as follows:

We simply denote by Pθ the law of the whole sequence of observations when the value of the parameter is θ. Moreover, if Πn denotes the conditional distribution of θ, given the sample x1,…, xn, it can be represented as

Finally, let δx stand for the point mass at x.
THEOREM 1. Suppose the model in (1) is identifiable. Then, there exists a random element

such that

as n → ∞, for any A in σ(Θ), and the distribution of

coincides with Π. Moreover,

is essentially unique.
Proof. Before entering the details of the proof we outline the strategy we will follow. As a first step, we work with a general prior on a space of density functions and show that the posterior admits an almost sure weak limit. This result is used to show that the sequence of predictive densities converges. Next, we translate the problem to fit it to the model (1), where the prior is defined on the (possibly infinite-dimensional) parameter space Θ. This allows the identification of a function

that is shown to be measurable. Finally, using a representation theorem, we show that the distribution of

is the distribution Π appearing in (1).
Let Q be a distribution on the space

of density functions (with respect to some σ-finite measure λ) on the complete and separable metric space

. Moreover, let

denote the Borel σ-algebra on

. If X1,…, Xn is a sequence of observations generated by

the posterior distribution of f is given by

Let fn(x) denote the predictive density (with respect to λ) of the (n + 1)th observation given the previous n, that is,

Moreover, fnA is the predictive density restricted to set

, namely,

Note that

where

is the marginal density of the vector of observations (X1,…, Xn). Hence it follows that

Because for any set A in

, almost surely, the martingale convergence theorem implies

Thus, exploiting tightness of

(for all n ≥ 1), by Theorem 2.2 in Berti, Pratelli, and Rigo (2006), one has that Q∞ is a random probability measure and Qn converges weakly (almost surely) to Q∞. At this point we will need to introduce a slight modification of the Hellinger distance between any two densities, f and g, which coincides with

Set σn to be the σ-algebra generated by (X1,…, Xn). By virtue of (4) one has

Consider, now, the martingale (SN,σN)N≥1 defined by

where we have obviously set Q0(A) := Q(A). Because

we have

from which it follows that

as n tends to +∞, which in turn yields

as n → +∞. Because Q∞ is a random probability measure, for any ω ∈ Ω there exists a density f* in

such that Q∞(Aε) > 0 for all ε > 0, where

. In particular, Aε can be chosen in such a way that Q∞(∂Aε) = 0, where ∂Aε is the boundary of set Aε. If fn*(xn+1) = f*(xn+1|x1,…, xn), by virtue of the triangular inequality one has

Because the first summand tends to zero, we only need to care about the second one. To this end, using convexity of h(·,·), one obtains

which implies that

To exploit the last limiting result in the setting of the model (1), one has to interpret Q as the prior on

induced by Π on Θ, and Π∞ is the (almost sure) weak limit of the sequence Πn corresponding to Q∞. Hence, working now on the space Θ, we have fn = ∫Θ f (·|x1,…, xn,θ)Π(dθ) and fn* = f (·|x1,…, xn,θ*). It can now be shown that such a θ* is unique. To this end, suppose that the convergence in (7) holds true also for some other θ** ∈ Θ. If fn** = f (·|x1,…, xn,θ**), from

one has h(fn*,fn**) → 0, almost surely, and by the identifiability assumption, it follows that θ* = θ**.
Now, let

be a function that associates to each ω a parameter value θ such that Π∞(Aε) > 0, for any ε > 0. Such a function is measurable. Indeed, for any B ∈ σ(Θ),

On the other hand, if ω ∈ Ω is such that Π∞(B) > 0, there exists a parameter θ in B such that θ is in the support of Π∞. This means that

and measurability of

follows from the fact that Π∞ is a random probability measure. Moreover, equality between the preceding two sets implies

By virtue of the stationarity assumption, a theorem due to Maitra (1977) implies that there exists some random element

with values in Θ such that, conditional on

, the distribution of the observations can be represented (almost surely) as

We aim to show that

, almost surely. If

for any B in

, then

where the last equality follows from the definition of conditional expectation. Because

and ∫Θ Pθ(B|x1,…, xn)Π∞(dθ) are bounded, one has

where the last equality follows from the fact that

and X(∞) denotes the whole sequence of observations. Moreover,

is measurable with respect to the σ-algebra generated by X(∞). Hence

for every B in

. This entails

(almost surely). Hence the result follows. █
3. CONCLUDING REMARKS
We have obtained a quite remarkable result regarding the asymptotic properties of Bayesian procedures for stationary models. Bayesians can be confident in carrying out analysis of models much more general than those based on the common assumption of exchangeability. An open question that remains is the case of nonstationary data, for which we are not able to extend the result of the present paper because of the lack of a suitable representation theorem. The proof to Theorem 1 can still be used to state that the sequence of posterior distributions converges to a point mass at a random parameter, but there is no guarantee that this random parameter is the one that generates the sequence. Indeed, in this more general case one can still assume that the joint distribution of the observations is written as a mixture with respect to the distribution of some parameter. However, the representation theorem does not apply, and the mixing parameter from which the data are generated is not identifiable. This is an important remark because it means that a Bayesian analysis of nonstationary data could lead to an answer in the form of the posterior converging to a point mass at the wrong parameter.


