1. Introduction
We first examine the idea, explored by many since it was suggested by Ramsey (Reference Ramsey1931) and de Finetti (Reference de Finetti, Kyburg and Smoklee[1937] 1964), that probabilities should be identified with idealized degrees of belief. In the first section of the paper, we argue against this idea. In the second section, we present a brief introduction to evidential probability (Kyburg and Teng Reference Kyburg and Teng2001), which combines elements of Keynesian and frequency views of probability. The main thrust of the article is contained in the third section, which considers the interaction of conditioning and hypothesis testing, the interaction of conditioning and tests of hypothesis, and the interaction of conditioning and confidence interval analysis. These are the three major kinds of application of classical statistics. We also examine the relation between Walley's (Reference Walley1991) generalized Bayes’ rule, and conditioning as it appears in evidential probability. The fourth section provides a semantic justification for the use of evidential probability, and in particular for the use of conditioning when it is warranted.
2. Degrees of Belief
I have argued elsewhere (Kyburg Reference Kyburg2003) that there are no degrees of belief—that as between Keynes (Reference Keynes1952) and Ramsey (Reference Ramsey1931), Keynes, who denied that ‘degrees’ of rational belief, i.e., probabilities, can be ordered was completely in the right. My belief in rain tomorrow is neither less than, nor greater than, nor yet equal to, my belief that the dollar will rise tomorrow relative to the euro. Let us say that beliefs like this are “incomparable”: two beliefs are incomparable when the first is neither less than, more than, nor yet equal to, the second.
This observation has a serious effect on how we think of regimenting partial belief. For example, it has a bearing on action: Would you rather stake a positive gain on possibility A or on possibility B? If your belief in A and your belief in B are incomparable, you cannot answer. Of course, a bully like Jimmy Savage could force you to choose, but that is no answer. If beliefs occur in real number degrees, then we can ask whether those degrees are related in the way called for by the probability calculus. We can argue (as did Ramsey) that they are only rational if so related. If A and B are exclusive, then the degree of belief in their disjunction should be the same as the sum of the degrees of belief of their disjuncts. Even Keynes's axioms provide for this in the special case when the probabilities are comparable. But if degrees of belief are not real-valued, this doesn't always even make sense!
More to our present point, Keynes's axioms include a “multiplication” axiom:
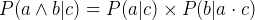 $P(a\wedge b\vert c) =P(a\vert c) \times P(b\vert a\cdot c) $
. (In many modern systems, this is replaced by a so-called “definition” of conditional probability; this is a poor definition, since one cannot replace the definiendum by the definiens unless one knows that
 $P(a\vert c) > 0$
.) The idea is that after you observe c, when you have background knowledge a, you should have a rational belief in b characterized by
 $P(b\vert a\cdot c) $
. But of course multiplication makes no more sense for non-numerical probabilities than does addition.
There is a further question about the relation between probability and belief. When beliefs and probabilities both come in real-valued degrees, the question is simple enough to state: are probabilities to represent degrees of belief? Or are degrees of belief to conform to probabilities. Even here the question is not simple to answer. Probabilities only represent these hypothetical degrees of belief to a certain point; in the case of conflict with the axioms of probability, it is the axioms that rule, and degrees of belief that give way, somehow or other. As Savage observed, in the case of conflict with the axioms, some change must be made, but in general the axioms don't tell what change in belief to make.
Keynes went further, and argued that probability was a matter of logic, and that probabilities were to be legislative for rational belief. But remember that probabilities were, for Keynes, non-numerical, except in special and idealized circumstances. Ramsey, focusing on real-valued degrees of belief, argued, to the contrary, that it was not “belonging to formal logic to say what should be a man's expectation of drawing a white or a black ball from an urn; his original expectations may within the limits of consistency be any he likes …” (Ramsey Reference Ramsey1931, 189). But Ramsey is committed to real number degrees of belief, and it is hard to pick one as against another. Keynes, of course, is free to say that what logic demands is sometimes a maximally indeterminate degree of belief.
Ramsey disregarded all that Keynes said about noncomparability, assumed that probabilities were numerical, and proceeded to explore a normative theory restricted to real number degrees of belief. In this he has been followed by many philosophers. But what was really called for was a treatment of “addition” and “multiplication” that made sense of Keynes's idea.
One idea that has been pursued (e.g., by de Campos et al. Reference de Campos, Heute and Moral1993) is to identify probability with intervals. For example one can assign interval probabilities to the atoms of a set of statements. It is possible to calculate with these interval probabilities, provided certain conditions are met. Intervals have the right lattice structure for Keynesian probabilities, if we take
 $[ r,\,s] < [ p,\,q] $
if and only if
 $s< p$
. Alas, providing an arithmetic for intervals is not simple: think of a die that is either biased towards one at the expense of two, or towards two at the expense of one. We want to say that the probability of a one is an interval around 1/6 and that the probability of a two is a interval around 1/6, but we also want to say that the probability of a one or a two is exactly 1/3, not an even bigger interval around 1/6 plus 1/6. We need to take account of where these intervals come from.
3. Evidential Probability
That is just what evidential probability tries to do. First developed in Kyburg (Reference Kyburg1959) and most recently laid out in Kyburg and Teng (Reference Kyburg and Teng2001), evidential probability is intended to measure the total support that a body of evidence gives a hypothesis.
Evidential probability requires that all probabilities be related to known relative frequencies, but since these relative frequencies are only approximately known, the corresponding probabilities are intervals rather than being real-valued: the probability of the sentence S, relative to the body of knowledge E is
 $\mathrm{Prob}\,(S\vert E) =[ p,\,q] $
, where
 $p\leq q$
. All probabilities are conditional in the sense that they are relative to evidence. But it is not the case that all probabilities can be represented as real-valued: the quest for objectivity leads to interval probabilities.
In slightly more detail: Let
 $\Gamma _{\delta }$
be a set of sentences that represents our evidence, including both background knowledge and data. The small number designated by δ represents the maximum chance of error to which sentences in
 $\Gamma _{\delta }$
are subject. We write
 $\ulcorner \% \overline{\eta }(\tau ,\,\rho ,\,p,\,q) \urcorner $
for the statement: the proportion of objects satisfying the reference formula ρ that also satisfy the target formula τ lies between p and q, where τ and ρ are canonical target and reference formulas characteristic of the language (ultimately we need a procedure for choosing between languages) and p and q are real variables or fractions in canonical form. If for some term α, the statements
 $\ulcorner S\equiv \tau (\alpha) \urcorner $
,
 $\ulcorner \rho (\alpha) \urcorner $
, and
 $\ulcorner \% \overline{\eta }(\tau ,\,\rho ,\,p,\,q) \urcorner $
are all in
 $\Gamma _{\delta }$
, then
 $[ p,\,q] $
is a candidate for the evidential probability of S relative to Γδ.
The problem is that there are many such candidates; this is the well known “problem of the reference class,” first discussed by Hans Reichenbach (Reference Reichenbach1949). For example, we may know of an applicant for insurance that he is 50 years old, that he smokes, that he is of Irish extraction, that he works out twice a week, … . Each of these properties, and each conjunction of these properties, generates a possible reference class. Reichenbach's solution was that we should use the narrowest (most specific) reference class about which we have “adequate statistics”. Since the narrowest reference class is the unit class of the applicant, about which we presumably have no statistical knowledge, we must judiciously weigh our knowledge against the specificity of each possible class. We offer here a modification of this idea that does not call for judiciousness.
There are three principles that can be used to resolve this problem, and they are precisely the principles that will allow us to deal with the tension between classical and Bayesian statistics.
We first define conflict between statistical intervals. Let us say that two intervals conflict just in case neither is included in the other. Thus [0.3, 0.5] and [0.4, 0.7] conflict, as do [0.1, 0.5] and [0.8, 1.0], but [0.5, 0.6] and [0.4, 0.6] do not, nor do [0.0, 1.0] and [0.5, 0.5].
The three principles are these:
1. If two statistical statements conflict and the first is based on a marginal distribution while the second is based on the full joint distribution, ignore the first. This gives conditional probabilities pride of place when they conflict with the corresponding marginal probabilities. We will call this the principle of conditioning.
Example: Suppose we have 30 black and 30 white balls in a collection C. The relative frequency of black balls among balls in C is 0.5, and this could serve as a probability that a specific ball a in C is black. But if the members of C are divided into three urns, one of which contains 12 black balls and 28 white balls, and two of which each contain 9 black balls, and one white ball, then if a is selected by a procedure that consists of (1) selecting an urn, and (2) selecting a ball from that urn, the relative frequency of black balls is
 $(1/ 3) (12/ 40) +(1/ 3) (9/ 10) +(1/ 3) (9/ 10) =7/ 10$
, and this is the appropriate probability that a, known to be selected in this way, is black. The marginal distribution is given by 30 black balls out of 60; the full distribution reflects the division of the balls into the urns, and the distribution of colors in each urn (table 1).
2. If two conflicting statistical statements both survive the principle of conditioning, and the second employs a reference class that is known to be included in the first, ignore the first. This embodies the well known principle of specificity.

| Urn 1 | Urn 2 | Urn 3 | Total | |
|---|---|---|---|---|
| Black | 12 | 9 | 9 | 30 |
| White | 28 | 1 | 1 | 30 |
| Total | 40 | 10 | 10 | 60 |
Example: Suppose we have a population of birds in a zoo, and that 95% of them can fly. The other 5% are penguins, and can't fly. Given that a bird is to be selected from the zoo (chosen, for example, by its acquisition number), the relative frequency with which it will be a flyer is 0.95, and this is also the appropriate probability that it can fly. Given that it is a penguin that is to be selected, the relative frequency of flyers is 0, and that is the probability that it can fly.
Those statistical statements we are not licensed to ignore we will call relevant. A set of statistical statements that contains every relevant statistical statement that conflicts with a statement in it will be said to be closed under difference.
3. The probability of S is the shortest cover of any non-empty set of relevant statistical statements closed under difference; alternatively, it is the intersection of all such covers. This is the principle of strength.
Example: Suppose we are considering a toss of a coin. The coin has been extensively tested, and we know that it yields heads between 0.4 and 0.6 of the time. It is being tossed by an expert whose record supports the hypothesis that he gets heads between 0.48 and 0.61 of the time. Of course we also know that coin tosses in general yield heads very nearly half the time—say between 0.495 and 0.505 of the time. There is nothing that conflicts with [0.495, 0.505], so the relative frequencies in the more specific classes (tosses of this coin: [0.40, 0.60], tosses by the expert: [0.48, 0.56]) can legitimately be ignored. Notice that the minimal covers of sets of statements closed under difference are nested; one set, {[0.4, 0.6], [0.48, 0.61]} yields [0.4, 0.61]; the other set is {[0.495, 0.505]}, yielding [0.495, 0.505]; the probability is the shortest cover, [0.495, 0.505].
We obtain a probability interval from these principles by taking it to be the shortest cover of a set of conflicting intervals that cannot be ignored on one of these three grounds. In many cases—for example, those involving a well calibrated gambling apparatus—we can get quite precise probabilities from the application of these principles. Whether this is always the case is something we will briefly consider later.
The general principle followed here is worth reflecting on. On the one hand, we would like to use the most specific and relevant information we have as a guide to an unseen instance. But this principle leads us toward reference classes about which we have very little information. We want to base the probability of death of a candidate Smith for life insurance on a class of individuals “just like” him. But this will be a small class, about which we have relatively little actual data, and therefore about which we know relatively little. An extreme point of view would accept this conclusion: frequencies lead us to the interval [0, 1], so we are thrust back into subjectivity.
We also want to base the probability of death for candidate Smith on the relative frequency in a class about which we have much data. We can apply the maximum amount of data by taking as reference class all U.S. citizens. But this seems wrong, too. To be sure, the estimate of relative frequency becomes ever more precise, as we expand the data, but it also becomes less relevant.
Thus we are led to ways in which we can use data from larger reference classes; Pollock (Reference Pollock1990), Levi (Reference Levi1980), and others have worked on this problem from a philosophical point of view. Our own approach, illustrated above, takes conflict among statements embodying statistical knowledge to be the key: one has to “do something” only when confronted with conflicting relative frequencies. In two cases, we have a principled way of adjudicating the conflict: first, when the conflict arises between an analysis that makes use of conditioning on an objective prior relative frequency and an analysis that does not; and second, when the two conflicting statistical generalizations concern reference classes, one of which is (known to be) a subclass of the other. When we have conflict that cannot be dealt with in either of these ways, we accommodate the conflict by taking the probability to be the cover of the conflicting intervals. This probability is not the known relative frequency in any reference class. It nevertheless is based on relative frequencies and reflects their combined effect.
This strategy deals nicely with the uniqueness of Mr. Smith. What we know about the relative frequency of death within a year in the very small class consisting of Mr. Smith alone, {Smith}, is that it is 0 or 1. Therefore, on our view, it does not conflict with anything. Therefore we may ignore it, just as our knowledge of coins (or of physics) allows us to ignore the fact that our tests of a particular dime give us reason to believe that it yields heads between 0.42 and 0.55 of the time. It is not merely intervals [0.0, 1.0] that can be ignored, but relatively uninformative intervals in general.
A natural question concerns the relation of these interval-valued probabilities to degrees of belief. Note that we had to suppose nothing about degrees of belief—even that they exist—in order to arrive at these probabilities. But Keynes proposes, and I will follow him in this, that probabilities are legislative for rational belief. What I take that to mean when probabilities are interval-valued is that however beliefs are construed, if they are represented by rational numbers, then those numbers should not conflict with probability intervals.
Thus one thing one might say of beliefs is that they are related to betting behavior (among other kinds of behavior). For example, if I am willing to pay $0.30 for a ticket that returns $1.00 if S is true, my belief in S might be said to be at least 0.30. Similarly, if I am willing to pay $0.20 for a ticket that returns $1.00 if S is false, my belief in ¬S might be said to be at least 0.20. Suppose I am unwilling to pay more for either ticket. One way to understand this situation is to say that I have a real-valued degree of belief in S between 0.30 and 0.80, but that I do not know what it is. Fair enough, if real-valued degrees of belief play an important role as theoretical terms in some abstract theory.
Alternatively, one could identify the belief state at issue with the interval [0.3, 0.8]. This is what C. A. B. Smith's approach does (Reference Smith1961, Reference Smith1965), as does the approach followed in elegant detail by Peter Walley (Reference Walley1991); in Walley's vocabulary, these limits are called “previsions,” following de Finetti (Reference de Finetti, Kyburg and Smoklee[1937] 1964). But one feels a bit unsure as to the maximum amount one would pay for a ticket, and in the light of vagueness about what one would pay for a ticket, we might also suppose that “degree of belief” was just au fond a rather amorphous notion.
It is worth noting that both Smith and Walley are writing within the Ramseyan tradition, in which degrees of belief, even if vague, come first, and probability or prevision, so far as it is related to degrees of belief, comes second. Thus in order to have something to work with, degrees of belief should at least have sharp edges. To be worthy of the honorific ‘rational’, the edges then have to satisfy conditions of coherence inherited from the probability calculus.
Our approach is the opposite. The sharply edged intervals come first, as logical probabilities determined by a body of evidence. Beliefs, vague and amorphous though they be, are enjoined not to violate those interval constraints. Probability is legislative for rational belief.
How about conditional probability? From a Keynesian point of view all probabilities are conditional: they are all conditional on the body of knowledge we have. Of course we can also talk hypothetically: Were I to know S (e.g., that the next roll of the die will yield an odd number), in addition to what I now know, what would be the probability of T (e.g., that the next roll will yield a one)? Were I to know what I know now, except for T (e.g., the outcome of the last roll), what would be the probability of S (e.g., that that roll would yield an odd number)?
If we start with beliefs, we may consider conditional beliefs, as did de Finetti (Reference de Finetti1972). That is, we may look at the probability of S conditional on T. As Levi was the first to point out (Reference Levi1967), and as Walley also recognized (Reference Walley1991), this is ambiguous. Does it mean my updated degree of belief in S when exactly the proposition T is added to my body of knowledge? Or does it mean something that might be characterized by a conditional bet?
Our present concerns are with updating beliefs. Walley recognizes that there may be reason, on occasion, to reevaluate our previsions, and thus that the updating of previsions need not always proceed by conditioning. Levi (Reference Levi1980) is even more adamant about this. In the case of much “Bayesianism,” however, conditioning (what Levi calls “temporal conditionalization”) is the norm for evidential updating. It surely seems to be the case that it is often the right thing to do. On the other hand, most actual statistical inference, most experimental design, conforms to the pattern established on the basis of frequentist principles. Although the calculus associated with evidential probability is only a calculus derived from relative frequencies, it throws an interesting light on this tension between conditioning and controlling frequencies of error.
4. Conditioning and Frequencies
At root, there is no conflict between conditioning and relative frequencies. The classic founding fathers—Neyman, Fisher, Pearson—all understood Bayes’ theorem to be a theorem, and took it to be applicable under appropriate conditions—namely, when there was knowledge of prior distributions.
As Levi (Reference Levi1980, Chapter 16) showed, there can be conflict between conditioning and direct inference, the foundation of evidential probability. The example concerns whether Peterson the Swede is a Protestant: S. We know that 90% of Swedes are Protestant. But we know that Peterson lives in Malmö and that either 89% of the residents are Protestant (
 $h_{0.89}$
), or 91% (
 $h_{0.91}$
) are, or 92% (
 $h_{0.92}$
) are. What has been called the “principle axiom” of conditional probability is
 $P(S,\,K) =\sum_{i}P(S,\,K,\,h_{i}) \times P(h_{i},\,K) $
, where the
 $h_{i}$
are exclusive and exhaustive. In the present case, we would supposedly want

But for this sum to be 0.9 requires that
 $\mathrm{Prob}\,(h_{0.92},\,K) =0$
. Similarly, we can show that
 $\mathrm{Prob}\,(h_{0.91},\,K) =0$
. This means that there is no real-valued probability that satisfies the constraints of evidential probability, and also conforms to classical conditional probability (the principle axiom).
Like Levi, I have argued against the universality of conditioning, though direct inference sometimes supports it. There is a problem to be faced, but it is a straightforward technical one; this is the problem generated by approximate knowledge. Conditional probability is easy enough to characterize on the basis of point-valued probabilities, but when we must be concerned with intervals or sets of probability functions, things are more complicated. Let us observe, first, that most statements of the form
 $\ulcorner \% \overline{\eta }(\tau ,\,\rho ,\,p,\,q) \urcorner $
are in our bodies of knowledge because they follow from distribution statements that are accepted in our bodies of knowledge. These distribution statements have the form: the random quantity Q has a distribution in R belonging to the nonempty set of distributions
 $\mathstrut{\cal D} $
. If b is a Borel set, we may note that

has just the form we stipulated for statistical knowledge in the previous section. As before, Q and R are constrained to be target and reference formulas.
From here to interval-valued conditional probabilities is a simple hop: condition on each of the underlying distributions for which the conditional distribution is defined, and take the resulting interval-valued probability to be the set of values thus obtained.
Example: Suppose our domain is rolls of a die. What we know of this die is that it is either fair (the distribution corresponds to a frequency function uniform over the six outcomes) or it is biased in favor of one and against two, corresponding to a multinomial frequency function
 $\langle 3/ 12,\,1/ 12,\,1/ 6,\,1/ 6,\,1/ 6,\,1/ 6\rangle $
. The probability of a five on the next roll is [1/6, 1/6] since 1/6 is both the inf and sup. The probability of a one is
 $[ 1/ 6,\,3/ 12] $
. The conditional probability of a one given an odd outcome on the next roll is obtained from the set of conditional distributions
 $\{ \langle 1/ 3,\,1/ 3,\,1/ 3\rangle ,\,\langle 3/ 7,\,2/ 7,\,2/ 7\rangle \} $
corresponding to the frequencies for 1, 3, or 5 given an unbiased or biased die, and is
 $[ 2/ 6,\,3/ 7] $
.
Let us see how far this simple idea takes us in understanding statistical inference.
4.1. Statistical Testing and Bayesian Inference
The standard treatment of inference in classical statistics revolves around the frequencies of possible errors. Thus the size, α, of a simple test of a hypothesis is the relative frequency with which the test will lead to the erroneous rejection of the hypothesis. The level of a test of one statistical hypotheses against another is indicated, for a given procedure, by the frequency with which the procedure would, in the long run, reject the hypothesis under test in favor of its alternative, when the hypothesis under test is true, and the power of the procedure is indicated by the frequency with which the procedure would fail to reject the hypothesis under test when in fact its alternative is true. The level of a confidence procedure, the confidence level, for arriving at an interval estimate of a relative frequency is the relative frequency with which that procedure would produce intervals that in fact include the parameter being estimated.
On the other hand, the Bayesian approach to statistical inference does not involve adopting a yes-or-no epistemic attitude toward a statistical hypothesis, but, taking account of all the evidence available, in determining the correct (or a correct) degree of belief for that hypothesis. One of the problems for this approach is that it demands prior probabilities for statistical hypotheses—probabilities determined in advance of the acquisition of statistical evidence. For this reason many statisticians reject the general applicability of Bayesian inference.
The simplest classical approach to statistics involves rejecting hypotheses when the probability of doing so by mistake is small; the usual result of conditioning is the assignment of a high probability to the hypothesis. If we associate low probability with rejection, and acceptance with high conditional probability, as is natural, these may be compared.
In the subsections that follow we will look at the three major applications of classical statistics (significance testing, testing statistical hypotheses, and confidence interval inference) and discuss two questions: first, what the small numbers (“size,” “confidence level”) mean, and second, how these procedures can be undermined by background knowledge. In both cases, evidential probability will throw light on what is going on.
The tension between the error frequency analysis of classical statistics and the conditioning analysis of Bayesianism potentially arises for a statistical hypothesis S and a piece of evidence E whenever we have evidential probabilities for
 $E\wedge S$
based on prior distributions for S and distributions for E given S. Often, in statistical inference, the conditional distribution for E given S is quite sharp. What may be quite vague is our knowledge of the frequency or frequencies underlying
 $\mathrm{Prob}\,(S) $
. The calculated set of conditional frequencies for S given E always exists, though it may be quite vague. This set of frequencies is certainly a candidate for the conditional evidential probability,
 $\mathrm{Prob}\,(S,\,K\cup \{ E\}) $
.
Nevertheless it may be defeated by the precision of the frequency or frequencies provided by an error analysis. On the other hand, if that set of frequencies conflicts with the frequencies provided by an error analysis, the principle of richness will demand that the error frequencies give way to the conditional frequencies.
It is important to note that all the probabilities involved are based on our knowledge of relative frequencies. Conditioning itself is construed as based on conditional frequencies. It is the frequencies, and our principles for choosing among them, that justify conditioning where it is justified.
4.2. Significance Testing
Significance testing is one of the most frequently applied forms of statistical inference. The general pattern is to formulate a hypothesis
 $H_{0}$
to be tested, which will be rejected just in case a particular kind of observation R is made. The observation is one that would be very unlikely were that hypothesis to be true. Thus rejecting the hypothesis, when it is true, will occur rarely. As characterized by R. A. Fisher (Reference Fisher1971, 39), “The force with which such a conclusion is supported is logically that of a simple disjunction: Either an exceptionally rare chance has occurred or [
 $H_{0}$
] is not true.”
For example, suppose we want to test the hypothesis
 $H_{1}$
that supplementary vitamin Z improves performance in the broad jump. Of course we must make this hypothesis more precise (how much Z? How much improvement? In what class of people?), but assuming we have done so, the time-honored way of proceeding is to obtain a sample of that class, to divide it (“at random”—about which more later) into an experimental group, to which we feed vitamin Z, and a control group, and to test the corresponding null hypothesis,
 $H_{0}$
, that there is no difference between the two groups, or rather that any observed difference between the two groups is “due to chance.” We reject
 $H_{0}$
if we observe a result in the comparison of the two groups that is too large, i.e., falls in the rejection region R of our test.
The size of our significance test is the chance of falsely rejecting the null hypothesis; or, given that the rejection region is R, it is the chance, given the null hypothesis, of obtaining a result in R. If the size of the test is 0.05, the frequency with which we make a mistake in rejecting
 $H_{0}$
as false is 0.05. We are often sternly warned against using the word “probability” here; that admonition reflects a commitment to a limiting frequency conception of probability under which it would, indeed, be a mistake to speak of the probability of a particular event. The evidential interpretation of probability allows this usage. If all we know about the experiment is that we have observed a datum in the rejection region, then the probability that rejection of
 $H_{0}$
would be mistaken is [0.05, 0.05]. But we make a mistake in rejecting
 $H_{0}$
as false if and only if
 $H_{0}$
is true. Thus under these circumstances the evidential probability of
 $\neg H_{0}$
is [0.05, 0.05]. We can, as we have always been tempted to do, say that the probability of the denial of the hypothesis under test is [0.05, 0.05]. Note that if we obtain a result that is not in the rejection region, we can draw no conclusion at all; this is why Fisher (Reference Fisher1971) regarded significance testing as only a preliminary of scientific inquiry.
Of course this is assuming no conflict. One way in which there could be conflict is that the test is a randomized one, in which an auxiliary experiment determines that the rejection region is
 $R_{1}$
, characterized by a frequency of false rejection 0.014, with probability 0.60, or
 $R_{2}$
, characterized by a frequency false rejection of 0.105, with probability 0.6. In that way we can achieve a mixture of the two unrandomized experiments with a long run false rejection rate of 0.05. But both unrandomized experiments conflict with 0.05, and, typically, we will know the outcome of the auxiliary experiment, and thus the specific rule we followed. Specificity would then rule out the mixed test in favor of one or the other of the more specific alternatives.
Another, more interesting, way in which there could be conflict is as a result of prior knowledge. If the prior probability of
 $H_{0}$
given background knowledge B,
 $\mathrm{Prob}\,(H_{0}\vert B) $
, is the whole interval [0, 1], then the posterior probability will cover the same interval, and conditioning would leave us with the uninformative interval; this is ruled out by (3), the principle of strength. But if the prior probability of the null hypothesis is not the vacuous interval [0, 1], then we may be led to the conditional probability as opposed to the error frequency. When will this be? When the conditional probability conflicts with [0.05, 0.05], or more generally with [r, r], where r is the size of our test. This will be the case, for a conditional probability [s, t], when t is less than r or s is more than r.
Let B be our background knowledge, and R be the rejection region, and let

These probabilities are based on frequency knowledge. For example,
 $\mathrm{Prob}\,(H_{0}\vert B) $
may be based on the knowledge that of the chemicals similar to Z in structure, subjected to the class of tests T like those contemplated, between p and q have proved useless,
 $H_{0}$
. That is, “
 $\% (H_{0},\,T,\,p,\,q) $
” is in B. Of course, “
 $\% (R,\,T\wedge H_{0}E,\,0.05,\,0.05) $
” is in B, since the set of statistical tests T is designed precisely to yield results in R 0.05 of the time when it is a useless drug being tested. And how about the effective drugs? What we might suppose ourselves to know is that a fraction between x and y of them will yield results in R under T, that is that “
 $\% (R,\,T\wedge \overline{H}_{0},\,x,\,y) $
” is in B.
On this basis, we may compute that “
 $\% (\overline{E},\,R\wedge T,\,s,\,t) $
” is in B, where the minimum and maximum frequencies possible for s and t are

This background knowledge accounts for the first three probability statements above concerning the particular compound Z, and allows us to calculate the values of s and t in the fourth.
We have a conflict with the significance test (
 $r=0.05$
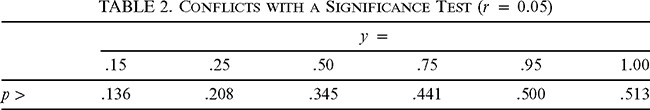
) just in case either t is less than 0.05 or s is greater than 0.05. Table 2 gives a feel for when there is conflict (
 $s> 0.05$
), where y is the upper probability of obtaining a point in the rejection region when
 $H_{0}$
is false, and p is the lower prior probability of
 $H_{0}$
.

| y = | ||||||
|---|---|---|---|---|---|---|
| .15 | .25 | .50 | .75 | .95 | 1.00 | |
| p > | .136 | .208 | .345 | .441 | .500 | .513 |
Note that whether or not there is conflict depends on the upper bound of the rejection frequency of R given
 $H_{0}\wedge B$
, as well as the lower bound of
 $H_{0}$
given B, i.e., the lower bound of
 $\mathrm{Prob}\,(H_{0}\vert B) $
. Thus if the probability of the null hypothesis
 $H_{0}$
is [0.20, 0.40] and the probability of a point in the rejection region given that
 $H_{0}$
is false is [0.10, 0.80], then (since the probability of a point in the rejection region R given
 $H_{0}$
is 0.05 by hypothesis)

which does not conflict with [0.05, 0.05], so
 $\mathrm{Prob}\,(H_{0}\vert B\wedge R) =[ 0.05,\,0.05] $
. The corresponding calculation when the frequency of a point in R among instances of
 $\overline{H}_{0}\wedge B$
is [0.10, 0.20] yields [0.058, 0.250], which does conflict with [0.05, 0.05], so the probability that Z is ineffective =
 $\mathrm{Prob}\,(H_{0},\,B\wedge R) $
. Similar considerations concern the other possibility of conflict, i.e., when the upper conditional frequency of
 $H_{0}$
given
 $R\wedge B$
is less than 0.05.
Thus if we take evidential probability, as legislative for rational belief, we obtain the classical frequentist constraints in some cases, and constraints from conditioning in others. Even in the latter case, however, the constraints reflect known relative frequencies.
4.3. Hypothesis Testing
In significance testing we are testing a hypothesis
 $H_{0}$
against its denial. In general, in significance testing, the denial of the null hypothesis is not very informative, though notice that even when the upper probability of the denial of the null hypothesis is 1 we may run into conflict with conditioning. In the ideal hypothesis testing case, we test one hypothesis,
 $H_{0}$
, against a specific alternative,
 $H_{1}$
. We associate such a test, construed as leading to the possible rejection of
 $H_{0}$
, with two kinds of error. Error of the first kind, or type I error, consists in erroneously rejecting
 $H_{0}$
. Error of the second kind, or type II error, consists in mistakenly failing to reject
 $H_{0}$
. The size of a test, α, is the probability that it will commit an error of type I. The power of a test,
 $1-\beta $
, is the probability that it will avoid committing an error of type II; it is the probability of obtaining a point in the rejection region under
 $H_{1}$
.
As before, these are ordinarily construed as frequencies: α is the relative frequency with which the test in question yields a point in the rejection region if
 $H_{0}$
is true.
The two kinds of error that can be made may both be bounded. In the case of testing a simple hypothesis against a simple alternative, both may be quite precise; and this may provide us with interval bounds on the error of applying a particular test. If the probability of making an error of the first kind is α, and the probability of making an error of the second kind is β, then the probability of making an error of one kind or the other (before conducting the test) is [α, β] (assuming
 $\alpha < \beta $
and that either
 $H_{0}$
or
 $H_{1}$
is true).
But of course when we have conducted the test, we know how the test came out, and so we know whether or not
 $H_{0}$
was rejected. If
 $H_{0}$
was rejected we know that the probability of error is (in this simple, idealized case) exactly α, the probability of false rejection. If
 $H_{0}$
was not rejected, our error, if any, was that we failed to reject
 $H_{0}$
, even though it was false, i.e., even though
 $H_{1}$
was true, and so the probability of error is β. In either case we have a precise probability with which to contrast the results of conditioning.
In general, of course, we are not testing a precise hypothesis against a precise alternative. The hypothesis tested,
 $H_{0}$
, may be composite. Nevertheless, we can typically find a value of α that will provide an upper bound for the probability of mistakenly rejecting
 $H_{0}$
. The probability of error of the first kind may thus be the interval [0, α], or the probability of not making an error in rejecting the hypothesis tested is [
 $1-\alpha $
, 1]. Again, typically, we find it even more difficult to find a lower bound for the power of a test; what is done is to seek a test of
 $H_{0}$
against
 $H_{1}$
for which the probability of type I error is bounded above, and for which the probability of error of the second kind is minimized among the set of alternatives
 $H_{1}$
being contemplated. (In general
 $H_{0}$
and
 $H_{1}$
are exclusive, but not exhaustive.)
After the test, this leaves us back in the significance testing state of affairs: if
 $H_{0}$
is rejected, we can assign a probability—perhaps the interval [
 $1-\alpha $
, 1]—to its denial, but if
 $H_{0}$
is not rejected, then we are left only with the “conclusion” that the test in question did not reject
 $H_{0}$
; the probability of
 $H_{0}$
may remain the whole interval [0, 1].
The status of Bayesian inference differs sharply in the two cases, according to whether
 $H_{0}$
is rejected or not. When
 $H_{0}$
is “rejected at the α level,” the existence of a set of prior frequency distributions that, conditioned on the same evidence, yields a posterior probability that conflicts with [
 $1-\alpha $
, 1] undermines that rejection, according to the first rule. On the other hand, when the test fails to reject
 $H_{0}$
, the relevant truth frequency of
 $H_{0}$
may be the whole interval [0, 1], and any (objective) prior distribution that, conditioned on the evidence, yields a non-vacuous posterior dominates, according to the third rule.
4.4. Confidence Intervals
Confidence interval analysis is pervasive and useful. When we weigh a rabbit, in a medical experiment, we know the characteristics of our scale, and we obtain a confidence interval estimate at a certain level (say 0.99) of the weight of the rabbit (say 1.300 Kg ± .005). Although, as in the previous cases of inference, we are carefully enjoined from saying that the probability is 0.99 that the weight of the rabbit is in this interval—this would clearly be false of frequencies—it is hard to avoid thinking it. Evidential probability does allow us to say this.
Inference leading to confidence intervals often depends on a lot of background knowledge (for example, in weighing the rabbit we make use of our knowledge that the distribution of errors of measurement of our scale is about Normal, with a standard deviation of about 0.002), but it is also possible to construct confidence intervals without background knowledge. This case is particularly interesting as helping to establish the possibility of the objective statistical knowledge required for evidential probability.
Let B be a finite set of objects; let some of these objects belong also to C. Let r be the proportion of B's that are C. For any value of r, we can easily enough compute upper,
 $U(r) $
, and lower,
 $L(r) $
, bounds that constitute the shortest interval into which, with a relative frequency of at least 0.95, the proportion of C's in a sample of N B's will fall. Of course this depends on r. But this shortest interval is longest for
 $r=1/ 2$
. In other words, we can know, a priori, that 95%–100% of the N-membered samples of B are representative in the sense that the relative frequency of C in a sample corresponds to a point between the set of upper bounds,
 $U(r) $
, and the set of lower bounds,
 $L(r) $
. These functions are not continuous—they are step functions—but that need not bother us since we are dealing in intervals anyway. (It did bother Fisher, who made much of the invertibility of the quantity—the so-called pivotal quantity—on which the fiducial inference is based. For this reason he denied the validity of the method of confidence limits (Reference Fisher1956, 65–66).) If f is the observed relative frequency of C's in our sample, then r is between
 $r^{*}_{l}=U^{-1}(f) $
and
 $r^{*}_{u}=L^{-1}(f) $
if and only if f is between
 $L(r) $
and
 $U(r) $
. We adopt the conservative minimum or maximum if we hit a point of discontinuity.
The proportion [0.95, 1.0] can give rise to a probability provided the three conditions mentioned earlier are satisfied: there is no interval conflicting with [0.95, 1.0] that is based on a subset of a distribution of which the distribution just described is a marginalization (rule 1); there is no subset of the set of N-membered samples that carries a conflicting interval for the conclusion (rule 2); and the cover of the set of intervals meeting the first two requirements is not properly included in [0.95, 1.0] (rule 3). We will now look at examples of how each of these conditions may be violated.
Suppose that the population of B's belongs to a collection of populations, within which we know something about the distribution of the proportion of C's, for example, that the proportion of C's,
 $r_{i}$
, is itself distributed according to the discrete density function
 $g(r_{i}) $
, where
 $0\leq g(r_{i}) \leq 1$
and
 $\sum_{i}g(r_{i}) =1$
. In this case, of course, we could condition on this prior density in order to obtain a posterior frequency for
 $U^{-1}(f) \leq r\leq L^{-1}(f) $
. If there are n possibilities for
 $r_{i}$
, this posterior frequency would be given by the sum

This expression yields a real number; if it is less than 0.95, it undermines [0.95, 1.0] by rule 1, conditioning; if it is in [0.95, 1.0] it defeats that interval by rule 3, strength. Of course in real life we do not know the exact distribution of the
 $r_{i}$
in the collection of populations of B's, so this calculation represents an idealization. What we might really have is a set of bounds on the distribution of the
 $r_{i}$
, and this set of bounds could yield, by means of calculations like that above, upper and lower bounds for the conditional frequency that
 $r\in [ U^{-1}(f) ,\,L^{-1}(f) ] $
. If these bounds conflict with [0.95, 1.0], then, since the interval [0.95, 1.0] is derived from the marginal distribution that takes account only of the sampling distribution, and ignores the prior density of the proportion, it is the conditioned density that determines the posterior distribution and thus the probability. But if our knowledge of prior distributions is vague, so that the upper and lower bounds include the confidence [
 $1-\alpha $
, 1] as a proper subinterval, the confidence interval analysis will hold by strength.
Can specificity undermine the confidence interval analysis? Yes. Suppose that the B's are kernels of corn in a railroad car, and that C is the set of cracked kernels. If the sample of N is taken from the upper surface of the corn in the car, we would not want to regard the sample as probably representative. But this is because it comes from a special subset of N-membered samples in which we know that cracked kernels have lower likelihood of appearing than in N membered samples in general. In this case, specificity rules out our confidence interval analysis. Note that it is not the mere existence of a more specific reference class that undermines the confidence interval inference, but the fact that we have grounds for assigning a measure conflicting with [0.95, 1.0] to the conclusion.
We claim that the confidence interval analysis involves no prior assumptions. It is often stated that the validity of this inference depends on the sampling hypothesis that each possible sample have the same chance (frequency probability) of being selected: that the sample be “random” or “selected at random.” This is itself a statistical hypothesis. It is one that we may sometimes (rarely!) have reason to believe—for example, if the population is numbered, and the sample is obtained by means of a table of random numbers. But this is not good enough. On rare occasions the sample may be patently unsuitable for our inferential purposes, even though it has been chosen strictly at random. For example, in a study of plumage, the set of birds in our sample may, by sheer bad luck, all turn out to be female. But we know that plumage is sex linked, so that we have grounds for thinking it unrepresentative.
Generally, we have no reason at all to accept the random sampling hypothesis and good reason to reject it. We are often sampling a population widely distributed in space and time, and the sampling method is such as to pick a sample near to our own space and time. What counts is whether we have reason to believe that the sample is less (or more) representative of the distribution of the characteristic we are seeking information about. This, of course, is just to ask that the second criterion, specificity, not be violated.
The most common application of confidence interval analysis—physical measurement—takes for granted an approximate distribution, the distribution of error. In an extraordinarily influential article about weighing potatoes, Savage et al. (Reference Savage, Edwards and Lindeman1963) make the case that the particular prior subjective distribution of weight one brings to a measurement problem doesn't ordinarily matter very much. One supposes that the error of measurement is approximately normally distributed with a mean of about zero; whatever your prior opinion about the weight of a potato, within reason, your posterior opinion after weighing it will be quite precise.
Our analysis agrees. If the prior frequency distribution is vague enough, conditioning on it will simply yield a probability interval that is less precise than the interval resulting from the assumed approximate normal distribution of error, and thus may be ruled out. It is not that conditioning on your prior distribution for the weight of the potato yields a result that is swamped by the result of measurement, but that this prior distribution is so vague as to be eliminated on grounds of strength. In terms of the present analysis, the frequency distributions on which your prior probability is based will no longer be relevant (at all!) once the measurement has been made.
4.5. Updating by General Bayes Rule (Walley)
Evidential probability provides a useful framework for evaluating the interactions between Bayesian conditioning and classical error based statistical reasoning, given that our interest is not in reflecting actual or idealized degrees of belief, but in establishing constraints to which the vague notion of belief should conform. We have generalized Bayesian conditioning slightly by means of the assumption that there is a set of prior frequency distributions that we should take account of, rather than a single precise distribution. Note that we have not even assumed that the set of prior distributions is convex in the sense of containing the mixture of any two distributions it contains.
Walley's (Reference Walley1991) approach to statistical inference is, like the approaches of Ramsey and De Finetti, belief based. But like C. A. B. Smith (Reference Smith1961, Reference Smith1965), Walley does not assume that beliefs come in precise real-valued “degrees.”
The basic quantities in this approach are lower previsions, or lower expectations,
 $\underline{P}$
; these correspond roughly to lower probabilities. How about updating? Walley introduces the notion of a conditional prevision,
 $\underline{P}(X\vert B) $
. This admits of two interpretations, one as a conditional reward: what you receive in case of X, provided B occurs, or as a commitment to your prevision of X in the case that you learn exactly B. The latter is what bears on inference. The connection between
 $\underline{P}$
and
 $\underline{P}(\cdot \vert B) $
is provided by the coherence. One way, among others, of proceeding after the observation of B is to adopt
 $\underline{P}(\cdot \vert B) $
as our new prevision
 $\underline{P}^{B}$
. If we do this, then we have updated our beliefs according to the generalized Bayes’ rule. Although not all coherent models are lower envelopes of standard Bayesian models, a “posterior class of linear [
 $\underline{P}=\overline{P}$
] previsions can be constructed by applying Bayes’ rule to update the extreme points of
 $\mathstrut{\cal M} (P) $
[the set of linear previsions]” (Walley Reference Walley1991, 403). This and the application of the generalized Bayes’ rule are “mathematically equivalent.”
We have seen how evidential probability accommodates Bayesian conditioning only when the joint distribution underlying the conditioning has a relative frequency justification in the sense that we have reason to accept that the joint distribution holds in the real world. Since the general Bayes’ rule is mathematically equivalent to the application of conditioning to extreme points of
 $\mathstrut{\cal P} $
, if lower previsions are based on our knowledge of frequencies, the same principles will adjudicate between it and classical error statistics, when there is conflict.
5. Inference and Belief—Semantic Justification
The major conflict between conditioning—even the general form of conditioning described by Walley—and classical statistical inference lies in the fact that adherents of conditioning admit as inference only deductive inference. This applies as well to Walley's theory of previsions: the natural extension of a prevision is its deductive propagation in the set of gambles. It is perfectly clear that we cannot get along with only deduction; Walley, for example, talks about “observation”; most Bayesians talk about “evidence” on which to condition new beliefs; many people talk about “background knowledge.” As Levi has pointed out, there are many ways, other than deduction, in which items can be added to your store of facts.
Although it is common in science to use statistical inference to arrive at new conclusions, both explicitly (subjecting psychological hypotheses to test, testing the efficacy of drugs) and implicitly (measuring physical quantities), many statisticians are embarrassed to talk about any “logic” other than classical deductive logic. Neyman (Reference Neyman1957), for example, preferred to talk about “inductive behavior, rather than inductive logic.”
One reason for this is that there is a classical justification for deduction: if the premises are true, the conclusion must be true. Every model of the premises is also a model of the conclusion. In the case of inductive inference, even if (as on the evidential view) the conclusion can be shown to be “highly probable” in the sense that its probability [p, q] has a lower bound p that is close to 1, we can ask for the connection between high probability and truth.
In this section we shall show that the set of finite models of our language that render our background knowledge true is related to evidential probability in the following way. If the probability of a statement S relative to K is the interval [p, q], then the proportion of those models of K that satisfy S lies between p and q. There is thus a connection between what is highly probable and what happens “for the most part.”
First let us specify the language. It is to be a first order logical language, with two sorts of variables, one for real numbers and one for empirical objects. The domain of empirical objects is to be finite, so that proportions are always well defined. The truth conditions for statements of the form
 $\ulcorner \% \overline{\eta }(\tau ,\,\rho ,\,p,\,q) \urcorner $
are just what you would expect: If
 $\overline{\eta }$
consists of n free variables, then the reference class for this statistical statement is the set of n-tuples that satisfy the formula ρ. The statement is true just in case the proportion of the set of n-tuples that satisfy ρ and also satisfy the target formula τ lies in the interval [p, q].
For example, let “L” stand for “is apparently longer than.” Then a plausible principle from the theory of measurement is that if x is apparently longer than y and y is apparently longer than z, then almost always x will be apparently longer than z. We represent this by the formula “
 $\% \langle x,\,y,\,z\rangle (L(x,\,z) ,\,L(x,\,y) \wedge L(y,\,z) ,\,0.99,\,1.0) $
,” which will be true just in case at least 99% of the triples x, y, z for which “
 $L(x,\,y) \wedge L(y,\,z) $
” is true are triples in which “
 $L(x,\,z) $
” is true. (Note that the variable y has no occurrence in the target formula “
 $L(x,\,z) $
.”)
Consider a particular sentence S of our language whose probability is [p, q]. In the simplest case there is a single reference class that gives rise to the probability of S. Let K be the body of knowledge and data relative to which we obtain this probability. There must be a variable free term α and formulas τ and ρ such that
1.
 $\ulcorner S\equiv \tau (\alpha) \urcorner $
is in K,
2.
$\ulcorner \% \overline{\eta }(\tau ,\,\rho ,\,p,\,q) \urcorner $
is in K, and3.
$\ulcorner \rho (\alpha) \urcorner $
is in K.


We claim that under any interpretation, the proportion of models of K that render S true lies between p and q.
The interpretation of the reference formula ρ will be a certain set of n-tuples from the finite (empirical) domain of our interpretation. (In the example, this is a certain set of triples ⌜〈x, y, z〉⌝; note that we may sample these triples and obtain a confidence interval for the relative frequency with which the first and third elements satisfy “
 $L(x,\,z) $
.”) We have stipulated that in every model of K, between p and q of these tuples will make the formula τ true (at least 99% of the triples ⌜〈x, y, z〉⌝ will make the formula “
 $L(x,\,z) $
” true). The variable assignment can be made independently of the interpretation of the term α. Therefore, the proportion of models of K in which ⌜τ(α)⌝ is true lies between p and q. In short, whenever the probability of S, relative to background and evidence K, is in the interval [p, q], the proportion of models (or worlds) making this background and evidence true in which ⌜τ-(α)⌝, or S, is also true lies in the interval [p, q].
This is subject to the constraint that the reference class be univocal. Of course, given the richness of our language, this will never be quite true. If the proportion of A's that are B's lies in [p, q] so does the proportion of singleton {A}'s that are singleton {B}'s. This need not bother us, since it is the same interval that is mentioned. What does concern us is the existence of statistical conflicts that are not adjudicated by our rules. Suppose that one bit of statistical knowledge gives rise to the interval [0.4, 0.6] and another bit of statistical knowledge gives rise to [0.5, 0.7], and neither rule 1 (conditioning) nor rule 2 (specificity) applies. Then the probability is the cover [0.4, 0.7], although that is not a frequency in any reference class. It turns out (Kyburg and Teng Reference Kyburg and Teng2001, 240, 241) that a sensible notion of partial validity nevertheless yields the result that the relevant proportion in the actual world lies between the upper and lower values of the interval cover. Probabilities reflect facts about the world, and these facts impose objective constraints on our statistical inferences.
If the probability [p, q] of S, relative to what we know is very close to 1 (i.e., if p is close to 1), then in almost every model of what we know S will be true; if the probability of T is very close to 0, then we will rarely be mistaken in taking T to be false.
6. Conclusion
We have claimed that evidential probability provides an objective framework for adjudicating conflicts within statistical inference—especially conflicts between classical and Bayesian inference. Furthermore, we have claimed that, subject to the determination in a given context of a level of “practical certainty,” the constraints on belief imposed by evidential probability are objective. There are still several issues to be faced.
Evidential and practical certainty. How high a probability is necessary for acceptance or full belief? Obviously that can't be answered in general. But in a given context it may make sense to reject hypotheses at the ∊ level: A probability of ∊ of being in error is, in that context, not worth bothering about.
 $1-\epsilon $
is thus the probability that corresponds to practical certainty in that context. As we have already suggested, evidence cannot plausibly be required to be absolutely certain. So how certain must the evidence be, relative to which you regard something as acceptably probable—i.e., so probable as to be “practically certain”? It seems clear that we should make greater demands on evidential acceptance than on practical acceptance. One suggestion (Kyburg Reference Kyburg and Savage1990) is to take the corresponding level to be
 $1-\epsilon / 2$
. This suggestion has the virtue of allowing any two evidential certainties to be conjoined as a practical certainty, and has the additional virtue of being systematic. An alternative would be to set the acceptance level for evidence to be
 $1-\epsilon / n$
; then n pieces of evidence could be conjoined in a single practical certainty.
Either procedure reduces the problem of a choice of a level of full belief for evidence to the level of full belief for practical certainty. People may not always agree on a level of practical certainty, and it isn't always clear how to adjudicate such differences. But if those differences can be adjudicated, differences in degrees of belief can be obviated.
The language. We have assumed that for our statistical purposes we employ a first order language with rich resources. We have already noted that the reference terms and the target terms must be constrained. If our language has rich resources, it can be used to define target classes and reference classes that we do not want to be concerned with. For example, take it for granted that about half of coin tosses land heads. Then we would like to take the probability of heads on the seventh toss to be about a half. The seventh toss is prime numbered, and the proportion of heads among tosses that are prime numbered or land heads is nearly one. But we do not want the set of tosses that are prime numbered or land heads to be a relevant subset of the set of coin tosses. A similar problem occurs in statistics itself, where what are called “relevant subsets” (Buehler Reference Buehler1959) can generate awkward problems.
We may well also want ‘meaning postulates’ such as ‘being longer-than is transitive’ to be part of our language. For these reasons, we need a principled and objective way of choosing between languages on the basis of a body of knowledge, such as that hinted at in Kyburg (Reference Kyburg and Savage1990). This is particularly important if we are to have an automatic procedure for applying evidential probability.
Background knowledge. The difficulties of choosing a language and deciding on a particular language are attenuated in real science, where a group of people concerned with a single subject matter tend to share large parts of their bodies of scientific knowledge. Where this requirement becomes more problematic is in areas that involve knowledge from several disciplines. We must be able not only to focus on a shared body of knowledge, but also, if we are to automate inference, to agree on a formalization.
Expectations. Just as evidential probabilities are intervals, so are the expectations defined on their basis. This has good consequences and bad ones. The good consequence is that since expectations turn out to be intervals anyway, there is less need to worry about a lack of cardinal utilities. The bad consequence is that decision theory has been developed for real-valued expectations, the classical rule being (roughly) to maximize expectation. But if expectation is interval-valued, this principle no can no longer be applied. We can say that an act whose interval expectation lies entirely above an alternative act should be preferred to it, but this hardly takes into account all the important possibilities. We need to expand our decision theory in fundamental ways.
Broad intervals. Another thing we need to worry about is whether, in realistic cases, we are forced to such broad intervals that the probabilities are not useful for inference or for computing expectations as a basis for decision. In some areas, such as insurance, in which the use of something close to evidential probability is common, this doesn't happen. But in general we will only be able to tell this when we have sizable bodies of knowledge expressed formally.
Evidential probability. Despite these questions, evidential probability has an important role to play where imprecise prior knowledge of conditional frequencies competes with the more precise error frequencies generated by classical statistics. Evidential probability can help when our statistical knowledge is both imprecise and varied, as it generally is.
It is important in general to seek objectivity in probabilistic knowledge: the probable should happen for the most part. It is important for epistemology, of course, unless one adopts a purely descriptive epistemology. But it is also important for science. Science seeks objectivity. To be sure, actual subjective beliefs, if they can play some sort of theoretical role in a rich enough theory of the mind, can be of interest. But in testing scientific hypotheses, in forming well founded opinions, and particularly in the development of artificial intelligence, objective probabilities are essential.