


1. INTRODUCTION
Discrete choice econometric models have been widely used in estimating models that involve discrete economic decision problems. When the economic decision is affected by fundamental macroeconomic or financial variables, many of which are known to show nonstationary characteristics, one may need to consider a discrete choice model with nonstationary explanatory variables. Examples of recent applications of this approach include Hu and Phillips (2004a, 2004b), where the authors estimate models of the federal fund rate targeting by the Federal Reserve and of overnight target rate adjustments by the Bank of Canada, respectively.
This paper studies a simple binary choice model in which the observable binary sequence yt is generated by

where sgn is the sign function (i.e., sgn(x) = 1 if x ≥ 0 and −1 otherwise), xt is a p-vector of I(1) observable explanatory variables, and ut is an unobservable variable whose distribution is unknown.
When the regressor xt and the error term ut in the binary choice model (1.1) are stationary (mostly assumed to be independent and identically distributed (i.i.d.)), and a parametric distribution of ut is assumed, it is well known that under regularity conditions the maximum likelihood estimator (MLE) of β0 is

-consistent and asymptotically normal. When the distribution of ut is not known, various semiparametric estimation methods have been proposed. See, for example, Horowitz (1998) for a survey of these developments and asymptotic properties of the various semiparametric estimators of β0 in (1.1) with i.i.d. variables.
The study of the nonstationary binary choice model is quite new. When the distribution function of ut is known and the true parameter β0 is different from zero, Park and Phillips (2000) show that the MLE of β0 converges at a rate of n1/4 and the limiting distribution of the MLE is a mixed normal. Hu and Phillips (2004b) extend Park and Phillips' nonstationary binary choice model to a multinomial setup and develop an asymptotic theory. When the true parameter β0 is zero, Guerre and Moon (2002) show that the MLE has a convergence rate of order n. When the distribution of ut in the nonstationary binary choice model is not known, very little is known about the asymptotic properties of the semiparametric estimators. Recently, Moon (2004) has shown that Manski's maximum score estimator (MSE) (see Manski, 1975, 1985) of β0 in model (1.1) is consistent but does not derive any consistency rate, a challenging issue in view of the history of this estimator in the i.i.d. framework. An additional concern with the MSE is that standard numerical routines cannot be used to compute the estimator which does not have a limit normal distribution, because of a discontinuous objective function. A standard solution to that issue is the smoothed maximum score estimator (SMSE) introduced in Horowitz (1992).
The main contribution of the paper is to find a convergence rate of the MSE and SMSE of the nonstationary binary choice model (1.1). As is well known, β0 is identified up to scale, and we focus on the estimation of its direction; that is, we restrict ourselves to parameters in the unit sphere to achieve identification. We find that, for such a normalization, the MSE and SMSE can be

-consistent at least, a surprisingly fast rate at first sight, which holds under fairly general conditions for the error term ut, allowing us in particular to relax standard exogeneity assumptions. This can be explained at an intuitive level by the fact that integrated covariates have an

divergence rate by a functional central limit theorem (FCLT) and dominate the error terms ut. Hence the latent variable yt* reduces to β0′xt asymptotically and the maximum score can detect departures from β0 within the inverse of the divergence rate

of the covariate. Another distinctive feature of the integrated framework is that the

-consistency rate of the MSE and the SMSE can be derived with similar techniques. This contrasts with the i.i.d. case where different methods are used to show that the exact convergence rates of the MSE and the SMSE are n1/3 and close to

, respectively (e.g., Kim and Pollard, 1990; Horowitz, 1993), which is slower than ours. Second, we compare the

-convergence rate of the semiparametric estimator to the convergence rate of the parametric MLE of the normalized parameter. In the parametric case where the error term has a fully specified distribution such as the standard normal or the logistic, the scale and direction of β0 are both identified. In such a framework where the parameters are not normalized, Park and Phillips (2000) have shown that the MLE rate is n1/4 with an asymptotic mixed normal distribution. We build on Park and Phillips (2000) to show that the MLE of the normalized β0 converges with a rate n3/4. Third, we discuss briefly how to apply our estimation method to a single-index model.
The paper is organized as follows. In Section 2, we introduce the regularity conditions assumed in the paper. In Section 3 we define the MSE and the SMSE. In Section 4 we present the main result on the lower bound of the convergence rate. In Section 5 we compare the main result with the i.i.d. semiparametric results and the Park and Phillips (2000) result. As an application, we also discuss how to apply the estimation method to a single-index model. Section 6 concludes the paper. The Appendix contains all the technical proofs. In what follows,

is the standard euclidean norm, so that the unit sphere

, which contains β0, is the set of β with ∥β∥ = 1. We use →p and ⇒ to denote convergence in probability and distribution, respectively.
2. ASSUMPTIONS
First, we introduce an assumption about the integrated explanatory variables xt. It corresponds to Assumption 1 of Park and Phillips (2000), except that these authors required r > 8.
Assumption X. Let xt = xt−1 + vt with x0 = 0 and where

, with Π(1) nonsingular and

. The innovations

are i.i.d. with mean 0 and E∥et∥r < ∞ for some r > 2, have a distribution that is absolutely continuous with respect to the Lebesgue measure, and have a characteristic function φe(t) that satisfies lim∥t∥→+∞∥t∥κφ(t) = 0 for some κ > 0.
Thanks to a multivariate strong approximation result due to Einhmal (1989) and using the Beveridge–Nelson decomposition of {xt}t≥1 as in Akonom (1993), one can reconstruct the variables jointly with a Brownian motion

with full-rank covariance matrix Σ such that

Because

, the exact order of

.
Next we introduce two different assumptions that deal with the tail behavior and dependence structure of the error term ut. The main results in Section 4 will be derived under each assumption.
Assumption U1. There exists a sequence rn ≤ Cn1/2−κ, for some C > 0 and κ in (0,½), such that max1≤t≤n|ut| = Op(rn).
Assumption U2. For all t, the distribution of |ut| given xt,xt−1,…, x1 only depends upon β0′xt, that is, P(|ut| < u|xt,xt−1,…, x1) = F(u;β0′xt), and ∫(1 − F(x; x)) dx < ∞.
Assumption U1 corresponds to Assumption 1(iii) in Moon (2004),

for some κ > 0, yielding that max1≤t≤n|ut| = Op(n1/(2+κ)) by the Markov inequality. The rate rn of Assumption U1 is such that max1≤t≤n|ut| = op(1)max1≤t≤n∥xt∥. Under Assumption U1, the distribution error term ut could depend upon time, being, for instance, affected by structural breaks. It also allows that ut can include some omitted stationary variables zt, that is, that

where

verify Assumption U1. As noted in Moon (2004), Assumption U1 does not impose any specific form for the conditional distribution of ut given {xt}t≥1, so that endogeneity and heteroskedasticity are possible.
Assumption U2 restricts the distribution of ut given xt,…, x1 to be time homogeneous. The error term ut can still depend upon the regressor xt, but only through the index β0′xt, allowing again for endogeneity and heteroskedasticity. For example, consider an error term ut = m(β0′xt) + s(β0′xt)ηt, where the i.i.d. ηt's are independent of the xt's. Notice that ut satisfies Assumption U2 as soon as ∫P(|m(x) + s(x)η| ≥ |x|) dx < ∞. By the triangular inequality, this holds provided ∫P(|m(x)| + s(x)|η| ≥ |x|) dx < ∞, a condition that relates the tails of ηt to the divergence rate of (|x| − |m(x)|)/s(x).
Notice that the two assumptions are not nested. The dependence of the ut's on the time index t and on the covariate xt is not restricted by Assumption U1, whereas it is under Assumption U2. On the other hand Assumption U2 sometimes allows fatter tails of the distribution of ut than under Assumption U1, and max1≤t≤n|ut| can diverge faster than

. For example, consider an i.i.d. ut that is independent of {xt}t≥1. Under Assumption U2, ut has finite first moment because

but the second moment of ut may not be finite, so that max1≤t≤n|ut| can diverge faster than

.
3. MAXIMUM SCORE AND SMOOTHED MAXIMUM SCORE ESTIMATORS
Our semiparametric estimation of β0 is based upon the SMSE proposed by Horowitz (1992). Define

(K(·) + 1)/2 is a cumulative distributive function, and hn > 0 is a bandwidth. Here K(x/hn) can be viewed as a suitable approximation of sgn(x). In the particular case of (K(x) + 1)/2 = 1(x > 0) that gives K(x) = sgn(x), Qn(β; hn) does not depend upon hn and is the objective function of the MSE, so that the MSE and SMSE can be studied in the same framework. For K(x) = sgn(x), we write

and then

is the maximum score estimator of Manski (1975). Our last assumption is about K(·) and hn Note that we allow for a diverging bandwidth, which must remain negligible with respect to the divergence rate

of the covariates xt.
Assumption K. The function (K(·) + 1)/2 from

is a cumulative distribution function with median

. The bandwidth sequence verifies n−1/2+κ/C ≤ hn ≤ Cn1/2−κ for some C > 1 and κ in (0,½].
As in Park and Phillips (2000), it is mathematically convenient to split

into a component

colinear to β0 and an orthogonal component α2. To this end, consider a rotation matrix R = (R1,R2) with R1 = β0. Set

so that

.
4. MAIN RESULTS
Moon (2004) establishes consistency of the MSE. The following theorem establishes consistency of the SMSE.
THEOREM 1. Under Assumptions X, K, and U1 or U2,

is a consistent estimator of β0.
The proof of Theorem 1 follows from suitable modifications of Moon (2004) to cope with the SMSE and is not reported here. We now give a preliminary result that is crucial to derive some lower bounds for the consistency rate of the MSE and SMSE. Define

This objective function is associated with the “idealistic” deterministic model yt = sgn(β0′xt), derived from (1.1) by removing the error term ut.
PROPOSITION 1. Assume that Assumptions X and K hold. Then, under Assumption U1,

Proposition 1 indicates that the error term ut of the auxiliary binary model (1.1) can be neglected when studying the smoothed score function Qn(β; hn). Indeed, under Assumption U1, the integrated covariates xt, 1 ≤ t ≤ n, diverge faster than the maximum of error terms max1≤t≤n|ut|, so that setting the ut's to 0 intuitively yields a suitable approximation

. That this still holds under Assumption U2 comes from the fact that the difference

can be bounded by an empirical mean of the nonlinear transformation of β′xt, which can be studied through local time limit results developed in Park and Phillips (1999, 2001). This gives the better order

for the uniform norm of

in Proposition 1. Proposition 1, together with suitable lower bounds for

given by Lemma 1 and Proposition 2 in the Appendix, shows that

is sensitive to small departures of β from β0. As a consequence, the next results show that the MSE and SMSE can achieve an

-rate under Assumption U2.
THEOREM 2. Assume that Assumptions X and K hold.

As a consequence, we immediately get the following corollary.
COROLLARY 3. Assume that Assumptions X, U2, and K hold with hn = h > 0. Then

is an

-consistent estimate of β0.
Remark 1. Note that Theorem 2 always gives a faster rate for

than for

. This is actually due to the spherical normalization that imposes that

. Indeed, because

by Theorem 1,

, so that

goes to 0 faster than

. However, such a result cannot be used in practice because

depends upon the unknown parameter β0. This means that the relevant rate from a statistical point of view is the rate derived for

, which is the slowest one as seen from the corollary.
Remark 2. Theorem 2 holds under rather weak conditions on the error terms ut of (1.1), which can depend on t and on the xt's. Moon (2004) has already noted that the usual error conditions of the i.i.d. setup can be relaxed for consistency in the presence of integrated covariates (see Theorem 1 in our paper). See also Chang and Park (2004) and de Jong (2002) for similar results in the context of nonlinear regression models with integrated covariates.
Remark 3. Smoothing does not seem to improve the convergence rates of the SMSE with respect to the MSE in Theorem 2. However, the rates given in Theorem 2 are only lower bounds, meaning that the MSE and SMSE can converge faster. In a simple setup we discuss the issue of the exact rate of the SMSE, whose limit behavior can be studied with a standard Taylor expansion of the objective function. To simplify the discussion, take h = 1 and assume that xt is bivariate, that β0′ = (1,0) = α0′ so that the rotation matrix in (3.2) is identity, and that xt = (x1t,x2t)′. We use an angular representation of β, β′ = (cos φ,sin φ). The first and second derivatives of the objective function with respect to φ are, because β′xt = x1t cos φ + x2t sin φ,

Let

be the SMSE of φ, so that a Taylor expansion gives

where βn is a unit vector of angle φn between

. Hence, if Q(2)(βn;1) = Q(2)(β0;1)(1 + op(1)) as could be expected from similar expansion in Park and Phillips (2000) and Chang and Park (2003),

Under Assumption U2, the limit behavior of these sums can be derived from Park and Phillips (1999, 2000, 2001). Introduce μ(x1) = E [yt|x1t = x1] = 1 − 2P(ut ≥ −x1), σ2(x1) = V [yt|x1t = x1] = 4P(ut ≥ −x1)P(ut < −x1), consider a Brownian motion B(·) independent of W′(·) = (W1(·),W2(·)), and let L1(·,r) be the local time of {W1(t)}t∈[0,r]. Then

where the first two terms correspond to a decomposition of Qn(1)(β0;1) given by yt = μ(x1t) + yt − μ(x1t). Hence, we expect that the distribution of

should be close to

which does not asymptotically vanish if ∫μ(x1)K′(x1) dx1 ≠ 0, in which case

is the exact rate of the

. On the other hand, ∫μ(x1)K′(x1) dx1 = 0 if the distribution of ut given x1t is symmetric, an assumption that is quite natural in the i.i.d. case. In this case, a faster rate is expected, which could be the MLE rate n−3/4. However, deriving such a rate would necessitate studying the first sum of (4.2), which writes as

with ∫f (x1) dx1 = 0, a case not covered by Park and Phillips (1999, 2000, 2001). Results showing that

can be found in Borodin and Ibragimov (1995) but are limited to the case of a random walk. Because x2t must be standardized by

, one can expect that

is of order n3/4, in which case the exact rate of the SMSE would be n3/4.
5. DISCUSSION
5.1. Comparison with i.i.d. Semiparametric Models
There are several remarks we would like to highlight when comparing our results to the i.i.d. case. First, we know that the convergence rates of the MSE and the SMSE in the i.i.d. binary choice model are n1/3 (Kim and Pollard, 1990) and close to

(Horowitz, 1992), respectively. When the regressors are nonstationary, according to our finding, the convergence rates of the MSE and the SMSE are faster than those of the i.i.d. binary choice model. This is due to the diverging nature of integrated covariates as discussed after Proposition 1. Second, note that the bandwidth of Corollary 3 is kept constant, which is different from the i.i.d. setting. Indeed, considering hn → ∞ as studied in Phillips and Park (1998) or hn → 0 as is usual in the i.i.d. setting will not improve the rate derived from Theorem 2(ii). Because the covariates diverge, taking a constant h means a certain selection of the observations, and the usefulness of a vanishing hn deserves further investigation.
5.2. Comparison with Parametric Nonstationary Binary Choice Model
In this section we compare the result in Theorem 2 and Corollary 3 with the asymptotic results of the parametric nonstationary binary choice model in Park and Phillips (2000). For this, we first summarize the main results in Park and Phillips. The parametric nonstationary binary choice model investigated by Park and Phillips is

where the regressor xt+1 is adapted to some filtration

, with respect to which the error term ηt is measurable. Given xt,…, x0, it is assumed that the error term ηt has a known standardized cumulative distribution function F, as, for instance, the standard normal (leading to the probit model) and the standard logistic (leading to the logit model). The covariate xt is integrated and obeys Assumption 1 in Park and Phillips, that is, Assumption X with r > 8. Also, following Park and Phillips, we assume that F satisfies Assumption 2 in Park and Phillips, which is used to derive the asymptotic distribution of the maximum likelihood (ML) estimator

. Finally, we assume that, as in the logit and probit cases, log F(x) and log(1 − F(x)) are concave to ensure uniqueness of the MLE and that θ0 ≠ 0. Let R be as in (3.2) and γ = (γ1,γ2′)′ = R′θ. Then, γ0 = ((θ0′θ0)1/2,0)′. Let

be the MLE of model (5.1). Denote

. According to Theorem 2 in Park and Phillips,

and

where MN denotes a mixed normal distribution with a random covariance matrix Q defined in equation (18) of Park and Phillips. This gives

We now turn to the comparison of estimation rates in the parametric and semiparametric binary models. Note that our semiparametric model uses a different identifying condition from the parametric model of Park and Phillips (2000). In Park and Phillips, it is assumed that ηt has a standardized conditional known distribution, whereas in model (1.1) the scale of the error term is unknown, so that it is assumed that β0 is in the unit sphere Sp, that is, that β0′ β0 = 1.1
The two identifying conditions can be related as follows. We have in (5.1) yt = sgn(θ0′xt − ηt) = sgn{[θ0′/(θ0′θ0)1/2]xt − [ηt /(θ0′θ0)1/2]}. Therefore, the inverse norm 1/(θ0′θ0)1/2 of θ0 in the binary model (5.1) can be interpreted as the unknown scaling parameter of the error term in the semiparametric specification (1.1).
Notice that the MLE of the normalized parameter θ0 /(θ0′θ0)1/2 is

. Premultiplying the rotating matrix R′, we write

. Comparing this to the notation in Section 3,

correspond to

in (3.2), respectively.
From (5.2), we have

. Therefore,

with probability approaching one. Define

, which are both Op(1). Because (1 + x)−1/2 = 1 − (x/2) + O(x2) and (1 + x)−2 = 1 − 2x + O(x2), we have

which leads to

Also, we have

, which leads to

Finally, from (5.3) and (5.4), we deduce that

Summarizing this gives the following theorem.
THEOREM 4. Assume Assumptions 1 and 2 in Park and Phillips (2000). Then, the

of the normalized parameter θ0 /(θ0′θ0)1/2 is n3/4-consistent, and its limit distribution is

This result complements Park and Phillips (2000) by showing that the MLE of the standardized direction θ0 /(θ0′θ0)1/2 converges with a rate n3/4, faster than the n1/4-consistency rate of

. This shows that (θ0′θ0)1/2 is difficult to estimate and slow down the MLE estimator. Indeed, the

converges with the slower rate n1/4.
In comparison with the MLE, the MSE of β0, which is comparable to θ0 /(θ0′θ0)1/2, converges with the

rate at least (see Corollary 3). However, this rate is derived under much weaker conditions than for the parametric specification of Park and Phillips.
5.3. Estimation of a Single-Index Model
In this section, we discuss briefly how to apply the MSE or SMSE estimation in the previous section to a nonstationary single-index model. In estimating a nonlinear nonstationary regression model, one critical problem is the curse of dimensionality of the nonstationary regressor, as it is in nonparametric statistics. Indeed, the p-dimensional Brownian motion W(t), which is the asymptotic counterpart of the nonstationary regressor xt in (2.1), is transient as soon as the dimension p is larger than three, and it has a slow logarithmic recurrence rate when p = 2. This prohibits accurate estimation of some parametric models. As a consequence, the existing studies on nonlinear modeling with integrated covariates are often limited to univariate explanatory variables; see for example, Park and Phillips (2001). A possible remedy to the curse of dimensionality is, as in nonparametrics, to consider index-based models. The parametric binary choice model of Park and Phillips (2000) can be interpreted as an index model with a known link function, as shown from their equation (3). See also Chang and Park (2003) and Hu and Phillips (2004a, 2004b).
Suppose that observations zt are generated by the following semiparametric single-index model:2
Notice that there is large literature on single-index models for stationary time series data. To mention an example of earlier work, Robinson (1982) investigated asymptotic properties of the Gaussian quasi maximum likelihood estimator of a censored Tobit model, which is a special case of the single-index model with a known link function, assuming general Gaussian stationary errors and stationary covariates. However, he assumes independence of the error and the covariates. We thank a referee for pointing us to Robinson's work.

In model (5.5), xt is a p-vector of an integrated process, εt is a stationary error, and G(·) is an unknown monotone link function that is assumed to be increasing. Again, we impose a normalization restriction β0′ β0 = 1 to ensure identification. Suppose that the goal is to estimate β0.
Assume that the link function G(x) diverges when |x| goes to infinity, so that the generalized inverse G−(y) = inf{x;G(x) ≥ y} is defined for all values of y. Now denote yt = sgn(zt). Then, by taking the sgn operator in (5.5), we transform the single-index model (5.5) into a binary model yt = sgn(G(β0′xt) + εt) = sgn(β0′xt + G−(εt)). Set G−(εt) = ut and assume that ut satisfies Assumption U1 or U2. Then, according to Corollary 3, the MSE or SMSE of β0 in the resulting binary model is

-consistent.
6. CONCLUSION
This paper studies estimation of the regression parameter of a semiparametric binary choice model with integrated regressors xt, t = 1,…, n, under a spherical normalization of the parameter. We show that the MSE and SMSE can achieve an

-consistency rate under fairly general conditions on the error terms ut, including the usual case of i.i.d. ut but relaxing standard exogeneity conditions. This carries over for the estimation of a single-index model, a specification that can be used to circumvent the curse of dimensionality resulting from integrated regressors. A key ingredient is the divergence of the xt's, a fact that contrasts with the standard i.i.d. case. Indeed, the integrated xt's are of order

by a FCLT, so that the error terms ut can be asymptotically neglected in the objective functions of the MSE and SMSE. Because β′xt is asymptotically sensitive to variations of β of magnitude

, the objective functions asymptotically detect departures from the true parameter β0 of order

and our estimators are

-consistent at least. Such a sketchy derivation suggests that finding consistency rates is possible for more general specification of the binary choice model, including, for instance, polynomial functions of the covariates in the regression. A discussion of the exact asymptotic behavior of the SMSE suggests that the SMSE can converge faster than

when the error term is symmetric given the covariate, a condition considered natural in the i.i.d. setup. However a formal derivation of such a result would necessitate extending the asymptotic theory of Park and Phillips (1999, 2001) for integrated processes; we leave this issue as a further research topic.
APPENDIX: Technical Proofs
To avoid notational burden, we sometimes abbreviate Qn(β) = Qn(Rα) into Qn(α), where R is from (3.2). In addition to the main statements given in the body of the paper, we will prove the following two intermediate results.
LEMMA 1. Let

be the objective function in (4.1). Define, under Assumption K,

. Then, under Assumption K,

, for any β in

, any z ≥ 0. Under Assumptions X and K,

.
PROPOSITION 2. Assume that Assumptions X and K hold and fix z ≥ 0 in Lemma 1. Let γn = max(rn,hn) under Assumption U1 and γn = 1 under Assumption U2. Define

, where ∥α2∥ is the euclidean norm of α2. Then, under Assumption U1 or U2, for any ε > 0 one can find a Cε such that, for any λ > 0,

.
A.1. Preliminary Results.
Define

. This gives, for all


We begin with a slight modification of Theorem 4 of Akonom (1993). Let

be a fixed vector and {bn}n≥1 {cn}n≥1 be two sequences of positive real numbers. Define

, and

.
LEMMA 2. Assume that n−1/2+κ/C ≤ bn ≤ Cn1/2−κ, 0 ≤ cn ≤ Cn1/2−κ for some C > 1 and κ in (0,½]. Let ζ be a fixed vector of

. Then under Assumption X, Nnx1,ζ(a,a + bn) = NnV1(a,a + bn)(1 + op(1)), Nnx1(a,a + bn) = NnV1(a,a + bn)(1 + op(1)), and

. Moreover, if bn = b > 0 for all n,

, for all κ′ > 0. If ftx1,ζ(·) = ftnx1,ζ(·) is the probability density function of

, then

The proof of Lemma 2 works by straightforward modifications of the arguments used in Akonom (1993) and is not reported here. The next two lemmas provide some useful consequences of Lemma 2.
LEMMA 3. Assume that Assumption X holds and let bn and cn be as in Lemma 2. Let

be a fixed vector, and a a fixed real number, and f (·) be a generalized Riemann integrable bounded function from

with ∫| f (x)| dx < ∞. Then

Proof of Lemma 3. Because f (·) is Rieman integrable in the generalized sense, one can, for any ε > 0, find

such that, using (A.2),

where

. Now (A.2) and

yield

This gives

for n large enough. Lemma 2 and (A.3) yield now, because I is finite,

where the last limit holds because the last limit of Lemma 2 holds jointly with respect to the di's, i = −I,…, I. Taking ε > 0 small enough in (A.3) shows that Lemma 3 is proved. █
LEMMA 4. Consider cn with n−1/2+κ/C ≤ cn ≤ Cn1/2−κ for some C > 0 and κ in (0,½], λ > 0 and z in

. Then

converges in distribution to

if cn → ∞ and, if cn = c > 0 for n large enough, to

(Recall that

is continuous with respect to (v,r) and, for a fixed v, increases with r; see, for example, Revuz and Yor (1999). The notation dL1(w,r), with w = 0 in the integrals in the preceding expression, indicates a Stieljes integral with respect to the increasing function L1(w,·).)
Proof of Lemma 4. Define, for any ε > 0,

which corresponds to the first item of the sum of Lemma 4, the study of the second being similar.
We first study each of the Sin's. Note that

We study Sin. The arguments of Theorem 2 in Akonom (1993) carry over and give

Now the change of variables

and the continuity of the local time yield

Consider now the case cn → +∞. A similar study for Sin yields, jointly for each finite subset of index i,

Therefore, for any integer number I > 0,

Observe now that

, so that, for each ε > 0, the sum

reduces to

with a high probability for Iε taken large enough. Taking ε small enough and the preceding limit distribution therefore give the result of the lemma when cn → ∞. The case cn = c can be dealt with similarly. █
LEMMA 5. Assume that Assumption X holds. Let λ > 0 and z and M be some fixed nonnegative real number. For η > 0, let

where Z(λ,δ) is either equal to

Then, for any ε > 0, one can find an η = ηε > 0 small enough and a Cε > 0, independent of λ, such that P(Yη ≥ Cε) ≥ 1 − ε, for any λ ≥ 1.
Proof of Lemma 5. Because η > 0 can be taken small enough, it is sufficient to show that

where

. We shall show that P(Ω) > 0 is impossible because it would contradict the law of large numbers. Recall first that L1(0,·) is a positive measure carried by the infinite set {r ∈ [0,1];V1(r) = 0} (see Revuz and Yor, 1999). Moreover, integrals with respect to L1(0,·) are Stieljes integral almost surely. Recall also that {V1(r),V2(r)}r∈[0,1] is a full-rank process under Assumption X.
Note that (λ,δ) [map ] Z(λ,δ) is a continuous function that has a limit when λ → ∞. As a consequence, there is a

such that

. Consider now an ω ∈ Ω that is such that Z(λ*,δ*) = 0. Then, by the definition of Z(·,·), |δ′V2(r)| = 0 or |δ′V2(r) + (z/λ)|1{−δ′V2(r) > (z/λ)} + |δ′V2(r) − (z/λ)|1{−λδ′V2(r) < −(z/λ)} = 0, L1(0,·) almost everywhere. In any case, one can find an infinite random increasing sequence in {r ∈ [0,1];V1(r) = 0} ρk = ρk(ω) with δ*V2(ρk) being a constant. This gives for all K ≥ 1

for any ω ∈ Ω. Observe now that the (ρk − ρk−1)−1/2(V2(ρk) − V2(ρk−1)) are i.i.d.

, where Σ2 is the covariance matrix of V2 and is therefore of full rank. The strong law of large numbers therefore gives that δ*′(ω)Σ2δ*(ω) = 0 with δ*(ω) ∈ Sp−1 for almost all ω ∈ Ω, which is impossible unless (A.5) is true. █
7.2. Proof of Main Results.
Proof of Proposition 1. Define

and observe that because

, with x1t = β0′xt. Note that
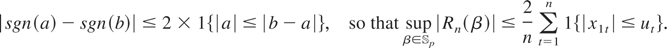
Consider first the case where Assumption U1 holds. Then, for M > 0 large enough,

, we have with a probability that can be made as close as wanted to 1

, by Lemma 3, taking f (x) = 1{|x| ≤ 1}, bn = cn = rn, ζ = 0, and a = 0.
Consider now the case where Assumption U2 holds. Define

which is such that at ≤ 2E [1{|x1t| ≤ |ut|}|xt] = 2P(|x1t| ≤ |ut||x1t) = 2(1 − F(|x1t|; x1t)), so that at = a(x1t) with ∫|a(x)|dx < ∞ under Assumption U2. We have by (A.6)

, where

. Notice that S1n = Op(1) by Lemma 3 and S2n is a martingale with quadratic variation

Applying the same Dambis, Dubins–Schwartz martingale construction as in Park and Phillips (2000, Lem. 3), yields that S2n = Op(n−1/4). █
Proof of Lemma 1. Let us begin with the first assertion of the lemma. Notice that sgn(K(β′xt /hn)) = sgn(β′xt) because the median of the cumulative distribution function (K(·) + 1)/2 is 0 under Assumption K. Observe also that, recalling x1t = β0′xt, 1{sgn(x1t) = sgn(β′xt)} + 1{sgn(x1t) ≠ sgn(β′xt)} = 1. This gives

because |K(·)| ≤ 1 and by definition of k(z). For the second assertion of Lemma 1, note that

under Assumption K and by Lemma 3 (taking f (·) = |K(·)| − 1, bn = cn = hn, a = 0, and ζ = 0). █
Proof of Proposition 2. Define

and observe that the proposition is proved if we can find Cε > 0 with

Observe that, if δ = α2 /∥α2∥, we have for any α2 = ∥α2∥δ with ∥α2∥ ≥ γn n−1/2λ > 0,

Define

, which is then such that

. Consider now an η-covering of Sp−1, B(δj;η) = B(δj), j = 1,…, J with balls centered at δj and radius η, where η > 0 will be chosen small enough subsequently. We have

Consider first the first item of (A.8) and let Z(λ,δ) be as in Lemma 5. Because the convergence of Lemma 4 holds jointly with respect to the δj's, we have for λ ≥ 1,

Let us now study the second term of (A.8). The definition of

shows that, for any δ ∈ B(δj),

Choose M such that

is small for n large enough. Then applying Lemma 3 with f (x) = 1(|x| ≤ λM), bn = cn = γn ζ = 0, and a = 0 yields

Expressions (A.9) and (A.10) give (A.7) by Lemma 5, choosing η small enough. █
Proof of Theorem 2. We limit ourselves to the proof of the second assertion of the theorem assuming hn = 1, the other cases being exactly similar. Fix z ≥ 0 in Lemma 1 with k(z) > 0. Let

. Consider an arbitrary ε > 0 and the associated Cε/2 of Proposition 2. Then Proposition 1 and Lemma 1 show that one can take a λε > 0 large enough such that

Therefore, if

we have, by Lemma 1 and Propositions 1 and 2, lim infn→∞ P(En) ≥ 1 − ε.
The definition of En shows that, on En and because Qn(α0; hn) ≤ supα∈Sp;∥α2∥≤n−1/2λε Qn(α; hn),

so that

by the definition (3.1) of the SMSE. Therefore

, because lim infn→∞ P(En) can be made arbitrarily large. To obtain the second assertion of the theorem, note that, because

. Moreover, Theorem 1 implies that

because

is a consistent estimator of 1. █


