


1. INTRODUCTION
In the M/G/1 and the GI/M/1 models in statistical equilibrium, one typically finds first the probabilities at the times after a departure and the probabilities before an arrival, respectively, and one then uses these probabilities to find random-time probabilities (see, e.g., [Reference Gross and Harris7, Reference Kleinrock9, Reference Prabhu10]). For doing this, one normally uses Markov renewal theory (see, e.g., [Reference Ross11]). However, in [Reference Grassmann, Chen and Kashyap4], we suggested using Bayes' law instead. This gives much shorter derivations. In this article, this method will be explored further and generalized. In particular, we are looking at the M/G/1 queue and the GI/M/c queue, and in both cases, we allow arrival rates to depend on the number in the system. We also consider a tandem queue with the first line never starved, and the first server having a general service time. However, queuing networks are also amenable to embedded Markov chain analysis if only one service time has a general distribution and all other service and interarrival times are Markovian.
2. THE M/G/1 QUEUE
Consider the queue with Poisson arrivals, general service times, and one server, where the arrival rates λi depend on i, the number in the system. The service rate is denoted by μ. It is well known that πi, the probability of having i elements in system after a departure, can be found by using an embedded Markov chain [Reference Grassmann, Chen and Kashyap4]. In many practical applications, such as finding costs, one needs the random-time probabilities P i rather than the πi. However, as shown in [Reference Grassmann, Chen and Kashyap4], we have the following relation between P i and πi:

Since similar ideas are used later, we repeat the proof of (1). If, at time t, the system is in a statistical equilibrium, one has, following the arguments of Bayes' theorem,

As h → 0, P{i at t | arrival in (t, t + h)} converges to Q i, the probability of having i elements in the system before an arrival. As is shown for instance by [Reference Gross and Harris6], Q i = πi. This completes the proof of (1).
For all i with λi > 0, one finds from (1)

where

However, since we do not know the P j, we cannot use (3) to find U. However, one can interpret U as the factor that ensures that ∑i=0∞P i = 1. This requires that we know P i for all i. If we have a buffer of size N, such that λi = 0 for i ≥ N, then λN = πN = 0, and, unfortunately, (2) cannot be used to find P N, and neither can we find U by (3). However, we have an alternative formula for U, namely

To prove (4), note that U is really the throughput. This follows because P{arrival in (t, t + h)} = Uh + o(h) and because the probability of more than one arrival is o(h). Alternatively, we can invoke the PASTA principle. The throughput is both the unconditional arrival rate and the unconditional departure rate, which, in turn, implies that the expected time between departures is 1/U. On the other hand, the expected time between departures is 1/µ if, after the previous departure, there were elements in the system and 1/μ + 1/λ0 if the previous departure left the system empty. This completes the proof of (4).
Once U is obtained from (4), (2) can be used, except that for P N, one has

Hence, the problem of relating the departure time probabilities to the random-time probabilities is solved.
If the arrival rate is independent of i, λi = λ, then U = λ, and by (2), P i = πi. Also, in this case, (4) works out correctly.
In [Reference Gross and Harris7, p. 232], the following formula is given when λi = λ, i < N, and λi = 0, i ≥ N:

in agreement with (2) and (4). This shows that our result generalizes the one given in [Reference Gross and Harris7].
3. THE GI/M/c QUEUE
In this section we discuss the GI/M/c queue with balking; that is, we assume that arrivals join with probability q i, where i is the number in the system. An embedded Markov chain can be used to find the probabilities πi of having i elements in the system before an arrival. As earlier, the πi are also equal to the probabilities that a departure leaves i elements behind. To find the transition probabilities of the embedded Markov chain, one can apply randomization, similar to the methods used in [Reference Ferreira and Pacheco2–Reference Grassmann, Chen and Kashyap4].
In order to obtain a relation between πi and the random-time probabilities P i, we use a similar argument as earlier. For this, we again need the throughput U. Since the total probability that an arrival joins is ∑∞j=0q jπj, U = λ∑j=0∞q jπj. On the other hand, if μj = jμ for j < c and μj = cμ otherwise, then U = ∑j=1∞P jμj. This relation, which can be obtained by the same arguments as earlier means that “departures see time averages.” Applying Bayes' theorem now yields

and, consequently,

Using U = λ∑i=0∞q iπi, (5) allows us to find all P i once the πi are known.
As a check, consider the GI/M/1 queue with λi = λ. In this case, U = λ, and (5) yields P i = πi−1λ/μ, which matches with the formulas give in the literature (see, e.g., [Reference Jain, Mohanty and Böhm8, p. 196]). In [Reference Grassmann and Zhao5], an algorithm is given for finding both πi and P i, given constant interarrival times, using classical Markov renewal-type arguments. We used this algorithm to calculate πi and P i for some cases with c = 2. For instance, for λ = 1 and μ = 1, one finds from (5) that P 1 = π0, whereas P 2 = π1/2. Our calculations showed that P 1 = π0 = .490871, whereas P 2 = .202840, and π1 = 0.405680, which works out exactly. Similar results were obtained for other values of λ and μ as well.
As an example of a finite-size buffer, consider the E 2 /M/3 queue with a buffer size N = 6, λ = 2, and μ = 1. In this case, q i = 1 for i < N, and q i = 0 otherwise. We formulated this problem as a continuous-time Markov chain and solved it as such. This provided us with the joint distribution of the arrival phase and the number in the system and, from this, we obtained the P i and πi as follows. Notice that the third row is obtained by (5), which matches exactly row 1.

4. A TANDEM QUEUE
We are now looking at a tandem queue in which the first line is never starved. The first server has a general service time with rate μ1, whereas the second server has an exponential service time with rate μ2. There is a buffer of size N, but when the buffer is full, the first server is blocked. We want to find a relation between πi, the probability of having i elements in the second line immediately before an arrival from line 1, and P i, the random time probability of having i elements in line 2. In this case, the expected time between arrivals to line 2 becomes

This is because a service completion with the first server at a point in time when there are N − 1 elements in the second line causes the first server to block for a time 1/μ2. After that, it takes an expected time 1/μ1 for server 1 to complete service. The throughput U is the reciprocal of expected time between arrivals to line 2; that is,

The relation between P i and πi is similar to the one given in (5):

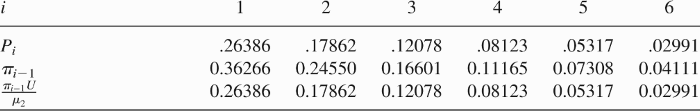
As an example, consider a tandem queue with μ1 = 0.75, μ2 = 1, and buffer size N = 6. The service times of the first server are Erlang-2. In this case, we found the values of P i and πi by a continuous-time Markov chain as follows. Again, the third row exactly matches the first row.
5. CONCLUSION
The approach presented here to link embedded Markov chain probabilities and random-time probabilities is simpler and numerically more efficient than the classical Markov renewal approach. To see this, we refer the reader to [Reference Chen1, Reference Gross and Harris7, Reference Jain, Mohanty and Böhm8]. There are many systems where an embedded Markov chain analysis is feasible. For instance, networks with all but one server having an exponential service time can be so analyzed, and in all these cases, the Baysian approach outlined in this article will work. Our method will also work in the case of the GI/M/c queue with heterogeneous server, a model analyzed in [Reference Grassmann and Zhao5] by Markov renewal methods. In some problems, it might be difficult to find the throughput, in which case one probability cannot be determined, and the others can only be obtained up to a factor. However, even in this case, our approach can be used as an accuracy check, and it provides useful insights.
Acknowledgments
This research was supported by the Natural Sciences and Engineering Research Council of Canada. We also thank the editor for his constructive remarks.


