


1. Introduction
Risk measures are widely used in both insurance and finance. Since the seminal work of Artzner et al. (Reference Artzner, Delbaen, Eber and Heath1999), classical risk measures are defined on univariate risks, that is, on random variables defined on some measurable space
 $(\Omega, \mathscr{F})$
. See, for instance, Föllmer and Schied (Reference Föllmer and Schied2002), Frittelli and Rosazza Gianin (Reference Frittelli and Rosazza Gianin2002). In practice, these classical risk measures usually require the acquirement of accurate distribution functions of the random variables. Mathematically, it equivalently requires an accurate probability measure on
 $(\Omega, \mathscr{F}),$
which is sometimes known as a reference measure or a scenario in the literature. For instance, value at risk (VaR) and expected shortfall (ES) are the cases, which are two standard risk measures popularly used in practice. It is also well known that the insurance premium principles have a close connection with risk measures. For instance, Wang et al. (Reference Wang, Young and Panjer1997) established a significant axiomatic approach to insurance pricing for univariate insurance risks, which is now known as distortion premium principles in the insurance literature. For more about risk measures for random variables, we refer to Föllmer and Schied (Reference Föllmer and Schied2016).
From the practical perspective, it is usually difficult to accurately capture the true distribution functions of random variables, because the distribution functions usually have to be estimated from dada (samples) or statistical hypothesis (simulation). Therefore, model uncertainty problem naturally arises. Model uncertainty issue could stem from Knightian uncertainty. See, for instance, Föllmer and Schied (Reference Föllmer and Schied2016, p. 5 and Section 4.2). Model uncertainty could have different disguises in different situations. However, it is worth mentioning that there are two natural and important approaches to deal with model uncertainty. One approach is to consider random variables on some measurable space
 $(\Omega, \mathscr{F})$
without assuming a reference measure (scenario) on it. See, for instance, Föllmer and Schied (Reference Föllmer and Schied2016, Sections 4.2 and 4.7). Such models are also called model-free models. See, for instance, Artzner et al. (Reference Artzner, Delbaen, Eber and Heath1999). Another approach is to consider multiple scenarios on
 $(\Omega, \mathscr{F})$
. See, for instance, Kou and Peng (Reference Kou and Peng2016, Section 3), Wang and Ziegel (Reference Wang and Ziegel2021), Fadina et al. (Reference Fadina, Liu and Wang2023) and the references therein. In the present paper, we will take into account model uncertainty. More precisely, we will follow the way of considering model-free models.
Besides dealing with stand-alone insurance risks separately, there is a strand of literature on dealing with multiple insurance risks as a whole. For instance, Yuen and Guo (Reference Yuen and Guo2001) studied ruin probabilities for two types of correlated claims. Yuen et al. (Reference Yuen, Guo and Wu2002) studied the ruin probability for the correlated aggregate claims. There have been studies about optimal multivariate reinsurance designs for multiple insurance risks. See, for instance, Denuit and Vermandele (Reference Denuit and Vermandele1998), Cai and Wei (Reference Cai and Wei2012), Cheung et al. (Reference Cheung, Sung and Yam2014), Zhu et al. (Reference Zhu, Chi and Weng2014) and the references therein. Mathematically, the random loss of an insurance risk faced by an insurer is described by a non-negative random variable defined on some measurable space
 $(\Omega, \mathscr{F}),$
which could be a claim or an aggregate of claims. Thus, the random losses of multiple insurance risks can be presented by a non-negative multidimensional random vector
 $\textbf{X} =(X_1, \ldots, X_d)$
defined on
 $(\Omega, \mathscr{F}).$
To assess the risk of a non-negative random vector
 $\textbf{X} =(X_1, \ldots, X_d),$
one traditional approach is to transform
 $\textbf{X} =(X_1, \ldots, X_d)$
into a random variable by using some aggregation procedure, for instance, using the sum of all components
 $X_i.$
Once the random vector
 $\textbf{X}$
has been transformed into a random variable, then classical univariate risk measures can be employed to quantify the risk. Another approach is to take into account the possible inter-dependence structure between the components of
 $\textbf{X}$
, and thus multivariate risk measures arises. Generally speaking, a (scalar) multivariate risk measure is to assign a random vector with a numerical value to quantify the risk of the random vector. See, for instance, Burgert and Rüschendorf (Reference Burgert and Rüschendorf2006, Reference Rüschendorf2013) and the references therein.
Burgert and Rüschendorf (Reference Burgert and Rüschendorf2006) axiomatically introduced and characterized the (scalar) multivariate coherent and convex risk measures for random vectors
 $\textbf{X} =(X_1, \ldots, X_d)$
defined on some probability space. For more related studies about multivariate risk measures, we refer to Rüschendorf (Reference Rüschendorf2006, Reference Rüschendorf2013), Ekeland and Schachermayer (Reference Ekeland and Schachermayer2011), Ekeland et al. (Reference Ekeland, Galichon and Henry2012), Wei and Hu (Reference Wei and Hu2014), Guillen et al. (Reference Guillen, Sarabia, Belles-Sampera and Prieto2018) and the references therein. As pointed by Burgert and Rüschendorf (Reference Burgert and Rüschendorf2006), a multivariate risk measure is to measure not only the risk of the components (i.e., marginals) of a random vector
 $\textbf{X}$
separately, but also to measure the joint risk of
 $\textbf{X}$
caused by the variation of the components and their possible inter-dependence. Thus, a natural and interesting question arises: how much risk could the joint risk of a random vector contribute? Motivated by the above observations, we focus on the evaluation of joint risk of non-negative random vectors. More precisely, we will establish and characterize a new class of multivariate risk measures to evaluate the joint risk, which we refer to as (scalar) distortion joint risk measures. Interestingly, it turns out that the resulting distortion joint risk measure has a connection with some vector-valued multivariate risk measures known in the literature; see Subsection 3.3 and Section 4 below. Therefore, we believe that distortion joint risk measures are worth studying.
By the Sklar’s Theorem, the inter-dependence structure of a random vector is determined by a (reference) probability measure on the measurable space
 $(\Omega, \mathscr{F})$
. Thus, model uncertainty can lead to inter-dependence uncertainty. In the present paper, we will make use of copula to describe the possible inter-dependence between the components of a random vector. In order to deal with the possible model uncertainty, we will work on the bounded random vectors on the measurable space
 $(\Omega, \mathscr{F})$
. For a model-free model
 $(\Omega, \mathscr{F})$
, the representations for univariate risk measures usually involve monotone set functions on
 $\mathscr{F}$
; see Föllmer and Schied (Reference Föllmer and Schied2016). Inspired by the above considerations, we will employ monotone set functions on the (multidimensional) measurable rectangles of the product
 $\sigma$
-algebra
 $\mathscr{F} \times \cdots \times \mathscr{F}$
to establish and characterize the distortion joint risk measures.
It should be mentioned that there have been many studies on vector-valued multivariate risk measures for multiple insurance risks. See, for instance, Cousin and Di Bernardino (Reference Cousin and Di Bernardino2013, Reference Cousin and Di Bernardino2014), Cossette et al. (Reference Cossette, Mailhot, Marceau and Mesfioui2013), Hürlimann (Reference Hürlimann2014), Di Bernardino et al. (Reference Di Bernardino, Fernandez-Ponce, Palacios-Rodriguez and Rodriguez-Grinolo2015), Maume-Deschamps et al. (Reference Maume-Deschamps, Rullière and Said2016), Landsman et al. (Reference Landsman, Makov and Shushi2016), Cai et al. (Reference Cai, Wang and Mao2017), Hermann et al. (2020), Shushi and Yao (Reference Shushi and Yao2020) and the references therein. For a random vector
 $\textbf{X} = (X_1, \ldots, X_d),$
a vector-valued multivariate risk measure is to respectively evaluate the risk of marginals
 $X_i$
in the context of
 $\textbf{X}.$
For instance, Cousin and Di Bernardino (Reference Cousin and Di Bernardino2013, Reference Cousin and Di Bernardino2014) studied vector-valued multivariate VaR and conditional-tail-expectation (CTE), respectively. Hürlimann (Reference Hürlimann2014) studied the properties of vector-valued VaR and CTE for Archimedean copulas. Landsman et al. (Reference Landsman, Makov and Shushi2016) studied vector-valued multivariate tail conditional expectation (TCE) for elliptical distributions. Cai et al. (Reference Cai, Wang and Mao2017) studied vector-valued multivariate tail distortion risk measures. In the present paper, we will also introduce a new class of vector-valued distortion joint risk measures for non-negative random vectors.
In this work, we focus on evaluating the joint risk of non-negative random vectors (i.e. for multiple insurance risks) under model uncertainty (i.e. under inter-dependence uncertainty). Inspired by the Nash utility function, we establish a joint risk measure to evaluate the joint risk of non-negative random vectors, which we refer to as a (scalar) distortion joint risk measure. Furthermore, we provide an axiomatic characterization of it by proposing a new set of axioms. Moreover, based on the resulting distortion joint risk measures, we propose a new class of vector-valued distortion joint risk measures for non-negative random vectors. Finally, we make comparisons with some existing vector-valued multivariate risk measures, such as vector-valued multivariate lower-orthant VaR and upper-orthant CTE, vector-valued multivariate TCE and vector-valued multivariate tail distortion risk measures. It turns out that those vector-valued multivariate risk measures have forms of vector-valued distortion joint risk measures, respectively. This paper mainly gives some theoretical results about the evaluation of joint risk under dependence uncertainty.
We would like to mention that the most relevant literature is the one by Guillen et al. (Reference Guillen, Sarabia, Belles-Sampera and Prieto2018). Guillen et al. (Reference Guillen, Sarabia, Belles-Sampera and Prieto2018, (5.1)) established an elegant distortion risk measure
 $\psi_{12\cdots d}[g\;:\;S_{12\cdots d}]$
for nonnegative multivariate risks. In this paper, we go further along this direction. First, instead of starting from certain distorted probability
 $g \circ P$
on the
 $\sigma$
-algebra
 $\mathscr{F}$
, we start from certain monotone set function on the (multidimensional) measurable rectangles of the product
 $\sigma$
-algebra
 $\mathscr{F}\times\cdots\times \mathscr{F}$
, so that we can deal with dependence uncertainty. Second, we establish and axiomatically characterize a new multivariate risk measure, which we refer to as a (scalar) distortion joint risk measure; see Definition 3.1 and Theorems 3.2 and 3.3 below. Third, we relate the resulting distortion joint risk measures to some existing vector-valued multivariate risk measures; see Subsection 3.3 and Section 4 below. For more details about the connection with the study of Guillen et al. (Reference Guillen, Sarabia, Belles-Sampera and Prieto2018), see the discussions after Definition 3.1 below. Taking the above considerations into account, this study could be viewed as a meaningful complement to the study of Guillen et al. (Reference Guillen, Sarabia, Belles-Sampera and Prieto2018).
The rest of this paper is organized as follows. In Section 2, we provide preliminaries. Section 3 is devoted to the statements of the main results. In the first subsection, we introduce some new axioms for joint risk measures, as well as financial interpretations. In the second subsection, we establish (scalar) distortion joint risk measures, and axiomatically characterize them. In the third subsection, we construct vector-valued distortion joint risk measures, and study their fundamental properties. In Section 4, comparisons with some known vector-valued risk measures are made. Concluding remarks are summarized in Section 5. In the appendix, we provide the proofs of all main results of this paper. For the sake of self-content, we address relevant issues in the appendix.
2. Preliminaries
Let
 $(\Omega, \mathscr{F})$
be a measurable space, and P a fixed probability measure on it, acting as a reference measure, which is also known as a scenario in some literature. See, for instance, Kou and Peng (Reference Kou and Peng2016, Section 3), Wang and Ziegel (Reference Wang and Ziegel2021) and Fadina et al. (Reference Fadina, Liu and Wang2023). We denote by
 $\mathscr{X}$
the linear space of all bounded measurable functions (i.e. random variables) on
 $(\Omega, \mathscr{F})$
equipped with the supremum norm
 $\|\cdot\|$
, and by
 $\mathscr{X}_+$
the subset of
 $\mathscr{X}$
consisting of those elements which are non-negative. To be consistent with the literature on risk measures under model uncertainty, we would like to concentrate on
 $\mathscr{X}$
rather than
 $L^\infty(\Omega, \mathscr{F}, P)$
of essentially bounded random variables on
 $(\Omega, \mathscr{F}, P)$
. See, for instance, Föllmer and Schied (Reference Föllmer and Schied2016, Sections 4.2 and 4.7), Kou and Peng (Reference Kou and Peng2016, Section 3) or Wang and Ziegel (Reference Wang and Ziegel2021). Let
 $d \geq 1$
be a fixed integer. We denote by
 $\mathscr{X}^d$
the space of all d-dimensional random vectors on
 $(\Omega, \mathscr{F})$
with each component (i.e. marginal) belonging to
 $\mathscr{X}$
, and by
 $\mathscr{X}^d_+$
the set of all d-dimensional random vectors on
 $(\Omega, \mathscr{F})$
with each component belonging to
 $\mathscr{X}_+.$
In the sequel, we will focus on joint risk measures on
 $\mathscr{X}^d_+.$
A random variable
 $X \in \mathscr{X}_+$
represents the random loss of an insurance risk faced by an insurer, for instance, it can be a claim or an aggregate of claims. Thus, a random vector
 $\textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+$
represents the random losses of d insurance risks, in which
 $X_i$
represents the random loss of the ith insurance risk. Although we concentrate on multiple insurance risks (i.e. on
 $\mathscr{X}^d_+$
), the resulting distortion joint risk measures are also applicable for multiple financial risks. Therefore, in the Appendix A.3, we will briefly make an address about general random vectors (i.e.
 $\mathscr{X}^d$
), in which a random variable
 $X \in \mathscr{X}$
represents the random loss of a financial position.
Generally speaking, a risk measure can be defined as any functional on
 $\mathscr{X}$
(or
 $\mathscr{X}_+$
). Suppose that
 $\mu$
is a normalized and monotone set function from
 $\mathscr{F}$
to [0,1], that is,
 $\mu(\emptyset) = 0,$
 $\mu(\Omega)=1$
and
 $\mu(A) \leq \mu(B)$
for any
 $A, B \in \mathscr{F}$
with
 $A \subseteq B,$
where
 $\emptyset$
stands for the empty set. Then for
 $X\in \mathscr{X}$
, the Choquet integral
 $\int X d\mu$
of X with respect to
 $\mu$
is defined by
 $$ \int X d\mu \;:\!=\; \int_{-\infty}^0[\mu(X{\,\gt\,} x)-1]dx+\int_0^{\infty}\mu(X{\,\gt\,} x)dx.$$
It is well known that distortion risk measures have a close connection with the Choquet integral. Given a non-decreasing function
 $g \;:\; [0,1] \rightarrow [0,1]$
with
 $g(0)=0$
and
 $g(1)=1$
, the distortion risk measure
 $\rho_g \;:\; \mathscr{X} \rightarrow \mathbb{R}$
is defined by
 \begin{align*} \rho_g(X)\;:\!=\; \int_{-\infty}^0 \left[ g(P(X {\,\gt\,} x))-1 \right]dx + \int_0^{+\infty} g(P(X {\,\gt\,} x)) dx, \quad X \in \mathscr{X}.\end{align*}
Such a function g is called a distortion function, and the composition
 $g \circ P$
of g and P is called a distorted probability. It is well known that the family of distortion risk measures includes VaR and ES. See, for instance, Föllmer and Schied (Reference Föllmer and Schied2016) or Wang and Ziegel (Reference Wang and Ziegel2021).
Let
 $\mathscr{S}$
be the set of all d-dimensional measurable rectangles of the product
 $\sigma$
-algebra
 $\mathscr{F}^d \;:\!=\; \mathscr{F} \times \cdots \times \mathscr{F},$
that is,
 $\mathscr{S} \;:\!=\; \{ A_1 \times \cdots \times A_d \;:\; A_i \in \mathscr{F}, 1\leq i\leq d \}$
. A mapping
 $\mu\;:\; \mathscr{S} \rightarrow [0, +\infty) $
is called a set function on
 $\mathscr{S}$
, if
 $\mu(\boldsymbol{ \emptyset } ) = 0, $
where
 $ \boldsymbol{\emptyset } \;:\!=\; A_1 \times \cdots \times A_d \in \mathscr{S} $
with some
 $A_i$
being an empty set. Given a set function
 $\mu$
on
 $\mathscr{S}$
, for
 $\textbf{A} = A_1 \times \cdots \times A_d \in \mathscr{S},$
we also write
 $\mu ( A_1 \times \cdots \times A_d)$
for
 $\mu(\textbf{A})$
if the emphasis is on
 $A_i, 1 \leq i \leq d.$
A set function
 $\mu$
on
 $\mathscr{S}$
is called normalized if
 $\mu (\Omega \times \cdots \times \Omega) = 1$
, and monotone if
 $ \mu (\textbf{A}) \leq \mu (\textbf{B})$
for all
 $\textbf{A} = A_1 \times \cdots \times A_d,$
 $\textbf{B} = B_1 \times \cdots \times B_d \in \mathscr{S} $
with
 $A_i \subseteq B_i, 1 \leq i \leq d.$
For a sequence of sets
 $ \{ \textbf{D}^{(n)} = D^{(n)}_1 \times \cdots \times D^{(n)}_d \in \mathscr{S};\; n \geq 1 \}$
and
 $\textbf{D} = D_1 \times \cdots \times D_d \in \mathscr{S},$
we say that the sequence of sets
 $ \{ \textbf{D}^{(n)};\; n \geq 1 \}$
increases to
 $\textbf{D}$
, if for any
 $n \geq 1,$
 $ D^{(n)}_i \subseteq D^{(n+1)}_i \subseteq D_i$
and
 $ \underset{n \rightarrow +\infty}{\lim} D^{(n)}_i = D_i$
for each
 $1 \leq i \leq d.$
In this situation, we write
 $ \textbf{D}^{(n)}\uparrow \textbf{D}.$
A set function
 $\mu$
on
 $\mathscr{S}$
is called continuous from below if
 $\underset{n \rightarrow +\infty}{\lim} \mu(\textbf{D}^{(n)})=\mu(\textbf{D})$
for any sequence of sets
 $ \{ \textbf{D}^{(n)} \in \mathscr{S}$
;
 $n \geq 1 \}$
and
 $\textbf{D} \in \mathscr{S}$
with
 $\textbf{D}^{(n)} \uparrow \textbf{D}.$
Similar to d-variate functions, we can define the increment of any set function
 $\mu$
on
 $\mathscr{S}.$
To be precise, for any
 $\textbf{A} = A_1 \times \cdots \times A_d, \textbf{B} = B_1 \times \cdots \times B_d \in \mathscr{S} $
, the increment of
 $\mu$
from
 $\textbf{A}$
to
 $\textbf{B}$
is defined by
 \begin{align*} \Delta^{\textbf{B}}_{\textbf{A}} \mu \;:\!=\; \Delta_{\textbf{B},\textbf{A}} \mu \;:\!=\; \Delta^{(d)}_{B_d, A_d} \Delta^{(d-1)}_{B_{d-1}, A_{d-1}} \cdots \Delta^{(1)}_{B_1, A_1} \mu,\end{align*}
where for any set function
 $\nu \;:\; \mathscr{S} \rightarrow [0, +\infty),$
 \begin{align*}\Delta^{(i)}_{B_i, A_i} \nu(D_1, \ldots, D_d) & \;:\!=\; \nu(D_1 \times \cdots \times D_{i-1} \times B_i \times D_{i+1}\times \cdots\times D_d)\\[5pt] & \quad - \nu(D_1\times \cdots \times D_{i-1}\times A_i\times D_{i+1}\times \cdots\times D_d).\end{align*}
A set function
 $\mu$
on
 $\mathscr{S}$
is called d-monotone if
 $ \Delta_{\textbf{B}, \textbf{A}} \mu \geq 0$
for all
 $\textbf{A} = A_1 \times \cdots \times A_d, \textbf{B} = B_1 \times \cdots \times B_d \in \mathscr{S} $
with
 $A_i \subseteq B_i, 1 \leq i \leq d.$
Note that the d-monotonicity of a set function implies the monotonicity, but the converse may not be true.
For
 $\textbf{X}= (X_1,\ldots,X_d) \in \mathscr{X}^d$
, denote by
 $ F_\textbf{X}(\textbf{x}) \;:\!=\; P(X_1\leq x_1,\ldots,X_d\leq x_d)$
and
 $ S_\textbf{X}(\textbf{x}) \;:\!=\; P(X_1{\,\gt\,}x_1,\ldots,X_d{\,\gt\,}x_d),$
 $\textbf{x}= (x_1,\ldots,x_d) \in \mathbb{R}^d,$
the joint distribution and joint survival functions of
 $\textbf{X}$
under P, respectively. Similarly, given a d-monotone and continuous from below set function
 $\mu\;:\; \mathscr{S} \rightarrow [0, +\infty)$
, the distribution function of
 $\textbf{X}$
with respect to
 $\mu$
, denoted by
 $F_{\mu,\textbf{X}}$
, is defined by
 \begin{align*} F_{\mu, \textbf{X}}(\textbf{x}) \;:\!=\; \mu (\{X_1 \leq x_1\} \times \cdots \times \{X_d \leq x_d\}), \quad \textbf{x}=(x_1,\ldots,x_d) \in \mathbb{R}^d,\end{align*}
and the survival function of
 $\textbf{X}$
with respect to
 $\mu$
, denoted by
 $S_{\mu,\textbf{X}}$
, is defined by
 \begin{align*} S_{\mu, \textbf{X}}(\textbf{x}) \;:\!=\; \mu (\{X_1 {\,\gt\,} x_1\} \times \cdots \times \{X_d {\,\gt\,} x_d \}), \quad \textbf{x}=(x_1,\ldots,x_d) \in \mathbb{R}^d.\end{align*}
Next, we recall the definitions of sub-copula and copula. For more details, we refer to Nelsen (Reference Nelsen2006).
Definition 2.1. Denote by
 $\mathscr{B}([0,1])$
the Borel algebra of Borel subsets of [0,1]. Given
 $A_i \in \mathscr{B}([0,1])$
,
 $1 \leq i \leq d,$
with
 $ 0,1 \in A_i$
. A function
 $C\;:\; A_1\times \cdots \times A_d \rightarrow [0,1]$
is called a sub-copula if it satisfies the following three properties: (i)
 $C(x_1,\ldots,x_d)=0$
, if there is an
 $i \in \{1,\ldots,d\}$
such that
 $x_i=0$
. (ii)
 $C(1,\ldots,1,x_i,1,\ldots,1)= x_i$
,
 $1\leq i\leq d$
. (iii) C is d-monotone, that is,
 $ \Delta_{\textbf{b}, \textbf{a}} C \geq 0$
for any
 $\textbf{a},\textbf{b} \in A_1\times \cdots \times A_d$
with
 $\textbf{a} \leq \textbf{b}$
. Furthermore, if
 $A_i=[0,1]$
,
 $1\leq i\leq d,$
then the sub-copula is called a copula.
Note that in the above definition,
 $ \Delta_{\textbf{b}, \textbf{a}} C $
stands for the increment of C on the interval
 $[\textbf{a}, \textbf{b}],$
see also Appendix A.2 for its definition. Denote by
 $\mathscr{C}$
the set of all copulas on
 $[0,1]^d$
.
By the Sklar’s Theorem, for any random vector
 $\textbf{X}$
 $=$
 $(X_1, \ldots, X_d) \in \mathscr{X}^d,$
there exists a copula C such that
 \begin{align*} F_\textbf{X}(x_1,\ldots,x_d)= C(F_{X_1}(x_1),\ldots,F_{X_d}(x_d)), \quad \ (x_1,\ldots,x_d)\in \mathbb{R}^d,\end{align*}
where
 $F_{X_i}(x_i)\;:\!=\; P(X_i \leq x_i), x_i \in \mathbb{R}$
, is the distribution function of
 ${X_i}$
under P,
 $1\leq i\leq d.$
In this case, we say that C is a copula for
 $\textbf{X},$
or that
 $\textbf{X}$
has a copula C. Furthermore, if
 $\textbf{X}$
is continuous, then the copula for
 $\textbf{X}$
is unique. Moreover, there exists a copula
 $\widehat{C}$
such that
 \begin{align*} S_\textbf{X}(x_1,\ldots,x_d)= \widehat{C}(S_{X_1}(x_1),\ldots,S_{X_d}(x_d)), \quad \ (x_1,\ldots,x_d)\in \mathbb{R}^d,\end{align*}
where
 $S_{X_i}\;:\!=\; 1- F_{X_i}$
is the survival function of
 ${X_i}$
under P,
 $1\leq i\leq d.$
Such a copula
 $\widehat{C}$
is called the survival copula for
 $\textbf{X}$
. Note that given a copula C for
 $\textbf{X},$
the survival copula
 $\widehat{C}$
can be given by
 $ \widehat{C} (u_1,\ldots,u_d) \;:\!=\; \Delta_{(1, \ldots, 1), (1-u_1, \ldots, 1-u_d)} C,$
see Nelsen (Reference Nelsen2006, p. 32) for the case of
 $d=2$
. In this situation, we also say that
 $\widehat{C}$
is associated with C. For more details, we refer to Nelsen (Reference Nelsen2006).
Given a normalized, d-monotone and continuous from below set function
 $\mu$
on
 $\mathscr{S}$
, we denote by
 $L_{\mu, \textbf{X}}$
the Lebesque–Stieltjes (L-S) measure induced by the survival function
 $S_{\mu,\textbf{X}}$
of a random vector
 $\textbf{X} \in \mathscr{X}^d$
with respect to
 $\mu,$
which is a probability measure on the Borel algebra
 $\mathscr{B}(\mathbb{R}^d)$
. For more details about
 $L_{\mu, \textbf{X}}$
, see Appendix A.2 or Denneberg (Reference Denneberg1994).
For convenience, we introduce more notations. Operations on
 $\mathscr{X}^d$
are understood in component-wise sense. Given a functional
 $\Gamma \;:\; \mathscr{X}^d \rightarrow \mathbb{R}$
, for
 $\textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d$
, we also write
 $\Gamma(X_1, \ldots, X_d)$
for
 $\Gamma(\textbf{X})$
if the emphasis is on
 $X_i, 1 \leq i \leq d.$
 $\Delta^{\textbf{Y}}_{\textbf{X}} \Gamma $
stands for the increment of
 $\Gamma$
from
 $\textbf{X}$
to
 $\textbf{Y}$
, see Appendix A.2 for its definition. For
 $a,b \in \mathbb{R}$
,
 $a \wedge b$
stands for
 $\min(a,b)$
.
 $\textbf{0}\;:\!=\; (0,\ldots,0)$
,
 $\textbf{1}\;:\!=\; (1,\ldots,1) \in \mathbb{R}^d$
. For
 $1\leq i\leq d,$
 $\textbf{e}_i \;:\!=\; (0,\ldots,0,1,0,\ldots,0)$
, where 1 occupies the ith coordinate, and
 $\bar{\textbf{e}}_i \;:\!=\; (1, \ldots, 1, 0, 1 \ldots, 1)$
, where 0 occupies the ith coordinate. For a non-empty set A,
 $1_A$
stands for the indicator function of A, while
 $1_{\emptyset} \;:\!=\; 0$
by convention. For a mapping h, Ran(h) stands for the range of h.
 $\mathbb{R}_+ \;:\!=\; \left[0,+\infty\right).$
 $ \mathbb{R}^d_+ \;:\!=\; [0, +\infty)^d, d \geq 1.$
Next, we recall the definition of comonotonicity. For more details about comonotonicity, we refer to Denneberg (Reference Denneberg1994) or Föllmer and Schied (Reference Föllmer and Schied2016).
Definition 2.2. Two random variables
 $X, Y \in \mathscr{X}$
are called comonotone, if
 $(X(\omega_1)-X(\omega_2))(Y(\omega_1)-Y(\omega_2)) \geq 0$
for every
 $\omega_1,\omega_2 \in \Omega$
. For any
 $\textbf{X} = (X_1,\ldots,X_d)$
,
 $\textbf{Y} = (Y_1,\ldots,Y_d) \in \mathscr{X}^d$
,
 $\textbf{X}$
and
 $\textbf{Y}$
are called comonotone if
 $X_i$
and
 $Y_i$
are comonotone for each
 $1 \leq i \leq d$
.
Remark 2.1. Two random variables X and Y are comonotone if and only if there exist continuous and non-decreasing functions
 $h_1, h_2$
on
 $\mathbb{R}$
such that
 $h_1(u)+h_2(u)=u$
,
 $u\in \mathbb{R}$
, and
 $X = h_1(X+Y), Y = h_2(X+Y)$
; or equivalently, there exist a random variable Z and non-decreasing functions
 $h_1, h_2$
on
 $\mathbb{R}$
such that
 $X = h_1(Z), Y = h_2(Z).$
See, for instance, Denneberg (Reference Denneberg1994, Proposition 4.5) or Föllmer and Schied (Reference Föllmer and Schied2016).
We end this section with two lemmas, which are crucial for this study. For the sake of self-content, their brief proofs will be provided in Appendix A.1.
Lemma 2.1. Let a random vector
 $\textbf{X}=(X_1,\ldots,X_d) \in \mathscr{X}^d_+$
have a copula C.
-
(1) If functions
 $g_1,\ldots,g_d$
are continuous and non-decreasing, then C is a copula for the random vector
$(g_1(X_1),\ldots,g_d(X_d)).$
-
(2) For any real numbers
$a_1,\ldots,a_d$
, C is a copula for the random vector
$(1_{\{X_1{\,\gt\,}a_1\}},\ldots,$
$1_{\{X_d{\,\gt\,}a_d\}}).$


Note that if the random vector
 $\textbf{X}=(X_1,\ldots,X_d)$
is continuous, and
 $g_1,\ldots,g_d$
are strictly increasing on Ran
 $(X_1)$
,
 $\ldots$
, Ran
 $(X_d)$
, respectively, then Lemma 2.1(1) is shown by Theorem 2.4.3 of Nelsen (Reference Nelsen2006).
Lemma 2.2. For each
 $1\leq i\leq d$
, let
 $n_i$
be a positive integer. Then for any integers
 $k_i,l_i \in \{ 1,\ldots,n_i\cdot 2^{n_i} \}$
,
 $1\leq i\leq d,$
and any
 $\textbf{X} = (X_1,\ldots,X_d) \in \mathscr{X}^d_+$
which has a copula C,
-
(1) the two random vectors
and
$$ \left(\sum\limits_{j_1=1}^{k_1} \left( X_1 \wedge \frac{j_1+1}{2^{n_1}} - X_1 \wedge \frac{j_1}{2^{n_1}}\right), \ldots, \sum\limits_{j_d=1}^{k_d} \left( X_d \wedge \frac{j_d+1}{2^{n_d}} - X_d \wedge \frac{j_d}{2^{n_d}}\right)\right)$$
are comonotone.
$$ \left(\sum\limits_{j_1=1}^{l_1} \left( X_1 \wedge \frac{j_1+1}{2^{n_1}} - X_1 \wedge \frac{j_1}{2^{n_1}}\right), \ldots, \sum\limits_{j_d=1}^{l_d} \left( X_d \wedge \frac{j_d+1}{2^{n_d}} - X_d \wedge \frac{j_d}{2^{n_d}}\right)\right)$$
-
(2) the random vectors
and
$$ \left(\sum\limits_{j_1=1}^{k_1} \left( X_1 \wedge \frac{j_1+1}{2^{n_1}} - X_1 \wedge \frac{j_1}{2^{n_1}} \right), \ldots, \sum\limits_{j_d=1}^{k_d} \left( X_d \wedge \frac{j_d+1}{2^{n_d}} - X_d \wedge \frac{j_d}{2^{n_d}}\right)\right)$$
$( Y_1, \ldots, Y_d )$
are comonotone, where one of the components of
$( Y_1, \ldots, Y_d )$
, say
$Y_l$
, equals to
$( X_l \wedge \frac{k_l+1}{2^{n_l}} - X_l \wedge \frac{k_l}{2^{n_l}} )$
, and the others
$Y_i, i\neq l$
, equal to
$\sum_{j_i=1}^{k_i} ( X_i \wedge \frac{j_i+1}{2^{n_i}} - X_i \wedge \frac{j_i}{2^{n_i}} )$
, respectively.
-
(3) C is a copula for the following four random vectors:
\begin{align*} \left( {2^{n_1}}\cdot\left( X_1\wedge \frac{k_1+1}{2^{n_1}}- X_1\wedge \frac{k_1}{2^{n_1}}\right), \ldots, {2^{n_d}} \cdot \left(X_d\wedge \frac{k_d+1}{2^{n_d}}- X_d\wedge \frac{k_d}{2^{n_d}}\right) \right),\end{align*}
\begin{align*} \left( {2^{n_1}}\cdot\left( X_1\wedge \frac{k_1}{2^{n_1}}- X_1\wedge \frac{k_1-1}{2^{n_1}}\right), \ldots, {2^{n_d}} \cdot \left(X_d\wedge \frac{k_d}{2^{n_d}}- X_d\wedge \frac{k_d-1}{2^{n_d}}\right) \right),\end{align*}
\begin{align*}\left(X_1\wedge\left(n_1-\frac{1}{2^{n_1}}\right), \ldots, X_d\wedge\left(n_d-\frac{1}{2^{n_d}}\right)\right)\ \mbox{and}\ \left( 1_{\left\{X_1{\,\gt\,} \frac{k_1}{2^{n_1}}\right\}}, \ldots, 1_{\left\{X_d{\,\gt\,} \frac{k_d}{2^{n_d}}\right\}} \right).\end{align*}


3. Distortion joint risk measures
In the first subsection, we will introduce some axioms (i.e. properties) for joint risk measures for non-negative random vectors. In the second subsection, we will establish and axiomatically characterize (scalar) distortion joint risk measures for non-negative random vectors. The third subsection is devoted to the construction of a vector-valued distortion joint risk measure, as well as the study of its properties. For the sake of presenting the main results, the proofs of all main results of this section will be postponed to Appendix A.1.
3.1. Axioms for joint risk measures
In general, a (scalar) joint risk measure is defined as any functional
 $\tau\;:\; \mathscr{X}^d_+ \rightarrow \mathbb{R}_+$
. A joint risk measure
 $\tau$
is called normalized, if
 $\tau(\textbf{1}) = 1$
. For any
 $\textbf{X} \in \mathscr{X}^d_+$
, the quantity
 $\tau(\textbf{X})$
can be interpreted as either the minimal amount of liquidity requirement caused by the joint risk of
 $\textbf{X}$
or the minimal amount of financial resource that can cancel the joint risk of
 $\textbf{X}$
. Here, liquidity refers to the ability of an agent to make cash payments as they become due. See, for instance, Hull (Reference Hull2015). This interpretation of liquidity requirement is consistent with the interpretation of capital requirement for univariate risk measures. In fact, if
 $d = 1$
, then from the viewpoint of regulation, the liquidity requirement caused by the joint risk of an one-dimensional random vector can be naturally regarded as the capital requirement for the random variable.
Before we introduce some axioms for a joint risk measure, let us briefly explain some intuitive considerations. For a univariate risk measure, the positive homogeneity (PH) is one of the most important properties. The PH reflects a linear relationship between the changes of the random variable and the (minimal) capital requirement. Hence, we expect to take PH into account when we quantify the joint risk of a random vector, so that the resulting PH for a joint risk measure can be consistent with the PH for univariate risk measures. Since the Nash utility function is one of important ways of describing dependent interaction of multiple ingredients, we will try the Nash utility function to establish a joint risk measure to quantify the joint risk of a random vector. Recall that the Nash utility function
 $u \;:\; (0, +\infty)^d \rightarrow (0, +\infty)$
is defined by
 \begin{align*}u(\textbf{x}) \;:\!=\; x_1 \ldots x_d, \quad \quad \textbf{x} = (x_1, \ldots, x_d) \in (0, +\infty)^d.\end{align*}
Hence, inspired by the Nash utility function, the influence of change of each component of a random vector on the joint risk is supposed to be positively homogeneous. Therefore, the above considerations motivate the Axiom (A1) on component-wise PH below. Comonotone additivity (CA) is another important property for a univariate risk measure. It is natural to expect that CA could be incorporated into the evaluation of the joint risk of a random vector. Such a consideration combined with the Nash utility function suggests the Axiom (A3) on comonotone additivity below.
It should be mentioned that the Nash utility function is one way of describing the dependent interaction and the influence of change of each component of a random vector on the interaction. A more general utility function is the Cobb-Douglas utility function
 $u \;:\; (0, +\infty)^d \rightarrow (0, +\infty)$
, which is defined by
 \begin{align*}u(\textbf{x}) \;:\!=\; A x_1^{\alpha_1} \cdots x_d^{\alpha_d}, \quad \quad \textbf{x} = (x_1, \ldots, x_d) \in (0, +\infty)^d,\end{align*}
where
 $A, \alpha_1, \ldots, \alpha_d$
are positive constants. If the general Cobb–Douglas utility function would be considered, then the Axioms (A1) and (A3) below would be no longer valid, and hence should be modified accordingly. In this paper, since we make an attempt to quantify the joint risk of random vectors and to axiomatically characterize the resulting joint risk measures, for simplicity, we temporarily employ the simpler Nash utility function rather than the general Cobb-Douglas utility function. Although the Nash utility function is simpler than the Cobb-Douglas utility function, it is interesting that the resulting (scalar) distortion joint risk measure has a close connection with some existing vector-valued multivariate risk measures; see Subsection 3.3 and Section 4 below. However, it would be interesting to see relevant study worked out in the future, in which the general Cobb-Douglas utility function is in use. For more details about the Nash and Cobb-Douglas utility functions, we refer to Moulin (Reference Moulin1988) and Sher and Pinola (Reference Sher and Pinola1981).
Now, we list some axioms (i.e. properties) for any joint risk measure
 $\tau:$
 $ \mathscr{X}^d_+ \rightarrow$
 $ \mathbb{R}_+$
, which we will concern in the sequel.
-
(A1) Component-wise positive homogeneity:
$\tau ((c_1 X_1, \ldots, c_d X_d)) = c_1 \ldots c_d \tau(\textbf{X})$
for any
$c_1, \ldots, c_d \geq 0$
and any
$\textbf{X}= (X_1,\ldots,X_d) \in \mathscr{X}^d_+$
. -
(A2) Monotonicity:
$\tau(\textbf{X}) \leq \tau(\textbf{Y})$
for any
$\textbf{X}, \textbf{Y} \in \mathscr{X}^d_+$
with
$\textbf{X} \leq \textbf{Y}$
. -
(A3) Comonotone additivity:
$\tau(\textbf{X}+\textbf{Y}) = \underset{\textbf{Z}}{\sum} \tau(\textbf{Z})$
for any comonotone
$\textbf{X} = (X_1, \ldots, X_d)$
and
$\textbf{Y} = (Y_1, \ldots, Y_d) \in \mathscr{X}^d_+$
, where the summation is summed over the
$2^d$
random vectors
$\textbf{Z} = (Z_1, \ldots, Z_d)$
with
$Z_i$
being either
$X_i$
or
$Y_i$
for each
$1\leq i\leq d$
. -
(A4) Continuity from below:
$\underset{n \rightarrow +\infty}{\lim} \tau(\textbf{X}_n)=\tau(\textbf{X})$
for any
$\textbf{X} \in \mathscr{X}^d_+$
and any sequence of random vectors
$\{\textbf{X}_n;\; n \geq 1\}$
with
$\textbf{X}_n \in \mathscr{X}^d_+$
,
$n \geq 1$
, and
$\textbf{X}_n \uparrow \textbf{X}$
. -
(A5) d-monotonicity:
$\Delta_\textbf{X}^\textbf{Y} \tau \geq 0$
for any
$\textbf{X},$
$\textbf{Y}$
$\in \mathscr{X}^d_+$
with
$\textbf{X} \leq \textbf{Y}$
. -
(A6) Distribution invariance:
$\tau(\textbf{X})=\tau(\textbf{Y})$
for any random vectors
$\textbf{X}$
and
$\textbf{Y} \in \mathscr{X}^d_+$
with
$F_\textbf{X}=F_\textbf{Y}$
.


Remark 3.1. Both (A2) and (A3) imply (A1). For the sake of self-content, a brief proof of this remark is provided in Appendix A.1.
Before we interpret above axioms in the context of finance, we would like to make two comments on the Axiom (A1). First, from Axiom (A1), we can easily conclude that
 $\tau(\textbf{X}) = 0$
, whenever there is at least one component of
 $\textbf{X}=(X_1, \ldots, X_d)$
being zero. For simplicity and without loss of generality, we assume that
 $X_d = 0$
. Then
 $\tau ((X_1, \ldots, X_{d-1}, 0)) = 0$
. This conclusion means that in such a case, one only needs to concern the joint risk of the
 $(d-1)$
-dimensional random vector
 $(X_1, \ldots, X_{d-1})$
rather than that of
 $(X_1, \ldots, X_{d-1}, 0)$
, because adding a zero-valued random variable to the random vector
 $(X_1, \ldots, X_{d-1})$
undoubtedly does not change anything about the joint risk of
 $(X_1, \ldots, X_{d-1})$
. That is to say that the acting joint risk of
 $(X_1, \ldots, X_{d-1}, 0)$
is nothing else but just that of
 $(X_1, \ldots, X_{d-1})$
. Therefore, the joint risk of
 $(X_1, \ldots, X_{d-1}, 0)$
should be quantified by a joint risk measure
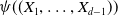 $\psi ((X_1, \ldots, X_{d-1}))$
of
 $(X_1, \ldots, X_{d-1})$
rather than the joint risk measure
 $\tau((X_1, \ldots, X_{d-1}, 0))$
itself, where the joint risk measure
 $\psi$
is defined on
 $\mathscr{X}^{d-1}_+$
rather than on
 $\mathscr{X}^d_+$
. This is also the main reason why we call the resulting multivariate risk measures joint risk measures rather than simply multivariate risk measures. In summary, when we evaluate the joint risk of a random vector
 $\textbf{X}$
, we should eliminate those zero-valued components of
 $\textbf{X}$
first and then evaluate the joint risk of the remaining l-dimensional random vector by using a joint risk measure defined on
 $\mathscr{X}^l_+$
,
 $1 \leq l \leq d$
. Second, the Axiom (A1) has essential distinction with the classical PH for multivariate risk measures. The classical PH states that for a multivariate risk measure
 $\rho:$
 $\mathscr{X}^d \rightarrow \mathbb{R}$
,
 \begin{align*}\rho(c\textbf{X}) \;:\!=\; \rho((cX_1, \ldots, cX_d)) = c \rho(\textbf{X}) \quad \mbox{for any} \ \textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d \ \mbox{and any} \ c \geq 0.\end{align*}
See, for instance, Burgert and Rüschendorf (Reference Burgert and Rüschendorf2006), Rüschendorf (Reference Rüschendorf2013) and Wei and Hu (Reference Wei and Hu2014). The classical PH reflects the impact of change of a random vector
 $\textbf{X}$
on the corresponding capital requirement, which reveals a linear relationship. In contrast to considering the capital requirement for a random vector
 $\textbf{X}$
as in the classical setting, we are now considering the liquidity requirement caused by the (possible) dependent interaction of the components of
 $\textbf{X}$
, and we assume the component-wise PH, which is inspired by the Nash utility function. The component-wise PH reflects the impact of change of each component of
 $\textbf{X}$
on the liquidity requirement caused by the joint risk of
 $\textbf{X}$
. The definition of the component-wise PH is consistent with the definition of the classical PH for univariate risk measures, because the liquidity requirement caused by the joint risk of an one-dimensional random vector can be naturally regarded as the capital requirement for the random variable. From the perspective of random vectors as a whole, the component-wise PH reveals a non-linear relationship between the changes of a random vector and the liquidity requirement caused by its joint risk. We argue that such a non-linear relationship should be, more or less, in accordance with intuition, because there could be a sort of endogenous incentive impact on the liquidity requirement regarding the dependent interaction of the joint risk, and such an endogenous incentive impact on the liquidity requirement might not necessarily be linear.
Now, we turn to the financial interpretations of the above axioms. The Axiom (A1) means that a linear change of each marginal would result in a same linear change of the corresponding liquidity requirement. The monotonicity says that a random vector with larger losses would yield a higher liquidity requirement. This axiom is totally similar to the classical monotonicity. Now we discuss the financial implication of the Axiom (A3). Given two random vectors
 $\textbf{X}= (X_1, \ldots, X_d),$
 $\textbf{Y} = (Y_1, \ldots, Y_d) \in \mathscr{X}^d_+$
, write
 $\textbf{Z} = (Z_1, \ldots, Z_d)$
, where
 $Z_i$
is either
 $X_i$
or
 $Y_i$
for each
 $1 \leq i \leq d$
. Then,
 $\textbf{Z}$
is considered as a sub-random-vector of the random vector
 $\textbf{X} + \textbf{Y}$
in the sense that there is a random vector
 $\textbf{W} = (W_1, \ldots, W_d)$
with
 $W_i$
being either
 $X_i$
or
 $Y_i$
,
 $1 \leq i \leq d$
, so that
 $\textbf{X} + \textbf{Y}$
 $ = $
 $\textbf{Z} + \textbf{W}$
. Hence, the Axiom (A3) says that spreading joint risk of
 $\textbf{X} + \textbf{Y}$
within comonotone sub-random-vectors can not reduce the total joint risk. When
 $d = 1$
, then the comonotone additivity (A3) reduces to the classical comonotone additivity for univariate risk measures. See, for instance, Denneberg (Reference Denneberg1994), Föllmer and Schied (Reference Föllmer and Schied2016) and Wang et al. (Reference Wang, Young and Panjer1997). Taking the above considerations into account, the comonotone additivity (A3) could also be viewed as a multivariate extension of the classical univariate setting. The Axiom (A4) is more or less due to the technical purpose. Nevertheless, it says that a small increment of any marginal of a random vector should not lead to a tremendous increment of the corresponding liquidity requirement. The Axiom (A5) is more or less a kind of technical condition, but it implies the monotonicity. The Axiom (A6) means that for two random vectors, if they have the same joint distribution function under the reference probability measure P, then their joint risks should be the same. This characteristic has some similarity to the law invariance in the classical setting, see Kusuoka (Reference Kusuoka2001), Föllmer and Schied (Reference Föllmer and Schied2016), Rüschendorf (Reference Rüschendorf2006, Reference Rüschendorf2013), and Wang et al. (Reference Wang, Young and Panjer1997).
3.2. Scalar distortion joint risk measures
In this subsection, we will establish and axiomatically characterize (scalar) distortion joint risk measures for non-negative random vectors. It is well known that the theory of risk measures has a close connection with the theory of expected utility. Motivated by the Nash utility function, for a random vector
 $\textbf{X} \in \mathscr{X}^d_+,$
we define the joint risk measure of
 $\textbf{X}$
by the expected utility with respect to the L-S measure
 $L_{\mu, \textbf{X}}$
induced by the survival function
 $S_{\mu, \textbf{X}}$
of
 $\textbf{X}$
with respect to certain pre-specified set function
 $\mu$
on
 $\mathscr{S},$
in which the utility function is chosen to be the Nash utility function. Hence, we come to the following definition of distortion joint risk measures.
Definition 3.1. Let
 $\mu\;:\; \mathscr{S} \rightarrow \mathbb{R}_+$
be a normalized, d-monotone and continuous from below set function. The distortion joint risk measure
 $\Gamma_{\mu}\;:\; \mathscr{X}^d_+ \rightarrow \mathbb{R}_+$
is defined by
 \begin{align} \Gamma_{\mu}(\textbf{X}) \;:\!=\; \int_{\mathbb{R}^d_+} x_1 \cdots x_d L_{\mu, \textbf{X}} (d x_1, \ldots, d x_d), \quad \textbf{X} \in \mathscr{X}^d_+.\end{align}
Notice that the distortion joint risk measure
 $\Gamma_{\mu}$
as in (3.1) also has the following expression, which we will often adopt in the sequel: for
 $\textbf{X}=(X_1,\ldots,X_d) \in \mathscr{X}^d_+,$
 \begin{align} \Gamma_{\mu}(\textbf{X}) = \int_0^{\infty}\cdots\int_0^{\infty} \mu(\{X_1{\,\gt\,}x_1\} \times \cdots \times \{X_d{\,\gt\,}x_d\}) dx_1\cdots dx_d.\end{align}
In fact, by the Fubini’s Theorem and the properties of
 $L_{\mu,\textbf{X}}$
, it is not hard to verify that (3.2) holds. By (3.2) we know that for any
 $\textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+$
, if
 $ \|X_i\| {\,\gt\,} 0$
,
 $1 \leq i \leq d,$
then a sufficient condition ensuring that
 $\Gamma_{\mu}(\textbf{X}) {\,\gt\,} 0$
is that
 $\mu (A) {\,\gt\,} 0$
for any non-empty
 $A \in \mathscr{S}.$
Notice also that when
 $d=1$
, define a normalized and monotone set function
 $\mu$
on
 $\mathscr{F}$
by
 $\mu(A)\;:\!=\; g(P(A))$
with some distortion function g, then
 $\Gamma_{\mu}$
reduces to
 \begin{align*} \Gamma_{\mu}(X)= \int_0^{+\infty} g(P(X{\,\gt\,}x)) dx, \quad X \in \mathscr{X}_+,\end{align*}
which is just the distortion risk measure
 $\rho_g$
for the non-negative random variable X. This is the main reason why the term distortion appears in the name of
 $\Gamma_{\mu}$
as in (3.1).
We would like to make one more comment on Definition 3.1. Let
 $\nu$
be a normalized and monotone set function on
 $\mathscr{S}$
. Similar to (3.2), we can define a functional (i.e. a joint risk measure)
 $\Gamma_{\nu}\;:\; \mathscr{X}^d_+ \rightarrow \mathbb{R}_+$
by
 \begin{align} \Gamma_{\nu}(\textbf{X}) \;:\!=\; \int_0^{\infty}\cdots\int_0^{\infty} \nu(\{X_1{\,\gt\,}x_1\} \times \cdots \times \{X_d{\,\gt\,}x_d\}) dx_1\cdots dx_d,\end{align}
 $\textbf{X}=(X_1,\ldots,X_d) \in \mathscr{X}^d_+$
. Let Q be an arbitrarily given reference measure (scenario) on
 $(\Omega, \mathscr{F}).$
Then we can define a normalized and monotone set function
 $\nu$
on
 $\mathscr{S}$
by
 \begin{align*}\nu(A_1 \times \cdots \times A_d) \;:\!=\; Q (A_1 \cdots A_d), \quad A_1 \times \cdots \times A_d \in \mathscr{S}.\end{align*}
Thus, the joint risk measure
 $\Gamma_{\nu} = \Gamma_{Q}$
given by (3.3) becomes
 \begin{align*} \Gamma_Q(\textbf{X}) = \int_0^{\infty}\cdots\int_0^{\infty} Q(X_1 {\,\gt\,} x_1, \ldots, X_d {\,\gt\,} x_d)) dx_1\cdots dx_d,\end{align*}
 $\textbf{X}=(X_1, \ldots, X_d) \in \mathscr{X}^d_+$
, which means that we can evaluate the joint risk of
 $\textbf{X}$
under different reference measures Q corresponding to plausible different inter-dependence of
 $X_i's.$
Furthermore, assume that g is a given distortion function. Then, we can define a normalized and monotone set function
 $\nu$
on
 $\mathscr{S}$
by
 \begin{align}\nu(A_1 \times \cdots \times A_d) \;:\!=\; g( Q (A_1 \cdots A_d)), \quad A_1 \times \cdots \times A_d \in \mathscr{S}.\end{align}
Thus, the joint risk measure
 $\Gamma_{\nu} = \Gamma_{g} $
given by (3.3) becomes
 \begin{align} \Gamma_{g}(\textbf{X}) = \int_0^{\infty}\cdots\int_0^{\infty} g(Q(X_1 {\,\gt\,} x_1, \ldots, X_d {\,\gt\,} x_d)) dx_1\cdots dx_d,\end{align}
 $\textbf{X}=(X_1, \ldots, X_d) \in \mathscr{X}^d_+$
, which coincides with the distortion risk measure
 $\psi_{12\cdots d}[g\;:\;S_{12\cdots d}]$
for nonnegative multivariate risks introduced by Guillen et al. (Reference Guillen, Sarabia, Belles-Sampera and Prieto2018, (5.1)). The joint risk measure
 $\Gamma_{g}$
given by (3.5) also corresponds to the special case of the multivariate distortion risk measure
 $\Psi_{\mu,g}$
introduced by Rüschendorf (Reference Rüschendorf2013, (8.54)), or
 $\Psi_{\mu}$
introduced by Rüschendorf (Reference Rüschendorf2006, (3.1)), when the measure
 $\mu$
on
 $\mathbb{R}^d_+$
there is set to be the Lebesque measure on
 $\mathbb{R}^d_+$
. Note that we have already provided a plausible interpretation for the joint risk measure
 $\Gamma_{\nu}$
given by (3.3), and hence for the joint risk measure
 $\Gamma_{g}$
given by (3.5). Therefore, we also provide a plausible alternative interpretation for the distortion risk measure
 $\psi_{12\cdots d}[g\;:\;S_{12\cdots d}]$
from the point of view of joint risk measure. However, since the monotone set function
 $\nu$
given by (3.4) might not be d-monotone and continuous from below, the joint risk measure
 $\Gamma_{g}$
given by (3.5) does not necessarily satisfy the Axiom (A3) due to Theorem 3.1 below. In order to axiomatically characterize the joint risk measure
 $\Gamma_{\nu}$
given by (3.3), we need extra conditions on the monotone set function
 $\nu$
, which are the d-monotonicity and the continuity from below of
 $\nu$
. Hence, to characterize
 $\Gamma_{\nu}$
given by (3.3) leads to extra assumptions imposed on the monotone set function on
 $\mathscr{S}$
as in Definition 3.1. For the axiomatic characterization of the distortion joint risk measure
 $\Gamma_{\mu}$
given by (3.2), see Theorems 3.2 and 3.3 below. Taking the above considerations into account, the present study of distortion joint risk measures could be viewed as a meaningful complement to the study of Guillen et al. (Reference Guillen, Sarabia, Belles-Sampera and Prieto2018).
Now, we are ready to state the main results of this subsection.
Theorem 3.1. Let
 $\mu$
be a normalized, d-monotone and continuous from below set function on
 $\mathscr{S}.$
Then, the distortion joint risk measure
 $\Gamma_{\mu}$
defined by (3.1) (or equivalently, as in (3.2)) is normalized, and satisfies the Axioms (A1)–(A5).
Next theorem provides an axiomatic characterization of
 $\Gamma_{\mu}$
as in (3.1) (or equivalently, as in (3.2)).
Theorem 3.2. Suppose that a normalized joint risk measure
 $\Gamma\;:\; \mathscr{X}^d_+ \rightarrow \mathbb{R}_+$
satisfies the Axioms (A1)–(A5). Then, there exists a normalized, d-monotone and continuous from below set function
 $\mu$
on
 $\mathscr{S}$
depending on
 $\Gamma,$
such that for any
 $\textbf{X}$
 $ = $
 $ (X_1, \ldots, X_d)$
 $ \in $
 $ \mathscr{X}^d_+$
,
 \begin{align} \Gamma(\textbf{X}) & = \int_0^{\infty}\cdots\int_0^{\infty} \mu(\{X_1{\,\gt\,}x_1\} \times \cdots \times \{X_d{\,\gt\,}x_d\}) dx_1\cdots dx_d.\end{align}
Remark 3.2. From the proof of Theorem 3.2 below, we know that
 \begin{align*} \mu ( A_1 \times \cdots \times A_d ) \;:\!=\; \Gamma((1_{A_1},\ldots,1_{A_d})), \quad A_1 \times \cdots \times A_d \in \mathscr{S},\end{align*}
which implies that
 $\mu$
is uniquely determined by
 $\Gamma.$
Furthermore, if we drop the normalization assumption on
 $\Gamma,$
then the above representation (3.6) becomes
 \begin{align*} \Gamma(\textbf{X}) = \Gamma(\textbf{1}) \int_0^{\infty}\cdots\int_0^{\infty} \mu(\{X_1{\,\gt\,}x_1\} \times \cdots \times \{X_d{\,\gt\,}x_d\}) dx_1\cdots dx_d.\end{align*}
Remark 3.3. When
 $d=1$
, the Axioms (A2)–(A5) become the classical monotonicity, comonotone additivity and continuity from below, respectively. Meanwhile, (3.6) becomes
 \begin{align*} \Gamma(X) = \int_0^{+\infty} \mu(X {\,\gt\,} x) dx, \quad X \in \mathscr{X}_+,\end{align*}
which is consistent with the univariate Greco’s Representation Theorem. See, for instance, Denneberg (Reference Denneberg1994, Theorem 13.2). Notice also that in the univariate Greco’s Representation Theorem, the monotonicity and comonotone additivity are crucial for a functional to be representable as a Choquet integral, while weaker lower marginal and upper marginal continuity are assumed instead of continuity from below. Thus, taking the above considerations into account, Theorem 3.2 could also be mathematically viewed as a kind of multivariate extension of the univariate Greco’s Representation Theorem.
Next, we will show that besides Axioms (A1)–(A5), if one further assumes Axiom (A6), then for any continuous
 $\textbf{X} \in \mathscr{X}^d_+$
, the distortion joint risk measure
 $\Gamma (\textbf{X})$
will have a more explicit expression in terms of certain copula and some distortion functions. As a priori, we naturally further assume that the probability space
 $(\Omega, \mathscr{F}, P)$
is large enough so that we can define any continuous random vector on it.
Theorem 3.3. Suppose that a normalized joint risk measure
 $\Gamma\;:\; \mathscr{X}^d_+ \rightarrow \mathbb{R}_+$
satisfies the Axioms (A1)–(A6). Then, for any continuous
 $\textbf{X} $
 $ = $
 $(X_1,$
 $ \ldots,$
 $ X_d)$
 $ \in $
 $ \mathscr{X}^d_+ $
which has a unique copula C, there exist left-continuous distortion functions
 $g_{_{1,C}}, \ldots, g_{_{d,C}}$
depending on C, and a copula
 $C^*$
depending on C, which is uniquely determined on
 $\Pi_{i=1}^d \mbox{Ran}(g_{_{i,C}})$
, such that
 \begin{align} \Gamma(\textbf{X}) = \int_0^{\infty}\cdots\int_0^{\infty} C^*\left(g_{_{1,C}} (P(X_1{\,\gt\,}t_1)), \ldots, g_{_{d,C}}(P(X_d{\,\gt\,}t_d))\right) dt_1 \cdots dt_d.\end{align}
Remark 3.4. If we drop the normalization assumption on
 $\Gamma,$
then (3.7) becomes
 \begin{align*} \Gamma(\textbf{X}) = \Gamma(\textbf{1}) \int_0^{\infty}\cdots\int_0^{\infty} C^*\left(g_{_{1,C}} (P(X_1{\,\gt\,}t_1)), \ldots, g_{_{d,C}}(P(X_d{\,\gt\,}t_d))\right) dt_1 \cdots dt_d.\end{align*}
Moreover, when
 $d=1$
, both the univariate copulas C and
 $C^*$
become the identity function, that is,
 $C(x)=C^*(x) = x,$
 $ x \in [0,1]$
. Hence, the distortion function
 $g_{_{1,C}}$
does not depend on the random variable
 $X \in \mathscr{X}_+$
anymore, and therefore (3.7) is consistent with the classical distortion risk measures for non-negative random variables. See, for instance, Wang et al. (Reference Wang, Young and Panjer1997, Theorem 2). Taking the above observations into account, Theorem 3.3 could also be mathematically viewed as a kind of multivariate generalization of univariate distortion risk measures.
3.3. Vector-valued distortion joint risk measures
In this subsection, we establish a new class of vector-valued joint risk measures, which we refer to as vector-valued distortion joint risk measures.
In general, a vector-valued joint risk measure is defined as any mapping
 $\tau \;:\; \mathscr{X}^d_+ \longrightarrow \mathbb{R}^d_+$
. For a random vector
 $\textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+$
, the ith component of
 $\tau (\textbf{X})$
is supposed to be a joint risk measure of certain nonnegative d-dimensional random vector with
 $X_i$
being a component of it,
 $1 \leq i \leq d$
. Let
 $\Gamma :$
 $\mathscr{X}^d_+$
 $ \longrightarrow $
 $ \mathbb{R}_+$
be a given normalized joint risk measure. For a random vector
 $\textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+$
, let us consider a background-stress-based risk test issue in the following sense. For each
 $1 \leq i \leq d$
, suppose that each of other components
 $X_j$
,
 $j\neq i$
, has a deterministic loss
 $c_j {\,\gt\,}0$
, how much risk could the
 $X_i$
contribute to the joint risk of the random vector
 $(c_1, \ldots, c_{i-1}, X_i, c_{i+1}, \ldots, c_d)$
? If
 $\Gamma$
satisfies the Axiom (A1), without loss of generality, we can naturally think about the joint risk measure
 $\Gamma (X_i\textbf{e}_i + \bar{\textbf{e}}_i)$
of the random vector
 $X_i\textbf{e}_i + \bar{\textbf{e}}_i = (1, \ldots, 1, X_i, 1, \ldots, 1)$
. Since only the ith component
 $X_i$
is random in
 $X_i\textbf{e}_i + \bar{\textbf{e}}_i$
, the quantity
 $\Gamma (X_i\textbf{e}_i + \bar{\textbf{e}}_i)$
might be regarded as the contribution of
 $X_i$
to the joint risk of
 $X_i\textbf{e}_i + \bar{\textbf{e}}_i$
. This viewpoint is consistent with the intuition as follows: if
 $X_i$
becomes null, then there should no longer have contribution of
 $X_i$
to the joint risk of
 $X_i\textbf{e}_i + \bar{\textbf{e}}_i$
, and thus there should have that
 $\Gamma (X_i\textbf{e}_i + \bar{\textbf{e}}_i)=0$
which is just guaranteed by the Axiom (A1). These d contributions of
 $X_i$
to the joint risk of
 $X_i\textbf{e}_i + \bar{\textbf{e}}_i$
,
 $1 \leq i \leq d$
, naturally form a vector
 $(\Gamma (X_1\textbf{e}_1 + \bar{\textbf{e}}_1), \ldots, \Gamma (X_d\textbf{e}_d + \bar{\textbf{e}}_d)) \in \mathbb{R}^d_+$
, which is just a vector-valued joint risk measure of
 $\textbf{X}$
. Furthermore, assume that
 $\Gamma$
satisfies the Axioms (A1)–(A6). Then, for any continuous
 $\textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+$
having a (unique) copula C, for each
 $1 \leq i \leq d$
, the quantity
 $\Gamma (X_i\textbf{e}_i + \bar{\textbf{e}}_i)$
is further determined by a distorted probability
 $g_{_{i,C}} \circ P$
, where the distortion function
 $g_{_{i,C}}$
depends on the copula C and
 $\Gamma$
; see Remark 3.5 below. Interestingly, it turns out that
 $\Gamma (X_i\textbf{e}_i + \bar{\textbf{e}}_i)$
is in accordance with some known vector-valued multivariate risk measures, respectively; see Examples 4.1–4.4 below. Consequently, we naturally introduce the following definition of vector-valued distortion joint risk measures.
Definition 3.2. Let
 $\Gamma\;:\; \mathscr{X}^d_+ \rightarrow \mathbb{R}_+$
be a normalized joint risk measure satisfying the Axioms (A1)–(A5), and let
 $\mu$
be the normalized, d-monotone and continuous from below set function as in Theorem 3.2 such that (3.6) holds. The vector-valued distortion joint risk measure
 $ H \;:\; \mathscr{X}^d_+ \rightarrow \mathbb{R}^d_+ $
is defined by
 \begin{align} H(\textbf{X}) & \;:\!=\; \left( \begin{array}{c} \Gamma (X_1\textbf{e}_1 + \bar{\textbf{e}}_1) \\[5pt] \vdots \\[5pt] \Gamma (X_d\textbf{e}_d + \bar{\textbf{e}}_d) \end{array} \right), \quad \textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+,\end{align}
where for each
 $1 \leq i \leq d,$
 $\Gamma (X_i\textbf{e}_i + \bar{\textbf{e}}_i)$
is given by
 \begin{align} \Gamma (X_i\textbf{e}_i + \bar{\textbf{e}}_i) = \int_0^{+\infty} \mu(\Omega \times \cdots \times \Omega \times \{X_i{\,\gt\,} x_i\}\times \Omega \times \cdots \times \Omega)dx_i.\end{align}
Remark 3.5. Assume that
 $\Gamma$
further satisfies the Axiom (A6). Then, for any continuous
 $\textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+$
having a (unique) copula C,
 $H(\textbf{X})$
can be expressed by
 \begin{align} H(\textbf{X}) = \left( \begin{array}{c} \int_0^{+\infty} g_{_{1,C}}(P(X_1{\,\gt\,}x_1))dx_1 \\[5pt] \vdots \\[5pt] \int_0^{+\infty} g_{_{d,C}}(P(X_d{\,\gt\,}x_d))dx_d \end{array} \right),\end{align}
where the distortion functions
 $g_{_{1,C}}, \ldots, g_{_{d,C}}$
are as in Theorem 3.3.
The verification of (3.10) is quite similar to the arguments of the proof of Theorem 3.3 below. Hence, we briefly demonstrate it here. Let us adopt all the notations used in the proof of Theorem 3.3. More precisely, define
 $ U_i \;:\!=\; F_{X_i}(X_i),$
 $ 1\leq i \leq d,$
then
 $U_i$
is uniformly distributed on (0,1). Let
 $\gamma_{_C}$
be defined as in (A17), the distortion function
 $g_{_{i,C}}$
be defined as in (A19),
 $1\leq i \leq d,$
and the copula
 $C^*$
be defined as in (A20). For each
 $1\leq i\leq d$
, by (A22), (A23), the definition of
 $\gamma_{_C}$
and the Axiom (A6), we have that for any
 $x_i \geq 0,$
 \begin{align*} \mu & (\Omega \times \cdots \times \Omega \times \{X_i{\,\gt\,} x_i\} \times \Omega \times \cdots \times \Omega) \\[5pt] & = \Gamma((1_{\{X_1{\,\gt\,}-1\}}, \ldots, 1_{\{X_{i-1}{\,\gt\,}-1\}}, 1_{\{X_i{\,\gt\,}x_i\}}, 1_{\{X_{i+1}{\,\gt\,}-1\}}, \ldots, 1_{\{X_d{\,\gt\,}-1\}})) \\[5pt] & = \Gamma((1_{ \{U_1 {\,\gt\,} 1-1\} }, \ldots, 1_{ \{U_{i-1} {\,\gt\,} 1-1\} }, 1_{ \{U_i {\,\gt\,} 1-S_{X_i}(x_i)\} }, 1_{ \{U_{i+1} {\,\gt\,} 1-1 \}}, \ldots, 1_{ \{U_d {\,\gt\,} 1-1\} })) \\[5pt] & = \gamma_{_C}(1, \ldots, 1, S_{X_i}(x_i), 1, \ldots, 1) \\[5pt] & = C^*(g_{_{1,C}}(1), \ldots, g_{_{{i-1},C}}(1), g_{_{{i},C}}(S_{X_i}(x_i)), g_{_{{i+1},C}}(1), \ldots, g_{_{d,C}}(1)) \\[5pt] & = g_{_{i,C}}(P(X_i{\,\gt\,}x_i)),\end{align*}
which, together with (3.9), yields (3.10), where the second equality holds because the distribution functions
 $F_{X_i}$
are continuous and non-decreasing and hence Lemma 2.1(1) can be applied; and the third equality holds by applying Lemma 2.1(2) to the random vector
 $(U_1, \ldots, U_d)$
that has the same copula C as that of
 $\textbf{X}$
because of Lemma 2.1(1) and the continuity of
 $\textbf{X}$
.
Next theorem discusses the properties of H defined as in (3.8).
Theorem 3.4. The H defined as in (3.8) satisfies the following properties:
-
(1) Positive homogeneity:
$H(c\textbf{X}) = cH(\textbf{X})$
for any
$\textbf{X} \in \mathscr{X}^d_+$
and any
$c {\,\gt\,} 0$
. -
(2) Translation invariance:
$H(\textbf{X}+\textbf{c}) = H(\textbf{X})+\textbf{c}$
for any
$\textbf{X} \in \mathscr{X}^d_+$
and
$\textbf{c} \in \mathbb{R}^d_+$
. -
(3) Monotonicity:
$H(\textbf{X}) \leq H(\textbf{Y})$
for any
$\textbf{X}, \textbf{Y} \in \mathscr{X}^d_+$
with
$\textbf{X} \leq \textbf{Y}$
. -
(4) Comonotone additivity:
$H(\textbf{X}+\textbf{Y}) = H(\textbf{X})+H(\textbf{Y})$
for any comonotone
$\textbf{X}$
and
$\textbf{Y} \in \mathscr{X}^d_+$
.


4. Comparisons
In this section, by four examples, we discuss connections of H as in (3.10) with some existing vector-valued multivariate risk measures.
Example 4.1. (multivariate lower-orthant VaR)
Given any
 $C \in \mathscr{C}$
, which is absolutely continuous with respect to the Lebesgue measure on
 $[0,1]^d$
, denote by
 $L_{C}$
the L-S measure induced by C on
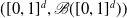 $([0,1]^d,\mathscr{B}([0,1]^d))$
. For
 $(t_1,\ldots,t_d)\in [0,1]^d$
,
 $1\leq i\leq d$
, define
 $U_i(t_1,\ldots,t_d)\;:\!=\; t_i$
, then we claim that
 ${\bf{U}}_C\;:\!=\; (U_1,\ldots,U_d)$
is a random vector on
 $([0,1]^d,\mathscr{B}([0,1]^d),L_C)$
with uniform marginal distribution functions and joint distribution function C. In fact, for any
 $(t_1,\ldots,t_d) \in [0,1]^d$
,
 \begin{align*} L_C(U_1\leq t_1,\ldots,U_d\leq t_d)= \Delta_{(0,\ldots,0)}^{(t_1,\ldots,t_d)}C= C(t_1,\ldots,t_d),\\[5pt] L_C(U_i\leq t_i)= C(1,\ldots,1,t_i,1,\ldots,1)= t_i.\end{align*}
Since
 $\textbf{U}_C$
satisfies the regularity conditions of Cousin and Di Bernardino (Reference Cousin and Di Bernardino2013), the joint probability density function of
 $\textbf{U}_C$
and
 $C(\textbf{U}_C)$
exists, as well as the probability density function of
 $C(\textbf{U}_C)$
, which are denoted by
 $f_{(\textbf{U}_C,C(\textbf{U}_C))}(u_1,\ldots,u_d,\alpha)$
and
 $f_{C(\textbf{U}_C)}$
, respectively.
For any
 $\textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+$
, denote by
 $F_{X_i}^{-1}$
the left-continuous inverse function of the distribution function
 $F_{X_i}$
of
 $X_i$
, that is,
 $F_{X_i}^{-1}(u)\;:\!=\; \inf \{ x\in \mathbb{R}_+\;:\; F_{X_i}(x)\geq u \}$
,
 $ u \in (0,1),$
 $1\leq i\leq d$
. For any
 $\alpha \in (0,1)$
, if the fraction
 \begin{align*} \frac{\int_0^1\cdots\int_0^1 F_{X_1}^{-1}(u_1) \cdots F_{X_d}^{-1}(u_d) f_{(\textbf{U}_C,C(\textbf{U}_C))}(u_1,\ldots,u_d,\alpha)du_1\cdots du_d}{f_{C(\textbf{U}_C)}(\alpha)}\end{align*}
makes sense, then denote it by
 \begin{align*} E_{L_C}\big[F_{X_1}^{-1}(U_1) \cdots F_{X_d}^{-1}(U_d)| C(\textbf{U}_C) = \alpha\big].\end{align*}
Otherwise, define
 \begin{align*} E_{L_C}\big[F_{X_1}^{-1}(U_1) \cdots F_{X_d}^{-1}(U_d)| C(\textbf{U}_C) = \alpha\big]\;:\!=\; 0,\end{align*}
where
 $E_{L_C}(\cdot)$
stands for the expectation with respect to the L-S measure
 $L_C$
.
Given any
 $\alpha \in (0,1)$
, define a normalized joint risk measure
 $\Gamma_{\alpha}\;:\; \mathscr{X}^d_+ \rightarrow \mathbb{R}_+$
by
 \begin{align*} \Gamma_{\alpha}(\textbf{X})\;:\!=\; E_{L_C}\big[F_{X_1}^{-1}(U_1) \cdots F_{X_d}^{-1}(U_d)| C(\textbf{U}_C) = \alpha\big], \quad \textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+.\end{align*}
Then, we can steadily verify that
 $\Gamma_{\alpha}$
satisfies the Axioms (A1)–(A6).
Given a continuous
 $\textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+$
so that C is the copula for it, then by the proof of Theorem 3.3, we know that the copula
 $C^*$
in Theorem 3.3 is given by
 \begin{align*} C^* (x_1, \cdots, x_d) = \frac{\int_{1-{g_{_{1,C}}^{-1}(x_1)}}^1 \cdots \int_{1-{g_{_{d,C}}^{-1}(x_d)}}^1 f_{(\textbf{U}_C, C(\textbf{U}_C))}(x_1,\ldots,x_d,\alpha)dx_1\cdots dx_d}{K'(\alpha)},\end{align*}
 $(x_1,\ldots,x_d)\in [0,1]^d$
, and the distortion functions
 $g_{_{i,C}}$
,
 $1\leq i\leq d$
, are given by
 \begin{align*} g_{_{i,C}}(1-u_i)= \frac{\int_{u_i}^1 f_{(U_i,C(\textbf{U}_C))}(x_i,\alpha)dx_i}{K'(\alpha)}, \quad u_i \in [0,1],\end{align*}
where the Kendall function
 $K(\alpha)\;:\!=\; L_C(C(\textbf{U}_C)\leq \alpha)$
,
 $K'(\alpha)$
is the first-order derivative of
 $K(\alpha)$
, and
 $f_{(U_i, C(\textbf{U}_C))}(x_i,\alpha)$
is the joint probability density function of the random vector
 $(U_i, C(\textbf{U}_C)), 1\leq i\leq d.$
Now, we claim that
 $H(\textbf{X})$
as in (3.10) with respect to
 $\Gamma_{\alpha}$
coincides with the multivariate lower-orthant VaR of Cousin and Di Bernardino (Reference Cousin and Di Bernardino2013). In fact, by Definition 3.2 and Remark 3.5, for each
 $1\leq i\leq d$
,
 \begin{align} \int_0^{+\infty} g_{_{i,C}}(P(X_i{\,\gt\,}x_i))dx_i = \frac{1}{K'(\alpha)}\int_0^{+\infty} \int_{F_{X_i}(x_i)}^1 f_{(U_i,C(\textbf{U}_C))}(u_i,\alpha)du_idx_i.\end{align}
Next, we calculate the right-hand side of (4.1). For
 $\textbf{x}= (x_1,\ldots,x_d)\in \mathbb{R}^d$
,
 \begin{align*} P & \left\{\omega \;:\; X_1(\omega) \leq x_1, \ldots, X_d(\omega) \leq x_d, P(X_1\leq X_1(\omega), \ldots,X_d\leq X_d(\omega))\leq \alpha \right\}\\[5pt] & = P \left\{ \omega \;:\; \widetilde{U_1}(\omega)\leq u_1, \ldots, \widetilde{U_d}(\omega)\leq u_d, C(\widetilde{U_1}(\omega),\ldots,\widetilde{U_d}(\omega))\leq \alpha \right\},\end{align*}
where
 $\widetilde{U_i} \;:\!=\; F_{X_i}(X_i)$
and
 $u_i \;:\!=\;F_{X_i}(x_i)$
,
 $1\leq i\leq d$
. Denote
 $\widetilde{\textbf{U}} \;:\!=\; (\widetilde{U_1},\ldots,\widetilde{U_d})$
. Then, by Lemma 2.1(1), C is a copula for
 $\widetilde{\textbf{U}}$
. Notice the fact that
 $\widetilde{{U_i}}$
and
 $U_i$
have the same distribution function,
 $1\leq i\leq d$
, hence
 $\widetilde{\textbf{U}}$
has the same joint distribution function as that of
 $\textbf{U}_C$
. Thus,
 \begin{align*}P & \left\{ \omega \;:\; \widetilde{U_1}(\omega)\leq u_1, \ldots, \widetilde{U_d}(\omega)\leq u_d, C(\widetilde{U_1}(\omega),\ldots,\widetilde{U_d}(\omega))\leq \alpha \right\} \\[5pt] & = P\circ{\widetilde{\textbf{U}}^{-1}}\left\{ \textbf{t}= (t_1,\ldots,t_d)\in [0,1]^d\;:\; t_1\leq u_1, \ldots, t_d\leq u_d, C(t_1,\ldots,t_d) \leq \alpha \right\}\\[5pt] & = L_{C}\circ \textbf{U}^{-1}_{C}\left\{ \textbf{t}= (t_1,\ldots,t_d)\in [0,1]^d\;:\; t_1\leq u_1, \ldots, t_d\leq u_d, C(t_1,\ldots,t_d)\leq \alpha \right\}\\[5pt] & = L_{C} \left\{ \textbf{t} \in [0,1]^d\;:\; {U_1}(\textbf{t})\leq u_1, \ldots, {U_d}(\textbf{t})\leq u_d, C({U_1},\ldots,{U_d})(\textbf{t})\leq \alpha \right\}.\end{align*}
Therefore,
 \begin{align*} P & \left\{ \omega \;:\; X_1(\omega) \leq x_1, \ldots, X_d(\omega) \leq x_d, P(X_1\leq X_1(\omega),\ldots,X_d\leq X_d(\omega))\leq \alpha \right\}\\[5pt] & = L_{C} \left\{ \textbf{t} \in [0,1]^d\;:\; {U_1}(\textbf{t})\leq u_1, \ldots, {U_d}(\textbf{t})\leq u_d, C({U_1},\ldots,{U_d})(\textbf{t})\leq \alpha \right\},\end{align*}
which implies that
 $ F_{(X_i,F_\textbf{X}(\textbf{X}))}(x_i,\alpha)= F_{(U_i,C(\textbf{U}_C))}(u_i,\alpha).$
Consequently,
 \begin{align} f_{(X_i,F_\textbf{X}(\textbf{X}))}(x_i,\alpha)= f_{(U_i,C(\textbf{U}_C))}(u_i,\alpha)f_{X_i}(x_i), \quad \quad P(F_\textbf{X}(\textbf{X})\leq \alpha)= K(\alpha),\end{align}
and when
 $x_i\leq F_{X_i}^{-1}(\alpha)$
,
 $f_{(X_i,F_\textbf{X}(\textbf{X}))}(x_i,\alpha)=0$
. From (4.1), (4.2), the Fubini’s Theorem and change-of-variable, it follows that
 \begin{align*} \int_0^{+\infty} g_{_{i,C}}(P(X_i{\,\gt\,}x_i))dx_i = \frac{1}{f_{F_\textbf{X}(\textbf{X})}(\alpha)}\int_{F_{X_i}^{-1}(\alpha)}^{+\infty} x_i\cdot f_{(X_i,F_\textbf{X}(\textbf{X}))}(x_i,\alpha)dx_i,\end{align*}
which coincides with the multivariate lower-orthant VaR of Cousin and Di Bernardino (Reference Cousin and Di Bernardino2013).
Example 4.2. (multivariate upper-orthant CTE)
Suppose that a copula
 $C \in \mathscr{C}$
is arbitrarily given, which is absolutely continuous with respect to the Lebesgue measure on
 $[0,1]^d$
. Given an
 $\alpha \in (0,1)$
, define a normalized joint risk measure
 $\Gamma_{\alpha}\;:\; \mathscr{X}^d_+ \rightarrow \mathbb{R}_+$
by
 \begin{align*} \Gamma_{\alpha}(\textbf{X})\;:\!=\; E_{L_C}\big[F_{X_1}^{-1}(U_1) \cdots F_{X_d}^{-1}(U_d)| S_{\textbf{U}_C}(\textbf{U}_C)\leq 1-\alpha\big], \quad \textbf{X} = (X_1, \ldots, X_d) \in \mathscr{X}^d_+,\end{align*}
where
 $\textbf{U}_C \;:\!=\; (U_1,\ldots,U_d)$
,
 $L_C$
and the inverse functions
 $F_{X_1}^{-1}, 1\leq i\leq d,$
are as in Example 4.1. Then, we can steadily verify that
 $\Gamma_{\alpha}$
satisfies the Axioms (A1)–(A6).
Given any continuous
 $\textbf{X} \in \mathscr{X}^d_+$
so that C is a copula for it, then by the proof of Theorem 3.3, we know that the copula
 $C^*$
in Theorem 3.3 is given by
 \begin{align*} C^* (x_1,\ldots, x_d) & = \frac{1}{L_C(S_{\textbf{U}_C}(\textbf{U}_C)\leq 1-\alpha)}\\[5pt] & \quad \cdot \int_{1-g_{_{1,C}}^{-1}(x_1)}^1\cdots \int_{1-g_{_{d,C}}^{-1}(x_d)}^1 \int_0^{1-\alpha} f_{(\textbf{U}_C, S_{\textbf{U}_C}(\textbf{U}_C))}(u_1,\ldots,u_d,y) dydu_1\cdots du_d,\end{align*}
and the distortion functions
 $g_{_{i,C}}$
,
 $1\leq i\leq d$
, are given by
 \begin{align*} g_{_{i,C}}(u_i) = \frac{1}{L_C(S_{\textbf{U}_C}(\textbf{U}_C)\leq 1-\alpha)} \cdot \int_{1-u_i}^1 \int_0^{1-\alpha} f_{(U_i,S_{\textbf{U}_C}(\textbf{U}_C))}(x_i,y)dydx_i,\end{align*}
where
 $f_{(\textbf{U}_C, S_{\textbf{U}_C}(\textbf{U}_C))}$
is the joint probability density function of
 $\textbf{U}_C$
and
 $S_{\textbf{U}_C}(\textbf{U}_C)$
, and
 $f_{(U_i, S_{\textbf{U}_C}(\textbf{U}_C)}$
is the joint probability density function of
 $U_i$
and
 $S_{\textbf{U}_C}(\textbf{U}_C)$
,
 $1\leq i\leq d$
.
By Definition 3.2 and Remark 3.5, an elementary calculation shows that the ith component of
 $H(\textbf{X})$
as in (3.10) is given by
 \begin{align*} \int_0^{\infty} g_{_{i,C}}(P(X_i{\,\gt\,}x_i))dx_i= \int_0^{+\infty} \int_{F_{X_i}(x_i)}^1 \int_0^{1-\alpha} f_{U_i,S_{\textbf{U}_C}(\textbf{U}_C)}(u_i,y)dydu_idx_i,\end{align*}
which, by the similar arguments as in Example 4.1, can be shown to coincide with the multivariate upper-orthant CTE of Cousin and Di Bernardino (Reference Cousin and Di Bernardino2014).
Example 4.3. (multivariate tail conditional expectation, MTCE)
Suppose that a copula
 $C \in \mathscr{C}$
is arbitrarily given, which is absolutely continuous with respect to the Lebesgue measure on
 $[0,1]^d$
. Given a
 $q \in (0,1)$
, define a normalized joint risk measure
 $\Gamma_q\;:\; \mathscr{X}^d_+ \rightarrow \mathbb{R}_+$
by
 \begin{align*} \Gamma_q(\textbf{X})\;:\!=\; E_{L_C}\left[F_{X_1}^{-1}(U_1) \cdots F_{X_d}^{-1}(U_d)| U_1 {\,\gt\,} \textrm{VaR}_q (U_1),\ldots, U_d {\,\gt\,} \textrm{VaR}_q (U_d)\right],\end{align*}
 $\textbf{X} = (X_1,\ldots, X_d) \in \mathscr{X}^d_+,$
where
 $\textbf{U}_C \;:\!=\; (U_1,\ldots,U_d)$
,
 $L_C$
and the left-continuous inverse functions
 $F_{X_1}^{-1}, 1\leq i\leq d,$
are as in Example 4.1,
 $\textrm{VaR}_q (U_i) \;:\!=\; F_{U_i}^{-1}(q), 1\leq i\leq d.$
Then, we can steadily verify that
 $\Gamma_{q}$
satisfies the Axioms (A1)–(A6).
Given any continuous
 $\textbf{X} \in \mathscr{X}^d_+$
so that C is a copula for it, then by the proof of Theorem 3.3, we know that the copula
 $C^*$
in Theorem 3.3 is given by
 \begin{align*} C^* (u_1,\ldots, u_d) = \frac{1}{p} \widehat{C}\big(g_{_{1,C}}^{-1}(u_1)\wedge \alpha,\ldots, g_{_{d,C}}^{-1}(u_d)\wedge \alpha\big),\end{align*}
and the distortion functions
 $g_{_{i,C}}$
,
 $1\leq i\leq d$
, are given by
 \begin{align*} g_{_{i,C}}(u_i)= \begin{cases} \frac{\widehat{C}(\alpha,\ldots, \alpha, u_i, \alpha,\ldots, \alpha)}{\widehat{C}(\alpha,\ldots, \alpha)}, & 0 \leq u_i \leq \alpha, \\[5pt] 1, & \alpha {\,\lt\,} u_i \leq 1, \end{cases}\end{align*}
where
 $\widehat{C}$
is the survival copula associated with the copula C,
 $\alpha \;:\!=\; 1-q $
and
 \begin{align*} p\;:\!=\;\widehat{C}(P(X_1 {\,\gt\,} \textrm{VaR}_q (X_1)),\ldots, P(X_d {\,\gt\,} \textrm{VaR}_q (X_d)))=\widehat{C}(\alpha,\ldots, \alpha).\end{align*}
By Definition 3.2 and Remark 3.5, an elementary calculation shows that the ith component of
 $H(\textbf{X})$
as in (3.10) is given by
 \begin{align*} \int_0^{\infty} g_{_{i,C}}(P(X_i {\,\gt\,} x_i))dx_i= \frac{1}{\widehat{C}(\alpha,\ldots,\alpha)} \int_0^{+\infty} \widehat{C}(\alpha,\ldots,\alpha,P(X_i {\,\gt\,} x_i),\alpha,\ldots,\alpha)dx_i,\end{align*}
which, by similar arguments as in Example 4.1, can be shown to coincide with the MTCE of Landsman et al. (Reference Landsman, Makov and Shushi2016).
Example 4.4. (multivariate tail distortion risk measure, MTDRM)
Suppose that a copula
 $C \in \mathscr{C}$
is arbitrarily given, and that
 $\widehat{C}$
is the survival copula associated with the copula C. Given d distortion functions
 $g_1,\ldots,g_d$
, define a normalized joint risk measure
 $\Gamma :$
 $\mathscr{X}^d_+ \rightarrow \mathbb{R}_+$
by
 \begin{align*} \Gamma &(\textbf{X}) \;:\!=\; \int_{[0,+\infty)^d} \frac{\widehat{C}(g_1( P(\Omega_\textbf{X} \cap \{ X_1{\,\gt\,}x_1 \})),\ldots,g_d( P(\Omega_\textbf{X} \cap \{ X_d{\,\gt\,}x_d \}))) dx_1\cdots dx_d}{P(\Omega_\textbf{X})},\end{align*}
 $\textbf{X} = (X_1,\ldots, X_d) \in \mathscr{X}^d_+,$
where
 $\Omega_\textbf{X}$
is a tail region defined as in Cai et al. (Reference Cai, Wang and Mao2017). Assume that if
 $\textbf{X} = (X_1,\ldots, X_d)$
and
 $\textbf{Y} = (Y_1,\ldots, Y_d) \in \mathscr{X}^d_+$
have the same copula, then for any
 $(u_1,\ldots,u_d) \in [0,1]^d$
,
 \begin{align*} P(\Omega_\textbf{X}\cap\{ F_{X_i}(X_i){\,\gt\,}u_i, i=1,\ldots,d \}) = P(\Omega_\textbf{Y}\cap \{ F_{Y_i}(Y_i){\,\gt\,}u_i, i=1,\ldots,d \}).\end{align*}
Note that this assumption holds when
 $ \Omega_\textbf{X}$
and
 $ \Omega_\textbf{Y}$
are specified to the sample space
 $\Omega$
. Under the above assumption, we can steadily verify that
 $\Gamma$
satisfies Axioms (A1)–(A6).
For any continuous
 $\textbf{X} = (X_1,\ldots, X_d) \in \mathscr{X}^d_+$
so that C is a copula for it, then by the proof of Theorem 3.3, we know that the copula
 $C^*$
in Theorem 3.3 is given by
 \begin{align*} & C^* (x_1,\ldots, x_d) = \ \frac{1}{P({\Omega}_\textbf{X})}\\[5pt] &\quad \cdot \widehat{C}(g_1( P({\Omega}_\textbf{X} \cap \{ F_{X_1}(X_1){\,\gt\,}1-{g_{_{1,C}}^{-1}(x_1)} \}),\ldots,g_d( P({\Omega}_\textbf{X} \cap \{ F_{X_d}(X_d){\,\gt\,}1-{g_{_{d,C}}^{-1}(x_d)} \})),\end{align*}
and the distortion functions
 $g_{_{i,C}}$
,
 $1\leq i\leq d$
, are given by
 \begin{equation*} g_{_{i,C}}(1-u_i)= \frac{1}{P({\Omega}_\textbf{X})} g_i( P({\Omega}_\textbf{X} \cap \{ F_{X_i}(X_i){\,\gt\,}u_i \})).\end{equation*}
By Definition 3.2 and Remark 3.5, an elementary calculation shows that
 $H(\textbf{X})$
as in (3.10) is given by
 $H(\textbf{X})= (H_{g_1,\Omega_\textbf{X}}(X_1),\ldots,H_{g_d,\Omega_\textbf{X}}(X_d))^T,$
where the superscript T stands for the transpose of a vector, and for each
 $1\leq i\leq d,$
 \begin{align*}H_{g_i,\Omega_\textbf{X}}(X_i) \;:\!=\; \frac{1}{P(\Omega_\textbf{X})} \int_{0}^{+\infty} g_i ( P(\Omega_\textbf{X}\cap \{ X_i{\,\gt\,} x_i \}))dx_i,\end{align*}
which coincides with the MTDRM of Cai et al. (Reference Cai, Wang and Mao2017).
5. Concluding remarks
Inspired by both the expected utility theory and the Nash utility function, we establish a (scalar) distortion joint risk measure to quantify the joint risk of non-negative random vectors. Furthermore, we provide axiomatic characterizations of distortion joint risk measures via a new set of axioms. Moreover, we introduce a new class of vector-valued distortion joint risk measures. The connections with some existing vector-valued multivariate risk measures are discussed. To the best of our knowledge, distortion joint risk measures are new type of multivariate risk measures.
We would like to mention that a more general utility function is the Cobb-Douglas utility function. Hence, it would be interesting to see relevant study worked out in the future, in which the general Cobb-Douglas utility function (or even more general dependent interaction) is in use.
Acknowledgements
The authors are very grateful to the Editor-in-Chief Professor Mario Wüthrich, Editor Professor Steven Vanduffel and the anonymous referees for their constructive and valuable comments and suggestions, which led to the present greatly improved version of the manuscript. In particular, the possible topics for future study mentioned in the concluding remarks were motivated by the anonymous referees. The authors are also very grateful to Professor Hailiang Yang for his very helpful discussions and comments on an earlier version of the manuscript.
Funding statement
Supported in part by the National Natural Science Foundation of China (Nos: 12271415, 12001411) and the Fundamental Research Funds for the Central Universities of China (WUT: 2021IVB024).
Competing interests
The authors declare no conflict of interest.
Appendix
A.1 Proofs Proof of Lemma 2.1
Let a random vector
 $\textbf{X} = (X_1,\ldots, X_d) \in \mathscr{X}^d_+$
have a copula C.
(1) For
 $1\leq i\leq d$
, define the right-continuous inverse function
 $g_i^{-1}$
of
 $g_i$
as
 $g_i^{-1}(u_i)\;:\!=\; \inf \{ x\in\mathbb{R}\;:\; g_i(x){\,\gt\,}u_i \}$
and
 $\inf{\emptyset}\;:\!=\; +\infty$
. Then for any
 $x_i \in \mbox{Ran}(g_i),$
 $ \{g_i(X_i)\leq x_i\}= \{ X_i \leq g_i^{-1}(x_i)\}.$
Thus,
 \begin{align*} P(g_1(X_1)\leq x_1,\ldots,g_d(X_d)\leq x_d) = C(P(g_1(X_1)\leq x_1),\ldots,P(g_d(X_d)\leq x_d)).\end{align*}
(2) Given any
 $(a_1,\ldots, a_d) \in \mathbb{R}^d,$
for each
 $1\leq i\leq d$
, if
 $0\leq x_i{\,\lt\,} 1$
, then
 $\{1_{\{X_i{\,\gt\,}a_i\}}\leq x_i \} = \{ X_i\leq a_i \}.$
If
 $x_i{\,\lt\,}0$
, then
 $\{ 1_{\{X_i{\,\gt\,}a_i\}}\leq x_i \} = \emptyset = \{ X_i\leq -\infty \}.$
If
 $x_i \geq 1$
, then
 $\{ 1_{\{X_i{\,\gt\,}a_i\}}\leq x_i \} = \Omega = \{ X_i\leq +\infty \}. $
Hence, for any
 $(x_1,\ldots, x_d) \in \mathbb{R}^d,$
we can steadily verify that
 \begin{align*} P(1_{\{X_1{\,\gt\,}a_1\}}\leq x_1,\ldots,1_{\{X_d{\,\gt\,}a_d\}}\leq x_d) = C(P(1_{\{X_1{\,\gt\,}a_1\}}\leq x_1),\ldots, P(1_{\{X_d{\,\gt\,}a_d\}}\leq x_d)).\end{align*}
Lemma 2.1 is proved.
Proof of Lemma 2.2
(1) Note that for any real numbers
 $a{\,\lt\,}b$
, the function
 $h_{b,a}(x)\;:\!=\; x\wedge b- x\wedge a$
,
 $x \in \mathbb{R},$
is continuous and non-decreasing. For each
 $1 \leq i \leq d$
, applying Remark 2.1 to
 $Z \;:\!=\; X_i$
and the non-decreasing functions
 \begin{align*}h_{i,1}(x) \;:\!=\; \sum\limits_{j_i=1}^{k_i} \left( x \wedge \frac{j_i+1}{2^{n_i}} - x \wedge \frac{j_i}{2^{n_i}}\right), \quad x \in \mathbb{R},\end{align*}
and
 \begin{align*}h_{i,2}(x) \;:\!=\; \sum\limits_{j_i=1}^{l_i} \left( x \wedge \frac{j_i+1}{2^{n_i}} - x \wedge \frac{j_i}{2^{n_i}}\right), \quad x \in \mathbb{R},\end{align*}
implies that
 \begin{align*}X_i^k \;:\!=\; \sum\limits_{j_i=1}^{k_i} \left( X_i \wedge \frac{j_i+1}{2^{n_i}} - X_i \wedge \frac{j_i}{2^{n_i}}\right)\ \ \mbox{and} \ \ X_i^l \;:\!=\; \sum\limits_{j_i=1}^{l_i} \left( X_i \wedge \frac{j_i+1}{2^{n_i}} - X_i \wedge \frac{j_i}{2^{n_i}}\right)\end{align*}
are comonotone. Consequently, the desired assertion is shown.
(2) By the same arguments of proving (1), we can show the desired assertion.
(3) By Lemma 2.1, we know that the desired assertions hold. Lemma 2.2 is proved.
Proof of Remark 3.1
First, we claim that from Axiom (A3) it follows that
 $\tau(\textbf{X}) = 0$
, if there is a zero-valued component of
 $\textbf{X}$
. Indeed, without loss of generality, we assume that
 $X_d = 0$
, that is,
 $\textbf{X} = (X_1,\ldots, X_{d-1}, 0).$
Note that any two random vectors of all random vectors involved later are comonotone. Consider the random vector
 $4\textbf{X}$
. On the one hand, by Axiom (A3),
 \begin{align} \tau(4\textbf{X}) = \tau(2\textbf{X} + 2\textbf{X}) = 2^d \tau(2\textbf{X}) = 2^d \tau(\textbf{X} + \textbf{X}) = 2 ^{2d} \tau(\textbf{X}).\end{align}
On the other hand, by Axiom (A3) again,
 \begin{align}\tau (4\textbf{X}) & = \tau( (2X_1,\ldots, 2X_{d-2}, X_{d-1}, 0) + (2X_1,\ldots, 2X_{d-2}, 3X_{d-1}, 0)) \nonumber \\[5pt] & = 2^{d-1} \tau( (2X_1,\ldots, 2X_{d-2}, X_{d-1}, 0)) + 2^{d-1} \tau( (2X_1,\ldots, 2X_{d-2}, 3X_{d-1}, 0)),\end{align}
where the second equality holds because when the
 $(d-1)$
th component of
 $\textbf{Z} =(Z_1,\ldots, Z_d)$
is fixed to be either
 $X_{d-1}$
or
 $3X_{d-1}$
, then
 $\textbf{Z}$
has
 $2^{d-1}$
same choice of being either
 $(2X_1,$
 $\ldots,$
 $2X_{d-2},$
 $X_{d-1},$
0) or
 $(2X_1,$
 $\ldots,$
 $ 2X_{d-2},$
 $ 3X_{d-1}, 0)$
. Similarly, by Axiom (A3),
 \begin{align}& \tau((2X_1,\ldots, 2X_{d-2}, X_{d-1}, 0)) \nonumber \\[5pt] & =2^{d-1} \tau( (X_1,\ldots, X_{d-2}, X_{d-1}, 0)) + 2^{d-1} \tau( (X_1,\ldots, X_{d-2}, 0, 0)),\end{align}
 \begin{align} &\tau( (2X_1,\ldots, 2X_{d-2}, 3X_{d-1}, 0)) \nonumber \\[5pt] & = 2^{d-1} \tau( (X_1,\ldots, X_{d-2}, X_{d-1}, 0)) + 2^{d-1} \tau( (X_1,\ldots, X_{d-2}, 2X_{d-1}, 0))\end{align}
and
 \begin{align} \tau( (X_1,\ldots, X_{d-2}, 2X_{d-1}, 0)) \geq 2^2 \tau( (X_1,\ldots, X_{d-2}, X_{d-1}, 0)),\end{align}
where the non-negativity of
 $\tau$
is used. From (A2) to (A5), it follows that
 $ \tau (4\textbf{X}) \geq (2^{2d-1} + 2^{2d}) \tau(\textbf{X}),$
which, together with (A1), yields that
 $\tau(\textbf{X}) = 0.$
Second, we further claim that
 $\tau ((X_1,\ldots, X_{d-1}, c_d X_d)) = c_d \tau(\textbf{X})$
for any positive integer
 $c_d \geq 1$
and any
 $\textbf{X} = (X_1,\ldots,X_d) \in \mathscr{X}^d_+$
. In fact, by Axiom (A3) and the previous claim,
 \begin{align*} \tau ( (X_1,\ldots, X_{d-1}, c_d X_d)) = \tau ((X_1,\ldots, X_{d-1}, X_d)) + \tau ((X_1,\ldots, X_{d-1}, (c_d-1)X_d)) = c_d \tau ( \textbf{X}).\end{align*}
Similarly, we can show that Axiom (A1) holds for any positive integers
 $c_1,\ldots, c_d$
. Finally, under monotonicity (A2), by an approximation approach similar to the arguments as in Lemma 4.83 of Föllmer and Schied (Reference Föllmer and Schied2016) or Exercise 11.1 of Denneberg (Reference Denneberg1994), we can steadily show that Axiom (A1) holds for positive numbers
 $c_1,\ldots, c_d$
. Remark 3.1 is proved.
Proof of Theorem 3.1
The monotonicity and continuity from below of
 $\Gamma_{\mu}$
are straightforward. We turn to show the comonotone additivity. Given comonotone
 $\textbf{X} = (X_1,\ldots,X_d)$
and
 $ \textbf{Y} = (Y_1,\ldots,Y_d)$
 $ \in $
 $ \mathscr{X}^d_+$
, by Remark 2.1, there exist continuous and non-decreasing functions
 $u_1,\ldots,u_d$
,
 $v_1,\ldots,v_d$
on
 $\mathbb{R},$
such that
 $u_i(u)+v_i(u)=u$
,
 $u\in \mathbb{R}$
and
 $X_i = u_i(X_i+Y_i)$
,
 $ Y_i = v_i(X_i+Y_i), 1\leq i\leq d$
. By (3.2),
 \begin{align*} \Gamma_{\mu} (\textbf{X}+\textbf{Y}) & \ = \int_0^{+\infty}\cdots\int_0^{+\infty} \mu \left( \{ X_1+Y_1 {\,\gt\,} x_1 \} \times \cdots \times \{ X_d+Y_d {\,\gt\,} x_d \} \right) dx_1 \cdots dx_d.\end{align*}
Given any
 $x_1,\ldots, x_d \geq 0$
and any
 $ \textbf{W} = (W_1,\ldots, W_d) \in \mathscr{X}^d_+,$
for each
 $1\leq i\leq d,$
consider the monotone set function
 $\nu_i \;:\; \mathscr{F} \rightarrow [0, 1]$
defined by
 \begin{align*} \nu_i(A) \;:\!=\; \mu \left( \{ W_1 {\,\gt\,} x_1 \} \times \cdots \times \{ W_{i-1} {\,\gt\,} x_{i-1} \} \times A \times \{ W_{i+1} {\,\gt\,} x_{i+1} \} \times \cdots \times \{ W_d {\,\gt\,} x_d \} \right).\end{align*}
For any
 $V \in \mathscr{X}_+,$
denote by
 $\int V d\nu_i$
the Choquet integral of V with respect to
 $\nu_i$
. By the comonotone additivity of Choquet integral, we know that
 \begin{align} \int (X_i + Y_i) d\nu_i = \int X_i d\nu_i + \int Y_i d\nu_i.\end{align}
Applying consecutively (A6) to
 $ i = 1,\ldots, d$
yields that
 \begin{align*} \int_0^{+\infty}\cdots\int_0^{+\infty}\mu \left( \{ X_1+Y_1 {\,\gt\,} x_1 \} \times \cdots \times \{ X_d+Y_d {\,\gt\,} x_d \} \right) dx_1 dx_2 \cdots dx_d = \underset{\textbf{Z}}{\sum} \Gamma_{\mu}(\textbf{Z}),\end{align*}
where the summation is summed over
 $2^d$
random vectors
 $\textbf{Z} = (Z_1,\ldots, Z_d)$
with
 $Z_i$
being either
 $X_i$
or
 $Y_i$
for each
 $1\leq i\leq d.$
The comonotone additivity of
 $ \Gamma_{\mu}$
is shown.
Finally, we show the d-monotonicity of
 $\Gamma_{\mu}$
. Given
 $\textbf{X}=(X_1,\ldots,X_d)$
,
 $\textbf{Y}=(Y_1,\ldots,Y_d) \in \mathscr{X}^d_+$
with
 $\textbf{X} \leq \textbf{Y}$
, denote
 $\textbf{Z} = (Z_1,\ldots,Z_d)$
with
 $Z_i$
being either
 $X_i$
or
 $Y_i$
for each
 $1 \leq i \leq d$
, and denote by
 $\mbox{card}(\textbf{Z};\textbf{X})$
the number of the components of
 $\textbf{Z}$
which are
 $X_i$
,
 $1\leq i\leq d$
. Since
 $\mu$
is d-monotone, then by (3.2) we have that
 \begin{align*} \Delta_\textbf{X}^\textbf{Y} \Gamma_{\mu} & = \ \int_0^{+\infty} \cdots \int_0^{+\infty} \underset{\textbf{Z}}{\sum} (\!-\!1)^{\mbox{card}(\textbf{Z}; \textbf{X})} \mu ( \{ Z_1 {\,\gt\,} x_1 \} \times \cdots \times \{ Z_d {\,\gt\,} x_d \} ) dx_1 \cdots dx_d \\[5pt] & = \ \int_0^{+\infty}\cdots\int_0^{+\infty} \Delta_{\{X_1{\,\gt\,}x_1\}\times \cdots \times\{ X_d {\,\gt\,}x_d\}}^{\{Y_1 {\,\gt\,}x_1\} \times \cdots \times \{Y_d {\,\gt\,}x_d\}} \mu dx_1 \cdots dx_d \geq 0,\end{align*}
where the summation is summed over
 $2^d$
random vectors
 $\textbf{Z}.$
The proof of Theorem 3.1 is completed.
Proof of Theorem 3.2
Define a normalized and monotone set function
 $\mu \;:\; \mathscr{S} \rightarrow \mathbb{R}_+$
by
 \begin{align*}\mu (A_1 \times \cdots \times A_d) \;:\!=\; \Gamma ((1_{A_1},\ldots,1_{A_d})), \quad A_1 \times \cdots \times A_d \in \mathscr{S}.\end{align*}
Note that the normalization, monotonicity and continuity from below of
 $\mu$
are straightforward. The d-monotonicity of
 $\Gamma$
follows from the d-monotonicity of
 $\mu$
, since
 $\Delta_{1_\textbf{A}}^{1_\textbf{B}} \Gamma = \Delta_{A_1\times \cdots \times A_d}^{B_1\times \cdots \times B_d} \mu$
for any
 $\textbf{A} = A_1\times \cdots \times A_d$
,
 $\textbf{B} = B_1\times \cdots \times B_d \in \mathscr{S}$
with
 $A_i \subseteq B_i$
,
 $1\leq i\leq d$
,
 $1_\textbf{A} \;:\!=\; (1_{A_1},\ldots,1_{A_d})$
and
 $1_\textbf{B}\;:\!=\;(1_{B_1},\ldots,1_{B_d})$
.
Next, we proceed to show (3.6). Given any
 $\textbf{X}= (X_1,\ldots,X_d)\in \mathscr{X}^d_+$
, for each
 $1\leq i\leq d$
, let
 $n_i$
be a positive integer, and define
 \begin{align*} u_{n_i,i}(x)\;:\!=\; \frac{1}{2^{n_i}}\sum_{j_{i}=1}^{n_{i} \cdot 2^{n_{i}}-1}{{1}}_{\{x{\,\gt\,}\frac{j_i}{2^{n_i}}\}}, \quad x \geq 0. \end{align*}
Note that for each
 $1\leq i\leq d$
,
 $j_i \in \{ 1,\ldots, n_i 2^{n_i}-1 \}$
and any
 $x\geq 0$
,
 \begin{align} 2^{n_i} \cdot \left( x\wedge\frac{j_i+1}{2^{n_i}}-x\wedge\frac{j_i}{2^{n_i}} \right) \leq {{1}}_{\{x{\,\gt\,}\frac{j_i}{2^{n_i}}\}} \leq 2^{n_i} \cdot \left( x\wedge\frac{j_i}{2^{n_i}}-x\wedge\frac{j_i-1}{2^{n_i}} \right), \end{align}
 \begin{align} \sum_{j_i=1}^{n_i\cdot 2^{n_i}-1}\left( X_i\wedge \frac{j_i+1}{2^{n_i}}- X_i\wedge \frac{j_i}{2^{n_i}} \right) = X_i\wedge n_i- X_i\wedge \frac{1}{2^{n_i}} \end{align}
and
 \begin{align} \sum_{j_i=1}^{n_i\cdot 2^{n_i}-1}\left( X_i\wedge \frac{j_i}{2^{n_i}}- X_i\wedge \frac{j_i-1}{2^{n_i}} \right) = X_i\wedge \left( n_i- \frac{1}{2^{n_i}} \right) \leq X_i.\end{align}
Hence, when
 $n_i$
goes to infinity,
 $u_{n_i,i}(X_i)$
almost surely converges to
 $X_i$
.
From (A7), the definition of
 $\mu$
and the monotonicity of
 $\Gamma$
, it follows that for each
 $1\leq i\leq d$
and
 $j_i$
 $\in$
 $\{ 1,\ldots, n_i 2^{n_i}-1 \}$
,
 \begin{align*}\Gamma & \left(\left( 2^{n_1} \cdot \left(X_1 \wedge\frac{j_1+1}{2^{n_1}}-X_1\wedge\frac{j_1}{2^{n_1}}\right),\ldots, 2^{n_d} \cdot \left(X_d \wedge\frac{j_d+1}{2^{n_d}}-X_1\wedge\frac{j_d}{2^{n_d}}\right)\right) \right)\\[5pt] & \leq \mu \left( \left \{ X_1{\,\gt\,}\frac{j_1}{2^{n_1}} \right \} \times \cdots \times \left \{ X_d {\,\gt\,}\frac{j_d}{2^{n_d}} \right \} \right)\\[5pt] & \leq \Gamma\left( \left( 2^{n_1} \cdot \left(X_1 \wedge\frac{j_1}{2^{n_1}}-X_1\wedge\frac{j_1-1}{2^{n_1}}\right),\ldots, 2^{n_d} \cdot \left(X_d\wedge\frac{j_d}{2^{n_d}}-X_d\wedge\frac{j_d-1}{2^{n_d}} \right) \right) \right).\end{align*}
Since
 $\Gamma$
is component-wise positively homogeneous, thus
 \begin{align} & 2^{n_1+\cdots+n_d} \cdot \Gamma\left(\left(X_1 \wedge\frac{j_1+1}{2^{n_1}}-X_1\wedge\frac{j_1}{2^{n_1}}, \cdots ,X_d \wedge\frac{j_d+1}{2^{n_d}}-X_1\wedge\frac{j_d}{2^{n_d}}\right) \right) \nonumber\\[5pt] & \quad \leq \mu \left( \left\{ X_1{\,\gt\,}\frac{j_1}{2^{n_1}} \right\} \times \cdots \times \left\{ X_d{\,\gt\,}\frac{j_d}{2^{n_d}} \right\} \right) \nonumber\\[5pt] & \quad \leq 2^{n_1+\cdots+n_d} \cdot \Gamma\left(\left(X_1 \wedge\frac{j_1}{2^{n_1}}-X_1\wedge\frac{j_1-1}{2^{n_1}},\ldots, X_d\wedge\frac{j_d}{2^{n_d}}-X_d\wedge\frac{j_d-1}{2^{n_d}}\right) \right).\end{align}
By Lemma 2.2, (A10) and the comonotone additivity of
 $\Gamma$
, we know that
 \begin{align*}\Gamma & \left(\left(\sum_{j_1=1}^{n_1\cdot 2^{n_1}-1}\left(X_1\wedge \frac{j_1+1}{2^{n_1}}-X_1\wedge \frac{j_1}{2^{n_1}}\right),\ldots, \sum_{j_d=1}^{{n_d}\cdot 2^{n_d}-1}\left(X_d\wedge \frac{j_d+1}{2^{n_d}}-X_d\wedge \frac{j_d}{2^{n_d}}\right)\right) \right) \\[5pt] & \leq \frac{1}{2^{n_1+\cdots+n_d}} \cdot \sum_{j_1=1}^{{n_1}\cdot 2^{n_1}-1}\cdots \sum_{j_d=1}^{{n_d}\cdot 2^{n_d}-1} \mu \left( \left\{ X_1{\,\gt\,}\frac{j_1}{2^{n_1}} \right\} \times \cdots \times \left\{ X_d{\,\gt\,}\frac{j_d}{2^{n_d}} \right\} \right)\\[5pt] & \leq \Gamma \left( \left( \sum_{j_1=1}^{{n_1}\cdot 2^{n_1}-1}\left( X_1\wedge \frac{j_1}{2^{n_1}}-X_1\wedge \frac{j_1-1}{2^{n_1}} \right),\ldots, \sum_{j_d=1}^{{n_d}\cdot 2^{n_d}-1}\left( X_d\wedge \frac{j_d}{2^{n_d}}-X_d\wedge \frac{j_d-1}{2^{n_d}} \right) \right) \right),\end{align*}
which, together with (A8), (A9) and the monotonicity of
 $\Gamma$
, yields that
 \begin{align}\Gamma & \left( \left( X_1\wedge n_1-X_1\wedge \frac{1}{2^{n_1}},\ldots, X_d \wedge n_d-X_d\wedge \frac{1}{2^{n_d}}\right) \right)\nonumber\\[5pt] & \quad \leq \frac{1}{2^{n_1+\cdots+n_d}} \cdot \sum_{j_1=1}^{n_1\cdot 2^{n_1}-1} \cdots \sum_{j_d=1}^{n_d\cdot 2^{n_d}-1} \mu \left( \left\{ X_1{\,\gt\,}\frac{j_1}{2^{n_1}} \right\} \times \cdots \times \left\{ X_d{\,\gt\,}\frac{j_d}{2^{n_d}} \right\} \right)\nonumber\\[5pt] & \quad \leq \Gamma \left( \left( X_1\wedge\left( n_1-\frac{1}{2^{n_1}} \right),\ldots, X_d\wedge\left(n_d-\frac{1}{2^{n_d}}\right)\right), \right)\nonumber\\[5pt] & \quad \leq \Gamma(\textbf{X}).\end{align}
Consequently, by (A11) and the continuity from below of
 $\Gamma$
, we have that
 \begin{align} \Gamma(\textbf{X}) = & \underset{n_d\rightarrow +\infty}{\lim} \cdots \underset{n_1 \rightarrow +\infty}{\lim} \frac{1}{2^{n_1+\cdots+n_d}} \cdot \notag\\[5pt] & \quad \quad \sum_{j_1=1}^{n_1\cdot 2^{n_1}-1} \cdots \sum_{j_d=1}^{n_d\cdot 2^{n_d}-1} \mu \left( \left\{ X_1{\,\gt\,}\frac{j_1}{2^{n_1}} \right\} \times \cdots \times \left\{ X_d{\,\gt\,}\frac{j_d}{2^{n_d}} \right\} \right).\end{align}
Now, we turn to calculate the right-hand side of (A12). First, we can steadily verify that
 \begin{align} & \frac{1}{2^{n_1+\cdots+n_d}} \cdot \sum_{j_1=1}^{n_1\cdot 2^{n_1}-1} \cdots \sum_{j_d=1}^{n_d\cdot 2^{n_d}-1} \mu \left( \left\{ X_1{\,\gt\,}\frac{j_1}{2^{n_1}} \right\} \times \cdots \times \left\{ X_d{\,\gt\,}\frac{j_d}{2^{n_d}} \right\} \right)\nonumber\\[5pt] & \qquad = \int_0^{+\infty} \cdots \int_0^{+\infty} \mu \left( \left\{ u_{n_1,1}(X_1){\,\gt\,}x_1 \right\} \times \cdots \times \left\{ u_{n_d,d}(X_d){\,\gt\,}x_d \right\} \right) dx_1\cdots dx_d.\end{align}
Second, from the monotonicity of
 $\mu $
, (A7), (A8) and (A9), it follows that for any
 $(x_1,\ldots,x_d)\in [0,+\infty)^d$
,
 \begin{align} \mu & \left( \left\{ X_1\wedge n_1- X_1 \wedge \frac{1}{2^{n_1}}{\,\gt\,}x_1 \right\} \times \cdots \times \left\{ X_d\wedge n_d- X_d \wedge \frac{1}{2^{n_d}}{\,\gt\,}x_d \right\} \right) \nonumber\\[5pt] & \quad \leq \mu \left( \left\{ u_{n_1,1}(X_1){\,\gt\,}x_1 \right\} \times \cdots \times \left\{ u_{n_d,d}(X_d){\,\gt\,}x_d \right\} \right) \nonumber\\[5pt] & \quad \leq \mu \left( \left\{ X_1{\,\gt\,}x_1 \right\} \times \cdots \times \left\{ X_d{\,\gt\,}x_d \right\} \right).\end{align}
Therefore, from (A14), the monotone convergence theorem and the continuity from below of
 $\mu,$
it follows that
 \begin{align} \underset{n_d\rightarrow +\infty}{\lim} & \cdots \underset{n_1 \rightarrow +\infty}{\lim} \int_0^{\infty}\cdots \int_0^{\infty} \mu \left( \left\{ u_{n_1,1}(X_1){\,\gt\,}x_1 \right\} \times \cdots \times \left\{ u_{n_d,d}(X_d){\,\gt\,}x_d \right\} \right) dx_1 \cdots dx_d \nonumber\\[5pt] & = \int_0^{\infty} \cdots \int_0^{\infty} \mu \left( \left\{ X_1{\,\gt\,}x_1 \right\} \times \cdots \times \left\{ X_d{\,\gt\,}x_d \right\} \right) dx_1 \cdots dx_d.\end{align}
Consequently, (3.6) follows from (A12), (A13) and (A15). Theorem 3.2 is proved.
Proof of Theorem 3.3
Let
 $\mu$
be the normalized and d-monotone set function on
 $\mathscr{S}$
as in Theorem 3.2 such that (3.6) holds, that is, for any
 $\textbf{W} = (W_1,\ldots, W_d) \in \mathscr{X}^d_+,$
 \begin{align} \Gamma \left( \textbf{W} \right) = \int_0^{+\infty}\cdots \int_0^{+\infty} \mu ( \{ W_1 {\,\gt\,} t_1 \} \times \cdots \times \{ W_d {\,\gt\,} t_d \} ) dt_1 \cdots dt_d,\end{align}
where
 $\mu (A_1 \times \cdots \times A_d) \;:\!=\; \Gamma \left((1_{A_1},\ldots, 1_{A_d}) \right)$
for
 $A_i \in \mathscr{F}$
,
 $1\leq i \leq d$
.
Let a continuous
 $\textbf{X} = (X_1,\ldots, X_d) \in \mathscr{X}^d_+$
be given, which has a unique copula C. For each
 $1\leq i \leq d,$
define
 $U_i \;:\!=\; F_{X_i}(X_i)$
, and denote
 $\textbf{U}$
 $ \;:\!=\; $
 $(U_1,\ldots, U_d)$
 $\in$
 $ \mathscr{X}^d_+.$
Clearly, for each
 $1\leq i \leq d$
,
 $U_i$
is uniformly distributed on
 $(0,1).$
C is a copula for
 $\textbf{U}$
due to Lemma 2.1(1).
Define a function
 $\gamma_{_C} \;: \ [0,1]^d \rightarrow [0, 1]$
by
 \begin{align} \gamma_{_C}(u_1,\ldots, u_d) \;:\!=\; \Gamma \left((1_{\{ U_1 {\,\gt\,} 1-u_1 \}},\ldots, 1_{\{ U_d {\,\gt\,} 1-u_d \}}) \right), \quad (u_1,\ldots, u_d) \in [0,1]^d.\end{align}
We have adopted the copula C rather than
 $\textbf{X}$
itself as a subscript in the notation
 $\gamma_{_C}$
to emphasize its dependence on the copula C. In the sequel, we will find that the desired distortion functions
 $g_{_{1,C}},\ldots, g_{_{d,C}}$
also depend on the copula C.
We first claim that
 $\gamma_{_C}$
defined as in (A17) is a grounded d-increasing function in the sense of Nelsen (Reference Nelsen2006, Definition 2.10.2 and p. 44). In fact, the normalization and monotonicity of
 $\Gamma$
imply that
 $ 0 \leq \gamma_{_C}(u_1,\ldots, u_d) \leq $
 $\Gamma(\textbf{1}) = 1$
for any
 $(u_1,\ldots,u_d)\in [0,1]^d$
. For any
 $ 0 \leq v_i \leq t_i \leq 1,$
 $ i=1,\ldots, d$
, from the d-monotonicity of
 $\Gamma$
, it follows that
 \begin{align}\Delta_{(v_1,\ldots,v_d)}^{(t_1,\ldots,t_d)} \gamma_{_C} & = \Delta_{(1_{\{ U_1 {\,\gt\,} 1-v_1 \}},\ldots,1_{\{ U_d {\,\gt\,} 1-v_d \}})}^{(1_{\{ U_1 {\,\gt\,} 1-t_1 \}},\ldots, 1_{\{ U_d {\,\gt\,} 1-t_d \}})} \Gamma\geq 0,\end{align}
which yields that
 $\gamma_{_C}$
is d-increasing. Clearly, for any
 $(u_1,\ldots, u_d) \in [0,1]^d,$
whenever there is at least one i such that
 $u_i = 0,$
then
 $ \gamma_{_C}(u_1,\ldots, u_{i-1}, 0, u_{i+1},\ldots, u_d) = 0,$
which exactly means that
 $\gamma_{_C}$
is grounded. Moreover, from the continuity from below of
 $\Gamma$
, it follows that
 $\gamma_{_C}$
is left-continuous with respect to each variable on
 $(0,1].$
By Lemma 2.1(2), we know that C is a copula for both random vectors
 $( 1_{\{ U_1 {\,\gt\,} 0 \}},$
 $\ldots,$
 $1_{\{ U_d {\,\gt\,} 0 \}})$
and
 $(1_\Omega,$
 $\ldots,$
 $1_\Omega)$
. Hence,
 $( 1_{\{ U_1 {\,\gt\,} 0 \}},\ldots, 1_{\{ U_d {\,\gt\,} 0 \}})$
and
 $(1_\Omega,\ldots, 1_\Omega)$
have the same joint distribution function. Thus, by the normalization and Axiom (A6),
 \begin{align*} \Gamma ( ( 1_{\{ U_1 {\,\gt\,} 0 \}},\ldots, 1_{\{ U_d {\,\gt\,} 0 \}})) = \Gamma ((1_\Omega,\ldots, 1_\Omega)) = 1.\end{align*}
For each
 $1\leq i \leq d,$
the ith one-dimensional margin of
 $\gamma_{_C},$
denoted by
 $g_{_{i,C}},$
is defined by
 \begin{align}g_{_{i,C}}(u_i) \;:\!=\; \gamma_{_C}(1,\ldots, 1, u_i, 1,\ldots, 1), \quad u_i \in [0, 1].\end{align}
See, for instance, Nelsen (Reference Nelsen2006, (2.10.2)). Apparently,
 $g_{_{i,C}}$
is a distortion function, and is left-continuous on
 $(0, 1].$
Define a function
 $C^*(u_1,\ldots, u_d)\;: \ \mbox{Ran}(g_{_{1,C}}) \times \cdots \times \mbox{Ran}(g_{_{d,C}}) \longrightarrow [0, 1]$
by
 \begin{align} C^*(u_1,\ldots, u_d)\;:\!=\;\gamma_{_C}(g_{_{1,C}}^{-1}(u_1),\ldots, g_{_{d,C}}^{-1}(u_d)),\end{align}
where
 $g_{_{i,C}}^{-1}$
is the right-continuous inverse function of
 $g_{_{i,C}},$
that is,
 $g_{_{i,C}}^{-1}(u_i) \;:\!=\; \inf \{ x \in [0,1] \;: \ g_{_{i,C}}(x) {\,\gt\,} u_i \}$
, if
 $ 0 {\,\lt\,} u_i {\,\lt\,} 1$
;
 $g_{_{i,C}}^{-1}(0)\;:\!=\; 0$
;
 $g_{_{i,C}}^{-1}(1)\;:\!=\; 1$
.
We conclude that
 $C^*$
is a sub-copula. In fact, for each
 $1\leq i\leq d$
,
 \begin{align*} C^* (u_1,\ldots, u_{i-1}, 0, u_{i+1},\ldots, u_d) = 0.\end{align*}
If
 ${g_{_{1,C}}},\ldots, {g_{_{d,C}}}$
are continuous, then
 $\mbox{Ran} (g_{_{i,C}}) = [0, 1], 1\leq i \leq d.$
Hence, by (A19) and (A20), for any
 $u_i \in [0, 1],$
 \begin{align} C^* (1,\ldots, 1, u_i, 1,\ldots, 1) = \gamma_{_C}(1,\ldots, 1, g_{_{i,C}}^{-1}(u_i), 1,\ldots, 1) = g_{_{i,C}}(g_{_{i,C}}^{-1}(u_i)) = u_i.\end{align}
If for some
 $i\in \{1,\ldots,d\}$
,
 ${g_{_{i,C}}}$
is not continuous, then (A21) is still true for
 $u_i \in \mbox{Ran} (g_{_{i,C}})$
. By (A18), we have that for any
 $0\leq v_i \leq t_i\leq 1,$
 $v_i,$
 $t_i \in \mbox{Ran} (g_{_{i,C}}),$
 $ 1\leq i \leq d,$
 $\Delta_{(v_1,\ldots,v_d)}^{(t_1,\ldots,t_d)} C^* = \Delta_{(\theta_1,\ldots,\theta_d)}^{(\tau_1,\ldots,\tau_d)} \gamma_{_C} \geq 0,$
where
 $\theta_i\;:\!=\; g_{_{i,C}}^{-1}(v_i)$
,
 $\tau_i\;:\!=\; g_{_{i,C}}^{-1}(t_i)$
,
 $1\leq i \leq d$
. Consequently,
 $C^*$
is a sub-copula. Particularly, if
 ${g_{_{1,C}}},\ldots, {g_{_{d,C}}}$
are continuous, then
 $C^*$
is a copula. In any case, by the copula extension lemma (see pp. 46–47 and Lemma 2.3.5 of Nelsen, Reference Nelsen2006),
 $C^*$
can be extended to a copula on
 $[0,1]^d$
, which is still denoted by
 $C^*$
.
Moreover, as a consequence of Nelsen (Reference Nelsen2006, Lemma 2.10.4), for any
 $\alpha_1,$
 $\ldots,$
 $\alpha_d$
 $\in$
[0,1],
 \begin{align} \gamma_{_C} (\alpha_1,\ldots, \alpha_d) = C^*( g_{_{1,C}}(\alpha_1),\ldots, g_{_{d,C}}(\alpha_d)).\end{align}
Next, we proceed to show that (3.7) holds for
 $\textbf{X}.$
We first claim that for any
 $t_1,\ldots, t_d \in \mathbb{R},$
 \begin{align} \Gamma((1_{\{X_1{\,\gt\,}t_1\}},\ldots, 1_{\{X_d{\,\gt\,}t_d\}})) = \Gamma((1_{\{F_{X_1}(X_1){\,\gt\,}F_{X_1}(t_1)\}},\ldots, 1_{\{F_{X_d}(X_d){\,\gt\,}F_{X_d}(t_d)\}})).\end{align}
Indeed, by Axiom (A6), it suffices to show that
 $(1_{\{X_1{\,\gt\,}t_1\}},\ldots, 1_{\{X_d{\,\gt\,}t_d\}})$
and
 $ (1_{\{F_{X_1}(X_1){\,\gt\,}F_{X_1}(t_1)\}}$
,
 $\cdots$
,
 $1_{\{F_{X_d}(X_d){\,\gt\,}F_{X_d}(t_d)\}})$
have the same joint distribution function under P. By Lemma 2.1, C is a copula for both random vectors
 $ (1_{\{X_1{\,\gt\,}t_1\}},\ldots, 1_{\{X_d{\,\gt\,}t_d\}}) $
and
 $ (1_{\{F_{X_1}(X_1){\,\gt\,}F_{X_1}(t_1)\}}, \ldots, 1_{\{F_{X_d}(X_d){\,\gt\,}F_{X_d}(t_d)\}})$
. Hence, it is further sufficient to show that for each
 $1\leq i \leq d,$
the random variables
 $ 1_{\{X_i{\,\gt\,}t_i\}}$
and
 $ 1_{\{F_{X_i}(X_i){\,\gt\,}F_{X_i}(t_i)\}}$
have the same distribution function, which is equivalent to showing that
 \begin{align} P(X_i {\,\gt\,} t_i) = P(F_{X_i}(X_i){\,\gt\,}F_{X_i}(t_i)).\end{align}
To verify (A24). Denote
 $t^*_i \;:\!=\; \sup \{ t \in \mathbb{R}\; : \ F_{{X_i}}(t) \leq F_{{X_i}}(t_i)\},$
then
 $t^*_i \in [t_i, +\infty]$
and
 $ F_{{X_i}}(t^*_i) = F_{{X_i}}(t_i).$
Hence,
 \begin{align*}P(X_i {\,\gt\,} t^*_i) = P(X_i {\,\gt\,} t_i) \quad \mbox{and} \quad \{ F_{X_i}(X_i) {\,\gt\,} F_{X_i}(t^*_i) \} = \{ F_{X_i}(X_i) {\,\gt\,} F_{X_i}(t_i) \}.\end{align*}
Therefore, to show (A24), it suffices to show that
 \begin{align*} \{X_i {\,\gt\,} t^*_i \} = \{ F_{X_i}(X_i){\,\gt\,}F_{X_i}(t^*_i) \},\end{align*}
which can be steadily verified by the definition of
 $t^*_i$
. Consequently, (A23) holds.
By (A22), (A23) and the definitions of
 $\mu$
and
 $\gamma_{_C}$
, for any
 $t_1,$
 $\ldots,$
 $t_d$
 $\in$
 $[0, +\infty),$
 \begin{align*} \mu (\{ & X_1{\,\gt\,} t_1 \} \times \cdots \times \{ X_d{\,\gt\,} t_d \} ) \\[5pt] & = \Gamma((1_{\{F_{X_1}(X_1){\,\gt\,}F_{X_1}(t_1)\}},\ldots, 1_{\{F_{X_d}(X_d){\,\gt\,}F_{X_d}(t_d)\}})) \\[5pt] & = C^*(g_{_{1,C}}(P(X_1{\,\gt\,}t_1)),\ldots, g_{_{d,C}}(P(X_d{\,\gt\,}t_d))),\end{align*}
which, together with (A16), yields (3.7). Theorem 3.3 is proved.
Proof of Theorem 3.4
Properties (1) and (3) are apparent due to Axioms (A1) and (A2). Now, we proceed to show the comonotone additivity of H. Given any comonotone
 $\textbf{X} = (X_1,\ldots, X_d)$
and
 $\textbf{Y} = (Y_1,\ldots, Y_d) \in \mathscr{X}^d_+,$
for each
 $1 \leq i \leq d,$
the ith component of
 $H(\textbf{X} + \textbf{Y})$
is
 $\Gamma((1,\ldots, 1, X_i + Y_i, 1,\ldots, 1)).$
Hence, by the comonotone additivity of
 $\Gamma,$
 \begin{align*}\Gamma ((1,\ldots, 1, X_i + Y_i, 1,\ldots, 1)) = \Gamma((1,\ldots, 1, X_i, 1,\ldots, 1)) + \Gamma((1,\ldots, 1, Y_i, 1,\ldots, 1)),\end{align*}
which implies the comonotone additivity of H. For any
 $\textbf{c} = (c_1,\ldots, c_d) \in \mathbb{R}^d_+$
, by Axiom (A1) and the normalization of
 $\Gamma,$
 $\Gamma((1,\ldots, 1, c_i, 1,\ldots, 1)) = c_i, 1\leq i\leq d.$
Hence, the translation invariance of H is a simple consequence of the comonotone additivity of H. Theorem 3.4 is proved.
A.2 Lebesque–Stieltjes measures induced by survival functions
In this section, we briefly review some basic facts about the Lebesque–Stieltjes measures induced by survival functions. For more details, we refer to Denneberg (Reference Denneberg1994).
Let
 $g\; : \ \mathbb{R}^d \rightarrow \mathbb{R}_+$
be a function, which is decreasing and right-continuous with respect to each variable. For any
 $\textbf{a}=(a_1,\ldots,a_d), \textbf{b}=(b_1,\ldots,b_d) \in \mathbb{R}^d$
with
 $\textbf{a} \leq \textbf{b}$
, the increment of g on
 $(\textbf{a},\textbf{b}]$
is then defined by
 \begin{align*} \Delta_\textbf{b}^\textbf{a}g \;:\!=\; \Delta_{\textbf{a},\textbf{b}}g \;:\!=\; \Delta_{b_1}^{a_1}\cdots\Delta_{b_d}^{a_d} g,\end{align*}
where for any function
 $h\; : \ \mathbb{R}^d \rightarrow \mathbb{R}_+$
,
 \begin{align*}\Delta^{a_i}_{b_i} h(x_1,\ldots, x_d) \;:\!=\; h(x_1,\ldots, x_{i-1}, a_i, x_{i+1},\ldots, x_d) - h(x_1,\ldots, x_{i-1}, b_i, x_{i+1},\ldots, x_d),\end{align*}
if
 $(\textbf{a},\textbf{b}]\neq \emptyset$
;
 $\Delta_\textbf{b}^\textbf{a}g\;:\!=\; 0,$
if
 $(\textbf{a},\textbf{b}]= \emptyset$
.
Assume that
 $\Delta_\textbf{b}^\textbf{a} g\geq 0$
for any
 $\textbf{a}\leq \textbf{b}$
. Denote by
 $\mathscr{S}\mathscr{R}$
the semi-ring
 $\{ (\textbf{a},\textbf{b}]\; : \textbf{a}\leq \textbf{b}, \ \textbf{a},\textbf{b} \in \mathbb{R}^d \}$
. Define a mapping
 $L_g\;: \mathscr{S}\mathscr{R} \rightarrow [0,+\infty)$
by
 $L_g((\textbf{a},\textbf{b}])\;:\!=\; \Delta_\textbf{b}^\textbf{a} g$
, if
 $(\textbf{a},\textbf{b}]\neq \emptyset$
;
 $L_g (\emptyset) \;:\!=\;0$
. It can be steadily verified that
 $L_g$
is a measure on
 $\mathscr{S}\mathscr{R}$
. Hence, by the Carathéodory’s Measure Expansion Theorem,
 $L_g$
can be uniquely extended to a measure on the Borel algebra
 $\mathscr{B}(\mathbb{R}^d)$
on
 $\mathbb{R}^d$
, which is called the L-S measure induced by g, and is still denoted by
 $L_g$
.
Let
 $\mu$
be a d-monotone and continuous from below set function on
 $\mathscr{S}.$
For any random vector
 $\textbf{X} = (X_1,\ldots, X_d)\in {\mathscr{X}}^d,$
applying the previous discussions to the survival function
 $S_{\mu,\textbf{X}}$
of
 $\textbf{X}$
with respect to
 $\mu$
obtains the L-S measure on
 $\mathscr{B}(\mathbb{R}^d)$
, which is denoted by
 $L_{\mu,\textbf{X}}$
.
Similar to d-variate functions, we can define the increment of any functional
 $\Gamma\; :\; \mathscr{X}^d \rightarrow \mathbb{R}$
. More precisely, for any
 $\textbf{X} = (X_1,\ldots, X_d)$
,
 $\textbf{Y} = (Y_1,\ldots, Y_d) \in \mathscr{X}^d$
, the increment of
 $\Gamma$
from
 $\textbf{X}$
to
 $\textbf{Y}$
is defined by
 \begin{align*} \Delta^{\textbf{Y}}_{\textbf{X}} \Gamma \;:\!=\; \Delta_{\textbf{Y}, \textbf{X}} \Gamma \;:\!=\; \Delta^{(d)}_{Y_d, X_d} \Delta^{(d-1)}_{Y_{d-1}, X_{d-1}} \cdots \Delta^{(1)}_{Y_1, X_1} \Gamma,\end{align*}
where for any functional
 $G \;:\; \mathscr{X}^d \rightarrow \mathbb{R}$
,
 \begin{align*}\Delta^{(i)}_{Y_i, X_i} G(Z_1,\ldots, Z_d) = G(Z_1,\ldots, Z_{i-1}, Y_i, Z_{i+1},\ldots, Z_d) - G(Z_1,\ldots, Z_{i-1}, X_i, Z_{i+1},\ldots, Z_d).\end{align*}
A.3 Distortion joint risk measures on
$\mathscr{X}^d$

Basically, by the same methods as in the Appendix of Wang et al. (Reference Wang, Young and Panjer1997) or Gong et al. (Reference Gong, Hu and Wei2025, Proposition 3.4), we can extend Theorems 3.2–3.4 to general random vectors
 $\textbf{X} \in \mathscr{X}^d.$
In this situation, all the notations and axioms for functionals are naturally extended from
 $\mathscr{X}^d_+$
to
 $\mathscr{X}^d.$
For simplicity, we consider the case of
 $ d = 2.$
Moreover, due to spaces, we temporarily state the extension of Theorem 3.2 to
 $\mathscr{X}^2,$
and omit its proof at this moment.
Theorem A.1. Suppose that a normalized joint risk measure
 $\Gamma\;:\; \mathscr{X}^2 \rightarrow \mathbb{R}$
satisfies the Axioms (A1)–(A5). Then, there exists a normalized, 2-monotone and continuous from below set function
 $\mu$
on
 $\mathscr{S}$
depending on
 $\Gamma,$
such that for any
 $\textbf{X}$
 $ = $
 $ (X_1, X_2)$
 $ \in $
 $ \mathscr{X}^2,$
 \begin{align*} \Gamma(\textbf{X}) & = \int_{-\infty}^0 \left [ \int_{-\infty}^0 \left[ \mu (\{X_1{\,\gt\,}x_1\} \times \{X_2{\,\gt\,}x_2\}) - \mu (\Omega \times \{X_2{\,\gt\,}x_2\}) \right. \right. \nonumber\\[5pt] & \quad \left. - \mu (\{X_1{\,\gt\,}x_1\} \times \Omega) + 1 \right] dx_1 \nonumber \\[5pt] & \quad + \left. \int_0^{\infty} \left[ \mu (\{X_1{\,\gt\,}x_1\} \times \{X_2{\,\gt\,}x_2\}) - \mu (\{X_1{\,\gt\,}x_1\} \times \Omega) \right] dx_1 \right ] dx_2 \nonumber\\[5pt] & \quad + \int_0^{\infty} \left [ \int_{-\infty}^0 \left[ \mu (\{X_1{\,\gt\,}x_1\} \times \{X_2{\,\gt\,}x_2\}) - \mu (\Omega \times \{X_2{\,\gt\,}x_2\}) \right] dx_1 \right. \nonumber\\[5pt] & \quad + \left. \int_0^{\infty} \mu(\{X_1{\,\gt\,}x_1\} \times \{X_2{\,\gt\,}x_2\}) dx_1 \right ] dx_2.\end{align*}



