


“Never, no matter what the progress of science, will honest scientific men who have a regard for their professional reputations venture to predict the weather.”
—François Arago (1786–1853)
“You don’t need a weatherman to know which way the wind blows.”
—Bob Dylan, 1965.
Meteorology leads the forecasting world. Across the twentieth century, it moved from a prescientific enterprise to a highly scientific one. Now, weather forecasting stands as a beacon, guiding other researchers who want to predict their chosen phenomena of study. As election forecasters, we can learn from weather forecasters. It seems profitable to develop the weather simile, holding that elections are like the weather. That is, we can advance methodologically if we move forward in ways analogous to the steps taken by pioneering meteorologists, such as Vilhelm Bjerknes, Lewis Fry Richardson, and their successors. In the following text, we draw out the parallels and perils of forecasting the weather and elections. We outline principles and practices from meteorology, and apply them to predicting US presidential elections. In particular, recent contests and modeling efforts are examined. As an organizing device, we pivot on the path-breaking work of Richardson, already known to political scientists for his seminal international conflict study, The Statistics of Deadly Quarrels (1960). By way of conclusion, we arrive at lessons election forecasters might follow and sound a few cautionary notes.
BJERKNES’S IDEA: ELECTIONS AS SCIENCE?
As the last century began, weather prediction was a catch-as-catch-can affair. A forecaster drew on personal experience, recollection of past events, and a grab bag with rules-of-thumb to create a weather map. The essential working assumption was that what happened yesterday would happen today, unless that was obviously wrong. Vilhelm Bjerknes, a Norwegian physicist and meteorologist, sought to change this conventional approach. Famously, he declared
If it is true… that subsequent atmospheric states develop from the preceding ones according to physical law, then it is apparent that the necessary and sufficient conditions for the rational solution of forecasting problems are the following: (1) A sufficiently accurate knowledge of the state of the atmosphere at the initial time. (2) A sufficiently accurate knowledge of the state of the laws according to which one state of atmosphere develops from the other (Bjerknes Reference Bjerknes1904, 1).
In addition to calling for improved observational data, he identified the atmospheric processes that could be computed based on fundamental equations: pressure, temperature, density, humidity, and velocity. In sum, he hoped to turn meteorology into an exact science similar to astronomy, in which “the acid test of a science is its utility in forecasting” (Lynch Reference Lynch2006, 8).
Election forecasting has exhibited a comparable early, prescientific, history. As the twentieth century opened, predicting which candidate would win was guesswork done mostly by insider politicos and newspaper columnists. There were occasional straw polls—head counts done at party meetings or run in the local gazette—but these were without scientific value. Even the advent of large-scale public-opinion polls became suspect because of notorious prediction errors such as when the 1936 Literary Digest survey predicted Landon over Roosevelt, and the 1948 Gallup poll foresaw Dewey defeating Truman.
Indeed, until recently, scientific election forecasting, in the sense of systematic accounting of the behavior of a dependent variable, a la Bjerknes, was thought impossible or, at best, frivolous (Lewis-Beck and Rice Reference Lewis-Beck and Rice1992, chapter 1). This view began to change around 1980, when simple regression models predicting presidential election outcomes began to appear in the literature (see, for example, Lewis-Beck and Rice 1982; Sigelman Reference Sigelman1979). Like Bjerknes, these scholars had an “atmosphere” (an electoral system) to study, and they tacitly assumed it to be governed by laws. Of particular interest within this atmosphere was the dependent variable of national presidential election outcomes. Like Bjerknes, they concerned themselves with modeling election processes with the aim of generating accurate forecasts in advance of the event.
THE RICHARDSON EQUATIONS: ELECTION FUNDAMENTALS?
Lewis Fry Richardson, who founded modern weather forecasting, read Bjerknes, determined to implement his theoretical agenda. He simplified the equations, basing them heuristically on the evolution of a fluid in hydrostatic equilibrium (Coiffier Reference Coiffier2011, 6). They came to be labeled the primitive equations, for their fundamental nature. In election forecasting, we can consider the Core Political Economy Equation, based on strong theory and evidence from electoral behavior studies, as the Primitive Equation. An initial presentation of such a Core Political Economy Model, with presidential vote share as a function of economic growth and presidential popularity, lagged, appears in Lewis-Beck and Rice (Reference Lewis-Beck and Rice1984).
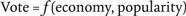 $${\rm{Vote}} = f({\rm{economy,popularity}}){\rm{ }}$$
This equation might be amended as follows, to add an institutional term:
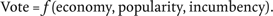 $${\rm{Vote}} = f({\rm{economy,popularity,incumbency}}){\rm{ }}$$
This model, containing three fundamentals, undergirds many election forecasting models in the United States (Lewis-Beck and Tien Reference Lewis-Beck, Tien, Clements and Hendry2011a) and abroad (Lewis-Beck and Bélanger Reference Lewis-Beck and Bélanger2012; Stegmaier and Norpoth Reference Stegmaier, Norpoth and Valelly2013).
Richardson solved his set of primitive equations numerically in the 1920s, making the first-ever scientific weather forecast of the change in surface pressure over a six- hour period. In some ways, his forecast can be evaluated favorably. It had lead time: six hours. It had reproducibility: the equation was later verified as mathematically correct, despite that it had taken him two years of hand-calculation (Lynch Reference Lynch2006, 16). However, it failed by the criterion of accuracy: it was wildly wrong. Why? He had a data problem, as well as a specification problem, as we shall see next.
RICHARDSON’S MISTAKE: THE 2000 ELECTIONS?
It is useful to consider how a scientist as sophisticated and careful as Richardson botched the world’s maiden scientific weather forecast. In his atmospheric pressure forecast, he considered short-term gravity waves and extrapolated from these, but he failed to account for the longer-term effects of the earth’s rotation. Lynch (Reference Lynch2006) provides intuition for “Richardson’s Mistake” through analogy to predicting ocean level. If one were to account only for the rise and fall of each wave over a few hours timespan and forgot about the tidal variations, the forecast would call for catastrophic flooding.
The implications of Richardson’s dream for election forecasting are many. First, more “data stations” are needed to take high-quality measures. The most obvious example here is repeated scientific polling in the relevant electoral unit, for example, the states. This makes possible repeated “snapshots” of the electoral atmosphere at close intervals, with ever-decreasing lead time as the event approaches.
A similar error appears to have occurred with the 2000 US presidential election forecasts, where most of the advertised models generated large forecasting errors, predicting a landslide Gore victory. These models appear to have extrapolated too far from wrong variables. They had a specification problem. For one, the models did not adequately consider incumbency: Gore running without Clinton, after two Democratic terms in office (Campbell Reference Campbell2001, Lewis-Beck and Tien Reference Lewis-Beck and Tien2001). Further, the models had a data problem. That is, the estimates were static, and aggregated to the nation, rather than to the states. Finally, because they were static, they remained too far (many months) from the election.
RICHARDSON’S DREAM: REPEATED MEASURES AT CLOSE RANGE
In Richardson’s day, weather stations were scarce and poorly placed. His “dream” was to have “weather factories” around the world, at the middle of each of geographic computational grid. His dream has been fulfilled. Today there are more than 10,000 fixed surface weather stations globally (Coiffier Reference Coiffier2011, 246). This routine data gathering makes possible the steady update of forecasts. But serious forecasting errors from a single model can still occur, because of faulty measurement, model misspecification, and the chaotic nature of the atmosphere. These errors in the initial weather model, no matter how tiny, are amplified over the forecast time horizon (Lorenz Reference Lorenz1963). This continuing uncertainty has brought about ensemble forecasting, which combines the estimates from numerous models.
The implications of Richardson’s dream for election forecasting are many. First, more “data stations” are needed to take high-quality measures. The most obvious example here is repeated scientific polling in the relevant electoral unit, for example, the states. This makes possible repeated “snapshots” of the electoral atmosphere at close intervals, with ever-decreasing lead time as the event approaches. For instance, start one year before the election and measure vote intentions monthly, then weekly, then daily. Lewis-Beck and Tien (Reference Lewis-Beck and Tien2012) have called this “nowcasting.” Other examples of its successful use are Erikson and Wlezien (Reference Erikson and Wlezien2012) at the national level and Linzer (Reference Linzer2013) at the state level.
A further implication is that the forecasts of multiple models should be combined to generate ensemble forecasts. A leading example of this has already occurred. Prior to the 2012 presidential election, PS: Politics and Political Science published 13 election forecasting models. The models yielded a median ensemble forecast of 50.6% of the two-party vote for Obama (Campbell Reference Campbell2012, 16).
FORECASTING RANGE: HOW CLOSE?
Weather models predict the average score of a recognized meteorological parameter, such as temperature, for a specified spatial domain. Predictability decreases as a function of time. Outside a certain range, accuracy cannot be achieved. We can compare forecasts generally as long-range versus short-range. We begin with the properties of long-range forecasts. Those with the most range are usually statistical averages from past weather data (labeled “climatic data”), for example, forecasting next year’s rainfall from the average rainfall over the last 30 years. These naive projections are not forecasts as usually understood, because in the long-run they do not improve on a simple forecast of the mean value. Therefore, to display forecasting skill, a model should demonstrate an improvement over this climatic average (Lutgens and Tarbuck Reference Lutgens and Tarbuck2001, 332). Other long-range weather forecasts of lesser extension, such as monthly or two week forecasts, have not shown much success. In the world of election prediction, range (lead time) is also very important. The greater the distance from the election, the more impressive the forecast. However, a year out, virtually no gain in prediction accuracy exists (Erikson and Wlezien Reference Erikson and Wlezien2012). But beginning around 6 months out, accuracy may become noteworthy. Take, for example, the Lewis-Beck and Tien (Reference Lewis-Beck and Tien2013) Proxy Model, which models the two-party presidential vote share as a function of the National Business Index six months before the election. Their model predicted an Obama victory with 52.7% of the two-party vote. Given President Obama received about 52.0% of the two-party popular vote, this yields a prediction error of only 0.7 percentage points, on an ex ante forecast with a six-month lead.
Election outcomes, like comet bursts, may follow deterministic laws, whose triggering values occur just before the event. In that case, well-specified structural models, measured with the optimal lead time, might ultimately be preferred over atheoretical tracking models.
Besides long-range forecasts, there are short-range weather forecasts—the ones we see on the morning news. Here meteorology has seen the greatest advances in accuracy because of improved data gathering, advances in computing, and the meteorologist’s interpretation of numerical weather prediction model results. In general, the shorter the range, the more accurate the forecast (Lutgens and Tarbuck Reference Lutgens and Tarbuck2001, 32934). With today’s advanced data collection techniques and computing power, this holds even for forecasts just a few hours into the future. In election forecasting, how well do the shorter-range models perform? If accuracy continually increases as the lead time shortens, then one might trade-off lead time for accuracy. Some argue that accuracy increases the closer to the election, but others argue that campaign events can temporarily pull some voters away from their preferred candidates. [See the discussion in Erikson and Wlezien (2012, chapter 5) and Lewis-Beck and Rice (1992, 35–38, 95–96)].
CONCLUSION
In sum, the science of weather forecasting contains useful lessons for election forecasters. First, models should be based on electoral theory, at least in their initial state. Second, the models should be dynamic, with forecasts updated at shorter intervals as the election approaches. Third, data gathering should be frequent and detailed. Fourth, repeated measures should be taken of the relevant model independent and dependent variables, for example, economic performance and electoral outcome. Fifth, in the absence of measures on the relevant model variables, it may be necessary to engage in “tracking,” rather than “explanation” (Lewis-Beck and Tien Reference Lewis-Beck and Tien2011b). That is, track the evolution of poll measures of vote intention, rather than the actual vote outcome. This amounts to engaging in what meteorologists call “trend forecasting,” merely marking the movement of the dependent variable of interest. For a weather forecaster that variable may be a coming storm, for the election forecaster it is the coming election.
Here we come to a major divide between weather and election forecasting—what we call the Big Dependent Variable problem. Predictions of some days are more politically relevant than others. Vote intention on Election Day counts much more than vote intention the day before. In election forecasting, in fact, we have One Big Day, when the people vote. Unlike the weather, national elections are not daily events. In other words, while elections are discrete, weather is continuous. Given the discrete character of the presidential election, the astronomy model, as opposed to the atmosphere model, might be the preferred simile. For example, Halley forecast the precise year (1758) his namesake comet would be seen above earth. Like US elections, the appearance of this comet has a fixed periodicity, a function of Newton’s laws of gravity and motion. Election outcomes, like comet bursts, may follow deterministic laws, whose triggering values occur just before the event. In that case, well-specified structural models, measured with the optimal lead time, might ultimately be preferred over atheoretical tracking models.
ACKNOWLEDGMENT
We thank Katie Crandall from the Department of Soil, Environmental, and Atmospheric Sciences at the University of Missouri for providing an introduction to weather forecasting and for comments on our article.


