




No CrossRef data available.
ESTIMATION OF DIFFERENTIAL-DIFFERENCE EQUATION SYSTEMS WITH UNKNOWN LAG PARAMETERS
Published online by Cambridge University Press: 15 March 2006
Abstract
This paper considers the estimation of the parameters of general systems of stochastic differential-difference equations in which the lag parameters themselves are treated as unknown and are not restricted to be integers and therefore form part of the parameter vector to be estimated. The asymptotic properties of an infeasible frequency domain maximum likelihood estimator are established in addition to those of a feasible version based on truncating an infinite series that arises in the computation of the spectral density function of the observed discrete time series. Precise conditions that the truncation parameter must satisfy for the asymptotic results to hold are provided.We are grateful to Gordon Kemp, Andrew Harvey, the Editor, and two anonymous referees for helpful comments on an earlier version of this paper. Any remaining errors are the sole responsibility of the authors. The first author thanks the Economic and Social Research Council for financial support under grant number R00429434216, and the second author thanks the Leverhulme Trust for financial support in the form of a Philip Leverhulme Prize.
Information
- Type
- MISCELLANEA
- Information
- Copyright
- © 2006 Cambridge University Press
1. INTRODUCTION
The continuous time econometrics literature to date is primarily concerned with the estimation of the parameters governing stochastic differential equations. As with many branches of econometrics, the field has grown and diversified over time, and part of this growth and diversification can be attributed to the stimulus provided by developments in economics and finance. A review of the development of linear continuous time systems and their applications in economics can be found in Bergstrom (1990), and an extensive survey of continuous time methods in finance, including the estimation of nonlinear diffusions, can be found in Sundaresan (2000).
A number of continuous time models finding recent application in economics can be classified as being forms of differential-difference equations (DDEs). Such models relate time derivatives of a variable to the levels and derivatives of the variable in current and previous time periods, unlike pure differential equations, in which the influence of lagged values is neglected in continuous time. An early and widely cited example of a DDE in economics is found in the work of Kalecki (1935), who, in his analysis of business cycles, derived an equation of the form (d/dt)y(t) = αy(t) + βy(t − θ), where y(t) denotes investment, α and β are constants, and θ denotes the lag parameter (often called the delay). A similar equation, but also involving the lagged derivative (d/dt)y(t − θ) on the right-hand side, was obtained by Ioannides and Taub (1992) in the context of time-to-build production technology and was further developed by Asea and Zak (1999).
More recent examples of DDEs in economics have enriched the specification in a number of directions. Boucekkine, de la Croix, and Licandro (2002), in an overlapping generations model of endogenous growth, derive a DDE for detrended human capital that (i) is of second order, i.e., the term on the left-hand side of the DDE is (d2/dt2)y(t); (ii) contains multiple lags of y(t) and (d/dt)y(t) on the right-hand side; and (iii) contains nonlinear parameter restrictions on the coefficients that also involve the lag parameters themselves. Benhabib (2004) analyzes monetary policy in a model in which nominal interest rates are set by a central bank in response to a lagged inflation measure. The resulting model is of second order in inflation but has the novel feature of containing leads of variables and derivatives on the right-hand side, a similar equation for the price level being obtained by von Kalckreuth and Schröder (2002) in an analysis of monetary transmission mechanisms. De Cesare and Sportelli (2005) consider an IS-LM macroeconomic model involving delayed tax revenues and obtain a system of DDEs (in output, the interest rate and money supply), the coefficient matrices of which involve nonlinear parameter restrictions.
The estimation of DDEs has only recently been given serious consideration in the econometrics literature, although a significant literature exists in statistics on the related problem of time delay estimation.1
References to some of this alternative literature can be found in Chambers and McGarry (2002).
In some circumstances, it may be possible to sample at a sufficiently high frequency so as to render all lags integer valued. However, for most applications in economics and, indeed, finance, such flexibility in the frequency with which a process is sampled is simply not available. It also presupposes that the true lag values are known, which is contrary to the objective of this paper, namely, the estimation of the unknown lag values.
The paper is organized as follows. Section 2 defines the most general system of equations with which we are concerned and derives the spectral density function of the discrete time vector of observations. The model allows for a system of higher order DDEs with unknown lag or lead parameters in which the variables may be a mixture of stocks and flows. Section 3 derives the asymptotic properties of the frequency domain maximum likelihood estimator of the unknown system parameters. We refer to this estimator as “infeasible” because it relies on the computation of a doubly infinite summation defining the spectral density of the observed discrete time series. We therefore also propose a feasible alternative estimator that truncates the infinite series, and we provide conditions on the truncation point that ensure that the desirable asymptotic properties of consistency and asymptotic normality continue to hold. Section 4 concludes. Throughout the paper, λ denotes frequency,
3This is actually the angular frequency representing the number of radians per unit of time. The number of cycles per time unit is then given by f = λ/2π, and the period of a cycle is 1/f.

. Proofs of theorems can be found in the Appendix.
2. THE DDE SYSTEM AND ITS SPECTRAL PROPERTIES
To deal simultaneously with the general features detailed in the previous section, we shall consider a real-valued stationary continuous time q-dimensional random process {y(t)}t=−∞∞ generated according to the system of DDEs defined by

where n ≥ 1 is an integer, D denotes the mean square differential operator, s0,…,sn are finite integers, and Alk(θ) (k = 1,…,sl; l = 0,…,n) are q × q matrices whose elements are known functions of an unknown p × 1 parameter vector θ, where p ≤ (s0 + ··· + sn)q2. The lag (or lead) terms νlk are finite real numbers satisfying νl1 < νl2 < ··· < νlsl, where νlk may equal zero for l ≠ n but νnk is restricted to be nonzero for all k. Although we shall refer to the νlk as lag parameters we stress that leads can appear in (1) if the relevant νlk are negative. The term ζ(dt) is a q × 1 vector of random measures satisfying E [ζ(dt)] = 0, E [ζ(dt)ζ(dt)′] = Ωdt, and E [ζ(Δ1)ζ(Δ2)′] = 0 for disjoint sets (intervals) Δ1 and Δ2 on the real line and where Ω is an unknown q × q symmetric positive definite covariance matrix. The differential order of the system (the highest order derivative) is equal to n, and the difference order of the system (the largest lag) is equal to max(|νlk|).
The system of DDEs in (1) clearly nests the specifications that have arisen recently in economics, as described in the previous section. It also nests the model considered in Chambers (1998), in which n = 1 and all lags are integer valued, in addition to the univariate specification in Chambers and McGarry (2002), although in the latter case the DDE was utlized to capture the cyclical movement of a series in an unobserved components model.
The unknown parameters in (1) are the p elements of θ, the

lag parameters νlk (l = 0,…,n; k = 1,…,sl) contained in the s × 1 vector ν, and the q(q + 1)/2 distinct elements of the symmetric covariance matrix Ω, which are contained in the vector ω. We shall assume that the vectors θ, ν, and ω belong to suitable parameter spaces

, respectively, where

and where

are defined in Assumption 1, which follows. It is convenient to combine the m = p + s + q(q + 1)/2 unknown parameters into the single m × 1 parameter vector β ≡ (θ′,ν′,ω′)′, which belongs to the composite parameter space

.
For reasons that shall become apparent, we propose a frequency domain maximum likelihood estimator of β. Central to formulating the frequency domain likelihood function is the spectral density function of the observed discrete time process generated by (1), which can be derived from the spectral density of the continuous time process y(t). First note that (1) has the representation α(D)y(t) dt = ζ(dt), where

denotes the characteristic function of (1) and whose dependence on θ and ν has been suppressed for notational convenience. The appropriate behavior of α(z) is ensured by restricting the parameter spaces

as follows.
Assumption 1. The parameter spaces

are restricted so that the product space

{θ,ν : the roots of the equation det[α(z)] = 0 have negative real parts and the matrix α(iλ) is nonsingular for all −∞ < λ < ∞}.
The condition governing the roots of the determinantal equation ensures that y(t) is a stationary process, whereas the inversion condition ensures that the spectral density matrix function of the continuous time process y(t) is defined for all frequencies. Proofs of the existence and uniqueness of solutions to systems like (1) are identical to Chambers (1998), and the spectral density matrix of the continuous time process y(t) is given by

which follows because the spectral density matrix of the white noise vector ζ(dt) is (½π)Ω and the frequency response function of the operator D is iλ. We have emphasized the dependence of the spectral density function on the parameter vector β for purposes of clarity.
The underlying time series is allowed to comprise both stock and flow variables, such that y(t) = [ys(t)′,yf(t)′]′, where the vector of stock variables (ys) has dimension qs × 1 and the vector of flows (yf) has dimension qf × 1 and where qs + qf = q. The observed discrete time vector is then given by

for t = 1,…,T, where T denotes the sample size. The frequency response function of the time invariant linear filter that transforms y(t) into yt is given by the matrix

where h(iλ) = (1 − e−iλ)/iλ is the filter for flows.4
This follows from the relationship yt f = h(D)yf(t) and the fact that the frequency response of the operator D is iλ. See, e.g., Priestley (1981, p. 175) for details.
For a formal proof see Priestley (1981, Sect. 7.1.1).

where

That f (λ,β) is Hermitian positive definite and integrable6
The Hermitian property requires f (λ,β) = f*(λ,β). Integrability is important as it ensures that y(t) has finite variance.
The aliasing phenomenon is, of course, relevant in this setting. It is impossible to detect variation at high frequencies in the continuous time series because it appears as variation below the Nyquist frequency π/Δt in the discrete time series, where Δt is the observation frequency. Using high-frequency data is one solution so that the continuous time spectral density becomes negligible outside [−π/Δt,π/Δt], but such an option is typically not available for the majority of economic time series. For conditions on the identification of the parameters in continuous time models the reader is referred to Hansen and Sargent (1983) and Phillips (1973).
The difficulty for estimation arises from the computation of the discrete time spectral density function (4). When the lags are integers it is possible to calculate (4) exactly. Chambers (1998) shows how to achieve this by exploiting the periodicity of the exponential terms7
The exponential term ei(λ+2πj)k = eiλk for j and k integer.

Only if νlk were integer could the periodicity of the exponential terms be exploited to reduce them to be of the form e−iλνlk.
One solution to the problem of computing (4), and the procedure used throughout this paper, is to simply truncate the summation at a finite number M, i.e., to use

Clearly (6) is only an approximation to the true discrete time spectral density function, but if the continuous time spectral density is sufficiently small after some finite point, i.e., if

is negligible, where

, then the approximation should be sufficiently accurate. We do at least know that the continuous time spectral density matrix f (λ,β) behaves like λ−2n uniformly in

as λ → ∞. Although the choice of truncation point M may seem somewhat arbitrary, we provide in the next section conditions on M that ensure the consistency and asymptotic normality of the frequency domain estimator.
The error arising from the use of (6) in place of (4) is given by

A useful property of the error, and one that will be called upon when investigating the asymptotic properties of the estimator, is that RM(λ,β) = O(M1−2n) uniformly in (λ,β).8
A proof can be found in Lemma 1 in the Appendix.
3. FREQUENCY DOMAIN MAXIMUM LIKELIHOOD ESTIMATION
A commonly used frequency domain estimator is the minimizer of the negative of (2/T) times the frequency domain approximation to the Gaussian log-likelihood function, given by

where

is the periodogram,
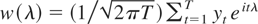
is the discrete Fourier transform of yt, and

. However, for the reasons stated earlier, it is not possible to accurately compute the spectral density function F(λ,β). We therefore consider a feasible version of (8), replacing F(λ,β) with FM(λ,β), resulting in

The likelihood function in (9) contains a bias term that may persist even asymptotically if the truncation is independent of the sample size. We therefore allow M to increase with T and prescribe appropriate rates of increase for the minimizer of (9) to be consistent and asymptotically normally distributed. In fact, we consider the asymptotic properties of two estimators, defined by

where

denotes the parameter space. We shall refer to

as being an infeasible estimator of β because the spectral density function F(λ,β) in (8) cannot be computed accurately. Conversely we shall refer to

as being a feasible estimator of β because the truncated spectral density FM(λ,β) can be computed exactly for finite M. We shall require the following additional assumptions to establish the consistency of both estimators.
Assumption 2. The elements of the matrices Alk(θ) (l = 0,…,n; k = 1,…,sl) are continuous functions of θ ∈ Θ.
Assumption 3. (a)

, where β0 is the true value of and

is a compact subset of

. (b) For β ≠ β0, F(λ,β) ≠ F(λ,β0) on a set of positive Lebesgue measure.
Assumption 4. The random measure ζ(dt) is Gaussian.
Assumption 5. M = O(Tδ) for some δ > 0.
Assumption 2 is a standard continuity assumption that ensures, in particular, that the spectral density function F(λ,β) is continuous in

. Assumption 3(a) is also standard in consistency proofs of optimization estimators, whereas 3(b) is an identification condition. Assumption 4 is equivalent to defining ζ(dt) as the increment of a Brownian motion process and ensures that the processes y(t) in continuous time and yt in discrete time are also Gaussian. This assumption could undoubtedly be relaxed so that non-Gaussian processes could be considered but at the cost of complicating the proofs. One consequence of doing this would be that the asymptotic covariance matrix in Theorem 2, which follows, would become more complicated and would depend on the higher moments of the process. Finally, Assumption 5 requires the truncation point M to increase at an arbitrary rate with T, so that asymptotically the approximation error is eliminated. The consistency result is as follows.
THEOREM 1. Under Assumptions 1–5,

as T → ∞.
The proof of Theorem 1 first establishes the consistency of the infeasible estimator

by demonstrating that LT(β) converges uniformly over

to a function L(β) that is uniquely minimized at β = β0. The consistency of the feasible estimator

is then shown by establishing the uniform convergence of LTM(β) to LT(β). The feasible estimator, based on the truncated spectral density, therefore shares the consistency property of the infeasible estimator, provided that the truncation point increases with sample size.
To derive the asymptotic distributions of the two estimators, two additional assumptions are required.
Assumption 5′. M = O(Tδ) for some δ > 1/(4n − 2).
Assumption 6. The elements of the matrices Alk(θ) (l = 0,…,n; k = 1,…,sl) are twice continuously differentiable functions of θ ∈ Θ.
Assumption 5′ represents a strengthening of Assumption 5 and is required for the asymptotic distribution theory. Note that δ is a decreasing function of the differential order n, so that in models with higher order derivatives, a slower rate of increase of M with T will suffice. The intuition behind this is fairly simple because we know that the error of truncation (RM) is inversely related to the order of derivative (n) and therefore as the order of derivative increases, the same magnitude for RM can be obtained with a smaller truncation point. In models containing just a first derivative the condition reduces to δ > 0.5 as in Chambers and McGarry (2002). Assumption 6 is common in the asymptotic analysis of optimization estimators and ensures that the objective functions (8) and (9) can be differentiated to second order.
THEOREM 2. Under Assumptions 1–4, 5′, and 6,

as T → ∞, where the (i,j) element of S(β0) is given by

for i,j = 1,…,m, and ∂F(λ,β0)/∂βi denotes the matrix ∂F(λ,β)/∂βi evaluated at β = β0.
Both estimators share the same normal limiting distribution, provided the truncation point for the infeasible estimator increases at the appropriate rate with sample size, as required in Assumption 5′. The proof of Theorem 2 relies on standard arguments for the infeasible estimator

, based on a mean value expansion of the score vector, whereas the result for

is obtained by establishing that

as T → ∞. It is worth noting that the elements of the matrix S(β0) can be consistently estimated using

, where the (i,j) element of the latter is defined by the computationally more convenient expression

where

denotes the matrix ∂F(λ,β)/∂βi evaluated at

. The matrix

is obtained in the same way with

replaced by

.
The estimators

are both asymptotically efficient under the stated assumptions. Departures from these assumptions, however, such as model misspecification or non-Gaussianity, can be expected to lead to inefficiencies, even asymptotically. Appropriately designed sampling experiments could be utilized to assess the extent of such inefficiencies in finite samples, but such an investigation remains beyond the scope of the present paper.
The asymptotic normality of the feasible estimator and the likelihood-based approach to estimation both mean that tests of hypotheses concerning β can be conducted using the standard trinity of Wald, likelihood ratio, and Lagrange multiplier test statistics. Under the appropriate null hypothesis standard techniques can be used to show that these statistics will be asymptotically distributed as chi-squared with degrees of freedom equal to the number of restrictions being tested. For example, tests of the nonlinear restrictions h(β) = 0, where

is twice continuously differentiable and the matrix ∂h/∂β′ evaluated at β = β0 has full rank, have asymptotic χc2 distributions under the null, but other hypotheses are also of interest. Prominent among these is a test of equality of lag parameters across the elements of y(t). In a simple setting, suppose

in which case the null of interest would be H0 : ν1 = ν2 = ··· = νq. This might correspond to a test of whether the time-to-build factors in a group of categories of investment expenditures were equal. Within the same setting another hypothesis might be that the νi were all equal to a particular integer value, e.g., unity. If this null hypothesis were found to be consistent with the data then its imposition would enable the spectral density function to be computed exactly using the techniques of Chambers (1998).
4. CONCLUDING COMMENTS
In this paper we have considered the problem of estimating the unknown parameters, including lag and lead parameters, in a system of DDEs of sufficient generality that nests the important recent DDE specifications that have appeared in economics, thereby expanding the scope for estimation of DDEs beyond those that have appeared in the econometrics literature to date. The main technical results of this paper concern the derivation of the asymptotic properties of the (infeasible) frequency domain maximum likelihood estimator and its feasible counterpart based on an approximation to the discrete time spectral density function. The feasible frequency domain maximum likelihood estimator, based on the truncated spectral density, is shown to share the same desirable asymptotic properties as the infeasible estimator, based on the exact spectral density, provided the truncation parameter increases at an appropriate rate with the sample size (which is given by Assumption 5 for consistency and by Assumption 5′ for asymptotic normality). It is therefore possible to obtain consistent and asymptotically normal estimates of the lag (or lead) parameters themselves in addition to the other parameters in the DDE system and to perform asymptotic chi-squared inference on hypotheses concerning those parameters.
APPENDIX
LEMMA 1. Let RM(λ,β) denote the error from truncating the spectral density after M terms, as defined in (7). Then RM(λ,β) = O(M1−2n) uniformly in (λ,β).
Proof. Recall, from (7), that

where Φ(λ,β) = H(λ) f (λ,β)H*(λ). The elements of Φ(λ ± 2πj,β) can be shown to be O(j−2n) uniformly in (λ,β) as j → ∞ by noting that f (λ ± 2πj,β) = O(j−2n) uniformly in (λ,β) and h(λ ± 2πj) = (1 − eiλ)/[i(λ ± 2πj)] = O(j−1) uniformly in λ. Hence, for k,l = 1,…,q,

uniformly in (λ,β) for 2n > 1 and where K is a generic constant. █
Proof of Theorem 1. The consistency of

is established first by demonstrating that

and that L(β) is uniquely minimized at β = β0, where

From the definition of LT(β) we have

, where

by the uniform convergence of the Riemann sums and the continuity of F(λ,β) under Assumptions 1 and 2 and

by Theorem 1 of Robinson (1976), which requires that

This follows from Theorem 2 of Hannan (1970, p. 203) because yt is a stationary Gaussian process with continuous spectral distribution function under Assumptions 1, 2, and 5. Hence LT(β) converges to L(β), uniformly in

, as T → ∞. That L(β) is uniquely minimized at β = β0 can be demonstrated following the argument in Dunsmuir and Hannan (1976).
To establish the consistency of

, note that

We have shown already that the second term converges to 0 in probability, so we consider |LTM(β) − LT(β)| ≤ B1T(β) + B2T(β), where

Fundamental to much that follows is the relationship

Considering B1T(β) first, the preceding decomposition implies that

where AM(λ,β) = I − F(λ,β)−1RM(λ,β). The diagonal elements of AM(λk,β) are of the form 1 + O(M1−2n), whereas the off-diagonal elements are O(M1−2n), both uniformly in (λ,β). Hence as T → ∞,

To deal with B2T(β), define DM(λ,β) = FM(λ,β)−1 − F(λ,β)−1 = AM(λ,β)−1 F(λ,β)−1 − F(λ,β)−1. Let {μi}i=1q denote the eigenvalues of F(λ,β)−1RM(λ,β), suppressing their dependence on M, λ, and β for notational convenience. From Theorem 3.7 of Marcus and Minc (1965), |μi| ≤ q maxi,j|φij|, where φij denotes the (i,j) element of F(λ,β)−1RM(λ,β). Hence |μi| = O(M1−2n) uniformly in (λ,β), and so, for large enough M, supλ,β|μi| < 1 (i = 1,…,q). Hence AM(λ,β)−1 can be written as a geometric progression of the form

where GM(λ,β) = O(M1−2n), uniformly in (λ,β). Hence

uniformly in (λ,β), and so

where K is a constant and because T−1 [sum ]k∥I(λk)∥ = Op(1). Under Assumption 5, the preceding expression is Op(Tδ(1−2n)) = op(1). Hence

, and so

, thereby implying that

. █
Proof of Theorem 2. Expanding the score vector

around β0 gives, for T large enough,

where ST(β) denotes the Hessian matrix whose ith row is equal to the ith row of the matrix ∂sT(β)/∂β′ = ∂2LT(β)/∂β∂β′ evaluated at β = βi, where βi lies on the line segment joining

and β0 and where β = [β1,…,βm]. Hence, because

,

We shall demonstrate that, as

, from which the assertion in the theorem concerning

follows.
(a) From the definition of the likelihood, we obtain, for i = 1,…,m,

where Gk,i(β) = Fk(β)−1[∂Fk(β)/∂βi]Fk(β)−1, Fk(β) = F(λk,β), and Ik = I(λk) for notational convenience. The required asymptotic normality of

then holds if conditions C2.1–C2.3 on p. 492 of Dunsmuir (1979) can be shown to be satisfied. (These conditions are required for Theorem 2.1 of Dunsmuir, 1979, to be valid, which concerns the asymptotic properties of the minimizer of a version of the likelihood that incorporates integrals of F(λ) and I(λ), rather than the discrete sums considered here. However, Dunsmuir's Corollary 2.2 and his Remark 1 [on p. 498] demonstrate that these same conditions yield identical asymptotic properties for the minimizer of the discrete version of the likelihood employed here.) Condition C2.1 is satisfied in view of the definition of F(λ,β) and Assumption 6. The differentiability of F(λ,β) (with respect to λ) implies that F(λ,β) satisfies a Lipschitz condition of order 1 (see, e.g., Zygmund, 1959, p. 43), and hence C2.2 is satisfied. Because F(λ,β) is continuous in both arguments and Hermitian positive definite, and yt is a stationary Gaussian sequence, Theorem 17.3.3 of Ibragimov and Linnik (1971) implies that yt is strong mixing. It is therefore, from Hannan (1970, pp. 202–204), also ergodic and has representation

with

and where the εt are independently normally distributed. This ensures that C2.3 is satisfied, and hence

.
(b) Differentiating (A.1) with respect to βj and evaluating at β = βi yields

where, e.g., ∂Fk(βi)/∂βi denotes ∂Fk(β)/∂βi evaluated at β = βi. The first two terms are of the generic form T−1 sum;k tr[Φk(βi)], whereas the remaining three are of the generic form T−1 [sum ]k tr[Φk(βi)Ik] with the matrix Φk(β) defined appropriately in each case. The terms satisfy, respectively,

and

as T → ∞, the latter following from Theorem 1 of Robinson (1976). This uniform convergence, the fact that

, and the consistency of

imply that the first two terms converge to

whereas Theorem 4.1.5 of Amemiya (1985) ensures that the final three terms converge in probability to

Combining these limits we find that

with Sij(β0) given by the final term in the preceding expression, and hence (b) is proved. The claim in the theorem concerning the distribution of

then follows by combining the results of (a) and (b).
To establish that

also, it is sufficient to establish that

. From the mean value expansion of the score vector of

, it can be shown that, for T large enough,

where

denotes the Hessian matrix whose ith row is equal to the ith row of the matrix ∂sTM(β)/∂β′ = ∂2LTM(β)/∂β∂β′ evaluated at

where

lies on the line segment joining

and where

. It can be shown therefore that

We have already established that

. To show that

, it is sufficient to show that (i)

and (ii)

. We look at each of these in turn.
(i) The score vector for

is given by

where FkM(β) = FM(λk,β) for notational economy. We know that ln det[FkM(β)] = ln det[Fk(β)] + γ1kM where γ1kM = AM(λk,β) = O(M1−2n) uniformly in (λk,β). Hence

where γ2kM = O(M1−2n) uniformly in (λk,β). Note that tr[(FkM(β)−1 − Fk(β)−1)Ik] can be written in the form tr[D(λk,β)Ik] = Op(M1−2n) uniformly in (λk,β). It therefore follows that tr[FkM(β)−1Ik] = tr[Fk(β)−1Ik] + γ3kM where γ3kM = Op(M1−2n) uniformly in (λk,β), and so

where γ4kM = Op(M1−2n) uniformly in (λk,β). Using (A.3) and (A.4) yields

implying that

uniformly in

. This gives the required result that

for δ > 1/(4n − 2), justifying the condition on δ that was given in Assumption 5′ in Section 3.
(ii) Differentiating equation (A.3) again with respect to βj yields

where ψ1kM = O(M1−2n) uniformly in (λk,β). Differentiating equation (A.4) again with respect to βj yields

where ψ2kM = Op(M1−2n) uniformly in (λk,β). Therefore

and so ST,ijM(β) − ST,ij(β) = Op(M1−2n) = Op(Tδ(1−2n)) = op(1) uniformly in

. Theorem 4.1.5 of Amemiya (1985) and the consistency of

then imply that

. █
References
REFERENCES
Amemiya, T.
(1985)
Advanced Econometrics.
Blackwell.
Asea, P.K. &
P.J. Zak
(1999)
Time-to-build and cycles.
Journal of Economic Dynamics and Control
23,
1155–1175.Google Scholar
Benhabib, J.
(2004)
Interest rate policy in continuous time with discrete delays.
Journal of Money, Credit and Banking
36,
1–16.Google Scholar
Bergstrom, A.R.
(1990)
Continuous Time Econometric Modelling.
Oxford University Press.
Boucekkine, R.,
D. de la Croix, &
O. Licandro
(2002)
Vintage human capital, demographic trends, and endogenous
growth.
Journal of Economic Theory
104,
340–375.Google Scholar
Chambers, M.J.
(1998)
The estimation of systems of joint differential-difference
equations.
Journal of Econometrics
85,
1–31.Google Scholar
Chambers, M.J. &
J.S. McGarry
(2002)
Modeling cyclical behavior with differential-difference equations in
an unobserved components framework.
Econometric Theory
18,
387–419.Google Scholar
De Cesare, L. &
M. Sportelli
(2005)
A dynamic IS-LM model with delayed taxation revenues.
Chaos, Solitons and Fractals
25,
233–244.Google Scholar
Dunsmuir, W.
(1979)
A central limit theorem for parameter estimation in stationary
vector time series and its application to models for a signal observed
with noise.
Annals of Statistics
7,
490–506.Google Scholar
Dunsmuir, W. &
E.J. Hannan
(1976)
Vector linear time series models.
Advances in Applied Probability
8,
339–364.Google Scholar
Hannan, E.J.
(1970)
Multiple Time Series.
Wiley.
Hansen, L.P. &
T.J. Sargent
(1983)
The dimensionality of the aliasing problem in models with rational
spectral densities.
Econometrica
51,
377–387.Google Scholar
Ibragimov, I.A. &
Y.V. Linnik
(1971)
Independent and Stationary Sequences of Random Variables.
Wolters-Noordhoff.
Ioannides, Y.M. &
B. Taub
(1992)
On dynamics with time-to-build investment technology and
non-time-separable leisure.
Journal of Economic Dynamics and Control
16,
225–241.Google Scholar
Kalecki, M.
(1935)
A macro-dynamic theory of business cycles.
Econometrica
3,
327–344.Google Scholar
Marcus, M. &
H. Minc
(1965)
Introduction to Linear Algebra.
Macmillan.
Phillips, P.C.B.
(1973)
The problem of identification in finite parameter continuous time
models.
Journal of Econometrics
1,
351–362.Google Scholar
Priestley, M.B.
(1981)
Spectral Analysis and Time Series.
Academic Press.
Robinson, P.M.
(1976)
Fourier estimation of continuous time models. In
A.R. Bergstrom (ed.),
Statistical Inference in Continuous Time Economic Models, pp.
215–266.
North-Holland.
Sundaresan, S.M.
(2000)
Continuous-time methods in finance: A review and an
assessment.
Journal of Finance
55,
1569–1622.Google Scholar
von Kalckreuth, U. &
J. Schröder
(2002)
Monetary Transmission in the New Economy: Service Life of Capital,
Transmission Channels and the Speed of Adjustment.
Discussion paper 16/02,
Economics Research Centre of the Deutsche Bundesbank.
Zygmund, A.
(1959)
Trigonometric Series,
2nd ed.
Cambridge University Press.
 You have
Access
- 5
- Cited by