

Impact Statement
IPSL-AID is a generative tool designed for climate downscaling—from the global to the regional scale—developed through a collaboration between computer scientists, AI/ML specialists, and climate scientists. This interdisciplinary team offers a multidimensional perspective that balances computational efficiency, statistical rigor, and physical consistency, hence making the work accessible to researchers across these fields.
1. Introduction
Anthropogenic climate change poses substantial risks to critical socioeconomic sectors, such as agriculture, forestry, energy, and water supply. The development of effective adaptation and mitigation strategies requires accessible, high-resolution (HR) climate projections to anticipate impacts at both local and regional scales. General circulation models (GCMs), which are widely used in climate research, typically operate at spatial resolutions of approximately 150–200 km (IPCC, 2023). This coarse resolution is insufficient to capture essential fine-scale processes, especially those shaped by topography, land–sea contrast, and surface heterogeneity, all of which are vital to regional climate dynamics and extreme weather events. Therefore, downscaling climate model outputs to finer resolutions is necessary to provide relevant climate information at the local level.
Weather and climate downscaling methods are typically classified into two categories (Hewitson and Crane, Reference Hewitson and Crane1996; Wilby and Wigley, Reference Wilby and Wigley1997): (i) Dynamic downscaling uses nested regional climate models (RCMs) to explicitly simulate physical processes at finer spatial scales (Giorgi and Mearns, Reference Giorgi and Mearns1991; Vrac et al., Reference Vrac, Drobinski, Merlo, Herrmann, Lavaysse, Li and Somot2012; Giorgi and Gutowski, Reference Giorgi and Gutowski2015). However, the high computational demands of this approach limit its feasibility for large ensembles or long simulation periods. (ii) Statistical downscaling establishes empirical relationships between large-scale climate predictors, such as pressure fields and circulation indices, and local-scale variables (Wilby et al., Reference Wilby, Charles, Zorita, Timbal, Whetton and Mearns2004; Vrac et al., Reference Vrac, Drobinski, Merlo, Herrmann, Lavaysse, Li and Somot2012; Maraun and Widmann, Reference Maraun and Widmann2017). However, this approach has limited capacity to capture complex nonlinear interactions and to maintain multivariate physical consistency within the generated fields.
Recent studies have shown that RCMs can be emulated with relatively low computational cost (Doury et al., Reference Doury, Somot, Gadat, Ribes and Corre2023; Rampal et al., Reference Rampal, Hobeichi, Gibson, Baño-Medina, Abramowitz, Beucler, González-Abad, Chapman, Harder and Gutiérrez2024). Artificial intelligence-based methods for weather prediction, including Pangu-Weather (Bi et al., Reference Bi, Xie, Zhang, Chen, Gu and Tian2023), GraphCast (Lam et al., Reference Lam, Sanchez-Gonzalez, Willson, Wirnsberger, Fortunato, Alet, Ravuri, Ewalds, Eaton-Rosen, Hu, Merose, Hoyer, Holland, Vinyals, Stott, Pritzel, Mohamed and Battaglia2023), and FourCastNet (Pathak et al., Reference Pathak, Subramanian, Harrington, Raja, Chattopadhyay, Mardani, Kurth, Hall, Li, Azizzadenesheli, Hassanzadeh, Kashinath and Anandkumar2022), have demonstrated significant potential (Koldunov et al., Reference Koldunov, Rackow, Lessig, Danilov, Cheedela, Sidorenko, Sandu and Jung2024). These data-driven models facilitate efficient, automated downscaling by learning to incorporate fine-scale details from reanalysis datasets such as ERA5. However, these approaches are generally deterministic and may introduce systematic biases. Critically, they often lack a robust framework for quantifying the uncertainty inherent in the downscaling process, which is essential for comprehensive risk assessment. Recent works in downscaling have highlighted the potential of diffusion models (Rampal et al., Reference Rampal, Hobeichi, Gibson, Baño-Medina, Abramowitz, Beucler, González-Abad, Chapman, Harder and Gutiérrez2024). CorrDiff, introduced by Mardani et al. (Reference Mardani, Brenowitz, Cohen, Pathak, Chen, Liu, Vahdat, Nabian, Ge, Subramaniam, Kashinath, Kautz and Pritchard2025), is a residual corrective diffusion model that downscales 25 km ERA5 inputs to 2 km resolution over Taiwan, demonstrating strong performance in reconstructing spatial spectra and synthesizing radar reflectivity. Similarly, Watt and Mansfield (Reference Watt and Mansfield2024) used a diffusion model to downscale 2° ERA5 fields to 0.25° over the continental United States, exhibiting superior performance compared to U-Net and linear interpolation. While these studies confirm the promise, they are constrained to fixed regional domains. Moreover, neither study addressed precipitation downscaling, a critical variable for impact assessment, and both relied on region-specific training that cannot be generalized to new geographic areas without retraining.
This article introduces IPSL AI Downscaling (IPSL-AID), a tool for global to regional downscaling using denoising diffusion probabilistic models (DDPMs; Ho et al., Reference Ho, Jain and Abbeel2020; Song et al., Reference Song, Meng and Ermon2020a, Reference Song, Sohl-Dickstein, Kingma, Kumar, Ermon and Poole2020b; Karras et al., Reference Karras, Aittala, Aila and Laine2022) with several key innovations. First, we propose a random block sampling strategy that enables training the model on global data with limited GPU resources, thereby delivering a model applicable to arbitrary regions without retraining, representing a step toward foundation models for downscaling. Second, the model architecture processes multiple time steps simultaneously, enabling temporally coherent evaluations. Third, the model jointly downscales multiple atmospheric variables (here, temperature, winds, and precipitation) using a flexible design to include more variables. Fourth, it provides a comprehensive evaluation, including deterministic metrics, distributional fidelity, spectral recovery, and probabilistic skills. Our results show that the model accurately reconstructs fine-scale variability and extreme events, while its generative nature enables uncertainty quantification—essential for risk assessment. This work addresses the super-resolution component of global-to-regional climate downscaling, providing a framework applicable to climate projections, including CMIP6 and future simulation sets.
2. Methodology overview
IPSL-AID is based on DDPMs. These models are trained to iteratively add and remove noise from data, thereby learning to reconstruct underlying fine-scale fields. For downscaling, we condition the model on coarse fields and their spatiotemporal context to generate multiple plausible realizations. While IPSL-AID encompasses the full design space of diffusion models introduced by Karras et al. (Reference Karras, Aittala, Aila and Laine2022), including variance-preserving, variance-expanding, and improved DDPM formulations, this work focuses on the Elucidated Diffusion Model (EDM). The core architecture is a U-Net implemented within the EDM framework. Supplementary Appendix A provides a technical description of the model architecture, training procedure, loss function, sampling algorithm, and overall workflow.
3. Data, sampling strategy, and metrics
The model is trained using four ERA5 variables (Hersbach et al., Reference Hersbach, Bell, Berrisford, Hirahara, Horányi, Muñoz-Sabater, Nicolas, Peubey, Radu, Schepers, Simmons, Soci, Abdalla, Abellan, Balsamo, Bechtold, Biavati, Bidlot, Bonavita, de Chiara, Dahlgren, Dee, Diamantakis, Dragani, Flemming, Forbes, Fuentes, Geer, Haimberger, Healy, Hogan, Hólm, Janisková, Keeley, Laloyaux, Lopez, Lupu, Radnoti, de Rosnay, Rozum, Vamborg, Villaume and Thépaut2020): 2-m temperature (t2m), 10-m zonal wind (u10), 10-m meridional wind (v10), and precipitation (tp) at 0.25° resolution. To balance temporal variability and computational cost, we select four random time steps per day.
Training HR global downscaling models is computationally intensive and requires substantial memory and GPU resources. To address this challenge, a random spatial block sampling strategy was developed. During each training epoch,
$ s $
 spatial blocks of size
$ 144\times 360 $
 are generated, with block centers placed randomly (Figure 1). The longitude of each block is treated as periodic, while the latitude is constrained within valid global boundaries. Several values for the number of spatial blocks per epoch (
$ s=6 $
 , 9, and 12) were tested, using
$ s=12 $
 was identified as an effective balance between computational efficiency and spatial diversity. For evaluation and inference, 20 fixed blocks corresponding to the ERA5 resolution of
$ 1440\times 721 $
 were used for global predictions. Our random block sampling strategy fundamentally differs from NVIDIA’s patch-based multidiffusion approach (Brenowitz et al., Reference Brenowitz, Ge, Subramaniam, Manshausen, Gupta, Hall, Mardani, Vahdat, Kashinath and Pritchard2025). Rather than training models in parallel on patches extracted from fixed domains using a Message Passing Interface (MPI) across multiple GPUs, IPSL-AID trains a single model using random blocks sampled across the globe. This enables direct application to arbitrary regions without retraining while retaining scalability to global inference.
An example of randomly sampled spatial blocks used during training of the global model.

Figure 1. Long description
A world map in a Robinson projection displays 2-m Temperature in Kelvin. Twelve numbered rectangular blocks are overlaid across various regions.
In the Northern Hemisphere
- Block 5 covers North America, showing cool blue and green tones.
- Block 8 covers Europe and Central Asia, showing a gradient from green to light blue.
- Block 3 covers Northeast Asia and the North Pacific.
In the Equatorial and Southern regions
- Block 1 is in the Central Pacific.
- Block 6 covers South America, showing warm red and orange tones.
- Block 12 covers Central and East Africa.
- Block 2 and 9 are in the Indian Ocean.
- Block 11 and 4 cover Southeast Asia and Australia.
- Block 7 is Southeast of Australia.
- Block 10 is in the South Pacific near Antarctica, showing cooler green tones.
At the bottom, a horizontal color bar represents the 2-m Temperature in K. The scale ranges from 230 in purple and dark blue, through 270 in green and yellow, to 310 in deep red. The temperature distribution generally follows latitudinal lines, with the warmest temperatures concentrated around the equator and cooling toward the poles.
A coarse-up (CU) procedure based on bilinear interpolation is used to separate large-scale and fine-scale components of the ERA5 fields. Let
$ {\mathbf{y}}^{\mathrm{HR}} $
 be a HR field. The HR field is first reduced to a coarse resolution of
$ 16\times 32 $
 (
$ \approx 2.25\hskip-0.25em {}^{\circ} $
 grid, comparable to typical GCMs resolution) by bilinear interpolation, which eliminates small-scale variability while preserving large-scale structure. The resulting coarse field is then scaled back to the original HR grid using the same interpolation method, yielding a smooth CU approximation,
$ {\mathbf{y}}^{\mathrm{CU}} $
 , unlike Mardani et al. (Reference Mardani, Brenowitz, Cohen, Pathak, Chen, Liu, Vahdat, Nabian, Ge, Subramaniam, Kashinath, Kautz and Pritchard2025), who typically rely on mean regression models. The residual field,
$ \mathbf{R}={\mathbf{y}}^{\mathrm{HR}}-{\mathbf{y}}^{\mathrm{CU}} $
 , represents the fine-scale information lost during the upscaling process and serves as the training target for the diffusion model.
A conditional diffusion model is trained to generate fine-scale residual fields given CU fields and auxiliary spatiotemporal conditioning. The CU fields are provided as spatial conditioning inputs and are augmented with geographical variables, including latitude, longitude, topography (
$ z $
 ), and land-sea mask (LSM). Temporal information is incorporated using cosine–sine representations of the day of year and hour of day (time embedding). The trained model generates residual fields (
$ {\mathbf{R}}^{\prime } $
 ) conditioned on the CU inputs and spatiotemporal context. The final HR prediction is obtained by adding the generated residual to the CU field (
$ {\mathbf{y}}^{\mathrm{CU}}+{\mathbf{R}}^{\prime } $
 ), which preserves large-scale consistency and enhances fine-scale details. The workflow is shown in Supplementary Appendix A.5. We set the optimal parameters of the sampler following an ablation study (Supplementary Appendix B.1). We trained a U-Net model as a baseline using the L2 loss function to predict the HR fields, using the network described in Supplementary Appendix A.2. The inputs include the CU fields, static geographical variables, and temporal embeddings. The diffusion model has 92,140,548 trainable parameters, compared with 92,135,940 for the U-Net baseline. The models were trained on data from 2015 to 2019, validated on 2020 data, and tested on 2021 data. Training ran for 100 epochs with a batch size of 70, using four NVIDIA A100 GPUs (64 GB each) on the LEONARDO supercomputer. Training, evaluation, and inference for the diffusion model took approximately 6 days.
As the current work focuses on the super-resolution step of downscaling, each HR prediction is compared with its corresponding ERA5 reference using pointwise metrics, complemented by distributional diagnostics. The primary metrics include the Mean Absolute Error
$ \mathrm{MAE}=\frac{1}{N}{\sum}_{\mathrm{n}=1}^{\mathrm{N}}\mid {y}_{\mathrm{n}}-{\hat{y}}_{\mathrm{n}}\mid $
 , the Normalized MAE
$ \mathrm{NMAE}={\sum}_{\mathrm{n}=1}^{\mathrm{N}}\mid {y}_{\mathrm{n}}-{\hat{y}}_{\mathrm{n}}\mid /{\sum}_{\mathrm{n}=1}^{\mathrm{N}}\mid {y}_{\mathrm{n}}\mid $
 , the Root Mean Square Error
$ \mathrm{RMSE}=\sqrt{\frac{1}{N}{\sum}_{\mathrm{n}=1}^{\mathrm{N}}{\left({y}_{\mathrm{n}}-{\hat{y}}_{\mathrm{n}}\right)}^2} $
 , the coefficient of determination
$ {R}^2=1-{\sum}_{\mathrm{n}=1}^{\mathrm{N}}{\left({y}_{\mathrm{n}}-{\hat{y}}_{\mathrm{n}}\right)}^2/{\sum}_{\mathrm{n}=1}^{\mathrm{N}}{\left({y}_{\mathrm{n}}-\overline{y}\right)}^2 $
 , and the Continuous Ranked Probability Score
$ \mathrm{CRPS}\left({F}_{\mathrm{n}},{y}_{\mathrm{n}}\right)={\int}_{-\infty}^{\infty}\mathrm{d}\hat{y}\hskip0.1em {\left({F}_{\mathrm{n}}\left(\hat{y}\right)-\mathbf{1}\left(\hat{y}-{y}_{\mathrm{n}}\right)\right)}^2 $
 . The CRPS is calculated using 100 time steps, for which the EDM sampler is run 10 times. Here,
$ {y}_{\mathrm{n}} $
 and
$ {\hat{y}}_{\mathrm{n}} $
 represent the HR fields from the ERA5 and predicted values,
$ \overline{y} $
 is the mean of the truth,
$ N $
 is the number of samples, and
$ F $
 is the predictive cumulative distribution function.
Power Spectral Density (PSD) analysis is used to evaluate the model’s ability to reconstruct spatial variability across scales, from large-scale structures to smaller scale features. Probability Density Functions (PDFs) on logarithmic scales enable comparisons of statistical distributions and the evaluation of extreme-value representation. Distributional consistency is further quantified using the Kullback–Leibler (KL) divergence
$ \mathrm{KL}\left(p\parallel q\right)=\int \mathrm{d}y\hskip0.1em p(y)\log \frac{p(y)}{q(y)} $
 , where
$ p $
 and
$ q $
 denote the reference and predicted PDFs, respectively. Additionally, the Pearson correlation coefficient
$ {\rho}_{\mathrm{p},\mathrm{q}}=\frac{\operatorname{cov}\left(p,q\right)}{\sigma_{\mathrm{p}}{\sigma}_{\mathrm{q}}} $
 is computed between the predicted and true fields to assess the similarity of their spatial patterns and overall structure, where
$ p $
 and
$ q $
 denote the flattened prediction and truth, respectively. The
$ q $
 th quantile of a sample
$ a $
 is
$ Q(q)=\left(1-g\right)\hskip0.1em y\left[j\right]+g\hskip0.1em y\left[j+1\right] $
 , with
$ y $
 sorted,
$ j=\left\lfloor \left(n-1\right)q\right\rfloor $
 , and
$ g=\left(n-1\right)q-j $
 .
For the diffusion model, we also evaluated rank histograms, which assess how well the predicted ensemble represents the truth, and the spread–skill ratio (SSR), which quantifies the consistency between ensemble spread and prediction error. Given an ensemble of size
$ M $
 (we used
$ M=10 $
 ), the sorted predictions are
$ {\hat{y}}_{(1)}\le {\hat{y}}_{(2)}\le \cdots \le {\hat{y}}_{(M)} $
 . The rank
$ r $
 of reference
$ {y}_{\mathrm{n}} $
 relative to the ensemble is given by
$ r={\sum}_{\mathrm{m}=1}^{\mathrm{M}}\mathbf{1}\left({\hat{y}}_{\mathrm{m}}\le {y}_{\mathrm{n}}\right) $
 , so that
$ r\in \left\{0,\dots, M\right\} $
 . The rank histogram is obtained by plotting the histogram of
$ r $
 over all prediction–truth pairs. The SSR is defined as
$ \mathrm{SSR}=\frac{\sigma_{\mathrm{ens}}}{\mathrm{RMSE}} $
 , where the ensemble spread is given by
$ {\sigma}_{\mathrm{ens}}=\sqrt{\frac{M+1}{M}}\sqrt{\frac{1}{N}{\sum}_{\mathrm{n}=1}^{\mathrm{N}}\frac{1}{M}{\sum}_{\mathrm{m}=1}^{\mathrm{M}}{\left({\hat{y}}_{\mathrm{n}}^{\left(\mathrm{m}\right)}-{\overline{\hat{y}}}_{\mathrm{n}}\right)}^2} $
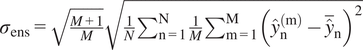 , and
$ \mathrm{RMSE}=\sqrt{\frac{1}{N}{\sum}_{\mathrm{n}=1}^{\mathrm{N}}{\left({\overline{\hat{y}}}_{\mathrm{n}}-{y}_{\mathrm{n}}\right)}^2} $
 . Here,
$ {\hat{y}}_{\mathrm{n}}^{\left(\mathrm{m}\right)} $
 denotes the
$ m $
 -th ensemble member (with
$ m=1,\dots, M $
 ),
$ {\overline{\hat{y}}}_{\mathrm{n}}=\frac{1}{M}{\sum}_{\mathrm{m}=1}^{\mathrm{M}}{\hat{y}}_{\mathrm{n}}^{\left(\mathrm{m}\right)} $
 is the ensemble mean,
$ {y}_{\mathrm{n}} $
 is the reference value, and
$ N $
 is the number of samples. The corrective factor in the definition of
$ {\sigma}_{\mathrm{ens}} $
 ensures the optimal value of the SSR is 1, as explained in Fortin et al. (Reference Fortin, Abaza, Anctil and Turcotte2014).
4. Results and discussion
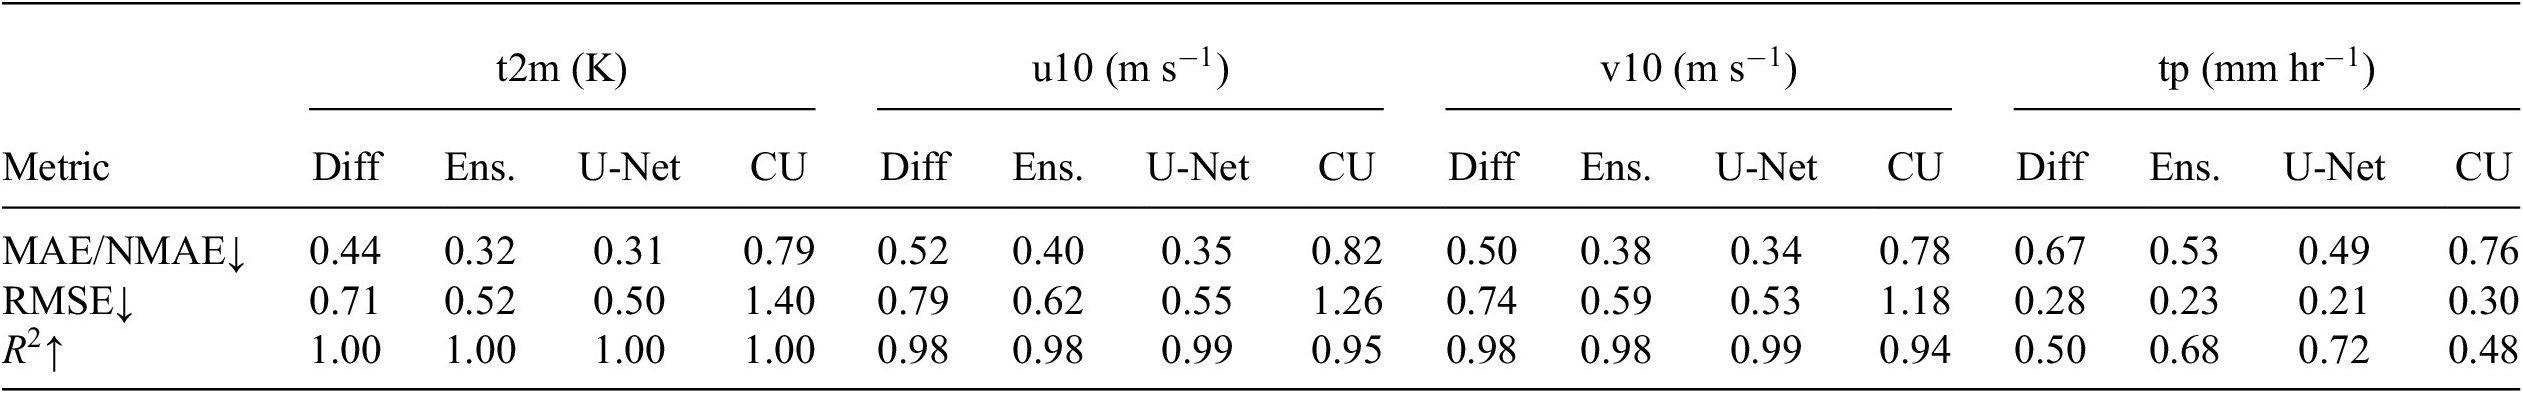
Figure 2 shows surface plots for the downscaled variables: t2m, u10, v10, and tp. Three representative members of a 10-member ensemble, the ensemble standard deviation, and a zoomed-in over South America are shown in Supplementary Appendix B.2 and Supplementary Appendix B.3, respectively. Visually, the model successfully reconstructs the fine-scale spatial details of the HR fields. Table 1 summarizes the performance of the CU input, U-Net, the diffusion model, and the diffusion ensemble mean. For t2m, the prediction achieves an MAE of
$ 0.44\pm 0.02 $
 K, an RMSE of
$ 0.71\pm 0.04 $
 K, and an
$ {R}^2 $
 of
$ 1.00 $
 . The corresponding ensemble mean improves these scores, with an MAE of
$ 0.32\pm 0.01 $
 K, an RMSE of
$ 0.52\pm 0.01 $
 K, and an
$ {R}^2 $
 of
$ 1.00 $
 . The wind components are predicted with similar accuracy. For u10, the prediction yields an MAE of
$ 0.52\pm 0.02 $
 m s
$ {}^{-1} $
 , an RMSE of
$ 0.79\pm 0.03 $
 m s
$ {}^{-1} $
 , and an
$ {R}^2 $
 of
$ 0.98 $
 , while the ensemble mean achieves an MAE of
$ 0.40\pm 0.01 $
 m s
$ {}^{-1} $
 , an RMSE of
$ 0.62\pm 0.03 $
 m s
$ {}^{-1} $
 , and an
$ {R}^2 $
 of
$ 0.988\pm 0.002 $
 . Similarly, for v10, the prediction has an MAE of
$ 0.50\pm 0.01 $
 m s
$ {}^{-1} $
 , an RMSE of
$ 0.74\pm 0.03 $
 m s
$ {}^{-1} $
 , and an
$ {R}^2 $
 of
$ 0.98 $
 , while the ensemble mean yields an MAE of
$ 0.38\pm 0.01 $
 m s
$ {}^{-1} $
 , an RMSE of
$ 0.59\pm 0.03 $
 m s
$ {}^{-1} $
 , and an
$ {R}^2 $
 of
$ 0.985\pm 0.002 $
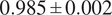 . For tp, the prediction shows an average MAE of
$ 0.10\pm 0.00 $
 mm hr
$ {}^{-1} $
 , which appears very low; however, the NMAE of
$ 0.67\pm 0.02 $
 indicates a larger relative error. The ensemble mean slightly improves the absolute error, with an MAE of
$ 0.055\pm 0.001 $
 mm hr
$ {}^{-1} $
 and an RMSE of
$ 0.234\pm 0.001 $
 mm hr
$ {}^{-1} $
 , while the NMAE remains relatively high at
$ 0.53\pm 0.01 $
 and
$ {R}^2 $
 reaches
$ 0.68\pm 0.01 $
 . The discrepancy between MAE and NMAE arises from the variable’s skewed distribution, characterized by a high frequency of zero values, which makes absolute error metrics less informative. Given its temporal and spatial variability, precipitation is one of the most complex fields to downscale; thus, the emphasis is on overall quality (see the following discussions).
Surface plots are shown for t2m, u10, v10, and tp (columns 1 to 4). The rows, from top to bottom, represent the CU ERA5 input, the HR ERA5 reference, the model prediction, and the difference between the prediction and the HR reference. All panels correspond to 2021-01-01 06:00 UTC.

Figure 2. Long description
The grid consists of four columns and four rows.
Column 1: Temperature [K]. The first three rows show a global heat map with high temperatures (red) near the equator and low temperatures (purple) at the poles. The bottom row shows the Delta Temperature [K] (Pred minus Truth) with a mostly white map indicating minimal error, with sparse red and blue speckles.
Column 2: Zonal Wind [m/s]. The first three rows show alternating bands of brown (positive) and teal (negative) representing wind direction. The bottom row shows Delta Zonal Wind [m/s] (Pred minus Truth) with very low intensity noise across the globe.
Column 3: Meridional Wind [m/s]. The first three rows show complex, swirling patterns of brown and teal. The bottom row shows Delta Meridional Wind [m/s] (Pred minus Truth) with faint, scattered noise.
Column 4: Precipitation [mm/h]. The first three rows show white maps with dark blue streaks representing high precipitation areas, primarily along the Intertropical Convergence Zone and storm tracks. The bottom row shows Delta Precipitation [mm/h] (Pred minus Truth) with purple and red clusters indicating localized prediction errors.
Row labels on the left are Coarse, Truth, Prediction, and Pred minus Truth. Color bars at the top and bottom define the scales for each variable and their respective difference maps.
Performance comparison of diffusion, ensemble diffusion, U-Net, and CU input

Table 1. Long description
The table compares four models: Diff (Diffusion), Ens. (Ensemble Diffusion), U-Net, and C U (C U input) across four variables: t 2 m (K), u 10 (m s super -1), v 10 (m s super -1), and t p (m m h r super -1).
* M A E / N M A E (lower is better):
- t 2 m: Diff 0.44, Ens. 0.32, U-Net 0.31, C U 0.79.
- u 10: Diff 0.52, Ens. 0.40, U-Net 0.35, C U 0.82.
- v 10: Diff 0.50, Ens. 0.38, U-Net 0.34, C U 0.78.
- t p: Diff 0.67, Ens. 0.53, U-Net 0.49, C U 0.76.
* R M S E (lower is better):
- t 2 m: Diff 0.71, Ens. 0.52, U-Net 0.50, C U 1.40.
- u 10: Diff 0.79, Ens. 0.62, U-Net 0.55, C U 1.26.
- v 10: Diff 0.74, Ens. 0.59, U-Net 0.53, C U 1.18.
- t p: Diff 0.28, Ens. 0.23, U-Net 0.21, C U 0.30.
* R super 2 (higher is better):
- t 2 m: All models show 1.00.
- u 10: Diff 0.98, Ens. 0.98, U-Net 0.99, C U 0.95.
- v 10: Diff 0.98, Ens. 0.98, U-Net 0.99, C U 0.94.
- t p: Diff 0.50, Ens. 0.68, U-Net 0.72, C U 0.48.
The CRPS metric is
$ 0.25\pm 0.01 $
 K for t2m,
$ 0.29\pm 0.01 $
 m s
$ {}^{-1} $
 for u10,
$ 0.28\pm 0.01 $
 m s
$ {}^{-1} $
 for v10, and
$ 0.04 $
 mm hr
$ {}^{-1} $
 for tp. Watt and Mansfield (Reference Watt and Mansfield2024) reported CRPS values of 0.254 K (t2m), 0.224 m s
$ {}^{-1} $
 (u10), and 0.232 m s
$ {}^{-1} $
 (v10) over the United States, whereas Mardani et al. (Reference Mardani, Brenowitz, Cohen, Pathak, Chen, Liu, Vahdat, Nabian, Ge, Subramaniam, Kashinath, Kautz and Pritchard2025), for the Taiwan domain, report higher values for extremes: 0.55 K, 0.86 m s
$ {}^{-1} $
 , and 0.95 m s
$ {}^{-1} $
 , respectively. The low CRPS for precipitation suggests that the model’s predicted distribution is confident, particularly in correctly capturing the prevalence of dry (zero-precipitation) conditions. Overall, the diffusion model yields physically consistent (an intervariable correlation analysis that is presented in Supplementary Appendix B.6) and statistically accurate downscaling, with the ensemble mean improving deterministic performance.
The statistical fidelity of the downscaled fields was evaluated by jointly analyzing density scatter plots, PDFs, and PSDs of the model predictions, the HR ERA5 reference, and the CU inputs (Figure 3). The first row displays density scatter plots comparing the diffusion model predictions with the HR reference across all variables. Each panel presents the joint distribution of values, with colors representing the logarithm of sample density and the one-to-one reference line. Quantitative metrics, including
$ {R}^2 $
 , MAE, and RMSE, are also given. For the t2m and (u10, v10) components, the predictions show a strong linear relationship with the reference fields, as indicated by points tightly clustered along the diagonal and
$ {R}^2 $
 values near
$ 0.99 $
 . Small vertical lines in the density plot for u10 and v10 indicate that some true values correspond to predicted values with the opposite sign. These discrepancies likely stem from challenges in downscaling coastal winds influenced by land–sea breezes (Figure 4) and affect only a small fraction of datapoints. For precipitation, although the scatter indicates increased spread, particularly at higher intensities, the model substantially sharpens near the center, reduces underestimation, and more closely aligns with the one-to-one relationship, producing the same zero-precipitation points.
Model evaluation for the complete 2021 evaluation dataset. Columns represent t2m, u10, v10, and tp, respectively. Rows display density scatter plots (top), PDFs (middle), and PSDs (bottom).

Figure 3. Long description
A series of four horizontal panels displaying global maps with red-shaded heat gradients.
* The first panel on the left shows M A E Temperature in Kelvin. Darker red concentrations are visible over Central Asia, Northern Africa, and the Andes mountain range. The scale ranges from 0 to 3.
* The second panel shows M A E Zonal Wind in meters per second. The error is distributed relatively evenly across the mid-latitudes with slight intensification over landmasses. The scale ranges from 0 to 3.
* The third panel shows M A E Meridional Wind in meters per second. Similar to the zonal wind, the error is widespread with minor peaks over mountainous regions. The scale ranges from 0 to 3.
* The fourth panel on the right shows M A E Precipitation in millimeters per hour. High error values are concentrated in a distinct horizontal band across the tropical Pacific and Atlantic oceans, as well as over the Amazon basin and Southeast Asia. The scale ranges from 0.0 to 1.0.
Spatial distribution of the MAE, averaged over the 2021 dataset, for the downscaled variables: t2m, u10, v10, and tp.

Figure 4. Long description
The figure is organized into a 3 by 4 grid.
Top Row: Scatter plots showing Predicted Values on the y-axis versus True Values on the x-axis. A color bar on the far right indicates log sub 10 (Count) from 10 super 0 to 10 super 8.
* Temperature (K): Linear correlation from 210 to 330. R super 2 is 0.999, M A E is 0.443.
* Zonal Wind (m/s): Concentrated along the diagonal from -40 to 40. R super 2 is 0.980, M A E is 0.524.
* Meridional Wind (m/s): Concentrated along the diagonal from -40 to 40. R super 2 is 0.976, M A E is 0.501.
* Precipitation (mm/h): High density near the origin (0,0) with a wide spread. R super 2 is 0.504, M A E is 0.067.
Middle Row: Line graphs showing log sub 10 (P D F) on the y-axis. Each plot compares Diffusion (solid blue), U-Net (dashed red), Truth (dashed green), and Coarse (dotted purple) data.
* Temperature (K): Multiple peaks between 225 and 300.
* Zonal Wind (m/s): A single bell-shaped curve centered at 0.
* Meridional Wind (m/s): A single bell-shaped curve centered at 0.
* Precipitation (mm/h): A sharp peak at 0 followed by a rapid decay.
Bottom Row: Line graphs showing P S D (k) on the y-axis versus Wavenumber k (cycles/degree) on a log-log scale.
* Temperature, Zonal Wind, and Meridional Wind: All models closely follow the Truth line, showing a linear decrease in power as wavenumber increases.
* Precipitation: The Coarse model (purple) drops off significantly earlier than the Diffusion and U-Net models, which stay closer to the Truth line until higher wavenumbers.
The model exhibits a strong capacity to replicate the full statistical distribution of t2m. The predicted mean (
$ \mu =278.89 $
 K) and standard deviation (
$ \sigma =21.33 $
 K) closely match those of the ground truth (
$ \mu =278.91 $
 K,
$ \sigma =21.32 $
 K), whereas the CU input displays a slightly reduced variance (
$ \sigma =21.18 $
 K). This high level of distributional agreement is quantitatively supported by a KL divergence of
$ 0.00 $
 and a Pearson correlation of
$ 1.00 $
 . The log-PDF curves of the prediction and reference are nearly indistinguishable across the t2m range, demonstrating accurate reproduction of both central tendencies and distribution tails. The model’s performance for the (u10, v10) components is comparably robust. For the u10, both the mean (
$ {\mu}_{\mathrm{pred}}=-0.04 $
 m s
$ {}^{-1} $
 ,
$ {\mu}_{\mathrm{truth}}=-0.04 $
 m s
$ {}^{-1} $
 ) and variance (
$ {\sigma}_{\mathrm{pred}}=5.63 $
 m s
$ {}^{-1} $
 ,
$ {\sigma}_{\mathrm{truth}}=5.64 $
 m s
$ {}^{-1} $
 ) are accurately captured, while the CU input underestimates variability (
$ \sigma =5.26 $
 m s
$ {}^{-1} $
 ). The predicted distribution aligns closely with the reference, as proved by a KL divergence of
$ 0.00 $
 and a Pearson correlation of
$ 0.99 $
 . The v10 shows similar results, with the model recovering the true variance (
$ {\sigma}_{\mathrm{pred}}=4.77 $
 m s
$ {}^{-1} $
 ,
$ {\sigma}_{\mathrm{truth}}=4.78 $
 m s
$ {}^{-1} $
 ) from the smoothed CU field (
$ \sigma =4.39 $
 m s
$ {}^{-1} $
 ), while maintaining a KL divergence of
$ 0.00 $
 and a Pearson correlation of
$ 0.99 $
 . Precipitation prediction presents significant challenges due to its intermittency, non-Gaussian distribution, and localized extremes. Nevertheless, the model demonstrates substantial improvement over the CU input, with a KL divergence of
$ 0.001 $
 and a Pearson correlation of
$ 0.73 $
 . The log-PDF indicates that the predictions more accurately capture the frequency of light-to-moderate precipitation and partially recover the tail of extreme events, which are suppressed in the CU field.
The U-Net baseline reproduces statistical distributions effectively (KL divergence and Pearson correlations of approximately
$ {10}^{-4} $
 and 0.99, respectively). However, its performance declines for precipitation with a KL divergence of 0.3. Analysis of residual fields (Supplementary Appendix B.4) shows that the U-Net generates PDFs that are more peaked and narrower than those from the diffusion model across variables, indicating underestimation of fine-scale variability and extremes.
The model’s ability to recover spatial variability across scales is evaluated by analyzing the PSDs of the generated fields and comparing them with the HR reference and the CU input, as illustrated in the third row of Figure 3. For all variables, the diffusion model prediction closely matches the reference spectrum throughout most of the resolved wavenumber range, extending into smaller scale regimes. The CU input shows significant depletion at high wavenumbers, reflecting the loss of small-scale variability due to spatial averaging. In contrast, the predicted spectra maintain both the spectral slope and amplitude, indicating the model’s capacity to reproduce physically consistent small-scale variability. U-Net spectra generally follow the large-scale truth data but exhibit earlier attenuation at higher wavenumbers, indicating a reduced ability to capture small-scale variability compared to the diffusion model. In the case of precipitation, the recovery of high-wavenumber energy is especially pronounced, signifying the restoration of fine-scale structures associated with convective and localized rainfall processes, which remain parameterized at the 25 km resolution. Only minor deviations are observed at the highest wavenumbers, where all spectra are affected by numerical noise and resolution constraints.
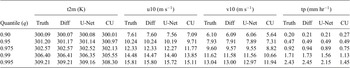
The model’s performance in predicting extreme values was quantified using quantile–quantile analysis of distribution upper tails (Table 2). For t2m, both diffusion model and the U-Net reconstruction closely match observed quantiles from 90th to 99.5th percentile. The diffusion model shows perfect agreement with truth (309.21 versus 309.21 K at
$ q=0.995 $
 ), while U-Net slightly underestimates the highest quantiles (309.16 versus 309.21 K). CU input underestimates high temperatures, with discrepancies reaching 0.91 K at the 99.5th percentile. For wind components, both models slightly underestimate extreme wind speeds. The diffusion model remains close to truth (15.80 versus 15.81 m s
$ {}^{-1} $
 at
$ q=0.995 $
 for u10), while U-Net shows larger underestimation (15.72 m s
$ {}^{-1} $
 ). Similar behavior occurs for v10. This shows both models reproduce most wind distribution, though capturing extreme events remains challenging. CU input performs worse, underestimating u10 extremes by 0.70 m s
$ {}^{-1} $
 at the 99.5th percentile. For precipitation, the diffusion model slightly underestimates moderate extremes but overestimates most extreme events (2.45 versus 2.43 mm hr
$ {}^{-1} $
 at
$ q=0.995 $
 ). The U-Net underestimates the upper tail more remarkably (2.15 versus 2.43 mm hr
$ {}^{-1} $
 at
$ q=0.995 $
 ). CU input overestimates lower precipitation quantiles but significantly underestimates the highest quantiles, with values below two-thirds of ground truth at
$ q=0.995 $
 .
Extreme true, diffusion model, U-Net, and CU input quantiles for the downscaled variables

Table 2. Long description
The table presents extreme quantiles (0.90, 0.95, 0.975, 0.99, and 0.995) for four variables: t 2 m in Kelvin, u 10 in meters per second, v 10 in meters per second, and t p in millimeters per hour. For each variable, four values are provided: Truth, Diff (Diffusion model), U-Net, and C U.
* For t 2 m (K):
- 0.90: Truth 300.09, Diff 300.07, U-Net 300.08, C U 300.01
- 0.95: Truth 301.20, Diff 301.17, U-Net 301.14, C U 300.97
- 0.975: Truth 302.57, Diff 302.57, U-Net 302.52, C U 302.13
- 0.99: Truth 306.40, Diff 306.41, U-Net 306.35, C U 305.55
- 0.995: Truth 309.21, Diff 309.21, U-Net 309.16, C U 308.30
* For u 10 (m s super -1):
- 0.90: Truth 7.61, Diff 7.60, U-Net 7.56, C U 7.09
- 0.95: Truth 10.24, Diff 10.24, U-Net 10.19, C U 9.71
- 0.975: Truth 12.33, Diff 12.33, U-Net 12.27, C U 11.77
- 0.99: Truth 14.48, Diff 14.47, U-Net 14.40, C U 13.85
- 0.995: Truth 15.81, Diff 15.80, U-Net 15.72, C U 15.11
* For v 10 (m s super -1):
- 0.90: Truth 6.10, Diff 6.09, U-Net 6.06, C U 5.64
- 0.95: Truth 7.93, Diff 7.91, U-Net 7.89, C U 7.31
- 0.975: Truth 9.60, Diff 9.57, U-Net 9.55, C U 8.82
- 0.99: Truth 11.62, Diff 11.58, U-Net 11.56, C U 10.66
- 0.995: Truth 13.04, Diff 13.00, U-Net 12.97, C U 11.94
* For t p (mm hr super -1):
- 0.90: Truth 0.20, Diff 0.21, U-Net 0.21, C U 0.27
- 0.95: Truth 0.47, Diff 0.49, U-Net 0.49, C U 0.49
- 0.975: Truth 0.92, Diff 0.94, U-Net 0.89, C U 0.75
- 0.99: Truth 1.71, Diff 1.73, U-Net 1.56, C U 1.13
- 0.995: Truth 2.43, Diff 2.45, U-Net 2.15, C U 1.45
Spatial error distributions indicate regional variation in model performance as illustrated in Figure 4. The MAE for t2m is higher at high latitudes, particularly near the poles, and in areas with complex topography, such as the Himalayas and the Andes. The (u10, v10) components also show increased errors in coastal regions and along steep topographic gradients, likely attributable to the modulation of surface winds by land–sea contrasts and orographic influences. In contrast, precipitation errors are most pronounced in the tropics, especially within the Intertropical Convergence Zone and over tropical rainforests, where intense and localized rainfall events pose significant challenges for downscaling. The analogous maps illustrating the relative error are provided in Supplementary Appendix B.5.
The rank histograms shown in Figure 5 are generally close to uniform, indicating that the diffusion model ensemble is reasonably well calibrated overall. However, the temperature histogram exhibits a slight upward slope with a negative bias, suggesting that the truth often lies above the ensemble members, indicating a tendency toward underestimation. The u10 histogram is fairly flat but shows a mild positive bias, pointing to a slight overestimation. In contrast, the v10 histogram is nearly uniform with negligible bias, indicating very good calibration. The precipitation histogram displays a noticeable spike at the lowest rank and a slight skew, suggesting that the truth frequently falls below the ensemble range, which implies overestimation and potential under-dispersion.
Rank histograms for the 10-member diffusion ensemble. Columns show t2m, u10, v10, and tp. Red dashed lines mark the expected uniform frequency.

Figure 5. Long description
A four-panel multiplot with a shared y-axis labeled Frequency and x-axis labeled Ranks from 0 to 10. Each panel includes a red dashed horizontal line at approximately 0.09 representing the expected uniform frequency and a Bias value in the top left.
* Panel 1 Temperature K. Bias -0.022. The blue bars show a linear increase from left to right, starting below the red line at rank 0 and ending above it at rank 10.
* Panel 2 Zonal Wind m/s. Bias 0.010. The bars are nearly flat and align closely with the red dashed line, showing a slight peak in the middle ranks.
* Panel 3 Meridional Wind m/s. Bias -0.000. The bars are almost perfectly uniform, following the red dashed line across all ranks.
* Panel 4 Precipitation mm/h. Bias 0.001. The distribution is L-shaped, with a very high peak at rank 1 followed by a gradual asymptotic decrease toward rank 10.
Figure 6 presents density plots of ensemble spread versus RMSE. The red dashed line represents the ideal 1:1 relationship (SSR = 1), which corresponds to a perfectly calibrated ensemble. All variables display SSR values slightly below 1, indicating a mild overall under-dispersion. The highest sample density is concentrated at low RMSE and low spread for all variables, which reflects strong predictive skill. Deviations from the 1:1 line become increasingly evident as the RMSE values increase. For u10, v10, and tp, the spread remains relatively small as RMSE increases, suggesting under-dispersion in higher error regimes. t2m exhibits a similar, though less pronounced, pattern.
Density plots of ensemble spread versus RMSE for t2m, u10, v10, and tp. The red dashed line indicates the 1:1 relationship corresponding to perfect spread–skill (SSR = 1). In each panel, the inset shows a zoomed-in view containing approximately 99% of the data points.

Figure 6. Long description
A four-panel density plot arrangement with a shared vertical color bar on the right. Each panel features a red dashed diagonal line representing a 1 to 1 relationship and an inset zoom of the high-density region near the origin.
* Panel 1 (Top-Left): Titled Temperature [K]. The y-axis is Ensemble std from 0 to 12 and the x-axis is R M S E from 0 to 12. S S R is 0.943. Data points are concentrated along the diagonal with a slight spread toward the x-axis.
* Panel 2 (Top-Center-Left): Titled Zonal Wind [m/s]. The y-axis is Ensemble std from 0 to 24 and the x-axis is R M S E from 0 to 24. S S R is 0.875. The data cloud is wider and sits lower than the diagonal line.
* Panel 3 (Top-Center-Right): Titled Meridional Wind [m/s]. The y-axis is Ensemble std from 0 to 20 and the x-axis is R M S E from 0 to 20. S S R is 0.866. Similar to zonal wind, the density is highest below the 1 to 1 line.
* Panel 4 (Top-Right): Titled Precipitation [mm/h]. The y-axis is Ensemble std from 0 to 30 and the x-axis is R M S E from 0 to 30. S S R is 0.786. The data is heavily skewed toward the x-axis, indicating under-dispersion.
The color bar on the far right is labeled log sub 10 [Count] on a scale from 10 super 0 to 10 super 6, transitioning from dark blue (low density) through green and yellow to dark red (high density).
5. Conclusions and limitations
This work introduces IPSL-AID, a diffusion-based generative model developed for global-to-regional climate downscaling, and presents its super-resolution component. IPSL-AID reconstructs HR fields of temperature, winds, and precipitation from coarse input data and their spatiotemporal context. The model is trained on ERA5 reanalysis using a novel random block sampling strategy, which allows for global applicability without the need for retraining in new regions. A key advantage of this approach is its probabilistic framework. By learning the underlying distribution of residuals at fine scales, IPSL-AID generates multiple plausible HR realizations from a single coarse input. This capability enables robust uncertainty quantification through ensemble spread analysis, rank histograms, and spread–skill ratio diagnostics.
Quantitative evaluation indicates that IPSL-AID achieves low deterministic errors (MAE of 0.44 K for T2m, 0.52 m s
$ {}^{-1} $
 for u10, and 0.50 m s
$ {}^{-1} $
 for v10) and accurately represents the statistical distribution of the variables. The model reproduces spatial variability across scales and captures extreme events, with quantile estimates closely matching observations up to the 99.5th percentile. IPSL-AID demonstrates robust performance across diverse atmospheric variables and regions while maintaining physical consistency, as shown by intervariable correlation analysis that reveals realistic multivariate dependencies, such as temperature–wind patterns over oceans and continents. The ensemble mean further enhances deterministic scores, reducing MAE to 0.32 K for T2m and 0.40 m s
$ {}^{-1} $
 for u10.
Despite its strengths, IPSL-AID exhibits certain limitations. Performance degrades in regions with complex topography (e.g., Himalayas, Andes), coastal zones, and areas characterized by intense convective precipitation, where errors remain elevated. For precipitation, the normalized MAE of 0.53 indicates a substantial relative error, despite a low absolute error, reflecting the inherent challenge of downscaling non-Gaussian fields. The rank histograms reveal systematic tendencies: a slight underestimation for temperature, a mild overestimation for u10 winds, and under-dispersion for precipitation extremes. Spread–skill analysis indicates under-dispersion in higher error regimes, suggesting the ensemble may not fully capture uncertainty in challenging conditions. Additionally, block boundary artifacts remain visible during global inference, and the five-year training period is short compared to the multi-decadal timescales typically required for climate studies. The computational demands of global training—six days on four A100 GPUs—may also limit accessibility for some research groups.
Several avenues for future development are planned. First, we aim to extend the model to additional atmospheric variables and apply the framework to downscale future projections from CMIP6 models. This will require developing and integrating appropriate bias correction or debiasing strategies (Wan et al., Reference Wan, Baptista, Chen, Anderson, Boral, Sha and Zepeda-Núnez2023, Reference Wan, Lopez-Gomez, Carver, Schneider, Anderson, Sha and Zepeda-Núñez2025). To address computational limitations, distributed multi-GPU training strategies will be explored to accommodate longer training periods (e.g., 40 years) while maintaining global coverage. For block boundary artifacts, several mitigation approaches are under investigation: (i) an overlap-block method with cosine-weighted blending during inference, (ii) explicit boundary regularization in the loss function to penalize discontinuities along seam lines, (iii) frequency domain spectral loss to suppress characteristic artifact frequencies, and (iv) adaptive Fourier domain filtering as a post-processing step.
Finally, we plan to incorporate additional conditioning variables (e.g., soil moisture and surface fluxes) and explore alternative diffusion formulations to improve performance for precipitation extremes. The apparent contradiction between low CRPS and high NMAE for precipitation reflects the different aspects they measure: CRPS captures probabilistic calibration, whereas NMAE reflects the difficulty of deterministic prediction for a non-Gaussian variable; with conditioning limited to topography, strong deterministic skill is not achieved.
Open peer review
To view the open peer review materials for this article, please visit http://doi.org/10.1017/eds.2026.10066.
Supplementary material
The supplementary material for this article can be found at http://doi.org/10.1017/eds.2026.10066.
Acknowledgments
We acknowledge the EuroHPC Joint Undertaking for awarding this project access to the EuroHPC supercomputer LEONARDO, hosted by CINECA (Italy) and the LEONARDO consortium through an EuroHPC Development Access call (EHPC-DEV-2024D10-070, EHPC-DEV-2025D08-095).
Author contribution
Conceptualization: All authors contributed equally. Data curation: K.K.; Formal analysis: All authors contributed equally. Funding acquisition: J.F.L, O.B, and K.A.; Investigation: All authors contributed equally. Methodology: All authors contributed equally. Project administration: O.B. and K.A.; Resources: O.B. and K.A.; Software: K.A. and K.K.; Supervision: J.F.L., O.B., and F.B.; Validation: K.K., K.A., and P.C.; Visualization: K.K., K.A., and P.C.; Writing—original draft: K.A.; Writing—review and editing: All authors contributed equally. All authors have reviewed and approved the final manuscript.
Competing interests
The authors declare none.
Data availability statement
The IPSL-AID source code is publicly available on GitHub at https://github.com/kardaneh/IPSL-AID. The specific code version, along with the pre-trained model checkpoints, configuration scripts, and the 2021 ERA5 dataset used for inference in this study, are archived and publicly accessible on Zenodo at https://doi.org/10.5281/zenodo.19200763.
Ethics statement
The research meets all ethical guidelines, including adherence to the legal requirements of the study country.
Funding statement
Project S24JROI011 supported this work from the Grantham Foundation (To K.A and O.B). R.L. acknowledges support from Agence Nationale de la Recherche – France 2030 through the PEPR TRACCS programme under grant number ANR-22-EXTR-0011 (LOCALISING).
Provenance
This article is part of the Climate Informatics 2026 proceedings and was accepted in Environmental Data Science on the basis of the Climate Informatics peer review process.






 Open access


Comments
Dear Editors,
Please find enclosed our revised manuscript entitled “IPSL-AID: Generative Diffusion Models for Climate Downscaling from Global to Regional Scales”, which we are pleased to submit for consideration for publication in Environmental Data Science.
This manuscript presents IPSL-AID, a generative diffusion-model framework for climate downscaling that enables the generation of high-resolution regional climate information from global-scale simulations. The work addresses an important challenge in environmental data science: developing data-driven approaches that can bridge global climate information and the spatial scales required for regional and local climate analysis. By leveraging generative diffusion models, our approach aims to provide a flexible and effective framework for producing realistic high-resolution climate fields while preserving relevant large-scale climate structures.
We believe that the manuscript is well aligned with the scope of Environmental Data Science, particularly its focus on innovative computational and data-driven methods for addressing challenges in environmental and climate science.
This revised manuscript incorporates the comments and suggestions provided during the review process. We sincerely thank the Meta-Reviewer and all Reviewers for their careful and constructive evaluation. Their feedback has substantially helped us improve the manuscript. We have addressed all comments in detail and have made the corresponding revisions throughout the manuscript.
We confirm that this manuscript is submitted for consideration by Environmental Data Science and that we have followed the journal’s submission requirements. We hope that the revised manuscript will be suitable for publication and will be of interest to the journal’s readership.
Thank you for your consideration. We look forward to hearing from you.
Sincerely,
Kazem Ardaneh
on behalf of all authors
IPSL, Sorbonne University
Paris, France