


1 Introduction
It is a standard assumption in constraint-based phonology that learning involves choosing both a ranking of constraints and a correct set of underlying forms. While a language's phonological properties can be uniquely described by its ranking, correct underlying forms for each lexical item are still crucial. Knowing the ranking *VoicedObstruentCoda≫Ident[voice] ensures that final /d/ maps to [t], but a speaker must also know the underlying voicing specification of every word-final obstruent to ensure that [rat] alternates correctly in suffixed forms, either as /rat+ə/→[ratə] or as /rad+ə/→[radə]. Learning underlying forms and rankings concurrently is particularly challenging, because assumptions about each can have consequences for the other; for relevant discussion, see Kager (Reference Kager1999), Boersma (Reference Boersma2001), Tesar et al. (Reference Tesar, Alderete, Horwood, Merchant, Nishitani and Prince2003), Jarosz (Reference Jarosz2006), Apoussidou (Reference Apoussidou2007), Tesar & Prince (Reference Tesar and Prince2007), Pater et al. (Reference Pater, Staubs, Jesney and Smith2012), inter alia.
One prominent strategy for tackling this problem is to divide and conquer: first learning just the surface phonotactics, regulating what is and is not observed in surface forms without reference to morphology, and only later incorporating evidence from alternations. This partitioning of the learning task allows the learner to initially ignore underlying forms, by assuming that mappings are always faithful. At the first stage, learning a language with final obstruent devoicing will mean observing unanalysed words like [rat], [ratə] and [radə], and constructing a grammar that treats each observed surface form as a fully faithful parse of some underlying form: /rat/→[rat], /ratə/→[ratə], /radə/→[radə]. We will call this approach Learning from the Identity Map.Footnote 1
Learning from the Identity Map has been very useful in the study of OT grammars and their learnability for at least two reasons. First, this approach appears to mirror natural L1 development. As emphasised by Hayes (Reference Hayes2004), perception studies have demonstrated convincingly that infants acquire extensive sensitivity to language-specific phonotactics before their first birthday (see, for example, the literature cited in Jusczyk Reference Jusczyk1997), while good evidence of alternations begins to emerge only at 14–17 months (see for example White et al. Reference White, Peperkamp, Kirk and Morgan2008). Very young learners must therefore acquire their knowledge of phonotactics without the paradigmatic evidence for unfaithful underlying forms – e.g. without knowing that [rat] and [radə] are related, and that they share the underlying representation /rad/.
Second, learning via the Identity Map in OT has proven quite successful in allowing a language's surface data to be captured restrictively. Error-driven learners can acquire phonotactics within this framework by examining a current grammar's errors, and reranking constraints via an algorithm which ensures that errors become suboptimal compared to the observed targets (§3 will provide careful illustration of this process). Some aspects of implementing this learning process have not yet been fully resolved (as observed by Prince & Tesar Reference Prince and Tesar2004 and Tessier Reference Tessier2007; see also Alderete & Tesar Reference Alderete and Tesar2002), but at least the correct ranking of markedness constraints in OT is easy enough to determine from errors when the Identity Map is assumed. As such, learning based on the Identity Map might well be the most effective simplifying assumption for establishing the crucial rankings that govern a language's phonotactics. (See Tesar Reference Tesar2008, Reference Tesar2011 for discussion of the informativeness of different types of mappings in OT learning.)
This paper demonstrates, however, that ease of learning is not stable across constraint-based frameworks. In Harmonic Serialism (starting with McCarthy Reference McCarthy2000, Reference McCarthy, Blaho, Bye and Krämer2007b), the Identity Map is in fact not at all suited to reasoning from observed errors to correct rankings – even when only the ranking of markedness constraints is involved.
2 Capturing inventory restrictions in constraint-based grammars
Various theoretical mechanisms exist for encoding phonotactic restrictions, but in Optimality Theory and related approaches this job falls solely to the workings of constraints. The constraint ranking is responsible for mapping the rich base of all possible underlying forms onto a language-specific set of licit surface forms, without any additional restrictions on the sounds or sequences posited underlyingly. For example, the claim that creaky front rounded vowels like [ ] are categorically absent from English is modelled by ranking the relevant markedness constraints above conflicting faithfulness constraints, thereby ensuring that any input // will map to a grammatical surface segment – perhaps a modal-voiced unrounded vowel, as in (1).Footnote
2
-
(1)


Under this ranking, input // undergoes two featural changes, losing its original specifications for both creak and rounding – and OT's parallel method of evaluation achieves these multiple changes in a single mapping. The fact that unrounding and loss of creak apply simultaneously is by now very familiar to OT practitioners, but it is still a peculiarity of the massively parallel candidate evaluation introduced by Prince & Smolensky (Reference Prince and Smolensky1993). In any framework where changes must be gradual, the ordering of those changes can have non-trivial consequences.
2.1 Capturing phonotactics in Harmonic Serialism
Harmonic Serialism (HS) is an alternative to parallel OT which was initially suggested by Prince & Smolensky (Reference Prince and Smolensky1993: 79), and which has been pursued in earnest in recent years, yielding some notable improvements in typological adequacy (see McCarthy Reference McCarthy2008a, Reference McCarthyb, Pruitt Reference Pruitt2010, Reference Pruitt2012, Jesney Reference Jesney2011, Kimper Reference Kimper2011, Elfner to appear, Pater to appear; and also §4.3). This paper cannot hope to argue comprehensively for Harmonic Serialism as a grammatical framework; instead, the focus here is on the properties of HS that affect the learnability of its grammars, and particularly on its implications for learning from the Identity Map.
At the heart of HS is a standard Eval function: the grammar takes an input and selects an optimal output, based on the relative ranking of markedness and faithfulness constraints. Crucially, and unlike parallel OT, HS is a fundamentally derivational model, which typically requires multiple loops through Eval to get from underlying to surface form. While a language's constraint ranking remains the same throughout the derivation, only the fully faithful form and forms that differ from the current input by a single change are considered as candidates at each step.Footnote 3 Once an optimum is selected, it becomes the input to the next step, where a similarly limited set of candidates is considered. In contrast to parallel OT, the transition from input to output in HS is therefore gradual.
In a Harmonic Serialist grammar, phonotactic restrictions are under grammatical control, just as they are in parallel OT. Due to the gradual nature of the model, however, any input that is more than one change away from a licit surface form will necessarily pass through Eval more than once in order to reach its optimal output state. In the example above, input // would need to pass through the derivation //→ø→[e] or the derivation //→ḛ→[e], where each form differs from the previous by a single change.
Crucially, such multi-step derivations require additional rankings of the markedness constraints that are unnecessary in parallel OT. One possible HS ranking that can map // to [e] is given in (2).
-
(2)
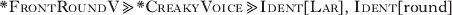
Given the ranking in (2), the derivation proceeds as follows. First, the HS Gen is fed an input, here //, and returns a finite set of output candidates, each of which differs from the input by a single change (characterising the set of ‘single changes’ is a large part of working on the theory – see McCarthy Reference McCarthy2010). In this example, Gen's operations will be changing the vowel's rounding and laryngeal specifications, so the candidate set for input // is (3).Footnote
4
-
(3)

Once the candidate set has been enumerated, Eval applies in its normal fashion to winnow the candidate set down to a single optimum. As the tableau in (4) shows, at this first step, the ranking in (2) prefers mapping // to [ḛ]. The licit output segment [e] is not a member of the candidate set at this stage, because it requires two featural changes.
-
(4)

Because the input and the output are non-identical, the output [ḛ] is taken as the input to the following step. Fed to Gen, this produces a new candidate set; the tableau in (5) shows the result of this second iteration.
-
(5)

Since /ḛ/→[e] only involves a change in laryngeal specification, [e] is an available output candidate at this step and, given the constraint ranking, is chosen as optimal. This form becomes the input for a third iteration, where the fully faithful form is selected. At this point the derivation is complete, and the third step's output is the final surface form.
-
(6)

For the purposes of this paper, the most important element of the derivation above is that the ranking of the two markedness constraints dictates the order in which processes apply. It is because *FrontRoundV is highest-ranked that the first step in (4) involves unrounding of the vowel. If *CreakyVoice were highest-ranked, the intermediate form [ø] would be selected at the first step instead, and the alternative path //→ø→[e] would prove optimal. In this case, both paths map input // to output [e], and so the ranking of the constraints affects only the internal workings of the grammar, not the surface vowel inventory.
There are many other circumstances, however, where the order of serial processes is indeed crucial in order for surface phonotactics to be adequately captured. The rest of this paper presents a specific example from one language, and demonstrates the challenge that such patterns present for any HS learner that acquires phonotactics via the Identity Map.Footnote 5
3 Learning a positional inventory restriction in Harmonic Serialism
3.1 The data: [+low] vowels in Punu
Our illustrative example comes from the distribution of low vowels in the Bantu language Punu, spoken in Gabon and the Republic of Congo. As described by Kwenzi Mikala (Reference Kwenzi Mikala and Nsuka-Nkutsi1980) and Hyman (Reference Hyman2002, Reference Hyman2008), Punu has eight surface vowels – [i u e o ε ɔ a ə] – whose distribution is restricted by phonological and morphological factors. The focus here is on the distribution of the vowels [ε e ɔ o], which Hyman (Reference Hyman2002, Reference Hyman2008) analyses together with [a] as phonologically [+low] (or ‘open’ in his terminology).
The vowels [o]∼[ɔ] and [e]∼[ε] participate in a productive [ATR] harmony process. As illustrated in (7a) for the back pair, these vowels surface as [+ATR] [o] when followed by [i], and as [−ATR] [ɔ] when followed by [ə]. The vowels [o] and [ɔ] are in free variation before [u], as shown in (7b).Footnote 6
-
(7)

The [+low] vowels are also subject to a positional restriction that limits them to radical (stem-initial) position. In (7) all instances of [o] and [ɔ] are stem-initial – either word-initial or following the [u-] infinitival prefix; Kwenzi Mikala (Reference Kwenzi Mikala and Nsuka-Nkutsi1980) provides similar data for [e] and [ε].Footnote 7 The [+low] vowel [a] respects the same basic distributional pattern, but can also appear in prefixes, and in certain additional morphological contexts that are set aside here (Kwenzi Mikala Reference Kwenzi Mikala and Nsuka-Nkutsi1980: 10–11). It is this basic positional restriction, and specifically its effect on the [−ATR] vowels [ɔ] and [ε], that is the primary focus of this section.
The restriction of [ɔ] and [ε] to stem-initial position can be captured using two interacting markedness constraints. The first, *Non-initial[+low], militates against [ε ɔ e o a] in positions outside the initial syllable of the stem. The second, *[−low, −ATR], militates against non-central [−low, −ATR] vowels, including [ı] and [ʊ], which are not found in the surface inventory of the language.Footnote 8 Prefixal quirks aside, these two markedness constraints are always obeyed in Punu, and so must outrank the conflicting faithfulness constraints Ident[low] and Ident[ATR] in the final grammar. Any general constraints on vowel-height features that are violated in Punu, like *[+low], will need to be dominated by Ident[low]. The HS ranking of this constraint set for Punu is given in (8).
-
(8)

The ranking of *Non-initial[+low] above *[−low, −ATR] is crucial to the treatment of input [ɔ] and [ε] vowels in non-initial positions. Given a hypothetical input like /pasɔ/, the grammar must ultimately map [ɔ] onto one of the vowels allowed in non-initial position, and any such mapping requires changes to multiple features of the input vowel. Mapping non-initial /ɔ/ to [u], for instance, requires changes to both the features [low] and [ATR]. The ranking of these two markedness constraints ensures that /ɔ/ is able to map to [u] by way of intermediate [ʊ].Footnote 9
Given input /pasɔ/, Gen provides the fully faithful candidate and the two unfaithful candidates [paso] and [pasʊ] as possible optima at the first step, but not yet the eventual winner [pasu]. With the ranking in (8), [pasʊ] is selected as optimal (9a). At the following step, the attested output form [pasu] is one change away from the new input and so is provided as a candidate by Gen and selected as optimal. With no further harmonically improving changes possible, the derivation converges at step 3 (not shown).
-
(9)

The ranking of [+low]/Non-initial above *[−low, −ATR] is key to this result; with the opposite ranking of these two markedness constraints, the initial mapping of /pasɔ/ to [pasʊ] would be blocked and /pasɔ/ would surface faithfully. With these facts in mind, we now turn to the Punu learning challenge of discovering these necessary rankings within HS using the Identity Map.
3.2 Learning Punu vowel distribution via the Identity Map
Following Smolensky (Reference Smolensky1996) and much subsequent work, we assume an initial state for learning in which all markedness constraints outrank all faithfulness constraints ({M}≫{F}). We assume further that this partial ordering is resolved into a total ordering every time the grammar is used (as argued for in Boersma Reference Boersma2009), so that all markedness constraints outrank all faithfulness constraints in the initial state, but vacillate in their ranking with respect to each other on every iteration of Eval.Footnote 10
-
(10)

From this {M}≫{F} starting point, the Identity Map learning approach attempts to discover the language's phonotactics by aiming to reproduce observed forms. When these attempts fail, the resulting errors are used to inform learning – i.e. the reranking of the implicated constraints. The learner of Punu will thus begin by observing surface forms like those in (7), and attempting to parse them as inputs using the grammar in (10). The ranking in (11) below represents one possible full ranking of the constraints that is consistent with the initial {M}≫{F} ranking.
Since [+low] vowels like [ɔ] are never observed outside of stem-initial position, and [−low, −ATR] vowels like [ı] and [ʊ] are never observed at all, the constraints *Non-initial[+low] and *[−low, −ATR] are not violated by any form inferred via the Identity Map. The only markedness constraint violated by identity mappings is thus general *[+low]. This is illustrated in (11), taking the observed surface form [posi] as input to the learner.
-
(11)

The error here is straightforward: while the target language allows the surface form [posi], the learner in the initial state instead raises the vowel, selecting the surface form [pusi]. Because [pusi] is the only candidate that violates none of the markedness constraints, it is the only optimum possible under any of the total rankings consistent with the {M}≫{F} initial state. Following Tesar & Smolensky (Reference Tesar and Smolensky1998, Reference Tesar and Smolensky2000) and much subsequent work, we refer to the observed target form [posi] as the ‘winner’ and the grammar's current optimum [pusi] as the ‘loser’. This terminology reflects the fact that under the ranking of the target grammar in (8) these forms are the ‘winner’ and ‘loser’ respectively. Given the Identity Map assumption, the ‘winner’ is consistently the fully faithful form, while the ‘loser’ will be one of the other candidates.
The ranking knowledge to be extracted from the error in (11) is elucidated in (12) using an Elementary Ranking Condition (ERC) vector (Prince Reference Prince2002). In this format, every column tracks whether a constraint prefers the winner (W), the loser (L) or neither (e).
-
(12)

The Constraint Demotion Lemma (originating in Prince & Smolensky Reference Prince and Smolensky1993: 148, and reworded with the terminology used in this paper in Prince & Tesar Reference Prince and Tesar2004: 255) characterises how an ERC vector's winner can be guaranteed to beat its loser – namely, for each error one of the constraints that prefers the winner must outrank all the constraints that prefer the loser. Achieving such a ranking is the first goal of the learner. Additionally, the learner must ensure that the grammar generates as few unobserved forms as possible – i.e. that it remains restrictive, e.g. Tesar (Reference Tesar1996). This goal of restrictiveness can be implemented as in Biased Constraint Demotion (Prince & Tesar Reference Prince and Tesar2004), with a persistent bias that favours all the initial state rankings, starting with {M}≫{F}, until evidence is given to the contrary (see also Hayes Reference Hayes2004).
For this biased learner, the ERC vector in (12) demonstrates that one M≫F ranking must be subverted: the only way to resolve the error is to rank the winner-preferring faithfulness constraint Ident[low] above the loser-preferring markedness constraint *[+low]. This ERC vector also demonstrates, however, that the remaining two markedness constraints do not distinguish between winner and loser, leaving them free to remain at the top of the hierarchy. The learner's new ranking after learning from the error in (12) is shown in (13).
-
(13)

With the Identity Map approach, the ranking in (13) is the end state of Punu phonotactic learning. Neither of the two top-ranked markedness constraints is violated on the surface, and so they never assign any Ls within the learner's ERC vectors. As a result, they remain undominated and unranked with respect to each other; no amount of additional Punu data can establish a ranking between them.
-
(14)

This situation is unproblematic for the parallel OT learner. As the tableaux in (14) show, when a full range of candidates is considered, this ranking is sufficient to ensure that [+low] vowels are tolerated in stem-initial syllables (14a), even as they are mapped unfaithfully in non-initial environments (14b). (For simplicity, only violations for the relevant vowel are shown.)
The end state of phonotactic learning in (13) does not, however, match the target HS grammar seen previously in (8). HS requires an additional ranking between the top two markedness constraints in order to restrict [+low] vowels to initial position. In the absence of a determined ranking, the learner must simply impose an ordering upon the unranked constraints. If, as in (15) below, the ranking *[−low, −ATR]≫*Non-initial[+low] is imposed, mappings like /pasɔ/→pasʊ→[pasu] are blocked. The fully faithful candidate [pasɔ] is selected at the first step, and the derivation converges upon an unattested surface form.Footnote 11
-
(15)

The end state in (13) is agnostic between the correct HS ranking in (8) and the incorrect one in (15). There is no way for the learner to detect the need for *Non-initial[+low] to dominate *[−low, −ATR] based on learning from the Identity Map. As a result, the learner's end-state grammar is insufficiently restrictive; faced with an input that violates the language's surface distributional pattern, the learner may incorrectly choose to map it faithfully.
Crucially, identifying this hidden markedness ranking is a problem just for HS. In parallel OT there is no need to rank these two markedness constraints with respect to each other, since both are always obeyed, and forms that diverge from the input in multiple ways can be immediately considered and deemed optimal (as illustrated above in (14)).
3.3 Diagnosing the problem of Punu vowels: blaming the Identity Map
We have already suggested that the HS phonotactic learner's failure to learn hidden rankings comes from its reliance on the Identity Map, rather than, for example, the constraint-demotion procedure itself. This section defends this analysis by reasoning from success: that is, by asking what kind of error could teach the learner that the ranking *Non-initial[+low]≫ *[−low, −ATR] is necessary in Punu.
In the case of Punu, the crucial error must cause the demotion of *[−low, −ATR], while leaving *Non-initial[+low] untouched. The error must therefore be one where, of the two markedness constraints, only *[−low, −ATR] is loser-favouring. In other words, the optimum selected by the current grammar – i.e. the loser – must contain fewer [−low, −ATR] vowels than the winner. Given the very limited candidate space considered thus far, this places [pasɔ] as the loser and [pasʊ] as the winner in the necessary error. In effect, the required winner∼loser pair is the first step of the derivation in (9) – i.e. /pasɔ/→pasʊ→[pasu].
-
(16)

This error provides the crucial evidence that *[−low, −ATR] must be demoted. Pairing it with the error in (12), as in (17) below, allows the learner to discover the hidden ranking.
-
(17)

An algorithm that can reason from (17) to the target ranking was described informally above, but its workings will now be illustrated step by step. This algorithm could be either Biased Constraint Demotion (Prince & Tesar Reference Prince and Tesar2004) or Low Faithfulness Constraint Demotion (Hayes Reference Hayes2004); with respect to these errors, they will find the same ranking. Both of these algorithms are biased to install markedness constraints as high as possible while building the new grammar stratum by stratum, beginning at the top. With the ERC vectors from (17) in hand, the first step is given in (18).
-
(18)

There is only one markedness constraint in (17) that is not loser-favouring on any comparison: *Non-initial[+low]. This constraint is installed in the top stratum, resolving the second error in (17). With only the first error left to resolve, the next stratum is built (shading indicates those constraints which have already been installed).
-
(19)

Step 1 then reapplies.
-
(20)

While *[−low, −ATR] does not prefer any losers, it also does not resolve the remaining error; its ‘e’ simply demonstrates to this learner that no evidence yet prevents the installation of *[−low, −ATR] in this relatively high-ranking stratum. In building the third stratum, the learner resolves the remaining error by installing the W-preferring faithfulness constraint.
-
(21)

With the installation of Ident[low], both errors in the ERC vector set have been resolved, and can be removed from the learning data. The ranking can then be completed purely on the basis of the learner's general biases – i.e. the preference for markedness over faithfulness rankings.
-
(22)

The final result, in (22b), is a success, capturing the hidden ranking necessary in order to ensure that the HS grammar selects the correct Punu output forms.
This walk-through of the learner's path based on the two ERC vectors in (17) demonstrates that error-driven HS learning can in fact find hidden rankings – but only with the correct data. Crucially, this requires an ERC vector like the one constructed in (16), where the winner [pasʊ] is not a possible surface form in the language being learned. Given the Identity Map assumption, this error should not be accessible to the learner.
Before moving on, we wish to emphasise that no observed surface form could substitute as the required winner in the ERC vector that drives learning of the hidden ranking *Non-initial[+low]≫*[−low, −ATR]. To create this ranking requires a candidate pair where *[−low, −ATR] is loser-favouring and *Non-initial[+low] is either winner-favouring or neutral. This means that the winner in this ERC vector must be [pasʊ], or some other non-observed form that includes a [−low, −ATR] vowel, while the loser must eliminate this vowel and so better satisfy *[−low, −ATR].
-
(23)

Because there are no surface forms in the language that contain [–low, –ATR] vowels, the constraint that favours [pasʊ] and causes it to win in (23) cannot be a faithfulness constraint. Input /pasʊ/ never maps faithfully onto itself in the target language, and so *[−low, −ATR] must dominate at least some faithfulness constraints that would prefer faithful mapping of /pasʊ/. The winner in (23) must therefore result from an unfaithful mapping of some other input, and this unfaithfulness must be driven by a markedness constraint that conflicts with *[−low, −ATR]. Within the limited space that we are considering here, the only input that meets these criteria is /pasɔ/, and the conflicting markedness constraint which prefers the winner [pasʊ] must be *Non-initial[+low].Footnote 13 We thus arrive at the fully specified ERC vector in (16).
In effect, learning from the Identity Map is only a modestly successful approach to learning an HS grammar. In cases where the observed output forms motivate the demotion of a markedness constraint to a position below faithfulness – as with the Ident[low]≫*[+low] ranking of Punu – the appropriate ranking can be achieved. In cases where a necessary ranking exists between two markedness constraints that are consistently satisfied at the surface, however, the Identity Map proves inadequate. Denied any informative errors, the learner fails to establish the crucial hidden ranking, and the end-state grammar proves insufficiently restrictive.
4 Possible solutions for the phonotactic learner
If the Identity Map is not sufficient to learn an HS grammar's hidden rankings, what conclusions can be drawn about the nature of the learner and the grammar?Footnote 14 We see three possibilities: (i) determining hidden rankings cannot be the goal of the HS learner during phonotactic learning, (ii) the learner must abandon HS as a model of grammar or (iii) the HS learner must abandon the Identity Map from the beginning, even when just learning phonotactics. This section briefly discusses these options, including the scope of the problem, and concludes in tentative support of the third possibility.
4.1 The scope of the hidden ranking problem
The origin of the hidden ranking problem lies in the limitations that HS places on the construction of the candidate set. As we have seen, in HS only candidates that differ from the current input by a single change are considered at each step in the derivation; this constrains the application of processes whose markedness benefits are only evident after further processes have applied. Coupled with the Identity Map, this means that only a very limited set of potential ‘losers’ is available for consideration in the construction of ERC vectors. Learning from the Identity Map presents a problem, then, for any derivational approach that requires harmonic improvement at each step. The question for this section is whether any refinements to the grammatical framework might facilitate the discovery of hidden rankings.
At least initially, Optimality Theory with Candidate Chains (OT-CC; McCarthy Reference McCarthy2007a – see also Walker Reference Walker2010) might appear to provide candidates that include enough information to avoid the learning problem discussed in this paper. In OT-CC, candidates are sequences of forms (‘chains’) comprising a mapping from input to output, with some chains involving multiple changes. These changes are still constrained, however, as each step in a candidate chain must be gradual and harmonically improving according to the constraint ranking of the language. In both HS and OT-CC, reliance on harmonic improvement makes (hidden) rankings of markedness constraints crucial – and reliance on the Identity Map means that these rankings cannot be consistently discovered.
Altering the mode of evaluation from ranked to weighted constraints, as in Harmonic Grammar (Legendre et al. Reference Legendre, Miyata and Smolensky1990, Smolensky & Legendre Reference Smolensky and Legendre2006; see also Potts et al. Reference Potts, Pater, Jesney, Bhatt and Becker2010, Pater to appear), likewise cannot eliminate the learning problem, provided that the requirements of gradualness and harmonic improvement are maintained. Indeed, if a learning model that assigns the same high initial weight to all markedness constraints and low initial weight to all faithfulness constraints is adopted (e.g. Goldwater & Johnson Reference Goldwater and Johnson2003, Jesney & Tessier Reference Jesney and Tessier2011), precisely the same problem as discussed in §3 will arise. Without the necessary evidence to force separation in the weights of markedness constraints that are consistently obeyed at the surface, no hidden ranking (or, in this case, hidden weighting) can be learned. Depending upon the specific assumptions about the initial state and the implementation of the bias, the Identity Map can also introduce further complications in a weighted-constraint version of HS. Because all constraint violations contribute to the selection of optima in weighted-constraint models, even very low-weighted faithfulness constraints can play a role. When learning from the Identity Map, faithfulness constraints consistently favour winners, and are therefore subject to increases in their weights. In order to establish a crucial hidden relationship between markedness constraints, then, the learner must achieve a large enough separation between their weights to overcome any faithfulness constraints that prefer a fully faithful but illegal mapping, like the one in (15).Footnote 15
The failure to learn hidden rankings also cannot be solved by encoding the constraint ranking in absolute numerical values and adding noise to the system, as in Stochastic OT (Boersma Reference Boersma1998, Boersma & Hayes Reference Boersma and Hayes2001 and subsequent works). If the critical markedness constraints have the same basic initial ranking value, noise will succeed in placing the constraints in the necessary configuration in some cases – 50% of the time if there are only two constraints whose ranking is crucial – but this will only be a temporary effect. Because these constraints are not implicated in any errors when learning from the Identity Map, their basic ranking values will not be altered, and the hidden ranking will not be learned. Including this type of noise within an HS framework may well be an effective means of capturing variation (e.g. Kimper Reference Kimper2011), and of ensuring that a full ranking of the constraints is employed by the learner on each iteration of Eval (Boersma Reference Boersma2009), but it does not provide a solution to the restrictiveness problem inherent to learning an HS grammar using the Identity Map.
We consider finally the possibility of solving the problem by changing the contents and the structure of Con. First, could the hidden ranking problem be avoided by better regulating the nature of the markedness constraints and their definitions? While this is a possibility in individual cases, it is not clear that it is a viable general solution. The constraints involved in the Punu hidden ranking are simple feature co-occurrence and positional markedness constraints of the type used in countless analyses. The required ranking of these constraints – with *Non-initial[+low] dominating *[−low, −ATR] – might suggest a revision to the learning algorithm biasing positional constraints toward higher ranking than general markedness constraints. As discussed initially by Prince & Tesar (Reference Prince and Tesar2004), however, this type of bias cannot be reliably implemented, because in the general case there is no reliable means of determining a priori which of two constraints targets a more specific context within a given language. Determining this relative specificity is a particular challenge when the features targeted are non-identical. In the current example, we note that, of the two markedness constraints, the higher-ranked one is if anything more general in its featural scope – that is, *[+low] rules out many more vowels than *[−low, −ATR] (see also the arguments in Tessier Reference Tessier2007).
Second, could the problem be avoided by relying on positional faithfulness rather than positional markedness to restrict Punu's non-low vowels to initial position? The answer here appears to be no. To suggest briefly why not, (24) provides a positional faithfulness translation of the Punu target ranking. The key here is the positional Ident[low]/Initial constraint that is ranked above general *[+low] at the top of the hierarchy. This ensures that initial [+low] vowels, as in [posi], are preserved.
-
(24)

Crucially, this grammar also includes a hidden ranking: *[+low]≫*[−low, −ATR]. Outside of initial position, the general *[+low] is now responsible for the first step in mapping unattested /pasɔ/ to [pasʊ] and then to [pasu]. This ranking is hidden, however, because outside of initial position there are no surface forms that violate either of these constraints, and therefore there are no accessible errors that could motivate the constraints' relative ranking. As long as the Identity Map assumption is maintained, the learning problem persists.
4.2 The need to learn hidden rankings without alternations
Given the results of the previous sections, it is worth emphasising that abandoning the goal of learning hidden rankings is not a viable option. Phonotactic learning must establish hidden rankings among undominated markedness constraints in order for various attested patterns to be captured. This is clear in Punu, where it appears that the morphology does not provide any alternations that could give evidence supporting the restriction on vowel heights outside of stem-initial position. The necessary hypothetical alternation would have to demonstrate that a surface form like [pasu] comes from the input /pasɔ/. While one could imagine scenarios that might provide this evidence – e.g. an opaque interaction whereby the underlying /ɔ/ triggers harmony before raising itself – Punu is not reported to have any such process. To deny the existence of hidden rankings learned solely from phonotactics, then, is to deny that Punu speakers should have any grammatical knowledge of the illegality of forms like /pasɔ/. In other words, it is to claim that their grammars can rule out non-initial mid vowels like [o], and also high [−ATR] vowels like [ʊ], but cannot construct derivations that rule out both for a single input.
While we cannot provide word-likeness ratings from Punu speakers to demonstrate this knowledge, it is well established that native speakers of better-studied languages are highly sensitive to static phonotactic regularities in their lexicons (e.g. Pertz & Bever Reference Pertz and Bever1975, Moreton Reference Moreton2002, Hayes & Londe Reference Hayes and Londe2006, Berent et al. Reference Berent, Lennertz, Jun, Moreno and Smolensky2008). Experimental studies have demonstrated that these sensitivities are under grammatical control, with speakers showing particular responsiveness to patterns that are robustly attested cross-linguistically (e.g. Moreton Reference Moreton2008, Becker et al. Reference Becker, Ketrez and Nevins2011). Alternations, then, cannot be required in order for the grammar to instantiate phonotactic patterns of the type observed in Punu. The learner must be able to acquire the necessary rankings on the basis of static distributional evidence alone.
4.3 The trade-off: Harmonic Serialism vs. the Identity Map
Harmonic Serialism has several key advantages in typological scope and efficacy compared to classic OT. For example, it offers a means of avoiding too-many-solutions problems involving medial cluster reduction (McCarthy Reference McCarthy2008a) and stress–syncope interactions (McCarthy Reference McCarthy2008b), it better predicts the factorial typology of iterative footing and stress (Pruitt Reference Pruitt2010, Reference Pruitt2012) and it offers a solution to pathologies arising with positional faithfulness constraints in parallel OT (Jesney Reference Jesney2011). On the other hand, other recent work has suggested that the type of fell-swoop derivations available in parallel OT are beneficial in capturing certain long-distance segmental processes (Walker Reference Walker2010, Kaplan Reference Kaplan2011; cf. Kimper Reference Kimper2012).Footnote 16 Should we therefore consider the present paper's learning result to be an argument for retaining classic OT's fully parallel evaluation?
Rather than concluding in favour of one framework over the other, our current goal is instead to identify the fundamental properties that distinguish parallel OT and HS, and then to ask what type of learner can best accommodate those properties. With regard to the learning problem raised by hidden rankings, we see the most crucial difference between the two frameworks to be the scope of the output candidate set available in any one evaluation. The limitation of the candidate set to forms that differ from the current input by a single change means that derivational paths which might ultimately lead to greater overall well-formedness are blocked if each step in the derivation is not itself harmonically improving. This has two effects: the candidate set in HS is considerably smaller than in parallel OT, and the ranking of constraints that are always satisfied at the surface becomes crucial.
One consequence of the difference in the candidate sets' scope might be that the child learning a parallel OT grammar is in greater need of a simplifying assumption like the Identity Map in order to identify informative errors and begin learning. The Identity Map assumption may be drastic in ignoring the possibility of unfaithful mappings in the target language, but it is sufficiently revealing to allow the parallel OT learner to learn key facts about the grammar's phonotactics. The HS learner, on the other hand, encounters a more manageable candidate set for any given input, but must also explore a wider range of input–output mappings to ensure that hidden rankings are discovered and a sufficiently restrictive grammar is built. The upshot might be the following trade-off: if the phonological grammar entertains a smaller set of output options for any given input form, its learner needs a larger set of input options in order to appropriately rank the relevant constraints. The Identity Map cannot be an effective simplifying assumption when it fails to provide the inputs necessary for adequate phonotactic learning.
5 Future directions
This paper has demonstrated that learning a restrictive grammar within Harmonic Serialism requires that the Identity Map be abandoned, so that unfaithful underlying forms are considered even during phonotactic learning. One means of addressing this issue is to give the learner complete access to the entire rich base of possible inputs, and then construct a grammar that will ensure that each of these inputs map to some observed surface form. Starting with Tesar & Smolensky's (Reference Tesar and Smolensky1998, Reference Tesar and Smolensky2000) work, assuming a rich-base approach has allowed for considerable progress on a number of OT learnability fronts; in particular, Jarosz's (Reference Jarosz2006) Maximum Likelihood learner explicitly entertains the entire rich base when acquiring a lexicon and grammar. While effective in many ways, it remains to us unclear that a rich-base approach can be effectively adapted to the real child's task of processing the impoverished data to which they are exposed. From our perspective, learning from the Identity Map was a highly effective starting point in parallel OT, and for the reasons discussed in §1, it remains worthwhile to consider some version of it in the HS context. The primary issue for future research on this question, then, is to establish a principled means of finding those input candidates that will allow the learner to make informative errors based on unfaithful mappings.
One avenue of investigation begins with the fact that the candidate set in HS is not only smaller than in parallel OT, but also more manageably structured. With this in mind, Tessier (Reference Tessier2013) sketches an HS learning technique which examines candidates that lose out in competition with observed surface forms, and then reasons backwards from such loser forms to the markedness constraints responsible, iteratively looking among these constraints for crucial hidden rankings. This technique exploits the gradualness property of HS, by initially expanding the set of inputs considered to include a carefully selected subset of forms that differ from the learner's current optimum by a single change. Staubs & Pater (to appear) tackle the issue of selecting underlying forms when learning an HS grammar along somewhat similar lines. In looking for an efficient solution to the problem of learning hidden structure and interacting processes, they strategically restrict their learner's input hypothesis space to include the Identity Map and a few crucial underlying forms that differ only in their violations of the key constraints.
Further research will determine whether any algorithmic approach to finding the necessary ERC vectors can be effectively applied to a range of cases without sacrificing too much of the simplicity afforded by the Identity Map. One potential complication lies in the possibility of multiple dependent hidden rankings – i.e. cases where more than two markedness constraints are crucially ranked with respect to one another (e.g. *A≫*B≫*C), with no surface evidence demonstrating their necessary configuration. In this circumstance, the learner will observe surface forms where losing candidates include violations of *C, but the search for unfaithful mappings will need to walk back through losers which violated *B, and then still other losers which violated *A, to find the entire hierarchy. Whether this process would prove tractable remains unknown. Regardless, our larger goal has been to demonstrate the difficulties in importing the learning assumptions of parallel Optimality Theory into the derivational world of Harmonic Serialism. It is the properties of each individual grammatical framework that will best determine how its languages can and should be learned.
 ], where the vowel is nasalised, and [
 ], where the vowel's [back] specification is altered. For simplicity we will consider only those candidates on the shortest path to the licit output [e].


