There is little doubt that adult SLA is different from typical child first language (L1) acquisition on many levels; however, there is no consensus as to what underlies observable dissimilarities in ultimate attainment and the path that leads to it. Focusing on the cognitive side of SLA—in the sense of the mental constitution of nonnative grammars—it is relevant to explore why adult SLA, as opposed to child L1 acquisition, is characterized by optionality and various degrees of fossilization, even at highly advanced proficiency levels (see, e.g., Lardiere, Reference Lardiere2007, Reference Lardiere2009; White, in press). This frequently observed phenomenon has prompted many acquisitionists from various cognitive traditions to argue that the processes of L1 and second language (L2) acquisition are maturationally conditioned to be different in the sense that the mechanisms that result in implicit acquisition for child language acquirers are no longer available to postcritical period adult learners (e.g., Bley-Vroman, Reference Bley-Vroman1990, Reference Bley-Vroman2009; DeKeyser, Reference DeKeyser2000; Long, Reference Long2005; Paradis, Reference Paradis2004; Ullman, Reference Ullman2001). On the other hand, empirical studies have demonstrated that L2 grammars provide robust evidence of incidental (i.e., nonexplicit) acquisition of target L2 properties, even despite poverty of the stimulus for their instantiation (see Rothman, Reference Rothman2008; Slabakova, Reference Slabakova2008). As Schwartz and Sprouse (Reference Schwartz, Sprouse and Archibald2000) argued, L2 competence for such properties constitutes robust evidence that adult SLA is guided by the same inborn linguistic properties as child L1 acquisition, which are taken to be Universal Grammar (UG).
One consequence of the claim that adults continue to have access to UG is the need to accompany this position with tenable explanations for the observable differences between L1 and L2 acquisition in developmental path and ultimate attainment. To explain the persistence and seeming pervasiveness of optionality in adult SLA, several contemporary generative L2 proposals, collapsed here under the label representational deficit accounts (RDAs),Footnote 1 have modernized the essence of earlier proposals of UG inaccessibility (e.g., Bley-Vroman, Reference Bley-Vroman1990; Tsimpli & Roussou, Reference Tsimpli and Roussou1991), claiming that many L1-L2 differences are representational within the L2 narrow syntax (e.g., Beck, Reference Beck1998; Franceschina, Reference Franceschina2001; Hawkins & Chan, Reference Hawkins and Chan1997; Hawkins & Franceschina, Reference Hawkins, Franceschina, Prévost and Paradis2004; Hawkins & Hattori, Reference Hawkins and Hattori2006; Hawkins & Liszka, Reference Hawkins, Liszka, van Hout, Hulk, Kuiken and Towell2003; Tsimpli & Dimitrakopoulou, Reference Tsimpli and Dimitrakopoulou2007).
According to current Minimalist Program assumptions (see Chomsky, 2001, Reference Chomsky2007), crosslinguistic differences in terms of which functional categories and features are instantiated in particular language grammars are driven by the acquisition of the lexicon within the primary linguistic data of the target language. Because UG is purported to provide a universal superset of formal features and functional categories, each particular grammar is, in a sense, a dialect of UG, in that it embodies a subset of its available features. Under such a view, the learning task of the child is relatively straightforward: To be able to parse and produce target input or output, upon exposure to primary linguistic data, the child selects from UG’s inventory which categories and features to instantiate, based on the particular grammar lexicon that best fits his or her interpretation or parse of the environmental input. The learning task for L2 adults is not a priori different from that of the child, which is not to ignore the fact that the process in adulthood is as much aided as it is complicated by intervening factors, such as the need to overcome learnability constraints arising from previous linguistic knowledge, more developed cognitive skills, differences in ability to process input, and so on. In addition to these factors, RDAs essentially claim that UG’s superset inventory of features is no longer available to the adult learner. Depending on the particular RDA proposal, only features instantiated within the L1 and, at most, new interpretable features—those relevant to the semantic component—are assumed to remain available.Footnote 2 This assumption amounts to an adult inability to reset the mental representations of syntactic properties in the L2, at least when they are contingent on the acquisition of new uninterpretable features. Essentially, RDAs maintain that the underlying syntax of L2 grammars is destined to remain like the L1 grammar, with only surface adjustments (e.g., in the acquisition of the L2 lexicon). RDAs assume that adult L2 learners can and do map L1 features onto newly acquired L2 morphophonological forms (but see Beck, Reference Beck1998). However, apparent L2 success that cannot be explained via L1 transfer and feature remapping is attributed to domain-general learning, which, in turn, is taken to account for ubiquitous L2 optionality, precisely because the underlying L2 grammatical representations are nontargetlike.Footnote 3
Despite the observable differences between L1 and L2 development and ultimate attainment, another position that has been argued to be empirically tenable is that of full accessibility to UG in adulthood (see, e.g., White, Reference White2003). Such a position does not diminish the significance of observable L1 and L2 differences but rather suggests that inaccessibility to UG is not the source of these problems. Insofar as the logical problem of primary language acquisition—inevitable L1 convergence on grammatical knowledge not exemplified in available input—is accounted for via UG, which fills the apparent gap between input and L1 end-state grammatical competence, full UG accessibility for adult L2 learners is supported by the apparent logical problem of SLA (see Schwartz, Reference Schwartz1998; Schwartz & Sprouse, Reference Schwartz and Sprouse1996, Reference Schwartz, Sprouse and Archibald2000). A significant and growing number of studies demonstrate true L2 knowledge of poverty-of-the-stimulus properties (see Rothman, Reference Rothman2008). On the one hand, because poverty-of-the-stimulus knowledge is taken to be prima facie evidence for UG in the first place (see Thomas, Reference Thomas2002), poverty-of-the-stimulus effects in SLA provide direct evidence that new (morpho)syntactic features (beyond those found in the L1) are available to adult L2 learners in the absence of sufficient or unambiguous evidence for their acquisition or learning in the L2 input. On the other hand, full-accessibility (FA) approaches have long pointed to L1 transfer as a possible source of L1-L2 differences in developmental sequence and ultimate attainment and maintain that L1 transfer alters significantly (and variably, depending on the L1-L2 pairing) the L2 learning task (but see Epstein, Flynn, & Martohardjono, Reference Epstein, Flynn and Martohardjono1996; Platzack, Reference Platzack and Clahsen1996). It has been argued within FA approaches that transfer can impose insurmountable learning obstacles, which result in representational differences despite full accessibility to UG (see Schwartz).
However, it has been taken as uncontroversial that L1 transfer alone cannot account for all the observed L1-L2 differences. A theory that claims adult access to UG’s full feature inventory without any further specifications thus appears to be in a weaker position than RDAs to explain why adult L2 (performance) outcomes are decisively different than in the case of child L1. Understanding the need to provide accounts of L1-L2 differences that are empirically verifiable and falsifiable, contemporary FA approaches maintain that L2 optionality does not necessarily result from deficits within the narrow syntax but instead may emerge from external learnability constraints and interface vulnerabilities (see Reference White, Ritchie and BhatiaWhite, in press). For example, the syntax-morphology-phonology interface has been shown to be especially vulnerable in adult SLA. Adult L2 acquirers, irrespective of their L1 and of the target L2, typically demonstrate target-deviant use of L2 functional morphology, differing from native adults and child L1 learners in their use of correct functional morphology (e.g., nominal agreement, verbal agreement, verbal tense, aspect, modal morphology) in discourse performance. Although incorrect L2 morphological production often decreases over time with an increase in proficiency levels, L2 morphological use rarely indistinguishably matches that of native speakers, even at the highest of L2 proficiency levels (see, e.g., Franceschina, Reference Franceschina2005; Lardiere, Reference Lardiere2007).Footnote 4 However, there is disagreement as to what these observations mean for the debate on adult access to UG. RDAs maintain that morphological optionality obtains precisely because the mental syntactic representation of the overt morphology is target-deviant (e.g., Franceschina, Reference Franceschina2001, Reference Franceschina2005; Hawkins & Franceschina, Reference Hawkins, Franceschina, Prévost and Paradis2004; Hawkins & Liszka, Reference Hawkins, Liszka, van Hout, Hulk, Kuiken and Towell2003). This position is consistent with the fact that problems in target morphological suppliance decrease over time as learners have a greater chance to apply rules based on pattern or frequency learning. FA accounts, on the other hand, appeal to the partial disassociation between morphological use and underlying syntactic representation (see, e.g., Lardiere 2007, 2009; Prévost & White, Reference Prévost and White2000) and point out that if morphological optionality were to indicate actual syntactic deficits, as claimed by RDAs, then syntactic and semantic reflexes that fall out from the L2 feature representation would be expected to demonstrate indeterminacy as well.
To investigate this possibility of indeterminacy, the current study tests English learners of L2 Spanish on the use of nominal morphology (gender and number). The syntactic and semantic reflexes of new nominal phi-feature acquisition in L2 Spanish are examined, focusing on properties that are directly related to noun-raising, an operation that is obligatory in Spanish to check nominal phi-features (number, person) but that English lacks. If RDAs are correct, then the L2 learners should demonstrate more than mere nominal morphological optionality and also show incomplete knowledge (as compared to native speaker controls) of the relationship between the syntactic position of adjectives in Spanish and the semantic restrictions on adjectival interpretation. However, if L2 learners demonstrate knowledge of the syntactic and semantic reflexes of adjective placement in line with native speakers, FA accounts will be supported and RDAs will not. The data from two tasks, related to the semantic interpretations of adjectives restricted by the syntactic structure and feature specification in Spanish, indicate that RDAs cannot account for the present L2 Spanish knowledge.
SYNTAX AND SEMANTICS OF THE SPANISH DETERMINER PHRASE
The relevant similarities and differences between Spanish and English regarding syntactic and semantic properties of different elements within the determiner phrase (DP) are discussed here. The DP is a functional projection instantiated in both languages that encompasses the elements that form the nominal structure, including determiners (e.g., definite and indefinite articles), adjectives, and nouns, among others. The relevant DP properties are grammatical features (e.g., gender and number) and the syntactic structure that relates nouns and adjectives in connection with their semantic interpretation.
The Syntax of Gender, Number, and the Resulting Word Order Within the DP
In addition to subject-verb agreement, Spanish shows overt agreement internal to the DP. Differently from English, adjectives and determiners must morphologically agree with the noun they modify in both gender and number, as illustrated in (1).
(1) La mujer americana baila.
The-fem-sing woman-fem-sing American-fem-sing dance-pres-3sg
“The American woman dances.”
Spanish has masculine and feminine morphological genders.Footnote 5 Most masculine nouns are marked by the suffix –o, whereas most feminine nouns are marked by the suffix –a. Exceptions for both genders end mainly in –e or a restricted number of consonants.Footnote 6 Spanish nouns are also inflected for plural number with the suffix –s.
Within the DP, English marks plural number morphology on nouns (represented in regular cases by the suffix –s). However, it lacks morphosyntactic gender features that trigger gender agreement within the DP (between the noun head and determiners or adjectives).Footnote 7 Additionally, English determiners are largely devoid of morphosyntactic number agreement (although demonstratives like this and these are inflected for number), and no English adjectives are inflected for number.
In the DP across languages, the determiner is the head of the nominal projection and selects a noun phrase (NP) as its complement. Depending on the language, additional projections are required within the DP in addition to the NP. The current analysis, based on aspects of Bernstein (Reference Bernstein1993, Reference Bernstein, Baltin and Collins2001) and others, assumes that the functional categories number (Num) and word marker (WM) sit between DP and NP, heading their own phrases ([DP D [NumP Num [WMP WM [NP N]]]]) and checking and valuing number and gender features, respectively.Footnote 8 The examples in (2) schematize the structure for Spanish DPs assumed herein.Footnote 9
(2) a. valientes incas “brave Incas” b. incas valientes “brave Incas”


Romance (Spanish) DPs instantiate the functional categories WM and Num, and gender and number feature checking within these categories requires overt raising of the noun head, as shown in (2). Under a minimalist approach, following Bernstein (Reference Bernstein1993; see, e.g., Cinque, Reference Cinque, Cinque, Koster, Pollock, Rizzi and Zanuttini1994; Picallo, Reference Picallo1991; Zagona, Reference Zagona2002), the head noun obligatorily raises from N to the head of WMP and then to the head of NumP. Overt noun-raising in Spanish can be triggered by an uninterpretable feature (e.g., a N feature) in the heads WM and Num. Crucially, Germanic (English) DPs, however, only have NumP, and number features are checked only via Agree, without overt raising of the noun.Footnote 10, Footnote 11 This parametric difference results in partially distinctive word orders for adjectives and nouns in both types of languages.
Because nouns must raise in Spanish, if an adjective is merged in an adjunct position to NP, noun movement to the head of WMP (and then to the head of NumP) results in the noun-raising past the adjective, producing the canonical noun-adjective (N-Adj) word order of Spanish (2b). However, because noun-raising is obligatory in Spanish, the noun must have moved to a higher position than the NP even when a surface Adj-N order obtains. In such cases, which correspond to the word order in (2a), the adjective phrase (AP) must adjoin to the specifier (Spec) of NumP, which results in a structure that on the surface appears to have English word order; however, the noun has actually moved to the head position of NumP. In English, this noun movement operation does not take place within the DP because there is no feature associated with either WM or Num that forces overt noun movement, which results in the only possible word order (Adj-N) at the surface in English.
Semantic Effects of Adjective Placement
There are thus two distinct groups of languages regarding the canonical position of adjectives: languages with prenominal adjectives (e.g., Germanic) and languages with postnominal adjectives (e.g., Romance). In Spanish, there are a few kinds of attributive adjectives that can only appear prenominally or postnominally (3a–3d). However, for a large set of (but not all) attributive adjectives, the position in which an adjective is ultimately realized (prenominal or postnominal) depends on the nature of the adjective’s semantic interpretation.
(3) a. La mera necesidad
“The mere necessity”
b. *La necesidad mera
“The mere necessity”
c. Las cortinas italianas
“The Italian curtains”
d. *Las italianas cortinas
“The Italian curtains”
Many adjectives can alternate between a prenominal and a postnominal position. Although these adjectives can keep a single lexical meaning, they display additional interpretive properties depending on whether they appear prenominally or postnominally. As can be seen by comparing (4a) and (4b), focus or emphasis can force adjectives to appear prenominally (see Demonte, Reference Demonte, Kennedy and McNally2008, for an analysis of this interpretive possibility).
(4) a. Unos libros interesantes
“Some interesting books”
b. Unos interesantes libros (focus interpretation, intonational stress not needed)
“Some interesting books”
Such possibilities introduce significant complexities in the syntax-semantics properties of adjectives that learners are expected to master. Crucially, learners need to master an additional twofold distinction in the interpretation of adjectives that alternate between prenominal and postnominal positions in Spanish, a distinction that is the focus of the experiments presented here. First, the adjective can restrict the set to which the NP refers, such that it delimits a subset of all possible members of this set. This interpretation, which will be referred to as set-denoting, matches the postnominal position of the adjective, as in (5b). Alternatively, the adjective must be interpreted as applying to all possible members of the set referred to by the noun. This interpretation, referred to as kind-denoting, matches the prenominal order of the adjective, as in (5a). The set-denoting interpretation of the adjective results from the adjunction of the AP to the NP projection, whereas the kind-denoting interpretation results from adjunction of the AP to the NumP. Crucially, in English, which does not display overt noun-raising within the DP, both interpretations map to the same prenominal placement of the adjective.Footnote 12
(5) a. Los valientes incas (kind-denoting)
b. Los incas valientes (set-denoting)
“The brave Incas”
The current study focuses on the syntactic and semantic properties—which correspond to the set- versus kind-denoting interpretation—of adjectives in L2 Spanish and adopts the basic aspects of a syntactic analysis that includes Num and WM in order to represent this distinction.
The Task for the English Learner of L2 Spanish
The syntactic and semantic properties that correspond to the set- versus kind-denoting interpretation of adjectives that must be mastered by English learners of L2 Spanish are highlighted here. Regarding the syntax, both languages exhibit the order Adj-N. However, differently from English, Spanish favors a N-Adj order, which obtains after noun-raising across the AP base position within the NP. The order Adj-N, which appears to be similar on the surface to English but is underlyingly distinct in Spanish, obtains after the AP adjoins to a higher position (NumP) as the result of noun-raising.
Crucially, for a large class of adjectives in Spanish, English L1 speakers need to learn that each of the two distinctive semantic interpretations is captured by a distinct syntactic word order (prenominal vs. postnominal adjectives). When these adjectives are realized prenominally in the position in NumP, they are interpreted as kind-denoting. When they are adjoined lower to the NP, they yield postnominal order after noun-raising and carry a set-denoting interpretation. English and Spanish are thus different in that prenominal adjectives can be unambiguous for a kind-denoting interpretation only in Spanish because each of the two available interpretations maps to a distinct linear order in Spanish. In English, adjectival interpretation is inherently ambiguous precisely because adjectives underlyingly link to either a high or a low position in the DP without varying in their linear or surface position with respect to the noun (because the noun does not raise, yielding the order Adj-N).
The parametric difference implicated here is whether the language requires overt noun-raising (which is a reflex of particular DP features that Spanish has and English lacks). Because Spanish requires nouns to raise, adjectives that are able to occupy more than one syntactic position can yield a distinct semantic interpretation (set- or kind-denoting) for each order. For the English learner of L2 Spanish, given the interaction of adjectives and nouns in the Spanish DP, its functional categories and features yield a learning task different from that involved in learning English L1 properties. Crucially, converging on the target syntax and semantics of Spanish adjectives involves the acquisition of the properties that require obligatory noun-raising, which English lacks. Furthermore, English L2 learners of Spanish are required to map each of the two distinct syntactic structures (N-Adj, Adj-N) to one of the two available semantic interpretations. However, in Spanish and other Romance languages, some types of adjectives can display mutually exclusive word order possibilities based on the subclass to which they belong. Spanish input does not provide L2 learners unambiguous input on adjectival syntax (i.e., from a frequency or linear learning point of view). Because it is not the case that all adjectives in Spanish are able to alternate their position, there does not seem to be sufficient unambiguous evidence of the type that one would need for English learners to straightforwardly induce via frequency alone the distinct syntactic structures and corresponding semantic interpretations of different adjectives in Spanish. Following Anderson (Reference Anderson2007a), there are three criteria that must be satisfied for learners to gain target knowledge of adjectival distribution from available input or instruction: (a) Input or instruction must robustly represent all possible contexts of use, (b) input or instruction must provide evidence such that learners notice that a certain (morphosyntactic) structure is possible in one (semantic) context but not another, and (c) it must be ensured that interference or noise does not prevent the emergence of this knowledge.
Tutored instruction does not faithfully or sufficiently account for the distribution of adjective placement and their entailed meaning alternations in native language corpora (see Anderson, Reference Anderson2007b).Footnote 13 Tutored learners are instructed that adjectives most naturally appear to the right of Spanish nouns and that some exceptions exist but that they correspond to referential, meaning-changing adjectives (e.g., pobre hombre “unfortunate man” vs. hombre pobre “materially poor man”). Crucially, L2 learners are not taught about the set- versus kind-denoting readings—the fact that these interpretations map to distinct syntactic orders—nor which adjectives (or adjective classes) allow this twofold syntax-semantics distinction.
Instruction, when available, thus does not provide or cover all contexts that one would need for attaining nativelike knowledge of the syntax of adjectives and nouns in the DP and their interpretations in Spanish. Moreover, it is not guaranteed that the semantic nuances of adjectival and noun placement explored here can be intuited unambiguously from the type of input provided in classrooms, based on frequency and contexts (see also Anderson, Reference Anderson2007b). Given this difficulty, the fact that the advanced learners of this study are able to interpret adjective position in a way equivalent to monolingual native speakers provides strong evidence against RDAs in adult SLA.
PREVIOUS STUDIES
The SLA of the features associated with the DP in several languages has been examined in previous studies, some of which have direct implications for the present study. Parodi, Schwartz, and Clahsen (Reference Parodi, Schwartz and Clahsen1997) demonstrated that SLA within the DP is relatively unproblematic when relevant L1 and L2 features are the same. However, this does not mean that if the L1 and the L2 share the same DP features, no developmental delays should be expected. For example, Bruhn de Garavito and White (Reference Bruhn de Garavito, White, Pérez-Leroux and Liceras2002) showed that French learners of L2 Spanish experience developmental target-deviant performance that might seem surprising, given that French has the same formal nominal features as Spanish.
In the case that the L1 and the L2 have different feature compositions, expected and possible outcomes for L2 convergence are less clear. Several researchers have investigated the acquisition of L2 DP syntax, motivated by the hypothesis that functional features not instantiated in the L1 become unavailable past the critical period (e.g., Franceschina, Reference Franceschina2001, Reference Franceschina2005; Granfeldt, Reference Granfeldt2000; Hawkins, Reference Hawkins1998; Hawkins & Franceschina, Reference Hawkins, Franceschina, Prévost and Paradis2004). Citing considerable variability with gender assignment on determiners and adjectives, these studies have posited that the mental representation of grammatical gender for English adult learners of Spanish and French is inevitably different; that is, differences in morphophonological suppliance were taken to indicate L2 inaccessibility to particular representational resources after the critical period.
Other research, however, argues that the problem is likely one of performance; that is, it is not a representational problem within the narrow syntax (Bruhn de Garavito & White, Reference Bruhn de Garavito, White, Pérez-Leroux and Liceras2002; Cabrelli, Iverson, Judy, & Rothman, Reference Cabrelli, Iverson, Judy, Rothman, Chan, Kapia and Jacob2008; Gess & Herschensohn, Reference Gess, Herschensohn, Camps and Wiltshire2001; Judy, Guijarro-Fuentes, & Rothman, Reference Judy, Guijarro-Fuentes, Rothman, Bowles, Foote, Perpiñán and Bhatt2008; White, Valenzuela, Kozlowska-MacGregor, & Leung, Reference White, Valenzuela, Kozlowska-MacGregor and Leung2004). If the position that L2 learners in general have problems with target L2 morphological suppliance is on the right track, then some level of production problems should be expected for all learners of a given L2—not only for those whose L1s do not have the syntactic features the morphology represents. Bruhn de Garavito and White demonstrated that despite the fact that French has grammatical gender, French learners of L2 Spanish also have problems with gender assignment similar to the pattern of difficulties noted for English learners of L2 Spanish (see Fernández, Reference Fernández, Gutiérrez-Rexach and Martínex-Gil1999; Judy et al.). Although this finding could support Beck’s (Reference Beck1998) version of the RDA (because she claims that features are transferred but remain permanently inert), this possibility is nullified by the data from advanced French learners in Bruhn de Garavito and White, who overcame the purported morphological problem. More recent research by White et al. and Cabrelli et al. has shown for L2 and L3, respectively, that syntactic reflexes of acquiring new Romance DP features—namely, nominal ellipsis (N-drop)—is accomplished early on by English adult learners.
In contrast, little or no research has been done on the partially related domain of acquisition of the syntactic and semantic properties of adjectival placement in L2 Spanish. Closely related to the current study, a series of recent articles on the acquisition of adjectival placement in L2 French have direct implications for similar research in L2 Spanish. Anderson (Reference Anderson, Camps and Wiltshire2001, Reference Anderson2007a, Reference Anderson2007b, Reference Anderson2008) investigated issues related to learnability (i.e., the effect of explicit teaching in the classroom) and parametric change (i.e., the effect of UG constraints in parameter resetting) in the nominal DP system in L2 French. Anderson’s studies examined, on the one hand, the differentiation between result and process nominals in the licensing of postnominal genitives and, on the other hand, the distinction between prenominal and postnominal adjectives in the two different contexts (i.e., unique vs. nonunique noun referents). Anderson’s (Reference Anderson, Camps and Wiltshire2001, Reference Anderson2007b, Reference Anderson2008) studies overall show that whereas parametric (i.e., representational) change is possible in what he contends is a poverty-of-the-stimulus context, as related especially to adjectival position and its semantic correlates, such change is not immediate, straightforward, or perfectly reflected in aggregate group data based on academic course levels. The cross-sectional data presented here are in line with what Anderson found for L2 French and support his conclusions as well as provide new and unique insight.
THE CURRENT STUDY
Participants
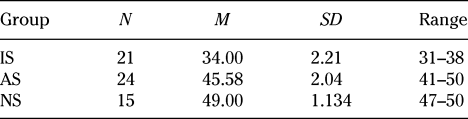
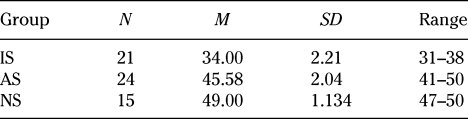
Three groups of participants took part in the current study: an intermediate adult L2 learner (IS) group, an advanced adult L2 learner (AS) group, and a native Spanish-speaking control (NS) group.Footnote 14 Each participant took a standardized written Spanish proficiency test with a maximum total possible score of 50, the results of which are summarized in Table 1.Footnote 15 The test consisted of a cloze section and a vocabulary section. Based on this test, the L2 learners were placed into two proficiency levels: 40–50 was the range used for the advanced level and 30–39 was the score range used to place individuals into the intermediate level. Any participant scoring less than 30 overall was deemed not to have achieved the minimum proficiency level necessary for the meaningful assessment of the theoretical approaches under investigation and was thus excluded from the study.
Proficiency scores by group
The NS group consisted of 15 participants from various Spanish-speaking countries whose ages ranged from 22 to 39 years. The AS group consisted of 24 participants with an age range of 23–32 years, all of whom were, at some point, instructed learners of Spanish but none of whom were currently enrolled in Spanish language courses. The IS group consisted of 21 participants whose ages ranged from 19 to 28 years, all of whom were taking university-level Spanish courses at the time of testing. Each participant completed a background questionnaire that sought information concerning, for example, their country of origin (all L2 participants were from the United States), the languages spoken in their home and the frequency with which each language is or was spoken (childhood bilinguals of Romance languages were eliminated, leaving only one German-English bilingual), the type and age of first exposure to Spanish, any courses the participant had taken in the Spanish language, and any other connection to the Spanish language that would provide the learner with extra input. To qualify as a L2 participant in this study, the first significant exposure to Spanish needed to have come via formal instruction and after the age of 14. At the moment of testing, the average time since first significant exposure to Spanish for the IS group was 4.9 years, with a range of 3–7 years. For the AS group, this average time was 8.46 years, with a range of 6–10 years.
Methodology
The current study provides a comprehensive and detailed analysis of two experimental tasks on the adjectival distinction between set- and kind-denoting interpretations, which are related to distinct syntactic features of the Spanish DP (including, in particular, uninterpretable features that trigger noun-raising in Spanish). In both tasks, following Anderson (Reference Anderson2007a, Reference Anderson2007b, Reference Anderson2008), the use of adjectives taught to L2 learners as so-called meaning-changing adjectives based on syntactic position (such as pobre, which can mean “materially poor” or “unfortunate, pathetic” depending on its placement relative to the head noun) was purposefully avoided.
Only adjectives that clearly maintain the same referential meaning irrespective of whether they appear prenominally or postnominally were selected. Alternating the syntactic position of such adjectives only affects the set to which the DP refers—that is, whether the adjective must be interpreted as pertaining to all possible members of the nominal set (a kind-denoting reading) or only to a subset of these members (a set-denoting reading). Only adjectives that allow a distinct target interpretation for each position, prenominal or postnominal, were selected, avoiding adjectives often taught to L2 learners as being lexically specified to appear in only one position. Therefore, these 20 adjectives, all of which meet the selection criteria, were used for both tasks: apasionado “impassioned,” aventurero “adventurous,” barato “cheap,” bonito “pretty,” cariñoso “caring,” caro “expensive,” deshonesto “dishonest,” enojado “angry,” estudioso “studious,” estúpido “stupid,” fuerte “strong,” honesto “honest,” importante “important,” inteligente “intelligent,” influyente “influential,” orgulloso “proud,” patético “pathetic,” valiente “brave,” simpático “nice,” and talentoso “talented.” Each adjective was used only once in each of the two tasks. For example, the adjective cariñoso “caring” was provided postnominally in a token for the first task (with a set-denoting reading). However, in the second task, cariñoso “caring” was provided with a context only felicitous with a kind-denoting reading and therefore should have been placed prenominally. If a L2 learner performed in line with natives across both tasks, then this learner was able to select the proper meaning or syntactic position (as required in the first and second experimental tasks, respectively) for each and every adjective, based on the syntactic position in which the adjective was provided in the test sentence (task 1) or on the meaning given in the context (task 2).
For statistical analyses in both tasks, the number of the L2 learners’ correct responses was assessed against the average number of answers provided by the NS group (which showed agreement of 93% or higher for each exemplar, consistent with the distinctive placement for nouns in the kind- and set-denoting readings in Spanish). Any deviation from the average native control answers was counted as incorrect, for example, if a participant (native or L2) indicated that both interpretations or syntactic positions were possible, chose the wrong answer, or claimed to not know such an answer.
Task 1: Semantic Interpretation Task
The first of the two tasks was a semantic interpretation task, designed to test the participants’ interpretation of both prenominal and postnominal adjectives. Participants were instructed to read a sentence that contained either a prenominal or postnominal adjective and to circle the correct interpretation of the underlined DP, out of two possible interpretations. To avoid the risk of favoring a certain interpretation beyond the syntactic structure of the DP, no additional discourse context for the test sentence was provided. It is important to note that the participants were instructed to circle both interpretations if they believed both answers to be possible (which English readily allows with its canonical Adj-N order) or to circle neither if they had no intuition. Because participants were not forced to choose one answer over the other, this task is considered to be a valid and reliable measure of implicit interpretation. There were 20 target sentences, 1 for each of the 20 adjectives; the 10 prenominal-adjective and 10 postnominal-adjective sentences served as counterbalances to each other. Examples with postnominal, set-denoting adjectives and prenominal, kind-denoting interpretations are shown in (6) and (7), respectively. Fillers (n = 20) such as (8) presented two nouns with different genders and a clitic that could only refer to one of the nouns, which required the learners to choose an interpretation for the clitic that matched the correct noun. Participants were not given a time limit and were permitted to ask the researcher about any vocabulary they did not understand. Bold boxes contain the correct interpretations.
(6)
(7)
(8)


Task 2: Context-Based Collocation Task
The second task was a context-based collocation task. Its purpose was to determine if the L2 participant groups could accurately produce prenominal and postnominal adjectives that would correctly match a description of either a set-denoting or a kind-denoting interpretation of the adjective-noun pair. If learners produce targetlike word order, this would indicate that noun-raising is obligatory in their Spanish grammar to account for the postnominal placement of the adjective with a set-denoting reading and that the adjective also needs to attach to a higher node (NumP) to allow its prenominal placement with a kind-denoting reading. In the task, participants were presented with a short context in Spanish describing only one possible semantic interpretation and were instructed to write the adjective provided in bold at the end of the sentence, in either a prenominal or postnominal blank. As in the first task, the instructions indicated that participants were permitted to write the adjective in both spaces if they believed both choices were equally possible or to leave both spaces blank if they had no relevant intuitions. There were 20 target sentences, 10 of which called for a prenominal adjective and 10 of which called for a postnominal adjective (using the same adjectives from task 1 and alternating the set- vs. kind-denoting interpretation across the list of adjectives). As in task 1, the target sentences served to counterbalance each other. Tokens of each type are shown in (9) and (10). The supporting context that introduced each test item matched only a set-denoting or a kind-denoting interpretation. If participants chose only the prenominal or only the postnominal placement for the adjective to match each context, this was a significant indicator that they unambiguously matched that placement with the provided interpretation.Footnote 16 Fillers for this task also employed clitics. The participants were asked to place the provided clitic in either a preverbal or postverbal position, alternating between finite clauses (which only allow proclisis) and nonfinite clauses (infinitives and gerunds, which allow both proclisis and enclisis).
(9) Prenominal adjective (kind-reading)
No hay super-héroe que no sea conocido por su coraje y fuerza; es decir ser super-héroe es tener mucho poder. Los super-héroes nunca tienen miedo de nada. (valiente)
“There is no super-hero that is not known for his or her courage and strength; that is, being a super-hero is having a lot of power. The brave superheroes are never afraid of anything.”
(10) Postnominal adjective (set-reading)
Entre los alumnos, siempre hay un equilibrio de inteligencia y estupidez en una escuela. Los estudiantes siempre están en las clases de ‘honor.’ (estudioso)
“There is always a balance of intelligence and stupidity in every school. The studious students are always in the honor classes.”
RESULTS
The statistical analyses presented here compare the performance of the three participant groups using a mixed-model ANOVA. Bonferroni post hoc tests were conducted when necessary and all analyses used a significance level of α = .05.
Empirical Results of the Semantic Interpretation Task
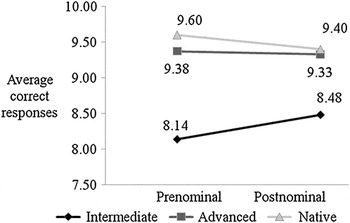
The purpose of the first task was to test for accurate semantic interpretations of prenominal and postnominal adjectives. The average number of correct responses (out of a total of 10) for each group can be seen in Figure 1. As Figure 1 shows, the AS group’s average number of correct responses for prenominal adjectives is very similar to that of the NS group (9.38 and 9.60, respectively). The IS group’s average correct responses (8.14) is below both the NS and the AS groups’ averages. Regarding the average number of correct responses for the postnominal adjectives, the AS group is nearly identical to the NS group (9.33 and 9.40, respectively). The IS group’s average correct responses (8.48) is again below the NS group and the AS group’s average correct responses for the postnominal adjectives. A mixed-model ANOVA revealed a main effect for proficiency level, F(2, 57) = 9.94, p < .001. There was no main effect found for adjectival position, F(1, 57) = 0.051, p = .822. Finally, no interaction between proficiency level and adjectival position was found, F(2, 57) = 1.341, p = .270. Bonferroni post hoc tests revealed no significant difference between the NS and the AS groups (p = 1.00); however, significant differences were found between the NS and the IS groups (p < .01) as well as between the AS and the IS groups (p < .01).
Results for task 1 (semantic interpretation).

The results of the semantic interpretation task indicate that the AS group interpreted both prenominal and postnominal adjectives as the NS group did. In contrast, significant differences were found between the IS group’s interpretation of adjectival position and that of both the NS and AS groups. The significance of these findings is that in intermediate stages of linguistic development, L2 learners did not consistently interpret the semantic nuances of adjectival positioning as the NS group did. However, with around 85% accuracy, the IS group performed well above chance and made the proper contrast in interpretation, albeit less precisely than the AS and the NS groups. Furthermore, the results indicate that the comparatively nonnativelike IS group’s trend is not permanent, as seen in the AS group, which demonstrates that, with continued exposure to Spanish, accurate semantic interpretations (set-denoting or kind-denoting) can be assigned to each adjective placement without significant optionality. These findings are noteworthy in that, unlike the possible syntactic positioning of the adjectives (tutored learners are explicitly told that most adjectives follow the noun in Spanish), the interpretations of the two positions are not explicitly taught in the way that one would need to acquire the full native distribution. At best, some adjectives are taught as being able to take a canonical and noncanonical syntactic position, but crucially no L2 instruction is provided that matches either placement with the set- versus kind-denoting entailment of the DP interpretation. Additionally, the proper interpretation that corresponds to each syntactic placement is not unambiguously evident from the input (especially considering that the position of each adjective may block or favor other interpretive options beyond the set- vs. kind-denoting contrast).
Empirical Results of the Context-Based Collocation Task
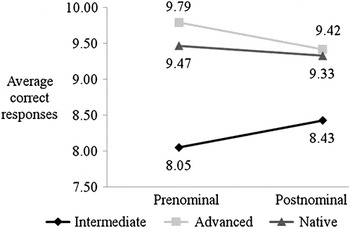
The purpose of the second task was to test for the accurate production (via collocation) of prenominal and postnominal adjectives. For each of the three participant groups, the average number of correct collocations (out of a total of 10) in the two contexts is shown in Figure 2. It is apparent that the AS group average is similar to that of the NS group for prenominal adjectives (9.79 and 9.47, respectively) as well as for postnominal adjectives (9.42 and 9.33, respectively). In contrast, the IS group’s average number of correct collocations is below that of the NS group for prenominal adjectives (8.05 and 9.47, respectively) and for postnominal adjectives (8.43 and 9.33, respectively). To establish with greater accuracy if the L2 participant groups performed like the NS group, two further analyses were completed. The first, a mixed-model ANOVA, revealed that there was a main effect for proficiency level, F(2, 57) = 8.158, p < .01. No main effect for the position of the adjective was found, F(1, 57) = 0.040, p = .842. There was no interaction between adjectival position and proficiency level, F(2, 50) = 1.257, p = .292. Bonferroni post hoc analyses revealed no significant difference between the NS and the AS group (p = 1.000). Nevertheless, significant differences were found between both the NS and the IS groups (p < .016) and the AS and the IS groups (p < .01).
Results for task 2 (context-based collocation).

The results of the context-based collocation task revealed that the AS group placed both prenominal and postnominal adjectives as the NS group did, thus indicating that they could accurately interpret and, more importantly, produce both prenominal and postnominal adjectives based on the semantic interpretation favored by the context.Footnote 17 The findings from this task are significant in that they show that L2 learners (in this case, the AS group) are not only able to access the distinct semantic interpretations like natives but also to map such interpretations to the correct syntactic structure like natives. The most probable explanation for the AS group’s performance is that these learners have in fact acquired a nativelike underlying structure of the Spanish DP regarding the relevant syntactic-semantic properties. In contrast, the IS group performed with optionality in recognizing the semantic interpretations that result from the two syntactic positions. However, as was the case in task 1, the IS group made proper distinctions at a rate well above chance (above 80% correct), which could indicate that, for at least some learners, the L2 syntax is correctly set as early as the intermediate level of overall proficiency.
DISCUSSION
One privilege for an empirically based field is that it produces its own evidence to test between competing proposals. New empirical evidence in SLA, such as that provided in the current study, thus allows for the epistemological testing and effective assessment of different theories. Other things being equal, all theories worthy of serious consideration must strive to account for available data. Considering the present data, the position that adults have partial or no access to UG and thus have no other recourse but to acquire a L2 via domain-general learning is a radical one. Examining L2 knowledge of semantic reflexes of functional morphology (e.g., resulting from feature checking) has proven important in testing RDA predictions. Previous work (see Slabakova, Reference Slabakova2006, Reference Slabakova2008) has demonstrated that L2 learners come to acquire very subtle semantic nuances that fall out from the checking of new L2 functional features. Examining this type of L2 knowledge is pivotal because it can allow researchers to substantiate claims that available input (L1 and L2 alike) either entirely lacks necessary evidence for a given property or provides impoverished or ambiguous evidence that, based on frequency alone, could not yield proficient acquisition of target interpretive properties.
The empirical results of the current study add to the latter type of research, providing further evidence against the predictions of RDAs. The results of a third task, not discussed in detail here, show that these intermediate and advanced learners of L2 Spanish are sensitive to gender morphology concord, the morphophonological representation of the features that bring about adjectival position alternations in Spanish. All participants completed a grammaticality judgment task (GJT) with correction, which tested L2 knowledge of good and poor morphological agreement (gender and number) in determiner-noun (Det-N) and N-Adj combinations (see the Appendix for a summary of the data).Footnote 18 The fillers for the GJT involved acceptability judgments and correction of prenominal and postnominal adjective placement, specifically of those that can only be prenominal or postnominal as part of their lexical properties (e.g., nationalities, which can only be postnominal in Spanish). The GJT results confirm the performance patterns revealed in previous studies that focused on DP morphology and tested comparable experimental groups (Bruhn de Garavito & White, Reference Bruhn de Garavito, White, Pérez-Leroux and Liceras2002; Fernández, Reference Fernández, Gutiérrez-Rexach and Martínex-Gil1999; Judy et al., Reference Judy, Guijarro-Fuentes, Rothman, Bowles, Foote, Perpiñán and Bhatt2008; White et al., Reference White, Valenzuela, Kozlowska-MacGregor and Leung2004). However, it could be argued that L2 knowledge of overt morphological gender concord and postnominal adjective placement of the type tested here is merely consistent with the possibility of new feature acquisition but in no way constitutes unassailable evidence for new feature acquisition. In this case, morphological agreement and postnominal adjective placement are (a) abundantly frequent in the input and thus inductable from frequency patterns, (b) explicitly taught to learners, and (c) in the case of placement, could derive from surface reordering (e.g., rightward movement, which is UG-compatible but could be transferred from the L1). This would be sufficient to account for plausible sources in the L1 or in instruction for the knowledge that L2 learners demonstrate in such a task. Therefore, results of the GJT alone would make it impossible, a posteriori, to differentiate between domain-general and domain-specific learning.
However, although RDAs could account for the data from the GJT task via domain-general learning, they cannot explain the results of the tasks presented in detail in the present article, given the clear predictions these results make for L2 knowledge of semantic reflexes that fall out from the checking of new L2 features. RDAs would instead predict optionality regarding the assignment of distinct semantic interpretations that match the syntactic structure corresponding to each placement of Spanish adjectives within the DP. First, recall that not all Spanish adjectives are able to appear both prenominally and postnominally; therefore, available L2 input is not devoid of the noise that needs to be eliminated to allow unambiguous evidence for frequency accounts (in the sense of Anderson, Reference Anderson2007a). Second, although some (not all) tutored learners receive explicit instruction that adjectives can appear in both syntactic positions, they are presented with incomplete lists that are lexically based and contain only the most common or salient ones. These adjectives are often treated by instructors as a restricted group of special cases, despite the fact that a large number of adjectives in Spanish can appear in either position. Third, even when instruction makes reference to possible meaning distinctions that correspond to the choice in adjective placement, the alternative placement is attributed to changes in the lexical interpretation of the adjective, as between hombre pobre “materially poor man” and pobre hombre “unfortunate man.”
In a comprehensive corpus-based study, Anderson (Reference Anderson2007b) demonstrated that pedagogical accounts do not faithfully reflect the actual distribution of adjectives and their semantic context in certain Romance languages. Despite this noise, which can actually complicate target convergence, Anderson demonstrated that English learners of L2 French overcome both the inherent learnability problem (as children do) and the added noise of pedagogical oversimplification (Anderson, Reference Anderson, Camps and Wiltshire2001, Reference Anderson2007a, Reference Anderson2007b, Reference Anderson2008). A similar scenario also applies to the L2 Spanish population tested in the current study. However, unlike Anderson, the present study tested syntax-semantics interface properties within the DP that do not involve change in the individual lexical meaning of the adjective but rather involve a more subtle set- versus kind-denoting distinction in the interpretation of adjective-noun pairs. Given the fact that this semantic distinction is less likely to be unambiguously accessible in the input or to be made explicit in the course of instruction, our results provide a new source of empirical evidence for the learnability challenge involved in assuming that L2 grammatical properties can be readily acquired only on the basis of classroom input or explicit instruction.
At the advanced level, L1 English learners of L2 Spanish demonstrated nativelike performance across both tasks. The fact that the advanced L2 learners reliably (to a nativelike level) intuited and produced set- versus kind-denoting interpretations of adjective-noun pairs in Spanish crucially demonstrates that they have acquired new DP-internal syntactic features. Therefore, this finding falsifies the predictions of RDAs; that is, the advanced learners clearly raised Spanish nouns, from which the syntactically restricted interpretations available for prenominal and postnominal adjectives obtain. It is important to note that noun-raising in Spanish has been argued to be triggered by the existence of an uninterpretable feature that must be checked or valued after noun movement (e.g., a N feature or an EPP feature, under different minimalist approaches to formal syntax). The English DP crucially lacks the general kind of noun-raising that would be indicative of the existence and specification of this uninterpretable feature. However, the current study provides evidence that English L2 learners of Spanish master noun-raising, which indicates that they can acquire the new (uninterpretable) feature specification of Spanish. Such noun-raising then yields the distinction between prenominal and postnominal adjectives, also resulting from the fact that adjectives can be linked (merged) to a higher or lower syntactic position within the DP.Footnote 19
The picture that emerges from the intermediate learners is less clear, at least at the group level. However, given the SLA theories under investigation here, explaining the variability in the intermediate data is less relevant, given that the predictions for ultimate attainment are the most important aspect to determining the explanatory adequacy of FA accounts versus RDAs to adult SLA. The AS group results are very clear in that only the FA set of accounts is supported; that is, it would be sufficient to claim that intermediate learners simply have not fully acquired the syntax of the Spanish DP at this point in interlanguage development, even if such a conclusion were not entirely supported by all individual data. Because testing an advanced group would have been sufficient to compare the competing theories considered here, the original motivation for testing an intermediate group as well was to try to determine the point in interlanguage development at which learners acquire DP-syntax properties of their L2. After all, if new feature acquisition is possible at all in adulthood, then it seems reasonable that grammatical restructuring and resetting in the L2 can occur before the most advanced level of proficiency is attained, especially for certain properties. Therefore, it is somewhat expected that evidence of this restructuring should not be exclusively found in advanced learners.
The intermediate learners as a group differ significantly on both tasks from the native controls and the advanced learners; however, they crucially show nativelike tendencies, performing with 80% accuracy or higher on both tasks. Although the group shows target-deviant optionality, it is interesting to consider a few things with respect to the overall native tendency of this group, asking whether the roughly 80% accuracy closely represents the individual performances of the group. In fact, a closer look at individual performances reveals that significant differences obtain in both tasks, as can be appreciated by comparing the standard deviations of the IS and AS groups: task 1, prenominal = 1.878 (IS), 0.647 (AS); task 1, postnominal = 1.303 (IS), 0.717 (AS); task 2, prenominal = 1.746 (IS), 0.711(AS); task 2, postnominal = 1.599 (IS), 0.711 (AS). These larger standard deviations indicate that the IS group’s 80–85% accuracy on both tasks is the result of averaging together two types of individual performance: Some intermediate learners hover close to chance and others perform more like the advanced learners and native speakers do. It is important to note that individual performances across both tasks correlate, such that if an individual (intermediate, advanced, or native) performed with native accuracy on one task, they also did on the other. If they did not perform like natives on one task, they also failed to do so on the other task. It seems, then, that although the overall proficiency of some IS individuals does not fall within the AS range, several IS individuals have already properly reset properties of their DP syntax toward the target.
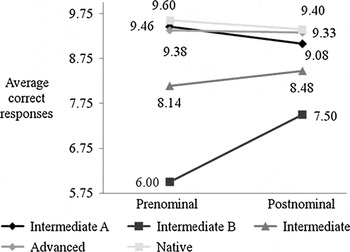
To further support this observation, the IS group was divided into two subgroups based on whether their performance was nativelike or not: ISA (n = 13) and ISB (n = 8). Statistical analyses that compare these learners with the NS group revealed that the two IS subgroups showed very different results from the original IS group. Figure 3 shows the average number of correct responses (out of 10) for the three original groups (IS, AS, and NS) along with the two IS subgroups (ISA and ISB) for task 1. As shown in Figure 3, the ISA group’s average number of correct responses for prenominal adjectives is very similar to the NS and AS groups’ averages (9.46, 9.60, and 9.38, respectively). However, the ISB group’s average (6.00) is substantially lower than that of all other groups. The ISA group’s average for the postnominal adjectives (9.08) is very similar to that of the NS group (9.40) and of the AS group (9.33). The ISB group’s average number of correct responses (7.50), however, was quite lower than that of the other groups. A mixed-model ANOVA was run to determine if the differences among the groups were significant. The results of this analysis revealed a main effect for proficiency level, F(3, 56) = 54.33, p < .01. There was no main effect found for adjectival position, F(1, 56) = 3.247, p = .077. Finally, an interaction between proficiency level and adjectival position was found, F(3, 56) = 8.98, p < .01. Bonferroni post hoc tests revealed that adjectival position was only significant for the ISB group, which not only performed differently (worse) than all other groups for both adjectival positions (p < .001 for all comparisons) but also performed significantly worse with prenominal adjectives as compared to postnominal adjectives (p < .001). This last effect might seem unexpected; given that adjectives can only appear prenominally in English, why would these learners perform worse with prenominal adjectives? However, considering the fact that these are tutored learners and that pedagogical oversimplification results in learners being drilled on the postnominal position of adjectives, then the interaction revealed is not entirely unanticipated.
Results for task 1 with subgroups.

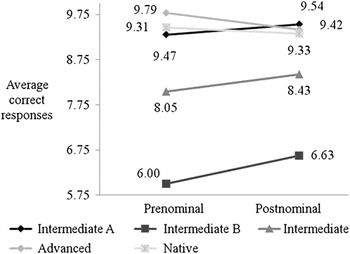
Figure 4 provides the average number of correct responses (out of 10) on task 2 for each of the three original groups (NS, AS, and IS) and the two IS subgroups (ISA and ISB). Figure 4 shows that the ISA group’s average number of correct answers for prenominal adjectives is very similar to that of the NS and AS groups (9.31, 9.47, and 9.79, respectively). The ISB group’s average for prenominal adjectives (6.00), on the other hand, is substantially lower than that of all other groups. The ISA group’s average number of correct responses for the postnominal adjectives (9.54) is again very similar to that of the NS group (9.33) and of the AS group (9.42). The ISB group’s average (6.63) is quite a bit lower than that of the other groups. The same statistical analyses as those performed with the original groups were conducted to determine if these differences were significant. The mixed-model ANOVA revealed that there was a main effect for proficiency level, F(3, 56) = 40.76, p < .001. No main effect for the position of the adjective was found, F(1, 56) = 0.148, p = .702. There was no interaction between adjectival position and proficiency level, F(3, 56) = 0.952, p = .435. Bonferroni post hoc analyses revealed no significant difference between the ISA group and the NS group (p = 1.000) or the AS group (p = 1.000). However, significant differences were found by comparing the ISB group to each one of the other groups—that is, the NS group (p < .001), the AS group (p < .001), and the ISA group (p < .001).
Results for task 2 with subgroups.

It is clear that the ISA group performs just like the native controls and that the ISB group is much more target-deviant than the overall IS group. This deeper analysis of the intermediate learners enables us to determine a more precise time in interlanguage development when the DP syntax of English learners of L2 Spanish is reset. Based on what the individual intermediate data reveal, it seems clear that relevant parameter resetting occurs during the intermediate level of proficiency. Those individuals who do not demonstrate such knowledge will likely do so soon, with continued exposure to Spanish input.
CONCLUSIONS
The current study explored L2 Spanish learners’ knowledge of adjectival semantic entailments that fall out from obligatory noun movement within the Spanish DP, in order to check and value functional features lacking in these learners’ L1. The results of two tasks demonstrated that advanced learners and some intermediate learners have acquired new functional features and apply the corresponding overt movement, consistently matching the semantic interpretation and corresponding feature specification associated with adjectives and nouns within the DP. In line with previous research that investigates knowledge of complex semantics stemming from the acquisition of specific aspects of the syntax (see, e.g., Slabakova, Reference Slabakova2008), the data presented here are argued to provide counterevidence to RDAs of adult SLA. Future research that examines corpora of language to which typical L2 Spanish students are exposed can further disprove the alternative view that the L2 behavior reported here could be attained exclusively via domain-general learning. Although Anderson (Reference Anderson2007b) already demonstrated, based on a corpus study for L2 French, that domain-general learning is not a plausible explanation for the observed behavior of learners, a similar study for L2 Spanish would further confirm whether the arguments provided here are warranted.
APPENDIX
SUMMARY OF THE GRAMMATICALITY JUDGMENT TASK
Sample Tokens
(1) Grammatical N-Adj
La tiza de esta sala es amarilla.
“The chalk in the room is yellow.”
(2) Ungrammatical N-Adj
Mis tíos de Los Ángeles son famosas. (should be famosos)
“My uncles from Los Angeles are famous.”
(3) Grammatical Det-N
La banda es muy popular aquí.
“The band is very popular here.”
(4) Ungrammatical Det-N
La familia Muñoz vive en la campo. (should be el campo)
“The Muñoz family lives in the country.”
Overview of Results