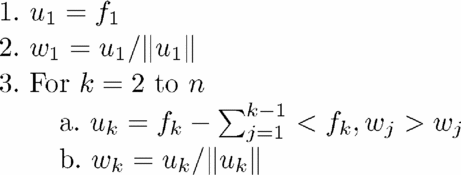1 Introduction
Textual similarity metrics are at the heart of many critical tasks such as search, text classification, document clustering, query by example, spam filtering, and really simple syndication (RSS) feeds aggregation. While good results may be obtained using lexical features only, there are situations where meaning cannot be ignored and reaching the correct answer requires semantics. For example, the sentences a couple of guys are shooting hoops in the car park and a few boys are playing basketball in the gym are conceptually very similar, yet they share no keywords. Conversely, a document where the words sweetheart, restaurant, and private conversation are used frequently may describe a romantic encounter, while another document may use the same words to describe an attempt at bribing one's political acquaintance. In the context of search, a physician might wish to conduct a study across canine-attack injuries, where she would type in, say dog bite, hoping to retrieve appropriate encounter records; or, a biologist interested in finding all reports relating to the topic of cell division would want to receive conceptually related search results about DNA replication, meiosis, and mitosis, where the words cell division may not be mentioned explicitly.
In computational linguistics, lexical semantic distance (or, reciprocally, similarity) measures are usually categorized as either corpus-based, where the proposed measures rely upon semantic information implicit in lexical and statistical quantities extracted from text corpora (e.g., frequency counts), or knowledge-based, where the proposed measures draw upon semantic information explicit in lexicons and ontologies, such as WordNet, UMLS, and GermaNet. It is difficult, based on current empirical evidence, to decide which of these approaches (if any) is superior to the other. In this paper, we follow the knowledge-based tradition, and describe a novel lexical semantic distance measure, with a formal mathematical foundation and an efficient implementation.
We use hyponymy as the topological essence of the lexicon, although any other semantic, partial order relation would be suitable. What we want, then, is a framework where we can relate lexical elements to mathematical objects, such that lexical items that are close in meaning correspond to objects that are close in a mathematically computable sense, and lexical items that are not close correspond to objects that are far apart in a computable sense. While there are several ways to define such a framework, some are more natural than others. Like all partial orders, hyponymy can be represented graphically as a directed acyclic graph, which can in turn be extended to a lattice. Most extant lexical semantic distances rely on various notions of edge counts or path lengths between concepts in such a lattice.
By contrast, we demonstrate a natural transformation from the partial order defined by the semantic relation into a function space, where by natural we mean that the metric on the function space is informed by the order relation on the graph. If the hyponymy semantic relation is meaningful at all, then there is indeed compelling reason to define a distance metric that is not just compatible with, but naturally derived from, the corresponding order relation. The proposed transformation maps nodes of the graph (i.e., noun-concepts) to vectors in the dual space of linear functionals. This dual space is a vector space with a well-defined inner product that can be used to promote the original graph to an inner product space, with a natural notion of distance between elements of the underlying node set for the graph.
We wish to make it clear at the onset that we leave a thorough empirical analysis of our method and comparison with other existing methods (especially, corpus-based ones) for future work. No definitive claims are made here about performance. We focus instead on showing how one can construct a plausible model for (lexical) semantic distance that (1) is founded upon the basic semantic relations (order relations), and (2) performs well on a variety of tasks. Our interest in knowledge-based approaches does not imply either that corpus-based, or statistical, approaches are wrong. At most, we suggest that a modeling technique that provides insight into the structure or behavior of a heretofore opaque mechanism can be beneficial. Again, empirical analyses beyond those presented here are necessary to explain the precise conditions under which ours and other methods may be expected to perform best.
The paper is organized as follows. Section 2 discusses related work. Section 3 details the mathematical derivation of our novel lexical semantic distance metric, and shows how its implementation can be made computationally efficient. In Section 4, we present experiments in the context of information retrieval that demonstrate the metric's ability to handle very large datasets, as well as document clustering experiments that point to its inducing better quality clusterings than other relevant approaches. Section 5 contains a discussion of relevant aspects of our approach and points to possible improvements. Finally, Section 6 concludes the paper.
2 Related work
A number of candidates, corpus-based similarity measures, mainly derived from lexical and statistical information, are described in (Lebart and Rajman Reference Lebart, Rajman, Dale, Moisl and Somers2000; Curran Reference Curran2004; Weeds, Weir and McCarthy Reference Weeds, Weir and McCarthy2004; Mohammad and Hirst Reference Mohammad and Hirst2006). Perhaps the most popular approach is latent semantic analysis (LSA) (Deerwester et al. Reference Deerwester, Dumais, Landauer, Furnas and Harshman1990; Landauer and Dumais Reference Landauer and Dumais1997; Landauer, Foltz and Laham Reference Landauer, Foltz and Laham1998). LSA relies on co-occurrence counts of words within documents, and applies a singular value decomposition (SVD) feature dimensionality reduction approach, from which a semantic relatedness measure can be derived. LSA makes the assumption that if words occur together within documents, then they are related in some conceptual way, thus measuring semantic relations of an implicit (or latent) nature. Probabilistic extensions of LSA have recently been proposed (e.g., see Hofmann Reference Hofmann1999; Blei, Ng and Jordan Reference Blei, Ng and Jordan2003).
On the other hand, several knowledge-based semantic measures are described and compared in (Budanitsky and Hirst Reference Budanitsky and Hirst2006). Most of these are based on some variation of path length in the WordNet graph. Some also use corpus statistics as additional information, as in (Richardson and Smeaton Reference Richardson and Smeaton1995), where an information-based function inspired by Resnik's work (Resnik Reference Resnik1993) and a concept-based function inspired by the work by Rada et al (Rada et al. Reference Rada, Mili, Bicknell and Blettner1989) are discussed. The former function uses the notion of information content, defined as the probability of occurrence in a large text corpus of the first class in the noun hierarchy that subsumes the classes of the words being compared (see Rensik Reference Resnik1999 for an extension). The latter function uses the sum of heuristically computed edge weights along the shortest path connecting the synsets of the words being compared. Recently, several of these same measures, and a couple more, were successfully adapted to the biomedical domain, where WordNet is replaced by the well-known medical ontology SNOMED-CT (Pedersen et al. Reference Pedersen, Pakhomov, Patwardham and Chute2007).
It is difficult, based on available empirical evidence, to declare either one of the above approaches as a clear winner in all cases. It may well be that hybrid systems, that combine the best-in-class from each approach, are the most promising. Although we do not pursue this idea here, it is worth mentioning that recent work in information retrieval seems to be headed in that direction (e.g., see Henstock et al. Reference Henstock, Pack, Lee and Weinstein2001; Mihalcea and Mihalcea Reference Mihalcea and Mihalcea2001; Kim, Seo and Rim Reference Kim, Seo and Rim2004; Rosso et al. Reference Rosso, Ferretti, Jiménez and Vidal2004; Marton, Mohammad and Resnik Reference Marton, Mohammad and Resnik2009).
The measure we describe in this paper is knowledge-based. It has a formal mathematical foundation, motivated by a natural transformation from the order relation in the lexicon to a metric in the dual function space. This transformation, together with a simple illustrative example, was originally shown in (Jensen and Giraud-Carrier Reference Jensen and Giraud-Carrier2007). While we are not the first to propose the formalization of a lexicon in terms of the relational structure induced by its underlying semantic relation (Priss Reference Priss and Fellbaum1998), we are first in showing how it can then be usefully embedded in a metric space. Furthermore, our approach, although demonstrated here on WordNet, is not tied to some particular implementation of the underlying lexicon. The approach works for any implementation that reflects a partial order, and what we are suggesting is that given such a conceptual ordering, there is a natural, mathematically meaningful way to interpret it as a metric space.
The work of Prince and Lafourcade (Reference Prince and Lafourcade2003) is closely related to our own. These authors describe a conceptual vector model wherein they take a set of spanning concepts in a taxonomy/hyperonymy model, and define a vector for a general concept as the “activation” of the spanning concepts (e.g., V(door)=(opening)[0.3], barrier[0.31], limit[0.32],. . .)). Vector operations, such as sum (union of semantic properties), product (intersection of semantic properties), angular distance (thematic proximity) and contextualization (context-sensitive property amplification) are then proposed to manipulate terms/concepts. We interpret this approach as the first step we take by projecting onto the basis chains, i.e., a kind of covariant representation. They do not, however, take the next step of shifting to the dual space setting and recasting the representation via a metric tensor. Hence, they miss out on the algebra of the dual space. In our approach, hyponymy is the conceptual basis and an explicit mapping is constructed.
In Jensen, Giraud-Carrier and Davis (Reference Jensen, Giraud-Carrier and Davis2008), we tested our lexical semantic distance measure on a well-known word similarity and relatedness dataset, and showed that it compared favorably with several other knowledge-based semantic distances. Here, we first extend the word-level distance to its natural document-level distance, and describe a space and time efficient implementation. We are then able to apply our proposed word-level and document-level measures to a number of large, real-world search, and document clustering tasks.
Semantic distance measures are particularly useful in tasks such as search and document clustering. In the context of search, techniques such as associating query words with results (e.g., see Beeferman and Berger Reference Beeferman and Berger2000; Roy et al. Reference Roy, Mohania, Bhamba and Raman2005; Norvig Reference Norvig2006) can be viewed as capturing some form of meaning implicitly. Of most relevance here, of course, are those papers that advocate the use of preexisting ontological structure, such as the Semantic Web, rather than inferring structure from statistical processing of representative corpora (e.g., see Guha, McCool and Miller Reference Guha, McCool and Miller2003; Rocha, Schwabe and de Aragão Reference Rocha, Schwabe and de Aragão2004; Zhang, Ghahramani and Yang Reference Zhang, Ghahramani and Yang2004). We note also that many researchers have leveraged WordNet in an attempt to add semantic information to improve such tasks as contextual analysis and query expansion (e.g., see Voorhees Reference Voorhees1994; Stairmand Reference Stairmand1997). For search tasks, the work presented here can be viewed as an alternative to query expansion, where instead of using standard metrics with semantically close words added explicitly to the query, we implicitly expand the search with a semantic-based metric.
In the context of document clustering, a number of researchers have also attempted to go beyond the simple vector space model (Salton, Wong and Yang Reference Salton, Wong and Yang1975) and add some form of (latent) semantic information to the clustering process. In most approaches, the semantic information is leveraged as a kind of preprocessing step before clustering takes place with a standard algorithm and standard distance metric. For example, one may apply some form of word sense disambiguation and use the disambiguated terms to build document vectors (e.g., see Choudhary and Bhattacharyya Reference Choudhary and Bhattacharyya2002; Wang and Hodges Reference Wang and Hodges2006). The preprocessing step may also involve a mapping from the original high-dimensional word vector space to a much lower-dimensional feature vector space, which also significantly decreases the computational demands on the clustering algorithm. For example, one can use frequent terms discovery (Blei, Ester and Xu Reference Blei, Ester and Xu2002), LSA (Song and Park Reference Song and Park2007), an ontology (Hotho, Staab and Maedche Reference Hotho, Staab and Maedche2001), or a hybrid of these (Termier, Rousset and Sebag Reference Termier, Rousset and Sebag2001) to effect a semantic-rich dimensionality reduction and cluster within the reduced space. Although our approach also reduces dimensionality prior to clustering, it goes one step further by using an explicit semantic distance function in the clustering algorithm.
3 A novel semantic distance metric
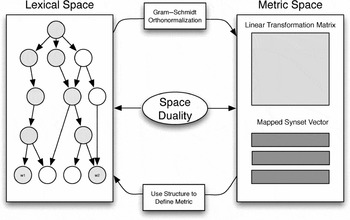
To be effective, a computational lexical semantic model must establish a quantitative context for that which is essentially qualitative in nature. Here, we leverage the notion of Galois connection (Erné et al. Reference Erné, Koslowski, Melton and Strecker1993) to create a correspondence between the order model of the lexicon and a suitable metric space model, such that the notion of closeness is preserved. Loosely speaking, a Galois connection is a mathematical technique, which allows one to go from a possibly poorly understood or relatively complex context to another one, where things may be clearer or easier to understand. A graphical representation of our proposed connection is shown in Figure 1.
Galois connection principle.

Such a connection, or mapping, would allow us to manipulate lexical elements via operations effected in the metric space. In this section, we show how a notion of semantic distance between noun-concepts, and by extension whole documents, might naturally be derived from a graphical model of hyponymy. We rely on ideas from topology (Hocking and Young Reference Hocking and Young1961) and functional analysis (Edwards Reference Edwards1965). Topology uses language and logic in a precise way to formalize, refine and extend the human-intuitive notion of space, and by extension distance, into a useful body of knowledge.
3.1 A model of the lexicon
While we provide a method for quantitatively representing any type of hierarchical semantic relationship, our primary focus here is on the hyponymy relationship, and its specific instantiation in WordNet (Miller et al. Reference Miller, Beckwith, Fellbaum, Gross and Miller1990; Miller Reference Miller1995; Fellbaum Reference Fellbaum1998). Our choice of WordNet is motivated by pragmatic concerns. Indeed, WordNet is widely used in research and easy to access, and its semantic relationship hierarchy is sufficiently rich and extensive for our purposes. We note, however, that recent research has looked into using Wikipedia rather than WordNet as the basis for computing semantic relatedness (Ponzetto and Strube Reference Ponzetto and Strube2007; Gabrilovich and Markovitch, Reference Gabrilovich and Markovitch2007). A similar course could be taken here and is left for future research.
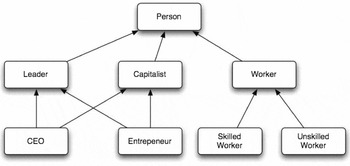
Now, recall that a graph is a set G of points, or nodes, and a relation (i.e., a subset of G × G). A directed graph is a graph where the relation is a partial order (i.e., reflexive, antisymmetric, and transitive).Footnote 1 Such graphs are also referred to as partially ordered sets, or posets for short. Figure 2, adapted from Figure 4 in (Mann Reference Mann2002), shows a simple directed graph where G = {Person, Leader, Capitalist, Worker, CEO,. . .} and the relation on G is hyponymy (e.g., Entrepreneur is-a Capitalist, Worker is-a Person, CEO is-a Person - by transitivity).
A simple pyponymy graph.

A chain is a totally ordered subset of a directed graph, and a maximal chain is not a proper subset of any chain. Each path from a leaf node to the graph's root node corresponds to a maximal chain. For example, {Leader, Person} and {Entrepreneur, Capitalist, Person} are chains of the graph of Figure 2, while {CEO, Leader, Person} and {Unskilled Worker, Worker, Person} are maximal chains.
Maximal chains play a pivotal role in our model, as they correspond to functions from the underlying poset to the reals. Intuitively, we effectively map maximal chains in the graph to the set ℝ of real numbers, as follows. Let ck be a maximal chain of length q. Let l be any node in the graph and ilk be the index, ordered from root to leaf, of the lowest (towards the leaf) point of intersection of l (via some chain containing l) with ck. The function fck, corresponding to the chain ck is defined by
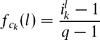
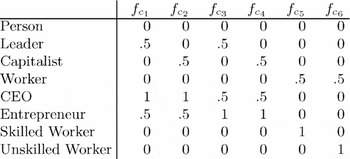
Letting ck be the maximal chain {Entrepreneur, Capitalist, Person} (q = 3) in Figure 2, we have fck(CEO) = 0.5 since the lowest point of intersection of a chain containing CEO and the chosen maximal chain is the Capitalist node, via the {CEO, Capitalist, Person} chain, and the index of Capitalist is 2 (the root's index is 1). Similarly, we have fck(Worker) = 0 since the lowest interesting point of any chain containing Worker with the chosen maximal chain is at the root of the graph.
Each maximal chain gives rise to a unique function, resulting in a set {fck} of functions from the graph to the real numbers. We extend this set into the minimum space of functions spanned by the set (see Gram–Schmidt orthonormalization box in Figure 1). Our strategy is to exploit (metric) structure on the function space by “mapping” (via duality) any such structure back to the poset. In particular, we conjecture that an inner product on the function space can be used to define a metric on the poset (see use structure to define metric box in Figure 1). A complete formal account of the topological embedding of the WordNet hyponymy graph into its corresponding metric space is given in the Appendix for the interested reader.
Here, we focus on intuition and simply illustrate, using the graph of Figure 2, how such a directed graph is bootstrapped into a topological vector space using the proposed approach. For such a small graph, we take the set of all maximal chains (from leaf to root) to induce our spanning set of coordinate functions {fck}. In practice, of course, we would not consider all chains, but project onto a contextually relevant subset of chains. The idea is to restrict attention to some relevant conceptual subspace (e.g., some conversational context, some domain of interest), with an obvious tradeoff between computation and accuracy. By restricting ourselves to contextually relevant conceptual domains, we are able to reduce the dimensionality of the problem, and hence its computational footprint. Yet, this same reduction in an empirical setting may put our method at a disadvantage in terms of accuracy, when compared to other methods. Some ideas on how to effect the selection of chains are given in our experiments, but the determination, in general, of a relevant conceptual subspace is an area of future research.
Here, the maximal chains are c 1 = {CEO, Leader, Person}, c 2 = {CEO, Capitalist, Person}, c 3 = {Entrepreneur, Leader, Person}, c 4 = {Entrepreneur, Capitalist, Person}, c 5 = {Skilled Worker, Worker, Person}, and c 6 = {Unskilled Worker, Worker, Person}. The value of fc 3(CEO) is .5, since the earliest point of intersection of CEO with c 3 is halfway down the chain. Similarly, since Skilled Worker does not intersect c 4 at any point except the root, the value of fc 4(Skilled Worker) is 0. The complete action of the coordinate functions {fck} on G is summarized in Figure 3.
Action of {fck} on G.

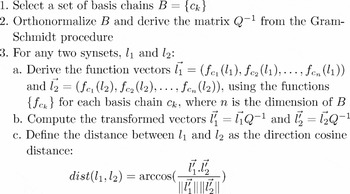
As pointed out above, the task is to find an orthonormal set of functions that provide a basis for the span of {fck}, and to produce a linear transformation, Γ, from the set of nodes in G to the corresponding conjugates in the metric subspace spanned by {fck}. We employ the Gram–Schmidt algorithm, which, given the finite set of vectors {fck}, produces an orthonormal basis of the space generated by {fck}. The algorithm is shown in Figure 4, where n is the size of the basis.
Gram–Schmidt algorithm.
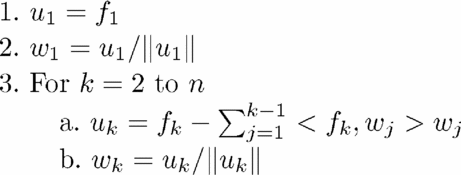
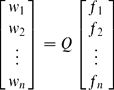
Clearly, n ≤| {fck} |, since if any fi is in the span of the others, i.e., the set {fck} is not linearly independent, then the computation of ui will yield the zero vector, signifying that fi should be discarded. The Gram–Schmidt procedure can be summarized in matrix form as follows (Jensen et al. Reference Jensen, Giraud-Carrier and Davis2008).
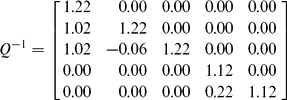
Returning to our example, we note that fc 4 is in the span of the other functions, specifically, fc 4 = −fc 1 + fc 2 + fc 3, and thus it is dropped from the computation of the basis. We then proceed to compute Q, and finally its inverse, yielding:
By making the appropriate substitution in the above expression, we then immediately obtain an explicit computational form for Γ.
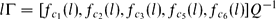
3.2 Word distance
Using the foregoing mathematical framework, it is straightforward to devise a procedure to compute distance between synsets, as shown in Figure 5.
Word-to-word distance algorithm.

Returning to our simple illustration, we get, for example, C O = (1, 1, 0.5, 0, 0) and Entre
 eneur = (0.5, 0.5, 1, 0, 0), so that CO′ = (1.75, 1.19, 0.61, 0, 0) and Entreeneur′ = (2.14, 0.55, 1.22, 0, 0). Finally dist(Entrepreneur, CEO) = 0.34, a relatively small value, as expected.Footnote 2 On the other hand, a similar computation gives dist(CEO, Worker) = 1.57, a relatively much larger value, also as expected.
As stated, the above algorithm computes distances over synsets. In practice, however, we are generally seeking distances between words rather than synsets. As it turns out, words may appear in more than one synset. For example, the word dog belongs to the synset [dog, domestic dog, Canis familiaris] as well as the synset [frank, frankfurter, hotdog, hot dog, dog, wiener, wienerwurst, weenie]. Hence, some process of lexical disambiguation is necessary. Word sense disambiguation has been and continues to be an active research topic (e.g., see Ide and Veronis Reference Ide and Veronis1998; Wiebe and Mihalcea Reference Wiebe and Mihalcea2006; Agirre and Edmonds Reference Agirre and Edmonds2007; Navigli Reference Navigli2009). It is outside the scope of this paper. Here, we adopt a rather simple approach, where we disambiguate to the closest senses, as follows:
• Let w 1 and w 2 be the two words whose distance we wish to compute;
• Let s 11,. . .,s 1n be the synsets that w 1 belongs to and s 21,. . .,s 2m be the synsets that w 2 belongs to;
• The distance between w 1 and w 2 is defined by d(w 1, w 2) = mini,jdist(s 1i, s 2j).
We note that WordNet sorts its synsets based on frequencies extracted from a human-labeled text corpus.Footnote 3 The first sense, according to this ordering, is assumed to be dominant, as the word of interest occurred most frequently as the first synset sense in the sample texts analyzed by the WordNet research group. We found, however, that using only dominant senses for disambiguation gave poorer results than the above approach, possibly due to the fact that in some instances the sense of one word, or an entire context, may trigger the sense of another, which may not be the dominant sense. For example, in an ornithological discussion, the sense of the word “crane” is more likely to be the one associated with the bird, which is not dominant in this case, than the dominant one associated with the construction implement. While not perfect, following the above approach increases the likelihood of using the distance between such mutually triggering senses for polysemous synsets or words.
3.3 Document distance
With a semantic distance measure defined for pairs of words, we now turn our attention to the notion of distance between sets of words (e.g., query string to document, document to document). In order to extend our word-level semantic distance measure to the document level, we must formulate documents so that they are conducive to this word-level metric. It is too computationally expensive to consider all of the words in a document. Rather, we employ a filtered bag-of-words, where we select only nouns and further focus our attention on the most frequently occurring (top N) nouns, to represent the document.
To extract nouns from our data, we use an effective English part-of-speech tagger that has been shown to achieve 97.1% tag classification accuracy on the Wall Street Journal corpus, and works very well for our noun extraction purposes (Tsuruoka and Tsujii Reference Tsuruoka and Tsujii2005). We then build a noun frequency histogram and sort it in descending order. The top N nouns to be considered correspond to the N nouns with highest frequencies in the document.
Note that the restriction to nouns is imposed upon us by the knowledge-based structure underlying our word-level semantic distance metric (Wordnet 3.0's noun hyponymy subgraph). We believe, however, that nouns are good indicators of topics or concepts that define documents. The restriction to only the top N nouns is advantageous computationally because of the induced reduction in document dimensionality (particularly when N is small). It is clear that, if one is willing to incur the additional computational cost, one could use other mechanisms to map documents to sets of nouns, such as LSA. When we refer to documents in the remainder of the paper, we mean documents that have been reduced as described here.
We can now extend our word-level distance measure to provide a meaningful quantitative distance between documents. Since we adopt the widely accepted, simplifying view that documents are sets of words, a number of alternative distance measures exist, such as the traditional single-link, average-link, and complete-link methods used in hierarchical agglomerative clustering. However, to maintain consistency with our basic approach at the word level, which is driven by topological arguments, we adopt the Hausdorff distance, defined as follows.
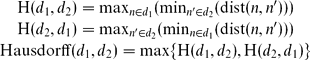
For each noun in a document, the minimum word-level distance to all nouns in the other document is found. Then, the maximum of all of these minimum distances is taken as the distance from the first document to the second one. This process is repeated reversing the order of the documents, since that measure is clearly not symmetric. Finally, the maximum of the two distances is the Hausdorff distance between the documents.
3.4 Implementation details
Our current implementation of the word-to-word semantic distance computation described above is in C++, using WordNet 3.0 for UNIX. Version 3.0 of WordNet contains 155,287 unique English synsets.
The algorithm of Figure 5 for computing word-to-word semantic distances, does not, by itself, run fast enough to be used practically on a large scale. However, the efficiency of the algorithm can be improved significantly through a series of pre-computational steps, whose results are stored in memory to be accessed when making the actual word-to-word semantic distance computations, as follows.
(1) Q−1. Consider steps 1 and 2 of the algorithm, where we select a set of basis chains and determine the linear transformation that maps words into the metric space. While nontrivial, these steps need only be computed once. We do so, and store Q−1 in memory.
(2)
 . Consider step 3(a), where we compute function vectors. Again, that computation is nontrivial as it requires finding the (lowest) intersection points between chains, which are used to generate the function values in the metric space. However, once the set of basis chains has been chosen, the value of for each synset l is fixed and can thus be precomputed. We do so, and index the resulting vectors as key value pairs in a hash table.

Once the above data structures have been stored, the cost of the computation of the distance between two words is essentially that of computing the dot product of their associated vectors. The cost of computing the dot product is itself proportional to the dimensionality of the projection space, i.e., the size of the basis. Since one always selects a finite basis, it follows that computation of the dot product is O(1) in practice.
Finally, we note that the use of precomputations and hash tables to improve efficiency is not unique to our approach. Traditional path-length approaches, such as Leacock–Chodorow and Jiang–Conrath, can also be improved through precomputations (e.g., see Pedersen, Patwardham and Michelizzi 2004). However, our embedding of the lexicon into a metric space allows some computation to be done on-the-fly, which also reduces the space needed to store precomputed values. The path-length approach essentially has to precompute all the scores, because calculating these at run-time would be prohibitive, whereas we can handle run-time calculation because computing the dot product when the size of the vectors is not too large is manageable.
4 Empirical analysis
In this section, we report on the use of our document-level semantic measure on several large, real-world search and document clustering tasks. Prior to doing this, we summarize earlier results with our word-level distance on a standard similarity benchmark.
4.1 Word similarity
In Jensen et al. (Reference Jensen, Giraud-Carrier and Davis2008), we applied our word-level semantic measure to the well-known benchmark dataset designed by Rubenstein and Goodenough (Reference Rubenstein and Goodenough1965). This dataset consists of 65 pairs of words that 51 human subjects were asked to rate for similarity of meaning on a scale of 0–4. The authors then averaged the ratings and produced a ranked list of pairs, which serves as a “gold standard” for computational methods to measure against. In particular, one seeks to design approaches that maximize the level of rank correlation with the human-generated ranking.
For simplicity, we selected the set of maximal chains generated by the entries in WordNet for the dominant sense of each of the unique words in the dataset's 65 noun pairs, which resulted in 62 maximal basis chains. Distances for each noun pairs were computed and ranked from most similar to least similar. For polysemous words, we use the simple disambiguation approach of Section 3.2.Footnote 4
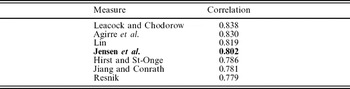
For comparison purposes, we include five other popular knowledge-based semantic measures surveyed and evaluated in (Budanitsky and Hirst Reference Budanitsky and Hirst2006), as well as a recently proposed measure based on personalized PageRank (Agirre et al. Reference Agirre, Alfonseca, Hall, Kravalova, Paşca and Soroa2009). A ranked list of these measures and ours, from most correlated to least correlated (with the gold standard), is given in Table 1.
Word pair similarity on R&G dataset

These results demonstrate that our distance measure compares well with other similar lexical semantic distance measures at the word level. We now turn to experiments in the domains of search and document clustering.
4.2 Search result reranking and query expansion
Search result reranking and query expansion offer two interesting ways of using a semantic distance measure in the context of common information retrieval tasks. To rerank search results, we use document-level distance metrics to determine the closeness of documents to a particular query for which the documents were retrieved. For query expansion, we identify additional query terms by extracting, from documents found in a preliminary result set, words that are determined to be semantically similar to the original query terms. When we discuss improving search results, both with search result reranking and query expansion, we do so in the context of retrieving, from a document repository, documents that are relevant to an user's keyword(s). These approaches are postprocessing steps in a typical information retrieval system; they perform some function on the initial result set obtained by the document retrieval system.
The document collection we use consists of the Aquaint dataset from TREC Disks 4 and 5 (Voorhees Reference Voorhees2005). The Aquaint dataset is comprised of approximately 1,033,000 English, plain-text documents (primarily news articles from the New York Times, the Associated Press and the Xinhua News Agency newswires). The underlying VSM-based IR system, for initial result set retrieval, is the C++ port of the very popular and open source Lucene information retrieval library (Lucene 2007). Note that our approach to reranking and query expansion is tied neither to Lucene nor indeed to any other IR system, VSM-based or otherwise. It can build on top of any IR model that can retrieve relevant documents for user-generated keyword queries. We choose VSM-based software here because it is very common and efficient.
In our experiments, and consistent with the TREC experiment requirements, we use the title of each topic as a keyword query. Information in the associated description and narrative provides additional insight to the human ranking process that occurred when the dataset was formed, but is not available to the system. For each of fifty annotated queries, the Aquaint dataset provides a human-generated relevancy judgment that associates documents with the query. Our experimental results are compared against these documents to compute the following traditional evaluation metrics:
• Precision: the ratio of the number of relevant retrieved documents to the number of retrieved documents. Three special cases of precision are computed here:
(a) Mean average precision: the arithmetic mean of the average precision values for individual queries.
(b) Precision after five documents: the precision score obtained from restricting the result set to the first five documents retrieved.
(c) Precision after ten documents: the precision score obtained from restricting the result set to the first ten documents retrieved.
• Recall: the ratio of the number of relevant retrieved documents to the total number of relevant documents.
For each task, these evaluation metrics are averaged over all fifty annotated queries. Finally, for our basis, we selected the set of maximal chains generated by the entries in WordNet for the dominant sense of each of the 346 regular nouns (i.e., labeled as N) in Longman's defining vocabulary of contemporary English.Footnote 5 These nouns are fairly generic and domain-independent, and thus should provide a reasonable, yet most likely not optimal, span for the Aquaint document collection. Hence, the results presented here may consequently also be suboptimal.
4.2.1 Search result reranking
A purely semantic algorithm for retrieving documents that are relevant to a particular keyword query can be defined directly with a document-level semantic distance measure, as follows:
(1) Represent the query as a document made of up of the keywords in the query.
(2) Compute pairwise document-level distances between the query document and documents in the collection.
(3) Return the closest documents in the collection (or all documents ordered by ascending distance values).
While possible, this approach is impractical with a document collection of any consequential size, as it could take a very long time to form the result set. To reduce the runtime, we propose a much faster solution which effectively reranks search results obtained by a much faster IR technique. This reranking method retains the theoretically pleasing, full semantic measure between documents, but operates much faster because of the reduced size of the initial result set in comparison to a full document collection. It operates as follows, for each query:
(1) Run the query against the VSM IR model to obtain the result set R.
(2) Represent the query as a document made up of the keywords in the query.
(3) Compute pairwise document-level distances between the query document and documents in R.
(4) Rank the documents in R by distance in ascending order.
For each of the 50 queries, the result set, R, contained 1,000 documents, i.e., |R| = 1,000. To improve efficiency, we also use our top N approach with N = 20 (i.e., each document is represented as a bag of its 20 most frequently occurring nouns).
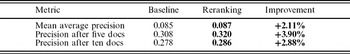
Results on the Aquaint dataset are shown in Table 2. The baseline is the performance of the unaltered Lucene IR system. Note that recall is irrelevant in this context, as we do not change the set of retrieved documents, only the order in which they are ranked.
Precision results for reranking

These results show a slight improvement, albeit not statistically significant, of reranking over the baseline for all three observed precision metrics. In particular, the highest gain in precision is after five documents, which is encouraging given the importance of this metric with respect to user-driven search engines.
4.2.2 Semantic query expansion
Another way to improve document retrieval is through query expansion, i.e., the process of adding additional terms to an initial query and rerunning the expanded query against the same document collection. Given an initial query, we formulate a new query that is the result of concatenating the keywords of the initial query with new terms that have been identified as semantically similar. This definition of query expansion does not take into account weightings of particular query terms, ordering of terms, or any boolean logic operations. For our purpose, query expansion is simply the process of (1) adding terms to an existing query, such that the new query contains a superset of keyword terms; and (2) re-issuing the expanded query to a keyword IR system.
In this experiment, our retrieval system looks similar to that of the previous system, with some minor modifications, as follows. Our objective again is to leverage information in an initial result set to improve the final result.
(1) Run the query against the VSM IR model to obtain the result set R.
(2) Extract p terms from the top δ documents of R that are semantically close to the query (viewed as a document), but that do not occur in the query (i.e., new keywords).
(3) Create a new query consisting of the original query together with the newly found keywords.
(4) Run the new query against the VSM IR model to obtain a new result set R′.
There are two parameters to this algorithm: the number p of new keywords to add, and the number δ of documents in R to consider for new keyword extraction. Clearly, we could consider all documents in R (i.e., δ = | R |). However, this would be computationally prohibitive. Furthermore, we also want to place a bound on the number of keywords in the expanded query so as to keep things meaningful and manageable. Using a small set of 5 randomly selected queries, we found that δ = 10 and p = 50 yielded the best results.
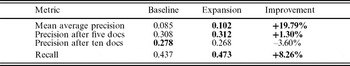
Precision and recall results on the complete Aquaint dataset of fifty queries are shown in Table 3. The baseline is again the performance of the unaltered Lucene IR system.
Precision and recall for semantic query expansion

As with reranking, these results show small, though not statistically significant, improvements on average over the baseline for mean average precision, precision after five documents, and recall.
4.2.3 Comparison against other metrics
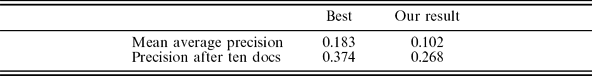
Although better than the baseline, our query expansion results are lower than state-of-the-art results reported for the TREC 2005 robust track (Voorhees Reference Voorhees2005). The actual differences from the best reported scores are summarized in Table 4.
Comparison with best scores
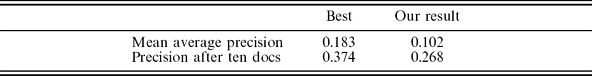
There are a couple of points worth mentioning here, however. First, none of the methods employed by participants in the TREC 2005 robust track use semantic distances. Furthermore, most rely on sophisticated and somewhat task-specific techniques to optimize their performance over that dataset. Second, and rather interestingly, our results are actually comparable with those of the ninth place submission, which were 0.113 for mean average precision and 0.264 for precision after ten documents. Were we to have submitted our results to the TREC 2005 robust track contest, we would have bumped out the tenth place contestant and actually made it on the scoreboard, which reported only the top ten entries. Hence, although our results are significantly worse than the best, they are also better than a number of unreported entries. Finally, our results are likely to be understated. Indeed, recall that no attempt was made at optimizing the choice of basis chains. Selecting contextually relevant chains would likely results in further performance improvements.
Given these results and those of Section 4.1 on word similarity, we expect that our metric performs similarly to other lexical, knowledge-based semantic distances on this task. Unfortunately, due to computational and/or space costs, we did not attempt to run these distances here. Computing distances on-the-fly is much too slow, so that we would need to precompute an index for the vocabulary at hand. Based on our experiments, it takes about 24 hours (per metric) to generate an index for a vocabulary of around 10,000 words using the well-known Perl implementation by Pedersen et al. (Reference Pedersen, Patwardham and Michelizzi2004) of the metrics listed in Section 4.1. By comparison, the Aquaint dataset has a vocabulary of over 50,000 words. Building its index could in principle be distributed over hundreds of machines to speed it up, but reading the index would still remain slow, since it would not fit in memory. Indeed, assuming 8Gb of RAM, anything over 44,000 words would put us out of RAM and on to disk. Moreover, given the size of the dataset (over 1 million documents), it would be a nontrivial project to set up such a distributed computing environment.
This discussion highlights the difficulty of using other knowledge-based semantic metrics on such large datasets, as well as the significant advantage of ours, since its storage requirement is linear in the size of the vocabulary. In the following experiment, where the vocabulary is significantly smaller, we include a comparison with other semantic metrics.Footnote 6
4.3 Semantic document clustering
Document clustering, the task of automatically discovering groups among textual entities, has proven useful in such applications as information summarization, text categorization, document collection browsing, news filtering and topic detection (e.g., see Lang Reference Lang1995; Leouski and Croft Reference Leouski and Croft1996; Zamir and Etzioni Reference Zamir and Etzioni1998; Zhang et al. Reference Zhang, Ghahramani and Yang2004). Although several clustering approaches have been proposed, including probabilistic techniques (e.g., see Fisher Reference Fisher1987; Gennari, Langley and Fisher Reference Gennari, Langley and Fisher1989) and neural network techniques (e.g., see Kohonen Reference Kohonen1982; Rumelhart and Zipser Reference Rumelhart and Zipser1985), we focus here exclusively on distance-based techniques, as these have become most popular in document clustering.
The standard taxonomy of distance-based clustering techniques splits methods into two general classes. Partitional methods, such as the well-known k-means algorithm, produce a single k-subset partition through iterative reassignment of items to clusters, based on distance to cluster centroids until all assignments remain unchanged (e.g., see MacQueen Reference MacQueen1967; Kaufman and Roussseeuw Reference Kaufman and Rousseeuw1990; Cutting et al. Reference Cutting, Karger, Pedersen and Tukey1992; Everitt Reference Everitt1993; Larsen and Aone Reference Larsen and Aone1999; Steinbach, Karypis and Kumar Reference Steinbach, Karypis and Kumar2000; Kogan, Teboulle and Nicholas Reference Kogan, Teboulle and Nicholas2003). Hierarchical methods, such as hierarchical agglomerative clustering algorithms, produce a series of nested partitions, each representing a possible clustering, through iterative proximity-based merging (e.g., see Johnson Reference Johnson1967; Jain and Dubes Reference Jain and Dubes1988; Willett Reference Willett1988; Fung, Wang and Ester Reference Fung, Wang and Ester2003).
We report on results with both the k-means algorithm and a hierarchical agglomerative clustering (HAC) algorithm. Our document collection is a reduced version of the Reuters-21578 dataset, which contains 200 documents, from 5 classes. We compare our distance metric (referred to as Jensen et al. Reference Jensen, Giraud-Carrier and Davis2008) with the two widely documented metrics that outperformed it in the word similarity task (see Section 4.1), namely Leacock and Chodorow's, and Lin's, as well as with one of the metrics that performed worse than ours did, namely Resnik's. For consistency, the document-level distance is computed the same way for all underlying word-level distances, namely using our Hausdorff distance. We simply substitute the corresponding word-level semantic distance metric in the formula.
A few preliminary experiments were necessary to fix the value of N in our top N approach to document representation. For each metric and each clustering algorithm, we varied the value of N from 1 to 30, and considered clustering results for 1–20 clusters. To make the comparison fairer, we then selected the value of N that produced the best clustering results (according to our metrics) overall. Finally, we use the same basis chains from Longman's vocabulary as in the above experiment.
4.3.1 Cluster quality metrics
One of the main challenges of research in data clustering is the assessment of the quality of the clusters resulting from some clustering process (e.g., see Yang Reference Yang1999; Slonim and Tishby Reference Slonim and Tishby2000). Here we focus on external quality metrics. External metrics are those that can be computed with a comparison to actual classification labels. The dataset used in our experiment (Reuters-21578) does contain such classification labels (1 of 5) for each document in the collection.
We select the following popular external quality metrics: F-measure, average entropy and adjusted Rand index. Let C 1,. . .,Cn be the correct target clusters (as per the available labeling) and HC 1,. . .,HCm be the computed clusters (as per the clustering algorithm). Then,

Now, let a be the number of pairs of documents in the same class in C = C 1 ∪. . .∪Cn and the same cluster in HC = HC 1 ∪. . .∪ HCm. Let b be the number of pairs of documents in the same class in C but not in the same cluster in HC. Let c be the number of pairs of documents in the same cluster in HC but not in the same class in C. Finally, let d be the number of pairs of documents in different classes and different clusters. The Rand index (RI) is defined by (see Hubert and Arabie Reference Hubert and Arabie1985):
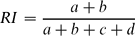
The adjusted Rand index (ARI) is an extension of the RI that addresses the fact that the expected value of the RI for two random partitions does not take a constant value. Let nij be the number of objects that are in both class Ci and cluster HCj. Let ni and nj be the number of objects in class Ci and cluster HCj, respectively. The ARI is defined as (see Hubert and Arabie Reference Hubert and Arabie1985):
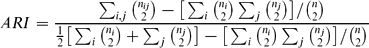
These external quality metrics essentially determine how effective the clustering algorithm is at reconstructing the grouping assigned by the original class labels. High values for F-measure and ARI, and low values for average entropy, indicate a better clustering with respect to class labels. These measures are useful when a clustering is desired, which strongly correlates with underlying classifications.
4.3.2 Semantic k-means
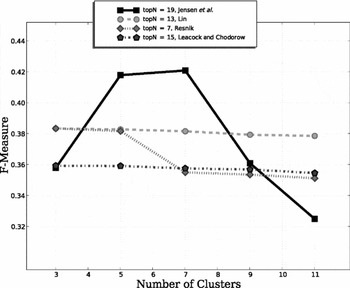
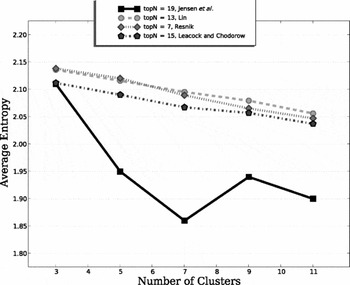
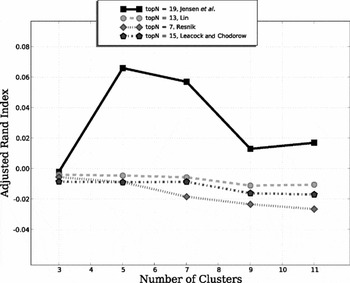
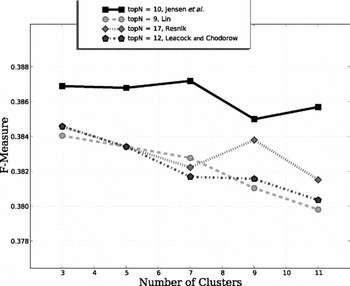
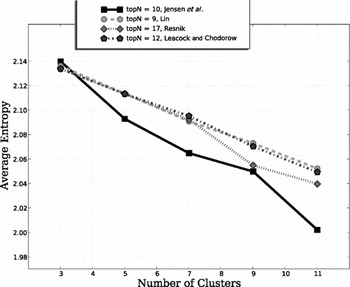
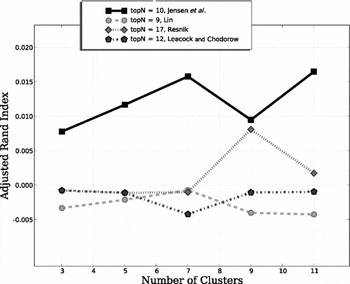
The performances of the selected distance measures in k-means clustering over the three cluster quality metrics for values of k ranging from 3 to 11 are shown in Figures 6–8.
k-means clustering: F-measure.

k-means clustering: entropy.

k-means clustering: adjusted Rand index.

The figures show that our distance metric produces generally better clusterings than the other competing metrics, according to our selected evaluation metrics. The differences are most significant for values of k between 5 and 7, which correspond closely to the number of underlying classes. This may indicate that these classes correspond to semantic topics of some description.
4.3.3 Semantic hierarchical agglomerative clustering
The performances of the selected distance measures in hierarchical agglomerative clustering (single link) over the three cluster quality metrics, again shown for values of k ranging from 3 to 11, are in Figures 9–11.
Hierarchical agglomerative clustering: F-measure.

Hierarchical agglomerative clustering: entropy.

Hierarchical agglomerative clustering: adjusted Rand index.

As with k-means, the use of our semantic distance measure in this experiment yields generally higher quality clusterings than the competing metrics. We further submit that our semantic distance will generalize, in distance based clustering algorithms, to other collections of natural language text, provided that the knowledge base structure used to determine word-level semantic distances adequately describes the semantic relationships of words in these collections.
5 Discussion
Before concluding, we make a few remarks about our proposed approach, highlighting some of its limitations and discussing possible extensions.
5.1 Choice of lexicon
Our approach is not tied to any implementation of the underlying conceptual graph. Indeed, it works for any implementation that reflects a partial order. However, it should be clear that the accuracy of our technique is directly related to the quality of the partial order, or in practical terms, the underlying lexicon. Indeed, the Hilbert space metric is profoundly influenced by, and in fact founded upon, the underlying graph topology.
We recognize that WordNet has some problems in the way hyponymy is implemented, as well as “holes” in its conceptual graph (see (Jensen et al. Reference Jensen, Giraud-Carrier and Davis2008) for an example), but it has the advantage of being freely accessible, and of covering a broad range of general concepts. For domain-specific tasks, such as in medicine, one would be better off using a domain-specific ontology as the underlying conceptual graph. What we are showing here is that given such a conceptual ordering, there is a natural, mathematically meaningful way to interpret such an ordering as a metric space.
Finally, we note that graphs are relatively easy to change, and appropriate modification of a semantic graph, whether by pruning or extension, is effectively an act of learning. We conjecture that an effective semantic algebra, like the one proposed here, is key to whatever mechanism informs a self-modifying process on the graph. Hence, an initially imperfect lexicon may be improved through time, thus also improving the metric's performance.
5.2 Choice of topology
In our implementation, we adopted the most obvious approach for the topological embedding, namely we used the order, or discrete (since G is finite), topology on G. There are clearly other, nontrivial T 0 topologies that might be considered, topologies that are entirely compatible with the order on G.
The answer as to whether one should try to construct a measure based on one of these more elaborate topologies is that one must be guided by one's intuition, and by the underlying “physics” of the model. The physical interpretation of natural language structure being open to discussion, discretion suggests that, in the absence of evidence to the contrary, we adopt the simple, discrete topology, as we have done here.
5.3 Choice of basis
While, in principle the complete set of chains, {ck}, is available, in practice one would be dealing with tens of thousands of chains, which would quickly make our approach computationally unfeasible. Consider instead a relatively small subset of chains {cφ} ⊂ {ck} that establishes a context for some local neighborhood of the text stream in process of assimilation. The chains could be generated by a sample of synsets taken from or associated with the local input stream, in addition to some constant set of chains representing general background knowledge. The span of such a subset corresponds to the (convex, closed) subspace  fc φ of fck, and the transform Γφ = ℋφQ−1 is a projection operator from ℒ onto ℒφ (represented isomorphically in the dual space).
We can think of {c φ} as establishing a context for some local neighborhood of the textual information of interest, the analog to an attention mechanism or filter for “working” memory, and Γφ as an operator that projects a point of view according to the context {c φ}. Hence, our interpretive context could easily be made to evolve as we process the input stream, producing a sequence of projection operators. This is evocative of situations where one approximates globally curvilinear coordinates on a manifold with a patchwork of local linear representations. In particular, the piecewise linear “curve” {Γφi} (interpreted geometrically as a path through an operator space) might function as a kind of signature for a basic story or line of discourse: something not unlike the notion of a sequence of frames, characterizing not only what does happen, but also what could happen at any point along the story line. Context-sensitive basis lists open the way for our approach to be used for such applications as tracking conversations.
5.4 Handling multiple relations
For simplicity, the description of our method focused on the single relation of hyponymy in the lexical semantic graph. The formalism is naturally extended, and indeed the way is clear for handling multiple relations. For example, let (N, oh) be the directed graph of nouns with respect to hyponymy (i.e., the graph we have worked with in this paper) and (N, om) be the directed graph of (the same) nouns with respect to meronymy.Footnote 7 Then, the vector space of bilinear functions on (N, oh) × (N, om) is the tensor product, fck* ⊗ gck*, of their respective dual function spaces, where the functions {gck} are associated with the maximal chains on (L, om). Our method carries seamlessly into the product space.
6 Conclusion
This paper presents a method to quantify lexical semantics by embedding the lexicon into an appropriate metric space through well-known topological operations. The proposed approach is a departure from most standard work in information extraction and natural language processing, which tends to use techniques from probability theory and statistical learning. Indeed, we show how topology can be effectively used to address the problem of semantic similarity, and define our document-level semantic distance metric as the Hausdorff distance between the duals of document summaries in some well-defined metric space.
Our motivation stems in part from the fact that many people have incorporated semantic relations such as hyponymy into their models for natural language semantics, and hyponymy is clearly an order relation. Order theory, topology and linear algebra are well defined disciplines in their own right and are well suited to modeling not just relations-as-ordered-sets, but as extended objects that contain the relations of interest. These objects have additional structure that derives from the order relation. Hence, it may be advantageous to develop a notion of conceptual metric that is founded on the techniques of these disciplines, rather than develop somewhat ad-hoc methods for computing semantic distance. What we achieve here is a notion of distance that is structurally dependent on the category of order relations, rather than the peculiar nature of a given object in the category. Given that the subjective distinctions in conceptual distance over different order relations should be manifest in the idiosyncratic detail of the order relations, we find a model wherein the metric tensor consistently and unambiguously arises from the structural aspects of semantic relations in the abstract, and then devise a procedure for computing distance based on the metric tensor.
Having described the procedure, we report on the successful use of the ensuing semantic distance, based here on WordNet's hyponymy graph, in the context of very large information retrieval tasks, as well as in one well-known document clustering task. The results suggest that our metric scales better than other WordNet-based approaches, making it more practical. They also show that it tends to produce higher quality clusterings. Further empirical analyses are necessary to compare our method with existing corpus-based methods, especially in the context of information retrieval, and to establish the precise conditions under which it may indeed be expected to perform better.
Appendix: Topological embedding
Intuitively, our approach can be summarized as follows. We first build a qualitative model of the lexicon in the form of a directed set. We then exploit the classic metrization theorems of elementary point-set-topology to map our qualitative model into a subspace of the Hilbert coordinate space. The Hilbert space being a function space, we modify the classical approach by Urysohn at this point by introducing the standard inner product, and require that the coordinate space metric be given with respect to an orthonormal basis (i.e., that the coordinate metric conform to the inner product). The Hilbert space, with its associated metric and inner product, is our proposed computational semantic model of the lexicon.
More formally, let (L, oh) be the directed graph of synsets with respect to hyponymy, and (L, τh) be the (discrete) order topology induced by oh. We exploit the topology τh to obtain a set of continuous functions {fck} in (L, τh), ℝ), where ck is the kth maximal chain in (L, oh) and ℝ is the real field (we assume, for practicality, that there are finitely many maximal chains). By continuous, we mean continuous with respect to τh. We define {fck} as follows. Let q be the cardinality of ck and mck: ck → ℝ, such that
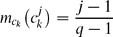
where cjk is the jth element of ck (ordered from root to leaf). Let l ∈ L be in (L, oh) and cilk be the lowest (towards the leaf) point of intersection of l (via some chain containing l) with ck (via oh). We define
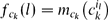
Let fck((L, τh),ℝ) be the subspace of ((L, τh),ℝ) spanned by {fck}. fck is our fulcrum for leveraging (L, τh) into a topological vector space (TVS). With the structure of a TVS our model provides the foundation for a semantic algebra that is consistent with the topology of the original graph, as well as motivates a coherent notion of distance between lexical semantic objects and sets of semantic objects. We map l ∈ L into fck via the transform
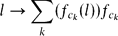
For any l ∈ L, consider the “pullback” operation of l on f ∈ fck, f = ∑k αck fck. We have
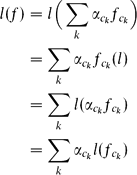
So we see that l is linear on fck. In fact, l is an element of fck*, the topological dual, or adjoint space, of fck. As elements of fck*, the notion of addition and scalar multiplication for elements l 1, l 2 ∈ L is defined as
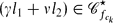
such that
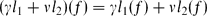
Let us therefore contemplate ℒ = fck*. Clearly L ⊑ ℒ. Via continuity, ℒ has a topology induced by τh on L, and so ℒ is an extension of L into a TVS.
In practice we constrain the range of fck to the closed interval [0, 1], and renormalize any algebraic expression in fck to the unit sphere in fck. In effect, our representation will associate vectors in ℒ with subspaces of fck, the so-called rays through the origin.
Suitably well-behaved function spaces, such as fck, are in fact inner product spaces. Typically the inner product of two vectors in a function space is given by
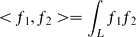
Since the nodes can be assigned a measure of one, we so stipulate and define the integral on that basis, thus obtaining a well-defined (and computable) notion of inner product on fck. Formally, we must demonstrate a suitable measure on L. Consider the Dirac measure at the point l, defined as εl(f) = l(f), where εl is a positive Radon measure on L, and is an analog of the Dirac delta function on ℝn. From the Dirac measures we can construct a so-called atomic measure of the form μ = ∑L δ(l) εl, where δ(l) is some continuous function from L to ℝ (i.e., a kind of “density function”). In the absence of any compelling argument to the contrary, one may as well take δ to be the constant function 1, a move we adopt in our implementation. With a valid measure μ, we can define integration on L and so obtain the needed notion of inner product on fck.
Since ℒ = fck*, we can express the dual relationship between ℒ and fck as a bilinear scalar function M: (l, f) → l(f) from ℒ × fck into the scalar field ℝ (Thrall and Tornheim Reference Thrall and Tornheim1970). Given a basis Bl = {bl} for ℒ and a basis Bf = {bf} for fck, we can write M(x, y) as XCYT where the row matrix X = (x 1, x 2,. . .,xn) is determined by x = x 1bl 1 + x 2bl 2 + ··· + xn bln, the row matrix Y = (y 1, y 2,. . .,yn) is determined by y = y 1bf 1 + y 2bf 2 + ··· + yn bfn, and the matrix C = [cij] is determined by cij = M(bli, bfj). Note that we are assuming that fck is finite dimensional (a practical consideration due to the fact that our graph (L, oh) is finite, and so has only finitely many chains) and observe that dim(ℒ) = dim(fck) = n since ℒ and fck are dual.
If we further have an orthonormal basis Bf ⊥ = {bf ⊥}, where YBf = YBf⊥Q, then we can effect a change of basis using the equivalent duality

The reader might recognize that in terms of linear transformations, we are constructing a representation for l in terms of its conjugate vector, i.e., we wish to obtain an isomorphic representation for vectors in ℒ with respect to an orthonormal basis for fck. Representations of this kind are important if we wish to recover the “standard” inner product formula < v 1, v 2 > = X1X2T, which works for coordinate-based representations only with respect to an orthonormal basis. Finally, note that we can always obtain such a representation, i.e., some C′ can always be obtained from some Q, since some {bf ⊥} is always obtainable in principle – and in practice – if by no other means than at least by performing a Gram–Schmidt procedure on Bf (Golub and Van Loan Reference Golub and Van Loan1996). Note that the Gram–Schmidt process is one way to free ourselves of coordinate dependence, so that we do indeed map to conjugate vectors. Other techniques, such as SVD, may be applied.
Consider the mapping ℋ: ℒ → fck given by
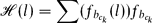
where {fbck} is a basis selected from the spanning set {fck}. Here, we are essentially utilizing Urysohn's lemma (via τh, on the space of attributes associated with hyponymy) to promote ℒ to a Hilbert space, the intermediate nodes along a basis chain corresponding to the “separating sets” (Hocking and Young Reference Hocking and Young1961). Letting Q = E 1E 2. . . En be the sequence of elementary row operations that yields an orthonormal basis {wi} from {fbck}, we can finally construct the transformation

This gives us a representational form for elements of ℒ with respect to an orthonormal basis in fck. Note that we have (necessarily) shifted from the language of bilinear forms to that of linear transformations, a fact implicitly acknowledged in the use of Q −1 as opposed to QT.
Vector addition in ℒ is defined via Γ:
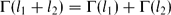
wherein one might interpret addition as a disjunctive operation on L (and so, by extension, on ℒ). The external product, ξl (ξ ∈ ℝ), is interpreted as leaving the semantic value unchanged; i.e., ξl = l. This is consistent with the notion that addition is disjunction on the graph, e.g., for ζ ∈ L, and taking ζ = l in the extension of L to ℒ, we have
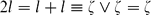
Thus, semantic value is inherent in the direction of lΓ. By “direction of lΓ,” we mean the “direction” of the ray defined by lΓ. From a topological point of view, we are essentially in the real projective space ℝP (n−1)), where n = dim(fck).