

Introduction
Approaches to the subject organisation and retrieval of legal information have conventionally differed somewhat from other disciplines. Although classification schemes exist for law libraries (of which Moys is undoubtedly the best known (Moys, Reference Moys2001)) and all of the general classification schemes make provision for law, in legal collections subject has usually been a secondary factor in the physical arrangement of resources. Although monographic works may be arranged by subject, since the major part of legal information is published in discipline specific formats, primary arrangement will normally be by form. Should more than one jurisdiction be represented in the collection that also will usually take precedence over subject.
As a result, in most situations, systematic order is of little help in identifying semantic content, and the retrieval of information on particular topics must be achieved by means of indexing. In a digital context, systematic organisation using taxonomies is not uncommon, but population of the taxonomy is usually effected through the assignment of index terms, keywords or metadata. These index terms may be arrived at in one of three ways: mechanically extracted from the text with automatic indexing tools based on computational methods (usually statistical, but increasingly informed by natural language processing techniques); humanly assigned in a manner informed by reading and interpretation of the text, but which is relatively ad hoc in the choice of terms; humanly assigned using a controlled vocabulary. This paper will concentrate on the role of controlled vocabularies in achieving and enhancing retrieval, and will examine the means by which such vocabularies are constructed.
Vocabulary tools in the field of law
A problem exists with the definition of different subject organisation and retrieval systems, since terms such as ‘thesaurus’, ‘taxonomy’, or, more recently, ‘ontology’, may be used interchangeably and with not much regard for the differences between these tools (Gilchrist, Reference Gilchrist2003). A large number of terminological and vocabulary tools exist for understanding and interpreting legal terminology, but many of these are straightforward dictionaries, although they include a number of works that style themselves thesauri. An interesting example of these is Burton's legal thesaurus (Burton, Reference Burton2007), which is a thesaurus on the model of Roget, the only one I know of for a specific subject area. It provides access to definitions and synonyms, as well as the substantial provision of cross-references which gives it some potential value as an indexing tool.
Thesauri intended for indexing and retrieval purposes are rather thinner on the ground. Conventionally, thesauri have provided the terms used in database indexing, but it is hard to detect their presence in most contemporary legal databases. Taxonomy warehouse (Taxonomy warehouse, n.d), a site which provides information about a vast number of controlled vocabularies of all kinds, has 58 titles in its ‘Law and administration’ category, including thesauri, taxonomies, legal subject headings, and classification schemes, of which 27 relate specifically to law, rather than politics, government, or administration. Twelve of the 27 are various sections of the Library of Congress Classification schedules for Class K, Law, and the list also contains three traditional dictionaries of legal terms, leaving just twelve tools designated as taxonomies or thesauri for the management of information about law, justice, criminology, or some narrower field of law.
Although it is relatively difficult for non-subscribers to view thesauri used in commercial law databases, some limited information can be found. Some thesauri, such as that employed in Butterworth's LexisNexis (LexisNexis, n.d.) service, do no more than act as a synonym finder, and for the most part such terminology tools seem to be very limited in their scope. Even Moys' ‘thesaurus-index’ to the classification scheme is restricted to the control of preferred and non-preferred terms, and ignores the other thesaural relationships for cross-referencing purposes. Another type of ‘thesaurus’ tool is that which provides for broad categorisation of documents using keywords, such as the Australian WebLaw thesaurus (WebLaw, n.d.) an extract from which is shown below. None of these examples exhibit the full range of features expected in a thesaurus conforming to the various British and international standards.
This is a pity, as a well constructed thesaurus offers all sorts of advantages as a support to information retrieval. In addition to providing a standardised set of indexing terms, the thesaurus allows for navigation of the vocabulary, and of resources indexed by it, can aid in query formulation and modification, often without the active intervention of the end-user. Such tools, often described as ‘search’ thesauri, have been well documented. The thesaurus of the Global legal information network (Global legal information network, n.d.) managed by the Library of Congress is a good example, providing the searcher with access to the thesaurus terms, and to broader, narrower, and related terms. Figure 2 opposite shows two of the hits on a search for ‘marriage’, expanded to show the related thesaurus entries.
WebLaw thesaurus.

Global legal information network thesaurus.

Such a thesaurus accompanied by a compatible taxonomy, can also act as a browsing tool.
The latter type of thesaurus is conveniently created by means of facet analysis, extracting the thesaurus from a faceted classification or taxonomy built as a starting point. Although there are other methods of thesaurus construction (notably using computational tools based on text analysis and word distribution and co-occurrence) facet analysis is widely recognized as the only approach with a clear intellectual and conceptual rationale (Hjorland, Reference Hjorland and López-Huertas2002). The faceted approach to knowledge organisation, for many decades the exclusive property of the library and information professional, is now very much more widely acknowledged as an effective way of managing resources of all kinds, and can be seen in virtual libraries, museum portals, and e-commerce sites, as well as in controlled vocabularies and their associated databases (La Barre, Reference La Barre2005). Its usefulness as a means of creating a thesaurus on the back of an associated classification was documented as long ago as the 1980s (Aitchison, Reference Aitchison1986), and several published thesauri were compiled manually using the technique, Aitchison et al., Reference Aitchison1969; Aitchison, Reference Aitchison1985; Aitchison et al., Reference Aitchison1992). Such thesauri meet all the requirements of the international standards, and in fact the most recent British standard explicitly states that the faceted approach provides a useful methodology for controlled vocabulary construction (BS 8723, 2005). Recent work on the Bliss Bibliographic Classification 2nd edition (Mills & Broughton, Reference Mills and Broughton1977–), has investigated the way in which this intellectual process can be mechanised, generating the thesaurus automatically from encoded data associated with the classification structure. To date, the research has concentrated on the fields of music, education, and the arts, but law promises to be a fruitful area for investigation.
Bliss Bibliographic Classification Class S, Law
The Bliss Bibliographic Classification 2nd edition (BC2) is a thorough going revision of H. E. Bliss's original Bibliographic Classification (BC1) published between 1940 and 1953. Acclaimed widely for its excellent overall structure and evident scholarly basis, BC1 nevertheless lacked the consistency in its internal structure required in a modern retrieval system. The revision programme, begun in the 1970 s, has been radical, subjecting the classification to a rigorous process of analysis and re-organisation according to the principles of S.R. Ranganathan, as developed by the UK Classification Research Group.
Class S of BC2 (Mills & Broughton, Reference Mills and Broughton1996) is an excellent example of the successful application of facet analysis to a subject domain. BC2 employs the standard categories determined by the work of the UK Classification Research Group as the basis of analysis and organisation of terminology in any particular domain; these are: thing, kind, part, property, material, process, operation, patient, product, by-product, agent, space, and time. Discussion and exposition of these fundamental categories can be found in the Introduction to BC2, and in other sources (Broughton, Reference Broughton2006). In the context of any given subject field, usually only a smaller number of the categories are relevant, and these are re-named as ‘facets’ in the subject. In the case of law, there are five significant facets:
1. Jurisdictions: these are roughly equivalent to the space category, with terms like English law, French law, European Community law, and so on, but occasionally the jurisdiction may be a community defined in ways other than location as is the case with religious law
2. Substantive law: the subjects of law, equivalent to the thing category, containing terms such as contract law, property law, criminal law, family law
3. Legal practice and procedure: the processes and operations category, covering courts, defence, prosecution, evidence, judgment, etc.
4. Attributes and principles of law, jurisprudence: the property category including legal philosophy, comparative law, law reform, causation, and so on
5. Common subdivisions: includes the more general categories such as agents (persons and organisations in the law), time (ancient law, mediaeval law), and also provision for forms of documentation.
Within each facet there may be many hundreds of terms, so these are further subdivided into ‘arrays’ or groupings of terms that represent a range of values, or options, associated with a particular ‘characteristic’ or ‘principle of division’. For example, under the law of persons, persons may be characterised (for instance) by age, by gender, by language, by ethnic group, by marital and kinship relations, by employment factors, or by citizenship status. These give rise to subordinate clusterings of terms like this:

Within these groups of terms, hierarchical position is indicated by indentation of subordinate concepts, so that the relationship of classes and sub-classes is clearly visible from the physical display. Across the whole classification the hierarchical structure is carefully monitored so that accurate representation of the relative positions of classes is guaranteed.
The notation is not in any way expressive of the hierarchy of concepts in the way that, for example, Dewey is. It serves only to maintain the linear sequence and there is no correspondence between the length of a class mark and the position of its class in the hierarchy. It does however function as a control number, or unique identifier, for each concept.
An important part of the function of a faceted scheme is to allow the representation of complex concepts through synthesis. In BC2 any number of individual concepts may be combined to express a compound topic. The order of combination, or citation order, is broadly the order of facets as listed above. The use of a default citation order (standard citation order) provides for regularity of structure in the classified sequence, and consistency in the process of combination that allows users to predict the position of compounds. So in the case of Arbitration in international investment agreements the title may be analysed into its constituent concepts: arbitration, international law, investment, agreements, and these combined in the order of facets:
International law [Jurisdiction] – investment/agreements [substantive] – arbitration [procedures]
In the published volumes many compounds are pre-combined and the basic classification populated with these examples of synthesis. This is done to aid the indexer in the rules of combination, and ensure that sought terms are entered into the alphabetical index. So, for example, under a particular jurisdiction, key concepts may be added from the main body of the classification, as in this example from Roman Catholic law:

By these various processes a complex classification is developed, but one which is very regular and logical in its structure and in which complexity is predictably handled.
The classification data itself is held in encoded format, using a customised system devised some years ago for BC2. The raw data is relatively simple and is produced with a basic text editor, but can be converted by the software into a much more sophisticated format for publication of the printed schedules. A sample of encoded data for law might look like the following:

The software interprets this encoding to create a database of the entry terms, which will contain information about the sequence of classes, the hierarchical position of a class, and the presence of ‘non-classes’, such as characteristics of division, or node labels; from this the programs can generate the classification display with appropriate typographical formatting, and a visually representative hierarchy. The encoding also contains data relating to the choice and form of entry terms for the alphabetical index to the classification.
With no manual or intellectual intervention, other than to set the programs running, the following schedule display would be output from the example above:

More substantial portions of text would involve greater typographical variation.
The BC2 thesaurus project
In 2004 it was decided to investigate the feasibility of converting BC2 to a thesaurus, or, more accurately, a thesauro-facet format, since the classification would still be maintained as part of the product. It was felt that opportunities for expanding the classification user base were limited, but that there was a larger market for well-structured terminologies for indexing and tagging in all kinds of subjects. Initially it was assumed that this would be a manual exercise, following the methodology of the ‘BC2 thesauri’ created in the past. But, given the close conceptual and structural correspondence between the faceted classification and its associated thesaurus, it was subsequently decided to see whether the BC2 programs could be developed to manage the conversion process.
The reason for the success of the faceted classification as a source for a thesaurus lies in the very clear and unambiguous conceptual structure of such schemes. The process of deriving the thesaurus is documented in a number of sources (Aitchison et al., Reference Aitchison2000; Shearer, Reference Shearer2004; Broughton, Reference Broughton2005) and provides a well established methodology which can easily be adopted by anyone wishing to create a thesaurus for a specialised field.
The hierarchical relationships of broader term (BT) and narrower term (NT) are very clearly evident in the classification display. In the following example, for instance, a variety of entry terms and their thesaurus tags are easily extracted:


Terms in the same array, or terms which are co-ordinate in the hierarchy, may also be candidates for associative relationship status although, unlike the BT/NT relationships, this usually has to be judged on an individual basis by the thesaurus compiler:
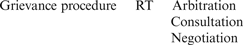
Preferred and non-preferred terms may also be deduced from the order of synonyms, or near synonyms, in the class headings, and used to generate equivalence relationships:
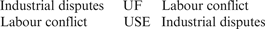
The range of associative relationships can also be extended by examining the examples of combination in the schedule, many of which qualify as compound terms for the purposes of the thesaurus. Whereas relationships between terms in the same facet, since they are all by definition of the same categorical status (things, or properties, or operations), are generally of the BT/NT kind, examples of combination between facets are more likely to give rise to associative relationships.
The law schedules are, for BC2, unusually lacking in compounds between facets, but nevertheless the few examples that there are illustrate the occurrence of RTs here.

In the first example, terms such as ‘Codification of offences’ or ‘Decriminalisation’ are created by the combination of the substantive facet term ‘Criminal offences’ with the philosophy facet term ‘Classification’. Therefore the relationships with the containing class are:
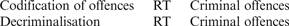
Similarly, in the second example, the combination is between the substantive facet, and the agents facet, to generate:

It should be noted that the problem of semantic and syntactic factoring (or splitting) of compound terms is a more complex matter and is not fully addressed here.
The BC2 thesaurus software
Although initially it was envisaged that the BC2 thesaurus format would be created manually, it was decided to investigate whether some saving of effort could be made by attempting to derive at least a first draft from the classification data files.
This required the extension of the software to accommodate a new type of display, but it was hoped that the information about the structural relationships between concepts already inherent in the encoding would support the identification of BT/NT relationships and equivalence relationships. It was not expected that RTs would easily be identified mechanically. A system specification was written for the thesaurus, and the then existing suite of programs were modified with the new objectives in mind (Broughton, Reference Broughton2008).
The classification coding carries information about the sequence of classes and their hierarchical position, as described above. Because the general scheduling rules for a faceted scheme control the organisation of classes into arrays and facets, the program also knows that there is an invariable sequence of:
• A class
• Its first offspring
• If no offspring, its next sibling
• If no more siblings, its parent's next sibling
• If no more parent's siblings, its grandparent's next sibling
• And so on, ad infinitum.
This provides the hierarchic order, and given that knowledge, and the level of each class, the program is able to infer the parent, previous sibling, next sibling, or offspring of an item, and to ascertain the relationship between any given pair of classes.
It is therefore possible to infer many of the thesaural cross-references from this information, where these are supported by the facet structure as discussed above. Because the program is able to infer an upward reference, i.e. to a class's immediate parent or, if the immediate parent is a non-class, to the grandparent, broader terms can be identified. Whenever an upward reference is inferred, the reciprocal downward reference is also inferred. Although upward and downward and BT and NT are not absolutely synonymous, they usually are and this is sufficient to infer these relationships unless otherwise instructed.
The programs also understand that synonyms in a class heading are separated by commas, and that the first of these is the preferred term, enabling the determination of equivalence, or USE/UF relationships.
Results
The software was tested initially on the most recently published schedule, that for the Fine Arts, and the results, while encouraging, have been mixed. It should be stressed that the input data for this schedule, like all previous schedules, was created only with the classification display in mind, and without any provision for the thesaurus format. It seemed likely therefore, that the structural components of the classification/thesaurus would be satisfactorily managed, but that vocabulary control aspects would be less so.
The product is certainly thesaurus-like in its appearance, and BT/NT relationships appear to be accurately identified. It was never anticipated that RTs could be conveniently managed in this way, but the programs allow for the addition of RT information to the encoding, which, while it requires intellectual effort at the data creation stage, will support automatic generation of RTs for new files.
As expected, problems occurred with equivalence relationships and with the form of the thesaurus terms (Aitchison, Reference Aitchison2004). Both of these difficulties are a consequence of the relative lack of attention given to the form of class headings when constructing a classification scheme. When working with concepts rather than terms, and where classes are represented by notational codes, there is no need to bother much about the formulation of terms, or the relative importance of synonyms, since the organisation of material, and its subsequent retrieval, is based on the codes.
Examples of the type of class heading that will generate a poor thesaurus term are easily found in the law schedules.

Here, typically for the classification, meaning is taken from the context, and the actual class name is not necessarily fully representative of the concept e.g. ‘Regulation’ rather than ‘Regulation of medical practice’, ‘Negligence’ rather than ‘Medical negligence’, ‘Trials’ rather than ‘Murder trials’. Since this practice is endemic in the existing source files, it cannot easily be remedied there. But for the future, editorial guidelines currently being developed will ensure that there is a smoother transition from the class name to the thesaurus term.
Conclusions
We know from experience that a faceted classification forms an excellent starting point for the creation of a thesaurus. Most of the relationships between terms are either explicit in the classification or may be inferred by the compiler from attributes of the terms, such as their relative hierarchical position, or facet membership. Equivalence relationships can be deduced where class headings include one or more synonyms.
If the classification data is held in a database or encoded format, this work can be carried out automatically using appropriate software, and a thesaurus can be generated from source files also used for classification display and indexing. However, not all thesaurus relationships are equally well handled, and some associative relationships need manual addition. Equivalence relationships also need some further work, as do other aspects of vocabulary control essential to a good thesaurus. These difficulties are the result of working with data originally intended only for the classification structure, and in the future an editorial policy for the formulation of class headings will ensure that much better results are achieved.



