



1. Introduction
One of the fundamental notions of an absolutely continuous lifetime random variable X is the hazard rate function
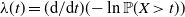 $\lambda (t)=({\mathrm{d}}/{\mathrm{d}} t)(\!-\ln\mathbb{P}(X>t))$
. The importance of the hazard rate function goes beyond the IFR and DFR situations of monotonic ageing. Whereas the notions of IFR and DFR can be defined without requiring the notion of hazard rate (for example, in terms of stochastic monotonicity of residual lifetime random variables), non-monotonic ageing (such as bath-tub shaped hazard rates) is best modeled and studied in terms of the hazard rate. However, the extension of the concept of univariate hazard rate to a multivariate situation is far from straightforward. A number of definitions of multivariate hazard rates have been proposed in the literature.
Basu [Reference Basu9] defined the bivariate failure rate as
 \begin{equation*}\lambda (x,y)=\dfrac{f(x,y)}{\overline{F}(x,y)},\end{equation*}
where f(x, y) is the joint probability density function (PDF) and
 $\overline{F}(x,y)$
is the joint survival function. However, in general,
 $\lambda (x,y)$
, defined above, does not determine the joint survival function. This fact has been noticed by several researchers including Arias-Nicolas et al. [Reference Arias-Nicolas, Mulero, Nunez-Barrera and Suárez-Llorens2], Finkelstein [Reference Finkelstein13], and Finkelstein and Esaulova [Reference Finkelstein and Esaulova14]. Navarro [Reference Navarro28] has shown that Basu’s failure rate and the two marginals together determine the joint distribution.
Johnson and Kotz [Reference Johnson and Kotz22] considered the vector of hazard components
 \begin{align*}(h_{1}(x,y),h_{2}(x,y)) &= \nabla (\!-\ln \overline{F}(x,y)) \notag \\ &= \biggl(\!-\dfrac{\partial }{\partial x}\ln \overline{F}(x,y),-\dfrac{\partial }{\partial y}\ln \overline{F}(x,y)\biggr).\end{align*}
Clearly,
 $h_{1}(x,y)$
is the hazard rate of X given
 $Y>y$
. Analogously,
 $h_{2}(x,y)$
is the hazard rate of Y given
 $X>x$
. It is well known that the vector
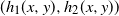 $(h_{1}(x,y),h_{2}(x,y))$
uniquely determines the joint distribution of X and Y; see, for example, Arnold and Gupta [Reference Arnold and Gupta3]. Johnson and Kotz [Reference Johnson and Kotz22] say that the distribution of (X, Y) has vector (or gradient) bivariate failure rate if
 $h_{1}(x,y)$
is increasing in x (for each y) and
 $h_{2}(x,y)$
is increasing in y (for each x).
Clayton [Reference Clayton11] proposed conditional age-specific hazard rates and Shaked and Shanthikumar [Reference Shaked and Shanthikumar37] developed a notion of multivariate conditional hazard rate functions. However, the definition of a universal multivariate hazard rate function capable of capturing the full intricacies of multivariate ageing remains elusive. In the literature on multivariate ageing, the names ‘increasing failure rate’ and ‘decreasing failure rate’ are commonly used to designate specific properties of positive or negative ageing, respectively, even if the properties at hand are not expressed in terms of any specific definition of ‘multivariate failure rate’ or even when no definition of ‘multivariate failure rate’ is taken into consideration. The different notions of multivariate ageing are best approached as properties of the joint distributions (or of the random vectors), rather than as properties of specifically defined multivariate failure rate functions. The literature on multivariate ageing focuses on developing multivariate IFR (multivariate DFR) via stochastic orderings and other analogies with the univariate case. The rich literature in this area includes Arias-Nicolas et al. [Reference Arias-Nicolas, Belzunce, Nunez-Barrera and Suárez-Llorens1, Reference Arias-Nicolas, Mulero, Nunez-Barrera and Suárez-Llorens2], Arriaza et al. [Reference Arriaza, Belzunce, Mulero and Suárez-Llorens4], Barlow and Spizzichino [Reference Barlow and Spizzichino5], Bassan et al. [8], Bassan and Spizzichino [Reference Bassan and Spizzichino6, Reference Bassan and Spizzichino7], Harris [Reference Harris19], Roy [Reference Roy33], and Savits [Reference Savits34]. Some definitions of multivariate ageing imply corresponding univariate ageing properties for the unidimensional marginals and some do not. Some approaches are based on orderings (multivariate convex, multivariate dispersive) with respect to a reference distribution that is (possibly conditionally rather than unconditionally) a multivariate exponential distribution.
We see a lot of merit in developing multivariate IFR (multivariate DFR) notions without explicitly tying them to any particular definition of multivariate hazard rate and without reference to any specific multivariate exponential distribution. In this connection, we propose a very natural way of defining a multivariate IFR (multivariate DFR) distribution as one whose multivariate survival function is a log-concave (log-convex) function of all the variables jointly. This, of course, is motivated by the corresponding definition for the univariate case. Although Barlow and Spizzichino [Reference Barlow and Spizzichino5] had recognized the appeal of log-concavity (log-convexity) as an approach to multivariate IFR (multivariate DFR), this notion has not been explored. The focus of the present paper is on the bivariate case, and we propose the following definition of bivariate increasing (decreasing) failure rate in the sense of log-concavity (log-convexity).
Definition 1.1. A bivariate random vector (X,Y) is bivariate increasing failure rate in the sense of log-concavity (BIFR-LCC) if the joint survival function
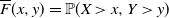 $\overline{F}(x,y)=\mathbb{P}(X>x,Y>y)$
,
 $(x,y)\in R^{2}$
, is log-concave, that is, if
 \begin{align*}\overline{F}\big(\alpha (x,y)+(1-\alpha )\big(x^{\prime },y^{\prime }\big)\big)\geq \big\{\overline{F}(x,y)\big\}^{\alpha }\big\{\overline{F}\big(x^{\prime },y^{\prime}\big)\big\}^{1-\alpha }\end{align*}
for
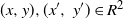 $(x,y),(x^{\prime },\ y^{\prime }) \in R^{2}$
,
 $\alpha \in (0,1)$
.
Similarly, we shall say that (X, Y) is bivariate decreasing failure rate in the sense of log- convexity (BDFR-LCX) if the joint survival function
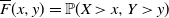 $\overline{F}(x,y)=\mathbb{P}(X>x,Y>y)$
,
 $(x,y)\in R^{2}$
, is log-convex. In this paper we will give the results for BIFR-LCC only. As in the univariate case, the results for BDFR-LCX and BIFR-LCC can differ in significant respects.
It is clear that if (X, Y) is BIFR-LCC, then the marginal distributions of X and Y have IFR in the usual univariate sense. This is in contrast to the various notions of multivariate IFR; see Brindley and Thompson [Reference Brindley and Thompson10] as well as the later papers in the literature on multivariateageing.
The outline of this paper is as follows. In Section 2 we first point out that the distributions having log-concave densities are BIFR-LCC. We then compare our notion of BIFR-LCC with the other notions of bivariate increasing failure rate distributions studied in the literature mentioned earlier. Our BIFR-LCC class has its own novelty and distinct character. In Section 3 we give an important necessary and sufficient condition for a twice differentiable survival function to be BIFR-LCC. This condition explains how and why the dependence between the lifetimes of the two components affects their joint ageing. The cross-derivative of
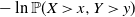 $-\ln \mathbb{P} (X>x,Y>y)$
, which serves as the vehicle for information beyond the hazard gradient, is connected to Clayton’s measure of association and Holland and Wang’s measure of local dependence. In Section 4 we provide a number of examples that explain BIFR-LCC for both positive and negative dependence. Finally, in Section 5, we offer some comments on the salient features of this paper.
2. Connections of BIFR-LCC with other notions of concavity and ageing
Throughout this paper we will assume that the joint survival function
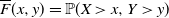 $\overline{F}(x,y)=\mathbb{P}(X>x,Y>y)$
is positive on a convex open set
 $S\subset R^{2}$
. Then the log-concavity of
 $\overline{F}$
amounts to saying that
 $\overline{F}(x,y)$
is expressible as
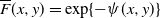 $\overline{F}(x,y)=\exp \{-\psi(x,y)\}$
, where
 $\psi (x,y)$
is convex on S. In fact the following is true.
Proposition 2.1. If
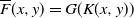 $\overline{F}(x,y)=G(K(x,y))$
is a survival function on S such that G is a univariate log-concave survival function and
 $K(x,y)$
is convex on
 $S$
, then
 $\overline{F}$
is BIFR-LCC.
We omit the proof that follows from well-known properties of log-concavity; see Klinger and Mangasarian [Reference Klinger and Mangasarian25] and Kallberg and Ziemba [Reference Kallberg and Ziemba24]. A special case of the above proposition occurs when
 $G(0)=0$
and
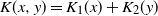 $K(x,y)=K_{1}(x)+K_{2}(y)$
, where
 $K_{1} $
and
 $K_{2}$
are non-negative increasing convex functions on
 $[0,\infty )$
with
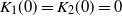 $K_{1}(0)=K_{2}(0)=0$
and
 $K_{1}(t)$
and
 $K_{2}(t)\rightarrow \infty $
as
 $t\rightarrow \infty $
.
As far as the relationships between BIFR-LCC and bivariate concave (convex) survival functions is concerned, the following fact is easy to verify.
Proposition 2.2.
 $(\text{a})$
If
 $\overline{F}$
is BIFR-LCC on S, then
 $\overline{F}$
is convex on S, but not conversely.
 $(\text{b})$
If a survival function
 $\overline{F}$
is concave on S, then
 $\overline{F}$
is BIFR-LCC on S.
2.1. Log-concave density
The most important sufficient condition for
 $\overline{F}$
to be BIFR-LCC is that it has a log-concave probability density function (PDF). If
 $\overline{F}(x,y)$
has a PDF f(x, y) that is log-concave, then both
 $\overline{F}(x,y)$
and
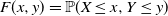 $F(x,y)=\mathbb{P}(X\leq x,Y\leq y)$
are log-concave. We refer the reader to Prekopa [Reference Prekopa31, Reference Prekopa32] for this and many other interesting facts. Logarithmic concavity is a fairly common property. The bivariate normal distribution is a well-known example. Many other bivariate densities, such as bivariate beta, bivariate Dirichlet, and bivariate Wishart, are log-concave (for suitable parameter values).
2.2. BIFR-LCC and BIFR-SCHUR-CONCAVE
An appealing approach to modeling monotonic ageing for random vectors is the notion of Schur-concavity (Schur-convexity) of the joint survival function. Although this approach is invalid if the joint survival function is not permutation-invariant (i.e. if the random vector is not exchangeable), it is still of interest to explore the relationship between our notion of BIFR-LCC and the Schur-concavity of
 $\overline{F}(x.y)$
. Some basic facts are given below.
Definition 2.1. A survival function
 $\overline{F}(x,y)$
of an exchangeable random vector
 $(X,Y)$
is Schur-concave if
 \begin{equation*}\overline{F}(x+\tau ,y-\tau )\geq \overline{F}(x,y),\quad x<y,\ 0\leq \tau\leq y-x.\end{equation*}
See Bassan and Spizzichino [Reference Bassan and Spizzichino7, page 323] and Marshall and Olkin [Reference Marshall and Olkin27].
Definition 2.2. A bivariate random vector
 $(X, Y)$
is said to be bivariate increasing failure rate in the sense of Schur-concavity (BIFR-SCC) if the joint survival function
 $\overline{F}(x,y)$
is Schur-concave. If
 $\overline{F}(x,y)$
is Schur-convex,
 $(X,Y)$
is said to have a bivariate decreasing failure rate in the sense of Schur-convexity (BDFR-SCX).
See Bassan et al. [8].
It is to be noted here that the condition of exchangeability of X and Y implicit in the definition of a Schur-concave joint survival function is a very strong requirement from the point of view of statistical modeling. We refer to Durante [Reference Durante12] for further discussion and for a method of constructing distributions that can describe the behavior of non-exchangeable randomvectors.
The motivation to interpret Schur-concavity of the joint survival function as bivariate positive ageing is given by an equivalent definition presented in the next subsection. The relationship between BIFR-LCC and BIFR-SCC will become clear from the following facts.
Theorem 2.1. Let
 $\overline{F}(x,y)$
be permutation-invariant and log-concave. Then
 $\overline{F}(x,y)$
is Schur-concave.
Proof. See Spizzichino [Reference Spizzichino38].

Remark 2.1. It is to be noted that
 $\overline{F}(x,y)$
being Schur-concave does not generally imply that
 $(X, Y)$
is BIFR-LCC. The log-concavity of
 $\overline{F}(x,y)$
is a stronger condition than the Schur-concavity of
 $\overline{F}(x,y)$
; see Barlow and Spizzichino [Reference Barlow and Spizzichino5]. Since BIFR-LCC does not require the survival function to be permutation-invariant, in general BIFR-LCC and BIFR-SCC have no implication relationships.
2.3. Notions of BIFR in terms of stochastic and hazard rate orderings of residual distributions
For the case of an exchangeable random vector (X, Y), Bassan and Spizzichino [Reference Bassan and Spizzichino6] (see also Bassan et al. [8]) introduced two extensions of the usual notion of univariate IFR. Definition 2.3 below is a restatement of one of Bassan and Spizzichino’s definitions to avoidconfusion.
Definition 2.3. An exchangeable random vector (X, Y) is bivariate IFR in the weak sense(w-BIFR) if
 \begin{align*}\mathbb{P}(X-x > u\mid X>x,Y>y)\geq \mathbb{P}(Y-y>u\mid X>x,Y>y),\quad u > 0,\ x<y.\end{align*}
Definition 2.4. An exchangeable random vector (X, Y) is bivariate IFR in the strong sense (s-BIFR) if
 \begin{equation*}\dfrac{\mathbb{P}(X-x>u\mid X>x,Y>y)}{\mathbb{P}(Y-y>u\mid X>x,Y>y)}\end{equation*}
is increasing in
 $u>0$
for
 $x<y$
.
Definition 2.3 is the stochastic ordering and Definition 2.4 is the hazard rate ordering between the conditional distributions of
 $X-x$
and
 $Y-y$
given
 $\{X>x,Y>y\}$
. Since hazard rate ordering implies stochastic ordering (see Shaked and Shanthikumar [Reference Shaked and Shanthikumar37]), Definition 2.4 presents a stronger notion of BIFR than Definition 2.3. Note that the two definitions appear to treat the conditional distributions of
 $X-x$
and
 $Y-y$
(given
 $\{X>x,Y>y\}$
) non-symmetrically, but that is not the case because (X,Y) is assumed to be exchangeable.
Remark 2.2. It can be shown that the w-BIFR notion of Definition 2.3 is exactly the same as the Schur-concavity notion BIFR-SCC. Therefore, in general, there are no implication relationships between BIFR-LCC and w-BIFR.
Remark 2.3. Neither w-BIFR nor s-BIFR imply that the marginal distributions of X and Y must be IFR (in the usual univariate sense). However, BIFR-LCC implies that the marginal distributions are IFR. Therefore, in general, BIFR-LCC has no implication relationships with w-BIFR or s-BIFR.
This means that
 $\overline{F}(x,y)$
being Schur-concave does not generally imply that X and Y are IFR; see Bassan and Spizzichino [Reference Bassan and Spizzichino6]. The following result provides conditions under which s-BIFR implies that the marginals are IFR.
Theorem 2.2. Let
 $(X,Y)$
be s-BIFR and let X be right tail decreasing in Y. Then the marginal distribution of X is IFR.
Proof. See Bassan et al. [8].
In the case of independent, identically distributed random variables, we have the following result.
Theorem 2.3. The joint survival function of independent, identically distributed random variables is Schur-concave if and only if the marginal distributions are IFR.
Proof. See Bassan and Spizzichino [Reference Bassan and Spizzichino6].
2.4. Comparison with multivariate IFR notions based on stochastic orderings
A number of concepts of multivariate (and hence bivariate) IFR have been proposed in the literature on the basis of orderings such as multivariate dispersing ordering and multivariate convex ordering. Arias-Nicolas et al. [Reference Arias-Nicolas, Belzunce, Nunez-Barrera and Suárez-Llorens1] proposed a multivariate IFR definition via a comparison of multivariate residual lives in terms of a multivariate dispersive order. Roy [Reference Roy33] studied a multivariate IFR notion in terms of multivariate convex order and a Gumbel multivariate exponential distribution. Arriaza et al. [Reference Arriaza, Belzunce, Mulero and Suárez-Llorens4] proposed a multivariate IFR ageing notion via a multivariate convex transform ordering with a multivariate conditional distribution defined by them. Their construction involves sequential conditional distributions modeled by shifted exponential distribution. However, our notion of BIFR-LCC bears no relationship to any of these approaches. Our motivation is to directly extend the univariate IFR (i.e. the concavity of a univariate survival function) without recourse to any comparisons with any specific bivariate models.
3. Conditions for BIFR-LCC in terms of a Hessian matrix
In this section we assume that the survival function
 $\overline{F}$
is twice differentiable on a convex open set S. The implications of the log-concavity of
 $\overline{F}$
are then illuminated by the second-order partial derivatives of
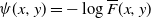 $ \psi (x,y)=-\log \overline{F}(x,y)$
.
We write
 \begin{align*}h_{1}(x,y)) &= -\dfrac{\partial }{\partial x}\ln \overline{F}(x,y)=-\dfrac{\partial }{\partial x}\ln \mathbb{P}(X>x \mid Y>y), \\[3pt]h_{2}(x,y) &= -\dfrac{\partial }{\partial y}\ln \overline{F}(x,y)=-\dfrac{\partial }{\partial y}\ln \mathbb{P}(Y>y \mid X>x), \\[3pt] h_{11}(x,y) &= \dfrac{\partial }{\partial x}h_{1}(x,y), \\[3pt] h_{22}(x,y) &= \dfrac{\partial }{\partial y}h_{2}(x,y), \\[3pt] h_{12}(x,y) &= h_{21}(x,y)=\dfrac{\partial }{\partial x}h_{2}(x,y)=\dfrac{\partial }{\partial y}h_{1}(x,y).\end{align*}
The vector
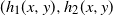 $(h_{1}(x,y),h_{2}(x,y)$
is called the hazard gradient of (X, Y). As noted earlier in Section 1,
 $h_{1}(x,y)$
is the univariate hazard rate (at x) of X given
 $Y>y$
. Likewise,
 $h_{2}(x,y)$
is the univariate hazard rate (at y) of Y given
 $X>x$
.
We shall say that the hazard gradient of (X, Y) satisfies the Johnson–Kotz conditions, abbreviated as JK conditions, if (i) for each fixed y,
 $h_{1}(x,y))$
is increasing in x, and (ii) for each fixed x,
 $h_{2}(x,y))$
is increasing in y. In terms of Johnson and Kotz [Reference Johnson and Kotz22], (X, Y) has vector (or gradient) BIFR if the JK conditions hold. As we shall see below, the notion does not fully take into account the possible interactions between ageing and dependence.
We first give a necessary and sufficient condition for
 $\overline{F}$
to be BIFR-LCC. Let H(x, y) denote the
 $2\times 2$
symmetric Hessian matrix of
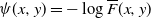 $\psi (x,y)=-\log \overline{F}(x,y)$
. Then the (i, j)th element of
 $H(x,y) $
is
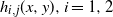 $h_{i,j}(x,y),i=1,2$
and H(x, y) has the determinant
 \begin{equation*}|H(x,y)|=h_{11}(x,y)h_{22}(x,y)-h_{12}^{2}(x,y).\end{equation*}
We now recall that a function with continuous partial derivatives on a convex open set S is convex if and only if its Hessian matrix is positive semidefinite on S. This fact, when stated in terms of the necessary and sufficient condition on H(x, y) to be positive semidefinite, gives the following proposition.
Proposition 3.1. A twice-differentiable survival function
 $\overline{F}$
on a convex open set S is BIFR-LCC if and only if, for all
 $(x,y)\in S$
,
 \begin{alignat*}{3}&\mathrm{(i)} &h_{11}(x,y &\geq 0, \\ &\mathrm{(ii)} &h_{22}(x,y) &\geq 0, \\ &\mathrm{(iii)}\quad &h_{11}(x,y)h_{22}(x,y)-h_{12}^{2}(x,y) &\geq 0.\end{alignat*}
This proposition makes it clear that there is much more to the notion of BIFR-LCC than the requirement that the univariate conditional distributions of X given
 $Y>y$
and Y given
 $X>x$
be IFR. The JK conditions are not sufficient for BIFR-LCC. A crucial role is played by the cross-derivative
 $h_{12}(x,y)$
because of requirement (ii) that
 $|H(x,y)\geq 0$
. The cross-derivatives
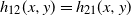 $h_{12}(x,y)=h_{21}(x,y)$
describe how the hazard rate function of X given
 $Y>y$
(hazard rate function of
 $Y$
given
 $X>x$
) behaves when y (x) varies. This can, of course, strongly depend on the nature of dependence between X and Y. For example, it can be easily seen that negative dependence such as
 $\mathrm{RR}_{2}$
leads to
 $h_{12}<0$
. It must be noted, however, that the requirement
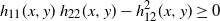 $h_{11}(x,y)\ h_{22}(x,y)-h_{12}^{2}(x,y)\geq 0$
for BIFR-LCC depends on the magnitude (i.e. the absolute value) of
 $h_{12}(x,y)$
, not on the sign of
 $h_{12}(x,y)$
. Nevertheless, it is of interest in its own right to see how the function
 $h_{12}(x,y)$
is related to other measures of association between X and Y. In particular, we would be interested in the relationship of
 $h_{12}(x,y)$
with Clayton’s association measure and Holland and Wang’s local dependence function.
For later use, we recall that a real-valued function g on
 $R^{2}$
is said to be totally positive of order two (
 $\mathrm{TP}_{2}$
) if
 \begin{equation*}g(x,y)g(u,v)\geq g(x,v)g(u,y),\quad x<u,\ y<v.\end{equation*}
The function g is called reversed rule of order two (
 $\mathrm{RR}_{2}$
) when the inequality is reversed. Further, if g is positive and twice differentiable, g is
 $\mathrm{TP}_{2}$
(
 $\mathrm{RR}_{2}$
) if and only if the cross-derivative
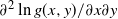 $\partial ^{2}\ln g(x,y)/\partial x\partial y$
is non-negative (non-positive); see Marshall and Olkin [Reference Marshall and Olkin27]. In terms of dependence between two random variables, the
 $\mathrm{TP}_{2}$
(
 $\mathrm{RR}_{2}$
) property of their joint probability density function is the strongest of all notions of positive (negative) dependence in the literature. We refer to Joe [Reference Joe21] for various dependence notions and their relationships.
In the context of bivariate survival models induced by frailties, Oakes [Reference Oakes30] studied the association measure:
 \begin{equation*}\theta (x,y)=\dfrac{\overline{F}\ \overline{F}_{(12)}}{\overline{F}_{(1)}\overline{F}_{(2)}},\end{equation*}
where
 $\overline{F}=\overline{F}(x,y)$
is the survival function,
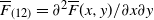 $\overline{F}_{(12)}=\partial ^{2}\overline{F}(x,y)/\partial x\partial y$
,
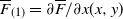 $\overline{F}_{(1)}={\partial\overline{F} }/{\partial x}(x,y)$
, and
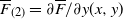 $\overline{F}_{(2)}={\partial\overline{F} }/{\partial y}(x,y)$
. This measure was derived by Clayton [Reference Clayton11].
It can be easily seen that
 \begin{equation*}\theta (x,y)=\dfrac{r(x \mid Y=y)}{h_{1}(x,y)}.\end{equation*}
The numerator is the hazard rate of X at time x given that
 $Y=y$
. The denominator is the hazard rate of X at time x given
 $Y>y$
.
It can now be verified that
 \begin{equation*} h_{12}(x,y) = \dfrac{\partial }{\partial y}h_{1}(x,y) =\dfrac{\overline{F}_{(2)}}{\overline{F}} [\!-h_{1}(x,y)+r(x \mid Y=y)]= \dfrac{\overline{F}_{(2)}}{\overline{F}}h_{1}(x,y)(\theta -1),\end{equation*}
suppressing the
 $\theta$
argument. Since
 $\overline{F}_{(2)}<0$
,
 $\theta >1$
is equivalent to
 $h_{12}(x,y)<0$
. Thus we have the following result.
Theorem 3.1.
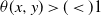 $\theta (x,y)>(<)1$
if and only if
 $h_{1}(x,y)$
is decreasing (increasing) in y.
Remark 3.1. It can also be verified that
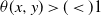 $\theta (x,y)>(<)1$
if and only if
 $\overline{F}(x,y)$
is
 $\mathrm{TP}_{2}$
(
 $\mathrm{RR}_{2}$
).
Local dependence function. Let (X, Y) be a two-dimensional random vector with probability density function f(x, y). In defining the local dependence function, we assume that the support K of the joint density f(x, y) is a Cartesian product set. When the set K is not a Cartesianproduct set, its shape can introduce dependence between X and Y, which is logically different from local dependence. Holland and Wang [Reference Holland and Wang20] defined the local dependence function as
 \begin{equation*}\gamma _{f}(x,y)=\dfrac{\partial ^{2}}{\partial x\partial y}\ln f(x,y),\end{equation*}
assuming that the partial derivatives exist. It can be verified that
 $\gamma_{f}(x,y)$
can be written as
 \begin{equation*}\gamma _{f}(x,y)=\dfrac{\partial ^{2}}{\partial x\partial y}\ln \lambda(x,y)-h_{12}(x,y),\end{equation*}
where
 \begin{equation*}\lambda (x,y)=\dfrac{f(x,y)}{\overline{F}(x,y)}=h_{1}(x,y)h_{2}(x,y)-h_{12}(x,y).\end{equation*}
It is clear from the definition that
 $\gamma _{f}(x,y)$
can be obtained by knowing any one of the conditional densities. The local dependence function and the marginals determine the bivariate density. For a proof, we refer to Wang [Reference Wang39]. See also Jones [Reference Jones23].
Theorem 3.2. Let
 $ f(x,y)$
be the PDF of
 $ (X,Y)$
, let
 $\overline{F}(x,y)$
be the survival function, and let K, the support of
 $f(x,y)$
, be a Cartesian product. Then
-
(1)
 $f(x, y)$
is
$\mathrm{TP}_{2}$
$(\mathrm{RR}_{2})$
if and only if
$\gamma _{f}(x,y)\geq (\leq)0$
,
-
(2)
$f(x, y)$
is
$\mathrm{TP}_{2}$
$(\mathrm{RR}_{2})\Rightarrow \overline{F}(x,y)$
is
$\mathrm{TP}_{2}$
$(\mathrm{RR}_{2})$
.


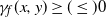


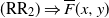


4. Illustrative examples
We now present specific examples of bivariate survival functions to illustrate and elucidate the concepts discussed and the points made in the preceding sections.
Example 4.1. (Bassan et al. [8].) The survival function is given by
 \begin{equation*}\overline{F}(x,y)=\exp \big\{1-\exp \big(x^{2}+y^{2}\big)\big\},\quad x,y\geq 0,\ \lambda >0.\end{equation*}
In this case
 \begin{align*}h_{1}(x,y) &= 2x{\mathrm{e}}^{x^{2}+y^{2}}, \\[3pt] h_{2}(x,y) &= 2y{\mathrm{e}}^{x^{2}+y^{2}}.\end{align*}
It can be verified that
 \begin{align*}h_{11}(x,y) &= 2{\mathrm{e}}^{x^{2}+y^{2}}\big(1+2x^{2}\big)>0, \\[3pt]
h_{22}(x,y) &= 2{\mathrm{e}}^{x^{2}+y^{2}}\big(1+2y^{2}\big)>0, \\[3pt]
h_{12}(x,y) &= 4xy{\mathrm{e}}^{x^{2}+y^{2}}>0.\end{align*}
These give
 \begin{equation*} h_{11}(x,y)h_{22}(x,y)-[h_{12}(x,y)]^{2}= 4{\mathrm{e}}^{2\big(x^{2}+y^{2}\big)}\big[1+2x^{2}+2y^{2}\big]>0.\end{equation*}
The log-concavity conditions of the survival function are satisfied and
 $(X,Y)$
is BIFR-LCC. Therefore the JK conditions are also satisfied.
In addition,
 $h_{1}(x,y)$
is increasing in y. This means that the survival function is
 $\mathrm{RR}_{2}$
. Further, according to Bassan et al. [8], (X, Y) is s-BIFR.
Example 4.2. ( Arias-Nicolas et al. [Reference Arias-Nicolas, Belzunce, Nunez-Barrera and Suárez-Llorens1].) Consider the survival function
 \begin{equation*}\overline{F}(x,y)=({\mathrm{e}}^{x}+{\mathrm{e}}^{y}-1)^{-\lambda },\quad x,y\geq 0,\ \lambda >0.\end{equation*}
In this case
 \begin{align*}h_{1}(x,y) &= \dfrac{\lambda {\mathrm{e}}^{x}}{{\mathrm{e}}^{x}+{\mathrm{e}}^{y}-1}, \\[3pt]h_{2}(x,y) &= \dfrac{\lambda {\mathrm{e}}^{y}}{{\mathrm{e}}^{x}+{\mathrm{e}}^{y}-1}.\end{align*}
It can be verified that
 \begin{align*}h_{11}(x,y) &= \dfrac{\lambda ({\mathrm{e}}^{x+y}-{\mathrm{e}}^{x})}{({\mathrm{e}}^{x}+{\mathrm{e}}^{y}-1)^{2}}, \\[3pt] h_{22}(x,y) &= \dfrac{\lambda ({\mathrm{e}}^{x+y}-{\mathrm{e}}^{y})}{({\mathrm{e}}^{x}+{\mathrm{e}}^{y}-1)^{2}}, \\[3pt] h_{12}(x,y) &= \dfrac{-\lambda {\mathrm{e}}^{x+y}}{({\mathrm{e}}^{x}+{\mathrm{e}}^{y}-1)^{2}}.\end{align*}
These give
 \begin{equation*} h_{11}(x,y)h_{22}(x,y)-[h_{12}(x,y)]^{2}= \dfrac{\lambda ^{2}{\mathrm{e}}^{x+y}}{({\mathrm{e}}^{x}+{\mathrm{e}}^{y}-1)^{4}}[1-({\mathrm{e}}^{x}+{\mathrm{e}}^{y})]<0.\end{equation*}
The log-concavity conditions of the survival function are not satisfied, and (X, Y) is not BIFR-LCC. Note that in this example (i) the JK conditions are satisfied, (ii)
 $\overline{F}(x,y)$
is
 $\mathrm{TP}_{2}$
, (iii)
 $\overline{F}(x,y)$
is Schur-concave, and (iv)
 $\overline{F}(x,y)$
is not log-concave.
Example 4.3. (Farlie–Gumbel–Morgenstern family with uniform marginals.) The survival function is given by
 \begin{equation*}\overline{F}(u,v)=(1-u)(1-v)\{1+\alpha uv\},\quad u,v\in \lbrack 0,1],\ |\alpha |<1.\end{equation*}
In this case
 \begin{align*}h_{1}(u,v) &= \dfrac{1}{1-u}-\dfrac{\alpha v}{1+\alpha uv}, \\[3pt] h_{2}(u,v) &= \dfrac{1}{1-v}-\dfrac{\alpha u}{1+\alpha uv}. \notag\end{align*}
These give
 \begin{align*}h_{11}(u,v) &= \dfrac{1}{(1-u)^{2}}+\dfrac{\alpha ^{2}v^{2}}{(1+\alpha uv)^{2}}>0, \\[3pt] h_{22}(u,v) &= \dfrac{1}{(1-v)^{2}}+\dfrac{\alpha ^{2}u^{2}}{(1+\alpha uv)^{2}}>0, \\[3pt] h_{12}(u,v) &= \dfrac{-\alpha }{(1+\alpha uv)^{2}}.\end{align*}
Thus
 \begin{align*}& h_{11}(u,v)h_{22}(u,v)-[h_{12}(u,v)]^{2} \\[3pt] &\quad = \biggl\{\dfrac{1}{(1-u)^{2}}+\dfrac{\alpha ^{2}v^{2}}{(1+\alpha uv)^{2}}\biggr\}\biggl\{\dfrac{1}{(1-v)^{2}}+\dfrac{\alpha ^{2}u^{2}}{(1+\alpha uv)^{2}}\biggr\} -\biggl\{\dfrac{-\alpha }{(1+\alpha uv)^{2}}\biggr\}^{2} \\[3pt] &\quad > \biggl\{1+\dfrac{\alpha ^{2}v^{2}}{(1+\alpha uv)^{2}}\biggr\}\biggl\{1+\dfrac{\alpha ^{2}u^{2}}{(1+\alpha uv)^{2}}\biggr\}-\dfrac{\alpha ^{2}}{(1+\alpha uv)^{4}} \\[3pt] &\quad = 1+\dfrac{\alpha ^{2}(u^{2}+v^{2})}{(1+\alpha uv)^{2}}+\dfrac{\alpha^{4}u^{2}v^{2}}{(1+\alpha uv)^{4}}-\dfrac{\alpha ^{2}}{(1+\alpha uv)^{4}} \\[3pt] &\quad > 1+\dfrac{\alpha ^{2}(u^{2}+v^{2})}{(1+\alpha uv)^{2}}+\dfrac{\alpha^{4}u^{2}v^{2}}{(1+\alpha uv)^{4}}-1,\quad \text{if }\alpha >0, \\[3pt] &\quad > 0.\end{align*}
The log-concavity conditions of the survival functions are satisfied and (U, V) is BIFR-LCC. It can be verified that the JK conditions are satisfied for all
 $\alpha$
(negative or positive). Also, the survival function is
 $\mathrm{TP}_{2}$
for
 $\alpha >0$
and
 $\mathrm{RR}_{2}$
for
 $\alpha <0$
.
Example 4.4. (Bivariate Pareto distribution.) Consider the density
 \begin{equation*}f(x,y)=\dfrac{c}{(\lambda _{0}+\lambda _{1}x+\lambda _{2}y+\lambda_{3}xy)^{\alpha +1}},\quad x>0,\ y>0.\end{equation*}
The restrictions on the parameters are as follows.
-
(i) If
$\alpha \in (0,1)$
,
$\lambda _{1}>0$
,
$\lambda _{2}>0$
,
$\lambda _{3}>0$
, and
$\lambda _{0}\geq 0$
. -
(ii) If
$\alpha \in (1,\infty )$
,
$\lambda _{0}>0$
,
$\lambda _{1}>0$
,
$\lambda _{2}>0$
, and
$\lambda _{3}\geq 0$
. -
(iii) If
$\alpha =1$
,
$\lambda _{i}>0$
,
$i=0,1,2,3$
.


It was shown in Gupta [Reference Gupta16] that
 $h_{1}(x,y)$
is decreasing in x and
 $h_{2}(x,y)$
is decreasing in y. This means that the Hessian matrix is not positive semidefinite. Hence (X, Y) is not BIFR-LCC.
Example 4.5. (Joint survival function of the smallest and largest order statistics.) Let
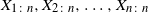 $X_{1\colon n},X_{2\colon n},\ldots, X_{n\colon n}$
be the order statistics of a random sample from a log-concave probability density function f(x). We are interested in the log-concavity of the joint survival function of
 $(X_{1\colon n},X_{n\colon n})$
.
The joint probability density function of
 $(X_{1\colon n},X_{n\colon n})$
is given by
 \begin{equation*}f_{X_{1\colon n},X_{n\colon n}}(x,y)=n(n-1)\biggl\{\int_{x}^{y}f((t)\,{\mathrm{d}} t\biggr\}^{n}f(x)f(y)I_{A}(x,y),\end{equation*}
where A is the set
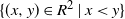 $\{(x,y)\in R^{2} \mid x<y\}$
and
 $I_{A}$
is its indicator function.
Since f(x) is log-concave,
 $\int_{x}^{y}f((t)\,{\mathrm{d}} t$
is log-concave; see Prekopa [Reference Prekopa32]. Also,
 $I_{A}(x,y)$
is log-concave. This implies that the joint density
 $ f_{X_{1\colon n},X_{n\colon n}}(x,y)$
is log-concave. Hence the survival function of
 $(X_{1\colon n},X_{n\colon n})$
is log-concave. In particular, the joint survival function of
 $\min(X_{1},X_{2})$
and
 $\max (X_{1},X_{2})$
is log-concave.
Example 4.6. (Freund’s bivariate exponential distribution [Reference Freund15].) The joint PDF is given by
 \begin{align*}f(x,y) &= \alpha \beta ^{\prime }\exp \{-\beta ^{\prime }y-(\alpha +\beta-\beta ^{\prime })x\},\quad 0\leq x<y, \\[3pt] &= \alpha ^{\prime }\beta \exp \{-\alpha ^{\prime }x-(\alpha +\beta -\alpha^{\prime })y,\quad 0\leq y<x,\end{align*}
for
 $\alpha ,\beta ,\alpha ^{\prime },\beta ^{\prime } > 0$
. For the survival function we refer the reader to Johnson and Kotz [Reference Johnson and Kotz22].
Under certain conditions on the parameters, the first hazard function is of the form
 \begin{align*}h_{1}(x,y) &= \dfrac{c_{1}}{c_{2}-c_{3}{\mathrm{e}}^{c_{4}x}},\quad x<y, \\[3pt] &= \dfrac{c_{5}{\mathrm{e}}^{c_{6}x}}{c_{8}{\mathrm{e}}^{c_{6}x_{1}}-c_{9}},\quad x>y,\end{align*}
where all constants are positive.
This gives
 \begin{align*}h_{11}(x,y) &= \dfrac{c_{3}c_{4}{\mathrm{e}}^{c_{4}x}}{(c_{2}-c_{3}{\mathrm{e}}^{c_{4}x})^{2}}>0,\quad x<y,\\[3pt] &= \dfrac{c_{6}{\mathrm{e}}^{c_{6}x}(c_{7}c_{8}-c_{5}c_{9})}{(c_{8}{\mathrm{e}}^{c_{6}x}-c_{9})^{2}}>0,\quad x>y,\end{align*}
where, as shown by Johnson and Kotz [Reference Johnson and Kotz22],
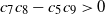 $c_{7}c_{8}-c_{5}c_{9}>0$
. Similarly
 $h_{22}(x,y)>0$
. Also,
 $h_{12}(x,y)=0$
. This gives
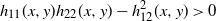 $h_{11}(x,y)h_{22}(x,y)-h_{12}^{2}(x,y)>0$
and (X, Y) is BIFR-LCC.
Example 4.7. (Bivariate normal distribution.) In this case the joint density function has been shown to be log-concave (see Gupta and Balakrishnan [Reference Gupta and Balakrishnan18] and Prekopa [Reference Prekopa32]) and hence the joint survival function is log-concave.
5. Some conclusions and comments
We have proposed and studied the log-concavity (log-convexity) of the joint survival function
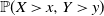 $\mathbb{P}(X>x,Y>y)$
as a model for ‘bivariate increasing (decreasing) failure rate’. Two immediately obvious advantages of the log-concavity (log-convexity) approach are (i) it is applicable to all random vectors without restriction to exchangeable random variables, and (ii) it guarantees that all lower-dimensional marginal distributions are IFR (DFR) as well. Both of these facts are often crucial in modeling real-life systems.
The class of BIFR-LCC survival functions is not small by any means. For example, it contains all distributions that have log-concave densities. We compared and contrasted our BIFR-LCC approach with other well-known models of BIFR. We gave a necessary and sufficient condition for a survival function to be BIFR-LCC. The condition is sensitive to the impact of dependence between X and Y on their joint ageing. We pointed out connections with Clayton’s measure of association and Holland and Wang’s local dependence function. Finally, we presented a number of examples that illustrate BIFR-LCC for positive and negative dependence between X and Y. The contributions of this paper should be of particular interest in bivariate survival analysis.
Acknowledgements
The authors are thankful to the referees for their useful suggestions.
Funding information
There are no funding bodies to thank relating to the creation of this article.
Competing interests
There were no competing interests to declare which arose during the preparation or publication process of this article.


