INTRODUCTION
In spite of our good intentions and explicit egalitarian convictions, we habitually disfavor the underprivileged. Typically, we hire, promote, appoint, and fund white, able-bodied, straight, cisgendered men at the expense of persons of other ethnicities, persons with disabilities, LGBTQ-persons and women. The rapidly growing literature on implicit bias – unconscious, automatic tendencies to associate negative traits with members of particular social groups – points towards explanations of this dissonance, although rarely towards generalizable solutions.
In a recent paper, Jennifer Saul (Reference Saul2013) draws attention to the alarming epistemological problems that implicit bias carries with it; since our judgments about each other are likely influenced by implicit bias, we have good reason to doubt their veracity. Problems arise not only on the individual level, but also on the group level. How can we know, for instance, that the way in which we have ranked a group of people for a certain position, reflects their actual competence (or the best estimate of their competence given the evidence)? As is clear from the literature (see e.g. Hardin and Banaji Reference Hardin, Banaji and Shafir2013, for an overview) implicit biases – to paraphrase a description of Descartes' evil demon – are as ‘deceitful as [they are] powerful, [and have] directed [their] entire effort to misleading [us]’ (Descartes [1641] Reference Descartes and Smith1952).
The knee-jerk response to the discovery of implicit bias, is to try to remove it by making people less biased. This response is also popular in the literature on implicit bias, which is somewhat surprising, considering that the concrete proposals of how to do this (e.g. Blair et al. Reference Blair, Ma and Lenton2001; Dasgupta and Greenwald Reference Dasgupta and Greenwald2001; Henry and Hardin Reference Henry and Hardin2006; Turner et al. Reference Turner, Hewstone and Voci2007; Stewart and Payne Reference Stewart and Payne2008) do not seem satisfactory.
In this paper we explore a novel alternative; the idea that at least a special case of the epistemological problem – the problem as it manifests itself in ranking situations – can be dealt with by correcting biased behavior after the fact. In particular, we investigate methods that modify implicitly biased rankings (of for instance, candidates for a position, promotion or grant), in an attempt to identify those methods that reliably improves veracity (and the conditions under which they do this). Our approach, then, consists in improving the veracity of rankings by changing these directly, rather than changing the people that generate them.Footnote 1
The paper is laid out as follows: Section 1 summarizes the literature on implicit bias that pertains to recruitment and ranking, and Section 2 summarizes the literature that pertains to how to make people less biased. Section 3 distinguishes solutions to the epistemological problem from solutions to related ethical problems, and then investigates how reliably three different methods can improve the veracity of biased rankings. It is concluded that the last of the methods reliably de-biases rankings (given a few assumptions), and thus solves the special case of the epistemological problem that we started out with.
1. IMPLICIT BIAS AND RECRUITMENT
The contrast between people's explicit attitudes and their actions has long been the subject of psychological research. Some of the earlier studies concerned explicit bias coupled with unbiased behavior, but modern day research on the topic – which has intensified during the last couple of decades – has converged on an alternative focus.Footnote 2 The now hundreds of available studies typically investigate the reverse form of incongruence; cases where explicitly egalitarian persons exhibit racist and sexist behavior (see Hardin and Banaji Reference Hardin, Banaji and Shafir2013, for a good overview).
Although implicit bias has been discovered in the most varied forms of social interaction, this section will highlight examples of particular relevance for recruitment and ranking. The most striking results here are from the so-called CV-studies (Steinpreis et al. Reference Steinpreis, Anders and Ritzke1999; Bertrand and Mullainathan Reference Bertrand and Mullainathan2004; Correll et al. Reference Correll, Benard and Paik2007; Moss-Racusin et al. Reference Moss-Racusin, Dovidio, Brescoll, Graham and Handelsman2012). These studies are carried out by sending out fake CVs as answers to job ads. Typically, the same CV is sent twice to each employer, with a single variation: the name on top of it. The name indicates a specific social group-affiliation such as male/female or black/white. Another variation is to add or withdraw some property from one of two otherwise equivalent CVs, for example to add “mother of a two-year-old child” to one of the CVs but to mention nothing about children on the other. The effect of this is that the quality of the same CV is perceived very differently depending on these variations, and that we can see that people belonging to some social groups are more likely to receive call-backs, be rewarded higher salaries and to be regarded likelier for promotion than others. Generally, typically white names are, for example, preferred to typically black names (Bertrand and Mullainathan Reference Bertrand and Mullainathan2004), male names are typically preferred to female (Steinpreis et al. Reference Steinpreis, Anders and Ritzke1999; Moss-Racusin et al. Reference Moss-Racusin, Dovidio, Brescoll, Graham and Handelsman2012), and women without children are preferred to women who are mothers (Correll et al. Reference Correll, Benard and Paik2007).
These results are in stark contrast to the explicit ambition of many employers. In the studies performed by Bertrand and Mullainathan (Reference Bertrand and Mullainathan2004), even companies claiming to be Equal Opportunities Employers discriminated to a high degree. Other studies have demonstrated that government agencies – which are supposed to award research grants on scientific merit alone – assign significantly lower competence scores to women than to men for comparable scientific productivity (Wennerås and Wold Reference Wennerås and Wold1997) and award black applicants research funding to a significantly lower degree than to comparable white applicants (Ginther et al. Reference Ginther, Schaffer, Schnell, Masimore, Liu, Haak and Kington2011).
These results are reinforced by a contrast found by Rooth (Reference Rooth2010) who measured call-back rates for people with Muslim-sounding and Swedish-sounding names in Sweden. Rooth found a strong correlation between negative implicit attitudes and the low call-back rate for people with Muslim-sounding names, but merely a weak correlation between the participant's explicit and implicit attitudes.Footnote 3
Findings like these have epistemological import. A recruiter that exhibits bias in the way described above is largely unaware of her bias, and thus has no information concerning how her bias influences her. It is hence clear that she is typically not justified (at least not in an externalist sense) in believing that her evaluation accurately reflects the competence of the individuals she is evaluating, and she cannot be said to know which of two persons are more qualified (even though she might feel that she does).
2. MAKING PEOPLE LESS BIASED
The natural reaction to the precarious epistemological situation of recruiters is to try to reduce their implicit bias, perhaps by convincing them to change. However, as a recent review of the literature reveals, even if a personal commitment to change exists, this is not nearly enough. In the words of Hardin and Banaji:
[I]t is nearly impossible to consciously correct for effects of implicit prejudice … To do so, one must be in the unlikely circumstance of having at once (a) knowledge that implicit prejudice is operating, (b) both the motivation and cognitive capacity to control it, and perhaps most unlikely of all, (c) precise knowledge of the magnitude and direction of the correction needed (e.g. Bargh Reference Bargh, Chaiken and Trope1999; Fazio and Towles-Schwen Reference Fazio, Towles-Schwen, Chaiken and Trope1999). (Hardin and Banaji Reference Hardin, Banaji and Shafir2013)
Just providing the information that a person is likely to be biased is thus not enough. Moreover, teaching people to apply facts about their biases to themselves in the right situations is extremely difficult (Kenyon Reference Kenyon2014). One obstacle here is the fact that people are susceptible to the bias blind spot (Pronin et al. Reference Pronin, Lin and Ross2002). That is, they tend to notice biased behavior in others, but to fail to do so in themselves. To manifest a blind spot does not require the belief that one is immune from bias, but merely the belief that a specific occasion is one where one is not biased (Kenyon Reference Kenyon2014).
To overcome these problems, various forms of interventions aimed at removing implicit bias have been proposed.
First, it has been suggested that friendly intergroup contact can decrease bias (Henry and Hardin Reference Henry and Hardin2006; Turner et al. Reference Turner, Hewstone and Voci2007). However, it has also been shown that this can increase bias (Gross and Hardin Reference Gross and Hardin2007), and that the kind of bias most effectively reduced is the bias towards high-status groups (e.g. black people's biases towards white people) (Henry and Hardin Reference Henry and Hardin2006). Other areas of the literature also cast doubt on how successfully friendly intergroup contact can remove bias, since implicit bias is often exhibited towards members of one's own group, where it is likely that friendly contact is common. For instance, women generally do not consider other women more employable than men do, and rate women as bad as men when it comes to promotion, proposed salaries and so forth (Steinpreis et al. Reference Steinpreis, Anders and Ritzke1999; Correll et al. Reference Correll, Benard and Paik2007; Moss-Racusin et al. Reference Moss-Racusin, Dovidio, Brescoll, Graham and Handelsman2012). Finally, from the perspective of recruitment, it seems plausible that not every kind of friendly intergroup contact is sufficient for a decrease in the relevant kind of implicit bias; in order for an employer to decrease his or her bias towards a certain social group he or she needs workplace-related friendly contact with members of that group. Such contact is, unfortunately, unlikely to occur since the employer's bias might prevent her from hiring members of the relevant group in the first place.
Second, it has been suggested that bias can be reduced by deliberately exposing people to counter-stereotypical examples. Studies by Dasgupta and Greenwald (Reference Dasgupta and Greenwald2001) for example, revealed a weakening in people's implicit preference for white people lasting at least 24 hours, after being presented with examples of admired black individuals and disliked white individuals. Similar results were presented by Blair et al. (Reference Blair, Ma and Lenton2001) who demonstrated that participants produced weaker implicit stereotypes after engaging in counter-stereotypical mental imagery, compared with participants who had engaged in neutral or stereotypical mental imagery.
Third, it has been suggested that implicit bias can be removed by going through de-biasing-training. An example of this is the strategy of implementation intentions. That is, to plan for a certain response on specific stimuli, for example to think ‘safe!’ if he or she encounters a black person in a videogame (Mendoza et al. Reference Mendoza, Gollwitzer and Amodio2010). Another type of de-biasing training consists in pressing a button that says ‘no’ when exposed to a pair of concepts that express a stereotype on a screen (such as a black face paired with the word athletic), and a button that says ‘yes’ when exposed to a pair of concepts which contradicts a stereotype (cf. Dasgupta and Greenwald Reference Dasgupta and Greenwald2001; Dasgupta and Asgari Reference Dasgupta and Asgari2004; Kawakami et al. Reference Kawakami, Phills, Steele and Dovidio2007; Stewart and Payne Reference Stewart and Payne2008; Phills et al. Reference Phills, Kawakami, Tabi, Nadolny and Inzlicht2011).
The problems with the last two suggestions are similar. First, it is not clear exactly how lasting the effects of the exposure or training is. The biases we are interested in are not available through introspection, and their influence on an agent might shift over time. That I successfully and deliberately have de-biased on one occasion and therefore declare myself bias-free does, for a start, not provide any evidence that I will not act or judge in a biased way in the future, and moreover, by pronouncing myself de-biased, I might set the stage for subsequent biased judgments, which will be made under the illusion of freedom from biases (Kenyon Reference Kenyon2014). Second, it is unclear that people are actually debiased in any interesting sense, rather than placed in situations where other factors are introduced (thinking of successful people belonging to a minority, or introducing an artificial correlation between group membership and a positively associated label) and the influence of these factors to some extent cancel out the influence of the bias. But this does not constitute genuine improvement, it hides the fact that people are still biased from a particular measure of implicit bias.
The overall state of this literature seems to point towards the conclusion that once biases are in place, they are very difficult to get rid off. Through socialization, we internalize certain beliefs about different social groups, and the automatic activation of certain biases and stereotypes is the result of this socialization process (Devine Reference Devine1989). These associations will therefore appear whether we like it or not when exposed to someone from a social group category we recognize, and it will, despite our explicit beliefs, cause us to judge or act in specific ways (Szabó Gendler Reference Szabó Gendler2011). Moreover, if the associations that underlie implicit bias are parts of our general conceptual system, they might be subject to the same kind of belief perseverance effects that other conceptual connections are subject to (cf. Anderson Reference Anderson, Baumeister and Vohs2007); to paraphrase Lee and Anderson's (Reference Lee, Anderson, Kahneman, Slovic and Tversky1982) classical paper: implicit sexist and racist beliefs might survive the total destruction of their original evidential bases. On the dim view that emerges from these considerations, nothing less than considerable social change towards widespread equality is likely to remove implicit bias (Pettigrew and Tropp Reference Pettigrew and Tropp2006). However, there is a troubling Catch-22 here; existing biases are likely to slow down or even halt the social change that can remove them.
3. MAKING RANKINGS LESS BIASED
One might at this point take some comfort in the possibility of preventing implicit bias from exerting an influence on recruitment and ranking by concealing which social groups applicants belong to. However, although anonymization has proven its worth in many situations (see Goldin and Rouse Reference Goldin and Rouse2000, for a very good example), many real-life situations of ranking and recruitment cannot be anonymized. With respect to certain jobs, it is hard to accurately evaluate the competence of someone while hiding the social groups to which they belong (e.g. in order to hire a salesperson you need to meet him or her face-to-face, or at least talk with him or her on the phone). In other situations, the identities of applicants are difficult to hide from evaluators (e.g. the identities of the ambitious undergraduates at an academic department who apply for PhD-positions are typically known by everyone involved). It is here that the epistemological problem is most pressing – how are we in these situations to accurately rank a group of candidates in terms of their competence when we are under the influence of implicit bias?Footnote 4
Before tackling the problem it should be noted that the epistemological question we are concerned with is different from the ethical questions raised by the existence of implicit bias. To see this, consider the use of (e.g. gender) quotas. Quotas are typically used as a fast-track way to improve representational or influence-related properties of members of underprivileged groups (see e.g. Tripp and Kang Reference Tripp and Kang2008), but the way in which quotas are typically enforced is by overriding perceived differences in qualifications between members of underprivileged and privileged groups. Although it is likely that this form of procedure has long-term positive political effects, it is obviously not a procedure that gives us reason to believe that the ranking that results from applying quotas is more accurate than the unmodified list (although it might be better for other reasons). So even if quotas solve ethical problems, they do not solve the epistemological problem.
However, by considering quotas, and their effects on rankings, one starts to wonder whether there are more sophisticated methods for changing rankings, that are such that they reliably improve veracity. These methods would be drastically different to the methods reviewed in the previous section; they would aim to change the rankings that people generate, rather than changing the people themselves. In what follows we will discuss three candidate methods, and argue that although the first two are defective, the third reliably improves the veracity of implicitly biased rankings (under certain conditions) and to this extent help us solve the epistemological problem that we are concerned with. The first of these methods apply to ordinal-scale rankings without recourse to past information about the ranking behavior of the evaluator. The second and third methods apply to ratio-scale rankings and makes use of the information contained in the evaluator's history of evaluations.
3.1 Set-up
Assume that E, an evaluator in charge of deciding who will get a certain position has produced the following ranking r 0 (the target ranking), which in E’s view orders the candidates from the most to the least qualified.

Assume (here and throughout the text) that whatever property p that E is supposed to base his or her ranking on, is similarly distributed in the populations corresponding to all relevant social groups, in particular, that in each of these populations, the property is distributed in the same kind of distribution (e.g. in a normal distribution), around the same mean and with the same variance. Call this the equal qualifications assumption. For instance, let us assume that the six people above are all legal secretaries that apply for a single paralegal position. p might then correspond to knowledge of legal processes and court procedures, a central qualification for this kind of promotion. r 0 thus corresponds to E’s (possibly biased) ranking of the candidates in terms of how much they know about legal processes and court procedures. Correspondingly, the equal qualifications assumption then amounts to saying that this kind of knowledge is distributed in the same way, in the population, among all relevant social groups (i.e. among men and women if we are only interested in these groups). This is not to say, implausibly, that all members of all relevant groups have this knowledge to the same degree. It is the contrastive claim that this knowledge is distributed among the men in the same way (in the same kind of distribution, around the same mean, and with the same variance) as it is distributed among the women.
Now assume that we are in a position to change the above ranking if we want to, but that we are only interested in doing so if we have reason to believe that the new ranking better reflects the actual qualifications of the group members.
The literature on implicit bias, gives us a (non-conclusive) reason to believe that despite E’s best efforts, r 0 might be less than perfectly accurate. If we focus on the difference between the ranked men and the ranked women, we can note that the men are ranked higher than the women. The men occupy places 1, 2, and 4 in the ranking, while the women occupy places 3, 5, and 6. This is consistent with an implicit bias against women.Footnote 5 We might thus ask ourselves, is there anything we can do that is likely to improve the veracity of r 0?
3.2 Method 1: Solipsistic Ordinal-Scale Update
Let us first – for illustrative purposes – consider a method that will clearly not do. This method assumes naively that the information we need in order to improve a ranking like r 0 is contained in the equal qualifications assumption together with the information contained in the relative ranking of individuals within the social groups that are represented in the target ranking. According to this method, individual rankings such as r 0 should be changed so that the ordinal positions are the same on average across social groups, all the while the relative positions of members within each social group are preserved. The idea here is to produce an unbiased sample by equalizing all social groups in the sample, while retaining as much of the unbiased information as possible from the target ranking (i.e. the ranking of individuals within each social group).
To make this more precise, let R be the set of all rankings r 0, …, r n that contains exactly the same members as the target ranking. Assign to each ranking r i an index x i by first calculating, for each relevant social group represented in r i , the sum of the ordinal numbers of the members of that group, and let x i be the absolute difference between these sums (or the average absolute difference if there are more than two relevant social groups represented in the ranking). Let R* be the subset of R that contains the rankings that are tied for having the lowest indices (i.e. the most egalitarian rankings possible). Finally, let r* be the member of R* which is the most similar to the target ranking with respect to the proportions of the sum of ordinal numbers assigned to members within each social group (i.e. the member in R* which preserves the most information from the target ranking).Footnote 6
Solipsistic ordinal-scale update (SOU)
Substituting r* for a ranking r will improve veracity (as long as r* is different from r).
To illustrate this method, consider the following three lists, and assume for the sake of illustration that we are only interested in two social groups, men and women.

All three of these are members of R* with respect to r 0, since the difference between the sums of the ordinal numbers for men and the sums of the ordinal positions for women in each of these three lists is as low as possible (=1). However, the three lists differ in how similar they are to r 0 with respect to the proportions of the sum of ordinal numbers assigned to members within each social group.Footnote 7

As can easily be seen, r 1 is more similar to r 0 with respect to the proportions of the sum of ordinal numbers assigned to members within each social group than the other two rankings.Footnote 8 Given that no other member of R* is as similar to r 0 as r 1 is, the method predicts that the veracity of r 1 is higher than that of r 0 (since r 0 ≠ r 1).
Unfortunately, there is in fact no guarantee that the veracity of r 1 will be higher than that of r 0. There are at least five problems with SOU.
The looks-biased, is-biased problem. Even though a certain property is evenly distributed in the populations of certain social groups, there is no guarantee that this is the case in any given sample from that population. Random sampling of pairs of samples from a population can produce samples that differ wildly depending on the size of the samples and the distribution of the population. To see this, assume that you role two 20-sided dice. Just because one rolls higher than the other does not mean that either die or both dice are loaded. So, even though r 0 looks biased, it might actually not be, and if it is not, r 1 is a distortion of r 0 rather than an improvement.
The ordinality-is-not-enough-problem. The method takes ordinal numbers as input, yet for the purposes of selecting which set in R* is most similar to the target ranking, it treats the size of the difference between pairs of ordinal values as significant. This cannot be assumed; just because Felicia's ordinal value is half of that of Latifah's does not mean that Felicia is twice as qualified as Latifah (e.g. that she has twice as much knowledge of legal processes and court procedures), and that she should receive a new ordinal value reflecting this. There is simply not enough information in the target ranking to meaningfully redistribute points in the way described above.
The zero-sum-problem. The new ordinal number of a member of a certain social group (i.e. that prescribed by r*) is determined by the relative rankings of members of that group. This amounts to a zero-sum game within each group where members belonging to a certain social group benefit from being ranked together with other members with poor initial ranking. In fact, the person that within his or her social group has co-members that rank proportionally worse than the worst members in the other group(s) will be ranked first in the new list. The original absolute position in the ranking will not play a role in producing the new ranking. This is clearly an unwanted consequence.
The equisize-problem. The method can, at best, only be reasonably applied to equisized groups. If there were, for instance, fewer women than men in the target ranking, they would each get higher values than they would have got, had their group been bigger (since the only rankings that would be selected for inclusion in R* are those were the ordinal numbers assigned to women are large enough to compensate for the fact that there are fewer women). This is also an unwanted consequence; the number of other members belonging to one's own social group should not determine one's ranking in this way.
The intersectionality-problem. Latifah has a black-sounding name. This could mean that the evaluator has allowed multiple biases to influence her decision. But there is nothing in the method that can handle this. This is a very difficult problem, since the bias that affects black women is no simple function of the bias that influence black people on the one hand and the bias that influence women on the other.Footnote 9
Although SOU is clearly defective, it helped us identify five problems that any reasonable de-biasing method must avoid. We now move on to a method that does so.
3.3 Method 2: Multiplicative, Informed Ratio-Scale Update
To avoid the ordinality-is-not-enough-problem, we will henceforth assume that E – the evaluator – assigns competence scores to the candidates, and that these scores can be meaningfully manipulated via addition, subtraction, multiplication and division (i.e. that there is an underlying ratio-scale). Many ranking situations, both in business, government and academia rely on scores like these. For instance, the U.S. Department of State recommends using detailed rating scales to help quantify subjective data when conducting structured interviews, and the Swedish Research Council ask evaluators to rate the merits of applicants for research grants using such scales.Footnote 10
It is thus now assumed that E produces lists such as the following.

We will also assume that we have access to E’s history of evaluations, i.e. a set H of rankings h 1, …, h n previously produced by E (when E has ranked other people for the same purpose as E is now producing the target ranking). Government hiring managers, or anyone else who is working professionally with hiring using something like competence scores, will produce large histories of evaluations. The same is true e.g. for the evaluators working for the Swedish research council, or institutions with similar rating procedures, who review a large number of research proposals each year, and typically serve as evaluators for several years.
A simple history of evaluations might look something like this:

In order to avoid the looks-biased, is-biased-problem the method assumes that a statistically significant difference have been found between the mean competence scores assigned to members of the represented social groups (across the rankings in H). To calculate this, the mean competence score
 $\bar X_{Si}^H $
across the rankings in H is calculated for each relevant social group S
i
represented in H, and these means are compared with a statistical test (e.g. a t-test). What a significant test tells us is that it is unlikely that the samples comes from the same, or identical, populations. But since we know (by the equal qualifications assumption) that the samples do come from identical populations, there must exist some distorting factor, such as implicit bias, modifying the real competence scores.
The second de-biasing method proceeds by updating the competence scores in the target ranking in proportion to the differences found between the mean scores of different social groups in the history of evaluations. More precisely, assign each social group S
i
represented in H a multiplier
 $S_i^x $
calculated by dividing
 $\bar X_{Si}^H $
with MAX(
 $\bar X_{S1}^H,..., \bar X_{Sn}^H $
). The ranking r** is then obtained by multiplying each score in the target ranking with the the multiplier corresponding to the relevant social group.
Multiplicative, Informed, Ratio-Scale Update (MIRU)
Substituting r** for a ranking r will improve veracity.
To illustrate this method, consider the history of evaluations above, and assume for the sake of illustration that we are only interested in three social groups, white men, white women and black women. Taking the means for these groups gives us
 $\bar X_{Swm}^H = 6$
,
 $\bar X_{Sww}^H = 4$
and
 $\bar X_{Sbw}^H = 3$
, which gives us the multipliers 1, 1.5 and 2 respectively. (We identify group membership here very coarsely, by noting whether a person has a male-sounding, female-sounding, white-sounding, or black-sounding name. More on this below.) By applying these multipliers to r
0 we get the following ranking.

This method has clear advantages over the first method; it avoids the looks-biased, is-biased problem and the ordinality-is-not-enough-problem, and in addition, it is applicable to rankings where different social groups are represented in different numbers (and thus avoids the equisize-problem). Moreover, it can apply to intersective categories (e.g. black women) without assuming that the bias that face members of these groups is a function of the biases that face the intersected groups (e.g. black people and women). It thus avoids the intersectionality-problem. Finally, how much an individual's competence score is changed is independent of the scores assigned to other members of the same social group as that individual, i.e. it avoids The zero-sum-problem. All in all, MIRU avoids all the problems that face SOU. It can also be noted that like SOU, MIRU always preserves the ordinal positions of members within a group and thus always preserves the information about the relative qualifications of group members contained in this ordering. However, there are a few points that, at least prima facie, speak against MIRU.
First, it might be objected that in situations (like the example above) where some social groups are only represented by very few members in the history of evaluations, the mean score is not a reliable indicator of the degree of bias. However, since we require that social groups in the history of evaluations be significantly different from each other in order for the method to apply, we thereby take care of this problem. If a group is significantly different from another group (according to a t-test for instance), it typically contains enough members for the mean to be a somewhat reliable estimate of the population mean (i.e. in this case, the degree of bias).
Second, it might be objected that social-group membership cannot always be straightforwardly read off a CV, or even less so off a list of names. This is certainly true. However, we do not have to assume this in order for the method to be reasonable. We only need the weaker requirement that we have access to the same information regarding social-group membership that the evaluator does, or – even weaker – that we classify people into the same social groups as the evaluator does. If everyone involved is mistaken about the actual group membership of a person, the evaluator's bias is still brought to bear on the individual, and we are still correcting for it. Although this convergence in classification is a substantial assumption, it bears emphasis how remarkably convergently we classify members of many important social groups (e.g. men and women, black people and white people). It should also be noted that if a person is both the evaluator, and the person applying the update method, the assumption is very reasonable to make (although not quite trivial, since the evaluator might not know the principles governing how she categorizes).
Third, the method assumes without argument that the bias operates in a certain way, in particular, that the competence scores of members of certain social groups are divided by some constant. To see the problem, assume that three men and three women are being ranked and that they in fact have corresponding competence scores, e.g. 3, 5 and 7. Now consider two different kinds of bias, one where the score of each woman is multiplied by 0.6, and one where 2 is subtracted from the score of each woman. In this example, this means that the mean score for women will in both cases be 3. If we – for simplicity – assume that the mean scores for the men and the women in the history of evaluations correspond to those in this ranking (i.e. 5 and 3 respectively), MIRU assigns the same multiplier to women in both corrections (1.66). But while this manages to restore the real competence scores in one case, it does not manage to do so in the other.
Bias 1 (*0.66)

Bias 2 (−2)

So the choice of a multiplicative corrective function is a substantial, unwarranted, assumption in MIRU.
Fourth, the method assumes that the estimates of the evaluator are done on a ratio-scale, and this presupposes that the evaluator can do these kind of judgments with some reasonable degree of accuracy. That an evaluator can make these kinds of judgments in a meaningful and accurate way is a substantially stronger assumption than the assumption that the evaluator is able to rank candidates from the most to the least qualified (as SOU presupposed). Although we concede that this is a fairly strong assumption, the underlying trade off here should be noted; on the one hand there is the amount of mathematically manipulations that can be meaningfully used to correct rankings, and on the other, there are the assumptions that we have to make about the abilities of the evaluator. More importantly, since the use of ratio-scale ratings is so widespread in hiring, the strength of the assumption that people can deliver these ratings with a reasonable degree of accuracy and reliability is not something that constrain the method's application, the assumption is already made in many contexts where the method is applicable.
Among these points, neither the first nor the second seems, on reflection, to be very problematic. The fourth point must be conceded, but is not damaging enough to refute the method by itself (it is rather a precondition for the existence of any useful de-biasing method at all). This leaves the third point, which must be dealt with.
3.4 Method 3: Generalized Informed Ratio-Scale Update
Although uncertainty about how implicit bias operates prevents us from updating a ranking in accordance with MIRU, there are ways around this problem. In particular, all plausible functions that are such that they make the scores in a history of evaluation the same across the represented social groups, should at least be considered. It was noted above that a precondition for MIRU is that the mean scores of different social groups are significantly different from each other, since this together with the equal qualifications assumption constitutes evidence that some distorting factor – such as implicit bias – is in effect. We can get additional traction from the equal qualifications assumption here. For given this assumption, and some corrective function f (such as the multiplicative function used in MIRU), if we still get significant differences between the social groups in our history of evaluation after we have applied f to these scores, then f makes incorrect assumptions about the way in which the bias operates. It is important here to use a sufficiently sensitive statistical test (like the two-sample Kolmogorov–Smirnov test) since after the corrective function have been applied to the scores in the history of evaluations, the means for all social groups will be the same. What will be different, however, are properties related to the variability of the scores, and this information is what we want to exploit here.Footnote 11
It is unlikely that this process will always rule out all but one of the candidate corrective functions. However, even in cases where we have multiple candidate functions we might learn something about the true ranking of individuals since these functions might partially or completely converge on specific rankings when applied to the target ranking. With this in mind, we can describe the third method in detail as follows.
Assume that you have a set of functions F of all functions f 1, …, f n such that when f i is applied to the competence scores of the history of evaluations, the mean competence score for each of the relevant social groups becomes the same (i.e. the mean competence for the group of all men and that for the group of all women in the history of evaluations becomes the same). Moreover, assume that F* is the subset of F corresponding to the functions in F that do not give rise to a statistically significant difference between any of the relevant social groups (as measured by, e.g. a two-sample Kolmogorov-Smirnov test which is also sensitive to differences in variance).
Generalized Informed Ratio Scale Update (GIRU)
Substituting the ranking r*** on which all functions in F* converge for a ranking r will improve veracity.
To illustrate GIRU recall the ranking r 0:

Now given the same history of evaluations as before, we have a function
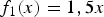 $f_1(x) = 1,5x$
which when applied to the white women of the history of evaluations gives them the same mean competence score as the white men from the history of evaluations. Consider now the function,
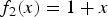 $f_2(x) = 1 + x$
. It, too, when applied to the white women of the history of evaluations, gives them the same mean competence score as the white men from the history of evaluations. For simplicity, assume that f
1 and f
2 are the only functions under consideration, and thus that F = {f
1, f
2}. Moreover, for the sake of argument, let us assume that neither f
1 nor f
2 yield statistically significant differences between e.g. white men and white women when they have been applied to the appropriate scores in the history of evaluations and thus that F = F*.
The method thus asks us to compare the rankings produced by f 1 and f 2. When applied to the target ranking these two functions yield the following two rankings.

At first glance, the two lists are quite different, but it should be noted that they converge in a number of ways that allow us to infer conclusions about the candidates that we did not have access to previously. For instance, we learn that Latifah is more qualified than both Sarah and Gordon, and that Felicia is at least as qualified as Mark.Footnote 12
Now, assume that we ran the Kolmogorov–Smirnov test and found e.g. that f 2 actually makes the men and women in the history of evaluations statistically different (even if they are assigned the same mean). It would then be unlikely that they have been sampled from the same populations, i.e. that f 2 doesn't capture how the bias is working. This means that F = {f 1}, and thus that the ranking produced by f 1 can be substituted for r 0 in order to increase veracity.
In both situations (i.e. independently of whether F contains more than one member) GIRU improves the veracity of the target ranking, and does so without making any assumptions about exactly how the bias is operating. GIRU is thus an improvement over MIRU.
Now, statistical methods like GIRU cannot guarantee improvements in any particular case, since ranking judgments on particular cases is subject to random variation. It does however, guarantee improvement across a sequence of future rankings (or, at least, it is guaranteed that GIRU will not distort such a sequence). To see this, assume that the evaluator's history of evaluations contain n rankings and consider the evaluator's next n rankings, on which GIRU is brought to bear. If there are no statistical differences between social groups in the history of evaluations, GIRU does nothing and thus does not distort the evaluator's next n rankings. If there are statistical differences, we know (due to the Equal Qualifications Assumption) that this is likely due to bias.Footnote 13 We assume (which seems reasonable in light of the discussion in §2) that the evaluator will persist in her bias when evaluating her next n rankings. It follows that the differences in means between the ratings of different social groups in the past and in the future will be roughly the same. All admissible corrective functions presupposed by GIRU are by definition such that they equalize the rating means for different social groups in the history of evaluations. But since the future differences are comparable to the past differences, it follows that the corrective functions used by GIRU will also equalize the rating means for different social groups in the future. There will thus not be any detectable bias there, which is an improvement over the past evaluations which did feature detectable bias.
3.5 Taking Stock
Although we believe that the third method – GIRU – does improve veracity reliably, it rests on five main assumptions, and its utility thus rests on how frequently we are warranted in making them.
First, in order for GIRU to be applicable, we must have access to a history of evaluations, in order to estimate how the evaluator is influenced by bias. Although this might limit the method's applicability somewhat, it appears to be a reasonable requirement; due to individual differences between evaluators, it is unlikely that we can reliably improve veracity without any knowledge of an evaluator's past behavior. Second, we assume that the estimated competence of a candidate can be meaningfully captured by a number on a ratio-scale (i.e. that it can be manipulated by addition, subtraction, multiplication and division). Although this is a substantial assumption, it it not unreasonable to think that it is an assumption that is independently being made by recruiters (in particular those that try to automate hiring by getting assessments of candidates from computer programs). So this assumption is already presupposed in some contexts where the method might be employed. Third, we assume that the evaluator persists in her bias. This seems very plausible in the light of the discussion in §2. Fourth, GIRU presupposes that we group people into the same social categories as the evaluator, which is also a very reasonable assumption. Fifth, it presupposes that candidates from all relevant social groups are drawn from populations that have the same overall distribution of the competence that is being evaluated (i.e. the equal qualifications assumption). This is very implausible in the extreme, but clearly holds for many groups with respect to many different kinds of competencies. Moreover, even if GIRU presupposes that all relevant populations are identical, it is likely that the statistical tests that it makes use of could be modified in such a way that GIRU can be applied as long as the population-distributions are known, even if they are not identical. So what is needed here is not the equal-qualifications assumption per se, but information about the relation between the populations that we sample. Given that we are warranted in making the five assumptions, GIRU avoids the main problem with MIRU and SOU and thus seems to be a reasonable debiasing method. It does not make any strong assumption about exactly how the bias is working, and makes recommendations for updating only where the corrective functions under consideration converge.
4. CONCLUSION
We have presented three different methods for updating implicitly biased rankings and argued that the last of these reliably improves veracity under certain conditions. We have thereby offered a new alternative to the de-biasing options previously considered in the literature. This is welcome, since they all have clear restrictions; making people less implicitly biased is extremely hard, enforcing quotas is not epistemologically helpful, and anonymization – despite its simplicity and power – is far from universally applicable.
The epistemological problem raises several questions that we have not (for reasons of space) attempted to answer here. For instance, how should we come to terms with the fact that different evaluators might be better or worse at evaluating competence (quite independently of their biases)? Or how should we approach the situations where a group of people – the exact constitution of which changes over time – jointly evaluate a set of candidates? Or how would the known presence of a corrective mechanism like GIRU influence an evaluator's behavior?
We have stressed that solutions to moral and political problems raised by implicit bias (e.g. quotas) need not be solutions to the epistemological problem that we have been concerned with. However, a solution like ours to the epistemological problem, will also help us come to terms moral and political problems. A better understanding of the actual qualifications of a group of candidates will help us avoid unjust distribution of power and resources.Footnote 14