1 Introduction
There has been a substantial interest in multimodal tasks that combine language and vision. One such task is Image Captioning (IC), where given an image the goal is to generate a caption that describes it (Vinyals et al. Reference Vinyals, Toshev, Bengio and Erhan2015; Karpathy and Fei-Fei Reference Karpathy and Fei-Fei2015; Kiros, Salakhutdinov and Zemel Reference Kiros, Salakhutdinov and Zemel2014). This interest has driven the community to create a series of datasets, including IAPR-TC12 (Grubinger et al., Reference Grubinger, Clough, Müller and Deselaers2006), UIUC PASCAL Sentences and Flickr8k (Rashtchian et al., Reference Rashtchian, Young, Hodosh and Hockenmaier2010), Flickr30k (Young et al., Reference Young, Lai, Hodosh and Hockenmaier2014) and MSCOCO (Chen et al., Reference Chen, Fang, Lin, Vedantam, Gupta, Dollár and Zitnick2015), the largest of them all. This has also led to the very popular MSCOCO captioning challenges. The success in IC has inspired other, more advanced, vision to language problems, including visual question answering (Antol et al., Reference Antol, Agrawal, Lu, Mitchell, Batra, Zitnick and Parikh2015) and Multimodal Machine Translation (MMT) (Specia et al., Reference Specia, Frank, Simaan and Elliott2016; Elliott et al., Reference Elliott, Frank, Barrault, Bougares and Specia2017).
Recent advances in deep learning models in the area of sequence modeling using Recurrent Neural Networks (RNN) have led to highly effective ways of learning sequential tasks (Elman, Reference Elman1990). End-to-end deep neural models achieve impressive results for various tasks including language modeling (Mikolov et al., Reference Mikolov, Karafiát, Burget, Cernockỳ and Khudanpur2010) and machine translation (Bahdanau, Cho and Bengio, Reference Bahdanau, Cho and Bengio2015). For IC, most state-of-the-art models condition a deep recurrent sequence generator (i.e., an RNN) on some image information. The image information is usually the penultimate layer of a Convolutional Neural Network (CNN) that has been pre-trained for object classification (Karpathy and Fei-Fei, Reference Karpathy and Fei-Fei2015; Vinyals et al., Reference Vinyals, Toshev, Bengio and Erhan2015). Alternatively, other layers in the network are used along with attention mechanisms on these representations to condition the RNN-based generator (Kiros et al., Reference Kiros, Salakhutdinov and Zemel2014; Xu et al., Reference Xu, Ba, Kiros, Cho, Courville, Salakhutdinov, Zemel and Bengio2015; Wu et al., Reference Wu, Shen, Liu, Dick and van den Hengel2016). The success obtained in these tasks comes to some surprise given the differences between the representational spaces of image embeddings and the language in RNN-based models. End-to-end deep neural IC methods are able to generate captions without resorting to higher-level semantic mappings of the image space into the language space. More recent work has also investigated representations of the image in the form of attributes, such as the objects potentially appearing in it, using class-based probabilistic distributions (Yao et al., Reference Yao, Pan, Li, Qiu and Mei2017). These methods achieve even better results on standard test sets for the tasks of IC and visual question answering (Wu et al., Reference Wu, Shen, Liu, Dick and van den Hengel2016). In MMT, the results are less conclusive.
This raises interesting questions about the informativeness of different types of representations, in particular, low- versus high-level information in the context of vision to language tasks. A sparse, attribute-level representation is indicative of the presence of a pre-defined, limited number of attributes (often objects) given an image. On the other hand, dense, low- or mid-level or the CNN-activation-based image representations are expected to capture more details in the images, such as abstract scene information.
Previous work utilizes several types of image representations coupled with different ways to use them in vision to language tasks. However, it is not clear what the representational contribution of these different types of image information is and why different representations lead to certain words being generated over others. In this work, we study the influence of different types of image information in a controlled setup and empirically probe the informativeness of the image representations. Our main contributions are as follows:
• We study the effect of different image-level representational features in the context of end-to-end IC and MMT systems.
• We show that end-to-end models, conditioned on image representations, mostly perform image matching in a common image-text space to generate sentences.
• We show that a low-dimensional, sparse and interpretable vector also performs competitively with higher-dimensional CNN image embeddings, suggesting that such low-dimensional features may be sufficient to generate sentences in the visual-semantic subspace.
2 Background and related work
In this section, we first describe various approaches used to tackle IC and MMT tasks (Sections 2.1 and 2.2 respectively). We then describe recent efforts in exploring different representations for vision to language tasks that provide some context for our study (Section 2.3).
2.1 Image captioning approaches
Approaches for IC can be categorized into three primary groups: (i) pipelined approaches, (ii) retrieval approaches and (iii) end-to-end approaches.
Pipelined approaches. We call early work on IC ‘pipelined’ as it follows a sequence of steps: First, object categories are explicitly detected with visual object detectors; then the output of such detectors is used as input to generate image descriptions through a generative model, such as template filling (Yao et al., Reference Yao, Yang, Lin, Lee and Zhu2010; Kulkarni et al., Reference Kulkarni, Premraj, Dhar, Li, Choi, Berg and Berg2011; Li et al., Reference Li, Kulkarni, Berg, Berg and Choi2011; Yang et al., Reference Yang, Teo, Daumé and Aloimonos2011; Mitchell et al., Reference Mitchell, Dodge, Goyal, Yamaguchi, Stratos, Han, Mensch, Berg, Berg and Daume2012; Elliott and de Vries, Reference Elliott and de Vries2015), combining phrases from a corpus (Li et al., Reference Li, Kulkarni, Berg, Berg and Choi2011), generating trees (Mitchell et al., Reference Mitchell, Dodge, Goyal, Yamaguchi, Stratos, Han, Mensch, Berg, Berg and Daume2012) or learning a statistical language model (Fang et al., Reference Fang, Gupta, Iandola, Srivastava, Deng, Dollár, Gao, He, Mitchell and Platt2015). Such methods are capable of generating captions not seen at training time, although their performance depends on the quality of the visual detectors, whose outputs form the input ‘representation’ to the caption generator.
Retrieval approaches. Retrieval approaches to IC retrieve existing captions from the training set or an external dataset. These methods include projecting images and captions onto a common representation space (Farhadi et al., Reference Farhadi, Hejrati, Sadeghi, Young, Rashtchian, Hockenmaier and Forsyth2010; Hodosh, Young and Hockenmaier, Reference Hodosh, Young and Hockenmaier2013; Socher et al., Reference Socher, Karpathy, Le, Manning and Ng2014) and utilizing some image similarity measure (Ordonez, Kulkarni and Berg, Reference Ordonez, Kulkarni and Berg2011) among other methods. For example, Hodosh et al. Hodosh, Young and Hockenmaier (Reference Hodosh, Young and Hockenmaier2013) use Kernel Canonical Correlation Analysis to project images and their captions into a joint representation space in which images and captions can be related and ranked to perform illustration and annotation tasks. Such retrieval methods produce image captions that are fluent and expressive (since they are ‘copied’ from human-authored captions in the training set) but cannot produce novel captions. Work towards generating novel captions retrieves and combines existing text fragments (Kuznetsova et al., Reference Kuznetsova, Ordonez, Berg, Berg and Choi2012, Reference Kuznetsova, Ordonez, Berg and Choi2014) or prunes irrelevant fragments for better generalization (Kuznetsova et al., Reference Kuznetsova, Ordonez, Berg, Berg and Choi2013). The resulting captions, however, may still be irrelevant to the image content. On the image side, such methods mainly use a global image representation (e.g., the penultimate layer of a CNN) or an intermediate representation, such as a semantic tuple.
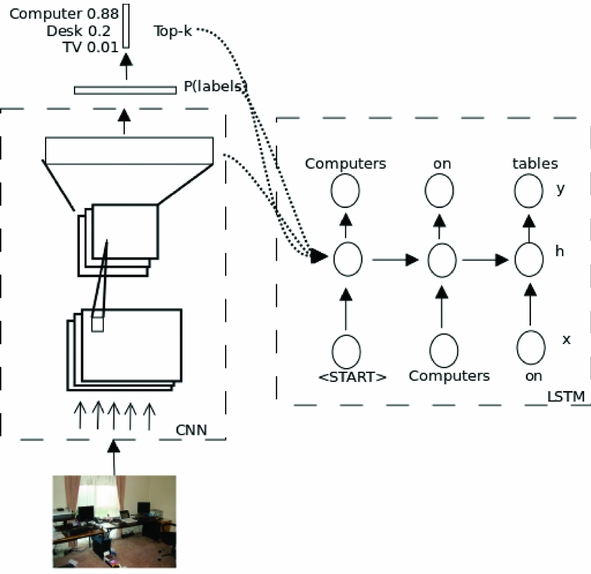
End-to-End approaches. Finally, end-to-end, deep neural-network-based approaches are currently the most popular method for IC, yielding state-of-the-art results. These approaches were inspired by the success shown in transferring image representations to other tasks (Razavian et al., Reference Razavian, Azizpour, Sullivan and Carlsson2014) using simple transfer learning approaches. End-to-end methods will be discussed in more detail in Section 3. In general, such approaches extract image-related features using a CNN, which are then fed to an RNN caption generator. A popular and simple approach to condition the RNN on the image representation is by initializing the start state of the RNN with the image encoding (Karpathy and Fei-Fei, Reference Karpathy and Fei-Fei2015; Vinyals et al., Reference Vinyals, Toshev, Bengio and Erhan2015) as shown in Figure 1. The CNN model used in most state-of-the-art approaches for IC (and MMT) is based on a classification model trained to optimally perform on an object classification task. The visual representation obtained as the activations of the penultimate layer have been shown previously to generalize to other tasks in the framework of transfer learning (Donahue et al., Reference Donahue, Jia, Vinyals, Hoffman, Zhang, Tzeng and Darrell2014). Most previous approaches use pre-trained deep CNN networks, such as VGGNet (Karpathy and Fei-Fei, Reference Karpathy and Fei-Fei2015), Inception CNN (Vinyals et al., Reference Vinyals, Toshev, Bengio and Erhan2015) and ResNet (Yao et al., Reference Yao, Pan, Li, Qiu and Mei2017), to obtain an image representation that is fed into a continuous sequence generator. Attention mechanisms have also been used. For example, Xu et al. Xu et al. (Reference Xu, Ba, Kiros, Cho, Courville, Salakhutdinov, Zemel and Bengio2015) learns an IC model that attends to the output of a convolutional layer of a CNN.
RNN conditioned on different types of image representations: (a) penultimate layer, (b) posterior over object class labels and (c) averaged word representations for the top-k object classes.

Other ways of inducing representations in end-to-end approaches include attribute-level information. These correspond to the class-based predictions of the image network, i.e., the posterior probability distribution on a pre-defined set of classes that can correspond to objects in the image, as shown in Figure 1. Wu et al. Wu et al. (Reference Wu, Shen, Liu, Dick and van den Hengel2016) further fine-tune the pre-trained image network on a new label set. This fine-tuning helps the image network predict classes that correspond to the expected vocabulary.
Image captions generated by end-to-end systems can be novel to a certain extent depending on search configurations, e.g., the beam size used during decoding. In these approaches, the proportion of novel descriptions has been reported to be between 30% and 50% for optimally trained systems (Devlin et al., Reference Devlin, Cheng, Fang, Gupta, Deng, He, Zweig and Mitchell2015; Vinyals et al., Reference Vinyals, Toshev, Bengio and Erhan2016; Karpathy, Reference Karpathy2016). The number of unique captions generated by such systems has also been reported to be approximately 30%. Humans, in contrast, rarely repeat descriptions, having a rate of 95%–99% unique descriptions reported for the MSCOCO dataset (Devlin et al., Reference Devlin, Cheng, Fang, Gupta, Deng, He, Zweig and Mitchell2015; Karpathy, Reference Karpathy2016). End-to-end systems also require a lot of parallel corpora (images with captions) for training, making it hard to adapt to different languages, styles or domains. Thus, end-to-end systems seem to predominantly ‘memorize’ parallel corpora, making it seemingly more like a ‘retrieval machine’ rather than genuinely generating image descriptions as in older pipelined approaches.
We refer readers to Bernardi et al. Bernardi et al. (Reference Bernardi, Cakici, Elliott, Erdem, Erdem, Ikizler-Cinbis, Keller, Muscat and Plank2016) for an in-depth discussion on various IC approaches.
2.2 Multimodal machine translation approaches
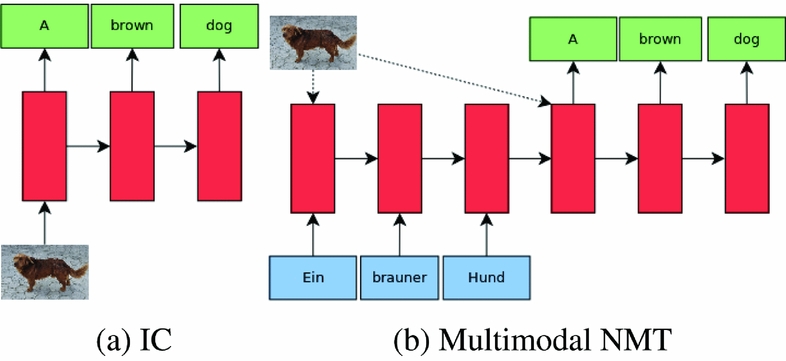
The task of MMT is closely related to that of IC. Most existing work focuses on end-to-end approaches, with an additional RNN used to encode the source sentence to produce a sequence of encoded vectors. Figure 2 illustrates the differences between typical IC and MMT architectures. In MMT, the visual information can be used to condition the source RNN, the target RNN, or both (Elliott, Frank and Hasler Reference Elliott, Frank and Hasler2015). Most existing work obtain the best results by combining the penultimate layer of the CNN (via concatenation, summation, etc.) with the final state of the source sentence representation and using it to initialize the target RNN (Caglayan et al. Reference Caglayan, Aransa, Wang, Masana, García-Martínez, Bougares, Barrault and van de Weijer2016; Calixto, Elliott and Frank Reference Calixto, Elliott and Frank2016; Huang et al. Reference Huang, Liu, Shiang, Oh and Dyer2016).
Typical architecture of IC and MMT systems. In (a), the input image is encoded as a vector, and a description is decoded using an RNN. In (b), the source sentence encoding is used as decoder input, and the image embedding as input to either (or both) the source encoder or target decoder.

Recent work also explores an attention mechanism where they use lower-level CNN features of the images, such as a convolutional layer, and condition the source and the target sentences on the image features (Calixto et al., Reference Calixto, Elliott and Frank2016; Calixto, Liu and Campbell, Reference Calixto, Liu and Campbell2017). The intuition here is that the lower-level CNN features capture information about different areas of the images and an attention mechanism could learn to attend to specific regions while both encoding the source and decoding the target sentence.
Alternative approaches rely on pre-generated candidate translations for each source sentence from a text-only MT model, which are then re-ranked based on visual information (Shah, Wang and Specia, Reference Shah, Wang and Specia2016), or use image information by pivoting on it to find relevant captions in external corpora (Hitschler, Schamoni and Riezler, Reference Hitschler, Schamoni and Riezler2016). Approaches that exploit multi-task learning to jointly model how to translate and learn visually grounded representations showed promising results (Elliott and Ká, Reference Elliott and Kádárd).
2.3 Studying visual representations
Recent work in analyzing multimodal representations include (Devlin et al., Reference Devlin, Cheng, Fang, Gupta, Deng, He, Zweig and Mitchell2015; van Miltenburg and Elliott, Reference van Miltenburg and Elliott2017), which focus on linguistic regularities in the generated captions. They are interested in comparing different IC architectures and the properties of the produced captions. In contrast, our work focuses on studying visual representations and their impact in vision to language tasks.
Focusing on MMT, Lala et al. Lala et al. (Reference Lala, Madhyastha, Wang and Specia2017) show that, given reliable image information in the form of captions, an ideal MMT system would be able to significantly benefit and obtain better translations.
Vinyals et al. Vinyals et al. (Reference Vinyals, Toshev, Bengio and Erhan2016) and Karpathy Karpathy (Reference Karpathy2016) present an analysis of lexical and syntactic properties of the generated captions. They conclude that almost 80% of the time the best caption for an image in the validation or test sets of MSCOCO can be retrieved from its training set, and that beam size often dictates the diversity in the output captions. Lebret, Pinheiro and Collobert Lebret et al. (Reference Lebret, Pinheiro and Collobert2015) also analyzed the syntax of image captions in Flickr30k and MSCOCO and found that they comprise a simple and predictable structure.
The MSCOCO shared task (Chen et al., Reference Chen, Fang, Lin, Vedantam, Gupta, Dollár and Zitnick2015) showed that participating systems using variants of retrieval-based approaches (Devlin et al., Reference Devlin, Cheng, Fang, Gupta, Deng, He, Zweig and Mitchell2015; Kolář, Hradiš and Zemčík, Reference Kolář, Hradiš and Zemčík2015) performed competitively with end-to-end approaches. Recent work seems to suggest that, in the end-to-end learning framework, using posterior distributions over a refined set of object classes (relevant to captions) performs better than using lower-level dense image representations (You et al., Reference You, Jin, Wang, Fang and Luo2016; Wu et al., Reference Wu, Shen, Liu, Dick and van den Hengel2016). Vinyals et al. Vinyals et al. (Reference Vinyals, Toshev, Bengio and Erhan2016) note that using a better image network (a network that performs better on the image classification task) results in improvements in the generated captions.
In this paper, we concentrate on the image side of IC, and systematically investigate the contribution of different types of visual representations in these tasks and study plausible reasons that drive the language generation component. We focus on the currently dominant end-to-end approaches, which represent the state-of-the-art for both IC and MMT. We acknowledge that there might be other types of approaches, e.g., Fang et al. Fang et al. (Reference Fang, Gupta, Iandola, Srivastava, Deng, Dollár, Gao, He, Mitchell and Platt2015) use different architectures and also achieve strong performance, but studying these is left for future work.
3 Model setting
We base our IC implementation on a simple end-to-end approach by Karpathy & Fei-Fei Karpathy and Fei-Fei (Reference Karpathy and Fei-Fei2015), and consider most state-of-the-art systems as predominantly variants of this architecture. We use the Long Short-Term Memory (LSTM) RNN (Hochreiter and Schmidhuber, Reference Hochreiter and Schmidhuber1997; Chung et al., Reference Chung, Gulcehre, Cho and Bengio2014) as our generative network, as described in Zaremba, Sutskever and Vinyals Zaremba, Sutskever and Vinyals (Reference Zaremba, Sutskever and Vinyals2014) work for IC.
In order to use the image information, we first perform a linear projection of the image representation followed by a non-linearity as shown below
 \begin{equation*}
Im_{feat} = \sigma {(W{\cdot }I_m)}
\end{equation*}
where  $I_m \in {\mathcal {R}}^d$ is the d-dimensional initial image representation,
 $W \in {\mathcal {R}}^{d{\times }m}$ is the linear transformation matrix and σ is the non-linearity. We use exponential linear units as the non-linearity (Clevert, Unterthiner and Hochreiter, Reference Clevert, Unterthiner and Hochreiter2015) since it is faster to compute. Following Vinyals et al. Vinyals et al. (Reference Vinyals, Toshev, Bengio and Erhan2015), we initialize the LSTM generative sequence model with the projected image information.
For MMT, we first build an attention-based, encoder–decoder framework as described in Luong, Pham and Manning Luong et al. (Reference Luong, Pham and Manning2015). We explore two approaches to use image information: (i) conditioning the encoder on image information; (ii) conditioning the decoder on image information. Both (i) and (ii) are similar to the afore-described approach for IC.
The sentence generator is trained to generate sentences conditioned on the image representation (IC and MMT), and also on the source sentence representation for MMT. This is done by using the cross-entropy loss. That is, the sentence-level loss corresponds to the sum of the negative log likelihood of the correct word at each time step. For IC, we have
 \begin{equation}
\Pr (S{\mid }Im_{feat};\theta ) = \sum _t{\log (\Pr (w_t|w_{t-1}..w_0;Im_{feat}))}
\end{equation}
where Pr(S|Imfeat;θ) is the sentence-level loss conditioned on the image features and Im feat and Pr(wt) is the probability of the word w t at time step t.
For MMT, given a source sentence F and the image features Im feat, we obtain the negative log-likelihood of the target sentence E as
 \begin{equation}
\Pr (E{\mid }F, Im_{feat};\theta ) = \sum _i{\log (\Pr (w_{t}|w_{t-1}..w_{0};F,Im_{feat}))}
\end{equation}
where Pr(E|F,Imfeat;θ) is now conditioned on both the source sentence F and the image features Im feat and w t are words corresponding to the sentence in the target language.
The standard maximum likelihood objective is used to train the model, with teacher forcing as described in Sutskever, Vinyals and Le Sutskever, Vinyals and Le (Reference Sutskever, Vinyals and Le2014), where the correct word information is fed to the next state in the LSTM. Inference is usually done using approximate techniques like beam search and sampling methods (Karpathy and Fei-Fei, Reference Karpathy and Fei-Fei2015; Vinyals et al., Reference Vinyals, Toshev, Bengio and Erhan2015). In this paper, as we are mainly interested in studying the effect of different image representations, we focus on the language output that the models can most confidently produce. Therefore, in order to isolate any other variables from the experiments, we generate captions using a greedy arg max based approach, i.e., no beam search.
4 Image representations
Various representations are explored in this paper to study the representational contribution of images for both IC and MMT. We first provide an overview of the various pre-trained image networks used to obtain image features (Section 4.1), which are then used to form image representations for IC (Section 4.2) and MMT (Section 4.3).
4.1 Pre-trained image networks
In computer vision, CNNs became the de facto choice for image representations after the successful performance of the AlexNet CNN (Krizhevsky, Sutskever and Hinton, Reference Krizhevsky, Sutskever and Hinton2012) in the 2012 ImageNet Large Scale Visual Recognition Challenge (ILSVRC 2012) (Russakovsky et al., Reference Russakovsky, Deng, Su, Krause, Satheesh, Ma, Huang, Karpathy, Khosla, Bernstein, Berg and Fei-Fei2015). Such networks are trained on the ILSVRC dataset for object classification, i.e., classifying images into a set of 1,000 pre-defined categories or synsets (‘is this an image of a cat?’). Intermediate layers of the CNN are also often extracted and used as off-the-shelf features for various other vision tasks (Donahue et al., Reference Donahue, Jia, Vinyals, Hoffman, Zhang, Tzeng and Darrell2014; Razavian et al., Reference Razavian, Azizpour, Sullivan and Carlsson2014). For IC and MMT, it is worth noting that the object categories may not be directly relevant to the captions and vice versa (the captions may mention concepts that are not covered by the 1,000 categories). We explore the following two CNNs, both pre-trained on the ILSVRC dataset:
VGG19: VGGNet (Simonyan and Zisserman, Reference Simonyan and Zisserman2015) achieved a top-5 accuracy of 92.7% in the ILSVRC 2014 challenge, making it among the top two best performing networks at the time. VGGNet is found to generalize well to different datasets and tasks, and is thus still widely used for different tasks. We use the pre-trained 19-layer version of VGGNet, which is reported to give slightly better performance in object classification over the 16-layer version, at the expense of being more complex.
ResNet152: ResNet (He et al., Reference He, Zhang, Ren and Sun2016) reported a top-5 classification accuracy of 97.4% in the ILSVRC 2015 challenge, a significant improvement over VGGNet. The improvement resulted from drastically increasing the number of layers to 152, compared to VGGNet’s 19. We also explore using the output of the pre-trained 152-layer version of ResNet for IC and MMT to investigate whether the improvement in classification accuracy on ILSVRC helps with downstream vision to language tasks.
We also explore two other variants of ResNet152 as follows:
Places365–ResNet152: Zhou et al. Zhou et al. (Reference Zhou, Lapedriza, Xiao, Torralba and Oliva2014) trained a CNN on the Places2 dataset (Zhou et al., Reference Zhou, Lapedriza, Khosla, Oliva and Torralba2017) to classify 365 scene categories (sky, baseball stadium, etc.). We investigate whether these networks predicting scene-specific categories are useful for IC, despite not predicting object-specific categories. We experiment with ResNet152 pre-trained solely on the Places2 dataset. Similar to the 1,000 ILSVRC categories, the scene categories may not be relevant to the captions, and some scenes mentioned in the captions may not exist in the 365 scene categories.
Hybrid1365–ResNet152: Zhou et al. Zhou et al. (Reference Zhou, Lapedriza, Xiao, Torralba and Oliva2014) also proposed training a CNN on the concatenation of both ILSVRC and Places2 datasets, thus predicting both object and scene categories (1,365 classes). Therefore, we examine whether such a network combining both types of information can be helpful for vision to language tasks. This network is again based on the ResNet512 architecture.
4.2 Image representations for IC
We now describe different representations explored for the task of IC. These include a lower-bound baseline (Section 4.2.1), representations derived from image classification (Section 4.2.2), and representations derived from object detectors (Section 4.2.3).
4.2.1 Lower-bound representation
Random: We condition the LSTM on a 300-dimensional vector containing random values sampled uniformly between [0,1].Footnote 1 This represents a worst case image feature and provides an artificial lower bound.
4.2.2 Representations from image-level classification
We explore various representations derived from pre-trained CNNs (Section 4.1) as follows:
Penultimate layer (Penultimate): Most previous attempts for IC use the output of the penultimate layer of a CNN pre-trained on the ILSVRC data. Previous work motivates using ‘off-the-shelf’ feature extractors in the framework of transfer learning (Donahue et al., Reference Donahue, Jia, Vinyals, Hoffman, Zhang, Tzeng and Darrell2014; Razavian et al., Reference Razavian, Azizpour, Sullivan and Carlsson2014). Such features have been often applied to IC (Donahue et al., Reference Donahue, Hendricks, Guadarrama, Rohrbach, Venugopalan, Saenko and Darrell2015; Gao et al., Reference Gao, Mao, Zhou, Huang, Wang and Xu2015; Karpathy and Fei-Fei, Reference Karpathy and Fei-Fei2015; Mao et al., Reference Mao, Xu, Yang, Wang, Huang and Yuille2015; Vinyals et al., Reference Vinyals, Toshev, Bengio and Erhan2015) and have been shown to produce state-of-the-art results. Therefore, for each image, we extract the fc7 layer of VGG19 (4096D) and the pool5 layer for the ResNet152 variants (2048D).
Class prediction vector (Softmax): We investigate higher-level image representations, where each element in the vector is an estimated posterior probability of object categories. As previously noted, the categories may not directly correspond to the captions in the dataset. While there are alternative methods that fine-tune the image network on a new set of object classes, extracted in ways that are directly relevant to the captions (Fang et al., Reference Fang, Gupta, Iandola, Srivastava, Deng, Dollár, Gao, He, Mitchell and Platt2015; Wu et al., Reference Wu, Shen, Liu, Dick and van den Hengel2016; Yao et al., Reference Yao, Pan, Li, Qiu and Mei2017), we study the impact of off-the-shelf prediction vectors on the IC task. The intuition is that category predictions from pre-trained CNN classifiers may also be beneficial for IC, alongside the standard approach of using mid-level features from the penultimate layer. Therefore, for each image, we use the predicted category posterior distributions of VGG19 and ResNet152 (1,000 object categories), Places365–ResNet152 (365 scene categories) and Hybrid-ResNet152 (1365 object and scene categories).
Object class word embeddings (Top-k): Here we experiment with a method that utilizes the averaged word representations of top-k predicted object classes. We first obtain Softmax predictions using ResNet152 for 1,000 object categories (synsets) per image. We then select the objects that have a posterior probability score >5% and use the 300-dimensional pre-trained word2vec (Mikolov et al., Reference Mikolov, Sutskever, Chen, Corrado and Dean2013) representationsFootnote 2 to obtain the averaged vector over all top object categories. This is motivated by the central observation that averaged word embeddings can represent semantic-level properties and are useful for classification tasks (Arora, Liang and Ma, Reference Arora, Liang and Ma2017).
4.2.3 Representations from object-level detections
We also explore representing images using information from object detectors that identify instances of object categories present in an image, rather than a global image-level classification as described earlier. The output of visual detectors can help form a more interpretable and informative image representation
• Ground truth (Gold) region annotations for instances of eighty pre-defined categories provided with MSCOCO, the dataset we use for the IC experiments. It is worth noting that these were annotated independently of the image captions, i.e. people writing the captions had no knowledge of the 80 categories and the annotations (and vice versa). As such, there is no direct correspondence between the region annotations and image captions.
• The state-of-the-art object detector YOLO (Redmon and Farhadi, Reference Redmon and Farhadi2017) pre-trained on MSCOCO for 80 categories (YOLO-Coco), or pre-trained on MSCOCO and ILSVRC for 9,000 categories (YOLO-9k) in a weakly supervised fashion (bounding boxes surrounding object instances are not provided).
We explore several representations as presented below, derived from instance-level object class annotations/detectors above:
Bag of objects (BOO): We represent each image as a sparse bag of objects vector, where each element represents the frequency of occurrence for each object category in the image (Counts). We also explore an alternative representation, where we only encode the presence or absence of the object category regardless of its frequency (Binary), to determine whether or not it is important to encode object counts in the image. These representations help us examine the importance of explicit object categories and in a sense interactions between object categories (dog and ball) in the image representation. We investigate whether such a sparse and high-level BOO representation is helpful for IC. It is also worth noting that BOO is different from the Softmax representation above as it encodes the number of object occurrences, and not the confidence of class predictions at image level. We compare BOO representations derived from the Gold annotations (Gold-Binary and Gold-Counts) and both YOLO-Coco and YOLO-9k detectors (Counts only).
Pseudo-random vectors: To further probe the capacity of IC models to make use of image representations, we experiment with noisy vectors that contain object-level information. More specifically, we examine a type of representation where similar objects are represented using similar random vectors. We then form the representation of the image from BOO Gold-Counts and BOO Gold-Binary; formally, Im feat = ∑o ∈ Objectsf × ϕo, where  $\phi _{o} \in {\mathcal {R}}^d$ is an object-specific random vector and f is a scalar representing counts of the object category. We call these pseudo-random vectors. In the case of Pseudo-random-Counts, f is the frequency counts from Gold-Counts. In the case of Pseudo-random-Binary, f is either 0 or 1 based on Gold-Binary. We use d = 120. We investigate whether these seemingly random representations (but which have a latent structure) can generate reasonable captions.
4.3 Image representations for MMT
Based on the observations from our experiments for IC, we explore the following image features for MMT:
Penultimate layer (Penultimate): As with previous successful approaches to MMT (Elliott et al., Reference Elliott, Frank and Hasler2015; Huang et al., Reference Huang, Liu, Shiang, Oh and Dyer2016; Libovický et al., Reference Libovický, Helcl, Tlustý, Bojar and Pecina2016), we use image information obtained from the penultimate layer of a pre-trained image network. Since, we observed that ResNet152-based representations were slightly better for IC, we only use ResNet152 pre-trained on object classification for MMT, with representations from the penultimate layer (Pool5) of the network.
Class prediction vector (Softmax): As in IC, we also use the posterior distribution from ResNet152 (1,000 object categories) as image information.
5 Experiments and results
To study the efficacy of vision to language models and understand the contribution of image information, we perform a series of experiments on standard datasets. We explore end-to-end approaches to IC and MMT, and make our source code and models available for replicability.
5.1 Datasets
IC: We use the most widely used evaluation setup for IC, i.e., MSCOCO (Chen et al., Reference Chen, Fang, Lin, Vedantam, Gupta, Dollár and Zitnick2015). The dataset consists of 82,783 images for training, with 5 captions per image, thus totaling 413,915 captions in total. The validation set consists of 40,504 images and 202,520 captions. We perform model selection on a 5,000-image development set and report the results on a 5,000-image test set using standard, publicly availableFootnote 3 splits of the MSCOCO validation dataset, as in previous work (Karpathy and Fei-Fei, Reference Karpathy and Fei-Fei2015).
Details about the collection of the images and captions can be found in (Chen et al., Reference Chen, Fang, Lin, Vedantam, Gupta, Dollár and Zitnick2015). While other IC datasets exist (Grubinger et al., Reference Grubinger, Clough, Müller and Deselaers2006; Rashtchian et al., Reference Rashtchian, Young, Hodosh and Hockenmaier2010; Young et al., Reference Young, Lai, Hodosh and Hockenmaier2014), we focus on MSCOCO as it is more recent and has been extensively used and evaluated in an open platform.Footnote 4 More information on different IC or image description datasets can be found in Ferraro et al. Ferraro et al. (Reference Ferraro, Mostafazadeh, Vanderwende, Devlin, Galley and Mitchell2015).
MMT: We use the Multi30k (Elliott et al., Reference Elliott, Frank, Sima’an and Specia2016) English-German (en-de) MMT dataset, which was released as part of the WMT 2016 shared task on MMT (Specia et al., Reference Specia, Frank, Simaan and Elliott2016). The dataset consists of English-German sentence pairs, where the English sentence is a caption belonging to the Flickr30k dataset (Young et al., Reference Young, Lai, Hodosh and Hockenmaier2014) and the corresponding German sentence is a translation of this description professionally crafted. We also experiment with using the same data and flipping the translation direction, i.e., with a German-English (de-en) dataset. This dataset is reasonably small, containing 29K sentence pairs for training, 1K for development and 1K for test. As in most datasets derived from IC tasks, sentences are very short: On average 11.9 tokens for English and 11.1 tokens for German.
5.2 Evaluation metrics
We evaluated system outputs using standard metrics for IC and MMT.
IC: The most common metrics for IC are BLEU (Papineni et al., Reference Papineni, Roukos, Ward and Zhu2002), Meteor (Denkowski and Lavie, Reference Denkowski and Lavie2014) and CIDEr (Vedantam, Zitnick and Parikh, Reference Vedantam, Zitnick and Parikh2015). All of these metrics are based on some form of n-gram overlap between the system output and the reference captions (i.e., no image information is used). BLEU is computed from 1-gram to 4-gram precision scores (B-1. . . B-4); as n increases (longer phrases), there will be less chances of an n-gram match resulting in a decrease in the overall score from B-1 to B-4. Meteor is an f-measure based metric that finds the optimal alignment between chunks of matched text and can incorporate semantic knowledge by allowing terms to be matched to stemmed words, synonyms and paraphrases, if such resources are available for the target language. CIDEr was developed specifically for IC, and measures the average cosine similarity between a generated caption and a reference, each represented as TF-IDF weighted bag of n-grams. We compare each system generated caption against five reference captions. We used the publicly available cocoeval script for evaluation.Footnote 5 Note that there are inherent weaknesses with these automatic metrics as they often do not correlate well with human judgements (Elliott and Keller, Reference Elliott and Keller2014; Kilickaya et al., Reference Kilickaya, Erdem, Ikizler-Cinbis and Erdem2017; Anderson et al., Reference Anderson, Fernando, Johnson and Gould2016). This is also reflected in the official MSCOCO metrics based on human judgements.Footnote 6 Other metrics have emerged in an attempt to address this issue (Anderson et al., Reference Anderson, Fernando, Johnson and Gould2016), but they have not been widely adopted.
MMT: We use the official metrics of the WMT16 MMT task – 4-gram BLEU and Meteor – computed using the publicly available multeval script.Footnote 7 Each generated caption is computed against one reference (human) translation. These are the most widely used metrics by the machine translation community for translation evaluation.
5.3 Model settings and hyperparameters
IC: We use a 2-layer LSTM with 128-dimensional word embeddings and 256-dimensional hidden dimensions.
MMT: We use a single hidden layer encoder and decoder both with 128-dimensional word embeddings and 256-dimensional hidden dimensions. We train with dropout set to 0.3 for the RNNs.
For both IC and MMT, as training vocabulary we retain only words that appear at least twice.
5.4 Results
5.4.1 Image captioning
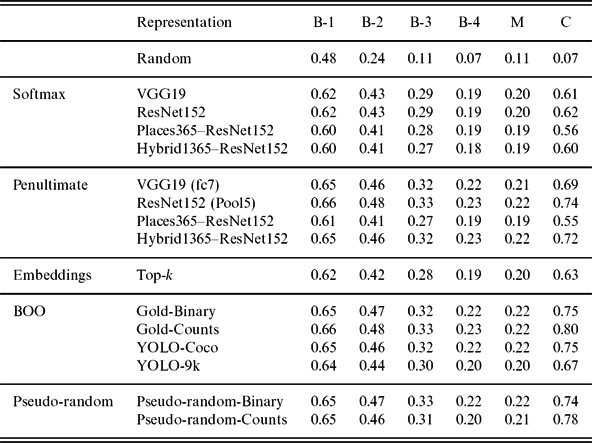
We first report results of IC on MSCOCO in Table 1, where the IC model (Section 3) is conditioned on the various image representations described in Section 4. As expected, using random image embeddings clearly does not provide any useful information and performs poorly. The Softmax representations with similar sets of object classes (VGG19, ResNet152, and Hybrid1365–ResNet152) have very similar performance. However, the Places365–ResNet representations perform worse. We note that the posterior distribution may not directly correspond to captions as there are many words and concepts that are not contained in the set of object classes. Our results differ from those by Wu et al. Wu et al. (Reference Wu, Shen, Liu, Dick and van den Hengel2016), Yao et al. Yao et al. (Reference Yao, Pan, Li, Qiu and Mei2017), and Fang et al. Fang et al. (Reference Fang, Gupta, Iandola, Srivastava, Deng, Dollár, Gao, He, Mitchell and Platt2015), where the object classes have been fine-tuned to correspond directly to the caption vocabulary. We posit that the degradation in performance is due to spurious probability distributions over object classes for similar looking images.
Results on the MSCOCO test split for IC, where we vary only the image representation and keep other parameters constant

Note: The captions are generated with beam = 1.
The performance of the Pool5 image representations shows a similar trend for VGG19, ResNet152 and Hybrid1365–ResNet152, with ResNet152 showing slightly better scores. Once again, the Places365–ResNet representation performs worse. The representations from the image network trained on object classes is probably able to capture more fine-grained image details from the images, whereas, the image network trained with scene-based classes captures more coarse-grained information.
The performance of the averaged top-k word embeddings is similar to that of the Softmax representation. This is interesting; since the averaged word representational information is mostly noisy: We combine top-k synset-level information into one single vector. However, it still performs competitively.
The performance of the Bag of Objects (BOO) sparse 80-dimensional annotation vector is better than all other image representations, if we consider the CIDEr scores. This is despite the fact that the annotations may not directly correspond to the semantic information in the image or the captions. The sparse representational information is indicative of the presence of only a subset of potentially useful objects. We notice a marked difference with Binary and Count-based representations. This takes us back to the motivation that IC ideally requires information about objects, as well as interactions between objects, with attribute-level information, such as number. Although our representation is really sparse on the object interactions, it captures the basic concept of the presence of more than one object of the same kind, and thus provides additional information. A similar trend is observed by Yin and Ordonez Yin and Ordonez (Reference Yin and Ordonez2017), although in their models they further try to learn interactions using another RNN for encoding objects.
Using objects predicted with YOLO-Coco performs better than using objects predicted with YOLO-9k. This is expected as YOLO-Coco was trained on the same dataset, hence, obtaining better object proposals. With YOLO-9k, a significant number of objects were predicted for the test images that had not been seen in the training set (around 20%).
The most surprising result is the performance of the pseudo-random vectors. Both the pseudo-random-Binary and the pseudo-random-Count vectors perform almost as well as the Gold objects. This suggests that the RNN is able to isolate the noise and learn some form of a common ‘visual-semantic’ subspace.
5.4.2 Multimodal machine translation
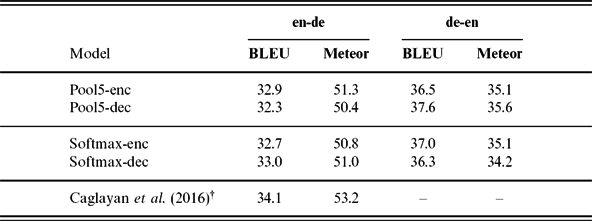
For MMT, we summarize the results in Table 2. Our models do not reach the performance of the top system at WMT16, but such a system is actually a combination of multiple strategies. We compare with one of best performing systems – Caglayan et al. Caglayan et al. (Reference Caglayan, Aransa, Wang, Masana, García-Martínez, Bougares, Barrault and van de Weijer2016). Their system uses a phrase-based statistical machine translation model, plus a re-scoring strategy using language model and visual information in the form of the penultimate layer of a pre-trained VGG network. The most interesting observation is that Pool5 and Softmax perform similarly, as in the IC task, and that the efficacy of the use of the visual information in the encoding versus decoding seems to depend on the type of visual representation and also on the dataset. In fact, no clear trend could be observed and additional experiments are needed, ideally with more realistic translation (not IC) data.
Results for en-de and de-en MMT test sets

Note: † are best WMT16 results taken from Caglayan et al. (Reference Caglayan, Aransa, Wang, Masana, García-Martínez, Bougares, Barrault and van de Weijer2016), which are generated based on a combination of statistical machine translation and re-scoring.
6 Analysis and discussion
In what follows we further analyze the results for the IC task, for which the representations and models studied in this paper seem to show a clearer trend than for MMT.
6.1 Image representations
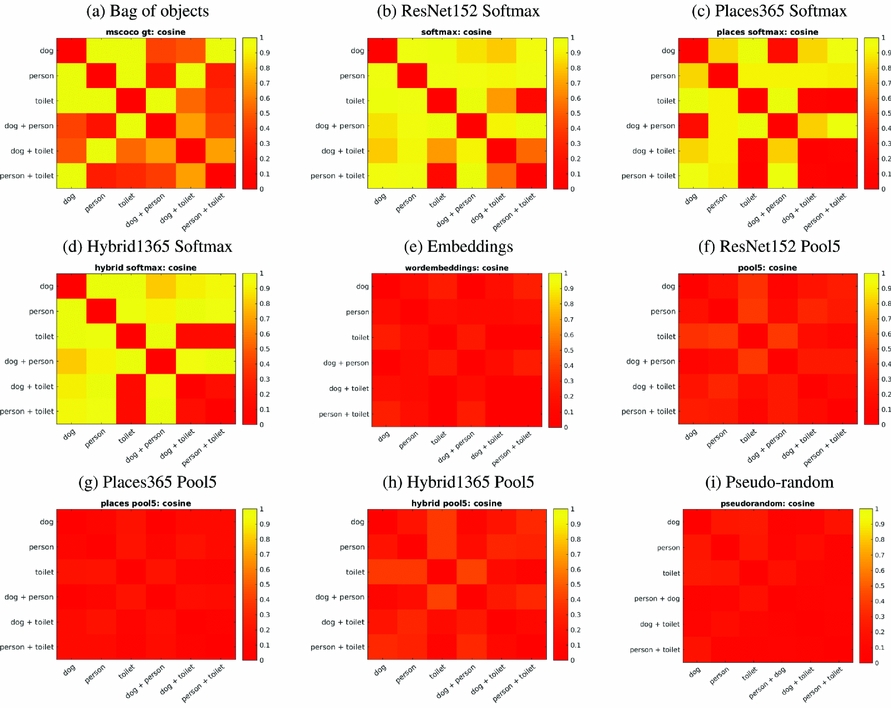
We first compare different image representations with respect to their ability to group and distinguish between semantically related images. For this, we selected three categories from MSCOCO (‘dog’, ‘person’ and ‘toilet’) and also pairwise combinations of these (‘dog + person’, ‘dog + toilet’ and ‘person + toilet’). Up to twenty-five images were randomly selected for each of these six groups (single category or pair) such that the images are annotated with only the associated categories. Each group is represented by the average image feature of these images. Figure 3 shows the cosine distances between each group, for each of our image representations. The Bag of Objects representation forms the clearest clusters, as expected (e.g., the average image representation of ‘dog’ correlates with images containing ‘dog’ as a pair like ‘dog + person’ and ‘dog + toilet’). The Softmax representations seem to also exhibit semantic clusters, although to a lesser extent. This can be observed with ‘person’, where the features are not semantically similar to any other groups. The most likely reason is that there is no ‘person’ category in ILSVRC. Also, Place365 and Hybrid1365 Softmax (Figure 3(c)) also showed very strong similarity for images containing ‘toilet’, whether or not they contain ‘dog’ or ‘person’, possibly because they capture scene information. On the other hand, Pool5 features seem to result in images that are more similar to each other than Softmax overall.
The cosine distance matrix between six groups: Three MSCOCO categories and pairwise combinations of the three categories from the training dataset. Each group is represented by the average image feature of twenty-five randomly selected images from the category or combination of categories.

6.2 Transformed representations
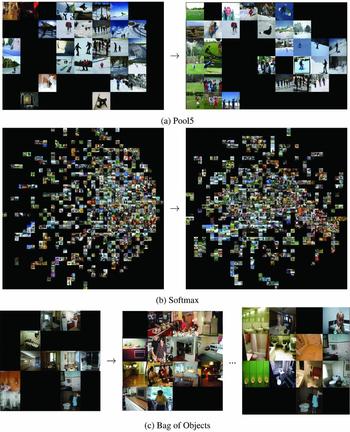
To test the possibility that the RNN conditioned on visual information learns some sort of common ‘visual-semantic’ space, we explore the difference in representations between the initial representational space and the transformed representational space. The transformation is learned jointly as a subtask of IC. To visualize both representational spaces, we use Barnes-Hut t-SNE (van der Maaten and Hinton, Reference van der Maaten and Hinton2008) to compute a 2-dimensional embedding over the test split. In general, we found that images are initially clustered by visual similarity (Pool5) and semantic similarity (Softmax, Bag of Objects). After transformation, linguistic information from the captions leads to different types of clusters.
Figure 4 highlights some interesting observations about the changes in clustering across three different representations. For Pool5, images seem to be clustered by their visual appearance, for example snow scenes in Figure 4(a), regardless of the subjects in the images (people or dogs). After transformation, separate clusters seem to be formed for snow scenes involving a single person, groups of people and dogs. Interestingly, images of dogs in fields and snow scenes are also drawn closer together.
Visualization of the t-SNE projection of the initial representational space (left) versus the transformed representational space (right).

Softmax (Figure 4(b)) shows many small, isolated clusters before transformation. After transformation, bigger clusters seem to be formed – suggesting that the captions have again drawn related images together despite being different in the Softmax space.
For Bag of Objects (Figure 4(c)), objects seem to be clustered by co-occurrence of object categories, for example, toilets and kitchens are clustered since they share sinks. Toilets and kitchens seem to be further apart in the transformed space.
A similar observation was made by Vinyals et al. Vinyals et al. (Reference Vinyals, Toshev, Bengio and Erhan2016) in which the authors observe that end-to-end IC models are capable of performing retrieval tasks with comparable performance to the task-specific models that are trained with ranking loss.
6.3 Generated captions
In this section we provide a qualitative analysis of different image representations and gain insights into how they contribute to the IC task. Bag of Objects led to a strong performance in IC despite being extremely sparse and low-dimensional (80D). Analyzing the test split, we found that each vector consists of only 2.86 non-zero entries on average (standard deviation 1.8, median 2). Thus, with minimal information being provided to the RNN generator, we find it surprising that it is able to perform so well.
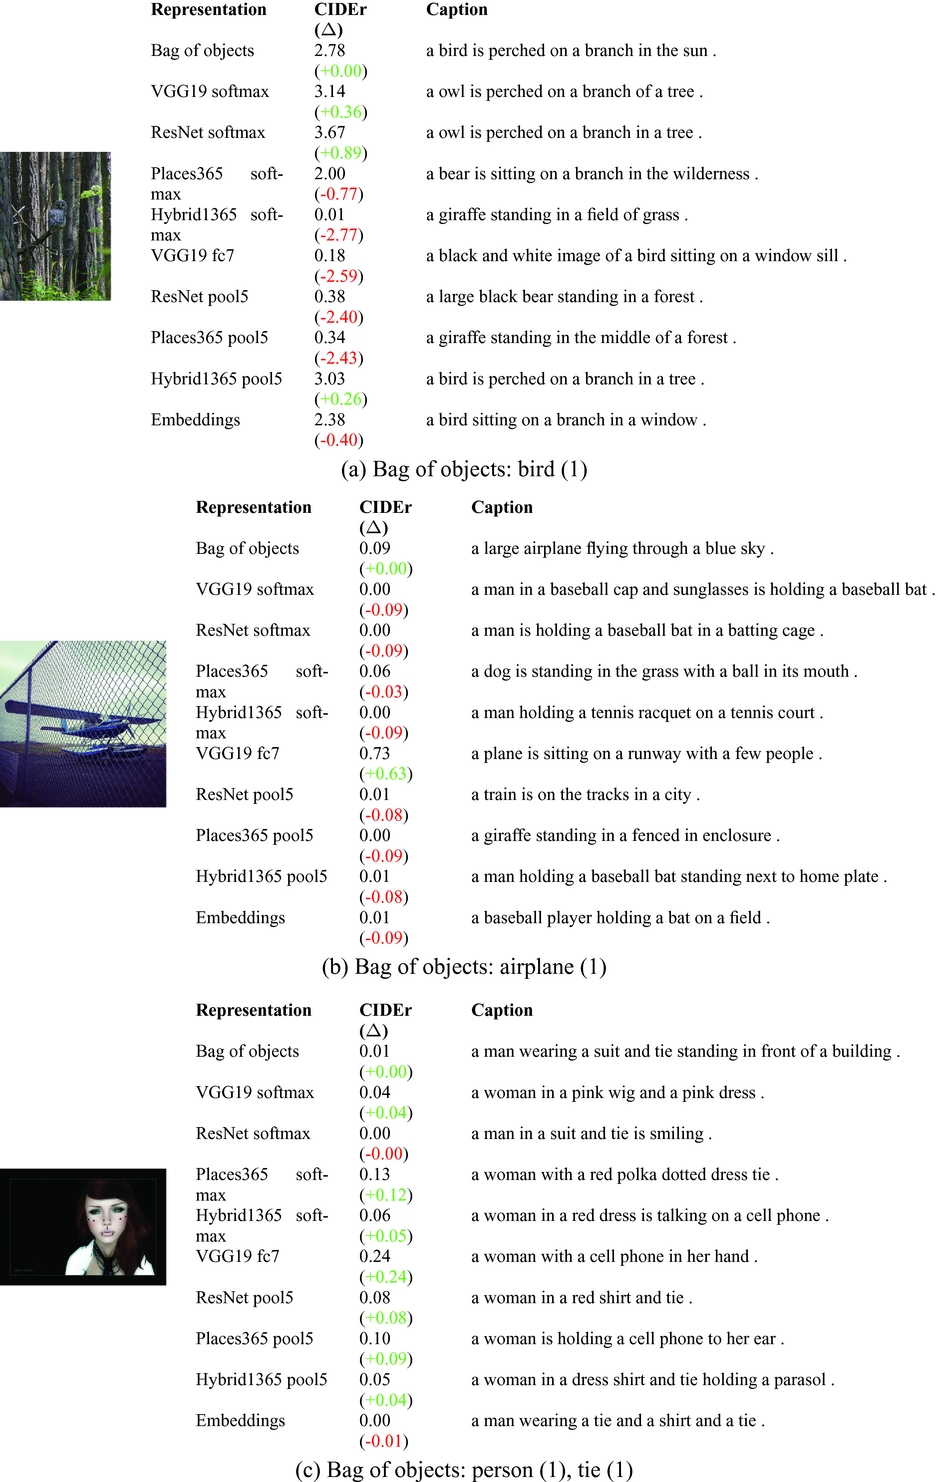
We compare the output of the remaining models against the Bag of Objects representation by investigating what each representation adds to or subtracts from this simple, yet strong model. We start by selecting images (from the test split) annotated with the exact same Bag of Objects representation – which should result in the same caption. For our qualitative analysis, several sets of one to three MSCOCO categories were manually chosen. For each set, images were selected such that there is exactly one instance of each category in the set and zero for others. We then shortlisted images where the captions generated by the Bag of Objects model produced the five highest and five lowest CIDEr scores (ten images per set). We compare the captions sampled for each of the other representations.
Figure 5 shows some example outputs from this analysis. In Figure 5(a), Bag of Objects achieved a high CIDEr score despite only being given ‘bird’ as input, mainly by ‘guessing’ that the bird will be perching/sitting on a branch. The object-based Softmax (VGG and ResNet) models led to an even more accurate description as ‘owl’ is the top-1 prediction of both representations (96% confidence for VGG, 77% for ResNet). Places365 predicted ‘swamp’ and ‘forest’. The Penultimate features on the other hand struggled with representing the images correctly. In Figure 5(b), Bag of Objects suffered from lack of information (only ‘airplane’ is given), the Softmax features mainly predicted ‘chainlink fence’, Places365 predicted ‘kennel’ (hence the dog description), and it is most likely that Penultimate has captured the fence-like features in the image rather than the plane. In Figure 5(c), Softmax features generally managed to generate a caption describing a woman despite not explicitly containing the ‘woman’ category. This is because other correlated categories were predicted, such as ‘mask’, ‘wig’, ‘perfume’ and ‘hairspray’, and for Places365 ‘beauty salon’ and ‘dressing room’. ResNet predicted categories like ‘stethoscope’, ‘suit’, ‘cloak’, where we assume that doctor roles may be male-dominated in the dataset, thus generating ‘man’.
Example outputs from our system with different representations, the sub-captions indicate the annotation along with the frequency in braces. We also show the CIDEr score and the difference in CIDEr score relative to the Bag of Objects representation.

6.4 Uniqueness of captions
Challenges with IC datasets have been well explored in previous work. Karpathy Karpathy (Reference Karpathy2016) perform both word- and syntactic-level analysis on the MSCOCO and Flickr8k datasets and concludes they both lack diversity. This means that most of the captions are generic descriptions and can fit multiple images. This extends directly for our experiments on the IC and MMT datasets.
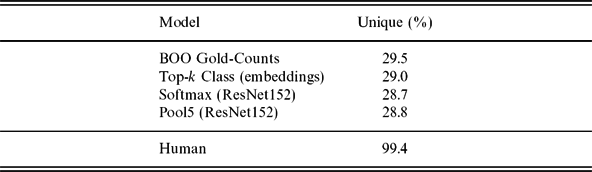
We now turn to the question on the ability of representations to produce unique captions for every distinct image. We use the validation portion of the MSCOCO dataset, which contains 40,504 images and produce captions with four types of image representations. We report the results in Table 3. We observe that in almost all cases, the produced representations are far from unique. In most cases, there is a significant portion of the captions that are repeated. This has also been observed by Devlin et al. Devlin et al. (Reference Devlin, Cheng, Fang, Gupta, Deng, He, Zweig and Mitchell2015) on different test splits, but using retrieval-based and pipeline methods for IC.
Unique captions with beam =1

7 Conclusions
Our experiments probe the contribution of various types of image representations and shed some light on the utility of image representations for vision to language tasks. We observed that a conditional RNN-based language model is capable of making sense of noisy information and correctly clustering the noisy representation in the projected space. However, the task datasets do not reflect the paucity of information content in the image representation and, in most cases, we obtain repeated captions for similar sets of images. Our empirical observations indicate that the direct use of lower-level image features may not be the only way to condition an RNN, and that higher-level, abstract, semantic features may also be beneficial in order to capture the semantic aspects of the images. As future work, we are interested in exploring more complex models that use attention-based architectures and those that exploit latent spaces.