



1 Introduction
Wordlikeness denotes the degree to which a sound sequence is considered typical of words in a language (Bailey & Hahn Reference Bailey and Hahn2001). Native speakers have consistent intuitions about which sound sequences are more wordlike. Not only can they tell which existing sequences sound more like typical words (e.g. English bag /bæg/ is considered more typical than squad /skwɑd/), but they can also make similar judgements for non-words (e.g. bnick /bnɪk/ sounds more wordlike than bdick /bdɪk/). In phonotactic research, one core interest has been the sources of such wordlikeness judgements. Previous literature has shown evidence for various sources of wordlikeness judgements, including phonotactic probability (Gathercole & Martin Reference Gathercole, Martin and Gathercole1996, Coleman & Pierrehumbert Reference Coleman and Pierrehumbert1997, Vitevitch et al. Reference Vitevitch, Luce, Charles-Luce and Kemmerer1997, Dankovičová et al. Reference Dankovičová, West, Coleman and Slater1998, Frisch et al. Reference Frisch, Large and Pisoni2000), lexical neighbourhood density (Greenberg & Jenkins Reference Greenberg and Jenkins1964, Gathercole & Martin Reference Gathercole, Martin and Gathercole1996, Bailey & Hahn Reference Bailey and Hahn2001), and orthotactic probability (Bailey & Hahn Reference Bailey and Hahn2001). ‘Phonotactic probability’ denotes the probability of finding a subpart of the string of segments in a word (e.g. abc in abcde). ‘Neighbourhood density’ is the degree to which a sound sequence overlaps with existing words in a lexicon. ‘Orthotactic probability’ involves graphemes rather than phonemes, and is calculated similarly to phonotactic probability.
Proposals for the modelling of wordlikeness judgements which incorporate these sources include the Syllabic Parser (Coleman & Pierrehumbert Reference Coleman and Pierrehumbert1997), the Generalised Neighbourhood Model (Bailey & Hahn Reference Bailey and Hahn2001), the Phonotactic Probability Calculator (Vitevitch & Luce Reference Vitevitch and Luce2004), the Phonotactic Learner (Hayes & Wilson Reference Hayes and Wilson2008), the Featural Bigram Model (Albright Reference Albright2009), the Simple Bigram Model (Jurafsky & Martin Reference Jurafsky and Martin2019) and the Generative Phonotactic Learner (Bailey & Hahn Reference Bailey and Hahn2001, Futrell et al. Reference Futrell, Albright, Graff and O'Donnell2017). See Daland et al. (Reference Daland, Hayes, White, Garellek, Davis and Norrmann2011) for an overview. Work on wordlikeness judgement has so far focused primarily on segments; studies incorporating suprasegmental features have been relatively limited. Some suprasegmental features, including stress and tone, are used contrastively in languages. Therefore, in order to understand wordlikeness, the factors which determine wordlikeness judgements should include suprasegmental features, in particular for languages where lexical contrasts can be created with suprasegmental features.
Previous work has examined how prosodic features related to stress should be incorporated into phonotactic models (Bird & Ellison Reference Bird and Ellison1994, Coleman & Pierrehumbert Reference Coleman and Pierrehumbert1997, Hayes & Wilson Reference Hayes and Wilson2008, Olejarczuk & Kapatsinski Reference Olejarczuk and Kapatsinski2018). There is previous work on wordlikeness judgements of tone languages which considers only segmental phonotactics, but omits tone. For example, Gong (Reference Gong2017) compares speakers’ acceptability and reaction times on lexical decisions involving systematic and accidental gaps in Mandarin, and considers the role of phonotactic probability and neighbourhood density in predicting the results. It was found that their influence on acceptability was independent from each other, but only neighbourhood density was a significant factor for reaction times. Gong also uses Hayes & Wilson's (Reference Hayes and Wilson2008) Phonotactic Learner, but without considering tone. Gong & Zhang (Reference Gong and Zhang2020) do consider tonal neighbours, i.e. syllables that differ only in tone. In their investigation of lexical neighbours, however, cases with both a segmental difference and a tonal difference were not included, so it is not possible to establish the relative contribution of segments and tones in determining lexical neighbours in Mandarin. Myers (Reference Myers2015) considers segmental phonotactics without tone in Mandarin, focusing on a comparison of the effect of lexical typicality and typological frequency on acceptability judgements. Lexical typicality is defined on the basis of how many lexical syllables in Mandarin share an item's onset consonant, and typological frequency in terms of the number of phoneme inventories that exhibit this consonant across languages. An examination of onset frequency in Mandarin and consonant frequency in the UCLA Phonological Segment Inventory Database (UPSID; Maddieson & Precoda Reference Maddieson and Precoda1989) showed that both typological frequency and Mandarin-specific lexical typicality had effects on which items speakers judged to be more wordlike.
Work incorporating tone includes Myers & Tsay (Reference Myers and Tsay2005), Kirby & Yu (Reference Kirby, Yu, Trouvain and Barry2007) and Shoemark (Reference Shoemark2013). These studies differ from each other in their aims (e.g. eliciting judgements on real words, systematic gaps, accidental gaps, etc.), but a primary goal is to identify the role of phonotactic probability and neighbourhood density in predicting native speakers’ wordlikeness judgements. Myers & Tsay (Reference Myers and Tsay2005) examined the role of neighbourhood density in predicting typicality judgements in Mandarin, and report that the judgements of real Mandarin words can be predicted by neighbourhood density, but that non-words are inversely correlated to neighbourhood density. The focus of Kirby & Yu (Reference Kirby, Yu, Trouvain and Barry2007) is to establish the role of phonotactic probability and neighbourhood density in understanding systematic and accidental gaps in Cantonese. The results show that neighbourhood density plays a major role in predicting wordlikeness judgements. Phonotactic probability also played a role, although there was a lower correlation with wordlikeness. They suggest that this may be because Cantonese does not permit complex onsets and codas, and thus has a much smaller number of possible monosyllables, leading to phonotactic probability being less important. Furthermore, because the possible monosyllables are limited by strict phonotactic restrictions, lexical items occupy a much larger portion of the space of possible monosyllables, resulting in a greater role for lexical density. This proposal is further pursued by Shoemark (Reference Shoemark2013), who argues that strict phonotactic restrictions in Cantonese create a denser phonological network, as a result of which the role of neighbourhood density becomes crucial.
While the findings are mixed, the overall results seem to suggest that neighbourhood density has a greater effect on tone language speakers’ wordlikeness judgements than phonotactic probability. However, the possible ways of incorporating tone into the modelling of wordlikeness judgements have not yet been fully explored. In order to incorporate tone in the modelling of wordlikeness judgements, we need to address two issues: first, how the major determinants of wordlikeness judgements, such as phonotactic probability and neighbourhood density, should be operationalised with tone, and second, how the contribution of these factors to wordlikeness judgement test results should be evaluated. For the first, we survey a variety of methods, and for the second, we provide a Bayesian hierarchical modelling. Both methods and modelling results will be presented using Cantonese as an example of a tone language. §2 introduces the basics of Cantonese phonotactics, and provides an overview of various methods of measuring the two determinants of phonotactic knowledge, i.e. phonotactic probability and neighbourhood density. It shows that both determinants have been primarily limited to the measurement of segments. §3 shows how phonotactic probability and neighbourhood density can be measured when tone is involved. Our methodology shows that ‘classic’ phonotactic probability calculation methods, originally proposed for segments such as n-phone models (see §2.1), can be applied to tone languages, but tonal probabilities need to be incorporated into the calculation by identifying the tonal representation from which we can predict speakers’ wordlikeness judgements. We also show how neighbourhood-density models, such as the Generalised Context Model (Nosofsky Reference Nosofsky1986) and the Generalised Neighbourhood Model (Bailey & Hahn Reference Bailey and Hahn2001), can be constructed when tone is incorporated: they should involve the correct measurements of phonological distances between words, which should incorporate measurements of segmental distances as well as tonal distances and their relative weights. To identify the role of phonotactic probability and neighbourhood density in predicting speakers’ wordlikeness judgements in Cantonese, we run a wordlikeness judgement test, presented in §4. Our results show that phonotactic probability, but not neighbourhood density, is a significant factor in predicting speakers’ wordlikeness judgements in Cantonese. When each syllabic component is considered, probabilities of nucleus and coda are shown to play the most important role in the wordlikeness judgements. We also show that phonotactic probability can predict both gradient items that fall between the two extreme judgements (i.e. between very wordlike and not at all wordlike) and categorically perfect items (very wordlike), but not categorically bad items (not at all wordlike). §5 discuss the implications of the findings of this paper for the study of phonotactic modelling incorporating tone and for the processes involved in wordlikeness judgements when tone is included.
2 Background
2.1 Cantonese phonotactics
Cantonese belongs to the Sinitic branch of the Sino-Tibetan/Trans-Himalayan language family. Phonemically, the language has 19 consonants and 19 vowels (eight monophthongs and eleven diphthongs, as shown in (1a) and (b). In this study, we assume that Cantonese has the six tones in (1c) (Bauer Reference Bauer1985, Matthews & Yip Reference Matthews and Yip2011).
-
(1)


The maximal syllable structure in Cantonese is CVC or CVV, with strict restrictions on which segments and tones are allowed in certain syllabic positions (Yip Reference Yip1989, Cheung Reference Cheung1991, Kirby & Yu Reference Kirby, Yu, Trouvain and Barry2007). The syllabic nucleus may be occupied by a nasal consonant (/m ŋ/). All consonants are allowed in onsets. We treat the secondary articulation /w/ as part of the onset, rather than as part of the nucleus. Only unreleased stops, nasals and high vowels are allowed in codas. We assume that the second vowels in diphthongs are codas, because there are strict phonotactic restrictions on diphthong–coda sequences. For example, falling-sonority diphthongs like /ei/ never co-occur with nasal or oral stop codas, leading Bauer & Benedict (Reference Bauer and Benedict1997: 13–14) to propose that the second component of a diphthong should be considered as part of the coda.
Additional phonotactic restrictions are found in the relations between syllabic positions. For example, the onset and coda of a syllable cannot both be labial (*/pap, mim/) (Yip Reference Yip1989, Cheung Reference Cheung1991, Kirby & Yu Reference Kirby, Yu, Trouvain and Barry2007). Rounded vowels cannot be followed by labial codas (*/-uːm, -ɔːp/), and front rounded vowels cannot be preceded by labial onsets (*/my-, pœː-/). The onset and coda of a syllable with a back vowel cannot both be coronal (*/nɔːn, tuːt/), and coronal onsets cannot be followed by /uː/ or /uːy/ (*/tuː, nuːy/).
A syllable ending in an unreleased stop can only take one of the three level tones in (1c) (˥, ˧, ˨). A syllable with an unaspirated stop or affricate in the onset cannot take e or l, while one with an aspirated stop or affricate in the onset cannot take ˨ (Kirby & Yu Reference Kirby, Yu, Trouvain and Barry2007). Exceptions to these phonotactic regulations are found in loanwords and ideophones (Bauer Reference Bauer1985). A wordlikeness test carried out by Kirby & Yu (Reference Kirby, Yu, Trouvain and Barry2007) showed that Cantonese native speakers’ phonotactic knowledge reflects the systematic and accidental gaps found in the lexicon.
A morphological aspect relevant to the current study is the status of monosyllabicity in Cantonese. The language favours disyllabicity, and many modern Cantonese monosyllabic morphemes are generally not used as independent words, only appearing in compounds (Bauer & Benedict Reference Bauer and Benedict1997).
In addition, various ongoing sound changes in Cantonese are relevant to the current study: merger of initial /n/ and /l/, merger of coda /t/ and /k/, merger of coda /n/ and /ŋ/ (Bauer & Benedict Reference Bauer and Benedict1997) and mergers of k and l, h and i, and e and i (Mok et al. Reference Mok, Zuo and Wong2013).
2.2 Determinants of wordlikeness judgements
Our central question concerns the basis on which native speakers make wordlikeness judgements in tone languages. For example, how do Cantonese native speakers tell that a novel sound sequence with coda /f/ is less wordlike than the one with coda /m/? As mentioned in §1, previous work suggests that there are two primary sound-related determinants of wordlikeness, namely phonotactic probability and neighbourhood density (see the review in Bailey & Hahn Reference Bailey and Hahn2001). Phonotactic probability and neighbourhood-density models are often correlated, but they quantify different aspects of wordlikeness. Phonotactic probability decomposes strings of sounds into substrings, and aggregates the probabilities of those substrings, creating measures of wordlikeness (Albright Reference Albright2009). This is an analytical approach, in that it decomposes words and calculates probabilities. Using metrics which we will discuss in §2.2, neighbourhood-density models count the number of words that are similar in a lexicon to the sound sequence in question, sometimes weighted by some criterion like frequency (e.g. the Generalised Neighbourhood Model of Bailey & Hahn Reference Bailey and Hahn2001). This is a holistic approach, in that the calculation is based on the lexicon as a whole. In the following sections, we first introduce the two determinants, and then consider how they can be measured in tone languages such as Cantonese.
2.2.1 Phonotactic probability
Numerous ways to compute phonotactic probability have been proposed. These methodological decisions can be seen as reflecting ‘researcher degrees of freedom’ (Simmons et al. Reference Simmons, Nelson and Simonsohn2011, Roettger Reference Roettger2019), which can critically affect the results. Although the various methodological approaches have the goal of generating good predictors of wordlikeness judgements (or performance on some other experimental task, such as spoken word recognition or non-word repetition), and are often quite strongly correlated, there is considerable variation in the underlying philosophy. Here we identify three main aspects in which the implementation of phonotactic probability may vary: (a) types of probabilities (§2.2.1.1), (b) methods of estimating probabilities (§2.2.1.2) and (c) methods of aggregating estimated probabilities (§2.2.1.3).
2.2.1.1 Type of probabilities
Phonotactic probability is generally calculated over n-phones of segments, where n is the length of the substring of segments considered. A uniphone is a single segment, a biphone consists of two contiguous segments, etc. The largest substring usually considered in phonotactics studies is the triphone. For Cantonese, when segment sequences are considered, uniphone to triphone calculations are straightforward, as the maximal syllable structure is CVC or CVV, and only one phoneme is allowed in each syllabic position. Some other models, rather than examining the probabilities of n-phones directly, consider the probabilities of n-phones on the basis of natural classes of phonemes, as well as the probabilities of individual phonemes given the natural class (Albright & Hayes Reference Albright and Hayes2003, Albright Reference Albright2009). Hybrid models also exist, generally based on syllable structure. The ‘syllable part’ approach of Bailey & Hahn (Reference Bailey and Hahn2001) computes probabilities over the onset, nucleus and coda of a syllable, each of which may vary in length in a language such as English. Similarly, the ‘syllable rhyme’ approach computes probabilities over onsets and rhymes, calculating the probabilities of onsets and rhymes as single units, and treating them as independent. For Chinese, it has sometimes been argued that there is no need to decompose the rhyme into nucleus and coda; instead, the rhyme can be treated as a single unit, the ‘rhymeme’ (Chao Reference Chao1934, Light Reference Light1977). The distinction between rhyme and rhymeme is important for the analysis of different syllables in different Chinese dialects, but for the purpose of our paper, they are comparable. If a rhymeme or rhyme is assumed to be a single unit, the syllable part approach cannot be pursued, and the syllable rhyme approach must be used. These issues do not arise in Cantonese, which allows only one phoneme in each syllabic position. An important issue in measuring phonotactic probability in Cantonese is determining the position of tone in relation to onset, nucleus and coda. We discuss this issue further in §2.3.
Once we determine the representation of syllable structure, the next step is to compute probabilities within a syllable. Two types of probabilities are relevant. First, ‘positional probability’ is the probability of a segment or n-phone appearing at a certain position in a word, for example the probability that the phone /a/ is the second segment in a word, or that the biphone /pl/ occupies the second and third segmental positions in a word. ‘Transitional probability’ is the probability of a segment appearing given the n−1 previous segments (where n = 2 for biphones, n = 3 for triphones, etc.) Word boundaries (#) are often considered ‘segments’ in these approaches, so that the probability distribution of the ‘actual’ first sound in a phoneme sequence is its conditional distribution given the first ‘segment’, namely the word boundary. Due to the restriction in Cantonese allowing only a single phoneme in each syllabic position, measuring positional and transitional probabilities of Cantonese segmental sequences is straightforward. As before, the issue in this approach is to determine the position of tone in relation to phonemes.
2.2.1.2 Methods of estimating probabilities
The probabilities themselves are concepts (or ‘parameters’, in statistical terms) that are unknown, and thus must be estimated using a corpus. This estimation is independent of the phonotactics of individual languages, and estimating probabilities with or without tone is not an issue here. Approaches have differed with respect to the estimation methods used. One popular method, especially among psycholinguists, is to use log frequencies in the computation of phonotactic probability (Jusczyk et al. Reference Jusczyk, Luce and Charles-Luce1994, Vitevitch & Luce Reference Vitevitch and Luce2004). To calculate the positional probability of an n-phone, for instance, the log frequency of that n-phone in a certain position is divided by the log of the total number of words that contain the n-phone in the position; to calculate the transitional probability of an n-phone, the log frequency of the n-phone is divided by the log of the total number of words where the first n−1 segments of the n-phone appears. The underlying assumption is that log frequencies are better measures of ‘perceived’ frequencies than raw frequencies.
A second approach is to use maximum likelihood estimation in calculating the probabilities (e.g. Albright Reference Albright2007, Reference Albright2009). Here, raw counts are used instead of log frequencies in the numerator and denominator; otherwise, the calculations are identical to those in the log-frequency approach. Some probabilities are likely to be zero, due to accidental or systematic gaps.
A third approach attempts to deal more adequately with such zero probabilities. It modifies the maximum likelihood estimation by adding a smoothing parameter to avoid overfitting (e.g. Dautriche et al. Reference Dautriche, Mahowald, Gibson, Christophe and Piantadosi2017; see also Jurafsky & Martin Reference Jurafsky and Martin2019 for a more detailed description of the method as applied to word n-phones). In methods that use log frequencies, zero counts are particularly problematic, as they would result in undefined log frequencies and hence undefined probability estimations. Some methods using log frequencies can deal with issues of zero counts, though in somewhat ad hoc ways: for example, Vitevitch & Luce's (Reference Vitevitch and Luce2004) phonotactic probability replaces the undefined probabilities for unattested n-phones, which have log 0 in the numerator, with 0 probabilities.
A further question arises, whether the frequencies used should be based on type frequencies or token frequencies (Daland et al. Reference Daland, Hayes, White, Garellek, Davis and Norrmann2011, Richtsmeier Reference Richtsmeier2011, Denby et al. Reference Denby, Schecter, Arn, Dimov and Goldrick2018). The former is counted over an entire lexicon, whereas the latter can be computed using a frequency wordlist or a corpus.
2.2.1.3 Aggregating estimated probabilities
Once the individual probabilities have been estimated, they have to be combined. As with estimation, the methods of combining the probabilities are independent of the involvement of tone. There are two main ways of combining the estimated probabilities into single measures of phonotactic probability: taking the sums (i.e. adding probabilities) or taking the products (i.e. multiplying probabilities). Note, though, that simply adding or multiplying probabilities may produce a measure that is not a true probability. For both methods, many variations exist. First, the probabilities may be logged before being combined, they may be combined before being logged or they may not be logged at all. (Note that the sum of the log of the probabilities is the same as the logs of the products.) Second, the probabilities may be normalised to account for word length; the arithmetic mean of the probabilities may be taken if we are summing the probabilities, and the geometric mean if we are multiplying them. Many of these methods are discussed in Bailey & Hahn (Reference Bailey and Hahn2001) and Vitevitch & Luce (Reference Vitevitch and Luce2004).
2.2.2 Neighbourhood density
The other major predictor of wordlikeness judgements is neighbourhood density, i.e. the degree to which an item under consideration resembles other items in the lexicon. Like phonotactic probability, neighbourhood density can be measured in many different ways. The simplest and most common measure is the number of lexical neighbours, where two words are neighbours if one can be obtained from the other by adding, deleting or changing one segment. For example, /kæt/ is a neighbour of /kæts/, /æt/ and /bæt/. This is the method used in Kirby & Yu (Reference Kirby, Yu, Trouvain and Barry2007) to measure neighbourhood density in Cantonese. In this approach, a neighbour is a categorical concept: two words are either neighbours or they are not. On this assumption, counting lexical neighbours with tone does not differ from counting lexical neighbours without tone. In Cantonese, for instance, /kaː˥/ is a neighbour of /kaːk/, /kʰaː˥/, /kaːn˥/ and /saː˥/.
A more sophisticated measure of lexical neighbourhood allows for gradience. For example, we would expect that /kæt/ is a closer neighbour of /kæts/ than of /bræts/, but also that it is closer to /bræts/ than to /brɪts/. To arrive at such ‘gradient’ neighbourhood models, we need to construct phonological distance measures for the exact distances between words. The literature on such measures is large, primarily for segments (see Kessler Reference Kessler2005 for an overview). The most common method is first to determine the distances between two corresponding phonemes, then to combine them in order to find the distances between phoneme strings. To measure the distance between two phonemes, Bailey & Hahn (Reference Bailey and Hahn2001) use Frisch et al.'s (Reference Frisch, Broe and Pierrehumbert1997) definition of natural class distance in (2), in which the number of non-shared natural classes between two phonemes is divided by the total number of natural classes, i.e. shared natural classes + non-shared natural classes, across the two phonemes. In other words, the distance between two phonemes is defined by the proportion of non-shared natural classes that the phonemes belong to.
-
(2)
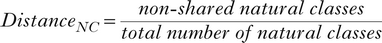
The Levenshtein distance (Jurafsky & Martin Reference Jurafsky and Martin2019) between the two phoneme strings is then computed: an algorithm is used to find the way of adding a segment, deleting a segment or substituting one segment for another that minimises the ‘cost’ of these operations, where cost is the distance between the two phonemes involved. The distance between two phoneme strings then becomes the average cost of the operation. When tone is involved in the distance calculation, the distance between two tones should be included in the calculation. We elaborate this point in §2.3.
Once the distance measure between two words, d(wi, wj), has been constructed, incorporating phoneme distances and tone distances, it is used to measure the lexical density of words. One approach to this is Nosofsky's (Reference Nosofsky1986) Generalised Context Model (GCM), which is an exemplar model in which the categorisation of a lexical item is based on its similarity towards all relevant stored exemplars, i.e. lexical neighbours. In the GCM, the neighbourhood density of a word is calculated by summing the exponents of the negative distance of every word in the lexicon from the word itself. In (3), L denotes the lexicon, i.e. the set of all words in the language. Because of the negation sign, words that are far away from the word under consideration have less weight than words that are close to the word under consideration.
-
(3)
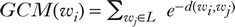
In order to include tone in the measurement of the distance of a word from other words, we need to identify the relative contribution of segmental and tonal distance in determining the distance between two words. In §3.2 we discuss methods of identifying the relative weighting of segmental and tonal distances.
Although the GCM does consider gradient similarity of all relevant words in the lexicon, one disadvantage is that lexical frequencies are ignored. To address this issue, Bailey & Hahn (Reference Bailey and Hahn2001) propose the Generalised Neighbourhood Model (GNM), where the contribution of a word depends not only on its distance to the word under consideration, but also on its frequency of occurrence. In the GNM, the frequency of a word's occurrence contributes to its ‘weight’, as shown in (4), where log frequency of occurrence is denoted by fj, and A, B, C and D are free parameters. These parameters give the relative contribution of the quantity weighted by the square of the log frequency (A), the quantity weighted by the raw frequency itself (B), the non-frequency weighted (i.e. GCM) quantity (C), along with a ‘sensitivity parameter’ (D), which is multiplied to each distance, as in (4).
-
(4)
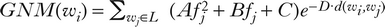
Generalised neighbourhood modelling with tone is similar to generalised context modelling with tone, except that the relative weight of tones and segments, which incorporates frequency information, is included in the distance measure. Due to the additional parameters, it is mathematically more complicated than the GCM, but the core components needed for generalised neighbourhood modelling with tone are similar to those for generalised context modelling: we need to identify both segmental and tonal distances and their relative contributions in determining the distances between words.
As an example of GCM and GNM applications to phoneme strings without tone, consider a miniature language which has five words taken from English, strata /streɪtə/, spray /spreɪ/, star /stɑr/, tar /tɑr/ and states /steɪts/. The words appear in the corpus 8, 15, 16, 5 and 20 times respectively. We consider the problem of determining the neighbourhood density of /stɑr/. The distance between /stɑr/ and the other four words are shown in Fig. 1 on the lines joining them with /stɑr/.
The distances between star /star/ and four other English words, with their frequencies (in parentheses).

The neighbourhood density of star /stɑr/ under the GCM and under the GNM is given in (5a) and (b) respectively. To build generalised context and generalised neighbourhood models with tone, the measurement of the distance of /stɑr/ from the other words in Fig. 1 (i.e. 1, 2, 3 and 4) should incorporate tonal distances, and the log frequency of occurrence, fj, and the four parameters in (4), A, B, C and D, should be informed by a lexicon which include tonal information.
-
(5)

As we will discuss below, our experimental design is constructed with reference to what we call the ‘number of neighbours’ measure (cf. Kirby & Yu Reference Kirby, Yu, Trouvain and Barry2007), as well as the GCM and GNM models. In §3, we show how these methods can be adapted to incorporate tone in calculations, using Cantonese as a case study.
3 Phonotactic modelling with tone
3.1 Phonotactic probability
As noted in §2, there are multiple methods for computing phonotactic probability, involving a large number of decisions concerning the type of probabilities, the estimation methods and the methods of aggregating the probabilities. For the computation of phonotactic probability, a guiding principle is to create a theoretically well-grounded measure of the joint probability of the entire syllable, including tone.
In our study of Cantonese, we use traditional biphone probabilities, as this method provided the best results in Kirby & Yu's (Reference Kirby, Yu, Trouvain and Barry2007) study. It should be noted that the use of uniphone or triphone probabilities would not be very different, because Cantonese allows only one segment or tone in each syllabic position. Biphone probabilities are calculated from the Hong Kong Cantonese corpus (Luke & Wong Reference Luke, Wong, Tsou and Kwong2015) on the basis of token frequency, which provided a better performance than a calculation based on type frequency in Kirby & Yu.Footnote 1 We adopt the syllable part approach, which computes probabilities over the onset, nucleus and coda of a syllable, rather than one which assumes a rhyme as a single unit, such as the syllable rhyme and rhymeme approaches (see §4). As Cantonese syllable structure only allows one phoneme in each of the syllable part slots (assuming that the second vowels in diphthongs are considered to be codas), we compute P(onset) – conceptually equivalent to P(onset∣#) for models that consider word boundaries – P(nucleus∣onset) and P(coda∣nucleus), then multiply the three together to give P(segments).Footnote 2 In other words, P(segments) is calculated by multiplying the probabilities of the n-phones of the syllabic components. Additive smoothing is performed to prevent zero probabilities, since this would result in an undefined log-probability (see §2.2). For smoothing, we simply add 1 to all counts for simplicity, and do not pursue more complicated methods.
To calculate probabilities of tone given the string of segments, we compute P(tone∣segments) using a multinomial logistic regression model with the nnet package (Ripley Reference Ripley2016) in R (R Core Team 2020). We assume here that the probability of a syllable having a certain tone is dependent on the identities of all segments in the syllable. Dummy variables representing onset, nucleus and coda are included in the model; we exclude interaction effects, to ensure that the probability of a tone can also be calculated for unattested segment strings. The probability of a monosyllable is then the joint probability of segments with tone conditioned on the segments: P(segments) × P(tone∣segments). Then we take the natural logarithm of this joint probability as a linear predictor of wordlikeness in our model. As an alternative, we also consider P(tone∣coda) rather than P(tone∣segments), because, as noted in §2.1, there is a strong co-occurrence restriction in most Cantonese words whereby final /p t k/ can only co-occur with ˥, ˧ and ˨ (Bauer & Benedict Reference Bauer and Benedict1997). We also consider P(tone∣onset), because Cantonese exhibits restrictions on the relation between onset and tone: syllables with unaspirated stops or affricates in onset do not take e or l, while syllables with aspirated stops or affricates in onset do not take ˨ (Bauer & Benedict Reference Bauer and Benedict1997). Three other conceptually possible probabilities are also tested: tone conditioned on nucleus, tone not conditioned on segments and segments without tone. This gives the six log-probability measurements shown in (6), each of which incorporates different assumptions with regards to the relationship between tone and segments.
-
(6)

3.2 Neighbourhood density
As mentioned in §2.2, counting the number of neighbours in tone languages is straightforward if tonal neighbourhood is assumed to be a categorical concept. For example, /khɐl/ is a neighbour of /khɐ˨/ (tone substitution), just as it is of /khiːl/ (segment substitution), /ɐl/ (segment deletion) and /khɐt˺l/ (segment addition). On the other hand, modelling neighbourhood density in tone languages using GCM or GNM is more complicated, mainly because (a) tonal distance should be measured and incorporated into the modelling, and (b) the relative contributions of segmental and tonal distances should be identified in determining the distance between words.
We first demonstrate how to construct distance metrics between two words, d(wi, wj) in the notation introduced in §2.2, including tonal distance. Instead of calculating segmental Levenshtein distances (Jurafsky & Martin Reference Jurafsky and Martin2019), we adopt a method that has been proposed for the measurement of phonological distance in Cantonese which takes both segments and tones into account. Do & Lai (forthcoming) put forward a proposal for how phonological distances between words should be measured when tone is involved, using Cantonese as an example. In their study, the distance between segments and tones was first calculated separately, assuming particular phonological representations of segments and tones. They collected judgement data on the phonological distance of pairs of items consisting of a real word and a nonce word, such as /sɛːe/ ‘snake’ and /thɛː˨/, by asking participants to indicate how similar the two items were on a scale from 0 (totally different) to 100 (identical). Various models were compared with the participants’ data to establish the optimal way to measure segmental and tonal distances. For segmental distance, Do & Lai found that a distance measure represented by a multivalued, mostly articulatorily based featural representation like that in Ladefoged (Reference Ladefoged1975) worked best. There are various ways of calculating segmental distances between such representations; the one that worked optimally in their study employed Hamming distance (Nerbonne & Heeringa Reference Nerbonne and Heeringa1997). Hamming distance measures the number of features that are not shared between two phonemes, and divides them into the total number of phonological features, i.e. shared and non-shared phonological features. The current study adopts Hamming distance measures for multivalued representations to measure segmental distances in Cantonese. For tonal distance, Do & Lai found that the Hamming distance measure, together with a representation of tone in terms of contour and offset, was optimal in predicting native speakers’ judgements of phonological distance. This result echoes the results of perception studies of Cantonese, where tonal contours have been found to be an important perceptual cue (e.g. Xu et al. Reference Xu, Gandour and Francis2006, Khouw & Ciocca Reference Khouw and Ciocca2007), which in fact is more important than tonal heights (Gandour Reference Gandour1981). The current study also adopts the same distance measure and tonal representations. The six tones of Cantonese are represented in (1c) above, using the contour-offset representation. The distance between the tones was 1 if both contour and offset were different (e.g. ˥ vs. e), 0.5 if either contour or offset was different (e.g. ˥ vs. k) and 0 if the two tones were the same.
Second, once we identify optimal distance measures for segments and tones, we must establish how the two measures should be combined. One straightforward way is to simply add them together. However, this does not allow for different weightings for segments and tones, for which there is experimental evidence from perception studies (Cham Reference Cham2003), word-recognition studies (Cutler & Chen Reference Cutler and Chen1997, Keung & Hoosain Reference Keung and Hoosain1979), word-reconstruction studies (Wiener & Turnbull Reference Wiener and Turnbull2016) and phonological distance studies (Yang & Castro Reference Yang and Castro2008, Do & Lai Reference Denby, Schecter, Arn, Dimov and Goldrickforthcoming). To model empirically informed weights of segments and tones, we chose the weights that can predict native speakers’ phonological distance judgements in Do & Lai's study, using the fixed intercept and coefficients for segmental and tonal distance.
The computation of a generalised context model is straightforward insofar as we can identify segmental and tonal distances and their relative weights. However, a generalised neighbourhood model presents additional complications. This is mainly because generalised neighbourhood modelling incorporates ‘frequency’, which is ignored in generalised context modelling. As mentioned in §2.2, there are four free parameters in Bailey & Hahn's (Reference Bailey and Hahn2001) model, A (the quantity weighted by the square of the log frequency), B (the quantity weighted by the raw frequency itself), C (a free parameter that gives the relative contribution of the non-frequency weighted quantity) and D (a sensitivity parameter that is multiplied to each distance). Bailey & Hahn mention that they computed these coefficients in GNM by regression. However, as they do not specify the details of the implementation, we devised our own method of estimating the parameters. In our modelling, to simplify calculations, we fixed sensitivity parameter D at 1 but inferred A, B and C empirically from the results of our wordlikeness test. This greatly simplifies the process of finding the values of A, B and C, as a GNM without a sensitivity parameter will become a linear combination of three quantities – the sum of the exponent of the negative distance from each word to the word under question, weighted by the square of the frequency, weighted by frequency and unweighted (i.e. GCM) respectively – with A, B and C as coefficients. Frequency weighting was based on token frequencies from Luke & Wong (Reference Luke, Wong, Tsou and Kwong2015). Given frequency information and segmental and tonal distances, as well as their relative weights, we need wordlikeness judgement data from native speakers. §4 discusses how we collected the wordlikeness judgement data from which we build the GCN and GNM models in §5.
4 Wordlikeness judgement test
In this section we test the roles of phonotactic probability and neighbourhood density in predicting Cantonese native speakers’ wordlikeness judgements when tone is incorporated. In our experiment, participants were asked to judge how wordlike given words are on a scale from 0 (not at all wordlike) to 100 (very wordlike).Footnote 3
4.1 Test
4.1.1 Participants
The experiment was designed using Qualtrics online survey software,Footnote 4 and was distributed through social media. Self-reported native speakers of Hong Kong Cantonese participated in the experiment and received $100 HK compensation upon the completion of the experiment. In total, 145 participants, aged between 18 and 60, were recruited. 44 participants did not complete the experiment, and four provided more than three incorrect answers out of twelve in the pre-test (see §4.1.3 for the specifics of the pre-test), and thus did not proceed to the main test. Data from the participants who did not complete the test or who did not pass the pre-test were excluded from the analysis. Consequently, data from 97 participants were analysed.
4.1.2 Design
In creating the experimental stimuli, we first calculated phonotactic probability and neighbourhood density following the measurement decisions presented in §3 for every logically possible combination of possible onsets, nuclei, codas and tones in Cantonese. The list was shortened to exclude the real words found in Luke & Wong (Reference Luke, Wong, Tsou and Kwong2015). We then chose 288 items from the list, including all possible onsets, nuclei and codas, ensuring that every single possible phoneme appeared in the stimuli list in each syllabic position. After the list was created, the second author examined the items to identify any possible Cantonese syllables that had not been present in the original corpus, and created corresponding non-existing syllables by modifying one syllabic component. For example, the string /kɛːp˺˨/ ‘press from both sides (colloquial)’ was replaced by non-existent syllable /kɛːt˺˨/. The list of stimuli is provided in Appendix A.
The stimuli were recorded by a Cantonese native speaker from Hong Kong. An examination of the speaker's natural speech revealed that it did not display the ongoing sound changes in Cantonese mentioned in §2.1. The stimuli were recorded in a sound-attenuated booth at the University of Hong Kong with a Marantz PMD661 MKII handheld solid state recorder and a Sennheiser MKE2-P-K clip-on Lavalier condenser microphone. All stimuli were recorded in .wav format in mono with 16 bit-resolution at a sampling rate of 44.1kHz, and were normalised using the built-in command in Praat (Boersma & Weenink Reference Boersma and Weenink2019).
4.1.3 Procedure
The experiment began with an introduction and an electronic consent form, followed by a demographic questionnaire related to participants’ language background. Participants had to complete a pre-test before entering the main experiment session. The pre-test was in the form of AXB test, to ensure that participants could perceptually distinguish between the segments and tones affected by the ongoing mergers discussed in §2.1. The AXB test also included items to check whether they could distinguish between tones k and l, ˧ and ˨, and e and ˨, which, as noted in §2.1, are merging for some Cantonese speakers. If participants submitted more than three incorrect answers to the twelve questions, the experiment stopped.
In the main session, which lasted on average 40 minutes, the experimental items were randomly presented to participants, one at a time. Participants were asked to rate the probability of each item being a Cantonese word on a scale from 0 to 100, using a slider. They were allowed to listen to each item multiple times.
4.2 Results
4.2.1 Data exploration
Before turning to modelling and statistical inference, we first give a descriptive analysis of the data. Plots of the wordlikeness-judgement data against the two assumed determinants, phonotactic probability and neighbourhood density, are provided. They show the proportion of categorically ‘wordlike’ judgements (henceforth ‘1 judgements’) and the proportion of categorically ‘not at all wordlike’ judgements (‘0 judgements’), as well as the average gradient judgement for each of the predictors that we use. Scatterplots of the raw data are given in Appendix B.
In Fig. 2a, the x-axis denotes log-probabilities of test items and the y-axis denotes wordlikeness judgements converted to the range of 0 to 1 by dividing the results from the experiment by 100, for ease of interpretation. For illustration, we chose a version of log-probabilities where tone is conditioned on all segments, but the graphs would be very similar across different types of log-probabilities. For log-probabilities, there is a clear relationship with the wordlikeness judgements, as seen in Fig. 2a. Aside from an outlier on the far left, the higher the log-probability, the greater the chances that participants rate wordlikeness as 1 or close to 1. In particular, ratings above 0.5 are quite sparse for log-probabilities below ―23, and become much more common for higher values, especially above around ―17. Ratings below 0.5 are quite rare for the three stimuli with the very highest log-probabilities. However, aside from the three items with the highest log-probabilities, the rest of the items all have a similar number of 0 rating judgements. There are also stimuli, such as those around ―23 log-probabilities, where there are frequent ratings of 1, but ratings in relatively higher regions are still sparse. This suggests that there is a great degree of variation among the participants’ wordlikeness judgements, and categorical 0 and 1 judgements and gradient judgements may not be produced by the same process; in particular, 0 judgements do not seem heavily affected by log-probabilities, whereas, at least visually, the trend is clearer for gradient judgements and 1 judgements.
Plots of the proportion of 0 judgements (triangles), the proportion of 1 judgements (circles) and average gradient judgement (squares) against (a) log-probability; (b) number of neighbours; (c) GCM values; (d) frequency-weighted GNM values; (e) square frequency-weighted GNM values.

The descriptive results for neighbourhood density measures are provided in Figs 2b–e. Each figure shows the judgement data against the number of neighbours (NN; Fig. 2b), the GCM (Fig. 2c) and the GNM (Figs 2c–e) respectively. As shown in Fig. 2b, 0 judgements (not at all wordlike) tend to be somewhat more common on the left side of the graph, in the lower NN regions. However, items with a higher NN were not clearly judged to be better, indicating that NN has no predictive power for the wordlikeness judgements.
When the neighbours’ gradience is taken into account, there is no clear pattern for any of the three terms A (the quantity weighted by the square of the log frequency), B (the quantity weighted by the raw frequency itself) and C (the unweighted GCM quantity). We start by examining the GCM value (coefficient C). As in Fig. 2c, for example, 0 and 1 judgements (the categorical judgements) tend to be concentrated in the middle of the GCM values. For intermediate judgements, there are items skewed towards high and low values across the entire x-axis. The addition of frequency weighting does not seem to create clear patterns either. Figure 2d gives judgements for raw frequency (coefficient B). For intermediate judgements, items in the lowest part of the graph tend to disfavour 1 judgements. But there is no clear tendency for the rest of the graph. Figure 2e shows the data for the square frequencies (coefficient A).We see a similar pattern, whereby items with values below around 50 disfavour 1s, but there are no very clear tendencies either for 0 judgements or for the judgements of other values.
Descriptive data thus seem to suggest that log-probability is relevant to wordlikeness judgements in Cantonese, but the effect of neighbourhood density, if present at all, is weak, both on categorical measures like NN and on gradient measures like the GCM and the GNM. The modelling results in §4.3 concur with these descriptive observations.
4.3 Modelling
Our modelling decisions were made on the basis of the descriptive data in §4.2. As noted above, there is a clear tendency for categorical judgements to be different from gradient judgements. For example, log-probability appears to have little effect on 0 judgements, but does seem to display a correlation with gradient judgements. Its role in 1 judgements is less clear, but items with low log-probability were rarely rated very wordlike. Based on the observations showing the distinctive patterns among 0 judgements, 1 judgements and gradient judgements, we chose a model that allows us to separate the three types. Specifically, we employ a mixed-effect zero-one-inflated beta regression model (ZOIB; Ospina & Ferrari Reference Ospina and Ferrari2012), which is similar to a beta regression model, but with extra components that allow the response to take on values of 0 or 1, modelled separately from judgements between 0 and 1. More familiar models would not be appropriate for modelling our data. For example, linear regression models assume the residuals to be normally distributed, which would be difficult to justify in the current case, because of the multimodality prevalent throughout the data, clearly seen in the scatterplots of the raw data in Appendix B. Beta regression models only cover the open interval (0, 1), and to use beta regression we would need to artificially turn categorical judgements into values such as 0.001 and 0.999. ZOIB is more appropriate for the current data type. It is an ‘inflated’ regression model, in that the distribution of the dependent variable is assumed to contain frequent 0s and 1s, which is consistent with our data. The ZOIB model was fitted using the brms package in R (version 2.13.0; Bürkner Reference Bürkner2017a, Reference Bürknerb), which employs Bayesian inference. We use a Bayesian analysis because most implementations of ZOIBs are Bayesian. Additionally, brms is the most accessible package for modelling ZOIBs that we are aware of, as it makes use of a syntax very similar to the familiar lme4 package. Moreover, Bayesian analyses allow us to put weakly informative priors on the coefficients, which allows easier convergence in the optimisation process. Details of the model settings and prior choices are given in Appendix C, along with an explanation of the basics of the ZOIBs.
Our modelling decision so far has been empirically driven. It may seem to go against some other empirical findings that both occurring words and nonce words lie on a continuum of acceptability (e.g. Coleman & Pierrehumbert Reference Coleman and Pierrehumbert1997, Bailey & Hahn Reference Bailey, Hahn, Gernsbacher and Derry1998, Hay et al. Reference Hay, Pierrehumbert, Beckman, Local, Ogden and Temple2003, Shademan Reference Shademan2006, Hayes & Wilson Reference Hayes and Wilson2008, Albright Reference Albright2009) and against the claim about the gradient nature of phonotactic well-formedness (Chomsky & Halle Reference Chomsky and Halle1968, Clements & Keyser Reference Clements and Keyser1983, Myers Reference Myers1987, Borowsky Reference Borowsky1989). Thus, if we accept that the grammar plays a role in wordlikeness judgements (Berent et al. Reference Berent, Shimron and Vaknin2001, Frisch & Zawaydeh Reference Frisch and Zawaydeh2001), as opposed to treating the gradient judgements as the product of mere performance (see the studies reviewed in Schütze Reference Schütze1996 and Hayes Reference Hayes, Dekkers, van der Leeuw and van de Weijer2000), we must establish the theoretical significance of our data, in order to justify the choice of the ZOIB model. Specifically, we need to check whether the grammar that generates wordlikeness judgements is both gradient and categorical in nature. Gorman (Reference Gorman2013) argues that the large number of gradient judgements reported in previous literature may not be due to the gradient nature of wordlikeness systems. Rather, the grammar may consist of categorical and gradient components, with gradient judgements being observed more frequently due to the nature of gradient rating tasks. More direct evidence showing both the categorical and the gradient nature of the grammar comes from Coetzee (Reference Coetzee and Parker2009), which tested wordlikeness judgements from Hebrew and English speakers. Two types of tests were conducted, a wordlikeness rating test on a gradient scale and a wordlikeness test which forced participants to compare the well-formedness of items. The results showed that grammatical and ungrammatical items were rated categorically in a wordlikeness rating test, but the comparative test elicited gradient wordlikeness distinctions from the participants. The results suggest that there are two independent cognitive processes involved in wordlikeness judgements, and that speakers use their grammar in both gradient and categorical ways. It may not be the case that both processes are used in all types of wordlikeness tasks, but, crucially, the nature of the grammar that generates wordlikeness judgements is not only gradient, but also categorical, supporting the choice of the ZOIB model.
With respect to the modelling decision on syllabic structure, recall that there are two possible options; one is the syllable part approach (Bailey & Hahn Reference Bailey and Hahn2001), which decomposes a syllable into onset, nucleus, coda and tone, and the other is the syllable rhyme approach, which decomposes a syllable into onset, rhyme and tone. If a syllable rhyme approach has psychological reality for Cantonese speakers, we would expect that syllables with unattested rhymes would tend to be judged to be not at all wordlike. This was not borne out in the present data. Consider the scatterplot in Fig. 3, which shows the relationship between log-probabilities (with tone dependent on all segments).
Scatterplot of log-probability against wordlikeness, depending on whether rhymes are attested. The size of the circles indicates the number of items at that log-probability value.

Items with unattested rhymes were overall rated less wordlike than items with attested rhymes. However, items with unattested rhymes have comparable judgement distributions to those with attested rhymes in the mid log-probability range, i.e. between ―25 and ―15, and many of the grey circles have a fair number of responses judging the items to be categorically wordlike. Based on this observation, we decided not to adopt a syllable rhyme analysis; rather, we pursue a syllable part analysis.
4.3.1 Comparison between phonotactic probability and neighbourhood-density measures
The ZOIB model we constructed was fitted using the combined measures of phonotactic probability and neighbourhood density. This enabled us to identify their relative contributions in predicting the wordlikeness judgements. We fitted the models using each of possible pairings of phonotactic probability measures in (6) above (six measures: log-probabilities with tonal probability conditioned on (a) onset only, (b) nucleus only, (c) coda only, (d) all segments, (e) tonal probability unconditioned on segments, (f) no tonal component) and three neighbourhood-density measures (NN, GNM and GCM), along with models that only have phonotactic probability measures (six in total) or only have neighbourhood-density measures (three in total). In total, there were 27 models, i.e. 6 × 3 combined models + 6 phonotactic probability models + 3 neighbourhood-density models. We then compared the model fits using the Widely Applicable Information Criterion (WAIC; Vehtari et al. Reference Vehtari, Gelman and Gabry2017), an approximation of the Akaike Information Criterion, which is used as a measure of models’ out-of-sample predictive power, i.e. of how good the model will be at predicting data beyond a particular sample.
The full ZOIB model in principle includes population-level coefficients for the predictors, along with item-level and participant-level random intercepts and participant-level random slopes for all predictors. Due to the limitation of modelling capacity, it was impossible to fit the full ZOIB model for all the combinations we tested, so we initially fitted all 27 models with random intercepts only. Once we had identified the optimal model only with random intercepts, we refitted it with both random slopes and intercepts. There were additional modelling complications for GNM. Because of the large sample size and, more crucially, the highly correlated nature of the three GNM-related predictors, it was not possible to fit the models containing all three GNM values in a timely manner, even with random slopes removed. Thus, for the models involving GNM, we decided to first fit a model with only the three GNM-related quantities as predictors, with no random effects. We then used those values, normalised to sum up to 1, to derive GNM quantities for each syllable; these were used to fit the GNM models including random effects.
Table I shows the performance of the models with random effects, with phonotactic probability effects on the horizontal axis and neighbourhood-density effects on the vertical axis. The performance of each model was based on WAIC values. The WAIC values in each cell indicate the model performance for the combination of the two assumed determinants. For example, the WAIC value of 11437.8 in the top left cell results when phonotactic probabilities are calculated on the assumption that tone is conditioned on the onset and neighbourhood density is measured by the number of neighbours. Lower WAIC values indicate better predictive power.
WAIC values of the different models and standard errors (in parentheses) of the WAICs, with columns indicating the measure of phonotactic probability, and rows indicating the measure of neighbourhood density. NoPP=no phonotactic probability.

The model with only log-probabilities using unconditional tonal probabilities (T) has the lowest WAIC values, indicating that it performed the best. However, it has only a slight edge over some other models, especially those with GNM: T with GNM, T∣O with GNM and T∣C with GNM. Note, however, that the WAIC values from the generalised neighbourhood modelling are not exactly comparable with the WAIC values from the other models. The generalised neighbourhood models correctly incorporated frequency effects, including the square of the log frequency and the raw frequency itself. The exact weights of the GNM quantities were also calculated from the wordlikeness-judgement data. However, this was done in the ‘first round’ of the fitting process, and was not factored into the calculation of WAIC in the final model. Recall that this was an inevitable modelling decision, due to the large sample size and the intrinsically high correlation of the three GNM-related predictors. In principle, the WAIC values from our ‘simplified’ generalised neighbourhood modelling are underestimated. Thus we refrain from interpreting the precise WAIC values from the generalised neighbourhood models, but instead infer the GNM performance from the GCM: given that the GNM is based on the GCM, but adds extra complications (rather highly correlated to the GCM value: both extra components have correlation coefficients above 0.99 with the GCM value), we suggest that if there is no evidence that the GCM is better than other models, it is unlikely that the GNM, which has many more parameters, but does not add much extra information, would perform any better. Thus, in our comparison of the models, we ignore the WAIC values of the GNM in Table I, and infer the performance of generalised neighbourhood models from the performance of generalised context models.
When the GNM is excluded from the comparison of the exact WAIC values across the models, the best model, i.e. the one with only log-probabilities using unconditional tonal probabilities (T), is still very similar to some other models, such as the one with log-probabilities without tone (NoT) and the one with log-probabilities of unconditional tonal probabilities along with the GCM (T with GCM). Given the closeness of their WAIC values, and given that the WAIC differences are around the same size as the standard error differences, it would be inappropriate to choose the optimal model on the basis of these values alone. We therefore decided to first identify whether the differences in performance between the six types of measurements of tonal probabilities are meaningful. In other words, we examined whether one tonal representation has a better predictive power than the others. The WAIC value differences between the optimal model (T) and the best models for each tonal representation were compared: the best models include tone conditioned on onset with no lexical effect, tone conditioned on nucleus with no lexical effect, tone conditioned on coda with NN, tone conditioned on all segments with NN and a representation excluding tone with no lexical effect. The WAIC differences are shown in Table II.
Differences in WAIC between the unconditioned tone model and the other models among other tonal representations.

The WAIC differences among the models are quite small, considering their standard errors: in most cases the magnitude of the difference is smaller than the standard error. Even for the greatest difference, the one for tone condition on all segments (T∣S), the WAIC difference is only slightly greater than the standard error. From the observation that the optimal models for each tonal representation do not significantly vary in their performance, we conclude that there are no grounds for preferring one tonal representation over any other. Therefore, for the purpose of presentation we report the results based on the optimal model (T) in the following discussion, but it should be borne in mind that the results are comparable across the different tonal probabilities we tested.
To understand the exact relation between log-probability and the wordlikeness judgements, we examined the coefficient estimates of the models. We fitted the best-performing model with full random effects for all predictors in the three regions considered, i.e. gradient judgements and the two categorical judgements. This was done using the model with unconditioned tonal representation (T) and no neighbourhood effects. We then examined point and interval estimates of the coefficients. Since the different models have roughly similar performance in terms of the WAIC, we also ran a robustness check known as multiverse analysis (see e.g. Steegen et al. Reference Steegen, Tuerlinckx, Gelman and Vanpaemel2016). This was performed using the models without random effects in Table I. That is, we examined a variety of logically possible ways to do the analysis, in this case all the different tonal representations and neighbourhood representations, and then examined the coefficient estimates for each one.
The results for the optimal model are given in Table III. The 95% credible intervals (CIs) indicate the range of values for which we can be 95% sure that the coefficient lies in. A 95% CI that excludes zero would indicate strong evidence that the coefficient is non-zero, meaning that the evidence is sufficient to support the considered effect.
The overall results of the optimal model.

Higher log-probabilities lead to intermediate judgements (between 0 and 1) being higher in general, since the coefficient of the log-probabilities in the beta regression component excludes zero (0.061, 0.097). There is sufficient evidence that higher log-probabilities substantially enhance the chances of items being judged as 1, since the 95% CI for its coefficient in the logistic regression component for 1s does not include zero (0.375, 0.647). In addition, we have some evidence for the logistic regression component for 0s being affected by log-probabilities, since the coefficient excludes zero (0.003, 0.073), though in an unexpected direction, whereby higher log-probabilities makes 0 judgements more frequent. This aligns with our descriptive observations in §4.2 that 0 judgements seem to be less affected by log-probabilities than 1 judgements and intermediate judgements. We thus have clear evidence that log-probability does contribute to the determination of sound sequences as categorically legitimate Cantonese words and as more or less wordlike.
We next performed a multiverse analysis, as a robustness check for the effects obtained above. We examined the CIs for the coefficients for phonotactic probability and neighbourhood density under each possible pairing of these measures in Table I above. The CIs were examined for each of the three regions: gradient judgements, 0 judgements and 1 judgements. CIs that exclude 0, i.e. do not intersect the dashed line, indicate that the predictor is effective.
The effect of phonotactic probability is examined in Fig. 4. As can clearly be seen, in the case of gradient judgements (Fig. 4a) and 1 judgements (Fig. 4c), the effect of phonotactic probability is completely robust, regardless of the tonal representations. However, only two possible combinations lead to an effect on 0 judgements (Fig. 4b), and both are very marginal. The results confirm that log-probability has an effect only on 1 judgements and gradient judgements, not on 0 judgements.
Multiverse results for the 95% credible intervals of the effect of log-probability on (a) gradient judgements; (b) 0 judgements; (c) 1 judgements. Exact numerical values are given in Appendix D.

The analysis of neighbourhood density is given in Fig. 5. For 0 judgements (Fig. 5b), every model shows CIs intersecting with the dashed line, suggesting no neighbourhood-density effect. For the effects on gradient judgements (Fig. 5a) and 1 judgements (Fig. 5c), the presence of a CI excluding 0, i.e. a neighbourhood-density effect, hinges crucially on the choices between NN and the GCM. Specifically, generalised context models almost always have a GCM coefficient excluding 0. Models with NN rarely have an NN coefficient excluding 0. This suggests that the GCM is a better predictor than NN of wordlikeness judgements. However, generalised context models were not shown to perform better in terms of the WAIC values in Table I. Recall that under no choice of log-probability measure in Table I does the generalised context model outperform the model with no neighbourhood-density measures. Therefore, while these graphs suggest that the GCM appears to be a better predictor than NN, our data still do not provide sufficient evidence for a GCM effect. In sum, our modelling results suggest that log-probability, regardless of tonal representations, does play a role in predicting the wordlikeness data for the categorically wordlike items and gradient items, but not for items which are categorically not wordlike. We do not have sufficient evidence for the role of neighbourhood density.
Multiverse results for the 95% credible intervals of the effect of neighbourhood density on (a) gradient judgements; (b) 0 judgements; (c) 1 judgements.

To summarise, log-probability predicts the wordlikeness judgements for gradient judgement and categorical 1 judgements, but not for categorical 0 judgements. This effect is robust across the different tonal representations that we have considered, and we have little evidence in favour of one tonal representation over any other. The number of neighbours is not a predictor of the wordlikeness-judgement data. Although we have suggestive, but by no means conclusive, evidence that the GCM may be involved in the prediction of gradient judgements and 1 judgements, we can be confident that it rarely plays a role in 0 judgements. Given the limited GCM effect, we infer that any GNM effect will be extremely minor.
4.3.2 Comparison of the relative contribution of syllable components
So far, we have only investigated the effect on phonotactic judgements of the log-probability of the items as a whole. An assumption underlying this is that the different parts of a syllable that make up these probabilities are equally important. Recall that our goal was also to establish whether the various components of the syllable (onset, nucleus, coda, tone) differ in their relative importance in determining wordlikeness judgements. To establish the relative roles of different syllable components towards the prediction of wordlikeness judgements, we separated the log-probabilities in Table III into the four syllable-component probabilities, and allowed the model to assign separate coefficients to each syllable component. The results, presented in Table IV, are based on the assumption that tone is conditioned on the onset, but the general trends are same for other tonal representations that we examined.Footnote 5
The results of the log-probability model assigning separate coefficients to each syllabic component.

First, for the beta regression component (gradient judgements), we have strong evidence for effects of nucleus and coda, because their CIs exclude zero; we also have sufficient evidence that the effect of nucleus conditioned on onset is greater than that of coda conditioned on nucleus in the beta regression component (estimated difference between nucleus and coda = 0.08, SE = 0.02, 95% CI = (0.05, 0.12)). Moreover, we have some evidence that the probability of the onset matters. This effect is also smaller than the nucleus effect (estimated difference between onset and nucleus = ―0.08, SE = 0.03, 95% CI = (―0.13, ―0.02)). We have no evidence for a difference between onset and coda (estimated difference = 0.01, SE = 0.03, 95% CI = (―0.04, 0.06)), or for a tonal effect. Second, in the logistic regression component for 1s, we see the same situation, with the coefficients of all three segmental probabilities excluding zero. We do not have evidence that their coefficients are different (estimated difference between onset and nucleus = 0.03, SE = 0.04, 95% CI = (―0.05, 0.1); estimated difference between onset and coda = 0.04, SE = 0.04, 95% CI = (―0.03, 0.11); estimated difference between nucleus and coda = 0.01, SE = 0.03, 95% CI = (―0.03, 0.06)). Third, we have no significant predictors for 0 judgements, consistent with the results in the previous subsection. Thus the general tendency for log-probability to be able to predict gradient judgements and the categorical 1 judgements, but not of 0s, is consistent across the model which assumes the syllable as a whole (Table II) and the model which assigns separate coefficients to each syllabic component (Table IV).
To summarise, we have found evidence that phonotactic log-probability is a good predictor of the wordlikeness-judgement data presented in this paper. We have not found evidence that neighbourhood density contributes to the prediction of the data patterns. Moreover, if we split up the log-probability into its syllabic component parts, we find that the conditional probabilities of nucleus and coda play a crucial role; onset is less important, but still plays a role to a certain degree, while tone does not. Finally, such effects tell us how likely participants are to rate an item as perfect (1) or, if their rating falls between 0 and 1, how likely the rating is to be high, but the predictors do not affect the likelihood that participants will judge items to be not at all wordlike.
5 General discussion
5.1 Phonotactics vs. lexical neighbourhoods
Our finding that phonotactic log-probability, but not neighbourhood density, is important in predicting wordlikeness judgements goes against some previous studies, including Kirby & Yu (Reference Kirby, Yu, Trouvain and Barry2007), who also tested wordlikeness in Cantonese, focusing specifically on lexical gaps. Recall that Kirby & Yu found a relatively weaker effect for phonotactic probability and a stronger effect for neighbourhood density. Since both studies tested Cantonese, despite differences in the exact research questions, it is worth considering the different results in greater detail. Kirby & Yu attributed their findings to the fact that Cantonese makes use of a larger space of possible monosyllabic words than some other languages, for example English. Because of the strict phonotactic restrictions of Cantonese, possible phonotactic combinations are more limited. As a result, larger portions of the relatively limited phonotactic space are occupied by real words in Cantonese. If this is the case, native speakers rely more on the lexicon in making wordlikeness judgements. Kirby & Yu also point out that, due to the high number of words in the limited phonotactic space, many non-words have lexical neighbours. This might encourage speakers to rely on lexical neighbours in making wordlikeness judgements. This idea is further pursued by Shoemark (Reference Shoemark2013), who argues that, because the connectivity of Cantonese phonological networks is denser than those of English, a greater proportion of the Cantonese lexicon is activated by any non-word. Beyond Cantonese, our results also go against work which has found independent effects of lexicon and phonotactics in English (Bailey & Hahn Reference Bailey and Hahn2001) and Mandarin (Myers Reference Myers2016). Gorman (Reference Gorman2013) also reports a major role for neighbourhood density in English, again differing from the results in this paper. Our results are, however, in line with Frisch et al. (Reference Frisch, Large and Pisoni2000) and Albright (Reference Albright2009). Frisch et al. reports that English native speakers’ wordlikeness judgements of multisyllabic non-words was better predicted by phonotactic probability than by neighbourhood density, although the difference was only marginal, while Albright found that, although judgements are correlated with lexical neighbourhood measures at a descriptive statistical level, they were not significant in the regression model.
There are several ways to account for such discrepancies across different studies. First, the differences might be due to the research design, specifically the inclusion of real words in some experiments. For example, both Bailey & Hahn (Reference Bailey and Hahn2001) and Kirby & Yu (Reference Kirby, Yu, Trouvain and Barry2007) included real words; in the latter case, over one-third of the test items were real words. This was not the case in our experimental design, where only non-words were tested. Some studies which reported no neighbourhood-density effect did not include real words either (e.g. Frisch et al. Reference Frisch, Large and Pisoni2000, Albright Reference Albright2009). Vitevitch & Luce (Reference Vitevitch and Luce1998, Reference Vitevitch and Luce1999) and Shademan (Reference Shademan2006) argue that the processing of real words is dominated by lexical influences, an idea that is supported by Myers & Tsay (Reference Myers and Tsay2005), who found lexical effects in the judgements of real words in Mandarin, but no such effect for non-words. The inclusion of real words may encourage lexical access, possibly leading to the observation of strong lexical effects. However, other studies which included only non-words did report strong effects of neighbourhood density (Gorman Reference Gorman2013, Myer Reference Myers2016). This suggests that the method of stimulus selection might affect the results and the conclusions drawn from different wordlikeness studies; however, the method itself is not the sole factor determining lexical effects in wordlikeness judgements.
Second, another factor may be the size of syllable inventory, which differs across languages. In comparison to languages like English, Cantonese has highly restricted phonotactics, allowing no consonant clusters and a fairly limited set of codas. Myers (Reference Myers2016) argues that lexical neighbourhoods are more important than phonotactic probability in languages with a small syllable inventory (e.g. Mandarin and Cantonese), due to their strict phonotactic restrictions, because the small numbers involved in the inventory makes syllables easier to access from rote memory. On the same logic, in languages with larger number of syllables, like English, speakers rely less on lexical neighbourhoods, because there are too many syllables which must be accessed, making the process too complicated. This idea is similar to Kirby & Yu (Reference Kirby, Yu, Trouvain and Barry2007), where the strict phonotactic restrictions are argued to encourage lexical effects, because a language with strict phonotactic restrictions makes use of a larger proportion of limited phonotactic possibilities. This predicts that our study on Cantonese wordlikeness judgements should have observed a strong lexical effect, but this was not the case. We believe that there is an alternative way to consider the relation between the level of phonotactic restrictions and the role of neighbourhood density in wordlikeness judgements. As Kirby & Yu (Reference Kirby, Yu, Trouvain and Barry2007) and Myers (Reference Myers2016) argue, if phonotactic restrictions are very strict in a language, the number of possible phonotactic patterns is limited. This results not only in a limited syllable inventory, but also in relatively little variation in lexical density in comparison with languages that allow varying degrees of phonotactic combinations (e.g. complex onsets and codas). For example, English syllables can contain as many as seven segments (e.g. strengths /streŋθs/), while Cantonese syllables can have no more than three segments and a tone. In principle, the range of values covered by the Cantonese phonological space is only from 0 to 4 (including tone), when a distance of 1 is assumed for each syllabic component, whereas in English, the variation is greater, from 0 to 7. Even if there were a lexical effect, it is possible that it would be difficult to estimate, since the range of the independent variable is too narrow. Further investigation is needed to identify the exact relation between the degree of variation in lexical density or phonological space in languages and the role of lexical effects in wordlikeness judgements. Crucially, as wordlikeness judgement tests using the same languages have frequently yielded contrasting results, including English (e.g. Bailey & Hahn Reference Bailey and Hahn2001, Albright Reference Albright2009) and Cantonese (e.g. Kirby & Yu Reference Kirby, Yu, Trouvain and Barry2007 and the current study), language-specific phonotactic factors are important, but should not be treated as deterministic in the prediction of wordlikeness judgements in specific languages.
Third, another possible explanation is related to speakers’ different perceptions of non-words, depending on the morphological systems of different languages. As mentioned in §2.1, many modern Cantonese monosyllabic morphemes are generally not used as independent words, but only appear in compounds (Bauer & Benedict Reference Bauer and Benedict1997). For instance, the morpheme /ʦɐk˺˥/ is used in many common words such as /kʷʰɐi˥ʦɐk˺˥/ ‘rules, regulations’, /sɐukʦɐk˺˥/ ‘regulation, code of conduct’, but the monosyllabic morpheme does not really mean anything on its own.Footnote 6 Previous work has consistently suggested that syllables, rather than individual phonemes, are the fundamental units in Chinese languages: Alpatov (Reference Alpatov1996) describes syllables in Chinese as ‘the most important psycholinguistic units’ and O'Seaghdha et al. (Reference O'Seaghdha, Chen and Chen2010) call Mandarin syllables ‘proximate units’. There is little doubt that Cantonese speakers can easily recognise and process monosyllabic items, which are for them basic units. However, they may not regard monosyllabic items as independent words which can potentially have corresponding Chinese characters bearing their own meanings, because of the frequent involvement of monosyllables in compounds. Indeed, Chan et al. (Reference Chan, Skehan and Gong2011) cast doubt on the validity of testing Cantonese speakers with monosyllabic non-words, arguing that non-words created on the basis of one language's phoneme inventory and phonotactic regulations are different from non-words created on the basis of other languages. In clinical work, Stokes et al. (Reference Stokes, Wong, Fletcher and Leonard2006) report the failure of monosyllable-based non-word repetition test to identify children with specific language impairment in Cantonese, while studies on English have found evidence that the monosyllabic non-word repetition test serves as a meaningful clinical marker (see the meta-analysis in Estes et al. Reference Estes, Evans and Else-Quest2007). This may suggest that monosyllabic non-words in Cantonese have a different status from those in English, a factor to which the current results might be attributed. The current study conducted neighbourhood analysis based on syllables, where an example like /tsɐk˺˥/ was counted as a neighbour of a stimulus. Given that such syllables are not used as independent words, it is conceivable that the results would differ in a neighbourhood analysis based on words. Future work should involve identifying which neighbourhood analysis matches better with speakers’ judgements in Cantonese. Additionally, an exploration of non-word processing is needed for languages differing from each other in their morphological systems.
We have considered the effects of the stimulus-selection methods, language-specific phonotactic complexity and language-specific morphological systems in determining the predictors of wordlikeness judgements. Crucially, the conclusions drawn from similar methods or from work on the same languages differ from each other. This suggests that the predictors of wordlikeness judgements should be considered comprehensively, taking into account both research design-specific and language-specific factors, and that the exact correlations of each factor should be further identified, in order to correctly model wordlikeness judgements.
5.2 The role of syllabic components
When splitting up the phonotactic log-probabilities into syllabic components, we found that the conditional probabilities of the nucleus and coda matter most and those of the onset are of marginal importance, while tonal probabilities play no role. Note that our experiment used only permissible Cantonese phonemes and tones. Compared to nuclei and codas, for which judgements can be based on their co-occurrence with the preceding phonemes, onsets, which occur in initial position, can be judged without reference to the context. It is therefore not surprising that permissible onsets were all simply treated as ‘acceptable’, resulting in low weight for onsets when items’ wordlikeness was rated. What is surprising is that the conditional probabilities of tone do not play a major role, given that there is at least one highly robust generalisation about Cantonese phonotactics, that oral stop codas are only compatible with ˥, ˧ and ˨ (and k, if it is a result of a change from one of the other tones). This, though, is compatible with previous studies on lexical access in Mandarin showing that tone plays a less important role than other syllabic components (Taft & Chen Reference Taft, Chen, Chen and Tzeng1992), especially for monosyllables (Lin Reference Lin2016). Why do results from different experimental paradigms and across two languages consistently show that tone is less important than segments in lexical processing? We suggest that this can be accounted for if the lexical predictability of syllabic components is taken into consideration. One measure for how ‘predictable’ a component is in a lexicon is its functional load. In Cantonese, for example, it has been found that onsets and tones have a higher functional load than nuclei and codas (Do & Lai Reference Do and Yau Laiforthcoming), where functional load is defined as the entropy of the language contrasts in a syllable component divided by the actual entropy of the language (e.g. Hockett Reference Hockett1966). This suggests that nuclei and codas are lexically more predictable (i.e. restricted) than onsets and tones in Cantonese, and hence play a smaller role in discriminating between lexical items. Thus our results may tentatively be interpreted as showing that lexically less predictable aspects of an item are more likely to contribute to wordlikeness judgements.
The weaker reliance on tone is also in line with results from perception studies on Cantonese. Cham (Reference Cham2003) reports that Cantonese speakers performed more poorly in tone-awareness tasks than in segment-awareness tasks, suggesting that tones are perceptually less salient than segments in Cantonese. Other studies (e.g. Keung & Hoosain Reference Keung and Hoosain1979, Cutler & Chen Reference Cutler and Chen1997) have shown that spoken word recognition is more challenging when tone differences are involved, implying that listeners have lower sensitivity to tone differences than to segment differences. If this is the case, the current study may suggest that the syllable is perceptually less salient than other components.
5.3 Categorical vs. gradient judgements
Our final finding is that the log-probability of syllabic components affects only the tendency to judge words as being absolutely perfect or as situated between two extremes. They do not affect the probability that the participants will judge items as absolutely unacceptable. This suggests that wordlikeness judgements potentially involve two different cognitive processes, for only one of which we have a solid predictor. The other, for categorically bad judgements, remains poorly understood. It is not surprising, though, that phonotactically illicit items are processed differently from absolutely grammatical and gradient items. There is a large amount of evidence suggesting difficulties in processing phonotactically illicit sequences in perception (e.g. Dupoux et al. Reference Dupoux, Kakehi, Hirose, Pallier and Mehler1999, Berent et al. Reference Berent, Steriade, Lennertz and Vaknin2007, Kabak & Idsardi Reference Kabak and Idsardi2007) and in production (Vitevitch & Luce Reference Vitevitch and Luce1998, Reference Vitevitch and Luce2005, Davidson Reference Davidson2005, Reference Davidson2006a,Reference Davidsonb, Rose & King Reference Rose and King2007), which may mean that speakers have a limited ability to process the representations of illicit sequences (Gorman Reference Gorman2013). While the gradient nature of wordlikeness judgements has been widely recognised (Ohala & Ohala Reference Ohala, Ohala, Ohala and Jaeger1986, Coleman & Pierrehumbert Reference Coleman and Pierrehumbert1997, Frisch et al. Reference Frisch, Large and Pisoni2000, Hayes Reference Hayes, Dekkers, van der Leeuw and van de Weijer2000, Bailey & Hahn Reference Bailey and Hahn2001), the exact processes involved in the judgements of absolutely perfect vs. absolutely bad vs. gradient are yet to be discovered. We do not speculate here on why this is the case, or whether it is generalisable to other languages and tasks.
Modelling work on wordlikeness judgements has shown that phonotactic probability and neighbourhood density are crucial determinants of speakers’ judgements (Bailey & Hahn Reference Bailey, Hahn, Gernsbacher and Derry1998, Reference Bailey and Hahn2001, Frisch et al. Reference Frisch, Large and Pisoni2000). However, a full understanding of speakers’ phonotactic knowledge has yet to be obtained, given the lack of a research focus on suprasegmental features in phonotactic modelling work. This paper is an attempt to model wordlikeness judgements incorporating tone. Future work should test other tonal languages on the basis of the methodologies presented in the current study, so that the determinants of speakers’ wordlikeness judgements can be understood when both segments and tones are included.



