1 Introduction
There is a substantial body of work applying automata theory to temporal reasoning, with strings (and trees) stretching to infinity to describe non-terminating computation runs (e.g. Emerson Reference Emerson and van Leeuwen1992; Vardi Reference Vardi, Blackburn, Wolter and van Benthem2007). Many natural language statements, however, describe temporally bounded events, including reports in the past tense, such as Pat walked to the post office or An event of such and such happened, that ensure the events have an end (if not a beginning). The question arises: can we employ ordinary finite-state methods (of the sort in, for example, Beesley and Karttunen Reference Beesley and Karttunen2003) to reason about strings that can be assumed finite? The main aim of this paper is to show how we might, and how that may stray from established practices. The focus is not on any particular natural language engineering application, but rather on basic conceptual issues that bear on such applications. These issues revolve around events and situations natural language statements are about—events and situations bounded in ways that merit investigation.
1.1 Linear temporal logic and finite situations
For orientation, we start with linear temporal logic (LTL) over the set 𝕫 of integers and a set P of atomic formulas (e.g. Vardi Reference Vardi, Blackburn, Wolter and van Benthem2007). LTL-formulas are evaluated against relations V ⊆ 𝕫 × P) between 𝕫 and P, with V(t,p) read ‘p is true at V,t’ and written V,t ╠ p
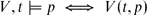
for t ∈ 𝕫 and p ∈ P. Fixing the evaluation time to 0, we can describe an infinite string of p's through the LTL-formula Gp that asserts V(n,p) for every non-negative integer n
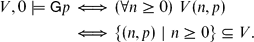
Negative integers come in to interpret past operators such as previous, from which we can form the LTL-formula previous(q) ∨ Gp that is true at V,0 iff G(p) is or q is true at V,-1
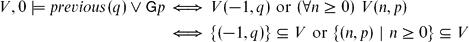
(for q ∈ P). Assuming P is closed under complementation,Footnote 1 one can, in general, map an LTL-formula ϕ and integer t to a set S [ϕ,t] of relations s ⊆ 𝕫 × P, reducing the truth of ϕ at V,t to some subset of V being in S [ϕ, t]
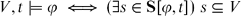
(e.g. Fernando Reference Fernando2009a). For instance, S[previous(q) ∨ Gp,0] consists of the two relations {(−1,q)} and {(n,p) | n ≥ 0}, each describing a way for previous(q) ∨ Gp to be true at 0. As this example shows, a relation s in S [ϕ, t] may or may not be finite.
Of course, if V were finite, then we can throw out all infinite relations from S([ϕ, t]. Put another way, we can restrict S[ϕ, t] to finite relations by focusing on finite subsets of V (reconstructing V as the union of its finite subsets, as in the reformulation of Büchi acceptance in terms of paths in Fernando Reference Fernando, Hanneforth and Würzner2008b). But we had better be careful about asserting line (1) above for different temporal spans (finite or not), as made clear by the formula Gp saying ‘p now and forever more’ within that span. To establish (1) for spans over only the two times 0 and 1, we put
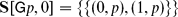
but if we add 2 to that span, we would require
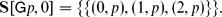
Evidently, varying the temporal spans under consideration (from 𝕫 to its finite segments) renders (1) untenable—at least for ϕ's such as Gp. Such complications beg the question: apart from sidestepping infinite relations s ∈ S[ϕ, t], why should we cut an infinite relation V ⊆ 𝕫 × P down to its finite parts?
At the philosophical end, there is something to be said for grounding semantics in our finite experience, minimizing mysterious abstractions such as possible worlds by working instead with situations that are partial (e.g. Barwise and Perry Reference Barwise and Perry1983). From a more practical natural language processing perspective, it is far from clear that one notion of time will do. Temporal spans vary, as does temporal granularity. Every Monday might mean every Monday in June or every Monday in 2010, and the previous moment might refer to the previous minute or previous second (among many other possibilities). The analysis of calendar expressions in Niemi and Koskenniemi (Reference Niemi, Koskenniemi, Piskorski, Watson and Yli-Jyrä2009) is particularly instructive for our purposes.
1.2 Calendar expressions and snapshots-as-symbols
In Niemi and Koskenniemi (Reference Niemi, Koskenniemi, Piskorski, Watson and Yli-Jyrä2009), temporal span and granularity depend on the calendar expression under consideration. For example, January and March 2008 is interpreted relative to the 12 months of 2008, represented as the string
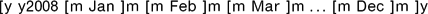
of length 39, with 4 bracket symbols ]y, [y, [m and ]m and the 13 symbols y2008, Jan, Feb, (. . .), Dec. The phrase January and March 2008 marks out the months of January and March in (2), leading to
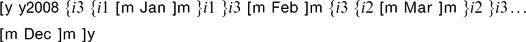
with six additional symbols {i3, {i2, {i1,}i3,}i2,}i1. We can rewrite (3) as the string
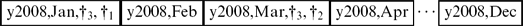
of length 12 (each box, a symbol) if we rewrite (2) as the string

also of length 12. In (4) and (5), a symbol is a subset of some set Φ of fluents (AI-speak for temporal propositions; McCarthy and Hayes Reference McCarthy, Hayes, Meltzer and Michie1969), enclosed by a box (rather than by the more usual curly braces {,}) to suggest a snapshot (or frame in a cartoon strip). As noted in Karttunen (Reference Karttunen2005), we can unpack such boxes, turning (5), for example, into the string

of length 48. If Φ is finite and includes neither [ nor ], it is trivial to devise a finite-state transducer mapping strings over the alphabet Pow(Φ) of subsets of Φ to strings over Φ ∪ {[,]}, allowing us to translate regular languages and relations freely between the alphabets Pow(Φ) and Φ ∪ {[,]}. Translating strings in Niemi and Koskenniemi (Reference Niemi, Koskenniemi, Piskorski, Watson and Yli-Jyrä2009) to strings over Pow(Φ) is a more complicated affair and is another day's work. For now, we abstract away from implementation issues for which the strings of Niemi and Koskenniemi (Reference Niemi, Koskenniemi, Piskorski, Watson and Yli-Jyrä2009) were carefully engineered, and work with strings of snapshots.
Strings of snapshots are arguably easier to read because snapshots are ordered chronologically (as in a cartoon or film strip). Indeed, finite subsets of 𝕫 × P for LTL translate straightforwardly into strings over Pow(P ∪ {0}), with, for example,
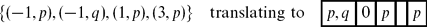
(suggesting we equate Φ with P ∪ {0}). That said, we should be careful not to fix the notion of time (say, to 𝕫) if we are to accommodate different granularities. That is, the brackets [ and ] in (6) should be understood as having indeterminate granularity (in contrast to [m and ]m in (2) and (3)). Moreover, we may compress (4) to
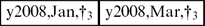
just as Niemi and Koskenniemi compress (3) to
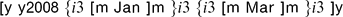
with unmarked calendar periods removed (Niemi and Koskenniemi Reference Niemi, Koskenniemi, Piskorski, Watson and Yli-Jyrä2009: 129). Unlike the timelines depicted by (4) and (5), there are gaps between the boxes in (7) that are familiar to conceptions of time based on discrete transitions, be they the input/output pairs of programs in dynamic logic (Harel, Kozen and Tiuryn Reference Harel, Kozen and Tiuryn2000) or strings of length ≥3 (with intermediate states) for temporal logic. In any case, it is of interest to isolate (7) from (4), or even better, (7)'s unmarked variant
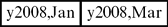
from (4)'s
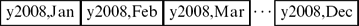
inasmuch as the mapping (9) ↦ (8) constitutes, in the words of Niemi and Koskenniemi (Reference Niemi, Koskenniemi, Piskorski, Watson and Yli-Jyrä2009), a ‘disambiguated intensional meaning’ of January and March 2008.
1.3 Carnap–Montague intensions and partiality
The (Carnap–Montague) intension of an expression is a function from indices to extensions (or denotations). For the expression January and March 2008 above, we can view the string (9) as an index, and (8) as an extension. Since Frege, it has been customary to identify the extension of a sentence (or statement) ϕ with one of two truth values, say True and False, essentially reducing the intension 𝓘[ϕ] of ϕ to the set of indices that 𝓘[ϕ] maps to True. For LTL, an index is a pair V, t where V ⊆ 𝕫 × P and t ∈ 𝕫, and
 = \mbox{True} & \TFbd{\iff} &
V,t\models \varphi.
\end{eqnarray*}](https://static.cambridge.org/binary/version/id/urn:cambridge.org:id:binary:20151022070640754-0330:S135132491100009X_eqnU8.gif?pub-status=live)
Now, the main idea behind the present work is to reconceptualize
(i) an index as a string over the alphabet Pow(Φ) built from a set Φ of fluents including now ∈ Φ) through which we can encode, for instance, the pair
as the string and
(ii) an extension of a sentence ϕ as a set of strings over Pow(Φ), rather than True or False
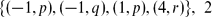
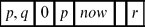
so that the intension 𝓘[ϕ] of ϕ maps a string s ∈ Pow(Φ)* to a set 𝓘[ϕ](s) ⊆ Pow(Φ)* of strings that make ϕ true at s inasmuch as
\neq\emptyset.
\end{eqnarray}](https://static.cambridge.org/binary/version/id/urn:cambridge.org:id:binary:20151022070640754-0330:S135132491100009X_eqn10.gif?pub-status=live)
If we relax the requirement that an intension be a function and require simply that it be a binary relation between indices and extensions, then we can formulate indices and extensions alike as strings over Pow(Φ), identifying the intension of ϕ with the binary relation
\}
\end{eqnarray*}](https://static.cambridge.org/binary/version/id/urn:cambridge.org:id:binary:20151022070640754-0330:S135132491100009X_eqnU11.gif?pub-status=live)
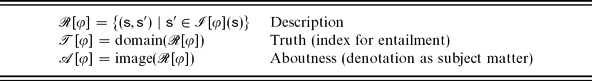
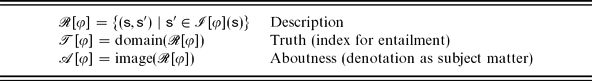
on Pow(Φ)*. A string in Pow(Φ)* can be understood as a situation in the sense of Barwise and Perry (Reference Barwise and Perry1983) (as opposed to that in McCarthy and Hayes Reference McCarthy, Hayes, Meltzer and Michie1969). In case 𝓘[ϕ](s) consists of exactly one situation s', we can say s' is the situation described by ϕ at s, linking the event time in Reichenbach (Reference Reichenbach1947) to the temporal span of s' (in contrast to the time now marks out in the index s). Indeed, events in Davidsonian semantics exemplify situations as truthmakers (Davidson Reference Davidson and Rescher1967; Mulligan, Simons and Smith Reference Mulligan, Simons and Smith1984). The domain of 𝓡[ϕ] consists, under (10), of the indices at which ϕ is true, qualifying as the truth set 𝓣[ϕ] of ϕ
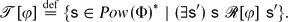
The image of 𝓡[ϕ] consists of situations that ϕ is about, making it the about set of ϕ, which we write 𝒜[ϕ]
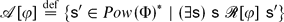
(see Table 1, Fernando Reference Fernando2009b).
Basic notions from an intension function 𝓘[ϕ].
Setting aside the problem that aboutness need not be grounded in truth, let us explore the intuition that
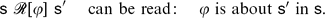
It is certainly plausible to assume that s 𝓡[ϕ] s' implies s' ⊑ s, for some ‘in’ relation ⊑ on strings over Pow(Φ). One way to formalize (11) then is to combine the about set 𝓐[ϕ] with ⊑ for the biconditional
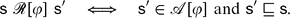
An immediate consequence of (12) is that for transitive relations ⊑, truth is persistent in that 𝓣(ϕ) is closed under ⊑
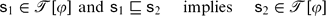
for all s1,s2 ∈ Pow(Φ)*. While (13) may hold for many sentences ϕ, there are well-known counter-examples to it, including the LTL-formula Gp in Section 1.1. Recall that the biconditional
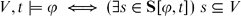
becomes problematic when we work with bounded temporal spans short of 𝕫 (replacing, as it were, V with its finite subsets). To link this discussion up with (12), some notation is helpful. Given a finite subset s of 𝕫 × P and an integer t, let us write str(s,t) for the shortest string over Pow(P ∪ {0, now}) encoding the pair s,t. For instance,
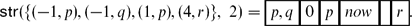
The notions of ‘in’ ⊑ then becomes essentially set inclusion ⊆
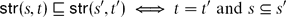
while ‘about’ 𝓐[ϕ] corresponds to  t∈𝕫S[ϕ, t]
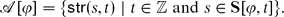
Now the difficulty (14) poses for Gp when V is replaced by its finite fragments s' suggests that the best we can salvage from (14) is to step from a set S[ϕ, t] of relations between 𝕫 and P to some suitable binary relation R[ϕ, t] between such relations, and weaken (14) to
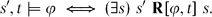
That is, if
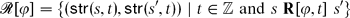
then (15) equates the truth set 𝓣[ϕ] with the domain of 𝓡[ϕ]. But if we are to read s 𝓡[ϕ] s' as
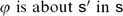
then we had better beware that
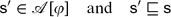
falls short of (16) for sentences ϕ such as Gp. Picking out the sentences where (16) reduces to (17), let us define ϕ to be absolute if
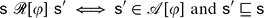
for all s,s' ∈ Pow(Φ)*. The LTL-formulas p and previous(q) are absolute; Gp is not.
Whether or not ϕ is absolute, it is useful for 𝓡[ϕ] to be a regular relation because it gives us a computational handle not only on its image, the about set 𝓐[ϕ], but also on its domain, the truth set 𝓣(ϕ). Entailment ├ between sentences is often relativized to constraints C, which we can identify with a set of strings (following, for example, Beesley and Karttunen Reference Beesley and Karttunen2003) to define
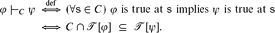
If 𝒯[ϕ], 𝒯[ψ] and C are all regular languages, then ├C above is decidable (since inclusion between regular languages is). Note that the strings in 𝓣[ϕ] are finite, whereas the relations V⊆ 𝕫 × P in LTL-semantics can be infinite, collectively inducing the entailments
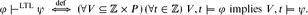
1.4 Claims and some finite-state matters
The bounded entailments ├C provide approximations of ├LTL that we take up in Section 3. But far from providing a new, improved way of calculating ├LTL (which we do not), the point of introducing relations 𝓡[ϕ] is to reason beyond ├LTL,
(a1) breaking free from the tyranny of the clock 𝕫 built into the semantics behind ├LTL
and
(a2) bringing out the about sets 𝓐[ϕ] that are at best implicit in that semantics.
The ‘tyranny of the clock 𝕫’ mentioned in (a1) is twofold: its span is infinite (two ways), and its ticks (grain) are fixed by the successor (plus-1) relation (in 𝕫). The focus below is on bounding span, although a few words about grain are offered at the conclusion on which I hope to expand elsewhere.
As for (a2), the proposed relational semantics 𝓡[ϕ] consists not only of the indices in 𝓣(ϕ) that shape ϕ ├C ψ, but also of denotations in 𝓐[ϕ], exemplified by events (e.g. Fernando Reference Fernando2009b). It is notable that Hans Kamp, famous in temporal logic for since and until, leaves temporal logic out of Discourse Representation Theory (Kamp and Reyle Reference Kamp and Reyle1993: 492) and works instead with events. As useful as it has proved in computer science, LTL is an artificial language, unfit for linguistic analyses that posit, for instance, two forms of until, dependent on the (a)telicity of event descriptions, featuring presuppositional as well as assertional dimensions (e.g. Karttunen Reference Karttunen1974; Condoravdi Reference Condoravdi, Hanson and Inkelas2009). Introducing relations 𝓡[ϕ] moves us, I claim, closer to an account of events (as denotations) and presuppositions (via indices). This is not a small claim, and I shall confine myself here to events as denotations. Analyzing presuppositions as requirements on indices calls for (in my view) adjustments to the definitions of 𝓡[ϕ] given below.
Presuppositions and telicity aside, let us consider the past tense, and ask if the LTL clause
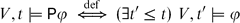
supports a reading of Pϕ as ‘ϕ in the present or in the past’? It is plausible enough in case ϕ is an atomic formula p for which V(t,p) says there is a V-situation of type p with time t. But suppose ϕ were constructed from the connective until, under the LTL clause
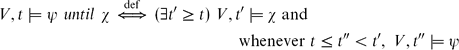
(such as it isFootnote 2). It is natural to assume that part of a V-situation of type ψ until p is a V-situation of type p. But for V ° = {(0,q), (1,q),(2,q),(3,p)}, we have
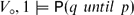
even though every V °-situation of type q until p stretches to 3, which is not in the past of 1. In general, for non-atomic ϕ, one cannot conclude from V,t' ⊧ ϕ and t' < t that there is a V-situation of type ϕ in the past of t. To report ϕ in the past tense at speech time t in V, what we require is not some t' < t such that V,t' ⊧ ϕ but a truthmaker for ϕ in the past of t.Footnote 3 That is, it is not so much the domain 𝓣[ϕ] of 𝓡[ϕ] that is relevant, but rather the image 𝓐[ϕ] of 𝓡[ϕ] and the ‘in’ relation ⊑.
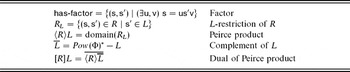
The next section fleshes out relations 𝓡[ϕ] and ⊑ in finite-state terms. Under the conventions adopted in, for example, Regular Model Checking (Bouajjani et al. Reference Bouajjani, Jonsson, Nilsson and Touili2000), regular relations can hold only between strings of the same length. But for ⊑ (for instance) to be regular, we drop this requirement, and follow Beesley and Karttunen (Reference Beesley and Karttunen2003) in permitting a finite-state transducer to make componentwise ε-moves (where ε is the null/empty string). A notable difference between Bouajjani et al. (Reference Bouajjani, Jonsson, Nilsson and Touili2000) and Beesley and Karttunen (Reference Beesley and Karttunen2003) is that regular relations are closed under intersection in the former but not in the latter. What is important for our purposes, however, is that the basic notions summarized in Table 2 are regular. A factor of s is a string s' such that s = us's for some strings u and v. The relation has-factor defined by
Some regular notions given a regular language L and relation R.

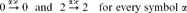
is computed by the finite-state transducer with three states 0,1,2, all final (accepting), 0 initial, with loops
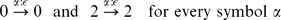
plus transitions
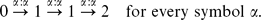
Given a finite-state transducer for R with transitions →R and a finite automaton for L with transitions →L, we can form a finite-state transducer for the (right) L-restriction R L of R defined by
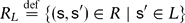
by collecting the transitions
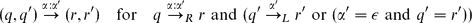
(as in the usual construction for the intersection of regular languages, but with ε-moves). The domain of R L is the Peirce product 〈R〉 L of R with L Footnote 4
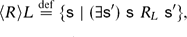
for which we existentially quantify α' out from (20) for
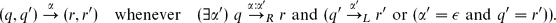
And as regular languages are closed under Boolean operations, including complementation  over the alphabet Σ, we can form the dual [R]L of the Peirce product 〈R〉L
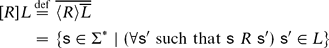
just as ∀ is the dual of ∃.
In the remainder of this paper, strings are formed from the alphabet Σ = Pow(Φ), under the assumption that Φ is finite, so that there are only finitely many subsets of Φ (i.e. symbols) which we write α, α', β), etc. That is, a string s∈ Pow(Φ)* is a sequence of the form α1. . .αn, while a symbol α is a box of fluents (from Φ). Largely a matter of convenience, this choice of alphabet provides a level of abstraction that simplifies many of the constructions below.
2 Relations 𝓡[ϕ] for some absolute formulas ϕ
This section starts with a simple generalization of set inclusion to strings over the alphabet Pow(Φ), which is then used to formulate constraints such as
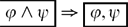
picking out strings that contain ϕ ∧ ψ only if they contain ϕ and ψ in the same box. Some refinements are then made to capture the ‘in’ relation ⊑ and define 𝓡[ϕ] for various absolute sentences ϕ.
2.1 Subsumption and constraints
Checking set inclusion ⊇ componentwise between strings from Pow(Φ)* of the same length, let
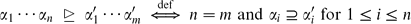
for all symbols αi,α'i ⊆ Φ). (Exactly what is in Φ does not matter just now, as long as Φ is finite.) In Fernando (Reference Fernando2004), s ⊵ s' is pronounced: s subsumes s'. The relation is computed by the finite-state transducer with a single state 0, both initial and final, and transitions
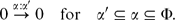
Next, given a language L over Pow(Φ), we let s ⊵ L mean s belongs to the Peirce product 〈⊵〉L (read: s subsumes L)
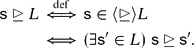
Then, given another language L' over Pow(Φ), let L ⇒ L' be the set of strings s such that every factor of s that subsumes L also subsumes L'
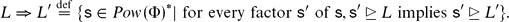
Collecting the factors of s that subsume L in the 〈⊵〉 L-restriction of has-factor
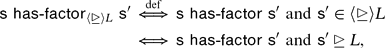
it follows that
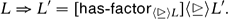
From the regularity of the constructs in Table 2, we can conclude that L ⇒ L' is a regular language if L and L' are. Indeed,
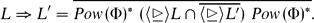
Among the constraints we can formulate with ⇒ are
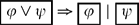
picking out strings that contain ϕ ∨ ψ only if they contain ϕ or ψ in the same box,

requiring either ϕ or its negation ϕ to be in every box. and

banning ϕ and ϕ from occurring in the same box.
We can also form
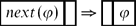
to put ϕ at every box succeeding one containing next(ϕ), in line with the LTL clause
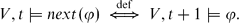
But to require that there be a box after every box containing next(ϕ), we form
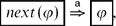
where  is pronounced ‘L’ after every L' and
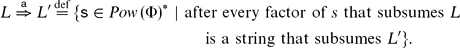
Defining
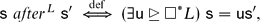
we get
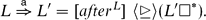
It is not difficult to convert a finite automaton for L into a finite-state transducer for after L. Hence,  is regular if L and L' are. In fact,
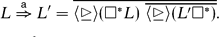
Modulo subsumption  is one form of Koskenniemi's restrictions (Beesley and Karttunen Reference Beesley and Karttunen2003), a second one being
 , read ‘L’ before every L,' defined by
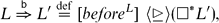
where
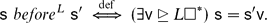
As with ⇒ and  is regular if L and L' are, with
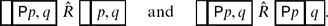
We can also strengthen 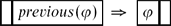 to
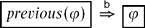
for the LTL clause
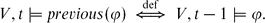
Both ⇒ and  are useful to analyze ϕ until ψ through auxiliary formulas ϕ ntil ψ
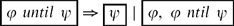
with
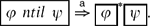
(Thus, if p and q are atomic formulas, we can picture p until q roughly as  ) Similarly, for since under the LTL clause
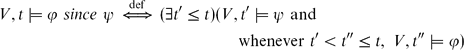
we apply  and auxiliary formulas ϕ sinc ψ
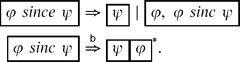
If we fix a tautology ┬ with the vacuous constraint

then the Priorean past Pϕ can be understood as an abbreviation of ┬ since ϕ, and its future counterpart Fϕ as ┬ until ϕ.
2.2 Unpadding for information content
Although the relation ⊵ is just right for formulating constraints, it is convenient to weaken it slightly to compare strings of different lengths. A candidate for the converse of the ‘in’ relation ⊑ from Section 1.3 satisfying
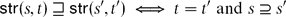
for all finite s,s'⊆𝕫 × P and t,t' ∈ 𝕫 is the relation ⊒° composing has-factor with ⊵
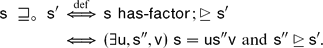
A finite-state transducer for ⊒° can be built from the one described in Section 1.4 above for has-factor by generalizing the transitions in line (19) to
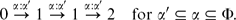
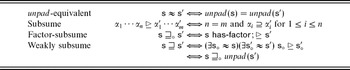
The relation ⊒° has the defect, however, that s ⊒ s' may fail to hold because of empty boxes in s' — e.g. 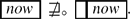 Accordingly, we unpad a string sinPow(Φ)* by deleting all initial and final □'s
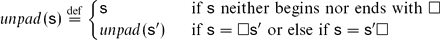
so that for example,  Next, we say s and s' are unpad-equivalent if their unpadding is identical
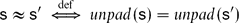
and say a string sweakly subsumes s', written s⊒ s', if some string unpad-equivalent to s subsumes some string unpad-equivalent to s'
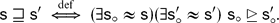
The relations unpad and ≈ are regular, and as
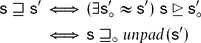
we can turn the finite-state transducer for ⊒° above into one for ⊒ by adding the loops
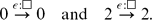
Of course, if we arrange that s' = unpad(s') for strings s' that we put to the right of ⊒, we can make do with ⊒° instead of ⊒.
Comparing information content

It is natural to think of strings in a language as possibilities in the same way that worlds in a proposition are under possible worlds semantics (or models of a sentence are in model-theoretic semantics). We lift ⊒ to languages L,L′ through the Peirce product
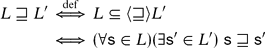
paralleling the definition in possible worlds semantics that a proposition A entails a proposition A′ if A ⊆ A′. To weed out spurious possibilities, it is useful to bring in a language C to intersect with 〈⊒〉L for
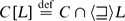
and then beef up L ⊒ L′ to an entailment
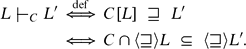
Clearly, L ├CL′ whenever L ⊒ L′. The introduction of C allows us not only to enlarge a string in L to one in 〈⊒〉L, but also to restrict attention to strings meeting the membership conditions for C
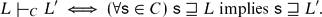
These membership conditions can be viewed as constraints (to satisfy), as we see next.
2.3 Some absolute formulas
A sentence ϕ is absolute if its description relation 𝓡[ϕ] is the 𝓐[ϕ]-restriction of ⊒, making its truth set 𝓣(ϕ) the Peirce product 〈⊒〉𝒜[ϕ]. We now flesh out 𝓐[ϕ] for certain absolute LTL-formulas ϕ—in particular, those belonging to the set P + of formulas that can be formed from a set P of atomic formulas using the connectives ∧, ∨, next, previous, until, ntil, since, sinc. We start with constraints 𝓒(ϕ) for ϕ ∈ P +, setting
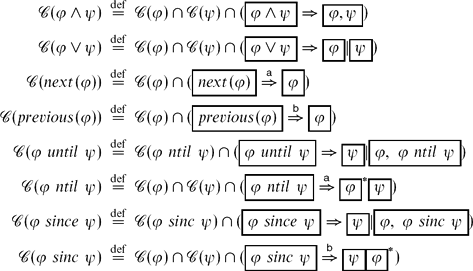
and for p ∈ P,
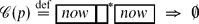
saying the fluent now occurs at most once. Next, we intersect 𝓒(ϕ) with the set  of strings in which ϕ and now occur in a box, to form
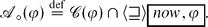
But what alphabet Pow(Φ) are we assuming for 𝓒(ϕ) and  Φ had better be finite if the Peirce product 〈⊑〉L is to be regular. It suffices (for our purposes) to let Φ be the finite subset Ψ(ϕ) of P + ∪ {now} consisting of ϕ and formulas mentioned in the definition of 𝓒(ϕ) — roughly ϕ, its subformulas and (now). For example,
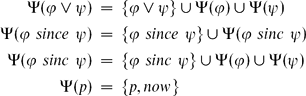
so that for p,q,r ∈ P,
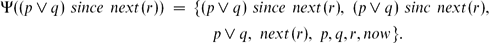
Even with the alphabet restricted, the language 𝒜°(ϕ) is quite massive. But we can reduce it a couple of ways. The first is through ⊵-minimization: given a language L, define the set L ⊵ of ⊵-minimal strings in L by
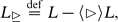
where ⊳ is ⊵ minus equality
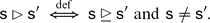
For example,
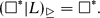
Notice that L ⊵ is regular if L is (as a finite-state transducer for ⊳ can be easily obtained from the one above for ⊵ by requiring that there be a proper inclusion ⊃). The second way of trimming a language is by projecting every string α1···αn in it to the string
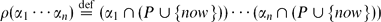
restricting the symbols to subsets of P ∪ {now}. For instance, if p ∈ P then

Clearly, as a relation, ρ is regular. Now, for ϕ ∈ P +, we take the ⊵-minimal strings in 𝒜°(ϕ), and apply ρ and unpad in succession to form
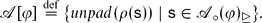
From the closure properties of regular languages, it follows that 𝓐[ϕ] is regular, as is 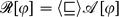 . To relate 𝓐[ϕ] to LTL, let us adopt the obvious interpretation of the connectives ntil
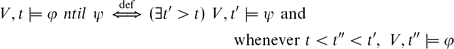
and sinc
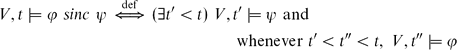
against relations V⊆𝕫 × P and integers t ∈ 𝕫). Moreover, as 0 is not one of the fluents out of which we construct strings in 𝓐[ϕ], we delete the fluent 0 in our encoding str(s,t) of a finite relation s ⊆ 𝕫 × P and an integer t ∈ 𝕫 to form the string str°(s,t). For example,
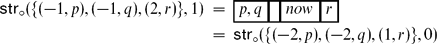
illustrating the possibility that now can be set without loss of generality to 0.Footnote 5 To establish the faithfulness of the about sets 𝓐[ϕ] to LTL, we can prove by induction on ϕ ∈ P + that
Theorem. For all 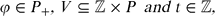

2.4 Irregular replace
All the clean-up on 𝒜°(ϕ) above just to extract 𝓐[ϕ] invites the question: why not define a regular relation unwinding a non-atomic formula ϕ rather than a regular language 𝓐[ϕ] via a system of constraints and projections? (Or for readers familiar with Beesley and Karttunen (Reference Beesley and Karttunen2003), why not replace, rather than constrain?) Take, for example, the formula Pp saying p holds now or sometime in the past. It is easy enough to construct a finite-state transducer for a relation  replacing Pp by p or shifting Pp backwards one square so that, for example,
Repeatedly applying , let tc() be the transitive closure of . We have for all non-negative integers m and n,
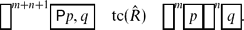
The difficulty, however, is tc() is not regular, even though is. To see this, consider feeding strings from the language  as inputs to tc(). What output strings do we get that belong in the language
 (where
 , as usual)? As each input string
 can move at most n p's into
 , there can be no more
 s than
 s in an output string, and we have
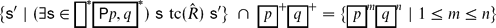
which is non-regular. It follows that tc() cannot be a regular relation since the languages and are regular. By contrast, constraints applied with  -minimization and unpad intersect with to give the regular sublanguage
 .
3 Conclusion
Regular relations 𝓡[ϕ] were defined for various absolute LTL formulas ϕ (collected in the set P +) from regular languages 𝓐[ϕ] satisfying constraints 𝒞(ϕ) that essentially reformulate well-known LTL tableau rules in finite-state terms. A theorem was isolated at the end of Section 2.3 asserting that 𝓐[ϕ] encodes satisfaction ⊧ relative to arbitrary relations V ⊆ 𝕫 × P over the full set 𝕫 of integers. The theorem is not surprising, but introduces machinery that is, I believe, of interest beyond the theorem. That said, the theorem does raise further questions about the relationship with LTL. Can we apply the about sets 𝓐[ϕ] to capture LTL entailments ├LTL between formulas in P +? What about non-absolute LTL formulas such as Gp? We turn to these questions below, before briefly touching one of the points behind introducing regular relations 𝓡[ϕ]—i.e., that of varying temporal granularity.
3.1 Entailments short of ├LTL
A problem with reducing LTL entailments
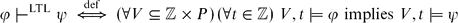
to 𝒜[ϕ] ⊑ 𝓐[ψ] is that a string in 𝓐[ϕ] may be too small to contain one in 𝒜[ψ]. Accordingly, the entailment
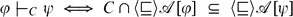
enlarges a string in 𝓐[ϕ] to one in C before searching for a (sub)string in 𝒜[ψ]. Each string, however, has a bounded temporal span short of 𝕫, representable as a finite segment
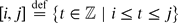
for i, j ∈ 𝕫. In effect, V, t ⊧ ϕ is replaced by
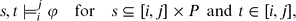
where for example,
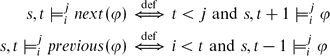
and
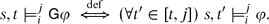
For non-negative integers m and n, let Cmn be the constraint
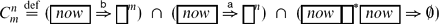
requiring that there be at least m boxes before the evaluation time now and n boxes after, and at most one occurrence of now. Then for ϕ, ψ ∈ P +,
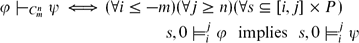
with now normalized to 0 to simplify notation. To build the negation p of an atomic proposition p into P, we intersect Cmn with the constraint
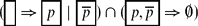
corresponding to a restriction in (21) to relations s ⊆ [i,j] × P satisfying

for t ∈ [i,j]. Observe that next n(p ∨ p) holds at 0 for any such relation s,
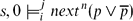
but not necessarily next n+1(p ∨ p). Similarly for previous m(p ∨ p).
Stepping beyond absolute formulas, notice that the LTL entailment
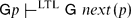
(saying ‘if p is true now and forever more, then so is next(p)’) does not go through for ├C (unless C precludes Gp), as
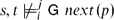
for all s ⊆ [i,j] × P and t ∈ [i,j].
3.2 Gp and some other non-absolute formulas
To say Gp is not absolute is to deny that 𝓡[Gp] can be the 𝒜[Gp]-restriction of ⊒, whatever 𝒜[Gp] might be. But if, in place of ⊑, we define a relation by
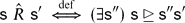
(sandwiched between ⊒ and ) and put
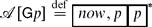
then we can set 𝓡[Gp] to the 𝒜[Gp]-restriction of
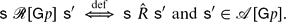
Similarly, for the past counterpart H of G with the semantic interpretation
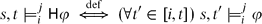
let
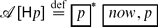
and
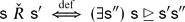
for
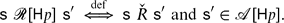
Generalizing over Gp and Hp, we can use in place of ⊑, or Ř, provided we pad 𝒜[Gp] to the left for
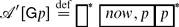
and 𝒜[Hp to the right for
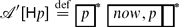
so that
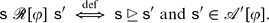
Under (22), 𝒜′[ϕ] need not be padded
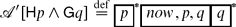
although for absolute formulas, the price of strengthening ⊒ to is padding to the left and rightFootnote 6
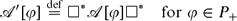
(undoing the step from ⊒ to ). Padding goes against the grain of defining 𝓡[ϕ] to get a handle on the temporal span of a ϕ-situation (useful, for example, for past tense reports; recall Section 1.4 above). On the other hand, it is easy enough to unpad 𝒜′[ϕ] for 𝓐[ϕ].
3.3 From temporal span to grain
If the image of 𝓡[ϕ] is unpadded, then we can replace ⊒ by ⊒° inasmuch as
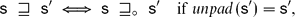
where
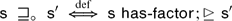
and factors are suffixes of prefixes (equivalently, prefixes of suffixes)
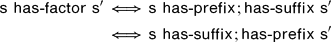
and a suffix is a tail end
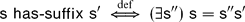
and a prefix is an initial fragment
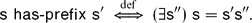
The ‘in’ relation for Gp replaces has-factor by has-suffix
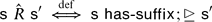
while the ‘in’ relation Ř for Hp uses has-prefix
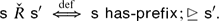
That said, an advantage of the formulation ⊒ over ⊒°
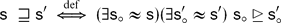
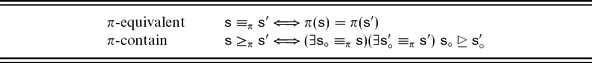
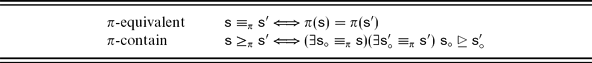
(where 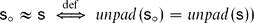 is that it generalizes from unpad to an arbitrary function π (Table 4).
Comparing information content modulo π.
An example of π suggested by the slogan ‘no time without change’ (Kamp and Reyle Reference Kamp and Reyle1993: 674) reduces all adjacent identical boxes ααn to one α. More precisely, the block compression bc(s) of a string s is given by
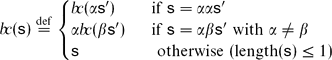
so that, for example,
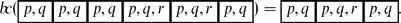
For a finite-state transducer computing bc, let the set of states be the alphabet plus the initial state 0, with transitions
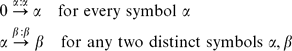
(to remember the symbol last seen)
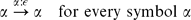
(to remove duplications) and all states final (accepting). If a string s is construed as a sequence of observations, the effect of bc(s) is to keep time still if no change (from the previous box) is observed. Exactly what observations are allowed is the crucial issue of granularity, which amounts in the present context to what fluents may occur in a symbol α. The LTL connective previous makes each tick of the clock 𝕫 count as an observation, thereby neutralizing bc. For instance, the string  is treated in LTL as
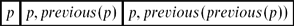
which bc leaves unchanged, whereas 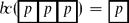 . Evidently, we must apply block compression on a string only if it records all information of interest explicitly as fluents. As our interests may change, it is useful to define for any set X ⊑ Φ) of fluents, a function ρX on strings that restricts the observations to X by intersecting componentwise with X
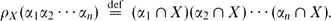
For example, if X = {Jan, Feb,. . ., Dec}, ρX projects the string

(over the 43 fluents Jan, Feb,. . ., Dec, d1, d2,. . ., d31) representing a leap year to
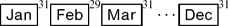
which bc maps to the string
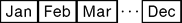
of length 12. Composing ρX; bc further with unpad gives regular relations
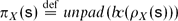
relative to which event structures (in the sense of Kamp and Reyle Reference Kamp and Reyle1993) can be constructed as inverse (projective) limits over finite sets X of fluents (Fernando Reference Fernando2007, Reference Fernando2010). Integrating calendar expressions with temporal propositions, the basic idea is to work with strings that have no more and no less information than what is given. Natural language descriptions do not, as a rule, mention a clock, and rarely the clock 𝕫 (however natural that may be for LTL applications).
Acknowledgments
I thank my referees for their critical and constructive comments, and Anssi Yli-Jyrä for his work as editor.
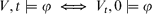
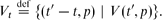
 in Fernando (