



1. Introduction
The mean-variance criterion, introduced in [Reference Markowitz14], has long been recognized as the foundation of modern portfolio theory. It allows us to balance the goal of maximizing the return of an investment against minimizing the variability of that return, a measure of the risk. Since Markowitz’s pioneering work, a large number of papers have been devoted to generalizing [Reference Markowitz14] to a multi-period or a continuous-time framework. However, because the variance term in the mean-variance objective does not satisfy the iterated-expectation property, which implies that the criterion does not satisfy the dynamic programming principle, the traditional dynamic-programming approach cannot be directly applied to dynamic mean-variance asset allocation problems, thereby resulting in time inconsistency.
One way to handle this time inconsistency in mean-variance analysis is to construct a ‘time-consistent’ solution, that is, to place the problem within a game-theoretic framework to determine a subgame perfect Nash equilibrium for the game, a game where the decision maker essentially plays against all future versions of herself. By using this framework, [Reference Basak and Chabakauri1] created a recursive representation for the mean-variance functional. In a general Markovian setting, [Reference Björk and Murgoci3] considered a fairly general class of time-inconsistent objective functions, using the game-theoretic approach to derive an extended Hamilton–Jacobi–Bellman (HJB) system of equations and provide a corresponding verification theorem. This was extended in [Reference Björk, Murgoci and Zhou4] to find the time-consistent strategy for a mean-variance portfolio problem with a state-dependent risk aversion. [Reference Landriault, Li, Li and Young11] investigated equilibrium investment strategies for a dynamic mean-variance problem over a random horizon.
In recent decades, individuals have become increasingly responsible for managing their own retirement funds and are strongly encouraged to invest in retirement savings plans to supplement government-provided pensions. This trend suggests that life annuities will likely become more useful in retirement planning in the coming decades. To help individuals make better decisions and enjoy a more secure retirement, many researchers have focused on studying strategies for purchasing life annuities and investing in a risky financial market. For example, [Reference Milevsky and Young15] analyzed the optimal investment, consumption, and annuitization strategies for a retiree with random time of death and preferences exhibiting constant relative risk aversion. [Reference Bayraktar and Young2] allowed the decision maker to purchase deferred life annuities to minimize the probability of lifetime ruin. Under the framework of [Reference Milevsky and Young15], [Reference Wang and Young17] assumed that the retiree can surrender part of her existing annuity income by paying a proportional surrender fee. [Reference Liang and Young12] considered an annuitization model in which the individual can purchase life annuities gradually at a bounded, continuous rate. [Reference Guan, Liang and Ma10] studied the optimal consumption, investment, and annuitization problem for a retiree with a consumption habit.
In this paper we solve two dynamic mean-variance problems for an individual who purchases life annuities and invests her wealth in a risky asset. In the first problem, the buyer is allowed to purchase life annuities at a bounded, continuous rate. By following the approach in [Reference Björk and Murgoci3], we find the individual’s time-consistent equilibrium control strategies explicitly, along with her value function, from the relevant extended HJB system of equations. We show that the equilibrium annuitization strategy is a type of barrier strategy. Specifically, when the current cumulative annuity income is less than the barrier, the individual purchases life annuities at the maximum annuity rate; when the current cumulative annuity income is above that barrier, however, the individual buys no additional life annuity income. Although the extended HJB system of equations is similar to the system in [Reference Landriault, Li, Li and Young11] in that the horizon is random, the application to the problem of purchasing life annuities is new. Specifically, [Reference Landriault, Li, Li and Young11] considered only investment problems with a random horizon, and it might be argued that allowing for a random horizon generated by the time of death of the individual is more realistic for life-annuity problems than for those only modeling investment.
In the second problem, the buyer may purchase any amount of life annuity income at any time. This setting results in a singular control problem, as studied in the stochastic control literature. To our knowledge, there are only two papers on singular control in time-inconsistent optimization problems [Reference Dai, Jia and Jin6, Reference Liang, Luo and Yuan13]. [Reference Dai, Jia and Jin6] considered Merton’s problem with proportional transaction costs under the mean-variance criterion. Proportional transaction costs led to singular control, as in [Reference Davis and Norman7]. [Reference Liang, Luo and Yuan13] showed the existence of equilibria for a reinsurance problem with singular control in the reinsurance strategy; time inconsistency arose from non-exponential discounting. Our contributions to this new area are as follows: (i) In Definitions 3.1, we define equilibrium strategies and the corresponding value function, allowing for singular controls. Our definition is similar to the one in [Reference Dai, Jia and Jin6]. (ii) We prove a verification lemma, Lemma 3.1, for our annuitization problem that contains a variational inequality due to the presence of singular control, a new result in the literature. (iii) In Theorem 3.1, we use the verification lemma to obtain an equilibrium explicitly. We find that the equilibrium annuitization strategy is also a barrier strategy, and the barrier is identical to the one we obtained in the first problem. In this singular-control case, if the current annuity income is below the barrier, then the individual will immediately purchase a lump sum of annuity income so that the total annuity income equals the equilibrium annuity barrier; otherwise, if annuity income is greater than the barrier, the individual will buy no additional annuity income. Interestingly, the equilibrium amounts invested in the risky asset in both models are also identical, each equaling a constant, independent of the individual’s current wealth and annuity income.
The rest of this paper is organized as follows. In Section 2 we present the financial and life annuity markets in which the individual can invest in a risky asset and purchase life annuity at a bounded, continuous rate, we obtain the buyer’s wealth process, and we define her problem under the mean-variance criterion. By applying the approach in [Reference Björk and Murgoci3], we find the individual’s time-consistent equilibrium control strategy and corresponding value function from the extended HJB system of equations. We also analyze the effects of the parameters on the equilibrium strategy. In Section 3, we modify the model of Section 2 by allowing the buyer to purchase any amount of life annuity at any time. To solve this problem, we prove a verification lemma that includes a variational inequality due to the nature of singular control. We obtain a time-consistent equilibrium control strategy and the value function by solving the variational inequality. Moreover, let
 $\tilde X$
denote the wealth process under the time-consistent equilibrium strategy given in Theorem 3.1; we find two representations of
 $\tilde X$
in Corollary 3.1, and we obtain the corresponding probability of lifetime ruin in Corollary 3.2. Section 4 concludes the paper.
2. Buying annuity income continuously at a bounded rate
In this section, we first present the financial ingredients (namely, consuming, investing in a risky asset, purchasing life annuity income continuously at a bounded rate). Then, we obtain the buyer’s wealth process, and we define her problem (namely, choosing her life annuity purchasing strategy and the dollar amount to invest in the risky asset) under the mean-variance criterion. We also obtain the time-consistent equilibrium strategy of the buyer. In Section 3, we modify the model of Section 2 by allowing the buyer more flexibility in how she buys annuity income.
Let
 $(\Omega,\mathcal{F},\mathbb{P})$
be a complete probability space with a filtration
 $\{\mathcal{F}_t\}_{t \ge 0}$
. Let
 $\tau$
be the random time of death of the decision maker, generally called the buyer (of life annuities), defined on the probability space
 $(\Omega,\mathcal{F},\mathbb{P})$
. We assume
 $\tau$
follows an exponential distribution with constant hazard rate
 $\lambda > 0$
, that is,
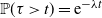 $\mathbb{P}(\tau > t) = \textrm{e}^{-\lambda t}$
,
 $t \ge 0$
. Furthermore, the buyer can invest her wealth in a risky asset whose price process
 $S = \{ S_t \}_{t \ge 0}$
follows geometric Brownian motion,
 $\textrm{d} S_t = \mu S_t\,\textrm{d} t + \sigma S_t\,\textrm{d} B_t$
, in which
 $\mu > 0$
,
 $\sigma > 0$
, and
 $B = \{ B_t \}_{t \ge 0}$
is a standard Brownian motion defined on the filtered probability space
 $(\Omega, \mathcal{F}, \mathbb{F} = \{\mathcal{F}_t \}_{t \ge 0}, \mathbb{P})$
and is independent of the individual’s random time of death
 $\tau$
. Let
 $\pi(x, A, t) \in \mathbb{R}$
denote the amount of wealth the individual invests in the risky asset at time t when her wealth and annuity income at that time equal x and A, respectively.
The buyer consumes at a continuous rate c. As an aside, if the buyer receives income other than from her life annuity, then we interpret c as the rate of consumption net of that non-annuity income. The lump-sum price of an immediate life annuity that pays $1 per year continuously until the insured’s death equals
 $\bar{a}$
, and we assume throughout that
 $\bar{a} \lambda \ge 1$
, that is, annuities are not ‘cheap’ relative to the individual’s mortality hazard rate.
Let
 $X_t$
denote the buyer’s wealth at time t, and let
 $A_t$
denote the cumulative amount of (immediate) life annuity income purchased at or before time t. Let
 $q(x, A, t) \ge 0$
denote the (dollar) rate at which the buyer purchases annuities at time t when her wealth at that time equals x and her annuity income at that time equals A. In this section, we assume the buyer has a fixed amount of disposable income for buying annuity, that is, we require
 $q(x, A, t) \in [0, \bar{q}]$
for all
 $(x, A, t) \in \mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+$
, in which
 $\bar{q} > 0$
is the maximum allowable annuitization rate. The buyer’s controlled wealth process
 $X = \{X_t\}_{t \ge 0}$
therefore follows
 \begin{equation} \textrm{d} X_t = (A_t - c + \mu \pi(X_t, A_t, t) - q(X_t, A_t, t))\,\textrm{d} t + \sigma \pi(X_t, A_t, t)\,\textrm{d} B_t,\end{equation}
with the cumulative annuity income process
 $A = \{A_t\}_{t \ge 0}$
satisfying
 \begin{equation*}\textrm{d} A_t = \dfrac{q(X_t, A_t, t)}{\bar{a}} \, \textrm{d} t.\end{equation*}
Next, we define admissible life annuity and investment strategies for the buyer.
Definition 2.1. (Admissible life annuity and investment strategies) A life annuity and investment strategy
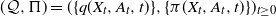 $(\mathcal{Q},\Pi) = (\{q(X_{t},A_t,t)\},\{\pi(X_{t},A_t,t)\})_{t \ge 0}$
is called admissible if it satisfies the following properties:
-
(i) Equation (2.1) has a unique strong solution for any
 $X_{0} = x \in \mathbb{R}$
and
$A_0 = A \ge 0$
.
-
(ii) q is a non-negative Borel-measurable function in
$[0, \bar{q}]$
, and
$\pi$
is a real-valued Borel-measurable function. -
(iii)
$\int_0^t \pi^2(X_s, A_s, s)\,\textrm{d} s < \infty$
with probability 1, for all
$t \ge 0$
.


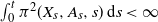

Note that admissible strategies are feedback strategies.
We assume that the buyer has mean-variance preferences and seeks to maximize the mean-variance functional evaluated at her wealth at death, namely,
 $X_\tau$
. Thus, given a life annuity and investment strategy
 $(\mathcal{Q}, \Pi)$
, the buyer’s objective function is
 \begin{equation} J(x, A, t; \mathcal{Q}, \Pi) = \mathbb{E}_{x, A, t}(X_\tau) - \dfrac{\gamma}{2} \, \mathbb{V}_{x, A, t}(X_\tau),\end{equation}
in which
 $\mathbb{E}_{x, A, t}$
and
 $\mathbb{V}_{x, A, t}$
denote expectation and variance, respectively, conditional on
 $X_{t} = x \in \mathbb{R}$
,
 $A_t = A \ge 0$
, and
 $\tau > t$
, and the parameter
 $\gamma > 0$
measures her aversion for variance. The mean-variance objective in (2.2) can lead to a time-inconsistent problem because variance does not satisfy the property of iterated expectations, which implies that the mean-variance criterion does not satisfy the dynamic programming principle. To handle this potential problem, we assume the buyer plays against all future versions of herself and seeks to maximize her criterion, given her future choices, as in [Reference Björk and Murgoci3, Reference Björk, Murgoci and Zhou4]. In the following, we define the time-consistent strategy
 $(\hat{\mathcal{Q}}, \hat \Pi)$
for the individual.
Definition 2.2. For a given admissible strategy
 $(\hat{\mathcal{Q}}, \hat \Pi)$
, fix an arbitrary initial time
 $t \ge 0$
, a positive number
 $\varepsilon$
, a non-negative number
 $q \in [0, \bar{q}]$
, and a real number
 $\pi$
. Then, define the strategy
 $(\mathcal{Q}^{\varepsilon}, \Pi^{\varepsilon})$
by
 \begin{equation*} q^{\varepsilon}_s = \begin{cases} q, & t \le s < t + \varepsilon, \\ \hat q_s, & s \ge t + \varepsilon; \end{cases} \qquad \pi^{\varepsilon}_s = \begin{cases} \pi, & t \le s < t + \varepsilon, \\ \hat \pi_s, & s \ge t + \varepsilon, \end{cases} \end{equation*}
in which we write
 $q^{\varepsilon}_s$
and
 $\pi^{\varepsilon}_s$
in place of
 $q^{\varepsilon}(X_{s}, A_{s}, s)$
and
 $\pi^{\varepsilon}(X_{s}, A_{s}, s)$
, respectively, and similarly for
 $\hat q_s$
and
 $\hat \pi_s$
. The strategy
 $(\hat{\mathcal{Q}}, \hat \Pi)$
is said to be a time-consistent equilibrium strategy if, for all
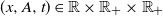 $(x, A, t) \in \mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+$
and all
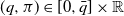 $(q, \pi) \in [0, \bar{q}] \times \mathbb{R}$
,
 \begin{equation*} \liminf_{\varepsilon \to 0^+} \, \dfrac{J(x,A,t \ ; \hat{\mathcal{Q}},\hat\Pi) - J(x,A,t \, ; \, \mathcal{Q}^{\varepsilon}, \Pi^{\varepsilon})}{\varepsilon} \ge 0, \end{equation*}
and the equilibrium value function V is
 \begin{equation} V(x, A, t) = J(x, A, t \, ; \, \hat{\mathcal{Q}}, \hat \Pi). \end{equation}
Before we find the time-consistent equilibrium strategy for the buyer, we present a verification lemma for solving her problem. For the statement of the verification lemma, we define a differential operator corresponding to our problem
 $\mathcal{L}^{(q, \pi)}$
, for all
 $\phi \in \mathcal{C}^{2, 1, 1}(\mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+)$
,
 $q \in [0,\bar{q}]$
, and
 $\pi \in \mathbb{R}$
, by
 \begin{align} \mathcal{L}^{(q, \pi)} \phi(x, A, t) & = \phi_t(x,A, t) + (A - c + \mu \pi - q)\phi_x(x,A,t) + \dfrac{1}{2} \, \sigma^2 \pi^2 \phi_{xx}(x, A, t) \nonumber\\ & \quad + \dfrac{q}{\bar{a}} \, \phi_A(x,A,t). \end{align}
We omit the proof of the following verification lemma for V because it is similar to the proof of [Reference Landriault, Li, Li and Young11, Theorem 3.1].
Lemma 2.1. Suppose there exist two real-valued functions
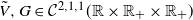 $\tilde V, G \in \mathcal{C}^{2, 1, 1}(\mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+)$
, except that
 $G(x, \cdot, t)$
might only be continuous along a curve
 $A = \hat{A}(x, t)$
with left and right derivatives along that curve, that satisfy the following conditions:
-
(i) For all
$(x, A, t) \in \mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+$
, (2.5)Let
\begin{multline} \sup_{q\in[0,\bar{q}],\,\pi\in\mathbb{R}}\bigg\{\mathcal{L}^{(q,\pi)}\tilde V(x, A, t) - \dfrac{\gamma}{2}\,\mathcal{L}^{(q,\pi)}G^2(x, A, t) + \gamma G(x, A, t)\,\mathcal{L}^{(q,\pi)}G(x, A, t)\bigg\} \\ = \lambda\bigg(\tilde V(x, A, t) - x + \dfrac{\gamma}{2}\,(G(x, A, t) - x)^2\bigg). \end{multline}
$\hat q(x, A, t)$
and
$\hat \pi(x, A, t)$
denote the maximizers of this HJB equation. Suppose the induced strategy
$(\hat{\mathcal{Q}}, \hat \Pi)$
is admissible.
-
(ii) For all
$(x, A, t) \in \mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+$
, (2.6)
\begin{equation} \mathcal{L}^{(\hat q(x, A, t), \hat \pi(x, A, t))} G(x, A, t) = \lambda(G(x, A, t) - x). \end{equation}
-
(iii) For all
$(x, A, t) \in \mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+$
, the following transversality condition holds: for
\begin{equation} \lim\limits_{s\to\infty}\textrm{e}^{-\lambda (s - t)}\,\mathbb{E}_{x, A, t}(\phi(X_{s}, A_s, s)) = 0 \end{equation}
$\phi = \tilde V$
, G, and
$G^2$
.
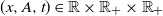


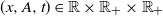


Then,
 $\tilde{V}$
equals the individual’s equilibrium value function V defined in (2.3), and
 $(\hat{\mathcal{Q}}, \hat \Pi)$
is a time-consistent equilibrium strategy for the buyer of life annuities. Moreover,
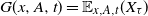 $G(x, A, t) = \mathbb{E}_{x, A, t}(X_\tau)$
under this strategy.
In the following theorem we use Lemma 2.1 to obtain a time-consistent equilibrium strategy and corresponding value function for the annuity buyer.
Theorem 2.1. Define the function
 $\hat q$
and constant
 $\hat \pi$
by
 \begin{equation} \hat q(A) = \begin{cases} \bar{q}, & A < \hat{A}, \\ 0, & A \ge \hat{A}; \end{cases} \qquad \hat \pi \equiv \frac{\mu}{\gamma \sigma^2}, \end{equation}
in which the barrier
 $\hat{A}$
is
 \begin{equation} \hat{A} = \dfrac{1}{\gamma}\bigg(\gamma c - \bigg(\lambda(\bar{a}\lambda - 1) + \frac{\mu^2}{\sigma^2}\bigg)\bigg)_+. \end{equation}
Then, the strategy
 $(\hat{\mathcal{Q}}, \hat \Pi) = (\{\hat q(A_t)\},\{\hat\pi\})_{t \in \mathbb{R}_+}$
is a time-consistent equilibrium strategy as defined in Definition 2.2. Moreover,
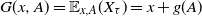 $G(x, A) = \mathbb{E}_{x, A}(X_\tau) = x + g(A)$
, in which
 \begin{equation} g(A) = \begin{cases} \dfrac{1}{\lambda}\bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg) - \dfrac{\bar{q}}{\lambda}\bigg(1 - \dfrac{1}{\bar{a}\lambda}\bigg) (1 - \textrm{e}^{-({\bar{a}\lambda}/{\bar{q}})(\hat{A} - A)}), & A < \hat{A}, \\[3mm] \dfrac{1}{\lambda}\bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg), & A \ge \hat{A}, \\ \end{cases} \end{equation}
and the corresponding time-independent value function is
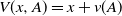 $V(x, A) = x + v(A)$
, in which, for
 $A \ge \hat{A}$
,
 \begin{equation} v(A) = \dfrac{1}{\lambda}\bigg(A - c + \frac{\mu^2}{2\gamma\sigma^2}\bigg) - \dfrac{\gamma}{2\lambda^2}\bigg(A - c + \frac{\mu^2}{\gamma\sigma^2}\bigg)^2 \end{equation}
and, for
 $A < \hat{A}$
, v(A) satisfies the following ordinary differential equation (ODE):
 \begin{equation} v'(A) - \frac{\bar{a}\lambda}{\bar{q}}\,v(A) + \frac{\bar{a}}{\bar{q}}\bigg(A - c + \frac{\mu^2}{2\gamma\sigma^2} - \bar{q} - \frac{\lambda\gamma}{2}\,g^2(A)\bigg)=0, \end{equation}
with boundary condition
 $v(\hat{A}^-) = v(\hat{A}^+)$
.
Proof. Because the problem is time-homogeneous, the value function is time-independent. Moreover, from the mean-variance criterion and from the dynamics of X in (2.1), we deduce that the value function equals
 $x + v(A)$
, for some function v(A). Thus,
 $V(x, A) = x + v(A)$
and
 $G(x, A) = x + g(A)$
for some function g(A). By substituting
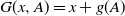 $G(x, A) = x + g(A)$
into (2.6), we obtain
 \begin{equation} (A - c + \mu \hat \pi - \hat q) + \dfrac{\hat q}{\bar{a}} \, g'(A) = \lambda g(A). \end{equation}
Also, by substituting
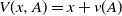 $V(x, A) = x + v(A)$
and
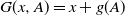 $G(x, A) = x + g(A)$
into (2.5), the HJB equation becomes
 \begin{equation} \sup_{q\in[0,\bar{q}],\,\pi\in\mathbb{R}}\bigg\{(A - c + \mu\pi - q) - \dfrac{\gamma}{2}\sigma^2\pi^2 + \dfrac{q}{\bar{a}}\,v'(A)\bigg\} = \lambda\bigg(v(A) + \dfrac{\gamma}{2}\,g^2(A)\bigg). \end{equation}
Note that the expression in braces is concave with respect to
 $\pi$
; thus, the critical point from the first-order condition gives us the equilibrium investment amount
 $\hat \pi$
, as stated in (2.7). Moreover, because the expression in (2.13) is linear with respect to q, the equilibrium solution generally takes values at the endpoints of the interval
 $[0, \bar{q}]$
, that is,
 \begin{equation*} \hat q(A) = \begin{cases} \bar{q}, & v'(A) > \bar{a}, \\ \textrm{anything in } [0,\bar{q}], & v'(A) = \bar{a}, \\ 0, & v'(A) < \bar{a}. \end{cases} \end{equation*}
Define
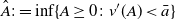 $\hat{A} := \inf\{ A \ge 0\colon v'(A)< \bar{a} \}$
; we hypothesize that the equilibrium annuitization strategy is
 \begin{equation*} \hat q(A) = \begin{cases} \bar{q}, & A < \hat{A}, \\ 0, & A \ge \hat{A}, \end{cases} \end{equation*}
which requires
 $v'(A) \le \bar{a}$
for all
 $A \ge \hat{A}$
.
In the following, we derive expressions or equations for v(A) and g(A), depending on whether
 $A \ge \hat{A}$
or
 $A < \hat{A}$
.
For
 $A \ge \hat{A}$
, our ansatz is
 $\hat q \equiv 0$
. By substituting
 $\hat q = 0$
and
 $\hat = {\mu}/{\gamma\sigma^2}$
into (2.12), we obtain
 \begin{equation*} g(A) = \frac{1}{\lambda}\bigg(A - c + \frac{\mu^2}{\gamma\sigma^2}\bigg). \end{equation*}
Similarly, by substituting these values of
 $\hat q$
and
 $\hat \pi$
into the HJB equation (2.13), we get
 \begin{equation*} A - c + \dfrac{\mu^2}{2 \gamma \sigma^2} = \lambda v(A) + \frac{\lambda \gamma}{2} g^2(A), \end{equation*}
from which we obtain the expression for v given in (2.10). The first and second derivatives of v(A) with respect to A are
 \[ v'(A) = \frac{1}{\lambda} - \frac{\gamma}{\lambda^2}\bigg(A - c + \frac{\mu^2}{\gamma\sigma^2}\bigg), \qquad v''(A) = -\frac{\gamma}{\lambda^2} < 0, \]
which shows that
 $v'(A) \le \bar{a}$
for all
 $A \ge \hat{A}$
because we obtain the value of
 $\hat{A}$
given in (2.8) by solving
 $v'(A)|_{A = \hat{A}^+} = \bar{a}$
.
If
 $A < \hat{A}$
,
 $\hat q \equiv \bar{q}$
. By substituting the values of
 $\hat q = \bar{q}$
and
 $\hat\pi = {\mu}/{\gamma\sigma^2}$
into (2.12), we obtain an ODE for g(A):
 \begin{equation*} \bigg(A - c + \frac{\mu^2}{\gamma\sigma^2} - \bar{q}\bigg) + \dfrac{\bar{q}}{\bar{a}}\,g'(A) = \lambda g(A), \end{equation*}
with the boundary condition
 \begin{equation*} g(\hat{A}^-) = g(\hat{A}^+) = \frac{1}{\lambda}\bigg(\hat{A} - c + \frac{\mu^2}{\gamma\sigma^2}\bigg). \end{equation*}
By solving this boundary-value problem, we get
 \begin{equation*} g(A) = \frac{1}{\lambda}\bigg(A - c + \frac{\mu^2}{\gamma\sigma^2}\bigg) - \frac{\bar{q}}{\lambda}\bigg(1 - \frac{1}{\bar{a}\lambda}\bigg) (1 - \textrm{e}^{-({\bar{a}\lambda}/{\bar{q}})(\hat{A} - A)}). \end{equation*}
(As an aside, note that
 $g'(A)|_{A \to \hat{A}^-} = \bar{a}$
, and
 $g'(A)|_{A \to \hat{A}^+} = {1}/{\lambda}$
; thus, g(A) is not continuously differentiable at the single point
 $A = \hat{A}$
, unless
 $\bar{a}\lambda = 1$
.) Similarly, by substituting the values of
 $\hat q$
and
 $\hat \pi$
into the HJB equation (2.13), we obtain
 \begin{equation*} \bigg(A - c + \frac{\mu^2}{2\gamma\sigma^2} - \bar{q}\bigg) + \dfrac{\bar{q}}{\bar{a}}\,v'(A) = \lambda v(A) + \frac{\lambda \gamma}{2} g^2(A), \end{equation*}
which is equivalent to (2.11) with boundary condition
 $v(\hat{A}^-) = v(\hat{A}^+)$
, and, from the continuity of
 $(\hat q/\bar{a}) v'(A) - \hat q$
in v’s differential equation, we deduce that
 $v'(\hat{A}^-) = v'(\hat{A}^+) = \bar{a}$
. In Lemma A.1 in Appendix A we show that
 $v'(A) > \bar{a}$
for all
 $A < \hat{A}$
.
To check that the proposed value function is, indeed, the value function as defined in (2.3) and that the corresponding strategies are equilibrium strategies, we verify the conditions given in Lemma 2.1. Conditions (i) and (ii) hold by construction. For the transversality condition, note that, under the candidate life annuity strategy,
 $A_s \le \max(A, \hat{A})$
for all
 $s \ge 0$
(in which
 $A_0 = A$
), and the candidate investment strategy is a constant, so the individual’s wealth process
 $X = \{X_t\}_{t \ge 0}$
in (2.1) reduces to a diffusion process with bounded coefficients; thus, condition (iii) holds. We thereby complete the proof of this theorem.
In the following corollary, we analyze properties of the equilibrium strategies; we present the corollary without proof because it is straightforward to prove from (2.7) and (2.8).
Corollary 2.1.
-
(i) The equilibrium amount to invest in the risky asset
$\hat \pi$
in (2.7) increases with respect to
$\mu$
, decreases with respect to
$\gamma$
and
$\sigma$
, and is independent of
$\lambda$
and c. -
(ii) The equilibrium cumulative annuity barrier
$\hat{A}$
in (2.8) increases with respect to
$\gamma$
, c, and
$\sigma$
, and decreases with respect to
$\lambda$
,
$\mu$
, and
$\bar{a}$
.


Remark 2.1. If
 $\hat{A}$
in (2.8) is positive, then we can write it as follows:
 \[ \hat{A} = c - \frac{\mu^2}{\gamma \sigma^2} - \dfrac{\lambda}{\gamma} \, (\bar{a} \lambda - 1). \]
We interpret the three terms in the above expression as follows:
-
• The first term equals the rate of consumption, thereby demonstrating that the individual will choose her level of annuity income to cover living expenses.
-
• The second term equals the amount that the individual invests in the risky asset, which increases as the financial market becomes more favorable, that is, as
$\mu$
increases or
$\sigma$
decreases. Thus, as the financial market becomes more favorable, the individual purchases less annuity income because expected returns in the market can cover some of her consumption. This phenomenon is related to survey data of [Reference Goedde-Menke, Lehmensiek-Starke and Nolte9], which found that those who believe they know better than financial institutions about how to prevent lifetime ruin also have a lower likelihood of purchasing annuity income. Note that as the individual becomes more variance averse, as measured by
$\gamma$
, she invests less in the financial market, and the negative effect of this second term on
$\hat{A}$
decreases. -
• The third term captures the effect of the individual’s rate of mortality when deciding how much annuity income to buy. As
$\lambda$
increases,
$\lambda(\bar{a} \lambda - 1)$
increases. (Recall that we assume
$\bar{a} \lambda - 1 \ge 0$
throughout this paper.) Thus, as the individual becomes more likely to die, she purchases less annuity income because she is less likely to fully recover the annuity’s value. This observation is related to empirical evidence that annuitants live longer than non-annuitants with similar characteristics; see, for example, [Reference Finkelstein and Poterba8]. Also, if annuity income becomes more expensive, that is,
$\bar{a}$
increases, then the individual purchases less income. As for the second term, the negative effect of the third term on
$\hat{A}$
decreases as the individual becomes more variance averse, that is, as
$\gamma$
increases.


3. Singular control of annuity income
In this section we do not require that the individual purchase annuity income at a bounded, continuous rate. For example, the individual might wish to spend a lump sum to purchase annuity income, which is suggested by the equilibrium solution in Section 2. Specifically, if existing annuity income is less than
 $\hat{A}$
, then in Section 2, the buyer spends at her maximum rate
 $\bar{q}$
to increase her annuity income so that it equals
 $\hat{A}$
.
We modify admissible life annuity strategies as follows: let the cumulative amount of annuity income purchased on or before time t,
 $A_t$
, be a Borel-measurable function
 $\mathcal{A}$
of
 $X_{t^-}$
,
 $A_{t^-}$
, and t, such that
 $\mathcal{A} = \{ A_t \}_{t \ge 0}$
is non-negative and non-decreasing over time. By allowing the individual to purchase annuity income in any manner, her wealth equation becomes
 \begin{equation} \textrm{d} X_t = (A_{t^-} - c + \mu \pi(X_{t^-}, A_{t^-}, t))\,\textrm{d}t + \sigma\pi(X_{t^-}, A_{t^-}, t)\,\textrm{d}B_t - \bar{a}\,\textrm{d} A_t, \end{equation}
in which
 $A_t = \mathcal{A}(X_{t^-}, A_{t^-}, t)$
. For a given admissible strategy
 $(\mathcal{A}, \Pi)$
, define the objective function
 $\mathcal{J}$
by
 \begin{equation} \mathcal{J}(x, A, t; \mathcal{A}, \Pi) = \mathbb{E}_{x, A, t}(X_\tau) - \dfrac{\gamma}{2} \, \mathbb{V}_{x, A, t}(X_\tau),\end{equation}
in which X follows the process in (3.1). In (3.2),
 $\mathbb{E}_{x, A, t}$
and
 $\mathbb{V}_{x, A, t}$
now denote expectation and variance, respectively, conditional on
 $X_{t^-} = x \in \mathbb{R}$
,
 $A_{t^-} = A \ge 0$
, and
 $\tau > t$
,
Next, we define the time-consistent equilibrium for this problem. We say a function f is
 $\alpha$
-Hölder continuous if there exists a positive constant
 $C_{\alpha}$
such that
 $|f(u+\varepsilon) - f(u)|\le C_{\alpha} \varepsilon^{\alpha}$
, when
 $\varepsilon$
is sufficiently small.
Definition 3.1. For a given admissible strategy
 $(\tilde{\mathcal{A}}, \tilde{\Pi})$
, fix an arbitrary initial time
 $t \ge 0$
, a positive number
 $\varepsilon$
, a non-negative number
 $\Delta A$
, a real number
 $\pi$
, and
 $\mathcal{H}$
, a non-decreasing deterministic
 $\alpha$
-Hölder continuous function on
 $[t, t + \varepsilon)$
with
 $\alpha \in (0,1]$
. Then, define the strategy
 $(\mathcal{A}^{\varepsilon}, \Pi^{\varepsilon})$
, which starts at time t, by
 \begin{equation} A^{\varepsilon}_s = \begin{cases} \tilde{A}_{t^-} + \Delta A + \int^s_t \textrm{d} \mathcal{H}_u, & t \le s < t + \varepsilon, \\ A^{\varepsilon}_{(t+\varepsilon)^-} + \Delta\tilde{A}_{t+\varepsilon} + \int_{t+\varepsilon}^s\textrm{d}\tilde{A}_u, & s \ge t + \varepsilon, \end{cases} \end{equation}
and
 \begin{equation} \pi^{\varepsilon}_s = \begin{cases} \pi, & t \le s < t +\varepsilon, \\ \tilde{\Pi}_s, & s \ge t + \varepsilon, \end{cases} \end{equation}
in which we write
 $A^{\varepsilon}_s$
and
 $\pi^{\varepsilon}_s$
in place of
 $\mathcal{A}^{\varepsilon}(X_{s^-},A_{s^-},s)$
and
 $\pi^{\varepsilon}(X_{s^-}, A_{s^-}, s)$
, respectively, and similarly for
 $\tilde{A}_s$
and
 $\tilde{\Pi}_s$
. The strategy
 $(\tilde{\mathcal{A}}, \tilde{\Pi})$
is said to be a time-consistent equilibrium strategy if, for all
 $(x, A, t) \in \mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+$
, all
 $(\Delta A, \pi) \in \mathbb{R}_+ \times \mathbb{R}$
, and all non-decreasing
 $\alpha$
-Hölder continuous functions
 $\mathcal{H}$
,
 \begin{equation} \liminf_{\varepsilon \to 0^+} \, \dfrac{\mathcal{J}(x, A, t \, ; \, \tilde{\mathcal{A}}, \tilde{\Pi}) - \mathcal{J}(x, A, t \, ; \, \mathcal{A}^{\varepsilon}, \Pi^{\varepsilon})}{\varepsilon^{\alpha}} \ge 0, \end{equation}
and the equilibrium value function
 $\mathcal{V}$
is
 \begin{equation} \mathcal{V}(x, A, t) = \mathcal{J}(x, A, t \, ; \, \tilde{\mathcal{A}}, \tilde{\Pi}). \end{equation}
We modify the differential operator
 $\mathcal{L}^{(q, \pi)}$
in (2.4) as follows: for
 $\pi \in \mathbb{R}$
, define a differential operator
 $\mathcal{D}^{\pi}$
by
 \begin{equation*}\mathcal{D}^{\pi} \phi(x, A, t) = \phi_t(x,A, t) + (A - c + \mu \pi)\phi_x(x,A,t) + \dfrac{1}{2} \, \sigma^2 \pi^2 \phi_{xx}(x, A, t),\end{equation*}
in which
 $\phi \in \mathcal{C}^{2, 1, 1}(\mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+)$
. Because the following verification lemma is relatively new in the literature, we prove it; for reference, [Reference Dai, Jia and Jin6] prove a related result, although their horizon is fixed.
Lemma 3.1. Suppose there exist two real-valued functions
 $\tilde{\mathcal{V}},\mathcal{G}\in\mathcal{C}^{2,1,1}(\mathbb{R}\times\mathbb{R}_+\times\mathbb{R}_+)$
, except that
 $\mathcal{G}(x, \cdot, t)$
might only be continuous along a specific curve of
 $A = \tilde{A}(x, t)$
with left and right derivatives along that curve, that satisfy the following conditions:
-
(i) For all
$(x, A, t) \in \mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+$
, (3.7)
\begin{align} \sup_{\pi\in\mathbb{R}}\bigg\{\mathcal{D}^{\pi}\tilde{\mathcal{V}}(x, A, t) - \dfrac{\gamma}{2}\,\mathcal{D}^\pi\mathcal{G}^2(x, A, t) + \gamma\mathcal{G}(x, A, t)\mathcal{D}^\pi\mathcal{G}(x, A, t)\bigg\} & \notag \\ -\,\lambda\bigg(\tilde{\mathcal{V}}(x, A, t) - x + \dfrac{\gamma}{2}\,(\mathcal{G}(x, A, t) - x)^2\bigg) & \le 0, \end{align}
(3.8)with equality in at least one of (3.7) and (3.8). Let
\begin{align} \tilde{\mathcal{V}}_A(x, A, t) - \bar{a} \tilde{\mathcal{V}}_x(x, A, t) & \le 0, \end{align}
$\tilde{\Pi}(x, A, t)$
denote the maximizer of the HJB equation in (3.7), and let
$\tilde{\mathcal{A}}$
denote the following annuitization strategy:-
(a) Define the buy region B and no-transaction region
${NT}$
by
\[ B = \{(x, A, t) \in \mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+ \colon \tilde{\mathcal{V}}_A(x, A, t) = \bar{a}\tilde{\mathcal{V}}_x(x, A, t)\}, \quad {NT} = (\mathbb{R} \times \mathbb{R}_+^2) \setminus B. \]
-
(b) If
$(x, A, t) \in B^o$
, in which
$B^o$
denotes the interior of B, then the individual immediately buys annuity income to reach the boundary of the no-transaction region
${NT}$
. Thereafter, she buys annuity income as needed to keep wealth in
$\overline{{NT}}$
, a type of singular control. Here,
$\overline{{NT}}$
denotes the closure of
${NT}$
. -
(c) If
$(x, A, t) \in {NT}$
, then the individual does not buy additional annuity income.
Suppose the induced strategy
$(\tilde{\mathcal{A}}, \tilde{\Pi})$
is admissible. -
-
(ii) For all
$(x, A, t) \in \mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+$
, (3.9)
\begin{multline} (\mathcal{D}^{\tilde{\Pi}}\mathcal{G}(x, A, t) - \lambda(\mathcal{G}(x, A, t) - x))\mathbf{1}_{\{(x, A, t) \in {NT}\}} \\ + (\mathcal{G}_A(x, A, t) - \bar{a}\mathcal{G}_x(x, A, t))\mathbf{1}_{\{(x, A, t) \in B\}} = 0. \end{multline}
-
(iii) For all
$(x, A, t) \in \mathbb{R} \times \mathbb{R}_+ \times \mathbb{R}_+$
, the following transversality condition holds for
$\phi = \tilde{\mathcal{V}}$
,
$\mathcal{G}$
, and
$\mathcal{G}^2$
:
$\lim_{s\to\infty}\textrm{e}^{-\lambda(s - t)}\,\mathbb{E}_{x, A, t}(\phi(X_{s}, A_s, s)) = 0$
.
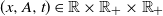


Then,
 $\tilde{\mathcal{V}}$
equals the individual’s equilibrium value function
 $\mathcal{V}$
defined in (3.6),
 $\tilde{\Pi}$
is a time-consistent equilibrium investment strategy for the individual, and
 $\tilde{\mathcal{A}}$
is a time-consistent equilibrium annuitization strategy. Moreover,
 $\mathcal{G}(x, A, t) = \mathbb{E}_{x, A, t}(X_\tau)$
under these strategies.
Proof. Suppose
 $\tilde{\mathcal{V}}$
,
 $\mathcal{G}$
, and
 $\mathcal{G}^2$
satisfy the conditions of this lemma.
Step 1. We first assert that
 $\mathcal{G}(x, A, t) = \mathbb{E}_{x, A, t}(X_\tau) = \mathbb{E}_{x, A, t}\big(\! \int_t^\infty\lambda\textrm{e}^{-\lambda(s-t)}X_{s}\,\textrm{d}s\big)$
, in which X is controlled via the investment strategy
 $\tilde{\Pi}$
and the annuitization strategy
 $\tilde{\mathcal{A}}$
of buying annuities when
 $(x, A, t) \in B$
. We omit the proof of this assertion because it is similar to the proof of [Reference Wang and Young17, Theorem 2.1].
Step 2. In this step, we show that
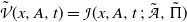 $\tilde{\mathcal{V}}(x, A, t) = \mathcal{J}(x, A, t \, ; \, \tilde{\mathcal{A}}, \tilde{\Pi})$
if
 $\tilde{\mathcal{V}}$
satisfies the variational inequality in condition (i). When
 $(x, A, t) \in {NT}$
, equations (3.7) and (3.9) imply
 \begin{equation*} \mathcal{D}^{\tilde{\Pi}}\bigg(\tilde{\mathcal{V}}(x, A, t) - \dfrac{\gamma}{2}\,\mathcal{G}^2(x, A, t)\bigg) = \lambda\bigg(\bigg(\tilde{\mathcal{V}}(x, A, t) - \dfrac{\gamma}{2}\,\mathcal{G}^2(x, A, t)\bigg) - \bigg(x - \dfrac{\gamma}{2}\,x^2\bigg)\bigg). \end{equation*}
When
 $(x, A, t) \in B$
, equations (3.8) and (3.9) imply
 \begin{align*} \dfrac{\partial}{\partial A}\bigg(\tilde{\mathcal{V}}(x, A, t) - \dfrac{\gamma}{2}\,\mathcal{G}^2(x, A, t)\bigg) & = \tilde{\mathcal{V}}_A(x, A, t) - \gamma\mathcal{G}(x, A, t)\mathcal{G}_A(x, A, t) \\ & = \bar{a}\tilde{\mathcal{V}}_x(x, A, t) - \gamma\mathcal{G}(x, A, t)\cdot\bar{a}\mathcal{G}_x(x, A, t) \\ & = \bar{a}\dfrac{\partial}{\partial x}\bigg(\tilde{\mathcal{V}}(x, A, t) - \dfrac{\gamma}{2}\,\mathcal{G}^2(x, A, t)\bigg). \end{align*}
Thus, from a proof similar to Step 1, we deduce that
 \begin{equation*} \tilde{\mathcal{V}}(x, A, t) - \dfrac{\gamma}{2}\,\mathcal{G}^2(x, A, t) = \mathbb{E}_{x, A, t}\bigg(X_\tau - \dfrac{\gamma}{2}\,X^2_\tau\bigg) = \mathbb{E}_{x, A, t}\bigg(\int_t^\infty\lambda\,\textrm{e}^{-\lambda(s - t)} \bigg(X_{s} - \dfrac{\gamma}{2}\,X^2_s\bigg)\,\textrm{d}s\bigg), \end{equation*}
in which X is controlled via the investment strategy
 $\tilde{\Pi}$
and the annuitization strategy
 $\tilde{\mathcal{A}}$
. It follows that, under
 $(\tilde{\mathcal{A}}, \tilde{\Pi})$
,
 \begin{align*} \tilde{\mathcal{V}}(x, A, t) & = \mathbb{E}_{x, A, t}\bigg(X_\tau - \dfrac{\gamma}{2}\,X^2_\tau\bigg) + \dfrac{\gamma}{2}(\mathbb{E}_{x, A, t}(X_\tau))^2 \\ & = \mathbb{E}_{x, A, t}(X_\tau) - \dfrac{\gamma}{2}\,\mathbb{V}_{x, A, t}(X_\tau) = \mathcal{J}(x, A, t \, ; \, \tilde{\mathcal{A}}, \tilde{\Pi}). \end{align*}
Step 3. It remains to show that
 $(\tilde{\mathcal{A}}, \tilde{\Pi})$
is an equilibrium strategy. To that end, define the strategy
 $(\mathcal{A}^{\varepsilon}, \Pi^{\varepsilon})$
as in (3.3) and (3.4), and we want to prove that the limit in (3.5) holds. Under this strategy, the individual first purchases annuity income with a lump sum payment of
 $\Delta A$
at time t; thus, the state (x, A, t) jumps to
 $(\bar{x}, \bar{A}, t)$
immediately, in which
 $\bar{x} = x - \bar{a}\cdot \Delta A$
and
 $\bar{A} = A + \Delta A$
. As in [Reference Landriault, Li, Li and Young11], we first expand
 $\mathcal{J}(x, A, t \, ; \, \mathcal{A}^{\varepsilon}, \Pi^{\varepsilon})$
up to order
 $o(\varepsilon)$
:
 \begin{align} & \mathcal{J}(x, A, t \, ; \, \mathcal{A}^{\varepsilon}, \Pi^{\varepsilon}) \notag \\ & \qquad = \mathbb{E}_{\bar{x}, \bar{A}, t}\bigg(X_\tau - \dfrac{\gamma}{2} X^2_\tau\bigg) + \dfrac{\gamma}{2}\,(\mathbb{E}_{\bar{x}, \bar{A}, t}(X_\tau))^2 \notag \\ & \qquad = \int^{t+\varepsilon}_t\lambda\textrm{e}^{-\lambda(s - t)} \mathbb{E}_{\bar{x}, \bar{A}, t}\bigg(X_s - \dfrac{\gamma}{2} X^2_s\bigg)\,\textrm{d}s + \mathbb{E}_{\bar{x}, \bar{A}, t}\bigg(\bigg(X_\tau - \dfrac{\gamma}{2}\,X^2_\tau\bigg) \mathbf{1}_{\{\tau>t+\varepsilon\}}\bigg) \notag \\ & \qquad\quad + \dfrac{\gamma}{2}\bigg(\int^{t+\varepsilon}_t\lambda\textrm{e}^{-\lambda(s - t)} \mathbb{E}_{\bar{x}, \bar{A}, t}(X_s)\,\textrm{d}s + \mathbb{E}_{\bar{x}, \bar{A}, t}\big(X_\tau \mathbf{1}_{\{\tau>t+\varepsilon\}}\big) \bigg)^2 \notag \\ & \qquad= \varepsilon\lambda\bigg(\bar{x} - \dfrac{\gamma}{2}\,{\bar{x}}^2\bigg) + \textrm{e}^{-\lambda\varepsilon}\mathbb{E}_{\bar{x}, \bar{A}, t} \bigg(\mathbb{E}_{X_{t+\varepsilon}, A^{\varepsilon}_{t+\varepsilon}, t+\varepsilon} \bigg(X_\tau - \dfrac{\gamma}{2} \, X^2_\tau\bigg)\bigg) \notag \\ & \qquad\quad + \dfrac{\gamma}{2}\big(\varepsilon\lambda\,\bar{x} + \textrm{e}^{-\lambda\varepsilon}\mathbb{E}_{\bar{x}, \bar{A}, t} \big(\mathbb{E}_{X_{t+\varepsilon}, A^{\varepsilon}_{t+\varepsilon}, t+\varepsilon}(X_\tau)\big)\big)^2 + o(\varepsilon) \notag \\ & \qquad= \varepsilon\lambda\bigg(\bar{x} - \dfrac{\gamma}{2}\,{\bar{x}}^2\bigg) + (1 - \varepsilon\lambda)\mathbb{E}_{\bar{x}, \bar{A}, t} \bigg(\tilde{\mathcal{V}}(X_{t+\varepsilon}, A^{\varepsilon}_{t+\varepsilon}, t+\varepsilon) - \dfrac{\gamma}{2}\,\mathcal{G}^2(X_{t+\varepsilon}, A^{\varepsilon}_{t+\varepsilon}, t+\varepsilon)\bigg) \notag \\ & \qquad\quad + \dfrac{\gamma}{2}\,\big(\varepsilon\lambda\,\bar{x} + (1 - \varepsilon\lambda)\mathbb{E}_{\bar{x}, \bar{A}, t} (\mathcal{G}(X_{t+\varepsilon}, A^{\varepsilon}_{t+\varepsilon}, t+\varepsilon))\big)^2 + o(\varepsilon), \end{align}
in which we used the equality
 \begin{equation*} \tilde{\mathcal{V}}(x, A, t) - \dfrac{\gamma}{2}\,\mathcal{G}^2(x, A, t) = \mathbb{E}_{x, A, t}\bigg(X_\tau - \dfrac{\gamma}{2} \, X^2_\tau\bigg). \end{equation*}
Moreover, for a sufficiently integrable function j, by using Itô’s formula for semi-martingales (see, for example, [Reference Protter16]), we deduce that
 \begin{align} & j(X_{t+\varepsilon}, A^{\varepsilon}_{t+\varepsilon}, t+\varepsilon) \notag \\& = j(x, A, t) + \int^{t+\varepsilon}_t j_t(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}s +\int^{t+\varepsilon}_t j_x(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}X^{\textrm{c}}_s + \int^{t+\varepsilon}_t j_A(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}(A^{\varepsilon}_s)^{\textrm{c}} \notag \\& \quad + \dfrac{1}{2}\int^{t+\varepsilon}_t j_{xx}(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}[X_s,X_s]^{\textrm{c}} +\sum_{t \le s < t+\varepsilon}(j(X_{s}, A^{\varepsilon}_{s}, s) - j(X_{s^-}, A^{\varepsilon}_{s^-}, s^-)) \notag \\ & = j(\bar{x},\bar{A},t) + \int^{t+\varepsilon}_t j_t(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}s + \int^{t+\varepsilon}_t j_x(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}X^{\textrm{c}}_s + \int^{t+\varepsilon}_t j_A(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}\mathcal{H}_s \notag \\ & \quad + \dfrac{1}{2}\int^{t+\varepsilon}_t j_{xx}(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}[X_s,X_s]^{\textrm{c}} + \sum_{t < s < t+\varepsilon}(j(X_{s}, A^{\varepsilon}_{s}, s) - j(X_{s^-}, A^{\varepsilon}_{s^-}, s^-)) \\ & = j(\bar{x}, \bar{A}, t) + \int^{t+\varepsilon}_t\mathcal{D}^{\pi^{\varepsilon}_s}j(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}s + \int^{t+\varepsilon}_t\sigma\pi^{\varepsilon}_s\,j_x(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}B_s \notag \\ & \quad + \int^{t+\varepsilon}_t(j_A(X_{s}, A^{\varepsilon}_{s}, s) - \bar{a}j_x(X_{s}, A^{\varepsilon}_{s}, s))\, \textrm{d}\mathcal{H}_s, \notag \end{align}
in which the superscript c denotes the continuous part of the stochastic process. (As an aside, note that the upper limit of the summation is
 $(t + \varepsilon)^-$
because in the definition of our objective function in (3.2), we condition on
 $X_{t^-} = x$
and
 $A_{t^-} = A$
.) The annuitization strategy
 $\mathcal{A}^{\varepsilon}$
on
 $[t,t+\varepsilon)$
first entails a lump-sum purchase of
 $\Delta A$
annuity income at time t, and then follows a non-decreasing deterministic
 $\alpha$
-Hölder continuous function
 $\mathcal{H}$
on
 $(t, t + \varepsilon)$
. On
 $[t, t+\varepsilon)$
we only have a discontinuous jump at time t; after that, the strategy is continuous, so in (3.11), the summation term is zero. Furthermore,
 $\mathcal{H}$
is
 $\alpha$
-Hölder continuous, and
 $\pi^{\varepsilon}_s \equiv \pi$
on
 $[t, t + \varepsilon)$
, from which we deduce that
 \begin{align*} j(X_{t+\varepsilon}, A^{\varepsilon}_{t+\varepsilon}, t+\varepsilon) & = j(\bar{x}, \bar{A}, t) + \varepsilon\mathcal{D}^{\pi}j(\bar{x}, \bar{A}, t) + \int^{t+\varepsilon}_t\sigma\pi\,j_x(X_{s}, A^{\varepsilon}_{s}, s)\,\textrm{d}B_s \\ & \quad + \varepsilon^{\alpha}K_{\alpha}(j_A(\bar{x}, \bar{A}, t) - \bar{a}j_x(\bar{x}, \bar{A}, t)) + o(\varepsilon^{\alpha}) + o(\varepsilon), \end{align*}
in which
 $K_\alpha$
is a positive constant such that
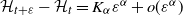 $\mathcal{H}_{t+\varepsilon} - \mathcal{H}_t = K_\alpha\varepsilon^\alpha + o(\varepsilon^{\alpha})$
. By taking expectations, we obtain
 \begin{align} \mathbb{E}_{\bar{x}, \bar{A}, t}(j(X_{t+\varepsilon}, A^{\varepsilon}_{t+\varepsilon}, t+\varepsilon)) & = j(\bar{x}, \bar{A}, t) + \varepsilon\mathcal{D}^{\pi}j(\bar{x}, \bar{A}, t) + \varepsilon^{\alpha}K_{\alpha}(j_A(\bar{x}, \bar{A}, t) - \bar{a} j_x(\bar{x}, \bar{A}, t)) \notag \\ & \quad + o(\varepsilon) + o(\varepsilon^{\alpha}). \end{align}
By substituting (3.12) into (3.10) with
 $j=\tilde{\mathcal{V}}$
,
 $\mathcal{G}$
, and
 $\mathcal{G}^2$
, and by simplifying the resulting expression, we obtain
 \begin{align} & \mathcal{J}(x, A, t \, ; \, \mathcal{A}^{\varepsilon}, \Pi^{\varepsilon}) \notag\\ & = \varepsilon\lambda\bigg(\bar{x} - \dfrac{\gamma}{2}\,{\bar{x}}^2\bigg) + (1 - \varepsilon\lambda)\big(\tilde{\mathcal{V}}(\bar{x}, \bar{A}, t) + \varepsilon\mathcal{D}^{\pi}\tilde{\mathcal{V}}(\bar{x}, \bar{A}, t) + \varepsilon^{\alpha}K_{\alpha}(\tilde{\mathcal{V}}_A(\bar{x}, \bar{A}, t) - \bar{a}\tilde{\mathcal{V}}_x(\bar{x}, \bar{A}, t))\big) \notag\\& \quad - \dfrac{\gamma}{2}\,(1 - \varepsilon\lambda)\big(\mathcal{G}^2(\bar{x},\bar{A},t) + \varepsilon\mathcal{D}^{\pi}\mathcal{G}^2(\bar{x},\bar{A},t) + 2\varepsilon^{\alpha}K_{\alpha}\mathcal{G}(\bar{x},\bar{A},t)(\mathcal{G}_A(\bar{x}, \bar{A}, t) - \bar{a}\mathcal{G}_x(\bar{x}, \bar{A}, t))\big) \notag \\& \quad + \dfrac{\gamma}{2}\,\big(\varepsilon\lambda\bar{x} + (1 - \varepsilon\lambda)\big(\mathcal{G}(\bar{x},\bar{A},t) + \varepsilon\mathcal{D}^{\pi}\mathcal{G}(\bar{x},\bar{A},t)\big) + \varepsilon^{\alpha}K_{\alpha}(\mathcal{G}_A(\bar{x}, \bar{A}, t) - \bar{a}\mathcal{G}_x(\bar{x}, \bar{A}, t))\big)^2 \notag\\& \quad + o(\varepsilon) + o(\varepsilon^{\alpha}) \notag\\ & = \tilde{\mathcal{V}}(\bar{x}, \bar{A}, t) + \varepsilon\bigg(\mathcal{D}^{\pi}\tilde{\mathcal{V}}(\bar{x}, \bar{A}, t) - \dfrac{\gamma}{2}\,\mathcal{D}^{\pi}\mathcal{G}^2(\bar{x},\bar{A},t) + \gamma\mathcal{G}(\bar{x},\bar{A},t)\mathcal{D}^{\pi}\mathcal{G}(\bar{x},\bar{A},t) \notag\\ & \qquad\qquad\qquad\qquad - \lambda\bigg(\tilde{\mathcal{V}}(\bar{x},\bar{A},t) - \bar{x} + \dfrac{\gamma}{2}(\mathcal{G}(\bar{x},\bar{A},t) - \bar{x})^2\bigg)\bigg)\notag \\ & \quad + \varepsilon^{\alpha}K_{\alpha}(\tilde{\mathcal{V}}_A(\bar{x}, \bar{A}, t) - \bar{a}\tilde{\mathcal{V}}_x(\bar{x}, \bar{A}, t)) + o(\varepsilon) + o(\varepsilon^{\alpha}). \end{align}
Because
 $\pi$
is an arbitrary real number, the coefficients of
 $\varepsilon$
and
 $\varepsilon^{\alpha}$
in (3.13) are non-positive, from which it follows that
 \begin{align*} \mathcal{J}(x, A, t \, ; \, \mathcal{A}^{\varepsilon}, \Pi^{\varepsilon}) & \le (\tilde{\mathcal{V}}(\bar{x},\bar{A},t) - \tilde{\mathcal{V}}(x,A,t)) + \tilde{\mathcal{V}}(x,A,t) + o(\varepsilon) + o(\varepsilon^{\alpha}) \\ & \le \tilde{\mathcal{V}}(x,A,t) + o(\varepsilon^{\alpha}). \end{align*}
In deriving the last inequality we used (3.8), which implies that
 $\mathcal{V}$
is non-increasing in the direction of purchasing annuities. Thus, we have obtained (3.5), thereby showing that
 $(\tilde{\mathcal{A}}, \tilde{\Pi})$
is a time-consistent equilibrium feedback strategy.
In the following theorem we use Lemma 3.1 to obtain the time-consistent equilibrium strategy when the buyer is allowed to purchase any amount of annuity income.
Theorem 3.1. Define the function
 $\tilde{\mathcal{A}}$
and constant
 $\tilde{\Pi}$
by
 \begin{equation} \tilde{\mathcal{A}}(A) = \begin{cases} \tilde{A}, & A < \tilde{A}, \\ A, & A\ge \tilde{A}; \end{cases} \qquad \tilde{\Pi} \equiv \frac{\mu}{\gamma \sigma^2}, \end{equation}
in which the barrier
 $\tilde{A}$
is
 \begin{equation} \tilde{A} = \dfrac{1}{\gamma}\bigg(\gamma c - \bigg(\lambda(\bar{a}\lambda - 1) + \frac{\mu^2}{\sigma^2}\bigg)\bigg)_+. \end{equation}
Then, the strategy
 $(\tilde{\mathcal{A}}, \tilde{\Pi}) = (\{\tilde{\mathcal{A}}(A_{t^-})\} , \{\tilde{\Pi}\})_{t \in \mathbb{R}_+}$
is a time-consistent equilibrium strategy as defined in Definition 3.1. Specifically, if existing annuity income A is less than
 $\tilde{A}$
, the individual will immediately spend
 $\bar{a}(\tilde{A} - A)$
to purchase annuity income so that total annuity income equals
 $\tilde{A}$
; otherwise, if A is greater than
 $\tilde{A}$
, the individual will purchase no additional annuity income. Moreover,
 $\mathcal{G}(x, A) = \mathbb{E}_{x, A}(X_\tau) = x + \mathcal{g}(A)$
, in which
 \begin{equation} \mathcal{g}(A) = \begin{cases} \dfrac{1}{\lambda}\bigg(\tilde{A} - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg) - \bar{a}(\tilde{A} - A), & A < \tilde{A}, \\[3mm] \dfrac{1}{\lambda}\bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg), & A \ge \tilde{A}, \end{cases} \end{equation}
and the corresponding time-independent value function is
 $\mathcal{V}(x, A) = x + \mathcal{v}(A)$
, in which
 \begin{equation} \mathcal{v}(A) = \begin{cases} \dfrac{1}{\lambda}\bigg(\tilde{A} - c + \dfrac{\mu^2}{2\gamma\sigma^2}\bigg) - \dfrac{\gamma}{2\lambda^2}\bigg(\tilde{A} - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)^2 - \bar{a}(\tilde{A} - A), & A < \tilde{A}, \\[3mm] \dfrac{1}{\lambda}\bigg(A - c + \dfrac{\mu^2}{2\gamma\sigma^2}\bigg) - \dfrac{\gamma}{2\lambda^2}\bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)^2, & A \ge \tilde{A}. \end{cases} \end{equation}
Proof. Because the problem is time-homogeneous, the value function is time-independent. As in the proof of Theorem 2.1, from the mean-variance criterion and from the dynamics of X in (3.1), we deduce that the value function equals
 $x + \mathcal{v}(A)$
for some function
 $\mathcal{v}(A)$
. Thus,
 $\mathcal{V}(x, A) = x + \mathcal{v}(A)$
and
 $\mathcal{G}(x, A) = x + \mathcal{g}(A)$
for some function
 $\mathcal{g}(A)$
. Furthermore, based on the equilibrium annuitization strategy in Theorem 2.1, we hypothesize that the equilibrium strategy is of the form
 \begin{equation*} \tilde{\mathcal{A}}(A) = \begin{cases} \tilde{A}, & A < \tilde{A}, \\ A, & A \ge \tilde{A} \end{cases} \end{equation*}
for
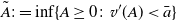 $\tilde{A} := \inf\{A \ge 0\colon \mathcal{v}'(A) < \bar{a}\}$
, which implies
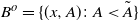 $B^o = \{(x, A)\colon A < \tilde{A}\}$
and
 ${NT} = \{(x, A)\colon A > \tilde{A}\}$
. Also, this ansatz requires
 $\mathcal{v}'(A) \le \bar{a}$
for all
 $A \ge \tilde{A}$
, which we verify below.
In the following, we derive expressions or equations for
 $\mathcal{v}(A)$
and
 $\mathcal{g}(A)$
, depending on whether
 $A \ge \tilde{A}$
or
 $A < \tilde{A}$
.
For
 $A \ge \tilde{A}$
our ansatz is
 $\tilde{A}_{t} \equiv A$
for all
 $t \ge 0$
. By substituting
 $\mathcal{V}(x, A) = x + \mathcal{v}(A)$
and
 $\mathcal{G}(x, A) = x + \mathcal{g}(A)$
into (3.7) with
 $=$
in place of
 $\le$
, the HJB equation becomes
 \begin{equation} \sup_{\pi \in \mathbb{R}}\bigg\{(A - c + \mu \pi) - \dfrac{\gamma}{2}\sigma^2\pi^2\bigg\} = \lambda\bigg(\mathcal{v}(A) + \dfrac{\gamma}{2}\,\mathcal{g}^2(A)\bigg). \end{equation}
Note that the expression in braces is concave with respect to
 $\pi$
; thus, the critical point from the first-order condition gives us the equilibrium investment amount
 $\tilde{\Pi}$
, which is as stated in (3.14). By substituting
 $\tilde{\Pi} = {\mu}/{\gamma\sigma^2}$
into (3.9), we obtain
 \begin{equation*} \mathcal{g}(A) = \frac{1}{\lambda}\bigg(A - c + \frac{\mu^2}{\gamma\sigma^2}\bigg). \end{equation*}
Similarly, by substituting these values of
 $\mathcal{g}$
and
 $\tilde{\Pi}$
into the HJB equation (3.18), we get
 \begin{equation*} A - c + \dfrac{\mu^2}{2\gamma\sigma^2} = \lambda\mathcal{v}(A) + \frac{\lambda\gamma}{2}\mathcal{g}^2(A), \end{equation*}
from which we obtain the second expression of
 $\mathcal{v}$
given in (3.17). The first and second derivatives of
 $\mathcal{v}(A)$
with respect to A are
 \[ \mathcal{v}'(A) = \frac{1}{\lambda}-\frac{\gamma}{\lambda^2}\bigg(A - c + \frac{\mu^2}{\gamma\sigma^2}\bigg), \qquad \mathcal{v}''(A) = - \frac{\gamma}{\lambda^2} < 0, \]
which shows that
 $\mathcal{v}'(A) \le \bar{a}$
for all
 $A \ge \tilde{A}$
because we obtain the value of
 $\tilde{A}$
given in (3.15) by solving
 $\mathcal{v}'(A)|_{A = \tilde{A}^+} = \bar{a}$
.
For
 $A < \tilde{A}$
,
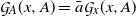 $\mathcal{G}_A(x, A) = \bar{a} \mathcal{G}_x(x, A)$
, which implies
 $\mathcal{g}'(A) = \bar{a}$
; similarly,
 $\mathcal{V}_A(x, A) = \bar{a} \mathcal{V}_x(x, A)$
implies
 $\mathcal{v}'(A) = \bar{a}$
. From
 $\mathcal{g}'(A) = \bar{a} = \mathcal{v}'(A)$
we obtain the first expressions for
 $\mathcal{g}$
and
 $\mathcal{v}$
in (3.16) and (3.17), respectively. The remainder of the proof follows as in the proof of Theorem 2.1, so we omit it.
Note that
 $\hat{A}$
in (2.8) equals
 $\tilde{A}$
in (3.15). Thus, when only allowed to purchase annuity income at a bounded rate or when allowed to purchase annuity income more generally, the individual will purchase the identical amount of income under either model. Similarly, the amount invested in the risky asset,
 ${\mu}/{\gamma\sigma^2}$
, is identical under either model: compare (2.7) and (3.14). It follows that Corollary 2.1 and Remark 2.1 apply to
 $\tilde{\Pi}$
and
 $\tilde{A}$
in (3.14) and (3.15), respectively.
Remark 3.1. As
 $\bar{q}$
approaches infinity, we see that g(A) given in (2.9) converges to
 $\mathcal{g}(A)$
given in (3.16), and the ODE in (2.11) degenerates to
 $v'(A) = \bar{a}$
; thus, v(A) given in (2.10) and (2.11) converges to
 $\mathcal{v}(A)$
given in (3.17). Hence, the results in Theorem 3.1 can be thought of as a limiting case of those in Theorem 2.1. This correspondence further demonstrates that the singular control problem can be approximated by a regular control problem with a bounded, continuous rate, as we know from the existing literature.
In the following corollary we compute the distribution of wealth at death,
 $\tilde X_\tau$
, under the time-consistent equilibrium strategy. We find two representations for this distribution.
Corollary 3.1. Let
 $\operatorname{Exp}(\theta)$
denote the exponentially distributed random variable with expectation
 $1/\theta$
, and let
 $\tilde X$
denote the wealth process under the time-consistent equilibrium strategy given in Theorem 3.1.
-
(i) Mixture of exponentials. If
$A_{0^-} = A \ge \tilde{A}$
and
$X_{0^-} = x$
, then
$\tilde X_\tau - x$
is a mixture of the negative of (3.19)and
\begin{equation} \operatorname{Exp}\bigg(\bigg(\dfrac{\gamma\sigma}{\mu}\bigg)^2\bigg( \sqrt{2\lambda\bigg(\dfrac{\mu}{\gamma\sigma}\bigg)^2 + \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)^2} + \bigg( A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)\bigg)\bigg) \end{equation}
(3.20)with respective weights
\begin{equation} \operatorname{Exp}\bigg(\bigg(\dfrac{\gamma\sigma}{\mu}\bigg)^2\bigg( \sqrt{2\lambda\bigg(\dfrac{\mu}{\gamma\sigma}\bigg)^2 + \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)^2} - \bigg( A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)\bigg)\bigg) \end{equation}
(3.21)and
\begin{multline} \lambda\bigg(\dfrac{\mu}{\gamma\sigma}\bigg)^2\dfrac{1} {\sqrt{2\lambda\bigg(\dfrac{\mu}{\gamma\sigma}\bigg)^2 + \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)^2}\,} \\ \times \dfrac{1} {\sqrt{2\lambda\bigg(\dfrac{\mu}{\gamma\sigma}\bigg)^2 + \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)^2} + \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2} \bigg)} \end{multline}
(3.22)If
\begin{multline} \lambda\bigg(\dfrac{\mu}{\gamma\sigma}\bigg)^2\dfrac{1} {\sqrt{2\lambda\bigg(\dfrac{\mu}{\gamma\sigma}\bigg)^2 + \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)^2}\,} \\ \times \dfrac{1} {\sqrt{2\lambda\bigg(\dfrac{\mu}{\gamma\sigma}\bigg)^2 + \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)^2} - \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)}. \end{multline}
$A_{0^-} = A < \tilde{A}$
and
$X_{0^-} = x$
, then
$\tilde X_\tau - (x - \bar{a}(\tilde{A} - A))$
is distributed according to the mixture described above with A replaced by
$\tilde{A}$
in (3.19), (3.20), (3.21), and (3.22).
-
(ii) Difference of independent exponentials. Let
$X_1$
and
$X_2$
denote the independent, positive, exponentially distributed random variables given in (3.19) and (3.20) respectively. If
$A_{0^-} = A \ge \tilde{A}$
and
$X_{0^-} = x$
, then
$\tilde X_\tau - x \sim X_2 - X_1$
. If
$A_{0^-} = A < \tilde{A}$
and
$X_{0^-} = x$
, then
$\tilde X_\tau - (x - \bar{a}(\tilde{A} - A)) \sim X_2 - X_1$
.


Proof. To prove (i), we compute the distribution of wealth at death,
 $\tilde X_\tau$
, under the time-consistent equilibrium strategy. To that end, first consider the case for which
 $A_{0^-} = A \ge \tilde{A}$
and
 $X_{0^-} = x$
; in that case, the individual does not buy additional annuity income, and her wealth process
 $\tilde X$
follows the dynamics
 \begin{equation*} \textrm{d}\tilde X_t = \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)\,\textrm{d}t + \dfrac{\mu}{\gamma\sigma}\,\textrm{d}B_t, \end{equation*}
which is Brownian motion with a (constant) drift. Equivalently, for
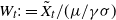 $W_t := \tilde X_t/({\mu}/{\gamma\sigma})$
,
 \begin{equation*} \textrm{d}W_t = \bigg(\dfrac{\gamma\sigma(A - c)}{\mu} + \dfrac{\mu}{\sigma}\bigg)\,\textrm{d}t + \textrm{d}B_t. \end{equation*}
From [Reference Borodin and Salminen5, (1.0.5), p. 256], we have the following probability density function of
 $W_\tau$
for a given initial value
 $W_0 = w$
:
 \begin{equation*} \mathbb{P}_{w, A}(W_\tau \in \textrm{d}z) = \dfrac{\lambda}{\sqrt{2\lambda + \tilde{\mu}^2}\,} \textrm{e}^{\tilde{\mu}(z - w) - |z - w|\sqrt{2\lambda + \tilde{\mu}^2}}\,\textrm{d}z, \end{equation*}
in which
 \begin{equation*} \tilde{\mu} = \frac{\gamma \sigma(A - c)}{\mu} + \frac{\mu}{\sigma} , \end{equation*}
which implies that the probability density function of
 $\tilde X_\tau$
for a given initial value
 $\tilde X_{0^-} = x$
and
 $A_{0^-} = A \ge \tilde{A}$
is
 \begin{align} \mathbb{P}_{x, A}(\tilde X_\tau \in \textrm{d}z) & = \dfrac{\gamma\sigma}{\mu} \cdot \dfrac{\lambda}{\sqrt{2\lambda + \tilde{\mu}^2}\,} \textrm{e}^{\tilde{\mu}(z - x)/({\mu}/{\gamma\sigma}) - |z - x|\sqrt{2\lambda + \tilde{\mu}^2}/({\mu}/{\gamma\sigma})}\,\textrm{d}z \notag \\ & = \dfrac{\lambda}{\sqrt{2\lambda + \tilde{\mu}^2}\,} \cdot \dfrac{\gamma\sigma}{\mu} \begin{cases} \textrm{e}^{-(x - z)(\sqrt{2\lambda + \tilde{\mu}^2} + \tilde{\mu})/({\mu}/{\gamma\sigma})}, & z \le x, \\ \textrm{e}^{-(z - x)(\sqrt{2\lambda + \tilde{\mu}^2} - \tilde{\mu})/({\mu}/{\gamma\sigma})}, & z > x. \end{cases} \end{align}
It follows from the expression in (3.23) that
 $\tilde X_\tau - x$
is distributed according to a two-sided exponential as given in the statement of the corollary. If
 $A_{0^-} = A < \tilde{A}$
and
 $X_{0^-} = x$
, then the individual immediately spends
 $\bar{a}(\tilde{A} - A)$
so that
 $A_0 = \tilde{A}$
and
 $X_0 = x - \bar{a}(\tilde{A} - A)$
, which implies that
 $\tilde X_\tau - (x - \bar{a}(\tilde{A} - A))$
is distributed according to the mixture described above with A replaced by
 $\tilde{A}$
in (3.19), (3.20), (3.21), and (3.22). We have thereby proved (i).
To prove (ii), calculate the moment-generating function of
 $X_2 - X_1$
, writing
 $\theta_1$
and
 $\theta_2$
for the parameters in (3.19) and (3.20), respectively: for
 $t < \theta_2$
,
 \begin{align*} M_{X_2 - X_1}(t) & = \mathbb{E}\big(\textrm{e}^{(X_2 - X_1)t}\big) \\ & = \mathbb{E}\big(\textrm{e}^{X_2 t}\big)\mathbb{E}\big(\textrm{e}^{X_1(-t)}\big) \\ & = \int_0^\infty\textrm{e}^{zt}\theta_2\textrm{e}^{-\theta_2 z}\,\textrm{d}z \cdot \int_0^\infty\textrm{e}^{-zt}\theta_1\textrm{e}^{-\theta_1 z}\,\textrm{d}z = \dfrac{\theta_2}{\theta_2 - t} \cdot \dfrac{\theta_1}{\theta_1 + t}. \end{align*}
Next, for
 $A_{0^-} = A \ge \tilde{A}$
and
 $X_{0^-} = x$
, use the probability density function in (3.23) to compute the moment-generating function of
 $\tilde X_\tau - x$
: for
 $t < \theta_2$
,
 \begin{align*} M_{\tilde X_\tau - x}(t) & = \dfrac{\lambda}{\sqrt{2\lambda + \tilde{\mu}^2}\,} \cdot \dfrac{\gamma\sigma}{\mu}\bigg\{\int_{-\infty}^0\textrm{e}^{zt}\textrm{e}^{\theta_1 z}\,\textrm{d}z + \int_0^\infty\textrm{e}^{zt}\textrm{e}^{-\theta_2 z}\,\textrm{d}z\bigg\} \\ & = \dfrac{\lambda}{\sqrt{2\lambda + \tilde{\mu}^2}\,} \cdot \dfrac{\gamma\sigma}{\mu}\bigg\{\dfrac{1}{\theta_1+ t} + \dfrac{1}{\theta_2 - t}\bigg\} = \dfrac{\theta_2}{\theta_2 - t} \cdot \dfrac{\theta_1}{\theta_1 + t}, \end{align*}
in which the last equality follows after a small amount of algebraic manipulation. Therefore, if
 $A_{0^-} = A \ge \tilde{A}$
and
 $X_{0^-} = x$
, then
 $\tilde X_\tau - x$
has the same distribution as
 $X_2 - X_1$
. Similarly, if
 $A_{0^-} = A < \tilde{A}$
and
 $X_{0^-} = x$
, then
 $\tilde X_\tau - (x - \bar{a}(\tilde{A} - A))$
has the same distribution as
 $X_2 - X_1$
. We have thereby proved (ii).
In the last corollary, we compute the probability of lifetime ruin for the individual who follows the time-consistent equilibrium strategy in Theorem 3.1, that is, the probability that wealth drops to zero or below before the individual dies.
Corollary 3.2. Suppose
 $(X_{0^-}, A_{0^-}) = (x, A)$
, and suppose the individual follows the time-consistent equilibrium strategy given in Theorem 3.1. If
 $A < \tilde{A}$
and
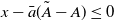 $x - \bar{a}(\tilde{A} - A) \le 0$
, then the resulting probability of lifetime ruin
 $\psi(x, A) = 1$
; otherwise, if
 $A < \tilde{A}$
and
 $x - \bar{a} (\tilde{A} - A) > 0$
, then the probability of lifetime ruin is
 \begin{multline} \psi(x, A) = \exp\bigg({-}(x - \bar{a}(\tilde{A} - A))\bigg(\dfrac{\gamma\sigma}{\mu}\bigg)^2 \bigg(\sqrt{2\lambda\bigg(\dfrac{\mu}{\gamma\sigma}\bigg)^2 + \bigg(\tilde{A} - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)^2} \\ + \bigg(\tilde{A} - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)\bigg)\bigg). \end{multline}
If
 $A \ge \tilde{A}$
and
 $x \le 0$
, then the probability of lifetime ruin
 $\psi(x, A) = 1$
; otherwise, if
 $A \ge \tilde{A}$
and
 $x > 0$
, then the probability of lifetime ruin is
 \begin{equation} \psi(x, A) = \exp\bigg({-}x\bigg(\dfrac{\gamma\sigma}{\mu}\bigg)^2 \bigg(\sqrt{2\lambda\bigg(\dfrac{\mu}{\gamma\sigma}\bigg)^2 + \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)^2} + \bigg(A - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg)\bigg)\bigg). \end{equation}
Proof. The expressions for the probability of lifetime ruin given in (3.24) and (3.25) follow from [Reference Borodin and Salminen5, (1.2.2), p. 257] by noting that
 $\psi(x, A) = \mathbb{P}_{x,A} \big(\inf_{0 \le t \le \tau} \tilde X_t \le 0 \big)$
. The details are similar to those in Corollary 3.1, so we do not reproduce them here.
4. Conclusion
We have studied two dynamic, mean-variance, asset-allocation problems for an individual. In the first problem, the buyer is allowed to purchase life annuities at a bounded, continuous rate. We found the individual’s time-consistent equilibrium control strategies and her value functions by solving an extended HJB system of equations. We showed that the optimal annuitization strategy is a barrier strategy. Specifically, the individual only purchases life annuities (at the maximum annuity rate) when the current cumulative annuity income is less than the barrier.
In the second problem, the buyer is allowed to purchase any amount of life annuity income at any time. By adapting the definition of equilibrium strategies with singular controls in [Reference Dai, Jia and Jin6] to our case, we proved a verification lemma to show that the solutions derived from the proposed extended HJB variational inequalities are the time-consistent equilibrium strategies and the value function, a relatively new result in the literature. We found that the optimal annuitization strategy is also a barrier strategy identical to the one we obtained in the first problem. Moreover, the equilibrium amounts invested in the risky asset in both models are the same, and both equal a constant, independent of time, wealth, and annuity income. Finally, we discussed the effects of the parameters on the equilibrium strategies.
Acknowledgements
We both thank two anonymous reviewers for their constructive comments.
Funding information
Xiaoqing Liang acknowledges the financial support from the National Natural Science Foundation of China (Nos. 12371468, 12326369, 12271274) and the Natural Science Foundation of Hebei Province (No. A2025202020). Virginia R. Young thanks the Cecil J. and Ethel M. Nesbitt Professorship for financial support of her research.
Competing interests
There were no competing interests to declare which arose during the preparation or publication process of this article.
Appendix A. Proof that
$v'(A) > \bar{a}$
when
$A < \hat{A}$
for Theorem 2.1


In the following lemma we prove that
 $v'(A) > \bar{a}$
for all
 $0 \le A < \hat{A}$
, which we used in the proof of Theorem 2.1.
Lemma A.1. Because
 $\bar{a}\lambda \ge 1$
, it follows that
 $v'(A) > \bar{a}$
for all
 $0 \le A < \hat{A}$
.
Proof. Without loss of generality, we can assume that
 $\bar{a}$
is such that
 $\hat{A} > 0$
; otherwise, the conclusion of the lemma is moot.
From (2.11), we deduce the following ODE for
 $y(A) = v'(A)$
for
 $A < \hat{A}$
:
 \begin{equation} y'(A) = \frac{\bar{a}\lambda}{\bar{q}}\,y(A) - \frac{\bar{a}}{\bar{q}}(1 - \lambda\gamma g(A)g'(A)), \end{equation}
with
 $y(\hat{A}) =\bar{a}$
. In (A.1), g is given in (2.9). Proving that
 $v'(A) > \bar{a}$
for
 $0 \le A < \hat{A}$
is equivalent to proving
 $y(A) > \bar{a}$
for
 $0 \le A < \hat{A}$
. Suppose, on the contrary, that there exists
 $A_0 < \hat{A}$
such that
 $y(A_0) \le \bar{a}$
. Then, let
 $A_m \in [0, \hat{A}]$
be such that
 $y(A_m) - \bar{a}$
is a global minimum, necessarily non-positive.
If
 $0 \le A_m < \hat{A}$
, then we have
 $y(A_m) \le \bar{a}$
and
 $y'(A_m) \ge 0$
(with
 $y'(A_m) = 0$
if
 $A_m \ne 0$
). From (A.1), we see that
 $y'(A_m) \ge 0$
is equivalent to
 $y(A_m) \ge ({1}/{\lambda}) - \gamma g(A_m) g'(A_m)$
. If we show the following inequality, then we have a contradiction to
 $y(A_m) \le \bar{a}$
:
 \begin{equation} \dfrac{1}{\lambda} - \gamma g(A_m) g'(A_m) > \bar{a}, \end{equation}
or equivalently
 \begin{multline} -\dfrac{\gamma}{\lambda}\bigg\{\bigg(A_m - c + \dfrac{\mu^2}{\gamma\sigma^2}\bigg) - \dfrac{\bar{q}(\bar{a}\lambda-1)}{\bar{a}\lambda} \big(1-\textrm{e}^{-({\bar{a}\lambda}/{\bar{q}})(\hat{A} - A_m)}\big)\bigg\} \big\{1 + (\bar{a}\lambda - 1)\textrm{e}^{-({\bar{a}\lambda}/{\bar{q}})(\hat{A} - A_m)}\big\} \\ - (\bar{a}\lambda - 1) > 0. \end{multline}
After writing c in terms of
 $\hat{A}$
and simplifying, the left-hand side of (A.3) becomes
 \begin{multline*} \dfrac{\gamma}{\lambda}\bigg\{\bigg(\hat{A} - A_m + \dfrac{\lambda(\bar{a}\lambda - 1)}{\gamma}\bigg) + \dfrac{\bar{q}(\bar{a}\lambda-1)}{\bar{a}\lambda} \big(1-\textrm{e}^{-({\bar{a}\lambda}/{\bar{q}})(\hat{A} - A_m)}\big)\bigg\} \big\{1 + (\bar{a}\lambda - 1)\textrm{e}^{-({\bar{a}\lambda}/{\bar{q}}) (\hat{A} - A_m)}\big\} \\ - (\bar{a}\lambda - 1), \end{multline*}
which we can show (after a great deal of algebraic manipulation) gives
 \begin{multline*} \dfrac{\gamma}{\lambda}\big(1 + (\bar{a}\lambda - 1)\textrm{e}^{-({\bar{a}\lambda}/{\bar{q}})(\hat{A} - A_m)}\big) \bigg\{(\hat{A} - A_m) + \dfrac{\bar{q}(\bar{a}\lambda - 1)}{\bar{a}\lambda} \big(1 - \textrm{e}^{-({\bar{a}\lambda}/{\bar{q}})(\hat{A} - A_m)}\big)\bigg\} \\ + (\bar{a}\lambda - 1)^2\textrm{e}^{-({\bar{a}\lambda}/{\bar{q}})(\hat{A} - A_m)} > 0, \end{multline*}
in which the inequality follows from
 $\bar{a}\lambda \ge 1$
. Thus, we have proved (A.2), which gives us a contradiction.
Suppose
 $A_m = \hat{A}$
. Then we have
 $y(\hat{A}) = \bar{a}$
and
 $y'(\hat{A}) \le 0$
. Because
 $A_0 < \hat{A}$
is such that
 $y(A_0) \le \bar{a}$
, and because
 $\hat{A}$
yields the global minimum of
 $y(A) - \bar{a}$
on
 $[0, \hat{A}]$
, we deduce that
 $y(A_0) - \bar{a} = 0$
also achieves the global minimum of
 $y(A) - \bar{a}$
on
 $[0, \hat{A}]$
. Using
 $A_m = A_0 < \hat{A}$
in the above argument gives us a contradiction.
Therefore, no
 $A_0 < \hat{A}$
exists such that
 $y(A_0) \le \bar{a}$
, which implies that
 $v'(A) > \bar{a}$
for all
 $A < \hat{A}$
.


