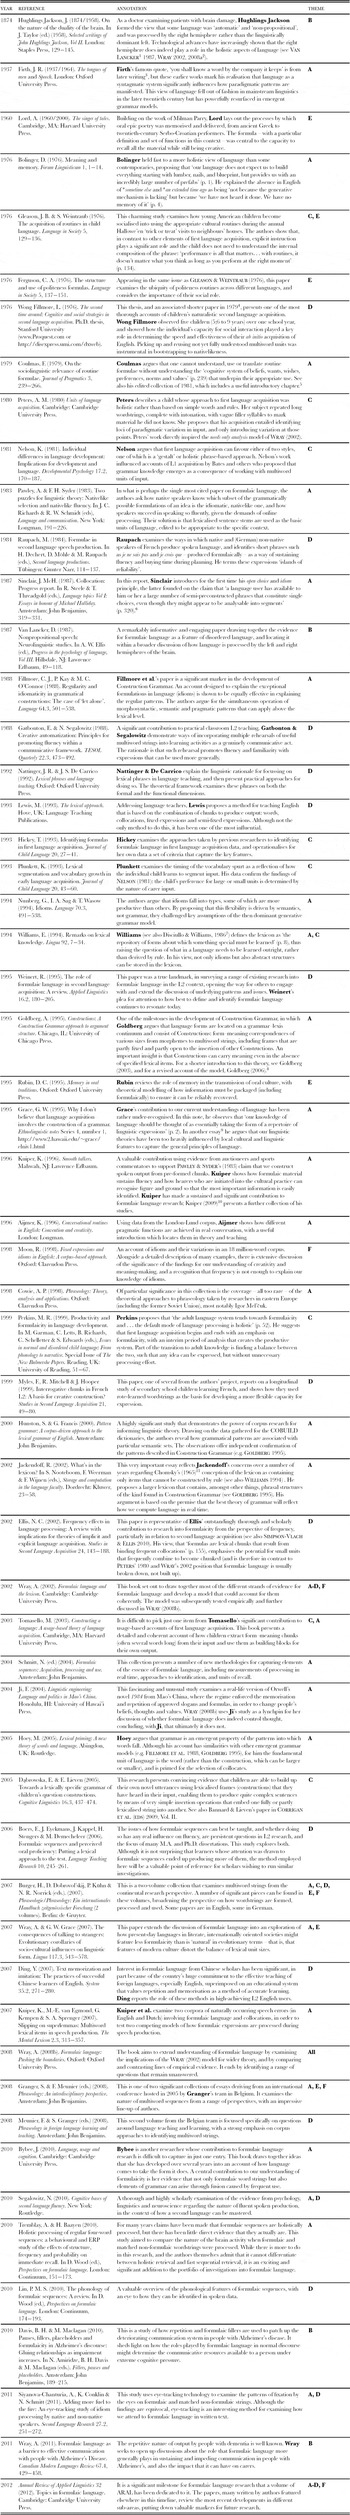
Creating a timeline for formulaic language is far from simple, because several partially independent lines of research have contributed to the emerging picture. Each exhibits cycles of innovation and consolidation over time: domains take a leading role in developing new knowledge and then fall back, while another area comes to the fore. Thus, some of the first observations about formulaic language, back in the nineteenth century, were in the clinical domain of aphasia studies. By the early to mid twentieth century it was theories of language structure that had most to say, until eclipsed by the Chomskian model, which saw little significance in lexicalised units larger than the word (an issue discussed by Jackendoff 2002; see table entry). Meanwhile, changes in language teaching methodology in the mid to late twentieth century increasingly urged teachers to ask how adult learners could best master multiword strings to improve fluency and idiomaticity – a question still asked today. By the end of the twentieth century, new technological advances revealed frequency in usage as a probable agent of formulaicity, and these chimed with new models of lexical knowledge based on neural pathways and networks that could be strengthened by repeated exposure. Drawing on these models, we have seen, as we move into the twenty-first century, the development of new approaches to modelling language as a system – emergent grammars, including Construction Grammar – that are more accommodating of large, internally complex units. And finally, as we gradually understand more about how the brain accesses and retrieves linguistic material, we are seeing a resurgence of interest in formulaic language in neurological and clinical contexts.
One important feature of the way an area of investigation develops over time is that some of the motivations for arguing a position become less relevant – perhaps even incomprehensible – to later readers. Some of the battles fought in the literature have now been won or lost, and no longer have to be re-fought. Thus, it is striking how many of the earlier works on this timeline are significant milestones because they argue that multiword strings might be a unit of lexical processing. They were written at a time when most considered that to be unlikely, so the assertion required courage and evidence to sustain. Yet researchers entering the arena now are generally very comfortable with this idea, and may puzzle about why it was such a big deal in the past. While we all progress our research by building on what has gone before, perhaps a word of caution is in order. It is not impossible for an assertion to become received wisdom just because it is repeated a lot – we should not forget the potential power of the Bellman's Rule of Three in Lewis Carroll's The Hunting of the Snark: ‘What I tell you three times is true’. It behoves every researcher to ask from time to time ‘how do we know this is true?’ and to look for evidence for the claim. The way we conceptualise formulaic language is highly contingent on particular cultural and contextual priorities and assumptions, which we use to impose order on phenomena that, being dually rooted in the human brain and in human society, are far too complex for us to engage with in any other way. The next generation of theories about formulaic language will develop when researchers take a step back and unpick some of those assumptions and priorities, in order to re-evaluate the now accumulated evidence. That work will then establish the significant new milestones in our developing understanding of the phenomenon.
Whilst mindful of the second language acquisition (SLA) focus of this journal, I have been keen not to present only the story of developments in that domain, though there would have been enough material for me to do so. The wider story outlined above seems to me crucial in evaluating the significance and usefulness of the L2-oriented research. That is, one cannot answer the question ‘how can multiword strings be most effectively taught to learners?’ unless one appreciates what a learner's memory and grammar are likely to be able to do with them. One cannot answer the question ‘which multiword strings should be prioritised in teaching?’ unless one understands what they are for in communication, and how they are managed in the linguistic system.
Before proceeding further, we need a working definition of formulaic language. There is none that is theory- or method-neutral, and there is not even consensus across domains of investigation about how open one should be to other definitions alongside one's own. Keeping focus on the issues most relevant to language teachers and learners, a plausible entry point is that ‘formulaic language’ refers to sequences of words that are in some regard not entirely predictable, whether on account of a meaning that is wildly or subtly different from the words they contain, a function that is only achieved with the whole expression, or features of structure such as morphology or word order that are non-canonical. For as long as language learning is construed or practised as the assemblage of single words using repeatable rules, formulaic language, under this definition, will be inherently troublesome to learners.
Most researchers will be comfortable to a greater or lesser extent with such a definition, but it does not by any means exhaust or adequately reflect some aspects of the potential broader phenomenon. For instance, it does not of itself address the frequency relationships between the elements in a wordstring, nor directly engage with the possibility that they are ‘holistically’ processed. It does not specifically allow for the flexibility of a partly fixed and partly open framework, nor does it help us understand how either the speaker or the language might acquire and retain examples of formulaic language. Finally, it has nothing directly to say about whether, or why, formulaic language should be resistant to language damage and loss. Yet all of these features, and others, are prevalent in the wider discussion of formulaic language that the timeline below represents. To my mind, it is the entire set of elements that make formulaic language as a whole interesting enough to care about researching – they require one to look for deep and sustainable answers to what might, within a single domain, seem rather simple questions.
The six themes into which I have organised the timeline references are far less discrete than the taxonomy might imply, but I have resisted extensive cross-labelling, since it should indeed be possible to track each line of the story more or less independently, particularly if those texts given multiple theme labels are used to touch base with how each might interact with the others.
The items on the cutting-room floor are many – I had to be brutal to keep to the required length of list. However, I hope that, with the exception of very recent works, there will be few omissions to which the interested reader cannot find reference via the items that I have included. Inevitably, this particular selection is personal. It is biased by my own interests, and no doubt compromised by my ignorance of some works that readers may feel should be here. At the very least, I hope this timeline will act as a springboard for new discussion about what else should be in the story, and what impact the foregrounding of different historical and current contributions might have on what we understand formulaic language to be.
Themes
A. Theory: Processing, lexis and grammar
Papers under this theme examine (a) the form, meaning and function of formulaic language, locating it, explicitly or implicitly, within theoretical accounts of how language works more generally; (b) how formulaic language is processed and stored.
B. Clinical: Language disorders
This theme recognises the curious resilience of formulaic language in some kinds of language and communication disorder, including several types of aphasia and Alzheimer's Disease. It is also a feature of autism, though none of the papers in this timeline directly addresses that. For a brief overview, see Wray (Reference Wray, Ball, Perkins, Müller and Howard2008a).
C. Development: First language acquisition
If we accept that formulaic language forms part of the adult speaker's lexical inventory, how does it get there? First language acquisition research helps tease apart two possible origins: we acquire small units and learn to build them up into chunks, or we acquire large units and gradually break them down.
D. Learning and teaching: SLA
Two sub-themes combine here: how L2 learners of different ages manage (or somehow fail) to acquire a reliable knowledge of the formulaic language inventory of the target, including the role of rules and creativity; and what ideally should be taught to learners to support their effective learning of useful multiword strings, in the interests of comprehensibility and fluency.
E. Culture: Oral traditions, social roles and cultural variation
In the literary domain, formulaicity is recognised as featuring in memorised and repeated texts – something that links with the clinical research, since rhymes and songs learned in childhood seem particularly resistant to loss. Research into how we engage creatively with memorised material, as in oral epics, informs our understanding of how memory works for multiword strings, and relates also to how memorisation is used for learning in general education and L2 classrooms. Meanwhile, the social roles that formulas play help us to understand why they persist and how they are acquired.
F. Text: Corpora
The relationship between formulaic language and the recurrent wordstrings found in corpora is complex, because the latter are an expression of absolute frequency, whereas some types of formulaic language have low frequency but high salience or uniqueness for their function. Models of language processing (theme A) that favour frequency of exposure as a key determinant of language learning (themes C and D) are likely to draw on corpus data for indications of what will be encountered.
Acknowledgements
This paper has been much improved as a result of insightful comments from Graeme Porte, Kon Kuiper and an anonymous reviewer.
Alison Wray is a Research Professor in Language and Communication at Cardiff University, UK. Her research characteristically synthesises evidence from across domains, to create models of how language works, before testing them empirically. Her contribution to research into formulaic language spans some 15 years, and includes scores of papers and two monographs (2002, 2008b). The former won the 2003 book prize of the British Association for Applied Linguistics. She founded the international Formulaic Language Research Network (FLaRN), and has co-authored two textbooks for students: Projects in linguistics (3rd edn, Taylor and Francis, 2012), with A. Bloomer, and Critical reading and writing for postgraduates (2nd edn, Sage Publications, 2011), with M. Wallace.