1. Introduction
Network science has emerged over the past two decades (see [Reference Barabási4] and [Reference Durrett13]). It studies general features of real-world networks. Examples of such networks include the World Wide Web, the Internet, the power grid, and biological, social, and trade networks. In the introduction of [Reference Barabási4], A. L. Barabási writes that
A key discovery of network science is that the architecture of networks emerging in various domains of science, nature, and technology are similar to each other’ and ‘we will never understand complex systems unless we develop a deep understanding of the networks behind them.
In their seminal paper [Reference Barabási and Albert5], Barabási and Albert listed various scale-free large networks (actor collaboration, the Web, the power grid, etc.), and they described the preferential attachment model. Moreover, they provided an argument and simulation evidence that the preferential attachment rule leads to a scale-free network. A network is called scale-free if its degree distribution is asymptotically a power law, that is, p k ~ Ck −γ as k → ∞, where p k is the probability that a node has degree k. Here and in what follows, a k ~ b k means that limk→∞ a k/b k = 1. The preferential attachment network evolution model is as follows. At every time step t = 2, 3, … a new vertex with N edges is added to the existing graph so that the edges link the new vertex to N old vertices. The probability π i that the new vertex will be connected to the old vertex i depends on the degree d i of vertex i, so that π i = d i/ Σj d j, where Σj d j is the cumulative sum of degrees.
We ought to mention that long before the publication of [Reference Barabási and Albert5], Yule proposed a model for the evolution of species where preferential attachment was present (see [Reference Yule27], and also [Reference Simon25]). Moreover, the precise mathematical formulation of the preferential attachment network evolution model and a rigorous proof of the power law degree distribution in the preferential attachment model was given by Bollobás et al. [Reference Bollobás, Riordan, Spencer and Tusnády7] (see also [Reference Chung and Lu11], [Reference Durrett13], and [Reference Van der Hofstad26]). Nevertheless, in [Reference Barabási and Albert5], Barabási and Albert revealed the connection between preferential attachment and the power law. In his monograph [Reference Van der Hofstad26], van der Hofstad underlined this connection: ‘A possible and convincing explanation for the occurrence of power-law degree sequences is offered by the preferential attachment paradigm.’
The concept of preferential attachment and the scale-free property has incited enormous research activity. In connection with the mathematical models we should also mention that the classical Erdős–Rényi graph (see [Reference Erdés and Rényi14], [Reference Erdés and Rényi15], and [Reference Gilbert19]) is not scale-free. Therefore, new mathematical models were necessary to describe real-life networks. For the mathematical theory, see the monograph [Reference Van der Hofstad26]by van der Hofstad (see also [Reference Chung and Lu11] and [Reference Durrett13]). Concerning the general aspects of network theory, we can consult the comprehensive book [Reference Barabási4] by A. L. Barabási, in which a complete chapter is devoted to the scale-free property. Based on previous studies of large real-life networks (e.g. the Web, the Internet, email, citations)the author claimed that the scale-free property is a ‘universal network characteristic’. On the other hand, he mentioned that ‘The ubiquity of the scale-free property does not mean that all real networks are scale-free’, and he listed networks not sharing this property. In the literature there are many papers devoted to the study of the scale-free property, but there are also papers that do not support this property. For example, Broido and Clauset [Reference Broido and Clauset9] claimed that ‘scale-free networks are rare’ and ‘real-world networks exhibit a rich structural diversity that will likely require new ideas and mechanisms to explain’. In our paper we do not study any specific real-life network, but we offer a new mathematical model to build a network. Our proposal is based on the star-like substructures of networks which, on the one hand, lead to a mathematically tractable model and, on the other hand, seem to be plausible ingredients of real-life networks.
There are several versions of the preferential attachment model; here we can mention only a few of them. Cooper and Frieze [Reference Cooper and Frieze12] introduced the following general graph evolution model. At each step either a new vertex or an old vertex generates new edges. In both cases the terminal vertices can be chosen either uniformly or according to the degrees of the vertices. In [Reference Ostroumova, Ryabchenko and Samosvat23], a general preferential attachment model (the so-called PA class) is defined. Several known models (the LCD model of [Reference Bollobás and Riordan6], the Holme–Kim model [Reference Holme and Kim20], the random Apollonian network [Reference Zhou, Yan and Wang28], the Buckley–Osthus–Móri model [10, 21]) belong to the PA class. In [Reference Ostroumova, Ryabchenko and Samosvat23], a power law degree distribution was proved for the PA class. In [Reference Fazekas, Noszály and Perecsényi18], the PA class was extended to describe the evolution of certain populations. In [Reference Backhausz and Mόri2], [Reference Backhausz and Mόri3], and [Reference Fazekas and Porvázsnyik17], the above-mentioned ideas of Cooper and Frieze [Reference Cooper and Frieze12] were applied, but instead of the original preferential attachment rule, the vertices were chosen according to the weights of certain cliques. An N-clique is a complete graph on N vertices. A clique can be considered as a particular model of a team. That is, any two members of the team are connected to each other. However, there are other structures of cooperation among team members.
In this paper we consider star-like structures, where we have a head of the team with connections to all other members. For example, a given person and his/her friends form a team, that is, the centre is the given person and the peripheral members are his/her friends. Usually, a person can play both roles. For example, John is the centre in the team of his friends, but he is a peripheral member in the team of Peter’s friends (assuming that John and Peter are friends). This kind of double role will be allowed in our model. Examples of star-like structures can be found in companies, authorities, universities, etc. Star topology is the usual structure in computer networks; see, for example, [Reference Bosworth, Kabay and Whyne8]. Our model was motivated by star-like structures in society and in technology. However, our aim was to give a real mathematical model and not to describe a particular network.
Here we explain the evolution of our network in terms of people. The basic unit of cooperation is a team of N people, for which one plays a central role and the others join to him/her. So the structure of a team looks like a star on N vertices. A star on N vertices (N-star for short) consists of a central vertex and N − 1 peripheral vertices which are connected to the central vertex. Here we consider a star as a directed graph, the starting point of an edge is always a peripheral vertex, and the target is the central vertex. In our model the cooperation of N people always means that they form an N-star. Cooperation of the same people can be activated several times. We allow multiple edges in order to show repeated cooperation. So we indicate the new cooperation by creating new edges. For example, if our network consists of one N-star which was activated twice, then it has 2(N − 1) directed edges so that its central vertex has in-degree 2(N − 1) and each of the N − 1 peripheral vertices has out-degree 2.
In our model the teams compete with each other. The strength of a team is measured by its weight. If a team is activated again, then its weight is increased by 1. The higher the weight of a team, the higher the chance that it will be activated again. During the evolution, new members can join to the network. A newcomer has two possibilities. Either he/she joins an existing team or he/she creates a new team. In the first case the newcomer chooses one of the existing teams according to the weights of the teams. In the second case the newcomer chooses N − 1 people uniformly at random and the newcomer himself/herself will be the head of the new team. There are also evolution steps when there is no new person to join to the network. In this case either an existing team is activated again or N randomly chosen members of the network form a new team. The in-degree d 1 and the out-degree d 2 will describe the role of the person. He/she is the head of any team d 1/(N − 1) times, and a non-head member of any team d 2 times.
In Section 2 we give the precise mathematical description of the model. Then the scale-free property is proved both for in-degrees and for out-degrees; see Theorem 2.1. The proofs are presented in Section 3. In the proofs the main probabilistic tools are the Doob–Meyer decomposition and convergence theorems for submartingales. These are the usual tools for obtaining asymptotic results for random graphs (see, e.g. [Reference Backhausz and Mόri2], [Reference Backhausz and Mόri3], and [Reference Fazekas and Porvázsnyik17]). However, the models in [Reference Backhausz and Mόri2], [Reference Backhausz and Mόri3], and [Reference Fazekas and Porvázsnyik17] were ‘homogeneous’, whereas in this paper we distinguish central and peripheral vertices. As such, our formulae are more complicated than those of the above-mentioned papers, so we cannot directly apply any of their calculations. In this paper the challenge of the proofs was to handle multiple sequences and to guess the formulae to be proved by induction.
2. The model and the main result
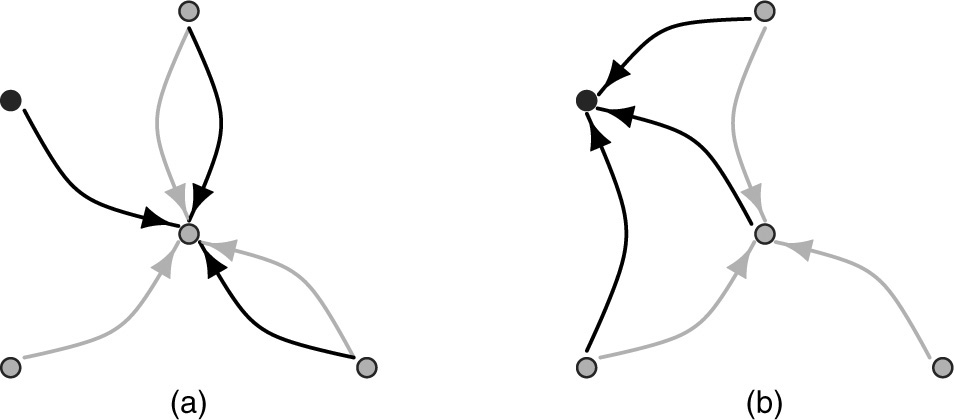
First we give a precise mathematical description of our random graph model. For the convenience of the reader, we also present figures. In Figures 1–3 the initial and the first possible steps are shown when N = 4 (the new vertices and edges are black, and the old vertices and edges are grey).
The initial graph, N = 4.

(a) Case I/1 in the first step, N = 4. (b) Case I/2 in the first step, N = 4.

(a) Case II/1 in the first step, N = 4. (b) Case II/2 in the first step, N = 4.

Let N ≥ 3 be a fixed number. We start at time 0, and the initial graph is an N-star graph. Throughout the paper, we call a graph an N-star graph if it has N vertices, one of which is called the central vertex and the remaining N − 1 vertices called peripheral vertices, and if it
has N − 1 directed edges. The edges start from the N − 1 peripheral vertices and their endpoint is the central vertex. So the central vertex has in-degree N − 1, and each of the N − 1 peripheral vertices has out-degree 1. The initial weight of the N-star is 1, and the initial weights of its (N − 1)-star subgraphs are also 1. (There are N − 1 of these (N − 1)-star subgraphs.)
The evolution of the graph is as follows. At each step, N vertices interact. Interaction (i.e. cooperation) means that we draw all edges from the peripheral vertices to the central vertex so that the vertices form an N-star graph. We allow parallel edges. When N vertices interact, not only are new edges drawn but the weights are also increased. At the first interaction of N vertices the newly created N-star gets weight 1, and its new (N − 1)-star subgraphs also get weight 1. If a subgraph is not newly created then its weight is increased by 1. When an existing N-star is activated again, then its weight and the weights of its (N − 1)-star subgraphs are increased by 1. So the weight of an N-star is the number of its activations. We can see that the weight of an (N − 1)-star is equal to the sum of the weights of the N-stars containing it.
The weights play a crucial role in our model. The higher the weight of a star, the higher the chance that it will be activated again.
We have two options in every step of the evolution.
Option I. With probability p, we add a new vertex, and it interacts with N − 1 old vertices.
Option II. With probability 1 − p, we do not add any new vertex, but N old vertices interact.
Here 0 < p ≤ 1 is fixed.
In option I, that is, when a new vertex is born, we again have two possibilities: option I/1 and option I/2.
Option I/1. The first possibility, which has probability r, is as follows. (Here 0 ≤ r ≤ 1 is fixed.) We choose one of the existing (N − 1)-star subgraphs according to the preferential attachment rule, and it will interact with the new vertex. Here the preferential attachment rule means that an (N − 1)-star of weight v t is chosen with probability v t/ Σh v h, where Σh v his the cumulative weight of the (N − 1)-stars. The interaction of the new vertex and the old (N − 1)-star means that they establish a new N-star. In this newly created N-star the centre will be that vertex which was the centre in the old (N − 1)-star, the former N − 2 peripheral vertices remain peripheral, and the newly born vertex will also be peripheral. New edges are drawn from the new and old peripheral vertices to the central vertex, and then the weights are increased by 1. More precisely, the newly created N-star gets weight 1; among its (N − 1)-star subgraphs there are (N − 2) new subgraphs, so each of them gets weight 1; finally, the weight of the only old (N − 1)-star subgraph is increased by 1.
Option I/2. The second possibility has probability 1 − r. Here we choose N − 1 old vertices uniformly at random, and they form an N-star graph with the new vertex, so that the new vertex will be the centre. The edges are drawn from the peripheral vertices to the centre. Then the weights are increased. As the N-star graph and all of its (N − 1)-star subgraphs are new, all of them get weight 1.
In option II, that is, when we do not add any new vertex, we again have two possibilities: option II/1 and option II/2.
Option II/1. The first possibility has probability q. (Here 0 ≤ q ≤ 1 is fixed.) We choose one of the existing N-star subgraphs by the preferential attachment rule, and draw all edges from its peripheral vertices to the central vertex. Then, as above, the weight of the N-star and the weights of its (N − 1)-star subgraphs are increased by 1. Here the preferential attachment rule means that an N-star of weight v t is chosen with probability v t/ Σh v h, where Σh v h is the cumulative weight of the N-star.
Option II/2. The second possibility has probability 1 − q. We choose N old vertices uniformly at random, and they establish an N-star graph. Its centre is again chosen uniformly at random out of the N vertices. Then, as before, new edges are drawn from the peripheral vertices to the central vertex, and the weights of the N-star and its (N − 1)-star subgraphs are increased by 1.
In this paper we show that this evolution leads to a scale-free graph.
Throughout the paper, 0 < p ≤ 1, 0 ≤ r ≤ 1, 0 ≤ q ≤ 1 are fixed numbers. Let
 $$\matrix{
{{\alpha _{11}}} \hfill & = \hfill & {pr,} \hfill & {{\alpha _{12}}} \hfill & = \hfill & {(1 - p)q,} \hfill \cr {{\alpha _1}} \hfill & = \hfill & {{\alpha _{11}} + {\alpha _{12}},} \hfill & {{\alpha _2}} \hfill & = \hfill & {pr{{N - 2} \over {N - 1}} + (1 - p)q,} \hfill \cr
{{\beta _1}} \hfill & = \hfill & {{{(1 - p)(1 - q)} \over p},} \hfill & {{\beta _2}} \hfill & = \hfill & {(N - 1)[(1 - r) + {{(1 - p)(1 - q)} \over p}],} \hfill \cr
\alpha \hfill & = \hfill & {{\alpha _1} + {\alpha _2},} \hfill & \beta \hfill & = \hfill & {{\beta _1} + {\beta _2}.} \hfill \cr
} $$
Let V n denote the number of vertices after n steps. Let Y(n, d 1, d 2) denote the number of vertices with in-degree d 1 and out-degree d 2 after the nth step, where the values of d 1 can be k(N − 1), k = 0, 1, 2, ….
Theorem 2.1. Let 0 < p < 1, 0 < q < 1, and 0 < r < 1. Then, for any fixed d 1 and d 2 with either d 1 = 0 and 1 ≤ d 2 or N − 1 ≤ d 1 and d 2 ≥ 0, we have
 $${{Y(n,{d_1},{d_2})} \over {{V_n}}} \to {y_{{d_1},{d_2}}}$$
almost surely as n → ∞, where the y d 1,d 2 are fixed nonnegative numbers.
Let d 2 be fixed. Then, as d 1 → ∞,
 $${y_{{d_1},{d_2}}} \sim A({d_2}){\left( {{{{d_1}} \over {N - 1}}} \right)^{ - \left( {1 + {{{\beta _2} + 1} \over {{\alpha _1}}}} \right)}}$$
where
 $$A({d_2}) = {{1 - r} \over {{\alpha _1}}}{1 \over {{d_2}!}}{{{\it{\Gamma}} ({d_2} + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} ({\beta _2}/{\alpha _2})}}{{{\it{\Gamma}} (1 + (\beta + 1)/{\alpha _1})} \over {{\it{\Gamma}} (1 + {\beta _1}/{\alpha _1})}}.$$
Let d 1 be fixed. Then, as d 2 → ∞,
 $${y_{{d_1},{d_2}}} \sim B({d_1})d_2^{ - (1 + ({\beta _1} + 1)/{\alpha _2})},$$
where
 $$B({d_1}) = {r \over {{\alpha _2}}}{1 \over {({d_1}/(N - 1))!}}{{{\it{\Gamma}} ({d_1}/(N - 1) + {\beta _1}/{\alpha _1})} \over {{\it{\Gamma}} ({\beta _1}/{\alpha _1})}}{{{\it{\Gamma}} (1 + (\beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}.$$
Here Γ denotes the gamma function.
Proof. The result is a consequence of Theorem 3.2.
3. Proofs and auxiliary results
3.1. The evolution of the graph
First we reformulate our model in order to simplify the proofs. We shall see that, using the new parameters, our formulae will be symmetric; therefore, we can shorten the proofs. At the same time the new parametrization gives us a new viewpoint. Our new description will be given in terms of undirected graphs without multiple edges. Instead of the multiple edges we shall use weights of the vertices. So, for every vertex, we define its central weight and its peripheral weight.
The central weight of a vertex is w 1 if the vertex was a w 1-times central vertex in interactions. The peripheral weight of a vertex is w 2 if the vertex was a w 2-times peripheral vertex in interactions. It is easy to see that the central weight of a vertex is equal to w 1 = d 1/(N − 1) and the peripheral weight of a vertex is equal to w 2 = d 2, where d 1 denotes the in-degree of the vertex and d 2 denotes its out-degree. After the weights w 1 and w 2 are fixed, we delete all edges between any two given connected vertices and replace them with a single undirected edge. Therefore, this new edge will show that the two vertices cooperated at least once during the evolution. In Lemmas 3.1 and 3.2 and in Theorems 3.1 and 3.2 we shall use this undirected graph. We recall that the weight of an N-star is w if the N-star took part in interactions w times. Similarly, the weight of an (N − 1)-star is w if the (N − 1)-star took part in interactions w times. Recall that V n denotes the number of vertices after n steps. Let X(n, d, w 1, w 2) denote the number of vertices of degree d, central weight w 1, and peripheral weight w 2 after the nth step. Furthermore, let ℱ n−1 denote the σ -algebra of observable events just after the (n − 1)th step. We define 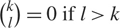 $$\left( {\matrix{
k \cr
l \cr
} } \right) = 0$$ if l > k.
Lemma 3.1. We have
𝔼{X(n, d, w 1, w 2) | ℱ n−1}
 $$\matrix{
{\quad \quad = X(n - 1,d,{w_1},{w_2})[1 - ({{{w_1}} \over n}{\alpha _1} + {{{w_2}} \over n}{\alpha _2} + {p \over {{V_{n - 1}}}}\beta )]} \hfill \cr
{\quad \quad \quad + X(n - 1,d,{w_1},{w_2} - 1)[pr{{(N - 2)({w_2} - 1)} \over {(N - 1)n}}} \hfill \cr
{{\quad \quad \quad \quad \quad \quad \quad \quad \quad \quad \quad \quad \rm{ }} + (1 - p)(q{{{w_2} - 1} \over n} + (1 - q){{d\left( {\matrix{
{{V_{n - 1}} - 2} \cr
{N - 2} \cr
} } \right)} \over {\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)N}})]} \hfill \cr
{\quad \quad \quad {\kern 1pt} + X(n - 1,d - 1,{w_1},{w_2} - 1)[p(1 - r){{N - 1} \over {{V_{n - 1}}}} + (1 - p)(1 - q){{({V_{n - 1}} - d)\left( {\matrix{
{{V_{n - 1}} - 2} \cr
{N - 2} \cr
} } \right)} \over {\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)N}}]} \hfill \cr
{\quad \quad \quad {\kern 1pt} + X(n - 1,d,{w_1} - 1,{w_2})[(1 - p)(q{{{w_1} - 1} \over n} + (1 - q){{\left( {\matrix{
d \cr
{N - 1} \cr
} } \right)} \over {\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)N}})]} \hfill \cr
{\quad \quad \quad {\kern 1pt} + X(n - 1,d - 1,{w_1} - 1,{w_2})[pr{{{w_1} - 1} \over n} + (1 - p)(1 - q){{\left( {\matrix{
{d - 1} \cr
{N - 2} \cr
} } \right)({V_{n - 1}} - d)} \over {\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)N}}]} \hfill \cr
{\quad \quad \quad {\kern 1pt} + \sum\limits_{m = 2}^{N - 2} X(n - 1,d - m,{w_1} - 1,{w_2})[(1 - p)(1 - q){{\left( {\matrix{
{d - m} \cr
{N - m - 1} \cr
} } \right)\left( {\matrix{
{{V_{n - 1}} - d + m - 1} \cr
m \cr
} } \right)} \over {\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)N}}]} \hfill \cr
{\quad \quad \quad {\kern 1pt} + X(n - 1,d - (N - 1),{w_1} - 1,{w_2})[(1 - p)(1 - q){{\left( {\matrix{
{{V_{n - 1}} - d + N - 2} \cr
{N - 1} \cr
} } \right)} \over {\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)N}}]} \hfill \cr
{\quad \quad \quad {\kern 1pt} + pr{\delta _{d,1}}{\delta _{{w_1},0}}{\delta _{{w_2},1}} + p(1 - r){\delta _{d,N - 1}}{\delta _{{w_1},1}}{\delta _{{w_2},0}}} \hfill \cr
} $$
for either w 1 = 0, 1 ≤ w 2 and 1 ≤ d ≤ w 2 or 1 ≤ w 1, 0 ≤ w 2 and N − 1 ≤ d ≤ w 1(N − 1) + w 2. Here δ k,l denotes the Dirac delta.
Proof. Throughout the proof, w 1 will denote the central weight and w 2 will denote the peripheral weight of a given vertex. The total weight of (N − 1)-stars having a fixed common vertex of weights w 1 and w 2 is w 1(N − 1) + w 2(N − 2). The total weight of N-stars after (n − 1) steps is n. The total weight of (N − 1)-stars after n − 1 steps is n(N − 1). The probability that a given vertex is chosen if we choose N − 1 vertices uniformly is
 $${{\left( {\matrix{
{{V_{n - 1}} - 1} \cr
{N - 2} \cr
} } \right)} \over {\left( {\matrix{
{{V_{n - 1}}} \cr
{N - 1} \cr
} } \right)}} = {{N - 1} \over {{V_{n - 1}}}}.$$
The probability that a given vertex is chosen if we choose N vertices uniformly is
 $${{\left( {\matrix{
{{V_{n - 1}} - 1} \cr
{N - 1} \cr
} } \right)} \over {\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)}} = {N \over {{V_{n - 1}}}}.$$
So the probability that an old vertex of weights w 1 and w 2 takes part in the interaction at step n is
 $$\eqalign{
& p\left( {r{{{w_1}(N - 1) + {w_2}(N - 2)} \over {(N - 1)n}} + (1 - r){{N - 1} \over {{V_{n - 1}}}}} \right) + (1 - p)\left( {q{{{w_1} + {w_2}} \over n} + (1 - q){N \over {{V_{n - 1}}}}} \right) \cr
& \quad \quad = {\alpha _1}{{{w_1}} \over n} + {\alpha _2}{{{w_2}} \over n} + \beta {p \over {{V_{n - 1}}}}. \cr} $$
At each step when a new vertex is born, we have two cases:
(i) with probability pr, a new vertex is born with central weight 0, peripheral weight 1, and degree 1;
(ii) with probability p(1 − r), a new vertex is born with central weight 1, peripheral weight 0, and degree N − 1.
Let us consider a fixed old vertex with degree d, central weight w 1, and peripheral weight w 2. For this vertex, the probability that in the nth step
• neither its degree nor its weights change is
 $$1 - \left({\alpha _1}{{{w_1}} \over n} + {\alpha _2}{{{w_2}} \over n} + \beta {p \over {{V_{n - 1}}}}\right);$$
• its degree does not change but its central weight is increased by 1 is
$$\left( {1 - p} \right)\left(q{{{w_1}} \over n} + \left( {1 - q} \right){{\left( {\matrix{
d \cr
{N - 1} \cr
} } \right)} \over {N\left( {\matrix{
{^Vn - 1} \cr
N \cr
} } \right)}}\right);$$
• its degree does not change but its peripheral weight is increased by 1 is
$$pr{{{w_2}(N - 2)} \over {n(N - 1)}} + (1 - p)q{{{w_2}} \over n} + (1 - p)(1 - q){{d\left( {\matrix{
{{V_{n - 1}} - 2} \cr
{N - 2} \cr
} } \right)} \over {N\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)}};$$
• its degree and its central weight are increased by 1 is
$$pr{{{w_1}} \over n} + (1 - p)(1 - q){{\left( {\matrix{
d \cr
{N - 2} \cr
} } \right)\left( {\matrix{
{{V_{n - 1}} - d - 1} \cr
1 \cr
} } \right)} \over {N\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)}};$$
• its degree and its peripheral weight are increased by 1 is
$$p(1 - r){{N - 1} \over {{V_{n - 1}}}} + (1 - p)(1 - q){{\left( {\matrix{
{{V_{n - 1}} - d - 1} \cr
1 \cr
} } \right)\left( {\matrix{
{{V_{n - 1}} - 2} \cr
{N - 2} \cr
} } \right)} \over {N\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)}};$$
• its degree is increased by m (1 < m < N − 1) and its central weight is increased by 1 is
$$(1 - p)(1 - q){{\left( {\matrix{
{{V_{n - 1}} - d - 1} \cr
m \cr
} } \right)\left( {\matrix{
d \cr
{N - 1 - m} \cr
} } \right)} \over {N\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)}};$$
• its degree is increased by N − 1 and its central weight is increased by 1 is
$$(1 - p)(1 - q){{\left( {\matrix{
{{V_{n - 1}} - d - 1} \cr
{N - 1} \cr
} } \right)} \over {N\left( {\matrix{
{{V_{n - 1}}} \cr
N \cr
} } \right)}}.$$


From these formulae we obtain (3.1).
Theorem 3.1. Let 0 < p < 1, 0 < q < 1, and 0 < r < 1. Then, for any fixed w 1, w 2, and d with either 0 = w 1, 1 ≤ w 2, and 1 ≤ d ≤ w 2, or 1 ≤ w 1, 0 ≤ w 2, and N − 1 ≤ d ≤ w 1(N − 1) + w 2, we have
 $${{X(n,d,{w_1},{w_2})} \over {{V_n}}} \to {x_{d,{w_1},{w_2}}}$$
almost surely as n → ∞, where the x d,w 1,w 2 are fixed nonnegative numbers.
Furthermore, the numbers x d,w 1,w 2 satisfy the recurrence relation
 $$\matrix{
{{x_{N - 1,1,0}} = {{1 - r} \over {{\alpha _1} + \beta + 1}} > 0,\quad \quad {x_{d,1,0}} = 0\quad {\it{for\,}}d \ne N - 1,} \cr
{{x_{1,0,1}} = {r \over {{\alpha _2} + \beta + 1}} > 0,\quad \quad {x_{d,0,1}} = 0\quad {\it{for\,}}d \ne 1,} \cr
{{x_{d,{w_1},{w_2}}} = {1 \over {{\alpha _1}{w_1} + {\alpha _2}{w_2} + \beta + 1}}} \cr
{\quad {\kern 1pt} \times [{\alpha _{11}}({w_1} - 1){x_{d - 1,{w_1} - 1,{w_2}}} + {\alpha _{12}}({w_1} - 1){x_{d,{w_1} - 1,{w_2}}}} \cr
{\quad \quad \quad \quad \quad \quad \quad + {\alpha _2}({w_2} - 1){x_{d,{w_1},{w_2} - 1}} + {\beta _1}{x_{d - (N - 1),{w_1} - 1,{w_2}}} + {\beta _2}{x_{d - 1,{w_1},{w_2} - 1}}]} \cr
} $$
for any w 1, w 2, and d. In the cases when x d,w 1,w 2 = 0, we have
 $${{X(n,d,{w_1},{w_2})} \over {{V_n}}} = {\rm{o}}({n^{ - a}}),$$
where a is a positive number which may depend on w 1,w 2, and d.
3.2. Proof of Theorem 3.1
In the proof we shall use two major tools: a submartingale convergence theorem and mathematical induction. For the reader’s convenience, we quote the submartingale convergence theorem in Appendix A (Lemma A.1). The proof will be divided into two subsections. In the first subsection we shall introduce a submartingale and calculate its Doob–Meyer decomposition. The second subsection will contain the mathematical induction. As the index set is two dimensional, we shall use multiple induction, further dividing the second section of the proof.
3.2.1. The basic submartingale and its Doob–Meyer decomposition
Let
 $$c(n,{w_1},{w_2}) = \prod\limits_{i = 1}^n {\left(1 - {\alpha _1}{{{w_1}} \over i} - {\alpha _2}{{{w_2}} \over i} - \beta {p \over {{V_{i - 1}}}}\right)^{ - 1}},\quad \quad {w_1} + {w_2} \ge 1.$$
We can see that c(n, w 1, w 2) is an ℱ n−1-measurable positive random variable. Applying the Marcinkiewicz strong law of large numbers to the number of vertices, we obtain
 $${V_n} = pn + {\rm{o}}({n^{1/2 + \varepsilon }})\quad {\rm{almost\,surely\,for\,any\,}}\varepsilon {\rm{ > 0}}{\rm{.}}$$
Now, using (3.3) and the Taylor expansion for log (1 + x), we have
 $$\matrix{
{\log c(n,{w_1},{w_2})} & = & { - \sum\limits_{i = 1}^n {\rm{ log}}\left( {1 - {\alpha _1}{{{w_1}} \over i} - {\alpha _2}{{{w_2}i} \over {}} - \beta {1 \over {i + o\left( {{i^{1/2 + \varepsilon }}} \right)}}} \right)} \cr
{} & = & {({\alpha _1}{w_1} + {\alpha _2}{w_2} + \beta )\sum\limits_{i = 1}^n {1 \over i} + {\rm{O}}(1),} \cr
} $$
where the error term is convergent as n → ∞. So
 $$c(n,{w_1},{w_2}) \sim {a_{{w_1},{w_2}}}{n^{{\alpha _1}{w_1} + {\alpha _2}{w_2} + \beta }}$$
almost surely as n → ∞.Here a w 1,w 2 is a positive random variable.
Let
 $$Z(n,d,{w_1},{w_2}) = c(n,{w_1},{w_2})X(n,d,{w_1},{w_2}),$$
where 1 ≤ d ≤ w 1(N − 1) + w 2, 1 ≤ w 1 + w 2. In (3.1) all terms are nonnegative. So multiplying both sides of (3.1) by c(n, w 1, w 2), we see that {Z(n, d, w 1, w 2), ℱ n, n = 1, 2, …} is a nonnegative submartingale for any fixed 1 ≤ d ≤ w 1(N − 1) + w 2 and 1 ≤ w 1 + w 2. By the Doob–Meyer decomposition of Z(n, d, w 1, w 2), we have
 $$Z(n,d,{w_1},{w_2}) = M(n,d,{w_1},{w_2}) + A(n,d,{w_1},{w_2}),$$
where M(n, d, w 1, w 2) is a martingale and A(n, d, w 1, w 2) is a predictable increasing process, and their general forms are
 $$\eqalign{{M(n,d,{w_1},{w_2})} & = {\sum\limits_{i = 1}^n [Z(i,d,{w_1},{w_2}) - {\mathbb E}(Z(i,d,{w_1},{w_2})|{{\cal F}_{i - 1}})],} \cr {A(n,d,{w_1},{w_2})} & = {{\mathbb E}Z(1,d,{w_1},{w_2}) + \sum\limits_{i = 2}^n [{\mathbb E}(Z(i,d,{w_1},{w_2})|{{\cal F}_{i - 1}}) - Z(i - 1,d,{w_1},{w_2})].} } $$
Here ℱ 0 denotes the trivial σ -algebra. From Lemma 3.1 and (3.5), we obtain
A(n, d, w 1, w 2)
 $$\matrix{{\quad = {\mathbb E}Z(1,d,{w_1},{w_2})} \hfill \cr
{\quad \quad {\kern 1pt} + \sum\limits_{i = 2}^n c(i,{w_1},{w_2})\{ X(i - 1,d,{w_1},{w_2} - 1)} \hfill \cr
{{\quad \quad \quad \quad \quad \rm{ }} \times [pr{{(N - 2)({w_2} - 1)} \over {(N - 1)i}} + (1 - p)\left(q{{{w_2} - 1} \over i} + (1 - q){{d\left( {\matrix{
{{V_{i - 1}} - 2} \cr
{N - 2} \cr
} } \right)} \over {\left( {\matrix{
{{V_{i - 1}}} \cr
N \cr
} } \right)N}}\right)]} \hfill \cr
{{\quad \quad \quad \quad \quad \rm{ }} + X(i - 1,d - 1,{w_1},{w_2} - 1)} \hfill \cr
{{\quad \quad \quad \quad \quad \quad \rm{ }} \times \left(p(1 - r){{N - 1} \over {{V_{i - 1}}}} + (1 - p)(1 - q){{({V_{i - 1}} - d)\left( {\matrix{
{{V_{i - 1}} - 2} \cr
{N - 2} \cr
} } \right)} \over {\left( {\matrix{
{{V_{i - 1}}} \cr
N \cr
} } \right)N}}\right)} \hfill \cr
{{\quad \quad \quad \quad \quad \rm{ }} + X(i - 1,d,{w_1} - 1,{w_2})\left((1 - p)q{{{w_1} - 1} \over i}\right)} \hfill \cr
{{\quad \quad \quad \quad \quad \rm{ }} + X(i - 1,d - 1,{w_1} - 1,{w_2})\left(pr{{{w_1} - 1} \over i}\right)} \hfill \cr
{{\quad \quad \quad \quad \quad \rm{ }} + \sum\limits_{m = 0}^{N - 1} X(i - 1,d - m,{w_1} - 1,{w_2})} \hfill \cr
{{\quad \quad \quad \quad \quad \quad \rm{ }} \times \left((1 - p)(1 - q){{\left( {\matrix{
{d - m} \cr
{N - m - 1} \cr
} } \right)\left( {\matrix{
{{V_{i - 1}} - d + m - 1} \cr
m \cr
} } \right)} \over {\left( {\matrix{
{{V_{i - 1}}} \cr
N \cr
} } \right)N}}\right)} \hfill \cr
{{\quad \quad \quad \quad \quad \rm{ }} + pr{\delta _{d,1}}{\delta _{{w_1},0}}{\delta _{{w_2},1}} + p(1 - r){\delta _{d,N - 1}}{\delta _{{w_1},1}}{\delta _{{w_2},0}}\} .} \hfill \cr
} $$
In the following we give an upper bound for B(n, d, w 1, w 2), where B(n, d, w 1, w 2) denotes the sum of the conditional variances of Z(n, d, w 1, w 2):
 $$\matrix{
{B(n,d,{w_1},{w_2})} & = &{\sum\limits_{i = 2}^n {\mathbb E}\{ (Z(i,d,{w_1},{w_2}) - {\mathbb E}(Z(i,d,{w_1},{w_2})|{{\cal F}_{i - 1}}{{))}^2}|{{\cal F}_{i - 1}}\} } \hfill \cr
{} & = &{\sum\limits_{i = 2}^n c{{(i,{w_1},{w_2})}^2}{\mathbb E}\{ (X(i,d,{w_1},{w_2}) - {\mathbb E}(X(i,d,{w_1},{w_2})|{{\cal F}_{i - 1}}{{))}^2}|{{\cal F}_{i - 1}}\} } \hfill \cr
{} & \le &{\sum\limits_{i = 2}^n c{{(i,{w_1},{w_2})}^2}{\mathbb E}\{ (X(i,d,{w_1},{w_2}) - X(i - 1,d,{w_1},{w_2}{{))}^2}|{{\cal F}_{i - 1}}\} } \hfill \cr
{} & \le &{{N^2}\sum\limits_{i = 2}^n c{{(i,{w_1},{w_2})}^2}} \hfill \cr
} $$
 $$ = {\rm{O}}({n^{2({\alpha _1}{w_1} + {\alpha _2}{w_2} + \beta ) + 1}}).$$
Here we used the facts that c(i, w 1, w 2)is ℱ i−1-measurable and that at each step N vertices interact, and then we applied (3.4).
As M(n, d, w 1, w 2) is a martingale, M 2(n, d, w 1, w 2) is therefore a submartingale because of Jensen’s inequality. Applying the Doob–Meyer decomposition for M 2(n, d, w 1, w 2), we obtain
 $${M^2}(n,d,{w_1},{w_2}) = Y(n,d,{w_1},{w_2}) + B(n,d,{w_1},{w_2}),$$
where Y(n, d, w 1, w 2) is a martingale and the predictable increasing process B(n, d, w 1, w 2)is the same as that in (3.7).
3.2.2. The mathematical induction
First we consider the particular case in which w 1 = 1 and w 2 = 0, then the case in which w 1 = 0 and w 2 = 1, and also the case in which w 1 = 1 and w 2 = 1. Then we use induction along the boundary of the domain, i.e. when w 1 = 0 or w 2 = 0. Finally, we use induction in the interior of the domain.
Step (a). Let w 1 = 1 and w 2 = 0. A vertex with these weights exists if and only if it was once the centre and it was never peripheral. In this case its degree has to be equal to N − 1. Using (3.6) and (3.4),
 $$\matrix{
{A(n,N - 1,1,0)} \hfill & { \sim p(1 - r)\sum\limits_{i = 2}^n c(i,1,0)} \hfill \cr
{} \hfill & { \sim p(1 - r)\sum\limits_{i = 2}^n {a_{1,0}}{i^{{\alpha _1} + \beta }}} \hfill \cr
{} \hfill & { \sim p(1 - r){a_{1,0}}{{{n^{{\alpha _1} + \beta + 1}}} \over {{\alpha _1} + \beta + 1}}} \hfill \cr
{} \hfill & { \to \infty \quad {\rm{almost}}\,{\rm{surely}}\,{\rm{as}}\,n \to \infty {\rm{.}}} \hfill \cr
} $$
Using (3.7),
 $$B(n,N - 1,1,0) = {\rm{O}}({n^{2({\alpha _1} + \beta ) + 1}}),$$
so
 $$B{(n,N - 1,1,0)^{1/2}}\log B(n,N - 1,1,0) = {\rm{O}}(A(n,N - 1,1,0)).$$
Now, applying Lemma A.1, we obtain
 $$Z(n,N - 1,1,0) \sim A(n,N - 1,1,0)$$
almost surely on the event {A(n, N − 1, 1, 0) → ∞} as n → ∞. Using (3.3), (3.4), (3.9), and (3.10), we have
 $$\matrix{
{{{X(n,\,N - 1,\,1,\,0)} \over {{V_n}}}} & = &{{{Z(n,\,N - 1,\,1,\,0)} \over {c(n,\,1,\,0){V_n}}}} \hfill \cr
{} &\sim &{{{A(n,\,N - 1,\,1,\,0)} \over {c(n,\,1,\,0){V_n}}}} \hfill \cr
{} &\sim &{{{p(1 - r){a_{1,0}}{n^{{\alpha _1} + \beta + 1}}/({\alpha _1} + \beta + 1)} \over {{a_{1,0}}{n^{{\alpha _1} + \beta }}pn}}} \hfill \cr
{} & = &{{{1 - r} \over {{\alpha _1} + \beta + 1}}} \hfill \cr
{} & = &{{x_{N - 1,1,0}}} \hfill \cr
{} & \gt &{0.} \hfill \cr
} $$
Otherwise, when d ≠ N − 1, then X(n, d, 1, 0) ≡ 0. So (3.2) holds for w 1 = 1 and w 2 = 0.
Step (b). Now let w 1 = 0 and w 2 = 1. In this case the degree of the vertex has to be 1. From (3.6),
 $$\matrix{
{A(n,1,0,1)} & \sim & {pr\sum\limits_{i = 2}^n c(i,0,1)} \hfill \cr
{} & \sim & {pr\sum\limits_{i = 2}^n {a_{0,1}}{i^{{\alpha _2} + \beta }}} \hfill \cr
{} & \sim & pr{a_{0,1}}{{{n^{{\alpha _2} + \beta + 1}}} \over {{\alpha _2} + \beta + 1}} \hfill \cr
{} & \to & {\infty {\rm{\,almost\,surely\,as\,}}n \to \infty. } \hfill \cr
} $$
Using (3.7), we have
 $$B(n,1,0,1) = {\rm{O}}({n^{2({\alpha _1} + \beta ) + 1}}),$$
so
 $$B{(n,1,0,1)^{1/2}}\log B(n,1,0,1) = {\rm{O}}(A(n,1,0,1)).$$
As before (see Lemma A.1), we obtain
 $$Z(n,1,0,1) \sim A(n,1,0,1)$$
almost surely on the event {A(n, 1, 0, 1) → ∞} as n → ∞. So, using (3.3), (3.4), (3.12), and (3.13), we have
 $$\matrix{
{{{X(n,\,1,\,\,0,\,\,1)} \over {{V_n}}}} & = & {{{Z(n,\,1,\,\,0,\,\,1)} \over {c(n,\,0,\,\,1){V_n}}}} \hfill \cr
{} & \sim & {{{A(n,\,\,1,\,\,0,\,\,1)} \over {c(n,\,0,\,\,1){V_n}}}} \hfill \cr
{} & \sim & {{{pra_{0,\,1}{n^{{\alpha _1} + \beta + 1}}/({\alpha _1} + \beta + 1)} \over {{a_{0,\,1}}{n^{{\alpha _1} + \beta }}pn}}} \hfill \cr
{} & = & {{{r} \over {{\alpha _1} + \beta + 1}}} \hfill \cr
{} & = & {{x_{1,0,1}}} \hfill \cr
{} & > & {0.} \hfill \cr
} $$
Otherwise, when d ≠ 1, then X(n, d, 0, 1) ≡ 0. So (3.2) also holds for w 1 = 0 and w 2 = 1.
Step (c). Now consider the case in which w 1 = w 2 = 1. Vertices with these weights exist only with degree N − 1 or N. First we deal with the case when the degree is N − 1. Now, by (3.4), (3.6), (3.11), and (3.14),
A(n, N − 1, 1, 1)
 $$\eqalign{
& \sim \sum\limits_{i = 2}^n {a_{1,1}}{i^{{\alpha _1} + {\alpha _2} + \beta }}\left( {{x_{1,0,1}}(1 - p)(1 - q){{N - 1} \over {p(i - 1)}} + {x_{N - 1,1,0}}(1 - p)(1 - q){{{{(N - 1)}^2}} \over {p(i - 1)}}} \right) \cr
& \sim \sum\limits_{i = 2}^n {i^{{\alpha _1} + {\alpha _2} + \beta - 1}}{a_{1,1}}{{(1 - p)(1 - q)(N - 1)} \over p}({x_{1,0,1}} + {x_{N - 1,1,0}}(N - 1)) \cr
& \sim {a_{1,1}}{{(1 - p)(1 - q)(N - 1)} \over p}({x_{1,0,1}} + (N - 1){x_{N - 1,1,0}}){{{n^{{\alpha _1} + {\alpha _2} + \beta }}} \over {{\alpha _1} + {\alpha _2} + \beta }}. \cr} $$
By (3.7),
 $$B(n,N - 1,1,1) = {\rm{O}}({n^{2({\alpha _1} + {\alpha _2} + \beta ) + 1}}).$$
So in this case
 $$B{(n,N - 1,1,1)^{1/2}}\log B(n,N - 1,1,1) \ne {\rm{O}}(A(n,N - 1,1,1)).$$
Using Lemma A.1, we can see that, for any ε > 0,
 $$M(n,N - 1,1,1) = {\rm{o}}(B{(n,N - 1,1,1)^{1/2}}\log B(n,N - 1,1,1)) = {\rm{o}}({n^{{\alpha _1} + {\alpha _2} + \beta + 1/2 + \varepsilon }})$$
almost surely on the event {B(n, N − 1, 1, 1) → ∞} as n → ∞. Furthermore, M(n, N − 1, 1, 1) is convergent on the event {B(∞, N − 1, 1, 1) < ∞} as n → ∞, so
 $$M(n,N - 1,1,1) = {\rm{o}}({n^{{\alpha _1} + {\alpha _2} + \beta + 1/2 + \varepsilon }})$$
almost surely. Therefore, from (3.3), (3.4), and (3.15), we obtain
 $$\matrix{
{{{X(n,\,N - 1,\,1,\,1)} \over {{V_n}}}} & = & {{{Z(n,\,N - 1,\,1,\,1)} \over {c(n,\,1,\,1){V_n}}}} \hfill \cr
{} & = & {{{M(n,\,N - 1,\,1,\,1) + A(n,\,N - 1,\,1,\,1)} \over {c(n,\,1,\,1){V_n}}}} \hfill \cr
{} & \le & {{{C{n^{{\alpha _1} + {\alpha _2} + \beta + 1/2 + \varepsilon }}} \over {{n^{{\alpha _1} + {\alpha _2} + \beta }}n}}} \hfill \cr
{} & \le & {C{1 \over {{n^a}}}} \hfill \cr
{} & \to & 0 \hfill \cr
} $$
as n → ∞ with  $${\textstyle{1 \over 4}} \lt a \lt {\textstyle{1 \over 2}}$$.
Consider the second case, that is, when the degree of vertices is equal to N. From (3.6),
 $$\matrix{
{A(n,N,1,1) \sim \sum\limits_{i = 2}^n {a_{1,1}}{i^{{\alpha _1} + {\alpha _2} + \beta }}[(N - 1)(p(1 - r) + (1 - p)(1 - q)){x_{N - 1,1,0}}} \hfill \cr
{{\quad \quad \quad \quad \quad \quad \quad \quad \rm{ }} + (1 - p)(1 - q){x_{1,0,1}}]} \hfill \cr
{{\quad \quad \quad \quad \rm{ }} \sim {a_{1,1}}[(N - 1)(p(1 - r) + (1 - p)(1 - q)){x_{N - 1,1,0}} + (1 - p)(1 - q){x_{1,0,1}}]} \hfill \cr
{\quad \quad \quad \quad \quad \quad {\kern 1pt} {\rm{ }} \times {{{n^{{\alpha _1} + {\alpha _2} + \beta + 1}}} \over {{\alpha _1} + {\alpha _2} + \beta + 1}}} \hfill \cr
{{\quad \quad \quad \quad \rm{ }} \to \infty \quad {\rm{almost\,surely\,as\,}}n \to \infty {\rm{.}}} \hfill \cr
} $$
Using (3.7),
 $$B(n,N,1,1) = {\rm{O}}({n^{2({\alpha _1} + {\alpha _2} + \beta ) + 1}}),$$
so
 $$B{(n,N,1,1)^{1/2}}\log B(n,N,1,1) = {\rm{O}}(A(n,N,1,1)).$$
As before, using Lemma A.1, we obtain
 $$Z(n,N,1,1) \sim A(n,N,1,1)$$
almost surely on the event {A(n, N, 1, 1) → ∞} as n → ∞. So from (3.3), (3.4), (3.16), and (3.17), we obtain
 $$\matrix{
{{{X(n,\,N,\,1,\,1)} \over {{V_n}}}} & = & {{{Z(n,\,N,\,1,\,1)} \over {c(n,\,1,\,1){V_n}}}} \hfill \cr
{} & \sim & {{{A(n,\,N,\,1,\,1)} \over {c(n,\,1,\,1){V_n}}}} \hfill \cr
{} & \sim & {{{(N - 1)(p(1 - r) + (1 - p)(1 - q)){x_{N - 1,1,0}} + (1 - p)(1 - q){x_{1,0,1}}} \over {({\alpha _1} + {\alpha _2} + \beta + 1)p}}} \hfill \cr
{} & = & {{1 \over {{\alpha _1} + {\alpha _2} + \beta + 1}}({\beta _1}{x_{1,0,1}} + {\beta _2}{x_{N - 1,1,0}})} \hfill \cr
{} & = & {{x_{N,1,1}}} \hfill \cr
{} & > & {0.} \hfill \cr
} $$
Otherwise, if d ≠ N − 1or d ≠ N, then X(n, d, 1, 1) ≡ 0. So (3.2) also holds for w 1 = 1 and w 2 = 1.
Step (d). Now we study the case in which w 1 = k and w 2 = 0, k > 1. These vertices were always central in interactions, and they were never peripheral. In this case N − 1 ≤ d ≤ k(N − 1), where d denotes the degree of vertices. Suppose that the statement holds for all central weights less than k, for zero peripheral weight, and for all possible degrees. Assume that at least one of the coefficients x d−1,k−1,0, x d,k−1,0, x d−(N−1),k−1,0 is positive. As before,
from (3.6),
 $$\matrix{
{A(n,d,k,0) \sim \sum\limits_{i = 2}^n {a_{k,0}}{i^{k{\alpha _1} + \beta }}[{x_{d - 1,k - 1,0}}(k - 1){p^2}r + {x_{d,k - 1,0}}(k - 1)p(1 - p)q} \hfill \cr
{{\quad \quad \quad \quad \quad \quad \quad \quad \rm{ }} + {x_{d - (N - 1),k - 1,0}}(1 - p)(1 - q)]} \hfill \cr
{{\quad \quad \quad \quad \rm{ }} \sim {a_{k,0}}{{{n^{k{\alpha _1} + \beta + 1}}} \over {k{\alpha _1} + \beta + 1}}[{x_{d - 1,k - 1,0}}(k - 1){p^2}r + {x_{d,k - 1,0}}(k - 1)p(1 - p)q} \hfill \cr
{{\quad \quad \quad \quad \quad \quad \quad \quad \rm{ }} + {x_{d - (N - 1),k - 1,0}}(1 - p)(1 - q)]} \hfill \cr
{\to \infty \quad {\rm{almost\,surely\,as\,}}n \to \infty {\rm{.}}}
} $$
Using (3.7), we have
 $$B(n,d,k,0) = {\rm{O}}({n^{2({k\alpha _1} + {\beta _2} + 1}}),$$
so
 $$B{(n,d,k,0)^{1/2}}\log B(n,d,k,0) = {\rm{O}}(A(n,d,k,0)).$$
As above, we have
 $$Z(n,d,k,0) \sim A(n,d,k,0)$$
almost surely on the event {A(n, d, k, 0) → ∞} as n → ∞. Therefore, using (3.3), (3.4), (3.18), and (3.20), we have
 $$\matrix{
{X(n,\,d,\,k,\,0) \over {V_n}} & = & {Z(n,\,d,\,k,\,0) \over c(n,\,k,\,0){V_n}} \hfill \cr
{} & \sim & {A(n,\,d,\,k,\,0) \over c(n,\,k,\,0){V_n}} \hfill \cr
{} & \sim & {{1 \over k{\alpha _1} + \beta + 1}[(k - 1)({\alpha _{11}}{x_{d - 1,k - 1,0}} + {\alpha _{12}}{x_{d,k - 1,0}}) + {\beta _1}{x_{d - (N - 1),k - 1,0}]}} \hfill \cr
{} & = & {{x_{d,k,0}}} \hfill \cr
{} & > & {0,} \hfill \cr
} $$
if at least one of the coefficients x d−1,k−1,0, x d,k−1,0 and x d−(N−1),k−1,0 is positive. Otherwise, the limit is zero. We can see that, for any fixed k, the limit of X(n, d, k, 0)/V n is positive if d ≥ N − 1 and d is ‘close to’ N − 1. However, if d is ‘close to’ k(N − 1), the limit of X(n, d, k, 0)/V n can be either zero or positive. If d < N − 1or d > k(N − 1), the limit is zero, because in these cases X(n, d, k, 0) ≡ 0.
Now, consider the case when the coefficients x d−1,k−1,0, x d,k−1,0, and x d−(N−1),k−1,0 are equal to zero. From (3.3), (3.4), and (3.6), and using the induction hypothesis, we obtain
A(n, d, k, 0)
 $$\matrix{
{\quad \quad \sim \sum\limits_{i = 2}^n {a_{k,0}}{i^{k{\alpha _1} + \beta }}({\rm{O}}({1 \over {{i^a}}}) + \sum\limits_{m = 2}^{N - 2} X(i - 1,d - m,k - 1,0)} \hfill \cr
{\quad \quad \quad \quad \quad \quad {\rm{ }} \times ((1 - p)(1 - q){{\left( {\matrix{
{d - m} \cr
{N - m - 1} \cr
} } \right)(N - 1)!} \over {m!}}{1 \over {{{(pi)}^{N - m}}}}))} \hfill \cr
{\quad \quad \le {C_1}\sum\limits_{i = 2}^n {a_{k,0}}{i^{k{\alpha _1} + \beta - a}} + {C_2}\sum\limits_{i = 2}^n \sum\limits_{m = 2}^{N - 2} {a_{k,0}}{i^{k{\alpha _1} + \beta }}{x_{d - m,k - 1,0}}{1 \over {{i^{N - m - 1}}}}} \hfill \cr
{{\quad \quad} \le {a_{k,0}}{C_1}{{{n^{k{\alpha _1} + \beta + 1 - a}}} \over {k{\alpha _1} + \beta + 1 - a}} + {a_{k,0}}{C_2}{{{n^{k{\alpha _1} + \beta }}} \over {k{\alpha _1} + \beta }}} \hfill \cr
{\quad \quad = {\rm{O}}({n^{k{\alpha _1} + \beta + 1 - a}}),} \hfill \cr
} $$
where C 1 and C 2 are appropriate constants. So we cannot apply (3.19). However, applying (3.3), (3.4), and Lemma A.1, we obtain
 $$\matrix{
{{{X(n,\,d,\,k,\,0)} \over {{V_n}}}} & = & {{{Z(n,\,d,\,k,\,0)} \over {c(n,\,k,\,0){V_n}}}} \hfill \cr
{} & = & {{{M(n,\,d,\,k,\,0) + A(n,\,d,\,k,\,0)} \over {c(n,\,k,\,0){V_n}}}} \hfill \cr
{} & = & {{{{\rm{O}}({n^{k{\alpha _1} + \beta + 1 - a}})} \over {{n^{k{\alpha _1} + \beta }}pn}}} \hfill \cr
{} & = & {{\rm{O}}({n^{ - a}})} \hfill \cr
{} & \to & 0 \hfill \cr
{} & = & {{x_{d,k,0}}\quad {\rm{almost\,surely\,as\,}}n \to \infty {\rm{.}}} \hfill \cr
} $$
Step (e). Consider the case in which w 1 = 0 and w 2 = l, l > 1. These vertices were always peripheral in the interactions and never the centre. In this case 1 ≤ d ≤ l, where d denotes the degree of vertices. Suppose that the statement holds for all peripheral weights less than l,for central weight zero, and for all possible degrees. We can see that at least one of the coefficients x d−1,0,l−1, x d,0,l−1 is positive. As before, from (3.6) we obtain
 $$\matrix{
{A(n,d,0,l) \sim \sum\limits_{i = 2}^n {a_{0,l}}{i^{l{\alpha _2} + \beta }}[{x_{d,0,l - 1}}p(l - 1)({{N - 2} \over {N - 1}}pr + (1 - p)q)} \hfill \cr
{{\quad \quad \quad \quad \quad \quad \rm{ }} + {x_{d - 1,0,l - 1}}(N - 1)(p(1 - r) + (1 - p)(1 - q))]} \hfill \cr
{{\quad \quad \rm{ }} \sim {a_{0,l}}{{{n^{l{\alpha _2} + \beta + 1}}} \over {l{\alpha _2} + \beta + 1}}[{x_{d,0,l - 1}}p(l - 1)({{N - 2} \over {N - 1}}pr + (1 - p)q)} \hfill \cr
{{\quad \quad \quad \quad \quad \quad \quad \rm{ }} + {x_{d - 1,0,l - 1}}(N - 1)(p(1 - r) + (1 - p)(1 - q))]} \hfill \cr
{\quad \quad \quad \quad {\rm{ }} \to \infty \quad {\rm{almost\,surely\,as\,}}n \to \infty {\rm{.}}} \hfill \cr
} $$
Applying (3.7), we have
 $$B(n,d,0,l) = {\rm{O}}({n^{2(l{\alpha _2} + \beta ) + 1}}),$$
so
 $$B{(n,d,0,l)^{1/2}}\log B(n,d,0,l) = {\rm{O}}(A(n,d,0,l)).$$
Again using Lemma A.1, we see that
 $$Z(n,d,0,l) \sim A(n,d,0,l)$$
almost surely on the event {A(n, d, 0, l) → ∞} as n → ∞. From the above formulae we obtain
 $$\matrix{
{{{X(n,\,d,\,0,\,l)} \over {{V_n}}}} & = & {{{Z(n,\,d,\,0,\,l)} \over {c(n,\,0,\,l){V_n}}}} \hfill \cr
{} & \sim & {{{A(n,\,d,\,0,\,l)} \over {c(n,\,0,\,l){V_n}}}} \hfill \cr
{} & \sim & {{1 \over {l{\alpha _2} + \beta + 1}}[{\alpha _2}(l - 1){x_{d,0,l - 1}} + {\beta _2}{x_{d - 1,0,l - 1}}]} \hfill \cr
{} & = & {{x_{d,0,l}}} \hfill \cr
{} & > & 0, \hfill \cr
} $$
because at least one of the coefficients x d−1,0,l−1, x d,0,l−1 is positive. If d < 1or d > l then X(n, d, 0, l) ≡ 0.
Step (f). Finally, in the last part of our proof we consider the case in which w 1 = k > 0 and w 2 = l > 0. These vertices were centre k times and peripheral l times in the interactions. Here N − 1 ≤ d ≤ k(N − 1) + l. Suppose that the statement holds for any vertex if either its central weight is less than k and its peripheral weight is not greater than l or its central weight is not greater than k and its peripheral weight is less than l. Assume that at least one of the coefficients x d−1,k−1,l, x d,k,l−1, x d−1,k,l−1, x d,k−1,l, x d−(N−1),k−1,l is positive. From (3.6) and using the induction hypothesis, we obtain
 $$\matrix{
{A(n,d,k,l) \sim \sum\limits_{i = 2}^n {a_{k,l}}{i^{k{\alpha _1} + l{\alpha _2} + \beta }}} \hfill \cr
{{\quad \quad \quad \quad \rm{ }} \times [{x_{d - 1,k - 1,l}}(k - 1){p^2}r + {x_{d - 1,k,l - 1}}(N - 1)(p(1 - r) + (1 - p)(1 - q))} \hfill \cr
{{\quad \quad \quad \quad \quad \rm{ }} + {x_{d,k - 1,l}}(k - 1)p(1 - p)q + {x_{d,k,l - 1}}(l - 1)p(pr{{N - 2} \over {N - 1}} + (1 - p)q)} \hfill \cr
{{\quad \quad \quad \quad \quad \rm{ }} + {x_{d - (N - 1),k - 1,l}}(1 - p)(1 - q)]} \hfill \cr
{{\quad \quad \rm{ }} \sim {a_{k,l}}{{{n^{k{\alpha _1} + l{\alpha _2} + \beta + 1}}} \over {k{\alpha _1} + l{\alpha _2} + \beta + 1}}} \hfill \cr
{\quad \quad \quad {\kern 1pt} {\rm{ }} \times [{x_{d - 1,k - 1,l}}(k - 1){p^2}r + {x_{d - 1,k,l - 1}}(N - 1)(p(1 - r) + (1 - p)(1 - q))} \hfill \cr
{{\quad \quad \quad \quad \rm{ }} + {x_{d,k - 1,l}}(k - 1)p(1 - p)q + {x_{d,k,l - 1}}(l - 1)p(pr{{N - 2} \over {N - 1}} + (1 - p)q)} \hfill \cr
{{\quad \quad \quad \quad \rm{ }} + {x_{d - (N - 1),k - 1,l}}(1 - p)(1 - q)]} \hfill \cr
{{\quad \quad \rm{ }} \to \infty \quad {\rm{almost\,surely\,as\,}}n \to \infty {\rm{.}}} \hfill \cr
} $$
Applying (3.7), we obtain
 $$B({n,d,k,l}) = {\rm{O}}( {{n^{2(k{\alpha _1} + l{\alpha _2} + \beta)+1}}}),$$
so
 $$B{(n,d,k,l)^{1/2}}\log B(n,d,k,l) = {\rm{O}}(A(n,d,k,l)).$$
Using Lemma A.1, we obtain
 $$Z(n,d,k,l) \sim A(n,d,k,l)$$
almost surely on the event {A(n, d, k, l) → ∞} as n → ∞. Therefore, from (3.3), (3.4), (3.21), and (3.22),
 $$\matrix{
{{{X(n,\,d,\,k,\,l)} \over {{V_n}}}} & = & {{{Z(n,\,d,\,k,\,l)} \over {c(n,\,k,\,l){V_n}}}} \hfill \cr
{} & \sim & {{{A(n,\,d,\,k,\,l)} \over {c(n,\,k,\,l){V_n}}}} \hfill \cr
{} & \sim & {{1 \over {k{\alpha _1} + l{\alpha _2} + \beta + 1}}[{\alpha _{11}}(k - 1){x_{d - 1,k - 1,l}} + {\alpha _{12}}(k - 1){x_{d,k - 1,l}}} \hfill \cr
{} & {} & {{\quad \quad \quad \quad \rm{ }} + {\alpha _2}(l - 1){x_{d,k,l - 1}} + {\beta _1}{x_{d - (N - 1),k - 1,l}} + {\beta _2}{x_{d - 1,k,l - 1}}]} \hfill \cr
{} & = & {{x_{d,k,l}}} \hfill \cr
{} & > & {0,} \hfill \cr
} $$
because of the assumptions. Otherwise, if d < N − 1or d > k(N − 1) + l then X(n, d, k, l) ≡ 0. So in this case (3.2) holds for all k, l ∈ ℕ.
The remaining case is when the coefficients x d−1,k−1,l, x d,k,l−1, x d−1,k,l−1, x d,k−1,l, and x d−(N−1),k−1,l are all equal to zero. From (3.6) and using the induction hypothesis, we obtain
A(n, d, k, l)
 $$\matrix{
{ \sim \sum\limits_{i = 2}^n {a_{k,l}}{i^{k{\alpha _1} + l{\alpha _2} + \beta }}({\rm{O}}({1 \over {{i^a}}}) + \sum\limits_{m = 2}^{N - 2} X(i - 1,d - m,k - 1,l)} \hfill \cr
{{\quad \quad \quad \quad \quad \quad \quad \quad \quad \quad \rm{ }} \times ((1 - p)(1 - q){{\left( {\matrix{
{d - m} \cr
{N - m - 1} \cr
} } \right)(N - 1)!} \over {m!}}{1 \over {{{(pi)}^{N - m}}}}))} \hfill \cr
{ \sim {C_1}\sum\limits_{i = 2}^n {a_{k,l}}{i^{k{\alpha _1} + l{\alpha _2} + \beta - a}} + {C_2}\sum\limits_{i = 2}^n \sum\limits_{m = 2}^{N - 2} {a_{k,l}}{i^{k{\alpha _1} + l{\alpha _2} + \beta }}{x_{d - m,k - 1,l}}{1 \over {{i^{N - m - 1}}}}} \hfill \cr
{ \le {a_{k,l}}{C_1}{{{n^{k{\alpha _1} + l{\alpha _2} + \beta + 1 - a}}} \over {k{\alpha _1} + l{\alpha _2} + \beta + 1 - a}} + {a_{k,l}}{C_2}{{{n^{k{\alpha _1} + l{\alpha _2} + \beta }}} \over {k{\alpha _1} + l{\alpha _2} + \beta }}} \hfill \cr
{ = {\rm{O}}({n^{k{\alpha _1} + l{\alpha _2} + \beta + 1 - a}}),} \hfill \cr
} $$
where C 1 and C 2 are appropriate constants. Using (3.3), (3.4), and Lemma A.1, we obtain
 $$\matrix{
{{{X(n,\,d,\,k,\,l)} \over {{V_n}}}} & = & {{{Z(n,\,d,\,k,\,l)} \over {c(n,\,k,\,l){V_n}}}} \hfill \cr
{} & = & {{{M(n,\,d,\,k,\,l) + A(n,\,d,\,k,\,l)} \over {c(n,\,k,\,l){V_n}}}} \hfill \cr
{} & = & {{{{\rm{O}}({n^{k{\alpha _1} + l{\alpha _2} + \beta + 1 - a}})} \over {{n^{k{\alpha _1} + l{\alpha _2} + \beta }}pn}}} \hfill \cr
{} & = & {{\rm{O}}({n^{ - a}})} \hfill \cr
{} & \to & 0 \hfill \cr
{} & = & {{x_{d,k,l}}} \hfill \cr
} $$
almost surely as n → ∞.
3.3. Scale-free property of the weights
Lemma 3.2. Let p > 0 and define
 $${x_{{w_1},{w_2}}} = {x_{1,{w_1},{w_2}}} + {x_{2,{w_1},{w_2}}} + \ldots + {x_{(N - 1){w_1} + {w_2},{w_1},{w_2}}}$$
for w 1 ≥ 0, w 2 ≥ 0, and w 1 + w 2 ≥ 1. Then x w 1,w 2 (1 ≤ w 1 + w 2) are positive numbers satisfying the recurrence relation
 $$\matrix{
{{x_{1,0}}} & = & {{{1 - r} \over {{\alpha _1} + \beta + 1}},} \cr
{{x_{0,1}}} & = & {{r \over {{\alpha _2} + \beta + 1}},} \cr
{{x_{{w_1},{w_2}}}} & = & {{{({\alpha _1}({w_1} - 1) + {\beta _1}){x_{{w_1} - 1,{w_2}}} + ({\alpha _2}({w_2} - 1) + {\beta _2}){x_{{w_1},{w_2} - 1}}} \over {{\alpha _1}{w_1} + {\alpha _2}{w_2} + \beta + 1}}} \cr
} $$
if 1 < w 1 + w 2.
Proof. From the recurrence formula (3.2), we have
 $$\matrix{
{{x_{{w_1},{w_2}}}} & = & {\sum\limits_{d = 1}^{(N - 1){w_1} + {w_2}} {x_{d,{w_1},{w_2}}}} \hfill \cr
{} & = & {\sum\limits_d {x_{d,{w_1},{w_2}}}} \hfill \cr
{} & = & {{1 \over {{\alpha _1}{w_1} + {\alpha _2}{w_2} + \beta + 1}}} \hfill \cr
{} & {} & {{\rm{ }} \times [{\alpha _{11}}({w_1} - 1)\sum\limits_d {x_{d - 1,{w_1} - 1,{w_2}}} + {\alpha _{12}}({w_1} - 1)\sum\limits_d {x_{d,{w_1} - 1,{w_2}}}} \hfill \cr
{} & {} & {{\quad \rm{ }} + {\alpha _2}({w_2} - 1)\sum\limits_d {x_{d,{w_1},{w_2} - 1}} + {\beta _1}\sum\limits_d {x_{d - (N - 1),{w_1} - 1,{w_2}}}} \hfill \cr
{} & {} & {{\quad \rm{ }} + {\beta _2}\sum\limits_d {x_{d - 1,{w_1},{w_2} - 1}}]} \hfill \cr
{} & = & {{{({\alpha _1}({w_1} - 1) + {\beta _1}){x_{{w_1} - 1,{w_2}}} + ({\alpha _2}({w_2} - 1) + {\beta _2}){x_{{w_1},{w_2} - 1}}} \over {{\alpha _1}{w_1} + {\alpha _2}{w_2} + \beta + 1}}} \hfill \cr
} $$
where we used the fact that x d,w 1,w 2 = 0 if d ∉ {1, 2, …, (N − 1)w 1 + w 2}.
Theorem 3.2. Assume that 0 < p < 1, 0 < q < 1, and 0 < r < 1. Let w 1 be fixed. Then, as w 2 → ∞,
 $${x_{{w_1},{w_2}}} \sim C({w_1})w_2^{ - (1 + ({\beta _1} + 1)/{\alpha _2})},$$
where
 $$C({w_1}) = {r \over {{\alpha _2}}}{1 \over {{w_1}!}}{{{\it{\Gamma}} ({w_1} + {\beta _1}/{\alpha _1})} \over {{\it{\Gamma}} ({\beta _1}/{\alpha _1})}}{{{\it{\Gamma}} (1 + (\beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}.$$
Here Γ denotes the gamma function. A similar result holds when w 2 is fixed and w 1 → ∞.
Proof. Throughout the proof, we shall use the following two facts for the gamma function:
 $$\sum\limits_{i = 0}^n {{{\it{\Gamma}} (i + a)} \over {{\it{\Gamma}} (i + b)}} = {1 \over {a - b + 1}}[{{{\it{\Gamma}} (n + a + 1)} \over {{\it{\Gamma}} (n + b)}} - {{{\it{\Gamma}} (a)} \over {{\it{\Gamma}} (b - 1)}}]$$
(see [Reference Prudnikov, Brychkov and Marichev24]); applying Stirling’s formula, we have
 $${{{\it{\Gamma}} (n + a)} \over {{\it{\Gamma}} (n + b)}} \sim {n^{ - (b - a)}}.$$
We shall use mathematical induction. As we have to handle the two-dimensional array x w 1,w 2 satisfying (3.23), our formulae will be quite long. Therefore, we divide the induction procedure into several steps.
Step (i): consider the cases in which one of the weights is equal to 0. Let w 1 = 0. Then, by Lemma 3.2, we obtain
 $$\matrix{
{{x_{0,1}}} & = & {{r \over {{\alpha _2} + \beta + 1}} > 0,} \hfill \cr
{{x_{0,l}}} & = & {{1 \over {l{\alpha _2} + \beta + 1}}((l - 1){\alpha _2} + {\beta _2}){x_{0,l - 1}},\quad \quad l > 1.} \hfill \cr
} $$
Using (3.28), we have
 $$\matrix{
{{x_{0,l}}} & = & {{x_{0,1}}\prod\limits_{j = 2}^l {{{\alpha _2}(j - 1) + {\beta _2}} \over {{\alpha _2}j + \beta + 1}}} \hfill \cr
{} & = & {{r \over {{\alpha _2} + \beta + 1}}{{{\alpha _2} + {\beta _2}} \over {2{\alpha _2} + \beta + 1}}{{2{\alpha _2} + {\beta _2}} \over {3{\alpha _2} + \beta + 1}} \cdots {{(l - 1){\alpha _2} + {\beta _2}} \over {l{\alpha _2} + \beta + 1}}} \hfill \cr
{} & = & {{r \over {l{\alpha _2} + \beta + 1}}\prod\limits_{j = 1}^{l - 1} {{{\beta _2}/{\alpha _2} + j} \over {(\beta + 1)/{\alpha _2} + j}}} \hfill \cr
{} & = & {{r \over {l{\alpha _2} + \beta + 1}}{{{\it{\Gamma}} (1 + (\beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + (\beta + 1)/{\alpha _2})}}} \hfill \cr
{} & = & {{r \over {{\alpha _2}}}{{{\it{\Gamma}} (1 + (\beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}}} \hfill \cr
{} & = & {C(0){{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}}.} \hfill \cr
} $$
Applying (3.27), we obtain our statement for w 1 = 0:
 $${x_{0,l}} = C(0){{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}} \sim C(0){l^{ - (1 + ({\beta _1} + 1)/{\alpha _2})}}\quad {\rm{as\,l}} \to \infty {\rm{.}}$$
When w 2 = 0, we can similarly obtain
 $${x_{1,0}} = {{1 - r} \over {{\alpha _1} + \beta + 1}} > 0,$$
 $${x_{k,0}} = {1 \over {k{\alpha _1} + \beta + 1}}((k - 1){\alpha _1} + {\beta _1}){x_{k - 1,0}},\quad \quad k > 1,$$
and
 $${x_{k,0}} \sim {C_0}{k^{ - (1 + ({\beta _2} + 1)/{\alpha _1})}}\quad {\rm{as\,{\it{k}}}} \to \infty {\rm{,}}$$
where
 $${C_0} = {{(1 - r){\it{\Gamma}} (1 + (\beta + 1)/{\alpha _1})} \over {{\alpha _1}{\it{\Gamma}} (1 + {\beta _1}/{\alpha _1})}}.$$
Step (ii): consider the case in which w 1 = 1. Analysing this particular case is very useful in order to find the general formulae which will be given in the next stage. We have already seen that statement (3.24) holds if w 1 = 0 or w 2 = 0 (cf. (3.30) and (3.31)). Applying (3.23) several times, we obtain
 $$\matrix{
{x_{1,l}} & = & {{{\beta _1}{x_{0,l}} + ({\alpha _2}(l - 1) + {\beta _2}){x_{1,l - 1}}} \over {{\alpha _1} + {\alpha _2}l + \beta + 1}} \hfill \cr
{} & = & \sum\limits_{i = 1}^l {{{\beta _1}\mathop \prod \nolimits_{j = i}^{l - 1} (j{\alpha _2} + {\beta _2})} \over {\mathop \prod \nolimits_{j = i}^l ({\alpha _1} + j{\alpha _2} + \beta + 1)}}{x_{0,i}} + {{{\beta _2}\mathop \prod \nolimits_{j = i}^{l - 1} (j{\alpha _2} + \beta )} \over {\mathop \prod \nolimits_{j = i}^l ({\alpha _1} + j{\alpha _2} + \beta + 1)}}{x_{1,0}} \hfill \cr
{} & = & {\sum\limits_{i = 1}^l b_{0,i}^{(l)}{x_{0,i}} + b_{1,0}^{(l)}{x_{1,0}},} \hfill \cr
} $$
where
 $$b_{0,i}^{(l)} = {{{\beta _1}} \over {{\alpha _2}}}{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + 1 + ({\alpha _1} + \beta + 1)/{\alpha _2})}}{{{\it{\Gamma}} (i + ({\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (i + {\beta _2}/{\alpha _2})}},\quad \quad 1 \le i \le l,$$
and
 $$b_{1,0}^{(l)} = {{{\beta _2}} \over {{\alpha _2}}}{{{\it{\Gamma}} (1 + ({\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + 1 + ({\alpha _1} + \beta + 1)/{\alpha _2})}}.$$
Let
 $$D(1) = {{C(0){\beta _1}} \over {{\alpha _2}}}{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + 1 + ({\alpha _1} + \beta + 1)/{\alpha _2})}},$$
where C(0) is from (3.25).
Now, using (3.26), (3.27), and (3.29) for the first term in (3.34), we obtain
 $$\matrix{
{\sum\limits_{i = 1}^l b_{0,i}^{(l)}{x_{0,i}}} & = & {D(1)\sum\limits_{i = 1}^l {{{\it{\Gamma}} (i + ({\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (i + ({\alpha _2} + \beta + 1)/{\alpha _2})}}} \hfill \cr
{} & = & {D(1)\sum\limits_{t = 0}^{l - 1} {{{\it{\Gamma}} (t + 1 + ({\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (t + 1 + ({\alpha _2} + \beta + 1)/{\alpha _2})}}} \hfill \cr
{} & = & {{{D(1)} \over {({\alpha _1} + \beta + 1)/{\alpha _2} - ({\alpha _2} + \beta + 1)/{\alpha _2} + 1}}} \hfill \cr
{} & {} & {{\rm{ }} \times [{{{\it{\Gamma}} (l + 1 + ({\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}} - {{{\it{\Gamma}} (1 + ({\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (({\alpha _2} + \beta + 1)/{\alpha _2})}}]} \hfill \cr
{} & = & {{r \over {{\alpha _2}}}{{{\beta _1}} \over {{\alpha _1}}}{{{\it{\Gamma}} (1 + (\beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}} \hfill \cr
{} & {} & {{\rm{ }} \times [{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}}} \hfill \cr
{} & {} & {{\kern 1pt} {\rm{ }}{\kern 1pt} - {{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + 1 + ({\alpha _1} + \beta + 1)/{\alpha _2})}}{{{\it{\Gamma}} (1 + ({\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (({\alpha _2} + \beta + 1)/{\alpha _2})}}]} \hfill \cr
{} & \sim & {{r \over {{\alpha _2}}}{{{\beta _1}} \over {{\alpha _1}}}{{{\it{\Gamma}} (1 + (\beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}}} \hfill \cr
{} & = & {C(1){{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}}} \hfill \cr
} $$
as l → ∞. Above we neglected the lower-order term. Now, using (3.27), we have
 $$\sum\limits_{i = 1}^l b_{0,i}^{(l)}{x_{0,i}} \sim C(1){l^{ - (1 + ({\beta _1} + 1)/{\alpha _2})}}\quad {\rm{as\,{\it{l}}}} \to \infty {\rm{.}}$$
Now, turning to the second term in (3.34). Applying (3.27) to (3.35), we obtain
 $$b_{1,0}^{(l)} \sim {{{\beta _2}} \over {{\alpha _2}}}{{{\it{\Gamma}} (1 + ({\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}{l^{ - (1 + ({\alpha _1} + {\beta _1} + 1)/{\alpha _2})}}\quad {\rm{as\,{\it{l}}}} \to \infty {\rm{.}}$$
Now, substituting (3.31), (3.36), and (3.37) into (3.34), we obtain the statement for w 1 = 1:
 $$\matrix{
{{x_{1,l}} \sim C(1){l^{ - (1 + ({\beta _1} + 1)/{\alpha _2})}} + {{{\beta _2}} \over {{\alpha _2}}}{{{\it{\Gamma}} (1 + ({\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}{l^{ - (1 + ({\alpha _1} + \beta + 1)/{\alpha _2})}}{{1 - r} \over {{\alpha _1} + \beta + 1}}} \cr
{ \sim C(1){l^{ - (1 + ({\beta _1} + 1)/{\alpha _2})}}\quad {\rm{as\,{\it{l}}}} \to \infty {\rm{. }}} \cr
} $$
Step (iii): consider the general induction step. Suppose that the statement holds for all central weights less than w 1. That is, the following holds as l → ∞:
 $${x_{k,l}} \sim C(k){{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}} \sim C(k){l^{ - (1 + ({\beta _1} + 1)/{\alpha _2})}},\quad \quad 0 \le k \le {w_1} - 1.$$
Then, from (3.23), we obtain
 $$\matrix{
{{x_{{w_1},l}}} & = & {{({w_1} - 1){\alpha _1} + {\beta _1}} \over {{\alpha _2}}}\sum\limits_{i = 1}^l {{\mathop \prod \nolimits_{j = i}^{l - 1} (j + {\beta _2}/{\alpha _2})} \over {\mathop \prod \nolimits_{j = i}^l (j + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})}}{x_{{w_1} - 1,i}} \cr
{} & {} & + {{{\beta _2}} \over {{\alpha _2}}}{{\mathop \prod \nolimits_{j = 1}^{l - 1} (j + {\beta _2}/{\alpha _2})} \over {\mathop \prod \nolimits_{j = 1}^l (j + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})}}{x_{{w_1},0}} \cr
{} & = & {\sum\limits_{i = 1}^l b_{{w_1} - 1,i}^{(l)}{x_{{w_1} - 1,i}} + b_{{w_1},0}^{(l)}{x_{{w_1},0}},}
} $$
where
 $$\matrix{
{b_{{w_1} - 1,i}^{(l)} = {{({w_1} - 1){\alpha _1} + {\beta _1}} \over {{\alpha _2}}}{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + 1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})}}} \cr
{\quad \quad \quad \quad \quad {\rm{ }}{\kern 1pt} \times {{{\it{\Gamma}} (i + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (i + {\beta _2}/{\alpha _2})}},\quad \quad 1 \le i \le l,} \cr
} $$
and
 $$b_{{w_1},0}^{(l)} = {{{\beta _2}} \over {{\alpha _2}}}{{{\it{\Gamma}} (1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + 1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})}}.$$
Let
 $$D({w_1}) = {{C({w_1} - 1)(({w_1} - 1){\alpha _1} + {\beta _1})} \over {{\alpha _2}}}{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + 1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})}},$$
where C(w 1 − 1) is given in (3.25).
Using (3.26), (3.27), (3.38), and (3.41) for the first term in (3.39), we obtain
 $$\matrix{
{\sum\limits_{i = 1}^l b_{{w_1} - 1,i}^{(l)}{x_{{w_1} - 1,i}}} & \sim & {D({w_1})\sum\limits_{i = 1}^l {{{\it{\Gamma}} (i + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (i + ({\alpha _2} + \beta + 1)/{\alpha _2})}}} \hfill \cr
{} & = & {D({w_1})\sum\limits_{t = 0}^{l - 1} {{{\it{\Gamma}} (t + 1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (t + 1 + ({\alpha _2} + \beta + 1)/{\alpha _2})}}} \hfill \cr
{} & = & {{{D({w_1})} \over {({w_1}{\alpha _1} + \beta + 1)/{\alpha _2} - ({\alpha _2} + \beta + 1)/{\alpha _2} + 1}}} \hfill \cr
{} & {} & { \times [{{{\it{\Gamma}} (l + 1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}} - {{{\it{\Gamma}} (1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (({\alpha _2} + \beta + 1)/{\alpha _2})}}]} \hfill \cr
{} & = & {{r \over {{\alpha _2}}}{1 \over {{w_1}!}}{{{\it{\Gamma}} ({w_1} + {\beta _1}/{\alpha _1})} \over {{\it{\Gamma}} ({\beta _1}/{\alpha _1})}}{{{\it{\Gamma}} (1 + (\beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}} \hfill \cr
{} & {} & {{\kern 1pt} \times [{{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}}} \hfill \cr
{} & {} & {\quad - {{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + 1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})}}{{{\it{\Gamma}} (1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (({\alpha _2} + \beta + 1)/{\alpha _2})}}]} \hfill \cr
{} & \sim & {C({w_1}){{{\it{\Gamma}} (l + {\beta _2}/{\alpha _2})} \over {{\it{\Gamma}} (l + ({\alpha _2} + \beta + 1)/{\alpha _2})}}\quad {\rm{as\, {\it{l}}}} \to \infty {\rm{.}}} \hfill \cr
{} & {} & {} \hfill \cr
} $$
Above we neglected the lower-order term. Using (3.27), we have
 $$\sum\limits_{i = 1}^l b_{{w_1} - 1,i}^{(l)}{x_{{w_1} - 1,i}} \sim C({w_1}){l^{ - (1 + ({\beta _1} + 1)/{\alpha _2})}}\quad {\rm{as\,{\it{l}}}} \to \infty {\rm{.}}$$
Applying (3.27) to (3.40), we obtain
 $$b_{{w_1},0}^{(l)} \sim {{{\beta _2}} \over {{\alpha _2}}}{{{\it{\Gamma}} (1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}{l^{ - (1 + ({w_1}{\alpha _1} + {\beta _1} + 1)/{\alpha _2})}}\quad {\rm{as\,{\it{l}}}} \to \infty {\rm{.}}$$
Now substitute (3.33), (3.42), and (3.43) into (3.39) to obtain our statement:
 $$\matrix{
{{x_{{w_1},l}}} \hfill & { \sim C({w_1}){l^{ - (1 + {\beta _1} + 1{\alpha _2})}}} \hfill \cr
{} \hfill & {\quad + {{{\beta _2}} \over {{\alpha _2}}}{{{\it{\Gamma}} (1 + ({w_1}{\alpha _1} + \beta + 1)/{\alpha _2})} \over {{\it{\Gamma}} (1 + {\beta _2}/{\alpha _2})}}{l^{ - (1 + {w_1}{\alpha _1} + {\beta _1} + 1{\alpha _2})}}{C_0}w_1^{ - (1 + {\beta _2} + 1{\alpha _1})}} \hfill \cr
{} \hfill & { \sim C({w_1}){l^{ - (1 + {\beta _1} + 1{\alpha _2})}}\quad {\rm{as}}\,l \to \infty {\rm{.}}} \hfill \cr
} $$
Appendix A
We use the following results on discrete-time submartingales. Let {Z n, ℱ n} be a submartin-gale. Its Doob–Meyer decomposition is Z n = M n + A n, where {M n, ℱ n} is a martingale and {A n, ℱ n} is an increasing predictable process. Here, up to an additive constant,
 $${A_n} = {\mathbb E}{Z_1} + \sum\limits_{i = 2}^n ({\mathbb E}({Z_i}|{{\cal F}_{i - 1}}) - {Z_{i - 1}}).$$
Now,  $$\{ M_n^2,{{\cal F}_n}\} $$ is again a submartingale. Let
 $$M_n^2 = {Y_n} + {B_n}$$
be the Doob–Meyer decomposition of  $$M_n^2$$. Here, up to an additive constant,
 $${B_n} = \sum\limits_{i = 2}^n {{\mathbb D}^2}({Z_i}|{{\cal F}_{i - 1}}) = \sum\limits_{i = 2}^n {\mathbb E}\{ ({Z_i} - {\mathbb E}({Z_i}|{{\cal F}_{i - 1}}{))^2}|{{\cal F}_{i - 1}}\} .$$
Lemma A.1. Let M 1 = 0. On the set {B ∞ < ∞} the martingale M n almost surely converges to a finite limit. Moreover, 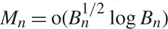 $${M_n} = {\rm{o}}(B_n^{1/2}\log {B_n})$$ almost surely on the set {B n → ∞}.
Let {Z n, ℱ n} be a square integrable nonnegative submartingale. If 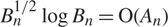 $$B_n^{1/2}\log {B_n} = {\rm{O}}({A_n})$$ then Z n ~ A n as n → ∞ almost surely on the set {A n → ∞}.
The first part of the lemma is contained in Propositions VII-2-3 and VII-2-4 of [Reference Neveu22]. The second part is a consequence of the first part and it can be found in Proposition 2.3 of [Reference Backhausz1].
Acknowledgements
The authors are grateful to the referee and the editor for careful readings of the paper and for valuable suggestions.