




No CrossRef data available.
FURTHER RESULTS INVOLVING THE MIT ORDER AND THE IMIT CLASS
Published online by Cambridge University Press: 22 June 2005
Abstract
The purpose of this article is to study several preservation properties of the mean inactivity time order under the reliability operations of convolution, mixture, and shock models. In that context, the increasing mean inactivity time class of lifetime distributions is characterized by means of right spread order and increasing convex order. Some applications in reliability theory are described. Finally, a new test of such a class is discussed.
Information
- Type
- Research Article
- Information
- Probability in the Engineering and Informational Sciences , Volume 19 , Issue 3 , July 2005 , pp. 377 - 395
- Copyright
- © 2005 Cambridge University Press
1. INTRODUCTION AND MOTIVATION
Various concepts of stochastic comparison between random variables have been defined and studied in the literature, since they are useful in modeling for reliability and economics applications and as mathematical tools for proving important results in applied probability (see Shaked and Shanthikumar [29] for an exhaustive monograph on this topic).
Two such well-known stochastic orders are the increasing convex order and the mean residual life order, whose definitions are recalled here. Let X and Y be two random variables having distribution functions F and G, respectively, and denote by F = 1 − F and G = 1 − G their respective survival functions.
The variable X is said to be smaller than Y in the increasing convex order (denoted by X ≤ICX Y) if and only if

Let us now denote by Xt = [X − t|X > t], with t ∈ (0,lX) and lX = sup{t : F(t) < 1} the residual life of the random variable X (i.e., the variable having Ft(s) = P[X − t ≤ s|X > t] as its distribution function) (Barlow and Proschan [6]). Similarly, denote Yt = [Y − t|T > t], and lY.
The random variable X is said to be smaller than Y in the mean residual life order (denoted by X ≤MRL Y) if they have finite means and E [Xt] ≤ E [Yt], for all t ∈ (0,lX) ∩ (0,lY).
The mean residual life order can be characterized by way of the increasing convex order observing that [29]

and

for all t ∈ (0,lX) ∩ (0,lY).
When X and Y represent lifetimes of systems or components (i.e., X and Y are nonnegative), the order ≤MRL is more informative than the order ≤ICX, since it compares the underlying systems at any time t in contrast to the global comparison offered by the order ≤ICX. However, it is reasonable to presume that in many realistic situations, the random variables are not necessarily related only to the future, but they can also refer to the past (see Di Crescenzo and Longobardi [11], Nanda, Singh, Misra, and Paul [22], and Kayid and Ahmad [17]). In fact, in many reliability problems, it is of interest to consider variables of the kind X(t) = [t − X|X ≤ t], for fixed t > 0, having distribution function F(t)(s) = P[t − X ≤ s|X ≤ t] and known in literature as the inactivity time (Ruiz and Navarro [28], Chandra and Roy [10], and Li and Lu [19]).
To compare inactivity times, another ordering has come to use in reliability and life testing problems (see [17,22]). Its definition is as follows:
Given two nonnegative random variables X and Y, we say that X is mean inactivity time smaller than Y (denoted by X ≤MIT Y) if and only if E [X(t)] ≥ E [Y(t)] for all t ≥ 0; that is, if and only if

Another condition equivalent to (1.2) is

For the ≤MIT order, there holds a characterization similar to the one in (1.1) but that involves the increasing concave order instead of the increasing convex order [17]. For the definition of the increasing concave order, see Shaked and Shanthikumar [29].
On the other hand, many nonparametric classes of distributions have been defined in the literature to describe reliability properties of random lifetimes (cf. Barlow and Proschan [6] and Ross [27]). In particular, the increasing mean inactivity time (IMIT) class of life distributions, defined as the class where E [X(t)] is increasing for all nonnegative t, has been studied by many researchers in the recent past (cf. Chandra and Roy [10], Nanda et al. [22], and Kayid and Ahmad [17]).
We recall here two equivalent conditions for increasing mean inactivity time: The nonnegative random variable X with distribution function F is said to have the IMIT property if and only if

or, equivalently, if and only if

Some authors have made efforts to investigate the characterizations of some nonparametric classes by means of various stochastic orders. These characterizations are meaningful because they help in the understanding of the intrinsic meaning of the reliability properties involved. For example, if we let t* = inf{x : F(x) > 0} and t* = sup{x : F(x) < 1}, characterizations are usually of the form (cf. Pellerey and Shaked [24])

where ≥st-ord denotes some stochastic orders and X ∈ A denotes the fact that X satisfies property A.
From the definition of ≤MIT order, it could be thought that the results one can obtain on the new order follow directly from the results on the ≤MRL order and the fact that X ≤MIT Y if and only if − X ≥MRL − Y. However, this is not generally true, since this property cannot be useful when one assumes nonnegativity of X and Y, which is assumed for most of the known results on ≤MRL order. Such equivalence can be applied only in the case that X and Y have a common finitely bounded support [0,l], l ∈ R+, since in that case, we can write it as X ≤MIT Y if and only if l − X ≥MRL l − Y. However, it is our intention, in this article, to consider also the case of unbounded supports (which are more common in real applicative problems). A similar approach applies to the results on the IMIT property (and DMRL property). In fact, for example, it is well known that a nonnegative random variable X is DMRL (decreasing in mean residual life) if and only if X ≥MRL Xt for all t ≥ 0, whereas it is not true that X is IMIT if and only if X ≤MIT X(t) for all t ≥ 0 (as one can verify).
The ≤MIT order and the IMIT class were introduced recently by Nanda et al. [22] and Chandra and Roy [10], respectively, whereas Kayid and Ahmad [17] studied some characterizations and preservation results for this order and introduced a life test for the present class. The purpose of this article is to provide some other preservation and characterization results for the ≤MIT ordering and the IMIT class. The construction of this article is as follows. In Section 2, results on characterizations and preservations under convolution, mixture, and shock models of the MIT order are given. In Section 3, the IMIT class is characterized by means of right spread order and increasing convex order, and the closure of IMIT property under shock models and series systems is studied. Finally, a new test for such a class that does not require density estimation is discussed in Section 4.
Throughout the article, we will use the term increasing in place of nondecreasing, and decreasing in place of nonincreasing. Moreover, it is always assumed in the sequel that the nonnegative random variables X and Y having distribution functions F and G, respectively, will have F = 1 − F and G = 1 − G as their respective survival functions and F−1 and G−1 as their corresponding right continuous inverses (which we assume to exist). All integrals, expectations, and derivatives are implicitly assumed to exist wherever they are given. Also, =st denotes equality in law.
2. CLOSURE PROPERTIES OF THE MIT ORDER
The first result of this section is the characterization of the ≤MIT order in terms of the ≤ICX order.
Theorem 2.1: Let X and Y be two nonnegative random variables. Then X ≤MIT Y if and only if X(t) ≥ICX Y(t) for all t ≥ 0.
Proof: Let F and G denote the distribution functions of X and Y, respectively. Note that X(t) ≥ICX Y(t) if and only if

Recall now that X ≤MIT Y if and only if

and also if and only if

Thus, (2.1) holds when these two inequalities are satisfied.
To prove the assertion in the reversed direction, it suffices to set u = 0 in (2.1). █
On the other hand, useful properties of stochastic orders are their closures with respect to typical reliability operations like convolution, mixture, and shock models (see, e.g., [29]). In the rest of this section we present some results of this kind for the mean inactivity time order.
To state and prove these properties, we first recall the TP2 (totally positive of order 2) concept from Karlin [16]. Let χ and γ be two subsets of the real line. A nonnegative function h defined on χ × γ is said to be TP2 if

whenever x ≤ x′, y ≤ y′ and x,x′ ∈ χ, y,y′ ∈ γ.
We also recall the following lemma, which is essentially due to Joag-Dev, Kochar, and Proschan [15]. For a similar type of results, one may refer to Lynch, Mimmack, and Prochan [20], Fagiuoli and Pellerey [13], and Hu, Kundu, and Nanda [14].
Lemma 2.1: Let ψ(θ,x) be any TP2 function (and not necessarily a survival function) in θ ∈ χ and x ∈ γ, and let Fi(θ) be a distribution function for each i. Further, let

If Fi(θ) is TP2 in i ∈ {1,2} and θ ∈ χ, and if ψ(θ,x) is decreasing in θ for every x, then Hi(x) is TP2 in x ∈ γ and i ∈ {1,2}.
Finally, we recall that a random variable X has a decreasing reversed hazard rate (DRHR) property if and only if [22]

where X ≤ST Y means F(x) ≤ G(x) for all x (see, e.g., [29, Sec.1.A.]).
2.1. Convolution
Here, we show that the ≤MIT order is preserved under convolutions, when appropriate assumptions are satisfied.
Theorem 2.2: Let Θ1, Θ2, and Z be three nonnegative random variables, where Z is independent of both Θ1 and Θ2. If Θ1 ≤MIT Θ2 and if Z has the DRHR property, then Θ1 + Z ≤MIT Θ2 + Z.
Proof: Let FW denote the cumulative distribution function of a general random variable W. For t,v > 0 and i = 1,2, define

Then Φ(i,t) can be rewritten as

where Gt(v) = FZ(t − v) and Gt(v) = FZ(t − v). Note that Gt(v) = FZ(t − v) is TP2 in (t,v) ∈ R2 (since Z is DRHR), whereas Θ1 ≤MIT Θ2 implies that φ(i,v) is TP2 in (i,v) ∈ {1,2} × R+. Moreover, φ(i,v) is increasing in v for every fixed i = 1,2. Therefore, applying Lemma 2.1, we have

or, equivalently, that the ratio

is decreasing in t, and hence the desired result. █
Repeated applications of Theorem 2.1, using the closure property of DRHR under convolution, yields the following result.
Corollary 2.1: Let (Xi,Yi), i = 1,…,m, be independent pairs of nonnegative random variables such that Xi ≤MIT Yi for i = 1,…,m. If Xi, Yi, i = 1,…,m, are all DRHR, then

Recently, Kayid and Ahmad [17] proved Theorem 2.1 and Corollary 2.1 under the stronger assumption of ILR (increasing likelihood ratio) instead of DRHR (a random variable is said to be ILR if it has a logconcave density function).
2.2. Mixture
Consider a family of distribution functions {Hθ, θ ∈ χ}, where χ is a subset of the real line R. Let X(θ) denote a random variable with distribution function Hθ. For any random variable Θ with support in χ and with distribution function Λ, denote by X(Θ) a random variable with distribution function G given by
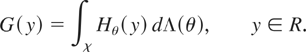
In this case, X(Θ) is called a mixture of the X(θ) with respect to Θ.
Recall that a random variable X with density f is said to be smaller than a random variable Y with density g in the reversed hazard rate order (denoted by X ≤RHR Y) if

[i.e., if the ratio F(t)/G(t) is decreasing in t ∈ (0,lX) ∩ (0,lY)].
Theorem 2.3: Consider a family of distribution functions {Hθ, θ ∈ χ} as above. Let Θ1 and Θ2 be two random variables with respective distribution functions Λ1 and Λ2. Let Y1 and Y2 be two random variables with Yi =st X(Θi), i = 1,2. If

and if

then

Proof: Let G1 and G2 be the distribution functions of Y1 and Y2, respectively, and denote

Note that (2.2) implies that φθ(t) is TP2 in θ ∈ χ and t ∈ R+. Also, since ≤MIT order implies the ≤ICV order [17], from (2.2) we get that φθ(t) is decreasing in θ ∈ χ for each fixed t ∈ R+. Assumption (2.3) means that Λi(θ), as a function of θ and of i ∈ {1,2}, is TP2. On the other hand,

Applying Lemma 2.1 to (2.4) yields the desired result. █
2.3. Poisson Shock Models
Shock models are of great interest in the context of reliability theory. The class of shock models arises in reliability theory when a system or an item is subjected to random shocks over time. The system is assumed to have an ability to withstand a random number of these shocks, and it is commonly assumed that the number of shocks and the interarrival times of shocks are independent. If we denote by N the number of shocks survived by the system, and by Xj the random interarrival time between the (j − 1)st and jth shocks, then the lifetime T of the system is given by

. Therefore, shock models are particular cases of random sums. In particular, if the interarrivals are assumed to be independent and exponentially distributed (with common parameter λ), then the distribution function of T can be written

where Pk = P[N ≤ k] for all k ∈ N (and P0 = 1).
Shock models of this kind, called Poisson shock models, have been studied extensively in the literature. Some recent references are by Alzaid, Kim, and Proschan [5], Pellerey [23], Fagiuoli and Pellerey [13], Shaked and Wong [30], and Belzunce, Ortega, and Ruiz [8], among others.
Consider now two devices subjected to shocks occurring as events of a Poisson counting process, as above, and let Pk and Qk be their probability of surviving the first k shocks, respectively. Let T1 and T2 denote the two lifetimes and let

be their respective cumulative functions. In the following, we give conditions on Pk and Qk such that the lifetimes T1 and T2 are ordered according to the mean inactivity time order.
Theorem 2.4: Let T1 and T2 have distribution functions defined as in (2.6). If the ratio

is decreasing in k ≥ 1, then T1 ≤MIT T2.
Proof: We need to prove that

or, equivalently, that

where

Observe that, by assumption, Φ(i,k) is TP2 in (i,k). Also, it is a well-known fact that ((λt)k/k!)e−λt is TP2 in (k,t). Thus, by the basic composition formula [16], it follows that Ψ(i,t) is TP2 in (i,t), hence the result. █
3. CHARACTERIZATIONS AND CLOSURE PROPERTIES OF THE IMIT CLASS
In this section, we provide some characterization properties and closure under shock models and series systems for the IMIT class.
3.1. Characterizations
First, we give a characterization by means of the right spread order, the definition of which is recalled here (see [7] for details).
A random variable X is said to be smaller than Y in right spread order (denoted by X ≤RS Y) if and only if

where F−1(p) = inf{t : F(t) ≥ p}, p ∈ (0,1).
Theorem 3.1: Let X be a continuous random variable with a finite left endpoint of the support lX and F(lX) = 0. Then X is IMIT if and only if X(s) ≤RS X(t), for all s < t ≤ lX.
Proof: First, note that X is IMIT if and only if

for all s < t. We must prove that (3.1) is equivalent to

for all s < t and p ∈ (0,1). For it, observe that for every s < t ∈ R+ and p ∈ (0,1), the following hold:
(i) FX(t)−1(p) = t − F−1[(1 − p)F(t)].
(ii) F [t − FX(t)−1(p)] = (1 − p)F(t).
(iii) F−1[(1 − p)F(s)] ≤ F−1[(1 − p)F(t)].
Now, let s < t and assume that (3.1) holds. Then we get

where the inequality follows from the IMIT property of X and property (iii). Therefore, (3.2) holds.
Suppose now that (3.2) holds. Then

or, equivalently,

Appealing to property (iii), we get that μ is increasing [i.e., we get (3.1)]. █
Our next result presents a characterization of the IMIT class by means of the increasing convex order.
Theorem 3.2: Let X be a continuous nonnegative random variable. Then X is IMIT if and only if X(s) ≤ICX X(t), for all s < t.
Proof: Note that X(s) ≤ICX X(t) if and only if

for all 0 ≤ u ≤ s ≤ t.
Observe now that X is IMIT if and only if for all 0 ≤ u ≤ s ≤ t,

holds and also if and only if

Thus (3.3) holds.
To prove the assertion in the reversed direction, it suffices to set u = 0 in (3.3). █
3.2. Shock Models
Another useful property of nonparametric classes is their closure with respect to shock models (i.e., the definition of conditions such that the lifetime of a device subjected to shocks satisfies some reliability property). The first results in this direction are due to Esary, Marshall, and Proschan [12], and other results of this kind are given by A-Hameed and Proschan [3,4], Block and Savits [9], Pellerey [23], Perez-Ocon and Gamiz-Perez [25,26], and Belzunce et al. [8]. Here, we give conditions for the IMIT class.
Theorem 3.3: Let T be the random lifetime of a device having cumulative distribution function H defined as in (2.5). If

is increasing in k, for all k ≥ 1, then T satisfies the IMIT property.
Proof: First, note that straightforward computations give

for all t ≥ 0. Note also that

is increasing in t if and only if

or, equivalently, if

where

Again, by the assumption and by the basic composition formula [16], it follows that Ψ(i,t) is TP2 in (i,t). This completes the proof. █
Now, we consider nonhomogeneous Poisson shock models. Let λ(t) be the rate of the nonhomogeneous Poisson counting process. Then the distribution of the random lifetime T of the device is

where

[3].
To state the closure of IMIT class under nonhomogeneous Poisson shock models, we need the following preliminary result.
Lemma 3.1: Let λ : R+ → R+ be a decreasing function and let Λ(t) be as just described. If X is IMIT, then also Y = Λ−1(X) is IMIT.
Proof: Let H* be the distribution function of X and let H be the distribution function of Y. Then

We need to prove that

that is, that

However,

where z = Λ(t). The last inequality follows from the fact that X is IMIT. █
According to Lemma 3.1, Theorem 3.4 is immediate.
Theorem 3.4: Let

be increasing in k, for all k ≥ 1, and let λ(t) be decreasing in t, t ∈ R+. Then the lifetime T having distribution function H defined as in (3.4) satisfies the IMIT property.
3.3. Series System
Preservation properties of nonparametric classes under series and/or parallel systems are of importance in reliability theory. In the following result, we show that the class of differentiable IMIT life distributions is closed under the formation of a series system with independent and identically distributed (i.i.d.) components.
Theorem 3.5: Let T1,T2,…,Tn be i.i.d increasing mean inactivity time random variables with common differentiable distribution function F. Let T = min(T1,…,Tn). Then T also satisfies the IMIT property.
Proof: Let f be the derivative of F. Observe that the Ti are IMIT if and only if

where F(t) is tacitly assumed to be positive. The assertion follows if we show that (3.5) remains true with [1 − Fn] and its derivative replacing F and its derivative, respectively. For it, it suffices to show that

or, equivalently,

It is now clear that the above inequality follows readily by establishing the following for all 0 ≤ u ≤ t:

Let us observe that

The last inequality follows from algebraic arguments. Thus, (3.6) is proved, and the proof is complete. █
4. TESTING IN THE IMIT CLASS
In the context of reliability and life testing, the hazard rate of a life distribution plays an important role for stochastic modeling and classification. Being a ratio of probability density function and the corresponding survival function, it uniquely determines the underlying distribution and exhibits different monotonic behaviors. The concept of the ageless notion is equivalent to the phenomenon that age has no effect on the hazard rate. Thus, the ageless property is equal to the constant hazard rate, that is, the distribution is exponential. Hence, testing nonparametric classes is done by testing exponentially versus some kind of classes. This applies to many nonparametric classes such as increasing hazard rate (IHR), increasing hazard rate average (IHRA), new is better than used (NBU), new is better than used in expectation (NBUE), harmonic new is better than used in expectation (HBNUE), and decreasing mean residual lifetime (DMRL), among many others.
For a recent literature on testing the above classes as well as others, we refer the readers to Ahmad [1], Ahmad and Mugdadi [2], and Mugdadi and Ahmad [21]. Much of the earlier literature is cited in those works, where definitions, interrelations, and discussions of the above-mentioned classes are presented.
Kayid and Ahmad [17] discussed testing if H0 : F = F0 versus H1 : F is IMIT and not equal to F0. The test procedure proposed is based on estimating the probability density function and, hence, requires the not so easy process of choosing window width. In contrast, here we present an empirical approach that is derived from the property of the IMIT class that if F is IMIT, then υ(x)/F(x) is increasing in x ≥ 0, where

. Thus, we can set the following as a measure for the rest:

Lemma 4.1: Let X1, X2, X3, and X4 be four independent copies of an IMIT distribution F. Then

Proof: First, observe that

Hence,

On the other hand,

and

Thus, we arrive at the desired result from (4.1) and (4.2). █
As indicated in [17], we select F0 to be exponential. Hence,

. Let X1,X2,…,Xn denote a random sample from F. An unbiased estimate of Δ is given by

where (n)4 = n(n − 1)(n − 2)(n − 3) and

The main result of this section is stated in the following.
Theorem 4.1: As

is asymptotically normal with zero mean and variance σ2 given in (4.3). Under H0, the variance is

.
Proof: Using the general theory of U-statistics and von Mises statistics (see Lee [18]), we need only to calculate the asymptotic variance, which is equal to

However, clearly we have

Under H0,

Direct calculations give the result. █
To perform the test, reject H0 if

, the standard normal variate.
To assess the goodness of this approach, we evaluate its asymptotic Pitman efficacy for an alternative that is in the IMIT class but is not exponential, and we compare it to similar values reported in [17]. The asymptotic Pitman efficacy of the test based on Δ is given by

The following two distributions, reported in [17], are IMIT but not exponential:
(i) The linear failure rate

(ii) The Makeham

Note that the exponential is attained at θ = 0 in both cases. The asymptotic Pitman efficacy of the above test is equal to

where

Direct calculations for the above two alternatives give the values 1.320 and 0.824, respectively. The corresponding values for the Kayid and Ahmad [17] test are 0.732 and 0.244, respectively, and the current test is obviously better.
Acknowledgments
We express our thanks to the referees for their valuable comments. Two of the authors (M.K. and F.P.) thank Professor Taizhong Hu and Professor Asok Nanda for their useful comments and suggestions on the first draft of this manuscript, which have greatly improved the presentation. I.A. Ahmed and M. Kayid were supported by the U.S.–Egypt Science and Technology Joint Fund in cooperation with the NSF and NRC under project OTH8-020-001.
References
REFERENCES
Ahmad, I.A.
(2001).
Moments inequalities of ageing families of distributions with
hypothesis testing application.
Journal of Statistical Planning and Inference
92:
121–132.Google Scholar
Ahmad, I.A. &
Mugdadi, A.R.
(2004).
Further moment inequalities of life distributions with hypothesis
testing applications: The IFRA, NBUC, DMRL
classes.
Journal of Statistical Planning and Inference
120:
1–12.Google Scholar
A-Hameed, M.S. &
Proschan, F.
(1973).
Nonstationary shock models.
Stochastic Processes Applications
1:
383–404.Google Scholar
A-Hameed, M.S. &
Proschan, F.
(1975).
Shock models with underlying birth process.
Journal of Applied Probability
12:
18–28.Google Scholar
Alzaid, A.,
Kim, J.S., &
Proschan, F.
(1991).
Laplace ordering and its applications.
Journal of Applied Probability
28:
116–130.Google Scholar
Barlow, R.E. &
Proschan, F.
(1981).
Statistical theory of reliability and life testing.
Silver Spring, MD:
To Begin With.
Belzunce, F.
(1999).
On a characterization of right spread order by the increasing convex
order.
Statistics and Probability Letters
45:
103–110.Google Scholar
Belzunce, F.,
Ortega, E., &
Ruiz, J.M.
(1999).
The Laplace order and ordering of residual lives.
Statistics and Probability Letters
42:
145–156.Google Scholar
Block, H.W. &
Savits, T.H.
(1978).
Shock models with NBUE survival.
Journal of Applied Probability
15:
621–628.Google Scholar
Chandra, N.K. &
Roy, D.
(2001).
Some results on reversed failure rate.
Probability in the Engineering and Informational Sciences
15:
95–102.Google Scholar
Di Crescenzo, A. &
Longobardi, M.
(2002).
Entropy-based measure of uncertainty in past lifetime
distribution.
Journal of Applied Probability
39:
434–440.Google Scholar
Esary, J.D.,
Marshall, A.W., &
Proschan, F.
(1973).
Shock models and wear processes.
Annals of Probability
1:
627–649.Google Scholar
Fagiuoli, E. &
Pellerey, F.
(1994).
Mean residual life and increasing convex comparison of shock
models.
Statistics and Probability Letters
20:
337–345.Google Scholar
Hu, T.,
Kundu, A., &
Nanda, A.K.
(2003).
A not on Bayesian imperfect repair model.
Technical Report,
Department of Statistics and Finance, University of Science and
Technology of China,
Hefei.
Joag-Dev, K.,
Kochar, S., &
Proschan, F.
(1995).
A general composition theorem and its applications to certain
partial orderings of distributions.
Statistics and Probability Letters
22:
111–119.Google Scholar
Karlin, S.
(1968).
Total positivity, Vol. I.
Stanford, CA:
Standford University Press.
Kayid, M. &
Ahmad, I.A.
(2004).
On the mean inactivity time ordering with reliability
applications.
Probability in the Engineering and Informational Sciences
18:
395–409.Google Scholar
Lee, A.J.
(1989).
U-Statistics.
New York:
Marcel Dekker.
Li, X. &
Lu, J.
(2003).
Stochastic comparisons on residual life and inactivity time of
series and parallel systems.
Probability in the Engineering and Informational Sciences
17:
267–275.Google Scholar
Lynch, J.,
Mimmack, G., &
Proschan, F.
(1987).
Uniform stochastic orderings and total positivity.
Canadian Journal of Statistics
15:
63–69.Google Scholar
Mugdadi, A.R. &
Ahmad, I.A.
(2005).
Moments inequalities derived from comparing life with its
equilibrium form.
Journal of Statistical Planning and Inference
(to appear).CrossRef
Nanda, A.K.,
Singh, H.,
Misra, N., &
Paul, P.
(2003).
Reliability properties of reversed residual lifetime.
Communications in Statistics: Theory & Methods
32:
2031–2041.Google Scholar
Pellerey, F.
(1994).
Shock models with underlying counting process.
Journal of Applied Probability
31:
156–166.Google Scholar
Pellerey, F. &
Shaked, M.
(1997).
Characterizations of the IFR and DFR aging notions
by means of the dispersive order.
Statistics and Probability Letters
33:
389–393.Google Scholar
Perez-Ocon, R. &
Gamiz-Perez, M.L.
(1995).
Conditions on the arrival process to obtain HNBUE survival
using a shock model.
Communications in Statistics: Theory & Methods
24:
931–944.Google Scholar
Perez-Ocon, R. &
Gamiz-Perez, M.L.
(1996).
HNBUE property in a shock model with cumulative damage
threshold.
Communications in Statistics: Theory & Methods
25:
345–360.Google Scholar
Ross, S.M.
(1996).
Stochastic process,
2nd ed.
New York:
Wiley.
Ruiz, J.M. &
Navarro, J.
(1996).
Characterizations based on conditional expectations of the double
truncated distribution.
Annals of the Institute of Statistical Mathematics
48:
563–572.Google Scholar
Shaked, M. &
Shanthikumar, J.G.
(1994).
Stochastic orders and their applications.
New York:
Academic Press.
Shaked, M. &
Wong, T.
(1995).
Preservation of stochastic orderings under random mapping by point
processes.
Probability in the Engineering and Informational Sciences
9:
563–580.Google Scholar
 You have
Access
- 61
- Cited by