


1. The problem
When evaluating choice options, we often face two types of uncertainty. Decision theory has focused on empirical uncertainty: uncertainty about empirical facts, such as facts about weather or election outcomes. Philosophers have recently turned to normative uncertainty: uncertainty about value itself, for instance because of competing normative intuitions. Contributions include Oddie (Reference Oddie, Fulford, Gillett and Soskice1994), Lockhart (Reference Lockhart2000), Jackson and Smith (Reference Jackson and Smith2006), MacAskill (Reference MacAskill2014, Reference MacAskill2016), Bradley and Drechsler (Reference Bradley and Drechsler2014), Sepielli (Reference Sepielli and Shafer-Landau2009), Weatherson (Reference Weatherson2014), Lazar (Reference Lazar2017), Greaves and Cotton-Barratt (Reference Greaves and Cotton-Barratt2019), Tarsney (Reference Tarsney2018 a, Reference Tarsney2019), Podgorski (Reference Podgorski2019), MacAskill and Ord (Reference MacAskill and Ord2020), Riedener (Reference Riedener2020) and Dietrich and Jabarian (Reference Dietrich and Jabarian2021 a). Normative uncertainty is omnipresent: parents wonder how valuable child autonomy is, even when they are certain about all relevant empirical facts; politicians wonder which consequences of a policy matter most and whether also procedural or other deontological considerations matter; reason-based agents (Dietrich and List Reference Dietrich and List2013, Reference Dietrich and List2017) may wonder which properties matter and how they matter; and so on.
Much can be debated about the metaphysical status of normative uncertainty: Is it uncertainty about subjective or objective facts? About real or constructed facts? And so forth. We put these important debates aside. But we stress two things: normative uncertainty is meaningful under many interpretations and metaethical views about value, and it is not formally reducible to standard choice-theoretic uncertainty. Footnote 1
This paper pursues three objectives: (i) providing a systematic analysis of choice under normative and empirical uncertainty; (ii) formally comparing normative uncertainty to identity uncertainty in a (Harsanyian or Rawlsian) ‘original position’, in which one’s future values are unknown; and (iii) asking how the most popular decision principle – the maximization of expected value (‘Expectationalism’) – could be stated under normative and possibly also empirical uncertainty.
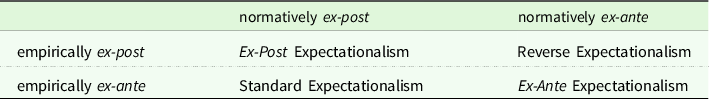
The third objective is, not to defend Expectationalism, but to ask how it could be defined in the first place. We shall propose different possible formulations, including Ex-Ante Expectationalism, Ex-Post Expectationalism, and hybrid versions. These formulations differ in the perspective from which the expected value is taken.
The recent literature on normative uncertainty has paid considerable attention to the principle of maximizing expected value, sometimes under the label ‘maximizing expected choice-worthiness’. See in particular pioneering work by Oddie, MacAskill and Ord, cited above. Riedener (Reference Riedener2020) provides a sophisticated axiomatic defence of the principle. Tarsney (Reference Tarsney2018 b) criticizes the reliance on a precise quantification of normative uncertainty and on certain types of measurements and comparisons of value. While the literature has focused on arguments for or against the principle, we focus on its very meaning and formulation. The literature has so far taken a particular formulation for granted, to be called Standard Expectationalism. Standard Expectationalism is a hybrid form of Expectationalism, which reasons ‘empirically ex-ante’, but ‘normatively ex-post’, as will be seen.
The dilemma between ex-ante and ex-post reasoning is prominent in other fields of formal ethics and aggregation theory. Footnote 2 The theory of normative uncertainty cannot escape the dilemma. Just as social egalitarians face a dilemma between ex-ante and ex-post equality, so expectationalists in individual decision theory face a dilemma between ex-ante, ex-post, and hybrid versions of Expectationalism. The ex-ante/ex-post dilemma always takes the same form: should the given paradigm or objective – for instance equality or (in our case) expected value – be pursued from an ex-ante or ex-post perspective? The ex-ante/ex-post dilemma also arises in non-expectational approaches to normative uncertainty; for instance, one could envision ex-ante, ex-post, and hybrid versions of maximin approaches to normative uncertainty. We here focus on Expectationalism.
The paper has a simple structure. Section 2 introduces a simple formal framework for capturing normative and (possibly) empirical uncertainty. Section 3 formally relates normative uncertainty to Harsanyi’s and Rawls’s thought experiment of an original position in which one’s future identity and values are unknown, and critically compares Harsanyi’s theory of choice in the original position with expectational choice under normative uncertainty. Sections 4–6 introduce and contrast four salient expectational theories – four solutions to the problem ‘expectation of what?’. Section 7 defines Expectationalism in full generality, going beyond the four special theories. Section 8 concludes the paper.
2. A framework of normative and empirical uncertainty
We now present the ingredients of what might be the simplest model of normative and empirical uncertainty.
The objects of evaluation. The agent – ‘you’ – considers a non-empty set A of objects, called ‘options’. They could be policy measures, social arrangements, income distributions etc. So far we leave open whether options contain empirical risk.
Competing valuations. You are uncertain about the correct value of options. Value is taken to be an absolute (cardinal) rather than comparative (ordinal) notion. So, a possible standard of evaluation is given by a value function rather than value order, i.e. by a real-valued function v on A. v is called a valuation, and assigns to each option a in A a value
 $v(a)$
. Let
 ${\cal V}$
be the set of those valuations which you deem possible, also called your first-order theories. Formally,
 ${\cal V}$
is a finite non-empty set of functions from A to
 $\mathbb R$
.
In a problem of moral choice,
 ${\cal V}$
could contain a utilitarian, an egalitarian, and some deontological valuation. In a problem of intertemporal choice,
 ${\cal V}$
could contain a valuation with exponential discounting and another with hyperbolic discounting. In these examples, the valuations in
 ${\cal V}$
differ radically: the agent hesitates between entirely different principles of evaluation. In other applications,
 ${\cal V}$
consists of similar valuations that differ only in a parameter, for instance: prioritarian social-welfare valuations with varying degrees of prioritarianism, or egalitarian social-welfare valuations with varying degrees of inequality-aversion, or valuations of intertemporal well-being with varying rates of discounting the future, or (for risky options) valuations with varying degrees of risk-aversion. In such parametric examples, normative uncertainty boils down to uncertainty about the correct parameter value: the correct amount of prioritarianism, inequality-aversion, discounting, risk-aversion, etc.
Our examples show that normative uncertainty comes in two species: uncertainty about a parameter of evaluation and uncertainty about the principle of evaluation. Footnote 3
Credences in valuations. You assign to each valuation v in
 ${\cal V}$
a correctness probability
 $Pr(v) \ge 0$
, representing your degree or belief (credence) in v, where
 $\sum\nolimits_{v \in {\cal V}} Pr(v) = 1$
.
Meta-value. Given your credences, how should you evaluate options overall? An answer takes the form of a meta-valuation or meta-theory. Like valuations in
 ${\cal V}$
, it is a real-valued function on the set of options A. To distinguish it from valuations in
 ${\cal V}$
, it is denoted by an upper-case letter V.
 $V(a)$
stands for the meta-value of option a. Two examples suffice for now:
-
Standard Expectationalism: The meta-value of an option
 $a \in A$
is its expected value:
$V(a) = \sum\nolimits_{v \in {\cal V}} Pr(v)v(a)$
.
-
Maximin: The meta-value of an option
$a \in A$
is its minimal possible
Footnote 4
value:
$V(a) = \mathop {\min }\nolimits_{v \in {\cal V}:Pr(v) \ne 0} v(a)$
.


Unlike for first-order theories, it was not essential to define meta-theories as functions rather than orders on A. Readers could replace in their mind any V by the value order
 $$\underline \succ $$
it induces.
Footnote 5
When we simply say ‘theory’, we mean a meta-theory V, not a first-order theory v in
 ${\cal V}$
.
Measurability and comparability of value. As usual in the expectational approach, we take first-order value to be measurable and comparable across valuations. Full measurability makes it meaningful to say that an option x has value 7 under a valuation v (
 $v(x) = 7$
), or is twice as valuable as another option y (
 $v(x) = 2v(y)$
), or exceeds z’s value by 2 (
 $v(x) - v(z) = 2$
), etc. Full comparability makes it meaningful to say that two valuations v and
 ${v'}$
assign same value to option x (
 $v(x) = {v'}(x)$
), or same value gain to the change from option x to option y (
 $v(y) - v(x) = {v'}(y) - {v'}(x)$
), etc.
Footnote 6
Such assumptions are strong and debatable. They can be relaxed, in ways that differ across the below-discussed versions of Expectationalism.
Footnote 7
We set aside when and how measurability and comparability can be justified,
Footnote 8
and how they could be relaxed by different versions of Expectationalism.
Adding empirical uncertainty: options as lotteries. The above framework is complete as a model of purely normative uncertainty; so far, empirical uncertainty in options is allowed, but not modelled. To add empirical uncertainty explicitly, we hereafter assume that options in A are lotteries on a given set X of outcomes, i.e. functions a from X to
 $[0,1]$
such that
 $\sum\nolimits_{x \in X} a(x) = 1$
, where
 $a(x)$
is non-zero for only finitely many x in X. An option is riskless if some outcome has probability one, and risky otherwise. Outcomes represent empirical states of affairs after resolution of empirical uncertainty. Under the simplest interpretation, outcomes are ‘consequences’ of actions; this limits us to (normative uncertainty between) consequentialist valuations. But outcomes could be broader than ‘consequences’. They could for instance encompass intentions and/or the choice context. This allows for non-consequentialist valuations.
Footnote 9
Not all lotteries on X need to count as options, i.e. belong to A. But let A contain at least the riskless lotteries, which assign probability one to some outcome. We occasionally apply valuations v to outcomes x rather than options; of course,
 $v(x)$
stands for the value
 $v(a)$
of the riskless option a corresponding to x.
Economists distinguish between ‘risk’, in which probabilities are (in some sense) objective, and ‘uncertainty’, in which they are subjective. In our model, all probabilities – of outcomes or valuations – are exogenously given. Technically, this makes our framework one of (empirical and normative) risk, not (empirical and normative) uncertainty. But one can interpret probabilities subjectively. Regarding valuations, our term ‘credence’ already suggests a subjective interpretation. Regarding outcomes, one can interpret
 $a(x)$
as the agent’s subjective probability of outcome x under option a.
Footnote 10
Valuations of vNM type and of non-vNM type. A valuation v in
 ${\cal V}$
could have the notorious von-Neumann–Morgenstern property, i.e. be of ‘vNM type’, as we shall say. A valuation v is of vNM-type if it evaluates each option by the expected value of its outcome, formally
Footnote 11
 $v(a) = \sum\limits_{x \in X} a(x)v(x)\,{\rm{for}}\;{\rm{all}}\;{\rm{options}}\;a \in A.$
Ever since the Harsanyi–Sen debate, it is controversial whether the vNM property is a necessary property of a coherent valuation, or (as we believe) a coincidental property that may or not hold. Footnote 12
Our model is ecumenical: you (the agent) could be utterly certain that correct value is of vNM-type, by having positive credence only in vNM-type valuations; or be utterly certain of the opposite, by having positive credence only in non-vNM-type valuations; or be uncertain about the issue, by having positive credence in both types of valuation. Being ecumenical is important, because even if we (as modellers) were certain that true value is of some type, the agent we model might not share this certainty. We should for instance not assume that
 ${\cal V}$
contains only vNM-type valuations or only non-vNM-type valuations; this would restrict the model to very special agents who are certain that value is of vNM-type or certain that value is not of this type, unlike most or all philosophers interested in the vNM property.
A deeper methodological issue is at stake. The field of normative uncertainty is engaged in meta-normativity. It should thus avoid prejudging first-order normative questions. It should take people’s actual normative beliefs and uncertainties at face value, however non-ideal or ‘mistaken’ they might be, and tell people how to respond to their non-ideal normative beliefs. Even if true value were necessarily of vNM type, as some philosophers argue, then we should not assume the agent is aware of this. This said, the (very common) restriction to vNM-type valuations can sometimes be legitimate as a working assumption. We avoid this restriction.
3. The formal analogy between normative uncertainty and identity uncertainty
Choice under normative uncertainty bears formal analogies to choice by an imaginary agent in the ‘original position’ who does not know their future identity and values, be that agent Harsanyi’s (1955, 1978) ‘impartial observer’ or Rawls’s (Reference Rawls1971) agent behind a ‘veil of ignorance’. In fact, Harsanyi already uses the term ‘moral uncertainties’ (Harsanyi Reference Harsanyi1975: 602). Harsanyi and Rawls famously disagreed on what choices are rational in the original position. Harsanyi defends an expected-utility rule, whereas Rawls argues for the maximin rule. This debate can be reinterpreted as a debate about the right decision rule under normative uncertainty. Harsanyi’s expected-utility rule looks similar to (Standard) Expectationalism – but it differs, as we shall see.
What exactly is the formal relationship between normative uncertainty and the original position à la Harsanyi or Rawls? We shall focus on Harsanyi rather than Rawls, because Harsanyi works within a mathematical theory. Like us, Harsanyi considers a choice situation under risk, given by a set of lotteries A over an underlying set of outcomes X (technically, he requires X to be finite and A to contain all lotteries over X, two assumptions we adopt in this section). He assumes this choice is faced by the individuals of a society, labelled
 $i = 1,2, \ldots ,n$
. He considers preference relations
 $${\underline \succ _1}$$
, …,
 $${\underline \succ _n}$$
on A of these individuals, and also a ‘social’ preference relation
 $${\underline \succ}$$
on A of an imaginary agent in the original position. He assumes that all these preference relations satisfy von-Neumann–Morgenstern’s three axioms (‘weak order’, ‘continuity’ and ‘independence’). By implication, they are representable by vNM-type
Footnote 13
utility functions. Let
 ${u_i}$
denote individual i’s vNM utility function, representing
 $${\underline \succ _i}$$
. We write ‘
 ${u_i}$
’ rather than ‘
 ${v_i}$
’ to avoid suggesting that vNM utility is the same as value.
Harsanyi offers two seminal theorems about the nature of social preferences, his Aggregation Theorem and his Impartial Observer Theorem. Each theorem makes certain assumptions about the relation between social and individual preferences (the Aggregation Theorem in fact makes a single assumption, the Pareto Principle). Although their assumptions differ, both theorems conclude that social vNM utility is a linear combination of individual vNM utility, i.e. that the social preference relation
 $$\underline \succ $$
is representable by a social vNM utility function U given by
 $U(a) = \sum\limits_{i = 1}^n {w_i}{u_i}(a)\;{\rm{for}}\;{\rm{all}}\;a \in A,$
for some fixed weights
 ${w_i} \ge 0$
(
 $i = 1, \ldots ,n$
). This formula superficially resembles the formula of Standard Expectationalism. But there are two major differences: (i) the use of vNM utility functions
 ${u_i}$
(
 $i = 1, \ldots ,n$
) instead of arbitrary valuations v (
 $ \in {\cal V}$
) and (ii) the use of weights
 ${w_i}$
instead of correctness probabilities
 $Pr(v)$
. More on both differences soon.
In fact, Harsanyi’s Impartial Observer Theorem comes much closer to normative uncertainty than his Aggregation Theorem. For one, as suggested by the names of the theorems, only in the Impartial Observer Theorem social preferences are interpreted as preferences of an impartial observer who does not know their future identity and values, whereas in the Aggregation Theorem social preferences are simply preferences of ‘society’ or a ‘social planner’. For another, in the Impartial Observer Theorem the weight
 ${w_i}$
represents the probability that the impartial observer takes on i’s identity and values, in analogy to the correctness probability of a valuation under normative uncertainty. Harsanyi was particularly interested in the ‘impartial’ case in which the observer has an equal probability of
 $${w_i} = {1 \over n}$$
of being any individual i in society; this special case is salient to social ethics, but not to the analogy to choice under normative uncertainty, because such a chooser need not have equal credence in different valuations. In the Aggregation Theorem, by contrast, the weights
 ${w_i}$
are just abstract coefficients, without an interpretation in terms of probabilities or uncertainty. So, the more relevant theorem of Harsanyi from the perspective of normative uncertainty might be his Impartial Observer Theorem.
Footnote 14
But does Harsanyi’s linear aggregation formula (1) really correspond to Standard Expectationalism? It does not, because the individuals’ vNM utility functions
 ${u_i}$
need not represent value or utility in a relevant cardinal and interpersonally comparable sense. Distinguishing between vNM utility and ‘true’ utility or value is of course controversial, ever since the Harsanyi–Sen debate. For Harsanyi, vNM utility is utility or value in the proper sense. We side with Sen (and Weymark), who object that the vNM function
 ${u_i}$
is just one of infinitely many possible numerical representations of i’s value order; any increasing transformation of
 ${u_i}$
would represent the same order. Except in a lucky coincidence,
 ${u_i}$
does not measure i’s utility or value in the full, non-ordinal and interpersonally comparable, sense. If for each individual i we let
 ${v_i}$
be i’s ‘true’ utility or value function, then the correct analogue of Standard Expectationalism is not a linear aggregation of vNM utility, given by (1), but a linear aggregation of ‘true’ utility, given by
 $V(a) = \sum\limits_{i = 1}^n {w_i}{v_i}(a)\;{\rm{for}}\;{\rm{all}}\;a \in A.$
This formula indeed captures the expectation of a’s value from behind the veil, assuming
 ${w_i}$
is the probability of obtaining i’s identity and values.
Grant et al. (Reference Grant, Kajii, Polak and Safra2010) have proved a version of Harsanyi’s Impartial Observer Theorem in which the observer’s preferences obey a more general representation than (1), obtained from (1) by replacing each individual vNM utility function
 ${u_i}$
by a (continuous) increasing transformation of it; formally,
 $U(a) = \sum\limits_{i = 1}^n {w_i}[{\phi _i} \circ {u_i}](a)\;{\rm{for}}\;{\rm{all}}\;a \in A,$
for some increasing (continuous) transformations
 $${\phi _i}:\mathbb R \to \mathbb R$$
(
 $i = 1, \ldots ,n$
). If each individual i’s transformed function
 ${\phi _i} \circ {u_i}$
is i’s ‘true’ utility functions
 ${v_i}$
, then Grant et al.’s observer preferences (3) reduce to (2), the analogous to Standard Expectationalism under normative uncertainty.
Let us sum up. If we formally reinterpret preferences under normative uncertainty as preferences in the original position, then Harsanyi-type preferences (1) and Grant et al.-type preferences (3) represent two meta-theories, which depart from Standard Expectationalism by taking the expectation of something else than value. But Harsanyi-type preferences match Standard Expectationalism in a special case, where all valuations are of vNM-type, and Grant et al.-type preferences match Standard Expectationalism in a broader special case, where valuations need not be of vNM-type, but must still be continuous increasing transformations of vNM functions (hence must still order the lotteries in accordance with von-Neumann–Morgenstern’s axioms Footnote 15 ).
4. Expected value of what?
As already seen, ‘expected value’ need not be ‘expected vNM value’, since valuations in
 ${\cal V}$
need not be of vNM-type (this marks the difference to the preferences of Harsanyi’s impartial observer, reinterpreted as an agent under normative uncertainty). Our next question is: expected value of what? Expectational theories evaluate options by the expected value of some object. That object is the prospect offered by the option, but there are different types of prospect: the ex-ante prospect, the ex-post prospect, and hybrid prospects from some intermediate (ex-interim) perspective.
Think of prospects as probability distributions. More precisely, one can define prospects equivalently as distributions over empirical-normative worlds (‘world prospects’) or distributions over resulting value levels (‘value prospects’). We shall later only work with value prospects. But let us start with world prospects. An empirical-normative world – for short, a world – is a pair
 $(x,v)$
of an outcome in X (an ‘empirical world’) and a valuation in
 ${\cal V}$
(a ‘normative world’). In a world, all empirical or normative uncertainty is resolved. A world prospect is a probability distribution over worlds, representing how likely worlds are (where for simplicity only finitely many worlds have non-zero probability). Each option a generates an (ex-ante) world prospect, under which the probability of a world
 $(x,v)$
is the product
 $a(x)Pr(v)$
of the probabilities of outcome x (under option a) and valuation v. This world prospect is ex-ante because no uncertainty is resolved; ex-post and hybrid world prospects will be defined shortly.
We can now give four possible answers to the question ‘Expected value of what?’, hence four ways to reason towards the meta-value of a given option
 $a$
. We keep the four answers informal; formal definitions follow in section 5.
-
Normatively ex-post reasoning: You place yourself in a normatively ex-post and empirically ex-ante position, by considering a given valuation v and the lottery of empirical outcomes generated by option a. So you face the normatively ex-post world prospect, in which v has (marginal) probability one and any outcome x in X has (marginal) probability
$a(x)$
. It yields the value
$v(a)$
. Stepping outside this position, you then form the expectation of the value
$v(a)$
across valuations v in
${\cal V}$
. This is Standard Expectationalism. -
Ex-post reasoning: You place yourself in a fully ex-post position, by considering a given outcome x and a given valuation v. So you face the ex-post world prospect, in which world
$(x,v)$
has probability one. It yields the value
$v(x)$
. Stepping outside this position, you then form the expectation of the value
$v(x)$
across worlds
$(x,v)$
in
$X \times {\cal V}$
. This is Ex-Post Expectationalism. -
Ex-ante reasoning: You place yourself in the fully ex-ante position, in which both parts of the empirical-normative world are unknown. So you face the ex-ante world prospect, defined above. You then form the expected value of this ex-ante prospect; how this works is shown in section 5. This is Ex-Ante Expectationalism.
-
Empirically ex-post reasoning: You place yourself in an empirically ex-post and normatively ex-ante position, by considering a given outcome x and the probability distribution over valuations
$Pr$
reflecting your normative uncertainty. So you face the empirically ex-post world prospect, in which x has (marginal) probability of one and any valuation v has (marginal) probability
$Pr(v)$
. You then form the expected value of this world prospect, in a way shown in section 5. This is Reverse Expectationalism. It is the reverse or ‘dual’ of Standard Expectationalism, as it reasons ex-ante where Standard Expectationalism reasons ex-post, and vice versa.


These four answers to the question ‘Expected value of what?’ were given in the form of world prospects, but they can be redescribed as value prospects. Value prospects are prospects of achieving certain value levels (not worlds) with certain probabilities, for instance achieving value 4 with probability 1/2 and value 0 with probability 1/2. A world prospect immediately induces a value prospect (mathematically, by taking the image of the world prospect under the mapping
 $(x,v) \mapsto v(x)$
from worlds to resulting values). For instance, the ex-post world prospect under which world
 $(x,v)$
is certain induces the riskless value prospect under which the value
 $v(x)$
is certain.
Formally, a value prospect is simply a lottery over real numbers, i.e. a function p assigning to each value k in a probability
 $p(k)$
in
 $[0,1]$
such that
 $\sum\nolimits_{k \in \mathbb R} {p(k)} = 1$$
, where (for simplicity) only finitely many values k in
$\mathbb R$
have non-zero probability
 $p(k)$
. Each option a generates a value prospect, denoted
 ${p_a}$
. It reflects empirical and normative uncertainty, as the resulting value
 $v(x)$
depends on both x and v, hence on the empirical-normative world
 $(x,v)$
. The probability that the resulting value is (say) 4 is the sum-total probability of all worlds
 $(x,v)$
such that
 $v(x) = 4$
. The just-defined value prospect
 ${p_a}$
of an option a is an ex-ante construct: no uncertainty is yet resolved. Indeed,
 ${p_a}$
is simply the value prospect induced by the ex-ante world prospect. Partly or fully ex-post value prospects are definable by eliminating one or both sources of uncertainty.
We now define the four kinds of value prospect formally. They correspond exactly to the four kinds of world prospect above, respectively: Footnote 16
-
The (ex-ante) value prospect of option
$a \in A$
is the value prospect ‘
${p_a}$
’ such that any value
$$k \in \mathbb R$$
has probability
$${p_a}(k) = {\rm{'probability}}\;{\rm{that}}\,a\,{\rm{leads}}\,{\rm{to}}\,{\rm{value}}\,k'{\rm{ = }}\sum\limits_{({{x}},{{v}}) \in {{X}} \times {{V}}:{{v}}({{x}}){{ = k}}} {\underbrace {{{a}}({{x}}){{Pr}}({{v}})}_{{\rm{prob}}.\,{\rm{of}}\,({{x}},{{v}})}}.$$
-
The (normatively ex-post) value prospect of option
$a \in A$
given valuation
$v \in {\cal V}$
is the value prospect ‘
${p_{a,v}}$
’ such that any value
$$k \in \mathbb R$$
has probability
${p_{a,v}}(k) = {\rm{'probability}}\,{\rm{that}}\,a\,{\rm{leads}}\,{\rm{to}}\,{\rm{value}}\,k\,{\rm{given}}\,v{\rm{'}} = \sum\limits_{x \in X:v(x) = k} a(x).$
-
The (empirically ex-post) value prospect given outcome
$x \in X$
is the value prospect ‘
${p_x}$
’ such that any value
$$k \in \mathbb R$$
has probability:
${p_x}(k) = {\rm{'probability}}\,{\rm{that}}\,x\,{\rm{leads}}\,{\rm{to}}\,{\rm{value}}\,k{\rm{'}} = \sum\limits_{v \in {\cal V}:v(x) = k} Pr(v).$
-
The (ex-post) value prospect given
$x \in X$
and
$v \in {\cal V}$
is the riskless value prospect ‘
${p_{x,v}}$
’ under which the value is
$v(x)$
with probability one.
Footnote 17


5. Four expectational theories
We now formally define the four expectational theories discussed in section 4. Each takes the expected value of a certain prospect, as will be clear either by definition or by Theorem 1 below. We begin with the two theories whose definitions do not explicitly refer to prospects.
Standard Expectationalism (‘
 $E{V_{stan}}$
’): The meta-value of an option
 $a \in A$
is the expected value of the option itself:
 $E{V_{stan}}(a) = \sum\limits_{v \in {\cal V}} Pr(v)v(a).$
This theory reasons empirically ex-ante, because the object whose expected value it forms (the option) contains empirical risk. The second theory reasons ex-post: it forms the expected value of the outcome, which no longer contains empirical risk. This requires averaging across both outcomes and valuations, hence across empirical-normative worlds
 $(x,v)$
. Formally:
Ex-Post Expectationalism (‘
 $E{V_{post}}$
’): The meta-value of an option
 $a \in A$
is the expected value of the outcome:
 $E{V_{post}}(a) = \sum\limits_{(x,v) \in X \times {\cal V}} \underbrace {a(x)Pr(v)}_{{\rm{prob.}}\,{\rm{of}}\,(x,v)}v(x).$
The third theory reasons fully ex-ante. It operates neither at the fully ex-post level of outcomes, nor at the empirically ex-post level of options, but at the level of ex-ante value prospects. But how can a valuation v in
 ${\cal V}$
evaluate value prospects rather than options, i.e. how should we define
 $v(p)$
for a value prospect p? We pick any option a in A whose value prospect given v is p, and identify
 $v(p)$
with
 $v(a)$
. If for instance p is the value prospect ‘the value is 1 or 0 equiprobably’, then we pick an option a which equiprobably has some outcome x of value
 $v(x) = 1$
or some outcome y of value
 $v(y) = 0$
, and define
 $v(p)$
as
 $v(a)$
. Formally, the value of a value prospect p under a valuation v in
 ${\cal V}$
– denoted
 $v(p)$
– is the value
 $v(a)$
of any option
 $a \in A$
such that
 ${p_{a,v}} = p$
. This definition implicitly rests on an assumption that we make for the rest of the paper:
Assumption: For each valuation v in
 ${\cal V}$
and value prospect p, (i) A contains an option a whose value prospect given v,
 ${p_{a,v}}$
, is p; and (ii) any two such options a in A have same value
 $v(a)$
.
Condition (i) is a typical richness assumption: the set of options A should be sufficiently inclusive, i.e. contain options with any given value prospects. Condition (ii) is a consistency assumption on the valuations in
 ${\cal V}$
. It is compatible with most or all first-order theories one would naturally want to consider.
Ex-Ante Expectationalism (‘
 $E{V_{ante}}$
’): The meta-value of an option
 $a \in A$
is the expected value of the ex-ante prospect:
 $E{V_{ante}}(a) = \sum\limits_{v \in {\cal V}} Pr(v)v({p_a}).$
Note an intended discrepancy: in
 $v({p_a})$
, a given valuation (v) is applied to a prospect (
 ${p_a}$
) that is formed ex-ante, when the valuation was uncertain rather than given. Precisely this is what ex-ante reasoning should do, as it should ask how attractive each ex-ante prospect is on average across possible valuations.
The fourth theory calculates the expected value of yet another object: the empirically ex-post value prospect. This requires averaging across outcomes and valuations, hence across empirical-normative worlds
 $(x,v)$
.
Reverse Expectationalism (‘
 $E{V_{rev}}$
’): The meta-value of an option
 $a \in A$
is the expected value of the empirically ex-post prospect:
 $E{V_{rev}}(a) = \sum\limits_{(x,v) \in X \times {\cal V}} \underbrace {a(x)Pr(v)}_{{\rm{prob}}{\rm{.\, of}}\, (x,v)}v({p_x}).$
This theory reverses the reasoning of Standard Expectationalism: it reasons empirically ex-post rather than normatively ex-post.
The following theorem re-expresses the four theories in a unified format, showing that they only differ in the ‘locus’ of expectation-taking, i.e. in the sort of prospect whose expected value they take.
Theorem 1
Each expectational theory
 $V \in \{ E{V_{ante}},E{V_{post}},E{V_{stan}},E{V_{rev}}\} $
evaluates any option
 $a \in A$
by the expected value of a specific value prospect, i.e.
 $V(a) = \sum\limits_{(x,v) \in X \times {\cal V}} \underbrace {a(x)Pr(v)}_{{\rm{prob.}}\,{\rm{of}}\,(x,v)}v(p),$
where ‘p’ is a place holder for the
-
ex-ante value prospect
${p_a}$
if
$V = E{V_{ante}}$
, -
ex-post value prospect
${p_{x,v}}$
if
$V = E{V_{post}}$
, -
normatively ex-post value prospect
${p_{a,v}}$
if
$V = E{V_{stan}}$
, -
empirically ex-post value prospect
${p_x}$
if
$V = E{V_{rev}}$
.


6. Illustration of these four expectational theories and their risk attitudes
Suppose you hesitate between just two valuations, v and
 ${v'}$
. You have credence
 $${1 \over 2}$$
in each of them, and credence 0 in all other valuations (if any) in
 ${\cal V}$
. Both valuations v and
 ${v'}$
are risk-averse: they penalize options for any uncertainty about how good their outcome is (what this means will become clear). So you are sure that risk-aversion is correct, i.e. that the correct valuation is risk-averse. You now compare two options. Both options lead to the value prospect ‘value 4 with probability
 $${1 \over 2}$$
, value 0 with probability
 $${1 \over 2}$$
’, denoted
 ${4_{50\% }}{0_{50\% }}$
, but for very different reasons:
-
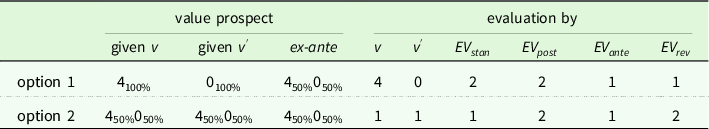
Option 1 involves only normative risk. It surely has some outcome x, whose value is either
$v(x) = 4$
or
${v'}(x) = 0$
. -
Option 2 involves only empirical risk. It has either some outcome y or some outcome z (equiprobably), where it is uncontroversial between v and
${v'}$
that y has value 4 and z has value 0. As v and
${v'}$
are risk-averse, they evaluate the option below the expected resulting value of
$${1 \over 2}4 + {1 \over 2}0 = 2$$
. Let them assign the value of 1 to the option. The gap from 1 to 2 is the ‘risk penalty’ or ‘risk premium’.


Four expectational theories and their modes of reasoning

Four expectational theories applied to two concrete options

Table 2 displays the (ex-ante and normatively ex-post) value prospects of the options and the evaluations by both first-order theories and the four expectational meta-theories. The four meta-evaluations are obtained as follows:
-
Standard Expectationalism forms the average value of the option. This yields
$${1 \over 2}4 + {1 \over 2}0 = 2$$
or
$${1 \over 2}1 + {1 \over 2}1 = 1$$
, respectively. -
Ex-Post Expectationalism forms the average value of the outcome. Recall that this in principle requires averaging across valuations in
${\cal V}$
(normative uncertainty) and outcomes (empirical uncertainty). Yet our options effectively need just one dimension of averaging, as they have just one source of uncertainty. The first option has just normative uncertainty: it surely has outcome x, of value 4 or 0. The second option has just empirical uncertainty: it has outcome y of sure value 4 or outcome z of sure value 0. Each option thus has the same average value of the outcome:
$${1 \over 2}4 + {1 \over 2}0 = 2$$
. -
Ex-Ante Expectationalism forms the average value of the ex-ante value prospect, which is the same prospect
${4_{50\% }}{0_{50\% }}$
for each option. So, regardless of which option we consider, we must calculate
$${1 \over 2}v({4_{50\% }}{0_{50\% }}) + {1 \over 2}v'({4_{50\% }}{0_{50\% }})$$
. What are
$v{(4_{50\% }}{0_{50\% }})$
and
${v'}{(4_{50\% }}{0_{50\% }})$
? As
${4_{50\% }}{0_{50\% }}$
is option 2’s value prospect given v,
$v{(4_{50\% }}{0_{50\% }}) = v(option\, 2) = 1$
. As
${4_{50\% }}{0_{50\% }}$
is also option 2’s value prospect given
${v'}$
,
${v'}{(4_{50\% }}{0_{50\% }}) = {v'}($
option 2
$) = 1$
. So,
$${1 \over 2}v({4_{50\% }}{0_{50\% }}) + {1 \over 2}v'({4_{50\% }}{0_{50\% }}) = {1 \over 2}1 + {1 \over 2}1 = 1$$
. -
Reverse Expectationalism forms the average value of the empirically ex-post value prospect. As for Ex-Post Expectationalism, this in principle requires averaging across both outcomes and valuations; but for each option one dimension of averaging drops out, because option 1 is empirically riskless and option 2 is normatively riskless. Option 1 surely has outcome x, whose value prospect
${4_{50\% }}{0_{50\% }}$
is evaluated at 1 by both (risk-averse) valuations, as just seen. The average value is thus
$${1 \over 2}1 + {1 \over 2}1 = 1$$
. Option 2 either has outcome y, whose value prospect
${4_{100\% }}$
has value 4 under both v and
${v'}$
; or has outcome z, whose value prospect
${0_{100\% }}$
has value 0 under both v and
${v'}$
. The average value is thus
$${1 \over 2}4 + {1 \over 2}0 = 2$$
.


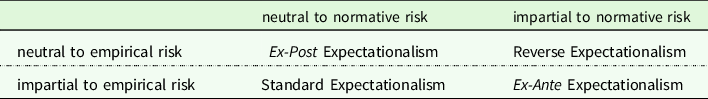
What attitudes to risk do the four expectational meta-theories take? Very different ones. We shall explain this point only informally here, since a separate paper focuses on risk attitudes (Dietrich and Jabarian Reference Dietrich and Jabarian2021 b). We construe risk aversion and other risk attitudes as attitudes to the risk about outcome value, such as (in our example) the risk of ending up either with value 4 or with value 0. This is not the only possible notion of risk attitudes. Different notions of risk attitudes differ in the quantity with respect to which risk is defined. For economists in the Arrow–Pratt tradition, this quantity is monetary wealth, or consumption, or some other empirical quantity; here, risk (aversion) lies in (aversion to) unknown wealth, or unknown consumption, etc. For other scholars, including ourselves, the quantity is outcome value; here, risk (aversion) consists in (aversion to) unknown outcome value. Footnote 18 In general, being risk-averse (-prone, -neutral) with respect to a given quantity Q means that any option leading to a risky amount of Q is ranked below (above, like) receiving the option’s expected amount of Q for sure; in the special case of von-Neumann–Morgenstern preferences, an equivalent condition is that vNM utility is convex (concave, linear) in Q. Footnote 19
Risk about outcome value can have an empirical, or normative, or mixed origin: it can stem from uncertainty about the outcome (empirical uncertainty), or uncertainty about the value of the outcome (normative uncertainty), or uncertainty about both. A meta-theory is risk-averse if its evaluation of options contains a penalty for risk in outcome value, i.e. lies below the expected outcome value; it is risk-neutral if evaluations match the expected outcome value. One may want the meta-theory to ‘borrow’ the risk attitude of those first-order valuations that you find credible, i.e. have non-zero credence in. For instance, if you have positive credence only in risk-averse valuations in
 ${\cal V}$
, then the meta-theory is risk-averse. We call this risk-impartiality, because your meta-level risk attitude defers to your risk-attitudinal judgments (Dietrich and Jabarian Reference Dietrich and Jabarian2021
b).
Footnote 20
We set aside what risk-impartiality requires when you are risk-attitudinally undecided, e.g. have non-zero credence both in a risk-averse valuation and a risk-neutral valuation. In our example, you are certain that risk-aversion is correct, as v and
 ${v'}$
are both risk-averse; here a risk-impartial meta-theory is risk-averse.
Footnote 21
Defending the principle of risk-impartiality goes beyond this paper. We merely note, in Table 3, that our four meta-theories differ in their risk attitudes: one is risk-neutral no matter what your risk-attitudinal judgements are (no penalty for risk), one is risk-impartial (deference to risk-attitudinal judgements), and two have hybrid risk-attitudes, i.e. are risk-neutral or risk-impartial depending on the origin of risk.
To explain why, we use again our example, in which all credible valuations (i.e. v and
 ${v'}$
) are risk-averse, so that risk impartiality reduces to risk aversion.
The risk attitudes of the four meta-theories in our example with risk-averse first-order theories

-
Standard Expectationalism applies the valuations v and
${v'}$
to the option, which captures only empirical risk. This leads (by risk-aversion of v and
${v'}$
) to a penalty or discount for empirical risk only: the theory is averse to empirical risk, but neutral to normative risk. This explains why in Table 2 the normatively risky option 1 gets the undiscounted value of 2, while the empirically risky option 2 gets the discounted value of 1. -
Ex-Post Expectationalism applies the two valuations to the outcome, which captures no risk. So no risk is penalized: the theory is globally risk-neutral. This explains why both options in Table 2 get the undiscounted value of 2.
-
Ex-Ante Expectationalism applies the two valuations to the ex-ante value prospect, which captures risk of both origins. So all risk is penalized: the theory is globally risk-averse. This explains why both options in Table 2 get the discounted value of 1.
-
Reverse Expectationalism applies the two valuations to the empirically ex-post value prospect, which captures only normative risk. So only normative risk is penalized: the theory is averse only to normative risk. This explains why in Table 2 only the normatively risky option gets the discounted value of 1.


7. The full taxonomy of Expectationalism
We now turn to a unification. We introduce a single generic expectational theory, of which our four earlier theories are nothing but special cases. The generic theory depends on a parameter that determines the reasoning mode, i.e. the extent of ex-post-ness. Particular choices of this parameter yield our four special expectational theories, and all other expectational theories. So there exist not just four expectational theories, but a large and unified class of expectational theories.
The parameter determining the expectational theory is the type of information relative to which reasoning is ex-post: full information yields Ex-Post Expectationalism, no information yields Ex-Ante Expectationalism, purely normative information yields Standard Expectationalism, purely empirical information yields Reverse Expectationalism, and yet other types of information yield other expectational theories.
We model an information by an empirical-normative event
 $I \subseteq X \times {\cal V}$
, containing the empirical-normative worlds
 $(x,v)$
which are consistent with the information. Salient examples:
-
The full information of a specific empirical-normative world
$(x,v)$
is
$I = \{ (x,v)\} $
, a singleton set of worlds. -
The vacuous or tautological information is
$I = X \times {\cal V}$
, the set of all worlds. -
The information of a specific valuation v is
$I = X \times \{ v\} $
, the set of worlds of type
$( * ,v)$
. -
The information of a specific outcome x is
$I = \{ x\} \times {\cal V}$
, the set of worlds of type
$(x, * )$
.


Recall that each option a generates a world prospect, i.e. a probability function over worlds. Let us denote it by
 ${P_a}$
. The probability of a world
 $(x,v)$
is
 ${P_a}(x,v) = a(x)Pr(v)$
, the product of the probabilities of x and v.
To define our general expectational theory, we need a general notion of value prospect. A general value prospect is based on a general degree of ex-post-ness: it conditionalizes on a general information. Formally, for any option
 $a \in X$
and information
 $I \subseteq X \times {\cal V}$
(of non-zero probability
 ${P_a}(I)$
), the value prospect of a given I is the value prospect
 ${p_{a|I}}$
such that the probability of a value level
 $$k \in \mathbb R$$
is the probability that a results in value
 $k$
given I:
 $${p_{a|I}}(k) = {\rm{probability}}{\mkern 1mu} \;{\rm{of\;final}}\;{\mkern 1mu} {\rm{value}}\;{\mkern 1mu} k{\mkern 1mu} \;{\rm{given}}{\mkern 1mu} \;I = {{{\rm{prob}}.\,\,{\rm{of}}\,[I \,{\mkern 1mu} {\rm{final}}{\mkern 1mu} {\rm{value}}\,{\mkern 1mu} k]} \over {{\rm{prob}}.\,\,{\rm{of\ }}{\mkern 1mu} I}} \\ = {{{P_a}(\{ (x,v) \in I:v(x) = k\} )} \over {{P_a}(I)}}.$$
Our four earlier notions of value prospect are special cases, obtained for special information:
Proposition 1
The value prospect
 ${p_{a|I}}$
of an option
 $a \in A$
given an information
 $I \subseteq X \times {\cal V}$
(of non-zero probability
 ${P_a}(I)$
) coincides with the
-
ex-ante value prospect
${p_a}$
if
$I = X \times {\cal V}$
(no information),
-
ex-post value prospect
${p_{x,v}}$
if
$I = \{ (x,v)\} $
(information of a full world
$(x,v)$
),
-
normatively ex-post value prospect
${p_{a,v}}$
if
$I = X \times \{ v\} $
(information of a valuation v),
-
empirically ex-post value prospect
${p_x}$
if
$I = \{ x\} \times {\cal V}$
(information of an empirical outcome x).


Recall that each valuation v in
 ${\cal V}$
can evaluate not just options, but (derivatively) also value prospects. So we can form
 $v({p_{a|I}})$
, which tells how valuable v finds the prospect of option a given I. We can call
 $v({p_{a|I}})$
a’s value given I or ex-I value, according to v.
An expectational theory reasons ex-post with regard to some type of information. A type of information is represented by an information partition: a partition
 ${\cal I}$
of the set
 $X \times {\cal V}$
of empirical-normative worlds.
 ${\cal I}$
contains those information I on which the reasoner conditionalizes when conceptualizing options as prospects. As such,
 ${\cal I}$
defines a degree of ex-post-ness of reasoning. Each reasoning mode draws on some partition
 ${\cal I}$
. The four salient special cases are:
-
Fully ex-post reasoning draws on the finest information partition,
${\cal I} = \{ \{ (x,v)\} :(x,v) \in X \times {\cal V}\} $
. -
Fully ex-ante reasoning draws on the coarsest partition,
${\cal I} = \{ X \times {\cal V}\} $
. -
Normatively ex-post reasoning draws on the partition into ‘valuation events’,
${\cal I} = \{ X \times \{ v\} :v \in {\cal V}\} $
. -
Empirically ex-post reasoning draws on the partition into ‘outcome events’,
${\cal I} = \{ \{ x\} \times {\cal V}:x \in X\} $
.


Each information partition
 ${\cal I}$
– each degree of ex-post reasoning – determines an expectational theory, which evaluates options by the expected value (across empirical-normative worlds
 $(x,v)$
) of the prospect given
 ${\cal I}$
. Formally:
Ex-
 ${\cal I}$
Expectationalism (‘
 $E{V_{\cal I}}$
’): The meta-value of an option
 $a \in A$
is the expected value of the prospect given
 ${\cal I}$
or expected ex-
 ${\cal I}$
value:
Footnote 22
 $E{V_{\cal I}}(a) = \sum\limits_{I \in \cal I} {P_a}(I)v(p_{a|I}) = \sum\limits_{(x,v) \in X \times {\cal V}} \underbrace {a(x)Pr(v)}_{{\rm{prob}} {\rm{.\,of}}(x,v)}v({p_{a|{\cal I}(x,v)}})$
where
 ${\cal I}(x,v)$
is the information in an empirical-normative world
 $(x,v)$
, i.e. the
 $I \in {\cal I}$
containing
 $(x,v)$
.
We can now define ‘Expectationalism’ as a general approach or type of theory:
Expectationalism:
Meta-value is given by
 $\underline {{{some}}} $
expectational theory, i.e. by Ex-
 ${\cal I}$
Expectationalism for
 $\underline {{{some}}} $
information type
 ${\cal I}$
(some partition
 ${\cal I}$
of
 $X \times {\cal V}$
).
Our four earlier theories are special cases, obtained using particular information types, i.e. by presupposing particular degrees of ex-post reasoning:
Theorem 2
Ex-
 ${\cal I}$
Expectationalism coincides with
-
Ex-Ante Expectationalism if
${\cal I} = \{ X \times {\cal V}\} $
(no information),
-
Ex-Post Expectationalism if
${\cal I} = \{ \{ (x,v)\} :(x,v) \in X \times {\cal V}\} $
(full information),
-
Standard Expectationalism if
${\cal I} = \{ X \times \{ v\} :v \in {\cal V}\} $
(normative information),
-
Reverse Expectationalism if
${\cal I} = \{ \{ x\} \times {\cal V}:x \in X\} $
(empirical information).


Are there any circumstances under which it becomes irrelevant how you reason? That is, can it happen that all degrees of ex-post reasoning yield the same expectational theory, hence the same evaluation of options, albeit through different procedures? This question obviously matters. If all reasoning modes were extensionally equivalent, then you could reason as you wish or find easiest. The question has a sharp answer:
Theorem 3
All expectational theories
 $E{V_{\cal I}}$
coincide (i.e. your reasoning mode has no effect)
 $\underline {{{if}}\,{{and}}\,{{only}}\,{{if}}} $
you are certain that value is of vNM type, i.e.
 $Pr(v) = 0$
for all non-vNM-type valuations v in
 ${\cal V}$
.
Recall that a valuation is of vNM-type if the value of any option is the expected value of its outcome (see section 2). Some scholars have argued that correct value is of vNM type, and many modellers routinely assume value is of vNM type for technical simplicity. But few people (if anyone at all) will be utterly certain that correct value is of vNM type. These few people can safely reason at any level of ex-post-ness they wish: their reasoning mode does not affect the resulting judgements by Theorem 3. But anyone who entertains at least some doubt that value is of vNM type faces the hard choice between expectational theories, hence between reasoning modes.
8. Conclusion
Expectationalism is an interesting approach when facing normative and possibly empirical uncertainty – but this approach is broader and less unique than believed so far. For one, since the competing valuations need not be of vNM-type, Expectationalism may depart from Harsanyi’s expectational doctrine for choice in the original position, formally reinterpreted as choice under normative uncertainty. For another, more than one expectational response to one’s normative uncertainty is possible. The various expectational theories differ ethically, by reaching different evaluations; procedurally, by using different reasoning; and risk-attitudinally, by taking different attitudes towards empirical as well as normative risk.
But all theories take the expected value of some type of prospect. At the two ends of the spectrum, Ex-Ante and Ex-Post Expectationalism respectively take the expected value of the ex-ante or ex-post prospect, hence reason from the perspective before or after resolution of any uncertainty (empirical or normative). Standard Expectationalism lies in between: it takes the expected value of the option itself, thereby effectively reasoning from an empirically ex-ante, but normatively ex-post perspective. Reverse Expectationalism does the opposite: it reasons empirically ex-post, but normatively ex-ante. The four mentioned theories stand out as salient, but they are just examples. In general, to any type of information (technically, to any ‘information partition’ of the set of empirical-normative worlds) corresponds an expectational theory, which reasons ex-post relative to this information.
The classical question ‘Expectationalism or not?’ should therefore be complemented by another pressing question: ‘Expected value of what?’. The problem of deciding between versions of Expectationalism might prove to be as difficult as the classic problem of deciding between ex-ante and ex-post versions of egalitarianism.
Acknowledgements
The paper has significantly evolved since its 2018 version. We are very grateful for generous suggestions by colleagues and referees. Franz Dietrich acknowledges support by the French National Research Agency through three grants (ANR-17-CE26-0003, ANR-16-FRAL-0010 and ANR-17-EURE-0001). Brian Jabarian acknowledges support by the Calouste Gulbenkian Foundation under a Global Excellence Scholarship, Paris School of Economics, and Sorbonne Economics Centre, and he thanks The Federmann Center and The CMPP at The Hebrew University of Jerusalem for their kind hospitality in summer 2018.
Franz Dietrich is Professor at Paris School of Economics and CNRS, following an interdisciplinary career with a PhD in mathematics (Oxford) and positions in philosophy or economics across Europe. His research between philosophy and economics addresses foundational and methodological topics around human agents and groups, including rationality, reason-based choice, preference change, reasoning, unawareness, moral philosophy, logic, democratic theory, and the aggregation of judgements, probabilistic beliefs or preferences. Additional information is available on his homepage at www.franzdietrich.net.
Brian Jabarian is a PhD candidate in philosophy at the University of Paris 1 Panthéon-Sorbonne, with a two-year stay in the Department of Economics at Princeton University. He works in philosophy of science, ethics, behavioural and experimental economics. He focuses on normative uncertainty and explores its philosophical foundations, economic dimensions and political implications.
Appendix: Proofs
Proof of Theorem 1. Let
 $a \in X$
. Firstly,
 $E{V_{ante}}(a) = \sum\limits_{v \in {\cal V}} Pr(v)v({p_a}) = \sum\limits_{v \in {\cal V}} Pr(v)v({p_a})\sum\limits_{x \in X} a(x) = \sum\limits_{(x,v) \in X \times {\cal V}} a(x)Pr(v)v({p_a}),$
where the second equality holds as
 $\sum\nolimits_{x \in X} a(x) = 1$
. Secondly,
 $E{V_{stan}}(a) = \sum\limits_{v \in {\cal V}} Pr(v)v(a) = \sum\limits_{v \in {\cal V}} Pr(v)v({p_{a,v}})$
 $ = \sum\limits_{v \in {\cal V}} Pr(v)v({p_{a,v}})\sum\limits_{x \in X} a(x) = \sum\limits_{(x,v) \in X \times {\cal V}} a(x)Pr(v)v({p_{a,v}}),$
where the second equality holds because
 $v({p_{a,x}}) = v(a)$
, and the third because
 $\sum\nolimits_{x \in X} a(x) = 1$
. Thirdly, the expression for
 $E{V_{rev}}(a)$
holds by definition. Finally,
 $${EV_{post}}(a) = \sum\limits_{(x,v) \in X \times {\cal V}} {a(x)Pr(v)} \,\underbrace {v(x)}_{ = v(\,p_{x.v})} = \sum\limits_{(x,v) \in \,X \times {\cal V}} {a(x) Pr (v)v(p_{x,v})}.$$
Proof of Proposition 1. Consider an option
 $a \in A$
and an information
 $I \subseteq X \times {\cal V}$
such that
 ${P_a}(I) \ne 0$
. As our definitions easily imply, if
 $I = X \times {\cal V}$
then
 ${p_{a|I}} = {p_a}$
, while if
 $I = \{ (x,v)\} $
where
 $(x,v) \in X \times {\cal V}$
then
 ${p_{a|I}} = {p_{x,v}}$
. If
 $I = X \times \{ v\} $
where
 $v \in {\cal V}$
, then
 ${p_{a|I}} = {p_{a,v}}$
because for all
 $$k \in \mathbb R$$
 $${p_{a|I}}(k) = {{{P_a}(\{ x \in X:v(x) = k\} \times \{ v\} )} \over {Pr(v)}} = {{a(\{ x \in X:v(x) = k\} )Pr(v)} \over {Pr(v)}}$$
 $ = a(\{ x \in X:v(x) = k\} ) = \sum\limits_{x \in X:v(x) = k} a(x) = {p_{a,v}}(k).$
Finally, if
 $I = \{ x\} \times {\cal V}$
where
 $x \in X$
, then
 ${p_{a|I}} = {p_x}$
because for all
 $$k \in \mathbb R$$
 $${p_{a|I}}(k) = {{{P_a}(\{ x\} \times \{ v \in {\cal V}:v(x) = k\} )} \over {a(x)}} = {{a(x)Pr(\{ v \in {\cal V}:v(x) = k\} )} \over {a(x)}} = Pr(\{ v \in {\cal V}:v(x) = k\} )$$
 $$= \sum\limits_{v \in {\cal V}:v(x) = k} \ Pr(v) = {p_x}(k).$$
Proof of Theorem 2. Regarding
 $E{V_{ante}}$
, for each option
 $a \in A$
 $E{V_{ante}}(a) = \sum\limits_{(x,v) \in X \times {\cal V}} a(x)Pr(v)v({p_a}) = E{V_{\cal I}}(a)\,{\rm{for}}\,{\cal I} = \{ X \times {\cal V}\},$
where the first identity holds by Theorem 1 and the second identity holds because by Proposition 1 we can replace
 ${p_a}$
by
 ${p_{a,X \times {\cal V}}} = {p_{a|{\cal I}(x,v)}}$
. Analogously, for each
 $a \in A$
 $E{V_{stan}}(a) = \sum\limits_{(x,v) \in X \times {\cal V}} a(x)Pr(v)v(\underbrace {{p_a}}_{{p_{a,X \times \{ v\} }}}) = E{V_{\cal I}}(a)\,{\rm{for}}\,{\cal I} = \{ X \times \{ v\} :v \in {\cal V}\} $
 $E{V_{rev}}(a) = \sum\limits_{(x,v) \in X \times {\cal V}} a(x)Pr(v)v(\underbrace {{p_x}}_{{p_{a,\{ x\} \times {\cal V}}}}) = E{V_{\cal I}}(a)\,{\rm{for}}\,{\cal I} = \{ \{ x\} \times {\cal V}:x \in X\} $
 $E{V_{post}}(a) = \sum\limits_{(x,v) \in X \times {\cal V}} a(x)Pr(v)v(\underbrace {{p_{x,v}}}_{{p_{a,\{ (x,v)\} }}}) = E{V_{\cal I}}(a)\,{\rm{for}}\,{\cal I} = \{ \{ (x,v)\} :(x,v) \in X \times {\cal V}\} ,$
where on each line the two identities use Theorem 1 and Proposition 1, respectively.
The proof of Theorem 3 begins with a lemma.
Lemma 1
A valuation
 $v \in {\cal V}$
is of vNM type if and only if it evaluates value prospects by their expectation, i.e.
 $v(p) = Exp(p)\,(=\sum\limits_{k \in \mathbb R} p (k)k)$
for all value prospects p.
Proof. 1. First, let
 $v \in {\cal V}$
be of vNM type. We fix a value prospect p and prove that
 $v(p) = Exp(p)$
. Pick an option
 $a \in A$
such that
 ${p_{a,v}} = p$
. We have
 $$Exp(p) = \sum\limits_{k \in \mathbb R} k p(k) = \sum\limits_{k \in \mathbb R} k \sum\limits_{x \in X:v(x) = k} a (x) = \sum\limits_{k \in \mathbb R} {\sum\limits_{x \in X:v(x) = k} a } (x)k = \sum\limits_{x \in X} a (x)v(x),$$
where the second equality uses that
 $p(k) = {p_{a,v}}(k) = \sum\nolimits_{x \in X:v(x) = k} a(x)$
, and the third and fourth equalities follow by reordering terms. The last expression equals
 $v(a)$
as v is of vNM-type, which equals
 $v(p)$
by choice of a.
2. Conversely, assume
 $v(p) = Exp(p)$
for all value prospects p. We let
 $a \in A$
and show
 $v(a) = \sum\nolimits_{x \in X} a(x)v(x)$
. Defining p as
 ${p_{a,v}}$
, we have
 $Exp(p) = \sum\nolimits_{x \in X} a(x)v(x)$
, as in part 1 of the proof. So it remains to show
 $v(a) = Exp(p)$
. This holds because
 $v(a) = v(p)$
(as
 $p = {p_{a,v}}$
) and
 $v(p) = Exp(p)$
. ▪
Proof Theorem 3. We shall use standard measure-theoretic arguments.
1. Assume
 $Pr(v) = 0$
for all non-vNM-type valuations
 $v \in {\cal V}$
. Fix an option
 $a \in A$
. We show that
 $E{V_{\cal I}}(a)$
is independent of the information partition
 ${\cal I}$
. On the set of worlds
 $X \times {\cal V}$
, consider the probability distribution
 ${P_a}$
(the world prospect of a) and the random variables
 ${\bf{x}}:X \times {\cal V} \to X,(x,v)\ \mapsto\ x$
and
 ${\bf{v}}:X \times {\cal V} \to {\cal V},(x,v)\ \mapsto\ v$
. Combining these variables yields a third variable,
 ${\bf{v}}({\bf{x}})$
, given by
 $X \times {\cal V} \to \mathbb R,(x,v)\ \mapsto\ v(x)$
and representing resulting value. The value prospect
 ${p_a}$
equals the distribution of the variable
 ${\bf{v}}({\bf{x}})$
, and so its expectation is
 $Exp({p_a}) = Ex{p_{{P_a}}}({\bf{v}}({\bf{x}}))$
. More generally, for any information
 $I \subseteq X \times {\cal V}$
(such that
 ${P_a}(I) \ne 0$
), the value prospect
 ${p_{a|I}}$
equals the distribution of
 ${\bf{v}}({\bf{x}})$
conditional on I, and so
 $Exp({p_{a|I}}) = Ex{p_{{P_a}}}({\bf{v}}({\bf{x}})|I)$
. Now for any information partition
 ${\cal I}$
(identifiable with the variable mapping
 $(x,v)$
to
 ${\cal I}(x,v)$
),
 $$\matrix{ {E{V_I}(a)} = {Ex{p_{{P_a}}}\,({\bf{v}}({p_{a|I}}))} {{\rm{by}}\;{\mkern 1mu} {\rm{definition}}} \cr {} = {Ex{p_{{P_a}}}\,(Exp({p_{a|I}}))} {{\rm{by}}{\mkern 1mu} \;{\rm{Lemma}}{\mkern 1mu} {\rm{1}}} \cr {} = {Ex{p_{{P_a}}}\,(Ex{p_{{P_a}}}({\bf{v}}({\bf{x}})|I))} {{\rm{as}}\; Exp({p_{a|I}}) = Ex{p_{{P_a}}}({\bf{v}}({\bf{x}})|I)} \cr {} = {Ex{p_{{P_a}\,}}({\bf{v}}({\bf{x}}))} {{\rm{by}}\;{\mkern 1mu} {\rm{the}}{\mkern 1mu} \;{\rm{law}}\;{\mkern 1mu} {\rm{of}}\,{\rm{iterated}}\;{\rm{expectations}},} \cr } $$
where Lemma 1 is applicable as valuations generated by
 ${\bf{v}}$
(with non-zero probability) are of vNM type. The last expression for
 $E{V_{\cal I}}(a)$
shows that
 $E{V_{\cal I}}(a)$
is independent of
 ${\cal I}$
.
2. Conversely, let
 ${\cal V}$
contain a non-vNM-type valuation
 $\tilde v$
of probability
 $Pr(\tilde v) \ne 0$
. As
 $\tilde v$
is not of vNM type, we may pick an option
 $a \in A$
such that
 $\tilde v(a) \ne \sum\nolimits_{x \in X} a(x)\tilde v(x).$
Denote the information of valuation
 $\tilde v$
by
 $I = X \times \{ \tilde v\} $
. We construct two information partitions
 ${{\cal I}_1}$
and
 ${{\cal I}_2}$
for which
 $E{V_{{{\cal I}_1}}}(a) \ne E{V_{{{\cal I}_2}}}(a)$
. Let
 ${{\cal I}_1}$
and
 ${{\cal I}_2}$
coincide outside I and be, respectively, maximally coarse or maximally fine within I. So
 ${{\cal I}_1} = {{\cal I}_0} \cup \{ I\} $
and
 ${{\cal I}_2} = {{\cal I}_0} \cup \{ \{ (x,v)\} :(x,v) \in I\} $
, for some partition
 ${{\cal I}_0}$
of
 $(X \times {\cal V})\backslash I$
. Thus
 $E{V_{{{\cal I}_1}}}(a) = S + {S_1}$
and
 $E{V_{{{\cal I}_2}}}(a) = S + {S_2}$
where
 $S = \sum\limits_{(x,v) \in (X \times {\cal V})\backslash I} a(x)Pr(v)v({p_{a|{{\cal I}_0}(x,v)}}))$
 ${S_1} = \sum\limits_{(x,v) \in I} a(x)Pr(v)v({p_{a|{{\cal I}_1}(x,v)}})) = \sum\limits_{x \in X} a(x)Pr(\tilde v)\tilde v({p_{a|I}})$
 ${S_2} = \sum\limits_{(x,v) \in I} a(x)Pr(v)v({p_{a|{{\cal I}_2}(x,v)}})) = \sum\limits_{x \in X} a(x)Pr(\tilde v)\tilde v({p_{a,\{ (x,\tilde v)\} }}).$
By Proposition 1,
 ${p_{a|I}} = {p_{a,\tilde v}}$
and
 ${p_{a,\{ (x,\tilde v)\} }} = {p_{x,\tilde v}}$
. So
 $\tilde v({p_{a|I}}) = \tilde v({p_{a,\tilde v}}) = \tilde v(a)$
and
 $\tilde v({p_{a,\{ (x,\tilde v)\} }}) = \tilde v({p_{x,\tilde v}}) = \tilde v(x)$
. Thus
 ${S_1} = \sum\limits_{x \in X} a(x)Pr(\tilde v)\tilde v(a) = Pr(\tilde v)\tilde v(a)\sum\limits_{x \in X} a(x) = Pr(\tilde v)\tilde v(a)$
 ${S_2} = \sum\limits_{x \in X} a(x)Pr(\tilde v)\tilde v(x) = Pr(\tilde v)\sum\limits_{x \in X} a(x)\tilde v(x).$
So
 $E{V_{{{\cal I}_1}}}(a) - E{V_{{{\cal I}_2}}}(a) = {S_1} - {S_2} = Pr(\tilde v)\left( {\tilde v(a) - \sum\limits_{x \in X} a(x)\tilde v(x)} \right).$
As
 $Pr(\tilde v) \ne 0$
and
 $\tilde v(a) \ne \sum\nolimits_{x \in X} a(x)\tilde v(x)$
, we deduce
 $E{V_{{{\cal I}_1}}}(a) \ne E{V_{{{\cal I}_2}}}(a).$