


1. Introduction
The Kochen-Specker (KS) theorem establishes that not all measurement outcomes predicted by quantum mechanics can result from detecting hypothetically predetermined values of the observables. Recently, there have been debates whether or not this result is relevant for inaccurate measurements (Pitowsky Reference Pitowsky1985; Meyer Reference Meyer1999; Kent Reference Kent1999; Clifton and Kent Reference Clifton and Kent2000; Cabello and García-Alcaine Reference Cabello and García-Alcaine1998; Cabello Reference Cabello2002; Simon et al. Reference Simon, Zukowski, Weinfurter and Zeilinger2000; Simon et al. Reference Simon, Bruckner and Zeilinger2001; Mermin Reference Mermin1999; Havlicek et al. Reference Havlicek, Krenn, Summhammer and Svozil2001; Appleby Reference Appleby2001). This debate was fueled by claims of Meyer (Reference Meyer1999), Kent (Reference Kent1999), and Clifton and Kent (Reference Clifton and Kent2000)—for short MKC—that for finite precision measurements the KS-theorem is irrelevant.
Infinite precision is crucial to the KS-argument because non-contextuality can be exploited only if two measurements intended to pick out the same observable as member of two different maximal sets pick out exactly the same observable. MKC show that non-contextual hidden variable models can be constructed if we relax the assumption of infinite precision by an arbitrarily small anmount. In these models it is not exactly the observables in a KS-set that are assigned non-contextual values, but observables arbirtrarily close to them. In fact it is possible to assign values to a dense set of observables, namely to the spin observables in directions with rational coordinates.
So the hidden-variable theorist is free to adopt the hypothesis that due to some apparatus misalignment, instead of the intended observable, he measures another observable, which cannot be distinguished from the intended observable by a measurement of finite precision. MKC show that the results of these finite precision measurements can be explained by a non-contextual hidden-variable model.
In Section 2 we will construct POV-observables representing finite precision measurements of a spin 1 particle. These POV-observables are constructed so as to yield exactly the statistics of outcomes associated with the intended measurement directions. Section 3 reviews the KS-theorem obtained in Breuer Reference Breuer2002 for these unsharp spin observables. Finally, in Section 4 I establish the new result.
2. Finite Precision Measurements of Spin 1 Observables
An experimenter who wants to measure spin in a direction n will have a procedure for trying to do this as exactly as possible. Simon et al. (Reference Simon, Bruckner and Zeilinger2001) refer to this procedure by saying he sets the “control switch” of his apparatus to the position n. The switch position is all the observer knows about. In an operational sense, the physical observable measured is entirely determined by the switch position. However, there will usually be some degrees of freedom of the apparatus which the experimenter cannot control. This results in an apparatus misalignment of which the experimenter is not aware. If he were aware of it he would correct it. Not being aware of the misalignment he interprets the outcome produced by the misaligned apparatus as result of an experiment without misalignment. Unlike in Simon et al. Reference Simon, Bruckner and Zeilinger2001, in this paper the misalignment will not be described by associating hidden variables to the apparatus. Instead, the effects of the misalignment are described by unsharp spin observables.
The sharp spin 1 observables in x, y, and z direction are given by the three three-dimensional Pauli matrices S x, S y, S z, each of which has eigenvalues 1, 0, and −1. For example S z is given by

Denote the eigenvectors of the spin matrix S z by ψz,1, ψz,0, ψz,−1 and the corresponding eigenprojectors by P z,i := ∣ψz,i〉〈ψz,i∣. The P z,i are sharp spin properties. Explicitly,

Similar notation will be used for the x- and the y-axes.
For an arbitrary direction n the sharp spin 1 observable is S n := n ⋅ S, where S is the Pauli vector (S x, S y, S z). S n also has eigenvalues 1, 0, and −1. Let ψn,i and P n,i be the eigenstates and eigenprojectors of S n corresponding to the eigenvalues i=1,0,−1. The sharp spin observable S n in direction n can be represented as a projection valued (PV)-measure on the value space Ω={1,0,−1}, which associates to each element i of the value space Ω the projector P n,i.
Now assume we are not sure that we actually measure the spin in the intended direction n. We only know that the directions m of actual spin measurements are distributed with a density w n,∊(m) around n. ψ describes the inaccuracy of the experiment. The probability that such an imprecisely specified measurement yields an outcome +1 when the system is prepared in some pure state ψ is

where dΩ is the Lesbesgue-measure of the sphere. Defining

the probability of outcome i can be written as

From (3) it is obvious that the
 $F^{\boldsymbol{n},\epsilon }$
are positive self-adjoint operators satisfying
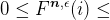 $0\leq F^{\boldsymbol{n},\epsilon }(i) \leq $
. But they are not projectors since
 $F^{\boldsymbol{n},\epsilon }(i) \neq F^{\boldsymbol{n},\epsilon }(i) ^{2}$
. The F n,∊(i) form a resolution of the identity,

which follows from (3) and
 $P_{\boldsymbol{n},1}+P_{\boldsymbol{n},0}+P_{\boldsymbol{n},-1}=$
. Thus we have a positive operator valued (POV) measure which associates to each element i of the value space
 $\Omega =\{ 1,0,-1\} $
the positive operator F n,∊(i). POV-measures are the standard tool for describing realistic experiments (Busch et al. Reference Busch, Grabowski and Lahti1995; Holevo Reference Holevo1982).
Proposition 1. If the distributions w n,∊ of apparatus misalignments transforms covariantly under rotations,
 $w_{R\boldsymbol{n},\epsilon }(R\boldsymbol{m}) =w_{\boldsymbol{n},\epsilon }(\boldsymbol{m}) $
, then the unsharp spin properities F n,∊ transform covariantly under rotations,
where D 1 is the spin 1-representation of the rotation group and R denotes an arbitrary rotation in three-dimensional space.


A proof of this Proposition can be found in the Appendix.
Since the F n,∊(i) transform covariantly under rotations, they are angular momentum properties and can be regarded as spin properties with the same justification as the sharp spin properties P n,i. This is in line with Weyl's idea of defining observables by their transformation properties under some kinematic group.
Proposition 2. If the distribution w n,∊ of measurement errors transforms covariantly under rotations,
$w_{R\boldsymbol{n},\epsilon }(R\boldsymbol{m}) =w_{\boldsymbol{n},\epsilon }(\boldsymbol{m}) $
, then every eigenvector of the sharp spin properties
$P_{\boldsymbol{m}i}$
is also an eigenvector of the unsharp spin properties F n,∊(i). Since the sharp spin properties
$\{ P_{\boldsymbol{n},i}\} _{i=1,0,-1}$
have simultaneous eigenvectors and commute, this is also the case for the unsharp spin properties
$\{ F^{\boldsymbol{n},\epsilon }(i) \} _{i=1,0,-1}$
.


A proof of this can be found in the Appendix.
Proposition 3. The eigenvalues of the unsharp spin properties F n,∊(i) are in the set {α1,…, α4},
which are all between 0 and 1. More precisely, each F n,∊(i) has eigenvalues (α1, α2, α3) or (α2 twice, α4). The eigenvalues of each F n,∊(i) add up to 1.

A proof can be found in the Appendix.
To give an explicit example, assume that the spin directions actually measured are uniformly distributed over C(n, ∊), the set of directions deviating from n by less than an angle ∊. Denoting by A the area of C(n, ∊) on the unit sphere, w n,∊ is 1/A times the characteristic function of C(n, ∊). The F z,∊(i) are diagonal matrices of the form (9) with

Observe that, as the measurement inaccuracy ∊ tends to zero, two eigenvalues (α2 resp. α3) of each F z,∊(i) go to zero, one eigenvalue (α1 resp. α4) goes to one. The unsharp spin properties F z,∊(i) converge to the sharp spin properties P z,i.
3. Review of a Kochen-Specker Theorem for Unsharp Spin 1 Observables
Determining the result i∊{1,0,−1} of a sharp spin measurement in direction n is picking one of the sharp spin properties {P n,i}i=1,0,−1 and assigning it the truth value 1. Since the sharp spin properties are projectors P n,i := ∣ψn,i〉〈ψn,i∣ they can be identified with the ray ψn,i. So, assigning the value 1 to one of the P n,i and the value 0 to the other two, is equivalent to assigning the colour T (true) to one of the rays ψn,i and the colour F (false) to the two other rays. The traditional KS-proofs show that for certain sets of directions this colouring rule cannot be satisfied.
Determining the result i∊{1,0,−1} of an unsharp spin measurement in direction n is picking one of the unsharp spin properties {F n,∊(i)}i=1,0,−1. But the unsharp spin properties are not projectors and therefore cannot readily be identified with rays. To arrive at a colouring rule for rays one can proceed in a different way (Breuer Reference Breuer2002). Fix some unsharpness tolerance 0.5>δ≥0.
Definition 1. If the outcome of a spin measurement with some intended direction n is some i∊{1,0,−1}, then the ray of the eigenvector of F n, ∊(i) corresponding to an eigenvalue larger or equal to 1−δ gets colour AT (almost true), and the rays of eigenvectors corresponding to eigenvalues smaller or equal to δ get colour AF (almost false). (Rays corresponding to some eigenvalue between δ and 1−δ are not assigned any colour.)
δ>0 is an unsharpness tolerance below which an eigenvalue counts as “almost zero.” An eigenvalue above 1−δ counts as “almost one.” The exact level of δ is a matter of taste, and our results do not depend on the exact level. But certainly δ should be smaller than 0.5, since otherwise some values could simultaneously be counted as almost zero and almost one.
In Proposition 2 we have seen that for a fixed intended measurement direction n the {F n,∊(i)}i=1,0,−1 have the same eigenvectors. If the measurement inaccuracy is sufficiently small—or to be more precise: if the density w n, ∊(m) of apparatus misalignments has enough probability mass sufficiently close to the intended measurement direction n—then the eigenvalues α1 and α4 in eqs. (6) will be larger than 1−δ, whereas α2 and α3 will be smaller than δ. If this is the case, exactly one ray in the orthogonal triad of eigenvectors of the F n,∊(i) will get colour AT, and two rays will get colour AF.
For example if we assume apparatus misalignments to be uniformly distributed over the set of directions deviating by less than an angle ∊, and if we choose δ=0.1, then we can calculate from (7) that for ∊ smaller than 0.459=26.3° the eigenvalues α1, α4 will be larger than 0.9, while α2, α3 will be smaller than 0.1. So for δ=0.1, if the measurement inaccuracy ∊ is smaller than 0.459, then in all orthogonal tripods one ray will be coloured AT and two rays will be coloured AF.
An example: Assume that one intends to measure spin in direction z and result 0 occurs. This means that the unsharp spin property F z,∊(0) is realised, whereas F z,∊(1) and F z,∊(−1) are not realised. Accordingly we assign the colour AT to the ray (0,1,0), which, by (9b), is the eigenvector of F z,∊(0) with eigenvalue close to 1. To (1,0,0) and (0,0,1) we assign the colour AF because they are eigenvectors of F z,∊(0) with eigenvalue close to 0. Had the outcome been +1, we would have assigned AT to (1,0,0) and AF to (0,1,0) and to (0,0,1).
One ray can be eigenvector of spin properties F n,∊(i), F m,∊(i) in different directions n, m. Non-contextuality of the hidden variable-model implies that such a ray is assigned a unique colour. Now the KS-theorem for unsharp spin observables follows in exactly the same way as the one for sharp observables (for an exposition of the traditional KS-theorem see Held (Reference Held2000)). In every orthogonal tripod one of the rays is constrained to get the colour AT, the other two rays get AF. For the KS-sets (Kochen and Specker Reference Kochen and Specker1967; Peres Reference Peres1995; Zimba and Penrose Reference Zimba and Penrose1993) of tripods such a colouring is impossible. Thus we arrive at
Theorem 1. For any unsharpness tolerance 0.5>δ≥0,if in an unsharp spin 1 measurement
(1) the densities of apparatus misalignments transform covariantly, i.e. if
$w_{R\boldsymbol{n},\epsilon }(R\boldsymbol{m}) =\,w_{\boldsymbol{n},\epsilon }(\boldsymbol{m}) $
for all rotations R, and(2) the measurement inaccuracy described by the densities
$w_{\boldsymbol{n},\epsilon }(\boldsymbol{m}) $
of apparatus misalignments is so small that in eqs. (6) α1 and α4 are larger or equal to 1−δ, while α2 and α3 are smaller or equal to δ, then not all the unsharp spin observables in a KS-set of directions can consistently be assigned approximate truth-values in a non-contextual way.


4. A New Kochen-Specker Theorem for Unsharp Spin 1 Observables
An alternative way to translate the predetermination of an outcome into a colouring would be this:
Definition 2. If the outcome of an inaccurate spin measurement with some intended direction n is some i∊{1,0,−1}, then each eigenvector of F n,∊(i) gets the colour {α1, α2, α3, α4} determined by its eigenvalue.
Non-contextuality of the hidden variable-model implies that such a ray is assigned a unique colour.
For example: Consider a spin measurement with intended direction z. The unsharp spin properties in direction z are given by equations (9) . From these equations we read off that if the outcome i=1 occurs, (1,0,0) gets the colour α1, (0,1,0) gets α2, and (0,0,1) gets α3. If i=0 occurs, (1,0,0) and (0,0,1) get α2 and (0,1,0) gets colour α4. If the outcome i=−1 occurs, (1,0,0) gets the colour α3, (0,1,0) gets α2, and (0,0,1) gets α1.
Conversely, one can read the measurement result off the colouring of the triple in the following way. The result of a measurement in direction n is determined by the colours of the triple of eigenvectors of any of the F n,∊(i). (By Proposition 2, F n,∊(1), F n,∊(0), F n,∊(−1) all have the same eigenvectors.) By the colouring rule of Definition 2 and by Proposition 3, exactly one vector in the triple gets colour α1 or α4, and the two other vectors get colours α2 or α3. The vector with colour α1 or α4 determines as result i∊{1,0,−1} of the spin measurement in direction n exactly the i for which this vector is an eigenvector of F n,∊(i) with eigenvalue α1 or α4. This works as long as both α1 and α4 are different from both α2 and α3.
For example, the results of a spin-z measurement are determined by the colours of the vectors (1,0,0), (0,1,0), (0,0,1). If (1,0,0) gets colour α1 or α4, this determines result i=1 because (1,0,0) is an eigenvector of F n,∊(1) with eigenvalue α1. Neither F n,∊(0) nor F n,∊(−1) have (1,0,0) as an eigenvector with eigenvalue α1 or α4. Similarly, if (0,1,0) gets colour α1 or α4, this determines result i=0 because (0,1,0) is an eigenvector of F n,∊(0) with eigenvalue α4. Neither F n,∊(1) nor F n,∊(−1) have (0,1,0) as an eigenvector with eigenvalue α1 or α4. And if (0,0,1) gets colour α1 or α4, this determines result i=−1 because (0,0,1) is an eigenvector of F n,∊(−1) with eigenvalue α1. Neither F n,∊(0) nor F n,∊(1) have (0,0,1) as an eigenvector with eigenvalue α1 or α4.
Now we are in a position to apply a theorem of Pitowsky (Reference Pitowsky1998, Theorem 4). This theorem says that for every finite set A of non-negative real numbers there is finite subset Γ ⊂ S 2 of directions such that every frame function on Γ with values in A is constant. A frame function on S 2 with weight 1 is a function fulfilling
 $\sum_{k=1}^{3}f(x_{k}) =1$
for every orthonormal basis {x1, x2, x3}.
Let us assume a non-contextual predetermination of unsharp measurement results were possible. The predetermined measurement results in turn determine via the colouring rule of Definition 2 colours for the vectors in a triple. Conversely, as long as both α1 and α4 are different from both α2 and α3, the colours of the rays in an orthogonal triple determine the outcome of the corresponding inaccurate measurement. By Proposition 3 these colours add up to one. Thus the colouring rule gives rise to a frame function with weight one and values in A={α1, α2, α3, α4}. By construction this frame function is not constant on any triple of rays. This contradicts Pitowsky's theorem, which implies that on some finite set Γ of directions every frame function has to be constant. This contradiction refutes the original assumption that a non-contextual predetermination of unsharp measurement results is possible. So we arrive at
Theorem 2. If the densities of apparatus misalignments transform covariantly,
$w_{R\boldsymbol{n},\epsilon }(R\boldsymbol{m}) =w_{\boldsymbol{n},\epsilon }(\boldsymbol{m}) $
, and if the density of misalignments is such that in eqs. (6) both α1 and α4 are different from both α2 and α3, then there is a finite set of intended measurement directions for which not all results of inaccurate measurements can be predetermined in a non-contextual way.

In Meyer's (Reference Meyer1999) model condition (1) of Theorem 1 is not satisfied: According to his model, if we intend to measure spin in a direction n with irrational coordinates, the apparatus is in fact aligned in some direction m with rational coordinates, which is very close to n. Now let R be a rotation by π/4 around an axis orthogonal to m. If w n,∊(m) were rotation covariant, in an experiment designed to measure spin in direction R n the apparatus would actually be aligned in direction R m. But R m cannot have rational coordinates if m has. So R m would not be assigned a colour. Thus Meyer's distribution w n,∊(m) of misalignments cannot not be covariant under all rotations.
Kent (Reference Kent1999) and Clifton and Kent (Reference Clifton and Kent2000) generalise Meyer's argument to unsharp observables. They show that there are non-contextual hidden variable models which recover the quantum probabilities of POV-measurements with arbitrarily small inaccuracy. Reading Theorems 1 and 2 contrapositively we conclude that the apparatus misalignments in their models are not covariant either. This can be checked directly on their model: the countable set of effect operators to which they assign values cannot be mapped onto itself by the uncountable set of maps {D 1(R) · D 1(R)−1 : R ∊ SO(3)}.
In contrast to Theorem 1, Theorem 2 does not rely on the assignment of approximate truth values in Definition 1, which some might consider as ontologically extravagant. Additionally, Theorem 2 is valid under weaker requirements on the measurement inaccuracy. There are very few distributions of misalignments for which either α1 or α4 are equal to either α2 or α3. The condition on the measurement inaccuracy required in Theorem 1 is stronger: whenever the requirement of Theorem 1 is satisfied, i.e., α1 and α4 are strictly larger than 1–0.5, then α2 and α3 both are strictly smaller than 0.5, so that the requirement of Theorem 2 is satisfied.
Appendix
A. Proof of Proposition 1
The sharp spin properties P m,i are angular momentum operators and therefore transform covariantly (Busch et al. Reference Busch, Grabowski and Lahti1995, 70),
Using this and (3) we obtainwhere new coordinates$\boldsymbol{m}\prime =R^{-1}\boldsymbol{m}$
were introduced and the covariance property
$w_{R\boldsymbol{n},\epsilon }(R\boldsymbol{m}) =w_{\boldsymbol{n},\epsilon }(\boldsymbol{m}) $
of the error distribution was exploited. This establishes (5).B. Proof of Proposition 2
We proceed in two steps. In a first step we consider the special case that the intended measurement direction n is the z-direction. The eigenvectors of P z,i are the vectors in the x, y, and z-directions. We will show that the F z,∊(i) have the same eigenvectors.
Using the explicit form of the spin matrices S x, S y, S z, one can calculate the P m,i. For i=1 and m in polar coordinates (θ, φ) it turns out that P m(θ, φ),1 equals
The covariance property of w n,∊ implies that w n,∊ is invariant under rotations around n: If R is a rotation around n, then$w_{n,\epsilon }(Rm) =w_{R^{-1}n,\epsilon }(R^{-1}Rm) =w_{R^{-1}n,\epsilon }(m) =w_{n,\epsilon }(m) $
. Since w z,∊ is invariant under rotations around the z-axis, we can write
$w_{\boldsymbol{z},\epsilon }(\boldsymbol{m}) =w_{\boldsymbol{z},\epsilon }(\boldsymbol{m}(\theta,\phi)) =\thinspace{:}\thinspace w_{\boldsymbol{z},\epsilon }(\theta) $
. Thus we have
Evaluating the integral on the right hand side yields the matrixThereforeSimilarly one can derivewhere the αi are given by (6). The F z,∊(i) are diagonal matrices. Therefore the unit vectors in the x, y, and z-directions are eigenvectors of all F z,∊(i). This finishes the proof of Proposition 2 for the special case n=z.In the second step we consider the general case that we want to measure spin in an arbitrary direction n. First we will show that the eigenvectors of F n,∊(i) are D 1(R)−1x, D 1(R)−1y, D 1(R)−1z, where R is a rotation fulfilling R −1n=z. Using the covariance property (5) and the fact that x, y, z are eigenvectors of the F z,∊(i) we verify F n,∊(i) D 1(R)−1x=D 1(R)−1 F z,∊(i) D 1(R) D 1(R)−1x=D 1(R)−1 F z,∊(i) x=D 1(R)−1 αx=αD 1(R)−1 x, which implies that D 1(R)−1x is an eigenvector of F n,∊(i). Similarly we can check that D 1(R)−1y and D 1(R)−1z are eigenvectors of F n,∊(i). Since F n,∊(i) only has three eigenvectors, D 1(R)−1x, D 1(R)−1y, D 1(R)−1z are the only eigenvectors of F n,∊(i).
Next we will show that D 1(R)−1x, D 1(R)−1y, D 1(R)−1z are the eigenvectors of P n,i. Using the covariance property (8) of the sharp spin observables and the fact that x, y, z are eigenvectors of the P z,i with eigenvalues λ=1,0,−1 we verify P n,i D 1(R)−1x=D 1(R)−1 P n,i D 1(R) D 1(R)−1x=D 1(R)−1 P n,i x=D 1(R)−1 λx=λD 1(R)−1x, which implies that D 1(R)−1x is an eigenvector of P n,i. Similarly we can check that D 1(R)−1y and D 1(R)−1z are eigenvectors of P n,i. Since P n,i only has three eigenvectors, D 1(R)−1x, D 1(R)−1y, D 1(R)−1z are the only eigenvectors of P n,i. Thus the P n,i and the F n,∊(i) all have the same three eigenvectors. This establishes Proposition 2 for the general case.
C. Proof of Proposition 3
By the covariance property (5), the F n,∊(i) have the same eigenvalues as F z,∊(i). The eigenvalues of the F z,∊(i) are the αi of eqs. (6). Obviously, each F z,∊(i) has eigenvalues α1, α2, α3 or α2 (twice) and α4. Taking into account that
$1=\int_{S^{2}}d\Omega (\boldsymbol{m}) w_{\boldsymbol{n},\epsilon }(\boldsymbol{m}) =2\pi \int_{0}^{\pi }d\theta \mathrm{sin}\,w_{\boldsymbol{n},\epsilon }(\theta) $
one easily verifies from (6) that 0≤αi≤1 and α1+α2+α3=1, α2+α4+α2=1.



