1 Introduction
In psychology, the base-rate fallacy refers to the error people commit by ignoring the relative sizes of population subgroups when assessing the likelihood of contingent events involving the subgroups; see Tversky and Kahneman (Reference Spanos1982). Various recent experiments, however, have shown that when the same information is presented to people in terms of ‘natural (relative) frequencies’, the error in reasoning often disappears; see Krämer and Gigerenzer (Reference Krämer and Gigerenzer2005).
In the context of Bayesian reasoning, the base-rate fallacy has been formalized as the error involved when the conditional probability of a hypothesis H given some evidence  —known as the posterior probability—is assessed on the basis of
 without taking account of the prior probability (base rate) of H, P(H). This fallacy stems from the fact that since probability calculus gives the relationship

when evaluating  , the base rates [P(H), P(E)] can be ignored at one's peril.
What is not so apparent is whether frequentist testing, which attaches no probabilities to hypotheses (P(H) is meaningless), is also vulnerable to such a fallacy. Howson (Reference Howson1997, Reference Howson2000) and Achinstein (Reference Achinstein2001, Reference Achinstein, Mayo and Spanos2010), inter alia, contend that frequentist testing, in general, and the severity assessment (Mayo Reference Lehmann1996), in particular, are not just susceptible to this fallacy, they are totally undermined by it.
The main objective of this article is to call into question this claim by demonstrating that the circumstantial case made against frequentist testing and the severity assessment, on the basis of examples like the Harvard Medical School test, is highly misleading. A closer scrutiny of such examples reveals that the reasoning connecting a medical to a statistical test using the false positive and false negative rates as analogous to the type I and type II error probabilities, respectively, is fallacious because it grossly misrepresents frequentist testing. It is argued that such examples have none of the basic features of a proper frequentist test (legitimate hypotheses, test statistics, data, sampling distributions, etc.), and relevant error probabilities are misconstrued as conditional probabilities among events under the guise of false positive and false negative rates. In fact, proper error probabilities are not conditional; they depend crucially on the sample size n, and they are invariably assigned to inference procedures, never to events.
Section 2 presents a brief introduction to frequentist testing, including the severity assessment, with a view to bring out certain crucial features that are either misunderstood or misrepresented by the base-rate fallacy argument. Section 3 revisits this argument with a view to untangle the various confusions pervading this argument and to reveal the fallacious reasoning underlying the charge against error-statistical testing.
2 Frequentist Testing and Error Probabilities
Frequentist statistics, pioneered by Fisher (Reference Fisher1922), is model-based inductive inference that commences with a prespecified statistical model  , in the context of which the observed data
 are viewed as a truly typical realization.
Fisher (Reference Fisher1925, Reference Fisher1934), almost single-handedly, proposed a frequentist theory of optimal estimation, and Neyman and Pearson
(1933) modified Fisher's significance testing to put forward an analogous theory for optimal testing; see Cox and Hinkley (Reference Cox and Hinkley1974).
2.1 The Notion of a Statistical Model
Consider the material experiment of randomly selecting n newborn babies in New York City during 2008, the aim being to pose the substantive question of interest:

Performing the experiment gives rise to a sequence of outcomes: (B, G, G, B, G, … , B). To specify an appropriate statistical model in the context of which this sequence of outcomes can be used to answer the substantive question of interest (2), one needs to embed the material experiment into a statistical model viewed as a purely probabilistic construct.
To that end, one begins by specifying the set of all possible distinct outcomes associated with the above experiment:  . The mathematical formalism of probability theory requires one to define the event space
 (the set of events of interest and related events) to be a field—a set of subsets of
 that is closed under the set theoretic operations of union, intersection, and complementation; see Billingsley
(Reference Billingsley1995). In this example,
 , where
 denotes the impossible event. The next step is to assign probabilities to all events in
 :

An important extension of the formalism based on the probability space  is the notion of a random variable (r.v.): a real-valued function,

The relevant random variable for the above experiment is defined by

This function defines an r.v. relative to  because it satisfies (4):

In this sense  assigns numbers to the elementary events in
 in such a way so as to preserve the original event structure of interest (
 ). This extension is important for bridging the gap between the mathematical formalism
 and the observable stochastic phenomena of interest, since observed data usually come in the form of numbers. The r.v.
 maps the original probability space
 onto the real line in the sense that all the relevant information in
 and (3) is now encapsulated by the Bernoulli density (nonnegative) function:

where  ,
 , and
 .
The material experiment of “randomly selecting n newborns in New York City during 2008 and noting their gender”
can now be framed in the form a stochastic process (an indexed sequence of random variables)  assumed to be Bernoulli, independent, and identically distributed
(BerIID).
Collecting all these pieces together defines the simple Bernoulli model:

assumed to describe an idealized mechanism that gave rise to data  ;
 has transformed the original sequence
 into
 .
In general, a complete description of a statistical model for inference purposes is given in terms of  , the distribution of the sample
 :

where  denotes the parameter space (the set of all possible values of the unknown parameter
 ) and
 , the sample space (the set of all possible values of the sample
 ). The data, generically denoted by
 are viewed as a typical realization of the process specified by (7). Note that r.v.'s like the sample
 are specified in capital letters and realizations like the data
 by the corresponding small letter.
In the case of the simple Bernoulli model, the parameter and sample spaces are  and
 , respectively, and
 simplifies to

where the first equality follows by imposing Independence, the second by imposing IID, and the last by imposing all three assumptions: Bernoulli, IID. In practice, the IID assumptions can and should be tested, vis-à-vis data  , to secure the reliability of the inductive inferences based on
 ; see Spanos (Reference Psillos1999).
Philosophers of science often prefer to hide the “ugliness”
of expressions like (6)
(7)–(8) behind the veil of “technical details” better swept under the carpet. The truth is that dodging this ugliness seriously impairs adequate understanding of frequentist inference. In particular, poor understanding of the pivotal role played by the notion of a statistical model could easily give rise to serious confusions because 
(a) specifies the inductive premises of inference,
(b) delimits legitimate events in terms of an univocal sample space
 ,
(c) assigns probabilities to all legitimate events via
,(d) delimitates what are legitimate hypotheses and/or inferential claims,
(e) identifies the relevant error probabilities in terms of which the optimality and reliability of inference methods are assessed, and
(f) designates what constitute legitimate data
for inference purposes
 ,
 ,
 for inference purposes
Legitimate events are defined in terms of well-behaved (Borel)
functions of the sample  ; formally an event is legitimate when it belongs to the
 -field generated by
 (Billingsley Reference Billingsley1995). Legitimate data come in the form of randomly selected newborns in New York City during 2008. For instance, the information that at St. Jude's Hospital in New York City the ratio of boys to girls during 2008 is 1.07 does not constitute legitimate data in the context of
 in (6) because this information cannot be regarded as comprising generic (IID) observations from the target population; purposeful selection invalidates the IID assumptions.
2.2 Hypothesis Testing
To understand what constitutes legitimate frequentist hypotheses, consider framing the above substantive question of interest (2)—whether the ratio of boys (B) to girls (G) is equal or greater than one—in the context of the simple Bernoulli model.
Since  and
 imply that the ratio is equal to or less than one and bigger than one, respectively, the archetypal Neyman-Pearson (N-P) framing takes the form of the statistical hypotheses:

What renders the hypotheses in (9) legitimate is that (i) they pose questions concerning the underlying statistical data-generating mechanism, (ii) they are framed in terms of the unknown parameter  , and (iii) they are framed in a way that partitions
 . This can be more clearly seen by recognizing that (9) can be equivalently specified as

where  denotes the ‘true’ distribution of the sample, and
 , and
 . That is, the question posed by (9) is whether the data
 were generated by
 or its complement
 relative to
 .
An example of an N-P test for hypothesis (9) is  , where

In words, the N-P rule is this: reject  when
 exceeds
 , otherwise accept it. The optimality of
 is defined in terms of the probability of the two types of error associated with accepting/rejecting
 :

It is important to emphasize that these error probabilities are associated with all the different outcomes of x satisfying the above inequalities ( and
 ), stemming from the sampling distribution of
 evaluated under different hypothetical
(single) values of
 , relating to
 and
 , respectively.
An optimal N-P test, known as uniformly most powerful (UMP), minimizes the probability of type II error for all  , for a given (small) type I error probability:

Equivalently, test  is said to be UMP if its power (Lehmann Reference Lehmann1986),

is higher than that of any other  -level test for all
 (
 ). In this sense, a UMP test provides the most effective
 -significance-level probing procedure for detecting any discrepancy (
 ) of interest from the null.
To evaluate the error probabilities in (11) and (12), one needs to derive the sampling distribution of  under hypothetical values of
 . In particular, the evaluation of the type I error probability
 is based on the sampling distribution

where “ ” stands for “distributed under
 as a binomial with mean 0 and variance
1, based on a sample size
 .” The result in (13) stems from the fact that, in the context of the simple Bernoulli model (6), the sampling distribution of
 is
 , which implies that

but, when standardized,

(evaluated under  ) has mean 0 and variance 1.
Similarly, the type II error probability (and the power) are evaluated “under all point alternatives”  :

where

and

The key difference between (13) and (14) is that, under  , the sampling distribution of
 has a nonzero mean
 . It is interesting to note that, for moderately large values of n (say,
 ) and values of
 close to .5, both distributions (13) and (14) can be closely approximated using the normal distribution;
see Spanos (Reference Psillos1999). Two remarks are in order.
First, it is unfortunate that most statistics books use the vertical bar  instead of the semicolon (;) in formulas (11)–(12) to denote the evaluation under
 or
 , as it relates to (13)–(14), encouraging practitioners to misinterpret error probabilities as being conditional on
 or
 ; see Cohen (Reference Cohen1994). Alas, such conditioning makes no probabilistic sense in frequentist statistics because both hypotheses are framed in terms of the unknown parameter
 , which is an unknown constant, not an r.v. As mentioned above, legitimate events that render conditioning meaningful in frequentist inference are only the ones specified in terms of the sample
 , which is a set of r.v.'s.
Second, it is important to emphasize that the optimality of test  depends crucially on
 , the sample mean, being a minimal sufficient statistic for
 (see Lehmann Reference Lehmann1986). Hence, any cannibalization of
 , like rendering some of its values indistinguishable (Howson and Urbach Reference Howson and Urbach2005, 136–37), will destroy its sufficiency, distort both sampling distributions (13)–(14), and ruin the optimality of the resulting test by blunting its capacity to detect certain discrepancies from the null.
Although the formal apparatus of the Fisher-Neyman-Pearson (F-N-P) frequentist testing was largely in place by the late 1930s, the nature of the underlying inductive reasoning was clouded in disagreements. Fisher (Reference Fisher1935) argued for a purely falsificationist ‘inductive inference’, spearheaded by his significance testing. This relied exclusively on the notion of the observed significance level, or a p-value:

where a small enough  is interpreted as indicating discordance with
 (Fisher Reference Fisher1955). Neyman argued for ‘inductive behavior’ based on N-P testing and allowed both the acceptance and rejection of
 (Neyman Reference Neyman1956). However, neither account gave a satisfactory answer to the basic question:
when do data
 provide evidence for (or against) a hypothesis or a claim H? Indeed, several crucial foundational problems were left unanswered, including
(a) the role of predata versus postdata error probabilities (Hacking Reference Hacking1965),
(b) the fallacy of acceptance—no evidence against
is misinterpreted as evidence for (Mayo Reference Lehmann1996), and(c) the fallacy of rejection—evidence against
is misinterpreted as evidence for a particular ; see Mayo and Spanos (2006).
 is misinterpreted as evidence for
 (Mayo
 is misinterpreted as evidence for a particular
 ; see Mayo and Spanos (2006).
2.3 A Severity-Based Evidential Interpretation
Error statistics (Mayo and Spanos Reference Mayo, Spanos, Gabbay, Thagard and Woods2010) proposes a postdata evaluation of inference to supplement the F-N-P testing in order to address the foundational problems a–c. To simplify the exposition, let us consider a particular example.
Numerical example. For the simple Bernoulli model (6), consider applying test  for
 and data
 , yielding
 . Fixing the significance level at
 , one can use the normal approximation to the binomial distribution in (13), then derive the threshold value
 ; this approximation is excellent for moderate values of n and
 close to .5.
Evaluating the test statistic in (10) yields

Since  , the test leads to accepting
 . The lack of discordance with the null is also affirmed by the p-value

Does this mean that data  provide evidence for
 , or, more accurately, does
 provide evidence for no substantive discrepancy from
 ? Not necessarily! To answer that question, one needs to go beyond the coarse N-P “accept/reject”
rules and apply the postdata severe-testing reasoning to evaluate the discrepancy
 , for
 , warranted by data
 (Mayo and Spanos Reference Mayo and Spanos2006).
A hypothesis or a claim H passes a severe test T with data  if
(S-1)  accords with H (for a suitable notion of accordance)
and
(S-2) with very high probability test T would have produced a result that accords less well with H than  does, if H were false.
Severity can be viewed as a feature of a test T as it relates to a particular data  and a specific claim H. Hence, the severity function has three arguments,
 , denoting the severity with which H passes T with
 .
In the case of the above numerical example, the test  in (10) passes
 , and the idea is to establish the smallest discrepancy
 from
 warranted by data
 by evaluating (postdata) the claim
 for
 . Condition S-1 of severity is satisfied since
 accords with
 because
 , but, in addition, severity requires one to evaluate the probability of “all outcomes
 for which test
 accords less well with
 than
 does”; that is,
 , under the hypothetical scenario that “
 is false” or equivalently “
 is true”:

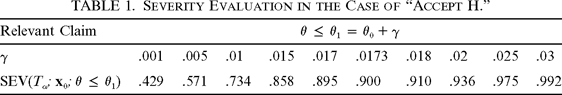
The evaluation of (16) relies on the sampling distribution (14) and for different discrepancies ( ) yields the results in table 1. Note that
 is evaluated at
 because the probability increases with
 . Assuming a severity threshold of, say, .90 is high enough, the above results indicate that the ‘smallest’
discrepancy warranted by
 is

That is, data  , in conjunction with test
 , provide evidence (with severity at least .9) for the presence of a discrepancy as large as
 . Is this discrepancy substantively insignificant?

| Relevant Claim |  |
|||||||||
| γ | .001 | .005 | .01 | .015 | .017 | .0173 | .018 | .02 | .025 | .03 |
 |
.429 | .571 | .734 | .858 | .895 | .900 | .910 | .936 | .975 | .992 |
In general, to answer this question one needs to appeal to substantive subject matter information to assess the warranted discrepancy on substantive grounds. In human biology it is commonly accepted that the sex ratio at birth is approximately 105 boys to 100 girls; see Hardy (Reference Hardy2002). Translating this ratio in terms of  yields
 , which suggests that the warranted discrepancy
 is, indeed, substantively significant, since this outputs
 , which exceeds
 —the substantive value of the human sex ratio at birth.
This is an example where the postdata severity evaluation addresses the fallacy of acceptance. The severity assessment indicates that the statistically insignificant result  , at
 , actually provides evidence against
 and for
 with severity at least .90.
Mayo and Spanos (Reference Mayo and Spanos2006)
show how the same conditions S-1–S-2 can be applied to the case of ‘reject  ’ to derive the corresponding severity evaluation function

The severe testing reasoning underlying (16) and (17) can be used to circumvent the fallacy of acceptance and rejection, respectively, by establishing the smallest (largest) discrepancy  from
 warranted by data
 , associated with the N-P decision to accept (reject)
 .
A direct comparison between, on the one hand, the type I and II error probabilities (11) and the power function (12) and the severity functions (16)–(17), on the other hand, reveals that they are all evaluated in terms of the sampling distributions (13)–(14) with one crucial difference: the former are predata (the threshold  is derived on the basis of a prespecified
 ), but the latter are postdata (the threshold
 becomes available only after
 is observed). Severity shares this postdata feature with the p-value, which is a postdata error probability, but unlike the p-value whose probability stems from (13), the probabilities associated with severity are based on the sampling distribution (14), resembling, in this respect, the type II error probability and power. Indeed, severity can be used to explain why the use of the p-value is also susceptible to the same fallacies as the accept/reject decision rules (Mayo and Spanos Reference Mayo and Spanos2006).
One can go a step further and make a case that the error-statistical framework anchored on the postdata severity component provides a harmonious blending of the Fisherian and Neyman-Pearsonian perspectives by weaving a coherent frequentist inductive reasoning anchored firmly on error probabilities. Predata, error probabilities are used to appraise the generic capacity (for any  ) of different testing procedures. Postdata, however, the particular realization
 can be used to transcribe the generic capacity, as it relates to the test outcome
 , to customize an evidential interpretation—beyond the crude true/false dichotomy—that pertains to whether data
 provide evidence for or against relevant claims concerning specific discrepancies (
 ) from
 . Indeed, the error-statistical perspective provides a unifying inductive reasoning for frequentist testing that addresses all three foundational problems a–c mentioned above; see Mayo and Spanos (Reference Mayo and Spanos2006) for further discussion.
3 The Base-Rate Fallacy Revisited
3.1 Summarizing the Fallacy
Psillos (Reference Neyman2007, 17–18) offers the following succinct summary:
Base-rate fallacy.—Best introduced by the Harvard Medical School test. A test for the presence of a disease has two outcomes, ‘positive’
and ‘negative’ (call them  and −). Let a subject (Joan) take the test. Let H be the hypothesis that Joan has the disease and
 the hypothesis that Joan doesn't have the disease. The test is highly reliable: it has zero false negative rate. That is, the likelihood that the subject tested negative given that she has the disease is zero (i.e.,
 . The test has a small false positive rate: the likelihood that Joan is tested positive though she doesn't have the disease is, say, 5 per cent (
 . Joan is tested positive. What is the probability that Joan has the disease given that she tested positive? When this problem was posed to experimental subjects, they tended to answer that the probability that Joan has the disease given that she tested positive was very high—very close to 95
per cent. However, given only information about the likelihoods
 and
 , the question above—what is the posterior probability
 ?—is indeterminate. There is some crucial information missing:
the incidence rate (base-rate) of the disease in the population. If this incidence rate is very low, for example, only 1 person in 1,000
has the disease, it is very unlikely that Joan has the disease even though she tested positive:
 would be very small. For
 to be high, it must be the case that the prior probability that Joan has the disease (i.e.
 ) is not too small. The lesson that many have drawn from cases such as this is that it is a fallacy to ignore the base rates because it yields wrong results in probabilistic reasoning.
It is clear from the above summary that any procedure relying on the posterior probability  will give rise to fallacious inferences when base rates are ignored because, as can be seen in (1), going from
 to
 depends crucially on the ratio of the prior probabilities
 and
 .
The question is whether the frequentist approach to testing is also vulnerable to the base-rate fallacy. Howson (Reference Howson2000, 54) contends that this fallacy seriously undermines frequentist testing, in general, and the severity assessment, in particular:
The central methodological claims of a recent book on methodology
(Mayo 1996) are based on committing it. In this book a version of the argument very similar to Fisher's is proposed. As in the tea-tasting, there is a notion of outcomes agreeing better or worse with some hypothesis  . … Similarly, spelling out explicitly what is implicit in Fisher's discussion, if E “fits” H, while there is a very small chance that the test procedure “would yield so good a fit if H is false”, then, “E should be taken as good grounds for H to the extent that H has passed a severe test with E” (Mayo 1996:177; my italics). In the Harvard Medical School test we have Mayo's formal criteria for H “passing a severe test with E” satisfied.
A similar view is expressed in Howson (Reference Howson1997), Achinstein (Reference Achinstein2001, Reference Achinstein, Mayo and Spanos2010), and Howson and Urbach (Reference Howson and Urbach2005).
3.2 Unraveling the Base-Rate Fallacy Argument
In order to simplify the untangling of the various confusions vitiating the base-rate fallacy argument, consider a numerical example due to Achinstein (Reference Achinstein, Mayo and Spanos2010), specified in terms of the following probabilities:

3.2.1 What Is the Underlying Statistical Model?
Since frequentist statistical inference is model based, the first thing one needs to uncover is the implicit statistical model that can then be used to delineate what constitute legitimate events, hypotheses, data, test statistics, error probabilities, and so forth.
Since there are only two outcomes in the Harvard Medical School test example, it is easy to recognize that the relevant random variables are Bernoulli distributed:
X denotes having the disease (X = 1) or not (X = 0), and Y denotes the medical test result, positive (Y = 1) or negative (Y = 0).
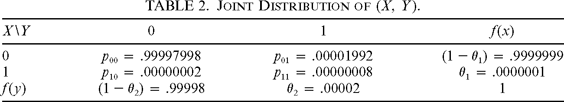
Thus, the probabilities in (18) can be written more transparently in terms of the joint probabilities  :

Solving (19) for  gives rise to the joint distribution in table 2.

| X\Y | 0 | 1 | f(x) |
| 0 |  |
 |
 |
| 1 |  |
 |
 |
| f(y) |  |
 |
1 |
This suggests that the underlying statistical model—assumed to describe the incidence of a disease in a particular population as it relates to the result of a medical test for that disease—is a simple (bivariate) Bernoulli model:

where


In direct analogy to (6), the distribution of the sample

simplifies to

where


denote the unknown parameters. The additional “ugliness”
notwithstanding,  in (20) is identical to the simple Bernoulli in (6), apart from the underlying process
 being bivariate!
The first thing one notices about  in (20) and table 2 is that the latter is an instantiation of the former that involves no unknown parameters. If frequentist inductive inference is all about learning from data about the data-generating mechanism, the question that naturally arises is, what could learning based on table 2 possibly mean?
3.2.2 Frequentist Hypotheses versus Events
As argued in section 2.2, the statistical hypotheses in frequentist testing are always framed in terms of the unknown parameters  , and they invariably pertain to the stochastic mechanism—assumed to be described by
 —that gave rise to data
 . An example of such N-P hypotheses in the context of the bivariate Bernoulli model might be

where  (unknown) denotes the proportion of the population that has the disease, given that they tested positive. The N-P hypotheses in (23) pose the sharp question whether or not
 , with a view to learn from data by narrowing the original model
 down to a subset:

A frequentist test for properly defined hypotheses such as (23) will involve constructing a test similar to  in (10), say,

for an appropriate estimator  of
 Using the sampling distribution of
 under both the null and alternative hypotheses, one can evaluate the predata and postdata error probabilities as shown in sections 2.2–2.3. One feature of the hypotheses in (23) worth bringing out is that because
 is rather small, one can guesstimate that the sample size n needed to give adequate power to the test to detect small discrepancies (third decimal) from
 is likely to be huge.
How does this frequentist set up relate to the “hypothesis”

around which the base-rate fallacy example revolves? The assignment of probability to h is a giveaway that it is not a legitimate frequentist hypothesis, since in that context hypotheses are framed in terms of  , which is assumed to be an unknown constant, not a random variable. The difficulty, however, is to disentangle the connections between
 , the data
 , and
 .
In contrast to (23), h in (25) assumes that  is known (
 ; table 2) and poses the question whether Joan—a particular member of the target population—has the disease or not. Due to the ambiguity as to the status of h vis-à-vis
 , one needs to distinguish between two different cases.
Case 1.—Joan is randomly selected from the target population.
In this case, h concerns the event (say  ) and represents an element of the random sample
 . In view of the fact that h does not pertain to the statistical data-generating mechanism, it is not a legitimate frequentist hypothesis; see Mayo (Reference Mayo1997a). Indeed, in this case
 constitutes a single observation from a size n sample Z.
Case 2.—Joan is not randomly selected from the target population;
for example, she requested the test. In this case the single observation  is no longer legitimate for
 . Indeed, the event
 lies outside the intended scope of the statistical model
 , which aims to provide an idealized description of the disease's incidence in the target population, and not the affliction of a particular individual; for the latter, one needs to specify a different statistical model (see Spanos Reference Spanos2009). The variable h is illegitimate as an event in the context of
 because
 does not constitute a “typical” realization of
 ; purposeful selection invalidates the IID assumptions underlying
 . Any attempt to interpret
 as an instantiation of the generic event
 will introduce statistical misspecifications that often lead to unreliable inferences.
Statistical adequacy—the validity (vis-à-vis data  ) of the IID assumptions underlying
 —ensures that the actual error probabilities are approximately equal to the nominal ones, rendering the reliability of inference ascertainable; see Mayo and Spanos (Reference Mayo, Mayo and Spanos2004). Applying a .025 significance level test when its actual type I error probability is closer to .99
will lead the inference astray!
In summary, h-Joan has the disease does not constitute a legitimate frequentist hypothesis because, at best, it pertains to an event (not to the data-generating mechanism) and, at worst, it lies outside the intended scope of  .
3.2.3 Error Probabilities versus Conditional Probabilities of Events
Focusing on the best-case scenario for the proponents of the base-rate argument, it is clear that when Joan is randomly selected, the event  constitutes a single observation from Z. It is well known, however, that with
 no consistent (minimally reliable)
estimator or test concerning
 is possible; see Cox and Hinkley (Reference Cox and Hinkley1974).
In light of this, how do the proponents of the base-rate argument make their case that frequentist testing is vulnerable to the fallacy?
Their argument is that the hypothesis  has “passed a severe test” on the basis of the following two conditional probabilities (table
2):

known as the false positive and the false negative probabilities, respectively. As the base-rate argument goes, since  (the prior probability of h) is low, the conditional (posterior or epistemic) probability,

is also low, and, thus, on the basis of (27), Joan's positive result gives very little reason to believe  , despite h's passing a severe test; see Achinstein (Reference Achinstein, Mayo and Spanos2010, 182).
Mayo (Reference Mayo1997a, Reference Mayo1997b, Reference Mayo2005) has called repeatedly into question the basic claim that “h has passed a severe test” on the basis of the probabilities in (26)–(27) on several grounds. Howson (Reference Howson2000, 54), however, maintains, “Mayo discusses the example in Mayo 1997, but I cannot see that she mitigates in any way its force”; see also Howson and Urbach (Reference Howson and Urbach2005, 25).
Focusing on the most telling of such grounds, the conditional probabilities (26)–(27) have nothing to do with any proper predata or postdata error probabilities. In particular, the severity functions in (16)–(17) have three arguments (a test T, data  , and a frequentist hypothesis or a claim H), and none of them is present in the base-rate argument. This argument replaces frequentist hypotheses with events;
the test and its error probabilities with conditional probabilities among events; and the data, at best, amount to a single observation
 .
One can go further and call into question the base-rate argument on other grounds, even when h is the legitimate event  in the context of
 . First, the claim that
 and
 represent the prior and posterior probabilities of h is unwarranted on Bayesian statistical grounds. This is because Bayesian inference is deemed legitimate when grounded on a posterior distribution:

where  is defined in (22),
 denotes the prior distribution of
 , and
 denotes the likelihood function. The latter is defined as being proportional to the distribution of the sample:

evaluated at  and viewed as a function of
 . However, any attempt to relate the assignments
 and
 to
 ,
 , or/and
 is a hopeless task because all these crucial components of Bayesian inference are missing. Indeed,
 in (27) is nothing more than a deductive calculation within the context of a known statistical model (table 2). Second, any attempt to associate
 and
 with subgroups of the original target population in a desperate attempt to provide some basis for any form of make-believe inductive inference is misguided; see Spanos (Reference Spanos2009). Finally, one can test legitimate hypotheses about the unknown parameters
 and
 in the context of
 in (20), but that requires a proper data set
 associated with randomly selected individuals from the target population.
3.2.4 What about the False Positive and False Negative Probabilities?
The medical test is conflated with a proper frequentist test using a beguiling analogical argument concerning the former's false positive and false negative conditional probabilities as being equivalent to the type I and type II error probabilities (Howson Reference Howson2000). The analogy misrepresents frequentist testing because there is no such a thing as a generic type I and II error probability for a frequentist test.
A glance at the sampling distributions of  in (13) and (14) reveals that all error probabilities (see [11]–[12] and [16]–[17]) depend crucially on the sample size n. For example, for
 and
 , a power value of
 at some discrepancy, say
 , from the null might be considered adequate, but for
 , it is not! Moreover, any attempt to identify the false positive/negative with asymptotic error probabilities, as being more generic, will not work because the power of any half-decent (consistent) N-P test goes to one as the sample size n goes to infinity; see Lehmann (Reference Lehmann1986).
In addition, a medical test aims to prognosticate the occurrence of an event (Joan has the disease), but a frequentist test aims to guide the quest for the data-generating mechanism that gave rise to the data. Although very important, distinguishing between the statistical and substantive data-generating mechanism is beyond the scope of this article; see Spanos (Reference Spanos2007). Hence, the use of conditional probabilities associated with particular events by the base-rate argument is a far cry from proper error probabilities pertaining to inference procedures. Why?
The type I and II error probabilities and the power of the test in (24) would take an almost identical form to (11) and (12). What is crucially important for this discussion is that these error probabilities are always associated with the test procedure (not the hypotheses); they are never conditional on a hypothesis—they are evaluated under different hypothetical values of  to yield (13)–(14)—and they invariably involve an infinity of events
(tail areas). For example, the type I error probability in (11) involves all outcomes
 such that
 , not to mention that they are meaningless for
 .
3.3 The Ampliative Dimension of Frequentist Induction
Summarizing the discussion so far, the base-rate argument relying on medical-test type examples is only superficially related to frequentist testing, because it involves none of the components that define a proper frequentist test: (a) appropriate data, (b) legitimate hypotheses, (c) a test statistic, (d) sampling distributions, and (e) the relevant error probabilities.
At best, the data amount to a single observation  ; the hypothesis of interest is illegitimate; and the test statistic, its sampling distribution, and error probabilities are replaced by conditional probabilities among events. As a result, the ampliative dimension of frequentist induction, in the sense of “learning from data” about the underlying statistical data-generating mechanism, is absent. When viewed in the context of frequentist induction,
 amounts to a deductive calculation of conditional probabilities associated with particular events within the context of a known model
(table 2). This is the reason why from that perspective the base-rate fallacy arguments appear to rely on
 and there are no unknown parameters in table 2; they are totally at odds with the implicit bivariate Bernoulli model
 in (20).
Mayo (Reference Mayo and Achinstein2010) elaborates further on how misleading the claim is that h passes a severe test with data  on the basis of the conditional probabilities in (19). For our purposes it suffices to reiterate that examples like the Harvard Medical School test demonstrate inadequate understanding of frequentist testing, insofar as (i) frequentist testing takes place within the boundaries of a clearly defined statistical model
 chosen so as to account for the regularities in data
 and not on the basis of a cluster of probabilities like (19) attached to particular events; (ii) frequentist hypotheses are framed in terms of the unknown parameter(s)
 (assumed to be constant) and always pertain to the statistical data-generating mechanism; and (iii) the ampliative dimension of frequentist testing revolves around the relevant error probabilities, which are (a) never conditional, (b) always assigned to inference procedures (never to hypotheses), and (c) invariably depend on the sample size
 .
4 Summary and Conclusion
The above discussion has demonstrated that the base-rate fallacy argument is riddled with obfuscations and false analogies that stem from inadequate understanding of frequentist testing anchored on the notion of a statistical model  .
Despite the apparent similarities between the Harvard Medical School test example and a frequentist test, it was pointed out that the two are fundamentally different. The medical test and its false positive and false negative probabilities have only superficial resemblance to a proper frequentist test and its type I and II error probabilities, because the latter are crucially dependent on the sample size n but the former are built-in.
In particular, learning from data about the underlying data-generating mechanism is absent from the base-rate fallacy example because the relevant error probabilities—around which the ampliative dimension of frequentist inference revolves—are replaced by conditional probabilities among events. These probabilities represent simple deductive calculations within the context of a known data-generating mechanism.