


1. INTRODUCTION
After its invention in the 1980s, the theory of cointegration developed rapidly, and the link between cointegration and linear vector autoregressive (VAR) error correction models was found to be particularly useful. More recently, nonlinear extensions of these models have also been considered. We refer to Bec and Rahbek (2004) and Kapetanios, Shin, and Snell (2006) for up-to-date discussions on the relevant literature of nonlinear cointegration and nonlinear error correction models.
Since the late 1990s, interest in nonlinear error correction models has been steadily growing, but the theory of these models is still rather undeveloped. The theory of linear error correction models was greatly advanced by the early development of a basic structural result often referred to as Granger's representation theorem (see Johansen, 1995, p. 49). This theorem provides conditions under which a linear VAR process is nonstationary and integrated of order one (or I(1)) but some of its linear combinations are stationary and can be interpreted as long-run equilibrium relations. In addition to its theoretical importance this result is also of practical significance because it links the linear error correction model to the concept of cointegration. For the theory and understanding of nonlinear error correction models analogues of this result are of utmost importance. Such results have recently been obtained by Corradi, Swanson, and White (2000), Escribano and Mira (2002), Bec and Rahbek (2004), Escribano (2004), and Saikkonen (2005). The purpose of this paper is to provide extensions of this previous work.
Threshold error correction models introduced by Balke and Fomby (1997) have probably been the most popular nonlinear error correction models considered so far, and recently their smooth transition counterparts have also attracted attention (see Kapetanios et al., 2006, and references therein). A smooth transition model assumes that the abrupt regime switches implied by a threshold model are gradual. In both models the regime switches are determined by observable transition functions. An unobservable transition function results when the threshold specification is modified by making its transition function dependent on an unobservable random term. Modifications of threshold error correction models based on this idea have been studied by Bec and Rahbek (2004) and Saikkonen (2005), who also provide references of earlier time series models based on the same idea. In this paper, fairly general versions of all these nonlinear error correction models, characterized by regime switches, will be considered, and conditions that ensure stationarity of the long-run equilibrium relations and differenced observations will be provided. Partial extensions of Granger's representation theorem are thereby obtained. The extensions are only partial because the precise I(1) nature of the considered process remains to be worked out.
Our work is closely related to that of Bec and Rahbek (2004) and Saikkonen (2005). Following these authors we use the theory of Markov chains and the concept of geometric ergodicity. However, we can allow for more general switching mechanisms or more general forms of nonlinearity than previously. This is achieved by exploiting the recent advances of Liebscher (2005) to establish geometric ergodicity and, hence, stationarity in nonlinear autoregressive models. These advances are based on a novel idea of using the concept of joint spectral radius of a set of square matrices to extend previous results on geometric ergodicity in nonlinear autoregressive models.
The paper proceeds as follows. The nonlinear error correction models studied in the paper are first introduced in Section 2, after which the main results are presented in Section 3. Section 4 concludes. Proofs are contained in the Appendix.
A few words on the notation. The symbol L is used for the usual lag opera-tor, whereas Δ = 1 − L is the corresponding differencing operator. The trace and determinant of the (square) matrix A are denoted by tr(A) and det(A), respectively. If A is positive semidefinite its unique positive semidefinite square root is denoted by A1/2. The rank of the k × l matrix B is signified by rk(B), and the orthogonal complement of B is a k × (k − l) matrix B⊥ of full column rank and such that B′B⊥ = 0 (k > l). An identity matrix of order n is denoted by In. Finally, ∥·∥ is used for the euclidean norm, and 1(·) signifies the indicator function.
2. REGIME SWITCHING ERROR CORRECTION MODELS
2.1. Illustrative Examples
For illustrative purposes this section provides an informal discussion of simple special cases of the general nonlinear error correction model to be considered in the paper. In these examples only a single long-run equilibrium relation is assumed, and the nonlinearity manifests itself as a regime dependent adjustment to disequilibrium errors.
Let yt (t = 1,2,…) be an n-dimensional time series that can be modeled by the threshold error correction model

where αs (n × 1), β (n × 1), Γj (n × n), and Ω (n × n) are parameters with β nonzero and Ω positive definite and R1 = (−∞,c1], R2 = (c1,c2], and R3 = (c2,∞). Moreover, εt ∼ i.i.d.(0,In), that is, a sequence of independent and identically distributed (i.i.d.) n-dimensional random vectors with zero mean and identity covariance matrix.
Thus, the model assumes three regimes with (possibly) different adjustment parameters. When the disequilibrium error β′yt−1 is in regime Rs a conventional linear error correction model with adjustment parameter αs applies. An abrupt change in the adjustment parameter results when the disequilibrium error enters another regime. For simplicity and in line with some recent applications the number of regimes has been restricted to three. Bec and Rahbek (2004) consider the case where α1 = α3 is nonzero and provide conditions under which an analogue of Granger's representation theorem holds, implying stationarity of the linear combination β′yt and the differences Δyt. The same conclusion can also be inferred from a general result in Saikkonen (2005).
When α1 ≠ α3 stationarity of β′yt and Δyt cannot be obtained from the results referred to earlier. The purpose of this paper is to provide extensions in this direction. In addition to threshold error correction models we also consider their smooth transition analogues. A smooth transition analogue of the threshold error correction model (1) is obtained by replacing the indicator function by a suitable smooth function. For instance, consider the logistic function

where γ > 0, s = 1,2, and c1 < c2. Instead of the threshold error correction model (1) one may wish to consider the model

where

and the notation is otherwise as in (1). Because of the smoothness of the functions hs the regime switches implied by this model take place gradually over a longer period of time as opposed to the abrupt regime switches implied by the threshold specification. The time it takes for the regime switches to realize depends on the value of the parameter γ. When the value of γ increases the regime switches get faster, and the threshold error correction model (1) is obtained in the limit as γ → ∞. If α1 = α3 is nonzero the stationarity of β′yt and Δyt can be concluded from Saikkonen (2005), but when α1 ≠ α3 no similar result is available.
Smooth transition models provide one way to modify threshold models. Another modification is obtained by adding randomness to the regime switches of threshold models. Thus, instead of the threshold error correction model (1) one may consider

where ηt is an unobservable i.i.d. sequence totally independent of the sequence εt and the remaining notation is as in (1). Thus, the only difference between this model and the threshold error correction model (1) is the occurrence of the random error ηt in the indicator function. When β′yt−1 + ηt ∈ Rs a linear error correction model with adjustment parameter αs applies. However, given β′yt−1 this only happens with some probability between zero and one. This probability depends on the value of the disequilibrium error β′yt−1 and the probability distribution of the random variable ηt. For instance, when the value of β′yt−1 is close to the value of the threshold parameter c1 both of the events {β′yt−1 + ηt ∈ R1} and {β′yt−1 + ηt ∈ R2} can have a nonnegligible probability to realize. Thus, the regime switching mechanism is more flexible than in the corresponding threshold specification where ηt = 0 is assumed and one of the aforementioned probabilities is always zero.
Error correction models of the type (3) have recently been considered by Bec and Rahbek (2004) and Saikkonen (2005). As shown by these authors the conditional distribution of Δyt given the past of the process is a mixture distribution, and consequently one may refer to the model as a mixture error correction model. On the other hand, model (3) implies that the conditional expectation of Δyt given the past of the process is similar to that in the smooth transition error correction model (2), and therefore this model may also be seen as a smoothed version of the threshold error correction model. If α1 = α3 is nonzero the stationarity of β′yt and Δyt can again be obtained from Bec and Rahbek (2004) and Saikkonen (2005), but these results do not apply when α1 ≠ α3, a case to be covered in this paper.
In addition to the case α1 ≠ α3 neither the results of Bec and Rahbek (2004) nor those of Saikkonen (2005) apply when α1 = α2 ≠ α3 or α1 ≠ α2 = α3, that is, when we have a model with two regimes and a single threshold. The extensions obtained in this paper can also be used for such models.
Although various regime switching error correction models have arguably been the most commonly used nonlinear error correction models considered so far, other specifications may also be of interest. For instance, Escribano (2004) suggests modeling the adjustment to the disequilibrium error β′yt−1 by a rational function with certain restrictions imposed on the degrees and coefficients of the numerator and denominator. Escribano (2004) studies the stability of this kind of nonlinear error correction model in a single equation context. The results of this paper cannot be directly used for models of this type.
2.2. General Regime Switching Error Correction Model
We shall now introduce a general nonlinear error correction model that encompasses the models discussed in the previous section. As before, yt (t = 1,2,…) is an n-dimensional stochastic process and εt ∼ i.i.d.(0,In) an n-dimensional error term. The scalar valued i.i.d. error term ηt used in model (3) is generalized to a vector of dimension l but is otherwise as before. The model is defined by

where αs (n × r), β (n × r), Γsj (n × n), μs (n × 1), and Ωs (n × n) are parameters with rk(β) = r and Ωs positive definite. Moreover, Yt−1 = [(β′yt−1)′ Δyt−1′ … Δyt−p+1′]′ and S ((n(p − 1) + r) × k) is a (known) nonrandom matrix of full column rank used to determine linear combinations of the vector Yt−1 on which the transition functions

depend. The matrix S could be imbedded in the functions hs, but its explicit use is convenient. Typically S′ is a selection matrix, but this is not necessary. Properties required for the functions hs will be described shortly.
If m = 1, h1 ≡ 1, and the parameter matrix α1 is of full column rank model (4) reduces to a standard linear error correction model. If m > 1 extensions of the models discussed in the previous section are obtained with suitable choices of the functions hs. For instance, a general threshold error correction model is obtained by choosing

where

is a (Borel) measurable function and the sets

form a partition of

. The transition function used in (1) is obtained by setting r = k = d = 1 and m = 3 and by choosing S′ = [1 0], φ1(S′Yt−1) = β′yt−1, and R1 = (−∞,c1], R2 = (c1,c2], and R3 = (c2,∞). Thus, S′ is a row vector that selects the first component from the vector Yt−1, and φ1 is an identity function. Even with these choices the resulting special case of model (4) is more general than (1) because, in addition to the adjustment parameters αs, also other short-run parameters and the error covariance matrix can be regime dependent and there is also a regime dependent intercept term. For r > 1 and d = 1 conceivable choices are S′ = [Ir 0] and φ1(S′Yt−1) = ∥β′yt−1∥ resulting in a transition function considered by Bec and Rahbek (2004). Like these authors and Saikkonen (2005) we also allow for the possibility that, in addition to the disequilibrium errors β′yt−1, the regime switches can be determined by the differences Δyt−1,…, Δyt−p+1. Note, however, that the disequilibrium errors β′yt−1 are supposed to be linear and the same in each regime. This feature is common to all the models considered in the paper.
A smooth transition analogue of the threshold error correction model discussed previously can be obtained in the same way as in the example of the previous section. For instance, suppose that in (5) d = 1 and define

where we now have m − 1 logistic functions and threshold parameters c1 < ··· < cm−1. Conceivable choices are again S′ = [Ir 0] and φ1(S′Yt−1) = ∥β′yt−1∥.
Note that the equality h1(Yt−1,ηt) + ··· + hm(Yt−1,ηt) = 1 holds in both of the two cases (5) and (6). This property is convenient for our developments and will therefore be assumed even generally. Among other things it implies that the commonly used assumption of conditionally homoskedastic errors in smooth transition error correction models can simply be obtained by assuming that the covariance matrices Ωs, s = 1,…, m, are equal.
A general extension of the mixture error correction model (3) is obtained by modifying equation (5) to the form

where the domain of the (Borel) measurable function φd is now

and the notation is otherwise as in (5). Similarly to the examples discussed in the previous section, the only difference between this choice and its counterpart (5) used in the threshold specification is the occurrence of the random error ηt, which now appears as an argument of the function φd. Assuming d = 1 one may have S′ = [Ir 0] and φ1(S′Yt−1,ηt) = ∥β′yt−1∥ + ηt, which gives a mixture version of the threshold specification discussed after equation (5). Even generally, the interpretation of the model defined by equations (4) and (7) and its relation to the corresponding threshold specification is basically the same as in the examples of the previous section. In what follows, the specification (7) will always be assumed when the functions hs are supposed to be dependent on the error term ηt.
It will be convenient to generalize model (4) slightly. To this end, let 1 be a subset of {1,…, m} and 2 = {1,…, m}[setmn ]1, the complement of 1 in {1,…, m}. Choose an s1 ∈ 1 and define

Model (4) can now be written as

where g(Yt−1,ηt) is defined in such a way that the right-hand sides of (4) and (8) match. Specifically, setting Ξs = [αs : Γs1 : ··· : Γs,p−1] we have

Of course, model (8) is just a reparameterized form of the original model (4), which can be obtained from (8) by assuming that the set 2 is empty or that αs = αs, Γsj = Γsj (s = 1,…, m, j = 1,…, p − 1), and

. From now on we shall consider model (8) and recall that the i.i.d. error terms εt (n × 1) and ηt (l × 1) are assumed to be totally independent of each other and, moreover, such that both εt and ηt are independent of yt−j, j > 0. Occasionally it may be useful to be explicit about the fact that the functions hs and g are supposed to be independent of the random error ηt. With a slight abuse of notation we then denote hs(·,ηt) = hs(·) and g(·,ηt) = g(·).
To see the motivation of the preceding extension, consider the threshold error correction model (1) and choose 1 = {1,3}. In this case Γsj = Γj and μs = 0 for all s = 1,2,3, whereas g(Yt−1) = 1(c1 < β′yt−1 ≤ c2)α2 β′yt−1. Thus, the function g(·) is bounded. This is beneficial because it means that the function g(·) can be ignored in the critical steps of our proofs. This in turn implies that the value of the parameter vector α2 is totally irrelevant and nothing needs to be assumed about this parameter. This widens the scope of our results. In particular, although our results require that the parameter vectors α1 and α3 are nonzero the parameter vector α2 can be totally unrestricted. The process yt may thus exhibit unit root type nonstationarity or even explosive behavior in the middle regime, and yet the disequilibrium error β′yt and the differences Δyt are stationary. With appropriate assumptions this can be generalized so that only the parameter matrices αs, s ∈ 1, are required to be of full column rank but the parameter matrices αs, s ∈ 2, can be totally unrestricted. The models studied by Bec and Rahbek (2004) and Saikkonen (2005) already allowed for this feature but only in the special case where a single element could be included in the set 1. In the case of the mixture model (3), where the functions hs depend on the error term ηt, the relevant boundedness is that of the expectation E∥g(·,ηt)∥. As in Saikkonen (2005), we can actually be somewhat more general than assumed here because slightly less than boundedness will suffice.1
Whether unit root or explosive behavior in the middle regime is reasonable or not depends on the considered application. The former was found relevant in Bec and Rahbek (2004), but the latter may be less appealing. Indeed, a referee pointed out that if the adjustment to disequilibrium errors is explosive in the middle regime the economically interesting equilibrium is almost never observed, even under stationarity.
In the example discussed earlier an important point is that the function g(Yt−1,ηt) depends on S′Yt−1 and not on the whole vector Yt−1. To achieve the same in the general case we have to assume that

To see the point of this assumption, notice that we can always write (Ξs − Ξs1)Yt−1 = (Ξs − Ξs1)PSYt−1 + (Ξs − Ξs1)PS⊥Yt−1 where the orthogonal projection matrices PS and PS⊥ project vectors on the column spaces of the matrices S and S⊥, respectively. When condition (10) holds we have (Ξs − Ξs1)Yt−1 = (Ξs − Ξs1)S(S′S)−1S′Yt−1 for all s ∈ 2. Thus, g(Yt−1,ηt) depends on the vector Yt−1 only through S′Yt−1, and equation (9) becomes

We shall now introduce assumptions needed in the discussion that follows. The first assumption concerns the error term εt.
Assumption 1. The distribution of the i.i.d.(0,In) random vectors εt has a (Lebesgue) density that is bounded away from zero on compact subsets of

.
From a practical point of view this assumption is innocuous. Regarding the functions hs, it appears convenient to first assume that they are independent of the random error ηt.
Assumption 2. The (Borel) measurable functions

do not depend on the error term ηt and satisfy the following conditions.
(a) h1(x) + ··· + hm(x) = 1 for all

.
(b) Either the set 2 is empty or, for all s ∈ 2, hs(x)x = o(∥x∥) as ∥x∥ → ∞.
Assumption 2(a) is trivially satisfied by threshold error correction models and also by typical smooth transition error correction models, possibly after reparameterization. For instance, the logistic specification (6) automatically satisfies this assumption. It is worth noting, however, that because the functions hs are assumed to take values on the unit interval many conceivable choices, including rational functions, are ruled out. If the set 2 is empty Assumption 2(b) becomes redundant. If not and condition (10) holds it implies that the function g[dagger] is dominated by a linear function when ∥x∥ gets large or that g[dagger](x) = o(∥x∥) as ∥x∥ → ∞. This condition is the slight weakening of the boundedness of the function g referred to before. In the threshold error correction model (1) and its extension discussed after equation (9) Assumption 2(b) clearly holds and guarantees the boundedness of the function g[dagger]. The same is true for the corresponding smooth transition analogues based on logistic functions.
As already mentioned, the functions hs are supposed to be as in (7) when they also depend on the random error ηt. In this case we need to consider the probabilities

Given Yt−1 = x, πs(S′x) is the conditional probability that the model defined by the regime Rs applies. Because the sets Rs form a partition of

we have π1(S′x) + ··· + πm(S′x) = 1. If the function φd is independent of the random error ηt the function πs(S′x) is zero-one valued so that the previous threshold error correction model is obtained as a special case.
Instead of Assumption 2 we now have the following assumptions
Assumption 2′. The functions hs are as defined in (7), and the functions

satisfy the following conditions.
(a) For some 1 ≤ s0 ≤ m, πs0(x) is bounded away from zero on compact subsets of

.
(b) Either the set 2 is empty or, for all s ∈ 2, πs(x)x = o(∥x∥) as ∥x∥ → ∞.
Assumption 2′(a) is technical and makes it possible to apply available results in the proofs. It appears reasonably mild and expected to hold if the random vector ηt has a density with properties similar to those required for the density of εt in Assumption 1. Assumption 2′(b) is entirely similar to Assumption 2(b). When the set 2 is nonempty and condition (10) holds it implies that E∥g[dagger](x,ηt)∥ = o(∥x∥) as ∥x∥ → ∞ but not necessarily boundedness of this function.
Next define the polynomial matrices

and make the following assumption.
Assumption 3. For all s ∈ 1, the polynomial matrices As(z) satisfy the following three conditions.
(a) If det As(z) = 0 then |z| > 1 or z = 1.
(b) The n × r matrices αs and β are of full column rank.
(c) The number of unit roots in condition (a) equals n − r.
Thus, we assume that the polynomial matrices As(z), s ∈ 1, satisfy conditions required for the polynomial matrix of a conventional linear VAR error correction model. In that special case, these conditions guarantee the validity of Granger's representation theorem (see Johansen, 1995, Thm. 4.2 and Cor. 4.3). The fact that similar conditions are only assumed for s ∈ 1 instead of all s ∈ {1,…, m} is related to the previously mentioned fact that the parameter matrices αs, s ∈ 2, are not required to be of full column rank.
Because we shall work with model (8) we also define the polynomial matrices
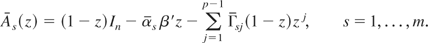
By the definitions of αs and Γsj, the polynomial matrices As(z) satisfy the three conditions of Assumption 3 for all s = 1,…, m. In addition to condition (10) and Assumption 3 a further condition has to be imposed on the parameters of the model. This condition will be introduced in the next section. It actually implies Assumption 3, but it is convenient to state both.
3. RESULTS
Following Saikkonen (2005) simple transformations of the polynomial matrices As(z) are employed. To this end, let c (n × r) be a matrix of rank r and such that c′β = Ir. One can choose c = β(β′β)−1, but any other choice will also do. Then the matrix Q = [β : c⊥]′ is nonsingular, and its inverse is Q−1 = [c : β⊥] where c⊥′ β⊥ = In−r. We also define the n × n polynomial matrices P(z) = [β : (1 − z)c⊥]′ and

. By Assumption 3 and Lemma 1 of Saikkonen (2005) we can write

where Bs*(z) = Q[Γs(z)c(1 − z) − αs z : Γs(z)β⊥] is a polynomial matrix such that Bs*(0) = In and det Bs*(z) ≠ 0, |z| ≤ 1. This result is now used to transform the model.
Recall that hs(·,ηt) stands for either hs(·) or 1(φd(·,ηt) ∈ Rs). Using condition (10) and the definition of the function g[dagger] (see (11)) we can write model (8) as

where use has been made of the fact that, by assumption,

. Transform the process yt as

and observe that the vectors Yt = [(β′yt)′ Δyt′ … Δyt−p+2′]′((n(p − 1) + r) × 1) and Zt = [zt′ … zt−p+1′]′ (np × 1) are related by

where the matrix J is of full row rank and given by

(for details, see Saikkonen, 2005).
Now define the polynomial matrices

. By equation (13), As(z) = Bs(z)Q−1P(z), which combined with equation (15) shows that As(L)yt = Bs(L)zt. From this and equations (14) and (16) we therefore find that
2When n = r, zt = yt, and, in the definition of the matrix J, β = c = In. When r = 0, zt = Δyt, and, in the definition of the matrix J, the first r rows are deleted and cβ′ = In is assumed.

As in Saikkonen (2005), we have thus shown that our nonlinear error correction model can be transformed to a nonlinear VAR model. We shall first obtain results for this nonlinear VAR model and use them to infer similar results for our nonlinear error correction model.
To be able to obtain our results, suitable assumptions have to be imposed on the matrices Bsj in (17). To this end, define the companion matrices

We need the concept of joint spectral radius of a set of square matrices. If

is such a set of square matrices its joint spectral radius is defined by

where

and the euclidean norm ∥·∥ could be replaced by any matrix norm (the value of

does not depend on the choice of this norm). If the set

only contains a single matrix A then the joint spectral radius of

coincides with the ordinary spectral radius or the largest absolute eigenvalue of A. In our applications the set

is always bounded, in which case the joint spectral radius can also be defined as

where ρ(A) signifies the spectral radius of the matrix A. This and several other useful results about the joint spectral radius can be found in a recent paper by Liebscher (2005), which also contains further references.
We need to consider the joint spectral radius of the (finite) set of matrices

and assume that

Note that from the definition of the joint spectral radius or from (18) one readily finds that this condition could equivalently be given by using the coefficient matrices of Bs*(z) instead of Bs(z) (s ∈ 1). Condition (19) implies that ρ(Bs) < 1 for every s ∈ 1, which in turn is equivalent to Assumption 3. This follows from Lemma 1 of Saikkonen (2005) and the fact that the matrices Bs, s = 1,…, m, are determined by the coefficient matrices of the polynomial matrices As(z), s ∈ 1. This latter fact also makes clear that condition (19) could equivalently be stated as ρ({Bs : s = 1,…, m}) < 1. It is worth noting, however, that even if ρ(Bs) < 1 holds for every s ∈ 1 it need not be the case that

(cf. the example in Liebscher, 2005, Sect. 4). Thus, in general condition (19) is a genuine strengthening of Assumption 3. An exception is the special case where the set 1 contains a single element s1 because then condition (19) is equivalent to ρ(Bs1) < 1. This special case is relevant for the models studied by Bec and Rahbek (2004) and Saikkonen (2005) and also for conventional linear models. Thus, condition (19) appears a natural extension of these previous conditions.
We shall show that the assumptions made in the previous section combined with condition (19) guarantee the existence of initial values that make the process zt stationary. By equation (15) we then get the stationarity of the linear combinations β′yt and the differences Δyt. The proof and formulation of this result are based on the theory of Markov chains. Therefore, we first note that the process Zt = [zt′ … zt−p+1′]′ can be viewed as a Markov chain. To see this, conclude from equation (17) that

where ϒ = [In : 0 : … : 0]′ (np × n) and, for simplicity,

Because εt and ηt are independent of Zt−1 by assumption this shows that Zt is a Markov chain on

.
We shall use the concept of V-geometric ergodicity of a Markov chain (see Meyn and Tweedie, 1993, p. 355). Here V is a real valued (Borel) measurable function defined on the state space of the considered Markov chain and such that V(·) ≥ 1. For such a function V, the Markov chain Zt is said to be V-geometrically ergodic if there exists a probability measure π on the Borel sets of

and constants ϱamp; < 1 and Mx < ∞ (depending on x) such that

The definition also assumes that the function V is integrable with respect to the probability measure π. The weakest form of this definition results when V ≡ 1. Then the Markov chain Zt is said to be geometrically ergodic. Geometric ergodicity entails that the t-step transition probability measure Pt(x,·) defined on the Borel sets of

by Pt(x,A) = P(Zt ∈ A|Z0 = x) converges at a geometric rate and for all

to the probability measure π(·) with respect to the total variation norm.
Geometric ergodicity implies stationarity of the process Zt if the distribution of the initial value Z0 is defined by the probability measure π (see Meyn and Tweedie, 1993, pp. 230–231). Of course, in this case the process zt is also stationary. Another convenient feature of V-geometric ergodicity is that it implies existence of moments. For instance, if the Markov chain Zt is initialized from the stationary distribution, existence of the expectation of v(Zt) for all v such that |v(·)| ≤ V(·) follows immediately from the definition of V-geometric ergodicity. Of course, it is a direct consequence of (21) that, for such a v, the conditional expectation E(v(Zt)|Z0 = z) converges at a geometric rate to the corresponding expectation taken with respect to the stationary distribution. Finally, in the case of stationary initial values geometric ergodicity is equivalent to β-mixing with geometrically decaying mixing numbers, and, with appropriate conditions on initial values, it implies the previously mentioned β-mixing property even when the initial values are nonstationary (see Liebscher, 2005). As is well known, β-mixing implies strong mixing and that conventional limit theorems apply (for definitions of these mixing concepts, see, e.g., Doukhan, 1994).
Now we can state the main result of this paper. Its proof is based on a slight modification of an idea due to Liebscher (2005). This modification makes it possible to obtain (1 + ∥x∥2)-geometric ergodicity and, hence, existence of second moments instead of mere geometric ergodicity.
THEOREM 1. Let yt(t = 1,2,…) be a stochastic process generated by (8) and zt as defined in (15). Suppose that Assumptions 1 and 2, or alternatively 2′, are satisfied. Then, if conditions (10) and (19) also hold the process Zt = [zt′ … zt−p+1′]′ is a V-geometrically ergodic Markov chain with V(x) = 1 + ∥x∥2. Thus, there exists a choice of initial values z−p+1,…, z0 such that the process zt is both strictly stationary and second-order stationary and, moreover, β-mixing with geometrically decaying mixing numbers. Hence, there exists a choice of initial values y−p,…, y0 such that the same is true for the process [(β′yt)′ (c⊥′Δyt)′]′.
Theorem 1 shows that in our nonlinear context the linear combinations β′yt and the differences Δyt are stationary just as in the standard linear case. Special cases are obtained with different choices of the matrix S. The most interesting special case probably assumes that the functions hs only depend on the disequilibrium errors β′yt−1. Then S′ = [Ir 0], and, to meet condition (10), we have to assume that Γsj = Γs1 j (j = 1,…, p − 1) holds for some s1 ∈ 1 and all s ∈ 2. Of course, these restrictions also need to be taken into account in condition (19). Note that equality of Γsj (j = 1,…, p − 1) is not required for all s = 1,…, m although this may be usual in practice and necessarily holds when the set 1 only contains a single element.
The preceding discussion particularly shows how to obtain sufficient conditions for the stationarity of β′yt and Δyt in models (1)–(3) discussed in Section 2 and also their extensions obtained by allowing for regime dependent intercept terms and error covariance matrices. In these cases the index set 1 is defined by 1 = {1,3}. Omitting the middle regime gives similar sufficient conditions for the stationarity of β′yt and Δyt in the corresponding two-regime models with only one threshold discussed at the end of Section 2. Neither of these cases can be handled with the previous results of Bec and Rahbek (2004) and Saikkonen (2005).
Theorem 1 does not provide a full extension of Granger's representation theorem. For that we would need to show that the levels yt are I(1) or, more precisely, that there are exactly n − r linearly independent linear combinations of yt that form an I(1) process, possibly around a deterministic trend. Such results are obtained by Bec and Rahbek (2004) and Saikkonen (2005) but only in special cases where the index set 1 contains a single element. As equations (8) and (11) show, the nonlinearity is then only due to the function g[dagger](·,ηt), which is dominated by a linear function in the sense that E∥g[dagger](x,ηt)∥ = o(∥x∥) as ∥x∥ → ∞ (see the discussions after Assumptions 2(b) and 2′(b)). The nonlinearity is therefore “small,” and methods similar to those used in the linear case can be applied to show the existence of exactly n − r (linearly independent) I(1) components. Obtaining similar results in the present case is more difficult because considerably more complicated nonlinearity is allowed.
The definition of an I(1) process used by Bec and Rahbek (2004) and Saikkonen (2005) is that, possibly after appropriate centering, the random vector T−1/2y[Ts] obeys a functional central limit theorem, that is, converges weakly to a Brownian motion. The rank of the limiting Brownian motion equals the rank of the long-run covariance matrix of the differenced process Δyt and therefore determines the number of searched I(1) components. However, in our context Δyt can be a very complicated nonlinear process, and therefore the rank of its long-run covariance matrix is not easy to find. The functional central limit theorem itself does not pose problems because it is implied by Theorem 1. Because β′yt is stationary the number of I(1) components is obviously at most n − r, but whether it is n − r is not obvious. This is due to the well-known fact that in nonlinear processes unit roots need not mean nonstationarity (see, e.g., Balke and Fomby, 1997, p. 630, and the references therein).3
Specifically, Balke and Fomby (1997, p. 630) note that first-order scalar threshold autoregressive processes with autoregressive coefficient equal to unity in each regime are stationary (or geometrically ergodic) if the signs of the intercept terms in the highest and lowest regimes are chosen suitably. The application of Liebscher's condition based on the joint spectral radius to this special case requires that the autoregressive coefficients in the highest and lowest regimes are smaller than one in absolute value (see Liebscher, 2005, Thm. 5). This shows that, in general, Liebscher's condition is not necessary for stationarity (or geometric ergodicity).
We shall leave the problem of finding the number of I(1) components for future research. In practice one may try to find it by simulation. For given values of the parameters of the model and distributions of the error terms εt and ηt (or only εt) one can simulate a long realization of the considered process and estimate the long-run covariance matrix of the differences Δyt. Using this estimate one can then study whether the rank of the long-run covariance matrix of Δyt is n − r or some smaller value. Statistical tests may also be used here.
As already pointed out, Theorem 1 applies to models not covered in previous work. It is also known that, in some cases, the assumed condition (19) restricts the parameters of the model less than some alternative sufficient conditions for geometric ergodicity (see Liebscher, 2005, Sect. 7). Unfortunately, however, condition (19) is generally hard to check in practice, and its implications on the parameters of the model are difficult to illustrate. As a very simple illustration, consider the case p = 1. Using the previously mentioned fact that condition (19) can equivalently be expressed in terms of the coefficient matrices of Bs*(z) one obtains the condition ρ({Ir + β′αs, s ∈ 1}) < 1. For r > 1 even this condition is unillustrative, but in the special case r = 1 it reduces to −2 < β′αs < 0, s ∈ I1. To simplify further, suppose that only the first components of the vectors αs, denoted by αs1 (s ∈ 1), are nonzero and normalize the first (nonzero) component of β to unity. Then the disequilibrium error only affects the first component of the process, and condition (19) becomes −2 < αs1 < 0, s ∈ I1. In the special cases of Section 2 we have m = 3 and I1 = {1,3}. Then only the first equation of the model is error correcting with negative coefficients α11 and α31 (larger than −2) in the lowest and highest regimes, respectively, and with the forms of adjustment depending on the slightly different adjustment mechanisms of the three models (1)–(3). Whether adjustment takes place in some way in the middle regime depends on the value of the parameter α21, which is not involved in condition (19) and can take any value.
In more general models an algorithm and MATLAB program provided by Gripenberg (1997) can, in principle, be used to find an arbitrarily small interval containing the joint spectral radius

. However, the needed computations can be infeasible unless the dimension of the matrices Bs (s ∈ I1) is reasonably small. This is reflected by the known fact that the problem of checking condition (19) is NP-hard, that is, cannot be solved in a number of steps that is a polynomial function of the dimension (see Blondel and Nesterov, 2005, Sect. 6). Upper and lower bounds of the joint spectral radius are therefore of interest. As already noticed, maxi∈1 ρ(Bi) provides a simple lower bound for

that can be used as a first check of condition (19).
4One can also consider general convex combinations of the matrices Bs, s ∈ 1, because it is known that

for all as such that [sum ]s∈1 as = 1 (see Blondel and Nesterov, 2005, Lem. 1).
For convenience and without loss of generality, consider the matrices B1 and B2. We denote by Dq the duplication matrix of dimension q2 × ½q(q + 1) and by Lq the elimination matrix of dimension ½q(q + 1) × q2 (for definitions, see Lütkepohl, 1996, Chs. 9.5 and 9.6). From Theorem 5 of Blondel and Nesterov (2005) one obtains the inequalities

where Bi[1] = Lnp(Bi [otimes ] Bi)Dnp with [otimes ] the Kronecker product. Thus, we have an upper bound and lower bound for the joint spectral radius ρ(B1,B2). The computation of these bounds only requires computing the spectral radius of a single matrix, B1[1] + B2[1]. However, for typical values of n and p the order of the matrix B1[1] + B2[1] is much larger than that of the original matrices B1 and B2. Specifically, the matrices B1 and B2 are of order np × np whereas B1[1] + B2[1] is of order q1 × q1 where q1 = ½np(np + 1). This dimensionality problem becomes even more critical if better bounds are needed. To see this, set Bi[2] = Lq1(Bi[1] [otimes ] Bi[1])Dq1 and note that the preceding bounds can be improved to

(see Blondel and Nesterov, 2005, discussion following Thm. 5). Further improvements are possible by continuing the preceding idea iteratively so that the jth step results in bounds of the form

Clearly, the joint spectral radius ρ(B1,B2) can be approximated by arbitrary accuracy by increasing the number of steps. However, the order of the matrix whose spectral radius needs to be computed at each step increases quickly, and even for moderate values of n and p the required computations become infeasible after the first few steps. For instance, if np = 10 (e.g., n = 5 and p = 2) the orders of the matrices Bi[1] and Bi[2] are already as large as 55 × 55 and 1,540 × 1,540, respectively.
4. CONCLUSION
In this paper we have extended previous results on the stationarity of long-run equilibrium relations and differenced observations in nonlinear VAR error correction models characterized by regime switches. Our extensions are based on a recent idea of using the joint spectral radius of a (bounded) set of square matrices to establish geometric ergodicity in nonlinear autoregressive models. This approach yields results that, in some cases, are known to be less restrictive than counterparts obtained with previous alternatives, but it involves the practical difficulty that the computation of the joint spectral radius is generally hard. One may hope, however, that the active research on joint spectral radius will be able to alleviate these computational difficulties in the future (cf. Blondel and Nesterov, 2005, Sect. 8). Future research is also needed to determine theoretically the exact number of I(1) components in the considered models, which were not found in this paper. Finally, it would be interesting to explore extensions to models in which the long-run equilibrium relations are allowed to be regime dependent.
APPENDIX
Proof of Theorem 1. The idea is to apply Theorem 15.0.1 of Meyn and Tweedie (1993), which first requires establishing irreducibility and aperiodicity of the Markov chain Zt. In addition to this, identification of appropriate small sets is needed. We shall assume that the set 2 is nonempty. If this is not the case the needed modifications are straightforward and will not be discussed. Mostly it suffices to interpret summation over s ∈ 2 as zero.
First note that a factorization similar to that obtained for the polynomial matrices As(z) in (13) can also be obtained for the polynomial matrices As(z). In other words, we have As(z) = Q−1Bs*(z)P(z), s = 1,…, m, where, with obvious notation, Bs*(z) = Q[Γs(z)c(1 − z) − αs z : Γs(z)β⊥] is a polynomial matrix such that Bs*(0) = In. However, unlike in (13) the condition det Bs*(z) ≠ 0, |z| ≤ 1, is not guaranteed to hold for all s = 1,…, m but only for s ∈ 1. These facts can be inferred from the assumption rk(β) = r and the proof of Lemma 1 of Saikkonen (2005) by observing that this proof only uses Assumptions 3(a) and (c) to obtain the condition on det Bs*(z).
Using the preceding factorization instead of (13) it is straightforward to proceed as in Section 3 and show that the original model can be transformed to

where the coefficient matrices Bjs are obtained from

.
Now consider the case of Assumption 2 so that in (A.1) hs(S′Yt−1,ηt) = hs(S′Yt−1) and

are independent of ηt. Recall that the matrices Ωs (s = 1,…, m) are assumed to be positive definite so that, by Assumption 2(a), the smallest eigenvalue of the matrix H(S′Jx) is bounded away from zero on compact subsets of

. Using this fact and Assumption 1 we find from (A.1) and Theorem 2.2(ii) of Cline and Pu (1998) that the Markov chain Zt is an irreducible and aperiodic T-chain and consequently all compact sets of

are small (see Meyn and Tweedie, 1993, Thms. 5.5.7 and 6.2.5). To see that the same is true when hs(S′Yt−1,ηt) = 1(φd(S′Yt−1,ηt) ∈ Rs), conclude from (A.1) that the conditional distribution of zt given Zt−1 = x is characterized by the density

where fs(x) equals

evaluated at Zt−1 = x and φε signifies the density of εt. Clearly,

Assumptions 1 and 2′(a) imply that the right-hand side is bounded away from zero on compact subsets of

. Thus, the desired conclusion again follows from Cline and Pu (1998) (see Theorem 2.2(ii) or 2.3 and also Example 2.3 in that paper).
The next step is to verify an appropriate version of condition (15.3) of Meyn and Tweedie (1993, p. 355). This is first done by assuming that hs(S′Yt−1,ηt) = 1(φd(S′Yt−1,ηt) ∈ Rs). Our proof is based on ideas similar to those in the proof of Theorem 3 of Liebscher (2005). First, because

we can find a real number

and a positive integer N such that

(cf. Liebscher, 2005, (33)). Next define the function

by

We need to consider the conditional expectation of q(Zt) given Zt−1 = x. To this end, denote

and conclude from (20) that

In what follows, c, c1, c2, … will denote positive real numbers. Clearly,

Thus, because H(S′Jx,ηt) is bounded and εt and ηt are independent the second term on the right-hand side of (A.4) satisfies

Next consider the third term on the right-hand side of (A.4) and first notice that

where the latter inequality is an immediate consequence of the definitions (see (11) and (A.3)). Thus,

As in (A.5) the last expectation can be bounded by a constant. This fact combined with (A.4) and (A.5) shows that

Now consider the first term on the right-hand side of (A.6) and conclude from (A.3) that

For the second term on the right-hand side we have

From this and the definition of g[dagger](·,ηt) (see (11)) it follows that

The third term on the right-hand side of (A.7) is dominated by

By the definition of g[dagger](·,ηt) we thus obtain

Combining the preceding derivations we can bound the right-hand side of (A.7) and hence the right-hand side of (A.6) and obtain

where

By the definition of

(a.s.), and therefore

Hence,

and this holds for all

. It is easy to check that it also holds with j = 0 if on the left-hand side we omit the supremum and set A = Inp. Thus, we can conclude that, for all

,

In view of (A.2) the third term on the right-hand side is bounded by ρ2∥x∥2, and it follows that, for all

,

where R2(x) = 1 − ρ2 + c12 R1(x).
By the definition of q(x), we have q(x) ≥ 1 + ∥x∥2, and therefore for all

,

From the definition of R1(x) and Assumption 2′(b) it follows that R1(x) = o(∥x∥2) as ∥x∥ → ∞. Hence, the same is true for R2(x), and we can find a real number M such that

On the other hand, the definition of q implies that

Thus, because R2(x) is bounded for ∥x∥ ≤ M the same is true for E(q(Zt)|Zt−1 = x) (see (A.9)). Hence, we can find a constant b such that

Because compact sets are small this shows that condition (15.3) of Meyn and Tweedie (1993, p. 355) holds with the function q. Hence, Theorem 15.0.1 of the same reference implies that the Markov chain Zt is q-geometrically ergodic and, because q(x) ≥ 1 + ∥x∥2, also (1 + ∥x∥2)-geometrically ergodic, as was to be shown.
Now consider the case hs(S′Yt−1,ηt) = hs(S′Yt−1) and define the bounded set of matrices

. By the definition of the matrices Bs, any

is a linear combination of matrices belonging to

. Recall that, by assumption,

. This is equivalent to the existence of a matrix norm ∥·∥* and a real number ρ ∈ (0,1) such that ∥Bs∥* ≤ ρ for all s = 1,…, m (see Shih, Wu, and Pang, 1997, Thm. 1; Liebscher, 2005, Thm. 1). Thus, for

,

and, by the same argument as before, this is equivalent to

.
The preceding discussion implies that (A.2) can also be assumed with the set

replaced by

. This means that the proof can be continued by following the steps in the case hs(S′Yt−1,ηt) = 1(φd(S′Yt−1,ηt) ∈ Rs). The function q is defined in the same way as before, and in place of G(Zt−1,ηt) we have

where

Replacing G(x,ηt) in (A.4) by G(x) and proceeding in the same way as in the previous case it is straightforward to check that in place of (A.6) we now have

where

By the definition of g[dagger](·),

Hence, for the second term on the right-hand side of (A.12) we have

In the last inequality we have used the Cauchy–Schwartz inequality and the assumption 0 ≤ hs(S′Jx) ≤ 1 to get a convenient upper bound.
The third term on the right-hand side of (A.12) can be treated in the same way as the third term on the right-hand side of (A.7). We get

Using the preceding inequalities we can bound the right-hand side of (A.12) and hence the right-hand side of (A.11). Thus, we find that, for all

,

where

Because

this implies that

Obviously, (A.13) differs from (A.8) only in that

is replaced by

and that constant terms in R3(x) are different from their counterparts in R1(x). Thus, repeating the arguments following (A.8) we can show that an analogue of (A.10) holds and further that the Markov chain Zt is (1 + ∥x∥2)-geometrically ergodic.
As discussed in Section 3, the assertions on stationarity and β-mixing of zt follow from the (1 + ∥x∥2)-geometric ergodicity of Zt. Finally, the results obtained for the Markov chain Zt readily yield similar results for the process [(β′yt)′ (c⊥′Δyt)′]′, which is a linear transformation of zt (see (15)). This completes the proof.


