


1 Introduction
Usually, repeated games (Fudenberg & Tirole, Reference Fudenberg and Tirole1991; Osborne & Rubinstein, Reference Osborne and Rubinstein1994; Mailath & Samuelson, Reference Mailath and Samuelson2006) are used as an important mathematical formalism to model and study long-term economic interactions between multiple self-interested parties (individuals or groups of individuals). They open attractive perspectives in modeling multiagent interactions (Littman & Stone, Reference Littman and Stone2005; Conitzer & Sandholm, Reference Conitzer and Sandholm2007). Repeated games have also been widely employed by the researchers for modeling fairness, reputation, and trust in the situations of repeated interactions between self-interested individuals (Ramchurn et al., Reference Ramchurn, Huynh and Jennings2004; Mailath & Samuelson, Reference Mailath and Samuelson2006; Jong et al., Reference Jong, Tuyls and Verbeeck2008).
Computer science (namely, the research on multiagent systems (MAS)) mainly considered repeated games as an environment in which multiagent algorithms evolved, often during only an initial phase of learning or mutual adaptation. As a matter of fact, the fundamental repetitive property of repeated games has been typically reduced to a way to give to an adaptive (or learning) algorithm a sufficient time to converge (often, jointly with another learning agent) to a fixed behavior (Bowling & Veloso, Reference Bowling and Veloso2002; Banerjee & Peng, Reference Banerjee and Peng2003; Conitzer & Sandholm, Reference Conitzer and Sandholm2007; Burkov & Chaib-draa, Reference Burkov and Chaib-draa2009). Thus, the repetitive nature of the game has only been considered as a permissive property, that is, a property that permits implementing an algorithm. However, repeated games possess another important property. This is a constraining property, which, as we will demonstrate in this overview, generously expands and, at the same time, rigorously limits the set of strategies that rationalFootnote 1 agents can adopt. A few exceptions are Papadimitriou (Reference Papadimitriou1992) and Papadimitriou and Yannakakis (Reference Papadimitriou and Yannakakis1994), two important but relatively ancient papers on the complexity of computing best-response strategies for repeated games, Littman & Stone (Reference Littman and Stone2005) describing an efficient algorithm for solving two-player repeated games, and Borgs et al. (Reference Borgs, Chayes, Immorlica, Kalai, Mirrokni and Papadimitriou2008) presenting an important inefficiency result about the solvability of general multiplayer repeated games.
The behavior to which the majority of the existing multiagent algorithms for repeated games converge is usually a stationary equilibrium. The player's behavior is called stationary when it is independent of the history of the game: the player always draws its actions from the same probability distribution, regardless of the actions executed by the opponent players in the past. This means that a player that adopts a stationary behavior acts in a repeated game (consisting of the player sequentially playing a certain stage-game with a constant set of opponents) as if each repetition of the stage-game was played with an entirely new set of opponents.
By focusing on stationary strategies, we often omit solutions having a greater mutual utility for the players. Consider the example of Prisoner's Dilemma shown in Figure 1. In this specific game, there are two players, called Player 1 and Player 2. Each player has a choice between two actions: C (for cooperation) and D (for defection, i.e., non-cooperation). The players perform their actions simultaneously; a pair of actions is called an action profile. Each action profile induces a corresponding game outcome. For each outcome, a player-specific payoff function specifies a numerical payoff obtained by the corresponding player. For example, when Player 1 plays action C and Player 2 plays action D, the action profile is (C, D) and the corresponding payoffs of players are, respectively, −1 and 3. To the so-called cooperative outcome (C, C) there corresponds the payoff profile (2, 2); and to the non-cooperative outcome (D, D) there corresponds the payoff profile (0, 0).
The payoff matrix of Prisoner's Dilemma

A combination of strategies, where each player always plays D no matter what the other does is a stationary Nash equilibrium in the repeated Prisoner's Dilemma. As it was mentioned above, the majority of multiagent algorithms for repeated games, with the exception of the algorithm by Littman and Stone (Reference Littman and Stone2005), content themselves with this sort of solution.
Now let us suppose that both players playing Prisoner's Dilemma know that the game with the same opponent will continue forever (or that the probability of continuation is close enough to 1). Additionally, let us suppose that when choosing between actions C or D, Player  $$\[--><$>i\, \in \,\left\{ {1,2} \right\}<$><!--$$
, knows that its opponent will start by playing C, but whenever Player i plays D, the opponent will start playing D until Player i reverts back to playing C. Such opponent's behavior is usually referred to in the literature as the ‘Tit-For-Tat’ strategy (TFT). If, before the game starts, both players were told that the opponent will behave according to TFT, no player would probablyFootnote 2 try to play D. The reason for this would be that an infinite sequence of cooperative outcomes generates for each player an infinite sequence of that player's payoffs (2, 2, 2, 2,…). This corresponds to an average per stage payoff of 2. On the other hand, the player's behavior in which it plays D once and then reverts to playing C forever, yields the average payoff (AP) inferior to 2, because the sequence of the player's payoff will be (3, −1, 2, 2,…). Finally, playing D forever will correspond to the sequence of payoffs (3, 0, 0, 0,…) whose AP tends to 0. It is easy to verify that no other behavior in which some player plays D can bring to this player an AP superior or equal to 2 (assuming that the other player follows TFT). In such a situation, the rationality principle dictates playing C whenever the other player does the same. Observe that in this repeated game, the pair of TFT strategies is also a Nash equilibrium: when one player behaves according to TFT, the other one cannot do better than playing according to TFT as well. Furthermore, the per stage payoff of each player in this Nash equilibrium, 2, is higher than the payoff of the stationary Nash equilibrium, that is, 0.
Repeated game theory studies the cases similar to the above example. It provides theorems about the existence and the properties of equilibria similar to TFT in different settings. These settings vary upon the long-term payoff criteria adopted by the players, the observability by the player of the actions made by the opponents, and the patience of the players (i.e. how they value the future payoffs, ‘promised’ by the proposed behavior, compared with the present stage-game payoff). Furthermore, a number of existing approaches permit constructing, in different games, the strategies in the spirit of TFT (Abreu, Reference Abreu1988; Judd et al., Reference Judd, Yeltekin and Conklin2003; Littman & Stone, Reference Littman and Stone2005; Burkov & Chaib-draa, Reference Burkov and Chaib-draa2010).
In this overview paper, we will talk about the solution notions of a repeated game; we see the latter as a general model for repeated multiagent interactions. We will present a number of important theoretical results originating from economics, the so-called folk theorems. The main property that distinguishes our overview of repeated game theory from a number of the existing references (Aumann, Reference Aumann1981; Pearce, Reference Pearce1992; Benoit & Krishna, Reference Benoit and Krishna1999; Mailath & Samuelson, Reference Mailath and Samuelson2006; Gossner & Tomala, Reference Gossner and Tomala2009), is its strict focus on the applicability of the existing theory to the artificial agents, that is, those that use a limited amount of memory and have limited computational capabilities.
2 Repeated game
The description of a repeated game starts with a stage-game (also referred to as a matrix game or a normal form game).
2.1 Stage-game
Definition 1 (Stage-game)A (finite) stage-game is a tuple  $$\[--><$>\left( {N{\rm{,}}\,{{{\left\{ {{{A}_i}} \right\}}}_{i\, \in \,N}},{{{\left\{ {{{r}_i}} \right\}}}_{i\, \in \,N}}} \right) <$><!--$$
. In a stage-game, there is a finite set N, |N| ≡ n, of individual players that act (i.e. make a move in the game) simultaneously. Player i ∈ N, has a finite set Ai of pure actions in its disposal. When each player i among N chooses a certain action ai ∈ Ai, the resulting vector a ≡ (a 1 ,…, an) is called an action profile and corresponds to a specific stage-game outcome. Each action profile belongs to the set of action profiles A ≡ ×iAi. A player-specific payoff function ri specifies player i’s numerical reward for different game outcomes, that is,
 $$\[--><$>{{r}_i}\,{\rm{:}}\,A\, \mapsto \,{\Bbb R}<$><!--$$
.
We denote the profile of payoff functions as r ≡ ×iri. Given an action profile, a, v = r(a) is called a payoff profile. A mixed action αi of player i is a probability distribution over player's actions, that is,  $$\[--><$>{{\alpha }_i}\, \in \,{\rm{\rDelta }}({{A}_i}) <$><!--$$
. The payoff function is extended to mixed actions by taking expectations.
The set of players’ stage-game payoffs that can be generated by the pure action profiles is denoted as
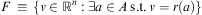 $$ F\, \equiv \,\left\{ {v \in {{{\Bbb R}}^n} :\exists a \in A\,{\rm{s}}{\rm{.t}}{\rm{.}}\,v = r{\rm{(}}a{\rm{)}}} \right\} $$
The set F † of feasible payoffs is the convex hull of the set F, that is, F † = co F. In other words, F † is the smallest convex set containing F. Feasible payoffs is an important concept in the context of repeated games. Observe that any point belonging to F †\F is a convex combination of two or more points from the set F. Therefore, any expected per stage payoff profile that can be obtained by the players in the repeated game belongs to the set F † of feasible payoffs.
A payoff profile  $$\[--><$>v \in {{F}^&#x2020; } <$><!--$$
is inefficient if
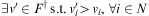 $$\[--><$>\exists v{\rm{'}} \in {{F}^&#x2020; } \,{\rm{s}}{\rm{.t}}{\rm{.}}\,v^{\rm{\prime}}_{i} \gt v{\pre}_{i},\,\forall i \in N <$><!--$$
. Otherwise,
 $$\[--><$> v <$><!--$$
is called Pareto efficient.
An important concept in both MAS and economics is one of individual rationality. This concept is closely related to the notion of minmax. The minmax payoff  $$\[--><$>{{\underline{v} }_i} <$><!--$$
of player i is defined as
 $${{\underline{v} }_i}\, \equiv \,{\mathop{{\min }}\limits_{{{{\alpha }_{{\rm{ - }}i}} \in \times {{\,}_{j\, \ne \,i}}{\rm{\rDelta }}({{A}_j})}}} \,{\mathop{{\max }}\limits_{{{{a}_i} \in {{A}_i}}}} \,{{r}_i}\,({{a}_i},{{\alpha }_{{\rm{ - }}i}})$$
The minmax payoff of player i is the minimal payoff, which it can guarantee itself regardless of the strategies chosen by the opponents. A payoff profile v is called individually rational if, for any  $$\[--><$>i,\,{{v}_i}\geq {{\underline{v} }_i} <$><!--$$
. An important remark is that any player in any game can always obtain in expectation at least its minmax payoff given the knowledge of the opponents’ action profile.
A mixed action minmax profile for player  $$\[--><$>i,\,\underline{{{{\alpha }}}}^i} }} = (\underline{a}}}} _{i}^{i}, {{\underline{{{{\alpha }}}}^i}} }} }_{ - i}}) <$><!--$$
, is a mixed action profile with the property that
 $$\[--><$>\underline{a} _{i}^{i} <$><!--$$
is player i's stage-game best response to the mixed action profile
 $$\[--><$>{{\underline{{{{\alpha }}}}^i} }} }_{ - i}} <$><!--$$
of the remaining players, and
 $$\[--><$>{{r}_i}(\underline{{{{\alpha }}}}^i } ) = \underline{{{{v}}}}_i}}} <$><!--$$
.
We define the set of feasible and individually rational payoffs and the set feasible and strictly individually rational payoffs as, respectively,  $$\[--><$>{{F}^{&#x2020; \ast}} \, \equiv \,\{ v \in {{F}^&#x2020; } :{{v}_i}\geq {{\underline{v} }_i} \ \forall i \in N\}<$><!--$$
and
 $$\[--><$>{{F}^{&#x2020; + }} \, \equiv \,\{ v \in {{F}^&#x2020; } :{{v}_i} \gt {{\underline{v} }_i} \ \forall i \in N\} <$><!--$$
.
In certain situations, the players cannot be allowed to randomize over their actions. In this case, the pure minmax payoff of player i, is defined as
 $$\underline{{v}}} _{i}^{p} \, \equiv \,{\mathop{{{\rm{min}}}}\limits_{{{{a}_{{\rm{ - }}i}} \in {{\times }_{j\, \ne \,i}}{{A}_j}}}} \ {\mathop{{\max }}\limits_{{{{a}_i} \in {{A}_i}}}} \,{{r}_i}\left( {{{a}_i},{{a}_{{\rm{ - }}i}}} \right).$$
A pure action minmax profile for player  $$\[--><$>i,\underline{{\,{{a}}}}^i} }} = (\underline{a} _{i}^{i}, {{\underline{{{{a}}}}^i} }} }_{ - i}}) <$><!--$$
, is an action profile with the property that
 $$\[--><$>\underline{a} _{i}^{i} <$><!--$$
is player i's stage-game best response to the action profile
 $$\[--><$>{{\underline{{{{a}}}}^i} }} }_{ - i}} <$><!--$$
of the remaining players, and
 $$\[--><$>{{r}_i}({{\underline{a} }^i} ) = \underline{v} _{i}^{p} <$><!--$$
.
Similarly, we define the set of feasible and pure individually rational payoffs as  $$\[--><$>{{F}^{&#x2020; \astp}} \, \equiv \,\{ v \in {{F}^&#x2020; } :{{v}_i}\geq <$><!--$$
 $$\[--><$>\underline{v} _{i}^{p} \,\forall i \in N\} <$><!--$$
and the set of feasible and strictly pure individually rational payoffs as
 $$\[--><$>{{F}^{&#x2020; + p}} \, \equiv \,\{ v \in {{F}^&#x2020; } :{{v}_i} \gt \underline{v} _{i}^{p} \ \forall i \in N\} <$><!--$$
.
Finally, we define the two most restrictive sets of individually rational payoffs, the set of pure individually rational payoffs and the set of strictly pure individually rational payoffs, respectively, as  $$\[--><$>{{F}^{{\rm{\ast}}p}} \, \equiv \,\{ v \in F:{{v}_i}\geq \underline{v} _{i}^{p} \,\ \forall i \in N\} \,\,{\rm{and}}\,\,{{F}^{\, + \,p}} \, \equiv \,\{ v \in F:{{v}_i} \gt \underline{{v_{i}^{p} {}}} \ \forall i \in N\} <$><!--$$
.
A number of theoretical results existing in the literature (Osborne & Rubinstein, Reference Osborne and Rubinstein1994; Mailath & Samuelson, Reference Mailath and Samuelson2006) have only been proven when the players’ payoffs were assumed to lie in the more restricted sets, such as  $$\[--><$>{{F}^{&#x2020; \ast p}} <$><!--$$
or
 $$\[--><$>{{F}^{ + p}} <$><!--$$
. Further throughout the paper, we will always assume players to be individually rational in either sense. The specific context will be indicated where necessary.
For the example of Prisoner's Dilemma shown in Figure 1, the four sets F, F †, F †+ and F †* are depicted in Figure 2. The set F of pure action payoffs includes four bold dots denoted as r(C, D), r(C, C), r(D, C) and r(D, D) These dots represent the payoff profiles for the respective pure action profiles. The set F † of feasible payoffs is the whole diamond-shaped area formed by the four dots and the bold lines that connects them. The set F †* of feasible and individually rational payoffs is shown as the shaded sector inside this diamond-shaped area including the bounds. The set F †+ of feasible and strictly individually rational payoffs is a subset of F †* that excludes the axes. As one can see, in Prisoner's Dilemma, the sets F †+p and F †*p coincide with, respectively, F †+ and F †*.
The sets F, F †, F †*, and F †+ in the Prisoner's Dilemma from Figure 1. The set F includes four bold dots denoted as r(C, D), r(C, C), r(D, C), and r(D, D). The set F † is the whole diamond-shaped area formed by the four dots and the bold lines that connects them. The set F †* is shown as the shaded sector inside this diamond-shaped area including the bounds. The set F †+ is a subset of F †* that excludes the axes
2.2 Repeated game
In the (infinitely) repeated game, the same stage-game is played in periods t = 0, 1, 2,…, also called repeated game iterations, repetitions or stages. At the beginning of each iteration, the players choose their actions, which consequently form an action profile. Then they simultaneously play this action profile, and collect the stage-game payoffs corresponding to the resulting stage-game outcome. Then repeated game passes to the next iteration.
The set of repeated game histories up to iteration t is given by H t ≡ ×tA. The set of all possible histories is given by  $$\[--><$>H = \bigcup _{{t = 0}}^{\infty } {{H}^t} <$><!--$$
. For instance, a history h t ∈ H is a stream of action profiles arose starting from period 0 up to period t − 1:
 $${{h}^t} = ({{a}^0}, {{a}^1}, {{a}^2}, \ldots, {{a}^{t{\rm{ - }}1}} )$$
A pure strategy σi of player i in the repeated game is a mapping from the set of all possible histories to the set of player i's actions, that is, σi : H ↦ Ai. A mixed strategy of player i is a mapping σi : H↦Δ(Ai). Like in the stage-games, a pure strategy is a special case of a mixed strategyFootnote 3.
A subgame (or, continuation game) of an original repeated game is a repeated game based on the same stage-game as the original repeated game but started from a given history h t. Imagine a subgame induced by a history h t. The behavior of players in this subgame after a history  $$\[--><$>{{h}^\tau } \in H <$><!--$$
will be identical to the behavior of players in the original repeated game after the history
 $$\[--><$>{{h}^t} {{h}^{\rm{\tau }}} <$><!--$$
, where
 $$\[--><$>{{h}^t} {{h}^\tau } \, \equiv \,{{h}^t} \cdot {{h}^\tau } \, \equiv \,({{h}^t}, {{h}^\tau } ) <$><!--$$
is a concatenation of two histories. Given a strategy profile
 $$\[--><$>\sigma \, \equiv \,{{({{\sigma }_i})}_i}{{\,}_{ \in \,N}} <$><!--$$
and a history h t, we denote the subgame (or, continuation) strategy profile induced by h t as
 $$\[--><$>\sigma {{{\rm{|}}}_{{{h}^t} }} <$><!--$$
.
An outcome path in a repeated game is an infinite stream of action profiles a ≡ (a 0, a 1, …). A finite prefix of length t of an outcome path corresponds to a history in H t + 1. A profile σ of strategies of players induces an outcome path  $$\[--><$>\bf a{\rm{(}}\sigma {\rm{)}}\, \equiv \,\left( {{{a}^{\rm{0}}} {\rm{(}}\sigma {\rm{)}},{{a}^{\rm{1}}} {\rm{(}}\sigma {\rm{)}},{{a}^{\rm{2}}} {\rm{(}}\sigma {\rm{)}}, \ldots } \right) <$><!--$$
as follows:
 $$\openup 3pt\matrix{ {{a}^{\rm{0}}} \left( \sigma \right) \sim \sigma \left( {\,{\varnothing }} \right), \hfill\cr {{a}^{\rm{1}}} \left( \sigma \right) \sim \sigma \left( {\,{{a}^{\rm{0}}} \left( \sigma \right)} \right), \hfill\cr {{a}^{\rm{2}}} \left( \sigma \right) \sim \sigma \left( {{{a}^{\rm{0}}} \left( \sigma \right),{{a}^{\rm{1}}} \left( \sigma \right)} \right), \hfill\cr \ldots, \hfill$$
where we denote by a t(σ) ~ σ(h t) the action profile played by the players at iteration t after the history h t according to the strategy profile σ. Obviously, in any two independent runs of the same repeated game, a pure strategy profile deterministically induces the same outcome path. On the contrary, at each iteration t, the action profile a t(σ) belonging to the outcome path induced by a mixed strategy profile σ is a realization of the random process σ(h t).
In order to compare two repeated game strategy profiles in terms of the payoff they induce to a player, we need a criterion permitting comparing infinite payoff streams. The literature (Myerson, Reference Myerson1991; Osborne & Rubinstein, Reference Osborne and Rubinstein1994) usually suggests two criteria: (i) the average payoff (AP) criterion, called also ‘the limit of the means’ criterion, and (ii) the discounted AP (DAP) criterion.
Notice that to an infinite outcome path a = (a 0, a 1, …), there uniquely corresponds an infinite sequence v = (v 0, v 1, …) of stage-game payoff profiles. We can now introduce the notion of a long-term payoff criterion.
Definition 2 (Average payoff criterion)Given an infinite sequence of payoff profiles v = (v 0, v 1, …), the average payoff (AP) ui (v) of this sequence, for player i, is given by
 $${{u}_{\rm{i}}}\left( \bf v \right) \equiv \mathop {\lim }\limits_{T \rightarrow \infty } \frac{1}{T}\mathop{\sum}\limits_{t{\rm{ = 0}}}^T {v_{i}^{t} } $$
Definition 3 (Discounted average payoff criterion)Given an infinite sequence of payoff profiles v = (v 0, v 1,…), the discounted average payoff (DAP) ui(v) of this sequence, for player i, is given by
 $${{u}_i}\left(\bf v \right) \equiv \left( {1{\rm{ - }}\gamma } \right)\mathop{\sum}\limits_{t = 0}^\infty {{{\gamma }^t} v_{i}^{t} } $$
where γ ∈[0, 1) is a so-called discount factorFootnote 4. Observe that the DAP is normalized by the factor (1 − γ). After the normalization, the player's payoffs computed according to the first and to the second criteria can be compared both between them and with the payoffs of the stage-game. Observe that regardless of the criterion, ui(v) ∈ F †, for any instance of v. Notice that if a sequence of payoff profiles a corresponds to an outcome path v, we can interchangeably and with no ambiguity write ui(v) and ui(a) referring to the same quantity.
There are two ways to interpret the discount factor γ. The first interpretation can for convenience be called ‘economic’. The idea behinds it is the following. It has been observed by economists that individuals (or groups of individuals, such as private companies) value their current well-being, or the well-being in the near term, substantially more than in the long-term. Thus, for the economists, the power of the discount factor permits reflecting this phenomenon. Another interpretation, which is mathematically equivalent to the first one, can for convenience be called ‘natural’. According to it, the discount factor γ ∈ [0,1) is viewed as a probability that the repeated game will continue at the next iteration (similarly, (1 − γ) can be viewed as the probability that the repeated game stops after the current iteration). This explanation is more convenient for artificial agents because it is generally questionable whether they have to value the future in a similar way as the humans do. The probability of continuation, in turn, seems to be more ‘natural’ because the machine has always a non-zero probability of fault at any moment of time.
If the economic interpretation of the discount factor is chosen, the discount factor is often called the player's patience. Each player is therefore supposed to have its own value of the discount factor. However, it appears that the main body of the research on the repeated games is done assuming that the players are equally patient (or equally impatient). The results we present in this paper are also based on this assumption. Different approaches can be found in Fudenberg et al. (Reference Fudenberg, Kreps and Maskin1990), Lehrer and Pauzner (Reference Lehrer and Pauzner1999) and Lehrer and Yariv (Reference Lehrer and Yariv1999).
To compare the strategy profiles, similar equations can be used. Let σ be a pure strategy profile. Then the AP for player i of the strategy profile σ is given by
 $${{u}_i}\left( \sigma \right) = {\mathop{{\lim }}\limits_{{T \rightarrow \infty }}} \frac{1}{T}\mathop{\sum}\limits_{t = 0}^T {{{r}_i}\left( {{{a}^t} \left( \sigma \right)} \right)} $$
The corresponding DAP can be defined as
 $${{u}_i}\left( \sigma \right) = \left( {1{\rm{ - }}\gamma } \right)\mathop{\sum}\limits_{t = 0}^\infty {{{\gamma }^t} {{r}_i}\left( {{{a}^t} \left( \sigma \right)} \right)} $$
As usual, when the players’ strategies are mixed, one should take an expectation over the realized outcome paths.
2.3 Nash equilibrium
In order to act effectively in a given environment, an agent needs to have a strategy. When we talk about rational agents, this strategy has to be optimal in the sense that it should maximize the agent's expected payoff with respect to the properties of the environment. In the single agent case, it can often be assumed that the properties of the environment do not change in response to the actions executed by the agent (Sutton & Barto, Reference Sutton and Barto1998). In this case, it is said that the environment is stationary. Obviously, in order to act optimally in a stationary environment, the agent has to solve the following optimization problem:
 $${{\sigma }_i} = {\mathop{{\max }}\limits_{{{{a}_i} \in {{A}_i}}}} \,{{{\rm{E}}}_{{{a}_j} \sim {{{\rm{\alpha }}}_j}}}\left[ {{{r}_i}\left( {{{a}_i},{{a}_j}} \right)} \right]$$
where j denotes the environment as if it was a player always playing a mixed action αj.
When an agent plays a game with the other rational agents, it needs to optimize in the presence of the other optimizing players. This makes the problem non-trivial, since an optimal strategy for one player depends on the strategies chosen by the other players. When the opponents can change their strategies, the player's strategy cannot usually remain constant in order to remain optimal.
We have already seen that one important property for finding a solution in such decision problems is the individual rationality. In other words, given the strategies chosen by the opponent players, the strategy chosen by a rational agent should at least provide a payoff that is not lower than that player's minmax payoff. Recall that the minmax strategy for player i, that is, the strategy guaranteeing player i at least its minmax payoff, is defined as follows:
 $$\openup 4pt{ & \; \; \; \; \; \; \; \; {{{\underline{\sigma } }}_i} = {\mathop{{\arg \max \,}}\limits_{{{{a}_i} \in {{A}_i}}}} {{r}_i}\left( {{{a}_i},{{\alpha }_{\ndash i}}} \right) \cr & {\rm{s}}{\rm{.t}}.\,{{\alpha }_{{\rm{ - }}i}} = {\mathop{{\arg {\rm{min}}}}\limits_{{{{\alpha }_{{\rm{ - }}i}} \in \times {{\,}_{j\, \ne \,i}}{\rm{\rDelta }}( {{{A}_j}} )}}} {\mathop{{\max }}\limits_{{{{a}_i} \in {{A}_i}}}}\, {{r}_i}\left( {{{a}_i},{{\alpha }_{\ndash i}}} \right) \cr}$$
However, the fact that player i plays its minmax strategy does not imply that the other players optimize with respect to player i. The concept of equilibrium describes strategies in which all players’ strategic choices simultaneously optimize with respect to each other.
Definition 4 (Nash equilibrium)A strategy profile σ, such that σ  $$\[--><$>\equiv$$$
(σi, σ −i), is a Nash equilibrium if for all players i ∈ N and strategies,
 $$\[--><$>\sigma{^{\prime}_i} <$><!--$$
,
 $$ {{u}_i}\left( \sigma \right)\geq {{u}_i}\left( {\sigma {^{\prime}_i},{{\sigma }_{{\rm{ - }}i}}} \right) $$
In other words, in the equilibrium no player can unilaterally change its strategy so as to augment its own utility.
One can wonder whether the Nash equilibrium strategy profile is a satisfactory concept with respect to the notion of individual rationality? Recall that any strategy profile is only satisfactory (in the sense of individual rationality) if the payoffs proposed to each agent by that strategy profile are not less than the agent's minmax payoff. The following lemma answers this question positively.
Lemma 1 If σ is a Nash equilibrium, then for all  $$\[--><$>i,\,{{u}_i}\left( \sigma \right)\geq {{\underline{{ {{v}}}} }_i} <$><!--$$
.
Proof. Let σ be a strategy profile having a property of Nash equilibrium. After any history h t, each player can simply play its best response to the action profile  $$\[--><$>a_{{{\rm{ - }}i}}^{t} (\sigma ) <$><!--$$
of the other players. Such a strategy will bring to player i a payoff of at least
 $$\[--><$>{{\underline{v} }_i} <$><!--$$
. But since, in equilibrium, no player can change its strategy so as to get its own utility increased, than i's payoff in the equilibrium is at least
 $$\[--><$>{{\underline{v} }_i} <$><!--$$
. □
In conjunction with the notion of individual rationality, another notion is important when we talk about the strategies in repeated games. This is the notion of sequential rationality or subgame-perfection. First of all, let us formally define it.
Definition 5 (Subgame-perfect equilibrium)A strategy profile σ is a subgame-perfect equilibrium (SPE) in the repeated game if for all histories h t ∈ H, the subgame strategy  $$\[--><$>{{\left. \sigma \right|}_{{{h}^t} }}<$><!--$$
is a Nash equilibrium of the continuation game.
Now let us informally explain why the notion of subgame-perfection is of such high importance in the repeated games. Consider a grim trigger strategy. This strategy is similar to TFT in the sense that two players start by playing C in the first period and continue playing C until the other player deviates. The difference with TFT is how the players act in the case of the opponent's deviation. In grim trigger, if the opponent deviates then starting from the next iteration the player always plays D regardless the subsequent actions of the deviator. Let the game be as shown in Figure 3. Observe that in this game, the only reason why each player continues preferring to play the cooperative action C while the opponent plays C is that the profile of two grim trigger strategies is a Nash equilibrium. For example, let suppose that the players’ payoff criterion in this game is AP 1. Let Player 1 ‘think’ about a possibility of deviation to the action D when Player 2 is supposed to play C. Player 1 knows that according to the strategy profile σ (which is a profile of two grim trigger strategies) starting from the next iteration, Player 2 will play D infinitely often. Thus, according to the AP criterion, after only one iteration at which the profile (D, D) is played following the deviation, Player 1 looses all the additional gain it obtains owing to the deviation.
A game in which a profile of two grim trigger strategies is not a subgame-perfect equilibrium
Now, let suppose that Player 1 still decides to deviate after a certain history h t. It plays D whenever Player 2 plays C and gains the payoff of 3 instead of 2. The repeated game enters into the subgame induced by the history h t + 1 = (h t, (D, C)). Now, according to the strategy profile  $$\[--><$>{{\left. \sigma \right|}_{{{h}^{t\, + \,{\rm{1}}}} }}<$><!--$$
Player 2 is supposed to always play D say, in order to ‘punish’ the deviator, Player 1. However, observe the rewards of Player 2. If it always plays D as prescribed by the Nash equilibrium, it certainly obtains the AP of −2 in the subgame, since the rational opponent will optimize with respect to this strategy. But if it continues playing C, it obtains the average playoff of −1 in the subgame, while its opponent, the deviator, will continue enjoying the payoff of 3 at each subsequent period. As one can see, even if after the equilibrium histories the profile of two grim trigger strategies constitutes a Nash equilibrium, it cannot be a Nash equilibrium in an out-of-equilibrium subgame. Thus, due to this simple example it becomes clear why, in order to implement Nash equilibria in practice, one needs to have recourse to the subgame-perfect equilibria. While one rational player should have no incentive to deviate being informed about the strategy prescribed to the opponents (the property of Nash equilibrium), its rational opponents, in turn, need to have incentives to follow their prescribed strategies after the player's deviation (the property of subgame-perfection).
Lemma 2 A subgame-perfect equilibrium always exists.
Proof. Consider a strategy profile σ that prescribes playing the same Nash equilibrium of the stage-game after any history of the repeated game. According to Nash (Reference Nash1950), in any stage-game there exists such an equilibrium. By the definition of the latter, when player i plays its part of a stage-game Nash equilibrium, it plays its immediate best response to the mixed action of the other players. At the same time, by the definition of σ, the future play is independent of the current actions. Therefore, playing a stage-game Nash equilibrium at every iteration will also be a best response in the repeated game after any history. The latter observation satisfies the property of subgame-perfection. □
The two most important questions about subgame-perfect equilibria are (1) what is the set of subgame-perfect equilibrium payoffs of a repeated game; and (2) what can be the form of a subgame-perfect equilibrium strategy profile. We will tend to answer both questions in the following subsections. But first, we need to introduce a way to represent strategy profiles.
2.4 Strategy profiles as finite automata
By definition, a player's strategy is a mapping from an infinite set of histories into the set of player's actions. In order to construct a strategy for an artificial agent (which is usually bounded in terms of memory and performance), one needs a way to specify strategies by means of finite representations.
Intuitively, one can see that, given a strategy profile σ, two different histories h t and h τ can induce identical continuation strategy profiles, that is, σ|ht = σ|hτ. For example, in the case of TFT strategy, agents will have the same continuation strategy both after the history ((C, C), (C, C)) and after the history ((D, C), (C, D), (C, C)). One can put all such histories into the same equivalence class. If one views these equivalence classes of histories as players’ states, then a strategy profile can be viewed as an automaton.
Let M ≡ (Q, q 0, ƒ, τ) be an automaton implementation of a strategy profile σ. M consists of (i) a set of states Q, with the initial state q 0 ∈ Q; (ii) a profile of decision functions f ≡ ×i ∈N f i, where the decision function of player i, fi : Q  $$\[--><$> \mapsto <$><!--$$
Δ(Ai), associates mixed actions with states, and; (iii) a transition function τ : Q × A
 $$\[--><$> \mapsto <$><!--$$
Q, which identifies the next state of the automaton given the current state and the action profile played in the current state.
Let M be an automaton. In order to demonstrate how M induces a strategy profile, one can first recursively define τ(q, h t), the transition function specifying the next state of the automaton given its initial state q and a history h t that starts in q, as
 $$\openup 3pt\left\{ {\matrix{ {{\rm{\tau (}}q,{{h}^t} {\rm{)}}\, \equiv \,{\rm{\tau }}\left( {{\rm{\tau (}}q,{{h}^{t{\rm{ - }}1}} {\rm{)}},{{a}^{t{\rm{ - }}1}} } \right),\,} \cr {{\rm{\tau (}}q,{{h}^1} {\rm{)}}\, \equiv \,{\rm{\tau }}\left( {q,{{a}^0} } \right)}\hfill \right$$
With the above definition in hand, one can define  $$\[--><$>\sigma _{i}^{M} <$><!--$$
, the strategy of player i induced by the automaton M, as
 $$\openup 3pt \left\{ {\matrix{ {\sigma _{i}^{M} \left( {\varnothing } \right)\, \equiv \,{{f}_i}\left( {{{q}^0} } \right),\,\,\,\,\,\,\,\,\,\,\,\,\,} \hfill\cr {\sigma _{i}^{M} \left( {{{h}^t} } \right)\, \equiv \,{{f}_i}\left( {{\rm{\tau }}\left( {{{q}^{\rm{0}}}, {{h}^t} } \right)} \right)} \right $$
An example of a strategy profile implemented as an automaton is shown in Figure 4. This automaton implements the profile of two grim trigger strategies. The circles are the states of the automaton. The arrows are the transitions between the corresponding states; they are labeled with outcomes. The states are labeled with the action profiles prescribed by the profiles of decision functions.
An example of an automaton implementing a profile of two grim trigger strategies. The circles are the states of the automaton; they are labeled with the action profiles prescribed by the profiles of decision functions. The arrows are the transitions between the corresponding states; they are labeled with outcomes
Since any automaton induces a strategy profile, any two automata can be compared in terms of the utility they bring to the players. Let an automaton M induce a strategy profile σ M. The utility ui (M) of the automaton M for player i is then equal to ui (σ M), where ui (σ M) is given by Equation (3).
Let |M| denote the number of states of automaton M. If |M| is finite, then M is called a finite automaton; otherwise the automaton is called infinite. In MAS, most of the time, we are interested in finite automata, because artificial agents always have a finite memory to stock their strategies and a finite processing power to construct them.
Note that any finite automaton induces a strategy profile, however, not any strategy profile can be represented using finite automata. Kalai and Stanford (Reference Kalai and Stanford1988) demonstrated that any SPE can be approximated with a finite automaton.
Note also that an automaton implementation of a strategy profile can be naturally split into a set of individual player automatons. Each such automaton will share the same set of states and the same transition function, and only decision functions will be individual. Below we will sometimes consider players’ individual automata as well.
Before presenting important theoretical results about repeated games, let us first outline a taxonomy of different settings, in which the model of repeated games can be applied.
3 Taxonomy
To construct a taxonomy of repeated game settings, let us enumerate a number of different assumptions that can affect the decision making in the repeated games. These assumptions are due to various conditions of the real-world environment, which we model as a repeated game. Players’ patience, their payoff criteria, ability to execute mixed strategies, observability of the opponents’ actions, and knowledge of their payoff functions are all examples of different conditions of the real-world environment. To reflect those conditions, there exists a set of formal assumptions that can be integrated into the model of repeated games. Approaches to the analysis of repeated games under different assumptions can also be quite different. The present overview paper covers only a small subset of all possible repeated game settings considered in the literature.
Number of iterations: Repeated games differ by the expected number of game iterations. One can distinguish finitely repeated games and infinitely repeated games. In the finitely repeated games (Benoit & Krishna, Reference Benoit and Krishna1985), the horizon T of the repeated game (i.e. the number of stage-game repetitions) is supposed to be finite, fixed, and known by the players before the repeated game starts. The analysis and the solutions in the finitely repeated games have quite specific properties due to the fact that one can use backward induction to compute game solutions.
Payoff criteria: Infinitely repeated games can be distinguished from the point of view of long-term payoff criteria adopted by the players. In previous section, we have already seen that players can have the AP criterion or the DAP criterion. In addition to the above two widely used criteria, Rubinstein (Reference Rubinstein1979) studies equilibrium properties in repeated games with another payoff criterion, called an overtaking criterion.
Player patience: In infinitely repeated games with the DAP criterion, players are considered patient if their discount factor is close to 1. On the other hand, players are said to be impatient if 0 < γ  $$\[--><$>\ll$$$
1. Fudenberg et al. (Reference Fudenberg, Kreps and Maskin1990) study a case where patient and impatient players are playing together.
Game information: Players can have different knowledge of the game. For instance, if all players know their own payoff functions and those of the other players, such game is said to be of complete information (Sorin, Reference Sorin1986). On the other hand, if all players are uncertain about either of game properties, such game is said to be of incomplete information (Rasmusen, Reference Rasmusen1994; Aumann et al., Reference Aumann, Maschler and Stearns1995). One can also distinguish an intermediate situation, in which players having a complete information about the game they play are playing together with players having only a partial information about certain game properties (Lehrer & Yariv, Reference Lehrer and Yariv1999; Laraki, Reference Laraki2002).
Game monitoring: Players can be supposed to either perfectly observe the actions executed by the other players, observe them with an uncertainty, or not to observe them at all. When the actions of the other players are observable, a repeated game is said to be of perfect monitoring. A special case of perfect monitoring is the observability of the opponent players’ mixed actions.
When the players receive only a stochastic signal giving only an imprecise idea of the actions taken by the opponents, a repeated game is said to be of imperfect monitoring. One can also distinguish between the games of imperfect public monitoring, where all players receive the same signal characterizing the executed action profile (Abreu et al., Reference Abreu, Pearce and Stacchetti1990; Fudenberg et al., Reference Fudenberg, Levine and Maskin1994); and the games of imperfect private monitoring, where the signals received by the different players are different but correlated (Piccione, Reference Piccione2002; Matsushima, Reference Matsushima2004).
Strategic complexity: One can distinguish between the basic properties of the strategies that can be implemented by players. We have already seen that strategies can be defined using either finite or infinite representations. An example of a finite strategy representation is a finite automaton (Neyman, Reference Neyman1985; Abreu & Rubinstein, Reference Abreu and Rubinstein1988; Kalai & Stanford, Reference Kalai and Stanford1988). An example of a non-finite representation of a strategy profile can be found in Judd et al. (Reference Judd, Yeltekin and Conklin2003), where, in order to choose an action at a given iteration, each player has to solve a linear program corresponding to a certain payoff profile.
Players’ strategies also generally have a less complex structure if the players are only allowed to adopt pure strategies (Abreu, Reference Abreu1988); on the other hand, strategy profiles usually have a more complex structure if mixed actions are allowed (Burkov & Chaib-draa, Reference Burkov and Chaib-draa2010).
Public correlation: An important special case includes repeated games with public correlation. In this case, an independent correlating device is available and it is capable of transmitting a random signal to the players at the beginning of each game period. It permits convexifying the set of payoff profiles without having recourse to complex sequence of outcomes (Mailath & Samuelson, Reference Mailath and Samuelson2006, p. 17). Possibility to convexify the set of payoff profiles is an important property permitting to considerably simplify both the study of subgame-perfect equilibrium payoffs of repeated game and the construction of the corresponding strategy profiles (Judd et al., Reference Judd, Yeltekin and Conklin2003). A correlating device can be viewed as a special player whose rewards are independent of the actions of the other players. Alternatively in two-player games, a special communication protocol can simulate a correlating device (Aumann et al., Reference Aumann, Maschler and Stearns1995).
In this overview, we are primarily focused at the setting characterized by the infinitely repeated games with complete information and perfect monitoring. The players are supposed to be sufficiently patient (γ is close enough to 1), capable of using only finite representations for their strategies and having either the average or the discounted average long-term payoff criterion. Our results presented in Section 4 are all based on these assumptions. In Section 5, we give a brief overview of important results for a number of other repeated game settings. For instance, we consider a setting described by the imperfect monitoring. Contrary to repeated games of perfect monitoring, which are relatively well studied, there exist considerably less results about games of imperfect monitoring, especially for the most complicated, private monitoring case. In particular, we do not know about any result concerning a finite strategic complexity in repeated games of imperfect monitoring.
Now let us first present a number of important results characterizing the repeated games of perfect monitoring.
4 Perfect monitoring
4.1 The folk theorems
There is a cluster of results, under the common name of folk theorems (FT), characterizing the set of payoffs of Nash and subgame-perfect equilibria in a repeated game. In this section, we will present only a few of these results. The reason is that the proofs of all folk theorems are conceptually similar, while certain are too space consuming for an overview paper.
As we have mentioned in the beginning of this paper, in order to use a strategy profile in practice, two notions are important: individual rationality and subgame-perfection. As we have seen, any Nash equilibrium is individually rational but not necessarily subgame-perfect. Recall that the property of subgame-perfection guarantees that when any player does actually deviate from the long-term equilibrium strategy in favor of a short-term gain, the other players will indeed prefer to continue following their prescribed strategies. The two following perfect folk theorems (PFT) characterize the set of payoff profiles of subgame-perfect equilibria.
Theorem 1 (PFT with the AP criterion)Every payoff profile v ∈ F †+is a payoff profile of a certain subgame-perfect equilibrium in the repeated game.
Proof. See Osborne and Rubinstein (Reference Osborne and Rubinstein1994, p. 147) for a proof for the case of pure strategies, that is, v ∈ F †+p That proof can easily be extended to mixed strategies. Here, let us briefly outline the intuition behind the proof. The proof is by construction. We first construct an automaton in which there are basically two types of states: cooperative states and punishment states. The cooperative states form a cycle. When all players follow this cycle, they obtain the AP v. If one player deviates, the other players punish the deviator by passing through a finite sequence of punishment states in which the minmax action profile for deviator is played. It is remaining to compute the length of the sequence of punishment states so that the maximal gain the deviator can obtain by deviating from the cooperative cycle is vanished by the punishment. As soon as the final punishment state is reached and the corresponding minmax profile is played, the automaton transits to the beginning of the cooperative cycle. Since the punishment sequence is finite, any loss one player endures when it punishes the other player becomes infinitesimal as the number of repeated game periods tends to infinity. This justifies that the deviator will indeed be punished by the remaining players, which is, in turn, a property of subgame-perfection. □
For repeated games with the DAP criterion, there is no corresponding exact folk theorem with the players’ strategies being represented with finite automata. In other words, there does not exist a theorem specifying the equilibrium payoffs laying in F †+. However, there are three mutually complementary results that can be satisfactory in many situations.
The first such result (Theorem 2) establishes an exact folk theorem for the case of feasible and pure strictly individually rational payoffs (i.e. v ∈ F †+p). This result is suitable for the case when the players are limited to use pure strategies. The two remaining results (Theorems 4 and 5) state that (i) any feasible and strictly individually rational payoff profile in repeated games with the DAP criterion is a payoff profile of a certain subgame-perfect equilibrium whenever the strategies are representable by infinite automata; and (ii) any subgame-perfect equilibrium strategy profile can be approximated to an arbitrary precision using finite automata.
A payoff profile v is said to be an interior feasible payoff profile if v is an interior point of F †, that is, v ∈ int F †.
Theorem 2 (PFT with the DAP criterion)Let v be an interior feasible and strictly pure individually rational payoff profile in a repeated game with the DAP criterion. For all ε > 0 there exist a discount factor  $$\[--><$>\underline{\gamma } \in ({\rm{0,}}\,{\rm{1}})<$><!--$$
and a payoff profile v′ for which
 $$\[--><$>\forall i\left| {v{^{\prime}_i}{\rm{ - }}{{v}_i}} \right| \lt {\epsilon} <$><!--$$
, such that for any
 $$\[--><$>\gamma \in (\underline{\gamma } {\rm{,}}\,{\rm{1}}) <$><!--$$
, v′ is a payoff profile of a certain subgame-perfect equilibrium.
Proof. For the proof of this theorem formulated in a slightly different form, see Ben-Porath and Peleg (Reference Ben-Porath and Peleg1987). In this paper, we only present the proof of Theorem 3, a simplified and restricted version of Theorem 2. Theorem 3 focuses on the payoff profiles from the set F +p, that is, all strictly pure individually rational payoff profiles that can be generated by pure action profiles. □
Before introducing perfect folk theorems for DAP criterion, let us first introduce the one-shot deviation principle (Fudenberg & Tirole, Reference Fudenberg and Tirole1991).
Definition 6 Given a strategy profile σ = (σi, σ−i), a one-shot deviation strategy for player i from strategy σi is a strategy  $$\[--><$>{{\hat{\sigma }}_i} <$><!--$$
with the property that there exists a unique history
 $$\[--><$>{{\hat{h}}{^t}} <$><!--$$
such that
 $$ \left\{ {\matrix{ {{{{\hat{\sigma }}}_i}\left( {{{h}^{\rm{\tau }}} } \right)\, \ne \,{{\sigma }_i}\left( {{{h}^{\rm{\tau }}} } \right),\,} \quad {if\,{{h}^{\rm{\tau }}} = {{{\hat{h}}}{^t}}, }\cr {{{{\hat{\sigma }}}_i}\left( {{{h}^{\rm{\tau }}} } \right)\,{\rm{ = }}\,{{\sigma }_i}\left( {{{h}^{\rm{\tau }}} } \right),\,} \quad \ \,{otherwise}\hfill \right $$
A one-shot deviation for player i is called profitable if  $$\[--><$>{{u}_i}({{\hat{\sigma }}_i}{{|}_{{{{\hat{h}}}{^t}} }},{{\sigma }_{{\rm{ - }}i}}{{|}_{{{{\hat{h}}}{^t}} }}) \gt {{u}_i}(\sigma {{|}_{{{{\hat{h}}}{^t}} }}) <$><!--$$
Recall that  $$\[--><$>{{\sigma }_i}({{h}^t} ) <$><!--$$
denotes the (possibly mixed) action player i should do according to the strategy σ after the history h t, while
 $$\[--><$>{{\sigma }_i}|_{{h}^t} <$><!--$$
is the complete description of strategy σi in the subgame induced by the history h t.
At first glance, it may appear that in order to verify whether a given strategy profile σ is a subgame-perfect equilibrium, one has to check, for every subgame induced by each possible history h t, whether  $$\[--><$>{{\sigma }}|_{{h}^t} <$><!--$$
remains Nash equilibrium in this subgame. To do this, one would have to check all possible deviations (typically, an infinity of them) of each player and after each history. However, in many situations the task can be drastically simplified. For instance, for repeated games with the DAP criterion it can be demonstrated that it is sufficient to check only the one-shot deviation.
Proposition 1 (The one-shot deviation principle)In any repeated game with the DAP criterion, a strategy profile is a subgame-perfect equilibrium if and only if for all players and after all histories there is no profitable one-shot deviation.
Proof. For the proof, see Mailath and Samuelson (Reference Mailath and Samuelson2006). The principal idea behind the proof is that since the payoffs are discounted, any strategy that offers a higher payoff than an equilibrium strategy, must do so in a finite number of iterations. Then, by using dynamic programming, one can show that when there is a profitable deviation, there should be a profitable one-shot deviation. □
Theorem 3 (PFT with DAP and pure action payoff profiles)If, in a repeated game with the DAP criterion, there is a payoff profile v ∈ F + pfor which there exists a collection {v j}j ∈N of payoff profiles such that (i)  $$\[--><$>\forall j \in N,\,{{v}^j} \in {{F}^{ + \,p}} <$><!--$$
and
 $$\[--><$>v_{j}^{j} \lt {{v}_j}<$><!--$$
, and (ii)
 $$\[--><$>\forall i\, \ne \,j,v_{j}^{j} \lt v_{j}^{j} <$><!--$$
, then there exists a discount factor
 $$\[--><$>\underline{\gamma } \in ({\rm{0,}}\,{\rm{1}})<$><!--$$
such that for every
 $$\[--><$>\gamma \in (\underline{\gamma } {\rm{,}}\,{\rm{1}})<$><!--$$
, there exists a subgame-perfect equilibrium yielding the payoff profile v.
Proof. The complete proof of this theorem can be found in Osborne & Rubinstein (Reference Osborne and Rubinstein1994, p. 151). As previously, here we will only outline the intuition behind the proof. Let us first explain why the existence of the collection  $$\[--><$>{{\left\{ {{{v}^i} } \right\}}_{i \in N}} <$><!--$$
with the aforementioned properties is necessary. This collection represents the so-called player-specific punishments (Mailath & Samuelson, Reference Mailath and Samuelson2006, p. 82). The basic idea behind the proof of any perfect folk theorem is that one needs to construct a profile of strategies with the property that when any player i deviates from the prescribed ‘cooperative’ behavior (yielding the payoff vi to player i) then two conditions are satisfied: (i) player i can be successfully punished by the other players (by vanishing its deviation gain) and (ii) any player j ≠ i has to prefer to punish i on penalty of being punished itself by the other players (including player i, which, thanks to the one-shot deviation principle, can be assumed to return to the equilibrium strategy right after its own deviation). Consequently, in the case of the DAP criterion one not only needs to find the length of the sequence of punishment states for each player, but also the condition under which any deviation from this punishment sequence by any punisher can be successfully punished by the remaining players. □
Now let us for a while consider strategies implementable with infinite automata. In this case, for repeated games with the DAP criterion there exists an exact folk theorem (Theorem 4) having the desired properties. That is, Theorem 4 considers all payoff profiles in the set F †+ and not only those that belong to F †+p. We will then show how this result can be approximated by reducing the space of player strategies to those implementable by finite automata.
Theorem 4 (PFT with DAP and infinite automata)For any payoff profile  $$\[--><$>v \in \{ \tilde{v} \in {{F}^{&#x2020; {\rm{ + }}}} :\exists v^{\prime} \in {{F}^{&#x2020; {\rm{ + }}}}, v{^{\prime}_i} \lt {{\tilde{v}}_i} \ {{\forall }_i}\} <$><!--$$
in a repeated game with the DAP criterion, there exists a discount factor
 $$\[--><$>\underline{\gamma } \in (0,\,1) <$><!--$$
such that for every
 $$\[--><$>\gamma \in (\underline{\gamma }, \,1) <$><!--$$
, there exists a subgame-perfect equilibrium yielding the payoff profile v.
Proof. For the complete proof, see Mailath and Samuelson (Reference Mailath and Samuelson2006, p. 101). Here, we will only draw the reader's attention to the fact that the formulation of this theorem is similar to that of Theorem 3. The ideas behind the proof are also similar. To prove this theorem, one needs to recall that any v∈F † can be obtained as a payoff of a (possibly infinite) sequence of pure action profiles (see Mailath & Samuelson, Reference Mailath and Samuelson2006, pp. 97–99). Fix  $$\[--><$>v \in \{ \tilde{v} \in {{F}^{&#x2020; + }} :\exists v^\prime \in {{F}^{&#x2020; + }}, {{v^{\prime}_i}} \lt {{\tilde{v}}_i} \ \forall i\} <$><!--$$
. Because F †+ is convex, one can always find a vector v′ of payoff profiles with the property that for all players i,
 $$\[--><$>{{v^{\prime}_i}} \lt {{v}_i} <$><!--$$
. Furthermore, one can find an ε > 0 such that for each player i there exists a payoff profile
 $$ {{v^{\prime}}^i} = ({{v^{\prime}_1}}\, + \,{\epsilon},{{v^{\prime}_2}}\, + \,{\epsilon}, \ldots, {{v^{\prime}}_{i{\rm{ - }1}}}\, + \,{\epsilon},{{v^{\prime}}_i},{{v^{\prime}_{i\, + \,1}}}\, + \,{\epsilon}, \ldots, {{v^{\prime}_n}}\, + \,{\epsilon}) $$
Observe that the collection {v′i}i ∈N of such payoff profiles specifies player-specific punishments analogous to those required for Theorem 3 with the difference that in the latter theorem, the punishment actions are pure and, therefore, any deviation is detectable. When the punishment actions are allowed to be mixed, deviations are only detectable when they are outside the support of the mixed action minmaxFootnote 5. Otherwise, short-term deviations of one player cannot be instantly detected by the other players. To tackle this problem, it is required that each player i were indifferent (in terms of expected payoff) between all its pure actions in the support of its mixed action  $$\[--><$>\underline{\alpha } _{i}^{j} <$><!--$$
in the mixed minmax profile
 $$\[--><$>{{\underline{\alpha } }^j} =(\underline{\alpha } _{i}^{j}, \underline{\alpha } _{{{\rm{ - }}i}}^{j} ) <$><!--$$
for any player j ≠ i. The technique is to specify the continuation play (after punishment is over) so as to obtain the required indifference during punishment. See Mailath and Samuelson (Reference Mailath and Samuelson2006, p. 102) for more details. □
Before presenting the approximation result, let us first define the notion of an approximately subgame-perfect equilibrium. A strategy profile  $$\[--><$>\sigma = ({{\sigma }_i},{{\sigma }_{{\rm{ - }}i}}) <$><!--$$
is a Nash ε-equilibrium of a repeated game if
 $$\[--><$>{{u}_i}(\sigma )\geq {{u}_i}({{\sigma ^{\prime}_i}},{{\sigma }_{{\rm{ - }}i}}){\rm{ - }}{\epsilon} <$><!--$$
for each player i ∈ N and every strategy
 $$\[--><$>{{\sigma ^{\prime}_i}}<$><!--$$
. Similarly, a strategy profile
 $$\[--><$>\sigma = ({{\sigma }_i},{{\sigma }_{{\rm{ - }}i}}) <$><!--$$
is a subgame-perfect ε-equilibrium of a repeated game, if for any h t ∈ H,
 $$\[--><$>{{\sigma }}|_{{h}^t} <$><!--$$
is a Nash ε-equilibrium of the subgame induced by h t.
Theorem 5 Consider a repeated game with the DAP criterion, and let ε > 0. Then for any subgame-perfect equilibrium σ, there exists a finite automaton M ≡ (Mi)i ∈N with the property that |ui(σ)−ui(M)| < ε for all i ∈ N, and such that M induces a subgame-perfect ε-equilibrium.
Proof. For the detailed proof, see Kalai and Stanford (Reference Kalai and Stanford1988). The key to the proof is the observation that one can partition the convex and, therefore, bounded set of feasible and individually rational payoff profiles (in  $$\[--><$>{{{\Bbb R}}^n} <$><!--$$
) into disjoint adjacent n-cubes. There will necessarily be a finite set C of such n-cubes. Let σ be a subgame-equilibrium strategy, which we want to approximate with precision ε. In each n-cube c ∈ C, choose a payoff profile, and find the corresponding subgame-perfect equilibrium strategy profile σ c. Recall that by definition, for each history h t,
 $$\[--><$>{{\sigma }}|_{{h}^t} <$><!--$$
is a subgame-perfect equilibrium. The approximate joint strategy g is implemented by the automaton M ≡ (C, c 0, ƒ, τ), where the set C of n-cubes plays the role of the automaton states; c 0 is the n-cube, which the payoff profile u(σ) belongs to;
 $$\[--><$>f(\overline{\sigma }, a)<$><!--$$
is the transition function that takes a subgame-perfect equilibrium strategy profile
 $$\[--><$>\bar{\sigma }<$><!--$$
and an action profile a, finds
 $$\[--><$>v\, \equiv \,u(\bar{\sigma }\left| {_{a} } \right.)<$><!--$$
and then returns the n-cube
 $$\[--><$>\bar{c}<$><!--$$
, which v belongs to;
 $$\[--><$>\tau (\bar{\sigma })\, \equiv \,\bar{\sigma }(\varnothing )<$><!--$$
. Kalai and Stanford (Reference Kalai and Stanford1988) show that when the side of each n-cube is of length (1−γ)2ε/2, the automaton M implements a subgame-perfect ε-equilibrium. □
4.2 Constructing an equilibrium strategy
Roughly speaking, the folk theorems tell us that in repeated games ‘everything is possible’ if the players are sufficiently patient. For instance, to any feasible and individually rational payoff profile there corresponds a strategy profile which every player will want to follow given that the other players do the same. However, the subject matter of the research in MAS has its inherent practical questions that are not directly addressed by the folk theorems. Here are two examples of such questions. The first question is: does a given collection of players’ strategies induce an equilibrium strategy profile? The second question is: how to construct a strategy of player i, such that the collection of all players’ strategies induces an equilibrium strategy profile? In this subsection, we explore several approaches to answering these two questions.
The case of AP is trivial: the players are supposed to be extremely patient (i.e. γ = 1). For example, a way to construct the player i's automaton yielding any payoff profile in F †+ is described in the proof of Theorem 1. Using the same principle, Littman and Stone (Reference Littman and Stone2005) describe an efficient algorithm for constructing equilibrium strategy profiles in any two-player repeated game. The opposite case is also trivial: when all players are extremely impatient (i.e. γ = 0), the set of subgame-perfect equilibrium strategies in the repeated game coincides with the set of stage-game equilibria (recall the proof of Lemma 2). In MAS, most of the time one deals with an intermediate case: the players are neither extremely patient, nor extremely impatient, that is, their discount factor is an interior point of the set (0, 1). The reader interested in a situation where patient players play a repeated game with a set of extremely impatient players is referred to Fudenberg et al. (Reference Fudenberg, Kreps and Maskin1990).
4.2.1 Nash reversion
As we already mentioned above, any strategy profile prescribing playing a stage-game Nash equilibrium at every iteration of repeated game is a subgame-perfect equilibrium. Such SPE are trivial and can be constructed for any game regardless of the discount factor.
The simplest non-trivial subgame-perfect equilibria can be constructed based on a similar principle, called Nash reversion (Friedman, Reference Friedman1971). We have already seen an example of Nash reversion when we considered the grim trigger strategy in Section 2. As in grim trigger, any Nash reversion-based strategy profile σ prescribes to start by playing a certain ‘cooperative’ sequence of action profiles. If either player deviates from the prescribed sequence, all players revert to permanently playing a certain stage-game Nash equilibrium. Therefore, stage-game Nash equilibrium is viewed as a punishment that supports the payoff profile corresponding to the cooperative sequence. Because such punishment is itself a subgame-perfect equilibrium, one can state that σ is a subgame-perfect equilibrium whenever no one-shot deviation from the cooperative sequence is profitable (due to the threat of the continuation strategy that prescribes to permanently play a stage-game Nash equilibrium).
Let us develop this argument more formally. As previously, let us limit ourselves to pure strategies. Given a strategy profile σ, one can rewrite Equation (3) as follows:
 $${ {{u}_i}(\sigma ) & \, \equiv \,(1{\rm{ - }}\gamma )\mathop{\sum}\limits_{t = 0}^\infty {{{\gamma }^t} {{r}_i}({{a}^t} (\sigma ))} \cr & = \,(1{\rm{ - }}\gamma ){{r}_i}({{a}^0} (\sigma ))\, + \,\gamma \left[ {\mathop{\sum}\limits_{t = 1}^\infty {{{\gamma }^{t{\rm{ - }}1}} {{r}_i}({{a}^t} (\sigma ))} } \right] \cr & = \,(1{\rm{ - }}\gamma ){{r}_i}({{a}^0} (\sigma ))\, + \,\gamma {{u}_i}(\sigma \left| _{{{a}^0} (\sigma )} \right.) \cr}$$
Let  $$\[--><$>{{v}_i}({{a}_i},\sigma \left| {_{{{{h}^t} }} } \right.) <$><!--$$
denote player i's long-term payoff for playing action ai after history h t given the strategy profile σ. Let
 $$\[--><$>\bar{a } \equiv ({{\bar{a}}_i},{{\bar{a }}_{{\rm{ - }}i}}) <$><!--$$
be the action profile prescribed by strategy σ after the history h t, that is,
 $$\[--><$>\bar{a }\, \equiv \,\sigma ({{h}^t} )\, \equiv \,\sigma \left| {_{{{{h}^t} }} (\varnothing )} \right. <$><!--$$
. For all
 $$\[--><$>{{a}_i} \in {{A}_i} <$><!--$$
one can write:
 $${{v}_i}({{a}_{i}},\,\sigma {{|}_{{{h}^t} }}) = (1{\rm{ - }}\gamma ){{r}_i}({{a}_i},{{\bar{a}}_{{\rm{ - }}i}})\, + \,\gamma {{u}_i}(\sigma {{|}_{{{h}^{t\, + \,1}} }})$$
where  $$\[--><$>{{h}^{t + 1}} = {{h}^t} \cdot a <$><!--$$
is obtained as a concatenation of the history h t and the action profile
 $$\[--><$>a \equiv ({{a}_{i,}}{{\bar{a}}_{{\rm{ - }}i}}) <$><!--$$
and
 $$\[--><$>{{u}_i}(\sigma {{|}_{{{h}^{t + 1}} }}) <$><!--$$
represents the so-called continuation promise of the strategy σ after the history h t·a.
Definition 7 (Continuation promise)The continuation promise of the strategy profile σ to player i,  $$\[--><$>{{u}_i}(\sigma {{|}_{{{h}^{t\, + \,1}} }})<$><!--$$
, is the utility of the strategy profile σ to player i if the history at the next period is h t + 1. The continuation promise for period t + 1 is computed at period t.
At each iteration of the repeated game, player i has a choice between different actions ai, each proposing to that player a particular long-term payoff vi. Consequently, each iteration of the repeated game can be represented as a certain normal form game whose payoffs equal to the stage-game payoffs augmented by the corresponding continuation promises. Let us call such game an augmented game.
Let the stage-game of a repeated game be as shown in Figure 5.
A generic stage-game
Given a strategy profile σ and a history h t, the augmented game corresponding to this stage-game is shown in Figure 6.
An augmented game for the generic stage-game from Figure 5
We can now reformulate the definition of subgame-perfect equilibrium by saying that a strategy profile σ is a subgame-perfect equilibrium if and only if it induces a stage-game Nash equilibrium in augmented games after any history.
Definition 8 A Nash reversion-based strategy profile is such that the players execute a certain infinite sequence of action profiles unless one agent deviates. Following the deviation, a certain stage-game Nash equilibrium is played at every subsequent period.
Grim trigger is an example of a Nash reversion strategy. Consider the repeated Prisoner's Dilemma from Figure 1. Let the strategy profile σ be a profile of two grim trigger strategies. We have already seen an automaton representation of a profile of two grim trigger strategies in Figure 4.
Consider a history h t in which all players played C at each iteration. Now, each player has to take a decision whether to play C, as prescribed by the strategy, or to play D instead. In particular, we have:  $$\[--><$>u(\sigma {{|}_{{{h}^t} }}_ {\cdot (C,\,C)}) = (2,2) <$><!--$$
. Because, in the case of deviation, the unique stage-game Nash equilibrium (C, C), whose payoff profile is (0, 0), should be played, we have
 $$\[--><$>u(\sigma {{|}_{{{h}^t} \cdot (D,C)}})\, = <$><!--$$
 $$\[--><$>\,u(\sigma {{|}_{{{h}^t} \cdot (C,D)}}) = u(\sigma {{|}_{{{h}^t} \cdot (D,D)}}) = (0,\,0) <$><!--$$
. The augmented game corresponding to this situation is shown in Figure 7.
An augmented game for Prisoner's Dilemma from Figure 1
When γ ≥ 1/3, both (C, C) and (D, D) are stage-game Nash equilibria in this augmented game. Observe that the payoff profile corresponding to the outcome (D, D) is inefficient.
Now, consider a history h τ in which either of two players has deviated. For this case, grim trigger prescribes permanently playing the action D regardless of the action played by the other player. The augmented game corresponding to this situation is shown in Figure 8. For any value of γ ∈ [0,1), the only stage-game Nash equilibrium in this augmented game is (D,D). Putting the above two results together, the profile of two grim trigger strategies is a subgame-perfect equilibrium in the repeated Prisoner's Dilemma if and only if γ ≥ 1/3.
An augmented game for Prisoner's Dilemma from Figure 1
In Prisoner's Dilemma, it is sufficient to study Nash reversion-based strategies, such as grim trigger. This is due to the fact that in this game the only stage-game equilibrium payoff profile coincides with the minmax profile for both players. Therefore, the strategy profile that prescribes playing (D,D) after any history is the most severe subgame-perfect equilibrium punishment available in this game. In other words, any playoff profile that can be supported by any subgame-perfect equilibrium continuation promise can be supported by Nash reversion. However, not all games have such a property. In many games, Nash reversion is not the most severe subgame-perfect equilibrium punishment, and the set of Nash reversion-based equilibria is either empty or excludes some equilibrium payoff profiles.
Another way to construct subgame-perfect equilibrium strategy profiles, appropriate in certain cases, is based on the notion of simple strategies. We now consider such strategies.
4.2.2 Simple strategies and penal codes
For the illustrative purposes, in this subsection we continue restricting ourselves to the case of two players.
If we do not apply restrictions on the size of player's automaton and only suppose that it is finite, the number of different pairs of automata capable of inducing an equilibrium strategy profile grows combinatorially with the number of automaton states. For example, we already mentioned above that any convex combination of payoffs can be attained using an infinite sequence of pure outcomes. Given a payoff profile v ∈ F †, such sequence need not be unique. This results in an overwhelming number of only cooperative states that can make part of player i's automaton. The same is true for punishment states as well.
Thereby, we need to narrow the choice of automata. This can be done in different ways. For example: (1) by applying restrictions on the set of players’ payoffs in equilibrium, (2) by focusing on a particular structure of players’ strategies, or (3) by restricting the size of players’ automata. A natural environment where one can restrict one's attention to pure action payoff profiles, without missing interesting opportunities, is an environment that can be modeled as a symmetric game (Cheng et al., Reference Cheng, Reeves, Vorobeychik and Wellman2004). To illustrate the construction of equilibrium in such setting, we follow an example taken from Abreu (Reference Abreu1988). Consider the Duopoly game in Figure 9. The payoff profile v = (10, 10) corresponding to the pure action profile (L, L) is clearly the only Pareto efficient payoff profile in this game, yielding the equal (symmetric) per player payoffs. Let suppose that we want to construct an automaton profile inducing a subgame-perfect equilibrium strategy profile with payoff profile v. One of possibilities is to have recourse to penal codes (Abreu, Reference Abreu1988). We begin with the concept of a simple strategy profile:
Payoff matrix of both players in the Duopoly
Definition 9 Given a collection of (n + 1) outcome paths Footnote 6 $$\[--><$>({\bf {{a}}}{\rm{(0),}} \, {\bf {{a}}}{\rm{(1)}}), \ldots, {\bf {{a}}}{\rm{(}}n{\rm{))}}<$><!--$$
the associated simple strategy profile
 $$\[--><$>\sigma ({\bf {{a}}}{\rm{(0),}}\,{\bf {{a}}}{\rm{(1),}} \ldots {\rm{,}}{\bf {{a}}}{\rm{(}}n{\rm{)}})<$><!--$$
is given by the following automaton for each player i:
• Set of states:
 $$\[--><$>{{Q}_i} = \{ q(j,t):j \in \{ 0\} \, \cup \,N,t = 0,1, \ldots \} . <$><!--$$
• Initial state:
$$\[--><$>{{q}^0} = q(0,\,0) <$><!--$$
.• Output function:
$$\[--><$>f(q(j,\,t)) = {{a}^t} (j) <$><!--$$
, and• Transition function: for an outcome a∈A.


 $$\openup 4pt \tau (q(j,\,t),a) = \left\{ {\matrix{ {q(i,\,0),} \quad\qquad{{if\,{{a}_i} \ne \,a_{i}^{t} (j) \wedge {{a}_{{\rm{ - }}i}} = a_{{{\rm{ - }}i}}^{t} (j),}}\cr {q(j,\,t\, + \,1),} \quad {otherwise}.\hfill\right$$
Therefore, a simple strategy profile consists of a cooperative outcome path a(0) and punishment outcome paths a(i) for each player i. A collection {a(i)}i ∈N is called a penal code and embodies player-specific punishments in the sense of Theorem 3. Using a one-shot deviation principle, one can show that a simple strategy profile σ(a(0), a(1), …, a(n)) induces a subgame-perfect equilibrium if and only if for any t (Mailath & Samuelson, Reference Mailath and Samuelson2006, p. 52):
 $$u_{i}^{t} ({\bf {{a}}}{\rm{(}}j{\rm{))}}\geq {\mathop{{{\rm{max}}}}\limits_{{{{a}_i} \in {{A}_i}}}} (1{\rm{ - }}\gamma ){{r}_i}({{a}_i},\,a_{{{\rm{ - }}i}}^{t} (j))\, + \,\gamma u_{i}^{0} ({\bf {{a}}}(i))$$
for all i ∈ N, and j ∈ {0} ∪ N, and t = 0, 1,…, where
 $$ u_{i}^{t} ({\bf {{a}}})\, \equiv \,(1{\rm{ - }}\gamma )\mathop{\sum}\limits_{\tau \,{\rm{ = }}\,t}^\infty {{{\gamma }^{\tau {\rm{ - }}t}} {{r}_i}({{a}^\tau } )} $$
In this context, Abreu (Reference Abreu1988, Proposition 5) shows that any feasible and pure individually rational subgame-perfect equilibrium payoff profile is supported by a certain simple strategy profile.
Therefore, there exists an optimal penal code {a(i)}i ∈N, such that there exists a collection of strategy profiles {σ(i)}i ∈ N in which each σ(i) ≡ σ(a(i), a(1), …, a(n)) is a subgame-perfect equilibrium. In other words, an optimal penal code is a collection of outcome paths, embodying player-specific punishments, with the property that the punishment outcome path a(i) for player i is supported (in the sense of subgame-perfection) by the threat of restarting a(i) from the beginning.
While, by focusing on simple strategy profiles, we have already considerably narrowed down the choice of strategies, there still remains an infinity of outcome paths that could induce a subgame-perfect equilibrium in simple strategies. Besides, verifying the conditions of Equation (5) for any arbitrary structure of the simple strategy profile and for any t can be extremely difficult. For our example of Duopoly games and with our preference for symmetric payoffs, we can narrow the choice further, by restricting our attention to a particularly simple structure of penal codes, called carrot-and-stick.
Carrot-and-stick (Abreu, Reference Abreu1988) is a punishment defined for each player i by two outcomes,  $$\[--><$>\bar{a}(i)<$><!--$$
and
 $$\[--><$>\tilde{a}(i)<$><!--$$
. The punishment outcome path for player i, a(i), looks as follows:
 $$ {\bf {{a}}}{\rm{(}}i{\rm{) = (}}\tilde{a}(i),\bar{a}(i),\bar{a}(i), \ldots {\rm{)}} $$
where the outcomes  $$\[--><$>\tilde{a}(i) <$><!--$$
and
 $$\[--><$>\bar{a}(i) <$><!--$$
play, respectively, the roles of stick and carrot. Abreu (Reference Abreu1986) has shown that in repeated Oligopoly games (that include our Duopoly example as a special case), the use of penal codes having a structure of carrot-and-stick, is sufficient to support any symmetric subgame-perfect equilibrium payoff. In other words, in such cases carrot-and-stick-based penal codes are optimal. In our example from Figure 9, let γ = 4/7. Choose stick and carrot for Player 1 to be, respectively,
 $$\[--><$>\tilde{a}(1) = (M,H)<$><!--$$
and
 $$\[--><$>\bar{a}(1) = (L,M)<$><!--$$
. It is easy to see that two outcome paths
 $$\openup 4pt \matrix{ {\bf {{a}}}(1) = ((M,\,H),(L,\,M),(L,\,M), \ldots ) \cr {\bf {{a}}}(2) = ((H,\,M),(M,\,L),(M,\,L), \ldots ) $$
define an optimal penal code. For instance, let a(1) be in force. Both Player 1 and Player 2 will follow this outcome path because:
1. By following strategy σ(1) ≡ σ(a(1), a(1), a(2)), Player 1 obtains its pure minmax payoff
$$\[--><$>\underline{v } _{1}^{p} = 0 <$><!--$$
, because −4(1 − γ) + 3γ = 0. Therefore, this payoff is individually rational. Make sure that the payoff of Player 2 exceeds its minmax payoff.2. Player 1 cannot ‘mitigate’ the punishment by deviating to playing L instead of M at the very beginning of a(1). This is because by deviating from it still obtains the same long-term payoff: 0(1 – γ) + 0γ = 0. Moreover, it cannot deviate afterwards, because playing M instead of L, whenever Player 2 plays M, yields the payoff of 7(1 − γ) + 0γ = 3, which equals the payoff of playing the prescribed action L: 3(1 − γ) + 3γ = 3.
3. Player 2 will play H whenever Player 1 is supposed to play M, that is, at the very beginning of a(1). This is because if Player 2 does not do so and deviates to playing M, it obtains the long-term payoff of 7(1 − γ) + 0γ = 3 due to the subsequent punishmentFootnote 7 on the part of Player 1 (i.e. a(2) is played instead of a(1)). On the other hand, if Player 2 follows a(1), it obtains 5(1 − γ) + 15γ = 75/7>3.

The corresponding subgame-perfect equilibrium strategy for Player 1 in the form of a finite automaton is shown in Figure 10.
A finite automaton representing a carrot-and-stick based subgame-perfect equilibrium strategy for Player 1 in the Duopoly game from Figure 9
4.2.3 Self-generation
There exist a number of numerical methods (Cronshaw & Luenberger, Reference Cronshaw and Luenberger1994; Cronshaw, Reference Cronshaw1997; Judd et al., Reference Judd, Yeltekin and Conklin2003) for computing the set of subgame-perfect equilibrium payoffs for a given stage-game and a given discount factor. Judd et al. (Reference Judd, Yeltekin and Conklin2003) describe an algorithmic approach permitting to first identify the set of subgame-perfect equilibrium payoff profiles, and then to extract players’ strategies yielding a certain payoff profile belonging to this set.
Let V p denote the set of subgame-perfect equilibrium payoffs that we want to identify. Recall Equation (4): after history h t, to make part of a subgame-perfect equilibrium strategy, action ai has to be supported by a certain continuation promise  $$\[--><$>{{u}_i}(\sigma {{|}_{{{h}^{t\, + \,1}} }}) <$><!--$$
. By the definition of subgame-perfection, this must hold after any history. Therefore, if ai makes part of a subgame-perfect equilibrium σ, then
 $$\[--><$>{{u}_i}(\sigma {{|}_{{{h}^{t\, + \,1}} }}) <$><!--$$
has to belong to V p as well as
 $$\[--><$>{{v}_i}({{a}_i},\sigma {{|}_{{{h}^t} }}) <$><!--$$
. This self-referential property of subgame-perfect equilibrium suggests a way by which one can find V p. The key to finding V p is a construction of self-generating sets (Abreu et al., Reference Abreu, Pearce and Stacchetti1990). The analysis focuses on the map B p defined on a set
 $$\[--><$> {{W}^p} \, \subset \,{\Bbb R}{{}^n} <$><!--$$
:
 $$ {{B}^p} ({{W}^p} ) = \bigcup\limits_{(a,w) \in A\,\times \,{{W}^p} } {(1{\rm{ - }}\gamma )r(a)\, + \,\gamma w} $$
where  $$\[--><$> w \in {\Bbb R}{{}^n} <$><!--$$
has to verify:
 $$ (1{\rm{ - }}\gamma ){{r}_i}(a) + \gamma {{w}_i}{\rm{ - }}(1{\rm{ - }}\gamma )B{{R}_i}(a) + \gamma {{\underline w}_i}\geq 0 $$
BRi(a) denotes a best response of player i to the action profile a, and  $$\[--><$>{{\underline w}_i} \equiv {{\inf }_{w \in {{w}^p} }}\,{{w}_i} <$><!--$$
. Abreu et al. (Reference Abreu, Pearce and Stacchetti1990) show that the largest fixed point of B p(W p) is V p, that is, B p(V p) = V p and V p is the largest such set.
Any numerical implementation of B p(W p) requires an efficient representation of the set W p in a machine. Judd et al. (Reference Judd, Yeltekin and Conklin2003) propose to use convex sets in order to approximate both W p and B p(W p) as an intersection of hyperplanes. With this in hand, each application of a B(W) (a convexified version of map B p(W p)) is reduced to solving a convex optimization problem. We omit further details: the interested reader can refer to Judd et al. (Reference Judd, Yeltekin and Conklin2003); an extended version of the paper with useful illustrations and examples is also available. The algorithm of Judd et al. (Reference Judd, Yeltekin and Conklin2003) permits computing only pure action subgame-perfect equilibria in repeated games. Burkov and Chaib-draa (Reference Burkov and Chaib-draa2010) leverage self-generation to approximate all (pure and mixed) action equilibria.
As we already mentioned in the beginning of this section, for any two-player repeated game with the AP criterion, there exists an efficient algorithm returning a pair of automata inducing a subgame-perfect equilibrium strategy profile (Littman & Stone, Reference Littman and Stone2005). For more than two players, however, it has recently been demonstrated that an efficient algorithm for computing subgame-perfect equilibria is unlikely to exist (Borgs et al., Reference Borgs, Chayes, Immorlica, Kalai, Mirrokni and Papadimitriou2008). In Section 4.3, we will explore the question of strategy computability and implementability.
4.3 Complexity in repeated games
The word ‘complexity’ in the context of repeated games can have two different meanings: design complexity and implementation complexity. Kalai and Stanford (Reference Kalai and Stanford1988) talk about implementation complexity as the complexity of player's strategy. More precisely, they define implementation complexity as the cardinality of the set  $$\[--><$>{{\sum }_i}({{\sigma }_i}) = \{ {{\sigma }_i}{{|}_{{{h}^t} }}:{{h}^t} \in H\} <$><!--$$
. This reflects the number of continuation game strategies, which the player's strategy induces after different histories. The authors then establish that this measure of strategic complexity is equal to the number of the states of the smallest automaton that implements the strategy (Kalai & Stanford, Reference Kalai and Stanford1988, Theorem 3.1). A similar theory is due to Abreu and Rubinstein (Reference Abreu and Rubinstein1988).
Another meaning of complexity, design complexity, can be described as the measure of computational resources of players required to compute (or design) a strategy having the desired properties (Gilboa, Reference Gilboa1988; Ben-Porath, Reference Ben-Porath1990; Papadimitriou, Reference Papadimitriou1992).
4.3.1 Implementation complexity
Abreu and Rubinstein (Reference Abreu and Rubinstein1988) modified the subgame-perfect equilibrium concept by incorporating into it the notion of implementation complexity. They first defined machine game as a two-player normal form game build upon an original repeated game. In a machine game, the set  $$\[--><$>{{{\cal M}}_i}<$><!--$$
of player i's actions, i ∈ {1, 2}, is a finite set containing finite automata
 $$\[--><$>{{M}_i} \in {{{\cal M}}_i}<$><!--$$
. Every such automaton induces a different player i's strategy in the original repeated game. In the machine game, player i prefers a strategy profile induced by an automaton profile M ≡ (M 1, M 2) to another strategy profile induced by an automaton profile
 $$\[--><$>M^{\prime} \equiv ({{M^{\prime}_1}},\,{{M^{\prime}_2}})<$><!--$$
(we then write
 $$\[--><$>M\,{{{\succ}}_i}\,M^{\prime}<$><!--$$
) if either
 $$\[--><$>{{u}_i}(M) \gt {{u}_i}(M^{\prime}) \wedge |{{M}_i}| = |{{M^{\prime}_i}}|<$><!--$$
or
 $$\[--><$>{{u}_i}(M) = {{u}_i}(M^{\prime}) \wedge |{{M}_i}| \lt |{{M^{\prime}_i}}|<$><!--$$
. In other words, the players playing a machine game have lexicographic preferences over the automata inducing equal payoffs. Abreu and Rubinstein (Reference Abreu and Rubinstein1988) then define a Nash equilibrium of the machine game as a pair of machines (M 1, M 2),
 $$\[--><$>M{_1} \in {{{\cal M}}_1}<$><!--$$
,
 $$\[--><$>M{_2} \in {{{\cal M}}_2}<$><!--$$
, with the property that there is no another automaton
 $$\[--><$>M{^{\prime}_1} \in {{{\cal M}}_1}\,{\rm{or}}\,M{^{\prime}_2} \in {{{\cal M}}_2}<$><!--$$
such that
 $$ ({{M^{\prime}_1}},\,{{M}_2})\,{{{\succ}}_1}\,({{M}_1},\,{{M}_2})\,or\,({{M}_1},\,{{M^{\prime}_2}})\,{{{\succ}}_2}\,({{M}_1},\,{{M}_2}) $$
Abreu and Rubinstein (Reference Abreu and Rubinstein1988) described the structure of an equilibrium strategy profile in the machine game: similarly to the subgame-perfect equilibrium strategies, which we constructed in the proofs of folk theorems, in a Nash equilibrium of the machine game the players’ automata must contain a non-cyclic punishment part and a cyclic cooperative part respecting a set of interdependent conditions.
An important result for the DAP criterion (a similar one exists for the AP criterion as well) is formulated as follows. Let (M 1, M 2) be a Nash equilibrium of the machine game. This induces two properties. First, the players’ automata M 1 and M 2 have an equal implementation complexity, and maximize the repeated game payoff against one another. Second, if in any two periods, M 1 (respectively, M 2) plays the same stage-game action, this must be true for the other automaton as well. The latter property permits restricting to a great extent the space of strategies the players can choose from. Also, this permits considerably reducing the set of payoffs that can arise in an equilibrium (see Abreu & Rubinstein, Reference Abreu and Rubinstein1988 for more details). Kalai and Stanford (Reference Kalai and Stanford1988) established similar results (while under distinct assumptions) about the implementation complexity for n-player (n > 2) machine games.
In order to demonstrate that not every subgame-perfect equilibrium strategy profile in a repeated game is also a Nash equilibrium in the corresponding machine game, let us consider the following example. Let us suppose there are two players playing a repeated Prisoner's Dilemma from Figure 1 using the profile of two TFT strategies. With the AP criterion, this strategy profile is clearly a subgame-perfect equilibrium. However, this is not a Nash equilibrium of the corresponding machine game. The reason is that when Player 2 uses TFT, Player 1 can be better of by deviating (in the machine game) to a one-state automaton strategy in which it always plays C. Such a strategy has a lower complexity while bringing the same AP to Player 1. On the other hand, if Player 1 chooses this one-state automaton strategy, Player 2 will prefer to choose a one-state automaton that always plays D. This process of strategy changes terminates when each player chooses a one-state automaton that always plays D. Observe that such a strategy profile now constitues a Nash equilibrium of the machine game and also a subgame-perfect equilibrium in the repeated Prisoner's Dilemma.
Notice the following implicit feature of the approach of Abreu and Rubinstein (Reference Abreu and Rubinstein1988). Assuming that the players playing a machine game have lexicographic preferences over the automata inducing equal payoffs is equivalent to assigning an infinitesimal cost to each state of the automaton. Neme and Quintas (Reference Neme and Quintas1995) followed the direction proposed by Abreu and Rubinstein. They considered the case when the complexity enters the utility function as a non-infinitesimal real number defining the cost of using each additional automaton state:
 $$u_{i}^{k} (\sigma )\, \equiv \,{{u}_i}(\sigma )\,{\rm{ - }}\,k(comp({{\sigma }_i}))$$
In the above definition,  $$\[--><$>u_{i}^{k} <$><!--$$
is called the utility function with cost, k is the cost function defined as a mapping
 $$\[--><$>k:{\Bbb N}\, \mapsto \,{{{\Bbb R}}^ + } <$><!--$$
and comp(σi) denotes the number of states of the minimal automaton inducing the strategy σi. Neme and Quintas studied the structure of Nash equilibrium in repeated games with complexity costs. They provided a corresponding folk theorem for infinite automata, as well as a finite approximation result (Neme & Quintas, Reference Neme and Quintas1995). At their turn, Ben-Sasson et al. (Reference Ben-Sasson, Kalai and Kalai2007) studied repeated zero-sum games with costs and the properties of certain game theoretic algorithms applied to such games. Notice that the notion of strategy cost naturally reflects a fundamental property of any real-world application: one should pay for every additional resource artificial agents can use in order to become more effective.
For their part, Lipman and Wang (Reference Lipman and Wang2000, Reference Lipman and Wang2009) introduced the concept of switching costs. In particular, the authors modify the standard repeated game model by adding a small cost endured by the players when they change their actions between two subsequent periods. The authors show that the addition of such costs changes the properties of equilibria. For example, a multiplicity of equilibria arise in certain games that have a unique subgame-perfect equilibrium without switching costs. On the other hand, in the coordination games, which have multiple equilibria without switching costs, it appears that with small switching costs one can have a unique subgame-perfect equilibrium.
Banks and Sundaram (Reference Banks and Sundaram1990) studied the structure of Nash equilibria in two-player repeated games played by finite automata. Their complexity criterion takes into account not only the size of the automaton but also its transitional structure. In this context, the authors show that the only Nash equilibria in machine games are the pairs of automata that every period recommend actions that are stage-game Nash equilibria.
Another approach to implementation complexity in repeated games is due to Neyman (Reference Neyman1985, Reference Neyman1995), Ben-Porath (Reference Ben-Porath1993), and others (Zemel, Reference Zemel1989; Papadimitriou & Yannakakis, Reference Papadimitriou and Yannakakis1994). According to this approach, players do not include complexity cost into their strategies, but each player i is exogenously restricted to choose among the automata having the number of states that does not exceed mi. In contrast to most of the results presented in this paper (i.e. applicable to infinitely repeated games) the following results have only been established for finitely repeated games.
As we already mentioned in Section 3, in finitely repeated games, the horizon T of the repeated game (i.e. the number of game repetitions) is supposed to be finite, fixed and known by all players before the game starts. The analysis and the solutions in finitely repeated games have quite different properties due to the fact that one can use backward induction to compute game solutions. For example, when the players are not given with an upper bound on the complexity of their strategies, it can be shown that cooperation cannot be an equilibrium solution of the finitely repeated Prisoner's Dilemma. Indeed, when there exists the last period T, in the absence of the threat of future punishments, the action profile of players at iteration t = T should constitute a stage-game Nash equilibrium (D, D). Therefore, at iteration t = T – 1, because the future play is known and independent of the present action profile, there is also no way to impose the cooperation, and so on. The similar considerations can apply to all other repeated games having the property that all Nash equilibria of the stage-game yield a payoff profile v, such that,  $$\[--><$>{{\forall }_i} \in N,\,{{v}_i} = {{\underline{v} }_i}<$><!--$$
(Osborne & Rubinstein, Reference Osborne and Rubinstein1994, p. 155). Notice that there exists a notion of subgame-perfection in finitely repeated games. There also exists a number of folk theorems for such games (Benoit & Krishna, Reference Benoit and Krishna1985).
Despite the absence, in finitely repeated Prisoner's Dilemma, of cooperative outcomes sustained by an equilibrium, it is known that a certain degree of cooperation is possible when the players’ strategic complexities are bounded. For example, this is true when the minimal of the players’ automata has the size that is less than exponential in the value of the repeated game horizon T. This result is due to Papadimitriou and Yannakakis (Reference Papadimitriou and Yannakakis1994). The seminal work providing a weaker result is due to Neyman (Reference Neyman1985). The main idea behind this phenomenon is that in the equilibrium, player i adopts a strategy that realizes a complex sequence of C and D. From the part of player −i, in order to have a profitable deviation, this would require to keep track of this sequence. The latter fact, in turn, would imply that player −i must have a number of states that exceeds the given bound. See Papadimitriou and Yannakakis (Reference Papadimitriou and Yannakakis1994) and Neyman (Reference Neyman1998) for the details of the proof.
4.3.2 Design complexity
In addition to characterizing the equilibrium behavior of automata under the condition of limited or paid resources, certain researchers also investigated the computational complexity of the task of designing a best-response automaton. Gilboa (Reference Gilboa1988) considered the problem of computing a best-response automaton Mi for player i in a repeated game with n players when the other players’ pure strategies are induced by finite automata. He demonstrated that both (1) the problem of determining whether Mi induces a strategy that is a best response to the strategy profile induced by the automata of the remaining players, and (2) the problem of finding an automaton Mi inducing such a best-response strategy, can be solved in a time polynomial in the size of the automata.
Ben-Porath (Reference Ben-Porath1990) demonstrated, in turn, that for a repeated two-player game where player 2 plays a mixed strategy by sampling pure finite automata from a distribution with a finite support, both (1) the problem of determining whether a given automaton of player 1 induces a best-response strategy to the strategy of player 2, and (2) the problem of finding such a best-response automaton, cannot be solved efficiently.
Papadimitriou (Reference Papadimitriou1992) explored the relationship between the computational complexity of finding a best-response strategy and the implementation complexity in the repeated Prisoner's Dilemma. In particular, he showed that if an upper bound M 1 is placed on the number of states of the automaton M 1 of Player 1, the problem of determining whether M 1 induces a best response to the strategy of Player 2, represented by the automaton M 2, can only be solved efficiently, when m 1 ≥ |M 2|.
The complexity of constructing a profile of strategies inducing a Nash equilibrium in a repeated game (and not only finding or verifying a best-response strategy) has been studied by Littman and Stone (Reference Littman and Stone2005) and Borgs et al. (Reference Borgs, Chayes, Immorlica, Kalai, Mirrokni and Papadimitriou2008). The former have shown that a subgame-perfect equilibrium strategy profile for a two-player repeated game with the AP criterion can be computed in a time polynomial in a number of input parameters. Borgs et al. (Reference Borgs, Chayes, Immorlica, Kalai, Mirrokni and Papadimitriou2008), in turn, have shown that for more than two players a polynomial algorithm cannot probablyFootnote 8 exist.
There exists another interesting complexity measure: the communication complexity. This complexity measure counts the amount of information exchanged between the participants of a distributed optimization problem. This measure is useful for establishing the results in the form of lower bounds on the number of bits of communication needed to solve the problem (Kushilevitz & Nisan, Reference Kushilevitz and Nisan1997). The applications include equilibrium computation in games with a large number of players. For example, Hart and Mansour (Reference Hart and Mansour2007) established that the worst-case amount of payoff information that must be exchanged between n players to reach a Nash equilibrium (when initially each player knows only its own payoff function) is exponential in n.
In Section 5, we pass from the setting of perfect monitoring to that of imperfect monitoring. We first adjust the model of repeated games so as to take into account the imperfection of the observability model. Then, we briefly overview the most important results obtained in this setting.
5 Imperfect monitoring
The setting of perfect monitoring in repeated games roughly corresponds to observability without noise in the algorithmic decision theory (Berry & Fristedt, Reference Berry and Fristedt1985; Sutton & Barto, Reference Sutton and Barto1998). Imperfect private monitoring can be compared with the notion of partial observability well known in the computer science (Kaelbling et al., Reference Kaelbling, Littman and Cassandra1998; Bernstein et al., Reference Bernstein, Givan, Immerman and Zilberstein2003). Indeed, the imperfect monitoring setting is closely related to general MAS, because the model of artificial agent assumes an uncertain observability of the environment by the agent due to its noised sensors (Russell & Norvig, Reference Russell and Norvig2009).
The study of repeated games of perfect monitoring is considerably simplified by the fact that often the structure of an equilibrium strategy is quite simple: a cycle of cooperative actions is followed; any deviation of one player is immediately detected and jointly punished by the other players. When monitoring is imperfect, not every deviation can be immediately and with certainty detected, as well as the identity of deviator cannot always be precisely determined. Therefore, an important part of the analysis in games of imperfect monitoring is devoted to specifying conditions, under which the deviations are detectable and the deviators are identifiable.
In Section 4, we have seen that equilibria in repeated games of perfect monitoring have a recursive structure: for any action, to make part of an equilibrium strategy, it should induce an equilibrium continuation strategy. This recursive structure can also be preserved in discounted repeated games of imperfect public monitoring. The latter fact considerably simplifies the study of such games. Furthermore, it can be asserted that the games of public monitoring are relatively well studied (Abreu et al., Reference Abreu, Pearce and Stacchetti1990; Fudenberg et al., Reference Fudenberg, Levine and Takahashi2007; Hörner & Olszewski, Reference Hörner and Olszewski2007). On the other hand, repeated games of private monitoring still remain considerably less explored in the literature.
In the next subsections, we survey the literature studying the games of imperfect monitoring. To do that, we first need to adjust our model of repeated games so as to take into account the imperfection of monitoring.
5.1 Repeated game: revisited
The model of repeated games of imperfect monitoring differs from the perfect monitoring model, which we defined in Section 2. As previously, there is a finite set of players N, a finite set of actions Ai for each player i ∈ N, and a collection {ri}i ∈N of player-specific payoff functions  $$\[--><$>{{r}_i}:A\, \mapsto \,{\Bbb R}<$><!--$$
, where
 $$\[--><$>A\, \equiv \,{{\times }_{i \in N}}{{A}_i}<$><!--$$
. The difference induced by the particular structure of imperfect game monitoring can be described as follows. At the end of each stage-game, each player observes a signal yi drawn from a finite signal space Yi. Let Y ≡ ×i ∈NYi. The function
 $$\[--><$>\rho :Y\,\times \,A\, \mapsto \,[0,\,1]<$><!--$$
defines the probability with which each signal profile y ∈ Y is drawn given an action profile a ∈ A.
Notice that in this model, a repeated game of perfect monitoring is a special case, in which for every player i, Yi ≡ A, and,
 $$\openup 3pt\left\{ {\matrix{ {\rho ({{{({{y}_i})}}_i}_{{ \in N}}, a) = 1,} \quad{{\rm{if}}\,y_i = a \ \forall i;} \hfill\cr {\rho ({{{({{y}_i})}}_i}_{{ \in N}}, a) = 0,} \ \ \,{{\rm{otherwise}}}.\hfill \right $$
A repeated game is said to be a game of public monitoring, if for all signal profiles y ∈ Y and for each pair of players i, j∈ N, we have yi = yj. Otherwise, the repeated game is said to be a game of private monitoring.
When thinking about decision making in repeated games with imperfect monitoring, two types of finite histories have to be considered. The first set of histories up to period t,  $$\[--><$>H_{i}^{t} \equiv {{\times }_t}({{A}_i}\times {{Y}_i})<$><!--$$
, contains player-specific histories of length t. Those histories are uniquely based on the information available to player i: the observed signals and the own played actions. The other set of histories,
 $$\[--><$>{{H}^t} \, \equiv \,{{\times }_t}(A\,\times \,Y)<$><!--$$
, contains the histories based on the full information generated in the repeated game up to period t. Any history belonging to the set H t can be viewed as a sequence of action profiles observed by an omniscient observer capable of perceiving an imperfect monitoring game as if it was a game of perfect monitoring.
Let  $$\[--><$>{{H}_i}\, \equiv \, \bigcup _{{t = 0}}^{\infty } H_{i}^{t} <$><!--$$
denote the set of player i's personal histories, and let
 $$\[--><$>H \equiv \bigcup _{{t = 0}}^{\infty } {{H}^t} <$><!--$$
be the set of game histories. A pure private strategy σi of player i is a mapping
 $$\[--><$>{{\sigma }_i}:{{H}_i}\, \mapsto \,{{A}_i}<$><!--$$
from the set of player i's personal histories to the set of player i's actions. Similarly, a mixed private strategy is a mapping
 $$\[--><$>{{\sigma }_i}:{{H}_i}\, \mapsto \,{\rm{\rDelta }}({{A}_{{i}}})<$><!--$$
.
In repeated games of imperfect monitoring, Nash equilibrium is defined similarly to the definition of this concept for games of perfect monitoring. On the other hand, we cannot simply define and study the subgame-perfect equilibria, because in the case of personal histories, there are no non-trivial subgames. The appropriate notion of sequential rationality in the imperfect information setting is sequential equilibrium (Kreps & Wilson, Reference Kreps and Wilson1982). In words, a strategy profile σ is a sequential equilibrium if, for each player i, after any personal history, player i's strategy is a best response to its beliefs over the strategies of the other players. The beliefs of player i are conditioned on its personal history.
5.2 Public monitoring
Studying equilibria in private strategies, such as sequential equilibria, is complicated by a potential need of keep track of player i's beliefs about the other players’ personal histories. Equilibrium actions will then depend on the infinitely nested beliefs of players, about the beliefs of other players about their beliefs, and so on. Reducing attention to public strategies permits simplifying the analysis of equilibria in repeated games of public monitoring (Abreu et al., Reference Abreu, Pearce and Stacchetti1990; Fudenberg et al., Reference Fudenberg, Levine and Takahashi2007).
5.2.1 Equilibria in public strategies
The set of public histories up to period t is denoted by  $$\[--><$>H_{{pub}}^{t} \, \equiv \,{{\times }_t}Y<$><!--$$
. The set of all public histories, Hpub, can then be defined as
 $$\[--><$>{{H}_{pub}}\, \equiv \, \bigcup _{{t = 0}}^{\infty } H_{{pub}}^{t} <$><!--$$
. A pure public strategy σi of player i is a mapping from the set of public histories to the set of player i's actions,
 $$\[--><$>{{\sigma }_i}:{{H}_{pub}}\, \mapsto \,{{A}_i} <$><!--$$
. A similar definition can be obtained for the mixed public strategies.
When we only consider public strategies, the notions of subgame and subgame strategy can easily be defined, because now after each game history all players use the same information to base their continuation play on.
Definition 10 A perfect public equilibrium is a profile of public strategies such that after every public history, each player's continuation strategy is a best response to the opponent's continuation strategy.
As we have already pointed out, in order to construct an equilibrium strategy in the conditions of imperfect monitoring, one needs to have all deviations detectable and all deviators identifiable.
Definition 11 A mixed action profile  $$\[--><$>\alpha \, \equiv \,({{\alpha }_i},{{\alpha }_{{\rm{ - }}i}}) <$><!--$$
hasindividual full rank for player i if the collection of probability distributions
 $$\[--><$>{{\{ \rho ( \cdot, {{a}_i},{{\alpha }_{{\rm{ - }}i}})\} }_{{{a}_i} \in {{A}_i}}} <$><!--$$
is linearly independent. If this holds for every player i ∈ N, then α has individual full rank.
In other words, if a mixed action profile has individual full rank, no player can change the distribution of its actions without affecting the distribution of public signals. Therefore, individual full rank is a condition of detectability of deviations.
Definition 12 Let  $$\[--><$>\alpha \, \equiv \,({{\alpha }_i},{{\alpha }_{{\rm{ - }}i}}) <$><!--$$
be a mixed action profile. Let the (|Ai|×|Y|) matrix Ri(α −i) have its element
 $$\[--><$>{{[{{R}_i}({{\alpha }_{{\rm{ - }}i}})]}_{{{a}_i}y}}\, \equiv \,\rho (y,{{a}_i},{{\alpha }_{{\rm{ - }}i}})<$><!--$$
. The profile α has pairwise full rank for players i and j if the (|Ai| + |Aj| × |Y|) matrix,
 $$ {{R}_{ij}}(\alpha ) = \left( {\matrix{ {{{R}_i}({{a}_{ - i}})} \hfill\cr {{{R}_j}({{a}_{ - j}})} }} \right) $$
has rank |Ai| + |Aj|−1. If this holds for every pair of players, then α has pairwise full rank.
Under the condition of pairwise full rank, deviations from two different players induce different distributions of public signals. Therefore, pairwise full rank is a condition of identifiability of deviators.
Several folk theorems for public monitoring have originally been established by Fudenberg et al. (Reference Fudenberg, Levine and Maskin1994). Here, we present a generalized and aggregated formulation from Mailath and Samuelson (Reference Mailath and Samuelson2006, p. 301).
Theorem 6 (The public monitoring FT with DAP)Let all pure action profiles yielding the extreme points of F †have pairwise full rank.
1. If
$$\[--><$>\tilde{\alpha } <$><!--$$
is an inefficient stage-game Nash equilibrium, then for all
$$\[--><$>v \in {\rm int}\{ v^{\prime}\, \in {{F}^&#x2020; } :{{v^{\prime}_i}}\geq {{r}_i}(\tilde{\alpha })\forall i\} <$><!--$$
, there exists
$$\[--><$>\underline{\gamma } {\rm{ \lt 1}} <$><!--$$
such that for all
$$\[--><$>\gamma \in (\underline\gamma, 1),v <$><!--$$
is a payoff of a certain perfect public equilibrium.2. If
$$\[--><$>\underline{v} \, \equiv \,{{({{\underline{v} }_i})}_{i \in N}} <$><!--$$
is inefficient and each player's minmax profile
$$\[--><$>{{\hat{\alpha }}^i} <$><!--$$
has individual full rank, then, for all
$$\[--><$>v \in {\rm int}\,{{F}^{&#x2020; + }} <$><!--$$
, there exists
$$\[--><$>\underline{\gamma } \,{\rm{ \lt }}\,{\rm{1}} <$><!--$$
such that for all
$$\[--><$>\gamma \in (\underline{\gamma }, 1),\,v<$><!--$$
is a payoff of a certain perfect public equilibrium.

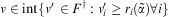


Proof. For the complete proof, see Mailath and Samuelson (Reference Mailath and Samuelson2006, p. 301). Intuitively, in the first case, the existence of an inefficient stage-game Nash equilibrium implies that it can be used as a threat to prevent deviations and to support the payoff profiles that Pareto dominate it. The punishment will happen because  $$\[--><$>\tilde{\alpha }<$><!--$$
is a stage-game equilibrium and therefore no one-shot deviation is profitable. In the second case, the fact that the profile of minmax payoffs is inefficient and that each player's minmax profile has individual full rank implies that punishment will happen since the deviations from it are detectable. □
5.2.2 Equilibria in private strategies
The payoffs generated by public perfect equilibrium strategy profiles do not cover all sequential equilibrium payoffs that can arise in repeated games of public monitoring. Certain sequential equilibrium payoffs can only be generated by the profiles of private strategies (Kandori & Obara, Reference Kandori and Obara2006). Due to the complexity of the setting, only few results exist that characterize the set of sequential equilibrium payoff in games of public monitoring with private strategies. The examples include Mailath et al. (Reference Mailath, Matthews and Sekiguchi2002) and Renault et al. (Reference Renault, Scarlatti and Scarsini2005, Reference Renault, Scarlatti and Scarsini2008).
5.3 Private monitoring
The main reason of difficulties in studying games of private monitoring lies in the fact that players do not have any common information to base their continuation play on. In games of perfect monitoring, this common information is the history of the repeated game. In games of imperfect public monitoring, players can maintain a common public history. The signals received by two different players in a repeated game of private monitoring can be different. Therefore, their private histories can differ. Consequently, the notion of subgame cannot easily be defined. There exist several approaches to bypass this problem. They consist in considering different important special cases of a more generally stated problem:
Almost perfect and almost public monitoring: These are two special cases of private monitoring (Mailath & Morris, Reference Mailath and Morris2002). Almost perfect monitoring is a private monitoring with the property that each player can identify the action taken by its opponents with an error ε. Almost public monitoring, in turn, is a private monitoring when all players receive the same public signal with an error ε. In both cases, the error ε is supposed to be small, that is, 0 < ε ⪡ 1.
The first significant result has been obtained by Sekiguchi (Reference Sekiguchi1997) in the repeated Prisoner's Dilemma with almost perfect monitoring. In this seminal work, he showed that the payoff profile corresponding to action profile (C, C) can be approximated by an equilibrium strategy profile when the monitoring is almost perfect. Bhaskar and Obara (Reference Bhaskar and Obara2002) then extended Sekiguchi's approach to support in equilibrium any payoff profile that Pareto dominates the minmax payoff profile. Ely and Valimaki (Reference Ely and Valimaki2002) then proved the folk theorem for the repeated Prisoner's Dilemma of almost perfect monitoring. Recently, Hörner and Olszewski (Reference Hörner and Olszewski2006) proved a folk theorem for general repeated games of almost perfect monitoring.
In their turn, Mailath and Morris (Reference Mailath and Morris2002) considered the repeated games of almost public monitoring and prove a folk theorem. Their results only apply when the strategies are of a finite memory (Mailath & Morris, Reference Mailath and Morris2002). Under similar conditions, Hörner and Olszewski (Reference Hörner and Olszewski2007) obtained a strengthened result.
Belief-free equilibria: Ely et al. (Reference Ely, Hörner and Olszewski2005) considered so-called belief-free equilibrium strategies. A sequential equilibrium is belief-free if, after every private history, each player's continuation strategy is optimal independently of its belief about the opponents’ private histories. The authors provided a characterization of equilibrium payoffs generated by those strategies. They showed that belief-free strategies are not rich enough to generate a folk theorem in most games besides the repeated Prisoner's Dilemma. In their turn, Hörner and Lovo (Reference Hörner and Lovo2009) characterized a set of payoffs that includes all belief-free equilibrium payoffs.
Other approaches: Efficient equilibria under private monitoring have been obtained in the repeated games with the AP criterion (Radner, Reference Radner1986). An approximated folk theorem for games of private monitoring has been established by Fudenberg and Levine (Reference Fudenberg and Levine1991). The idea behind those papers is to construct a strategy profile, in which a player has to deviate infinitely often in order to get a payoff improvement.
Another approach to bypass the aforementioned inherent difficulties of private monitoring, is to introduce a possibility of public communication between players. Compte (Reference Compte1998) proved a folk theorem with communication for more than two players and showed that an approximated result can be obtained for two-player case as well. There are two main ideas behind Compte's approach. The first one is that public communication histories are analogous to public histories defined in repeated games of public monitoring. Therefore, they permit establishing a notion of subgame. The second idea is the notion of delayed communication: the players reveal their private signals every T periods. The intuition is that deviating a small fraction of those T periods yields a small gain, while deviating a larger fraction of periods can be detected by the other players. Obara (Reference Obara2009) extends the idea of delayed communication to the case where private signals are correlated. He then proves a new folk theorem for repeated games with private monitoring and communication.
6 Conclusion
Repeated games are proven to be useful for MAS as a mathematical abstraction used to represent the interactive aspects of MAS in a compact form. The model of repeated games has been adopted by different researchers to represent complex multiagent interaction schemas. Computer scientists, however, mainly focused on the stationary solutions of repeated games, by only using its repetitive property as a mean to implement an iterative algorithm searching for a stationary equilibrium solution (Bowling & Veloso, Reference Bowling and Veloso2002; Banerjee & Peng, Reference Banerjee and Peng2003; Conitzer & Sandholm, Reference Conitzer and Sandholm2007). While stationary equilibria are the appropriate solutions in the repeated games, their corresponding set of players’ payoffs is typically very restricted. When a repeated game is supposed to be played only once by the same set of players, stationary equilibrium can be considered as the only possible solution. However, when multiagent interactions are extended in time and have a repeated nature, there can exist non-stationary strategy profiles whose payoffs are more attractive for the whole set of players. For instance, the payoffs of such non-stationary strategy profiles can Pareto dominate any stationary equilibrium payoff. The most important (and complex) question is to determine the conditions under which these strategy profiles constitute an equilibrium.
Research on repeated games in economics considered the repetitive property of repeated games as an important distinction from the other interaction models (Abreu, Reference Abreu1988; Aumann & Shapley, Reference Aumann and Shapley1994; Osborne & Rubinstein, Reference Osborne and Rubinstein1994; Mailath & Samuelson, Reference Mailath and Samuelson2006). Economists used the discounted factor to compare player's preferences between its present and future payoffs. The proper definition of the player's long-term payoff function gave rise to the variety of new solutions in the existing games. Thus, for example, the repeated Prisoner's Dilemma, which has the unique non-cooperative stationary equilibrium with low payoffs, obtains a variety of Pareto efficient equilibrium solutions in the form of the TFT strategy profile.
The basic model of repeated games then gives rise to a variety of different settings that can affect the preferences and therefore the decisions of players. These settings differ by the number of iterations of the repeated game, payoff criteria chosen by the players, their patience, information they dispose about the properties of the game, and the perfection (or imperfection) of game monitoring. A collection of folk theorems establish, for different such settings, the bounds on the long-term payoffs that can be obtained by the players in equilibrium when the discount factor tends to one.
After determining the set of all possible equilibrium payoffs, the next important question is which of these payoffs are attainable given a particular value of the discount factor. For instance, a low discount factor means that the players are impatient and, therefore, the future punishments for the present deviations cannot be severe enough to support all the payoffs promised by the corresponding folk theorem. As a consequence, a number of works exist on finding a set of equilibrium payoffs supported by a given discount factor (Abreu, Reference Abreu1988; Cronshaw & Luenberger, Reference Cronshaw and Luenberger1994; Cronshaw, Reference Cronshaw1997; Judd et al., Reference Judd, Yeltekin and Conklin2003; Littman & Stone, Reference Littman and Stone2005).
When the set of payoff profiles supported by a certain discount factor is found, the next step is the extraction of strategy profiles corresponding to a certain payoff from this set. In MAS, populated by artificial agents, this task is complicated by the fact that this extraction has to be done efficiently; furthermore, the extracted strategies have to be representable in a finite way. A number of works have been devoted to the study of computability of strategies in repeated games, and their representability as finite automata (Neyman, Reference Neyman1985; Abreu & Rubinstein, Reference Abreu and Rubinstein1988; Kalai & Stanford, Reference Kalai and Stanford1988; Papadimitriou, Reference Papadimitriou1992; Papadimitriou & Yannakakis, Reference Papadimitriou and Yannakakis1994; Littman & Stone, Reference Littman and Stone2005).
While the setting characterized by complete information and monitoring in repeated games is relatively well studied, a number of important questions are still remaining in the other settings. The most difficult one is the setting of imperfect private monitoring characterizing many important practical problems, including multirobot problem solving, electronic commerce, and others. The main difficulty of this setting is that when the observations of different players are different, there is no non-trivial notion of subgame. Therefore, in order to compute the set of equilibrium payoffs, one cannot generally leverage the self-referential structure of an equilibrium payoff, as, for example, was done for the settings characterized by perfect or public monitoring.
Even in the perfect monitoring case, a number of important questions is remaining. Characterization of payoffs in mixed strategies is one example; finding fast and efficient approximate algorithms for computing equilibrium strategies is another one. Finally, extending the existing theoretical results and algorithms for repeated games, that go beyond stationary equilibria, to more complex multistate environments, such as dynamic or stochastic games, is an exciting and challenging future research direction.



