

1. Introduction
Artificial intelligence (AI) is reshaping the landscape of the healthcare industry,Reference Rajpurkar1 particularly in areas such as drug development, disease diagnosis, and remote rehabilitation.Reference Cabral2 Medical innovations typically face long development cycles, high costs, and a substantial risk of failure.Reference Dutfield and Suthersanen3 Consequently, the field has become highly reliant on the protection of patents. In recent years, there has been a sustained increase in AI-related medical patent applications,Reference Aboy4 making the patent regime a critical tool for both technological protection and market positioning.
As a fundamental legal arrangement for promoting innovation and knowledge dissemination, the patent system rests on the principle of “disclosure in exchange for protection.”5 Under this principle, inventors are required to disclose their inventions in sufficient detail at the time of filing, such that a person having ordinary skill in the art (PHOSITA) can practice the invention without undue experimentation. However, the disclosure principle faces challenges in the domain of medical AI. The black-box nature of AI algorithms, together with the inherent unpredictability of biomedical inventions and the sensitivity of clinical data, results in a dual-opacity dilemma.Reference Tschider6 This high-risk context warrants examination from both legal and empirical perspectives. The study therefore raises the research question: Do current medical AI patents satisfy the legal requirement of sufficiency of disclosure?
Prior scholarship has explored the issue of AI patent disclosure primarily from a doctrinal standpoint. Early literature focused on the compatibility between the technical characteristics of software patents and legal doctrines, warning that functional generalizations, lack of technical specificity, and shallow disclosure may erode the patent bargain.Reference Guillén and Jurado7 Some scholars have argued that traditional disclosure standards may be ill-suited to technologies such as deep learning models, which often lack meaningful information on architecture, training process, data origin, or validation.Reference Upputuri and Üner8 This makes it difficult for a PHOSITA to implement the invention. It has also been suggested that disclosure should meet only the minimum threshold of enablement, and that there is no need to mandate the publication of source code or commercially sensitive components — especially where the invention can be implemented based on existing knowledge.Reference Robinson9 These divergent views reflect the unresolved tensions at the intersection of law and AI technology. However, empirical research on the subject remains scarce.
In the context of medical AI, which is an archetypal cross-disciplinary field, the challenge of patent disclosure is even more acute. Yet few studies have systematically assessed whether medical AI patents provide sufficient disclosure. In 2024, Aboy et al. pioneered a conceptual multi-dimensional scoring framework to evaluate medical AI patents, assessing dimensions such as model architecture, mathematical content, training processes, and code availability.Reference Aboy10 While their study provided a valuable foundation, the framework remained conceptual, relied only on manual assessment, and lacked cross-jurisdictional analysis.
To address these limitations, this study adopts a four-stage analytical framework — from normative foundations to technical reality, gap analysis, and institutional responses. It combines doctrinal interpretation with empirical methods to investigate the sufficiency of disclosure in medical AI patents. Specifically, the paper first examines the legal foundations and expectations under the sufficiency of disclosure requirement in patent law. Second, it implements a structured assessment using natural language processing (NLP) and expert scoring to evaluate 865 medical AI patents granted between 2015 and 2025 in the US, China, and the EU. The analysis focuses on five key dimensions: algorithm transparency, training data accessibility, model reproducibility, result verifiability, and mathematical support.
The objectives of this study are to: (1) assess the overall sufficiency of disclosure in medical AI patents; (2) evaluate disclosure performance across the five dimensions and identify structural imbalances; (3) examine variations in disclosure practices across different patent jurisdictions; and (4) analyze the potential causes of insufficient disclosure and the risks arising from them, providing a basis for considering targeted policy responses. Theoretically, this study contributes to the understanding of how normative ideals in patent law are reflected in real-world disclosure practices. Practically, it provides cross-jurisdictional evidence and data-driven insights to inform the refinement of examination standards, litigation assessment, and more effective governance of medical AI innovation.
2. Normative Foundations: The Legal Duty to Disclose
2.1. Theoretical Underpinnings of Patent Disclosure
The principle of “disclosure in exchange for protection” lies at the heart of the patent system. It serves as a crucial bridge between technological innovation and the public interest.Reference Graham and Hegde11 Under social contract theory, patent rights are not natural entitlements but state-granted incentives designed to encourage the disclosure of inventions that might otherwise remain secret. This mechanism seeks to expand the common pool of knowledge and enhance collective welfare.Reference Hughes12 As Merges has argued, the legitimacy of intellectual property exclusivity depends on the preservation of mechanisms for public access, since private control over knowledge without corresponding pathways into the public domain would undermine its justification.Reference Merges13 Disclosure, therefore, is not a mere technical requirement but the normative foundation upon which the legitimacy of the patent system rests.
A functionalist approach to patent law further reinforces the public-serving dimension of this principle. Under this framework, the purpose of patent law is not only to incentivize individual innovation, but also to facilitate the dissemination and reuse of technical knowledge. The patent specification has been described as a mandatory information disclosure platform, akin to a public “archive of knowledge” or “technical library.”Reference Burk and McDonnell14 At the same time, patent rights are inherently time-limited monopolies. While the right to exclude is temporary, the information disclosed in the specification becomes, in legal terms, a permanent public resource. In this temporal context, the disclosure obligation serves a transitional function. It ensures that the protected invention is reintegrated into the public domain once the patent expires. As such, the accessibility and intelligibility of the specification determine not only the patent’s immediate usability but also its long-term contribution to the public interest.
Viewed from the standpoint of the knowledge community, technological innovation is inherently cumulative and collaborative. The knowledge, tools, and methodologies employed by inventors are often grounded in long-term public contributions. In this light, the patent system, as a limited exception to knowledge commons, can only be justified if the specification effectively enables reciprocal knowledge sharing. Building on this view, some scholars advocate a contractually reconstructed research commons — a public or quasi-public space for scientific data — to ensure access, reuse, and cumulative innovation.Reference Reichman and Uhlir15
Taken together, the duty of sufficiency of disclosure in patent law possesses both instrumental and normative value. It is not merely a prerequisite for the grant of exclusive rights, but also a foundational element of their legitimacy. A failure to meet the basic standard of disclosure renders the patent’s exclusivity unjustified. Conversely, inadequate disclosure can impede technological diffusion, reduce the scope of public benefit, and ultimately undermine the social objectives the patent system is designed to achieve.
2.2. Legal Norms Governing Patent Disclosure
The principle of “disclosure in exchange for protection” has achieved broad international recognition as a cornerstone of the patent system. Article 29 of the Agreement on Trade-Related Aspects of Intellectual Property Rights (TRIPS) requires that applicants disclose their inventions “in a manner sufficiently clear and complete for the invention to be carried out by a person skilled in the art.” The core elements of sufficiency have been incorporated into domestic legislation and regional instruments across major patent jurisdictions. For instance, Section 112(a) of the United States Code (USC), Article 83 of the European Patent Convention (EPC), Article 26(3) of the Chinese Patent Law, Article 36(4)(i) of Japan’s Patent Act, and Article 42(3)(i) of the Korean Patent Act — together representing the IP5, the five largest intellectual property offices worldwide — each requires that the specification enable a PHOSITA to understand and carry out the invention without undue experimentation. While specific doctrinal nuances exist, such as the distinct requirements for written description and enablement under US law, which are often treated as a single statutory requirement of sufficiency in the EPC and Chinese systems, these provisions share a common functional objective.Reference Gupta16 All three jurisdictions mandate that the technical solution be disclosed in a manner that allows a PHOSITA to practically implement the invention. This overarching functional equivalence constitutes the doctrinal justification for the cross-jurisdictional comparison in this study.
Although no jurisdiction has yet enacted disclosure standards specifically for “medical AI patents,” most major patent offices have issued examination guidelines for AI-related inventions. Given that medical AI patents fall within this broader category, these general provisions also govern their disclosure requirements. Table 1 summarizes the disclosure standards adopted by the IP5 offices.
Comparative Overview of AI Patent Disclosure Requirements Across Jurisdictions

As shown in Table 1, despite varying emphases, these major jurisdictions generally require disclosure of sufficient technical details to enable a PHOSITA to implement the invention. This includes algorithm structures, training data features, input-output relations, and implementation pathways, while avoiding abstract functional language. Within this normative framework, the validity of AI patents hinges on the sufficiency and reproducibility of disclosure. Notably, medical AI, as a typical application of AI in a highly sensitive domain, faces heightened transparency demands and more complex implementation conditions. Whether these normative requirements are realized in practice remains uncertain. This study therefore empirically examines the sufficiency and transparency of medical AI patent disclosures under current legal standards.
3. Technical Reality: Empirical Assessment of Disclosure in Medical AI Patents
3.1. Construction of the Medical AI Patent Dataset
3.1.1. Dataset Construction
To conduct an empirical evaluation of disclosure levels in medical AI patents, this study drew upon the PatSnap global patent database. This platform aggregates patent records from 172 jurisdictions and contains over 190 million patent documents.17 It provides full-text data, legal status, citation records, and classification metadata, offering a high degree of data completeness and technical indexing. Due to its broad coverage and data quality, PatSnap has been commonly adopted in patentometric and innovation studies,Reference Didyk18 and serves as a reliable data source for the present research.
To ensure conceptual clarity, this study defines medical AI patents as patents that apply artificial intelligence or machine-learning techniques to diagnostic, monitoring, or interventional medical tasks. These include applications in diagnostic imaging, physiological-signal analysis, patient monitoring, psycho-physical testing, and surgical or interventional assistance. To operationalize this definition, the retrieval strategy combined AI-related keywords (“machine learning,” “deep learning,” “natural language processing,” “neural networks,” “computer vision”) with the International Patent Classification (IPC) system.
The search was centered on IPC A61B, which aligns with our research focus, as it covers medical technologies for diagnosis, surgery, and identification — including instruments and processes used to examine bodily functions, perform surgical interventions, or identify individuals based on biological or behavioral features.19 Although A61B is a single main class, it encompasses a range of medically oriented subclasses that correspond to the domains in which medical AI systems are most commonly deployed — for example, physiological-signal measurement (A61B5), radiological imaging (A61B6), ultrasonic imaging (A61B8), endoscopic and minimally invasive examination (A61B1), surgical instruments (A61B17), and computer-assisted or robotic surgery (A61B34). Using A61B as the primary IPC filter ensures that the retrieved patents reflect AI-enabled diagnostic and monitoring technologies rather than unrelated AI applications such as drug-discovery platforms (A61K/C07/C12), general computing (G06F) or hospital administration systems (G16H).
Given the rapid evolution of AI technologies, the retrieval period was restricted to patents granted within the past decade (August 1, 2015 to July 31, 2025) in order to capture contemporary disclosure practices while avoiding outdated technological contexts. As the assessment of disclosure necessarily relies on the final, legally stable specification, only granted invention patents were included and pending applications were not considered. In the case of China, utility model patents were excluded, ensuring that all patents in the dataset had undergone substantive examination. In terms of jurisdictional coverage, the dataset focuses on patents granted by the EPO (European Patent Office), USPTO (United States Patent and Trademark Office), and CNIPA (China National Intellectual Property Administration). These offices constitute three of the most influential jurisdictions, ensuring both representativeness and feasibility.Reference Hutukka20 Japan and Korea, while institutionally significant within the IP5 framework, are beyond the scope of the present study and may be considered in future extensions.
The final Boolean query is shown in Table 2.
Boolean Search Strategy

After retrieval, the dataset was refined through simple family consolidation according to the DOCDB standard. This approach is commonly adopted in patentometric research to avoid redundant counting of the same invention.21 Under this standard, a simple family comprises patent documents that cover a single invention, where the technical content is considered identical and all members share the same priorities. Consequently, the unique invention serves as the primary unit of analysis in this study instead of individual patent filings. Following a manual review to ensure data integrity, the final sample comprised 865 granted patents for the empirical analysis.
3.1.2. Dataset Description
The dataset is technologically concentrated in medical technologies classified under IPC A61B. Based on primary IPC groups, most patents fall within physiological measurement and patient monitoring subclasses (≈78%), followed by diagnostic imaging technologies (≈13%), with a smaller share involving surgical or interventional devices (≈8%). This distribution indicates that the sample primarily captures AI-enabled diagnostic and monitoring applications, consistent with the operational definition of “medical AI patents” adopted in this study.
Regarding jurisdictional distribution, the dataset includes 629 patents from China, 205 from the US, and 31 from the EU. While this distribution is numerically uneven, it reflects the empirical reality of the global medical AI patent landscape. According to the World Intellectual Property Organization (WIPO), China and the US have consistently accounted for a substantial share of AI-related patent activity, particularly in application-oriented technological domains.22 Consequently, the jurisdictional skew is understood as an empirical reflection of actual innovation activity rather than a sampling bias. For the US sample, potential count inflation from continuation or divisional strategies was addressed through DOCDB simple patent family consolidation.23 A secondary audit further confirmed that each of the 205 US patents in our final sample possesses a unique priority number, ensuring that no duplicate technical disclosures or count inflation coexist in our dataset.
Notably, given the limited sample size of the EU (N = 31), these data are treated throughout this study as descriptive observations only. In the subsequent presentation and analysis of findings, the EU results are used for exploratory purposes and are excluded from formal inferential testing or comparative conclusions to maintain statistical rigor. This approach ensures that the study’s primary findings are grounded in the statistically robust Chinese and US samples, while the EU data are used descriptively as a context-setting reference for disclosure characteristics in that jurisdiction.
3.2. Design of the Disclosure Evaluation Framework
To systematically assess the quality of disclosure in medical AI patents, this study develops a five-dimensional evaluation framework. The framework draws upon legal provisions, judicial precedents, and academic literature, while also incorporating the technical logic of AI implementation. It identifies the most critical and observable components of patent disclosure in the context of medical AI. The five dimensions are defined as follows.
-
1. Algorithm transparency: This dimension evaluates whether the patent clearly reveals the structure and key parameters of the algorithm, including model architecture, network layers, activation functions, and optimization methods. It is supported by EPO case law (T 0161/1824 and T 1191/1925) and explicitly required by the Guidelines for AI Invention Patent Applications (Trial) issued by CNIPA in 2024, which require the disclosure of “model structure and functional module features.”26
-
2. Training data accessibility: This dimension examines whether the patent discloses the source, acquisition method, sample size, and representativeness of the training data. EPO decisions T 0161/18 and T 1191/19 both have held that the absence of dataset characteristics constitutes insufficient disclosure. Aboy et al. (2024) likewise emphasize that “At a minimum, details of the AI model architecture and at least a description of the training data should be provided.”27
-
3. Model reproducibility: This dimension assesses whether the invention provides sufficient details regarding model development, training procedures, and parameter configurations to enable a PHOSITA to reproduce the experimental process. Its importance is affirmed in EPO decisions T 0606/2128 and T 1526/20,29 and further reflected in the Xiao-i Robot v. Apple case decided by the Supreme People’s Court of China, together with related administrative invalidation proceedings.30
-
4. Result verifiability: This dimension considers whether the invention specifies evaluation methods, validation metrics or experimental results to substantiate model performance. Its significance has been underscored in EPO decision T 1191/19 and in the Supreme People’s Court of China’s ruling on the invalidation of a “control method and system for payment operations” patent, where purely functional descriptions without verifiable mechanisms were found insufficient to meet disclosure requirements.31
-
5. Mathematical support: This dimension focuses on whether the invention includes mathematical formulae, logical reasoning, or theoretical models to support its core decision-making processes or algorithmic design.Reference Ebrahim32 The Guidelines issued by CNIPA and the KIPO Examination Guide in the AI Field require applicants to disclose concrete mathematical elements such as loss functions and optimization algorithms, and have found that abstract expressions (e.g., “connection sparsity”) are insufficient without mathematical grounding.33 The JPO’s AI-related Examination Case Examples (March 2024), Case 39, also demonstrates that mathematical specification of loss functions is necessary to substantiate technical effects.34
Furthermore, to ensure consistent and operational evaluation across dimensions, each patent is scored using a simplified three-point scale from 0 to 2: A score of 0 indicates no disclosure; 1 indicates incomplete or vague disclosure; 2 indicates clear structure and complete content, constituting substantive technical explanation. Compared with more complex five- or seven-point scales, this “absent-ambiguous-sufficient” structure minimizes subjectivity and improves inter-scorer consistency.35
3.3. Structured Workflow for Patent Disclosure Scoring
Building on the disclosure evaluation framework, this study implements a structured workflow combining three components: (1) construction of a keyword dictionary, (2) NLP-based keyword matching and context extraction, and (3) expert assessment. This process has been applied to the empirical analysis of 865 medical AI patent specifications.
First, a keyword dictionary was developed to cover the five disclosure dimensions. It identified relevant terms, expression patterns, and structural features. The dictionary integrated three sources: legal norms, domain-specific knowledge, and corpus-based text mining. Specifically, (1) legal principles and representative case law defined the core disclosure elements under each dimension; (2) technical terms and standardized expressions were drawn from medical AI literature and industry reports to expand coverage;Reference He36 and (3) a term frequency–inverse document frequency (TF-IDF) method was used to extract high-frequency but distinctive terms from real-world medical AI patents.Reference Shin37 TF-IDF assigns higher weights to terms that occur frequently within a document but are less common across the entire corpus, thereby filtering out trivial words while highlighting domain-specific expressions. This improved both the semantic representation and the technical coverage of the keyword dictionary.
The dictionary adopts a hierarchical structure, with multiple subcategories under each disclosure dimension. Each subcategory contains keyword groups linked to regular expression rules, which are stored in a structured table with four fields: dimension, subcategory, keyword, and the corresponding regex pattern (see Table 3). The final version comprises five dimensions, 20 subcategories, and more than 170 keyword groups (see Supplementary Table S1). The dictionary may be further expanded, modified, and reused as an iterative and transferable framework for future analyses.
Sample Structure of the Keyword Dictionary

Note: “Pattern” refers to the regular expression applied to capture different textual variants of a keyword
Second, the study used Python to implement keyword matching and context extraction, converting unstructured patent texts into structured semantic data for expert assessment. Preprocessing ensured consistent formatting and standardized input. Based on the dictionary (Supplementary Table S1), the NLP process scanned each sentence in the patent texts using predefined regular expressions, and recorded the matched disclosure dimension, subcategory, keyword, and sentences. For example, the sentence “This invention uses a Transformer architecture for diagnostic classification” is matched to the keyword “Transformer,” mapped to the subcategory “model type,” and retained in full for expert review. The output is a structured table containing fields such as patent number, disclosure dimension, subcategory, matched keyword, matching pattern, and contextual sentence. A representative schema is shown in Table 4.
Representative Disclosure Elements Extracted from Medical AI Patents

Note: Matched keywords are emphasized in bold. Context sentences have been truncated for clarity and brevity.
Finally, an expert scoring mechanism was applied to complement automated extraction. Experts reviewed each match and its context using consistent scoring criteria. A double-blind scoring process was adopted: each patent was independently assessed by two experts in AI and patent analysis. Discrepancies were resolved by a third expert. Each dimension was scored on a 0-2 scale, with 0 for no disclosure, 1 for incomplete or vague disclosure, and 2 for sufficient and clear disclosure. Table 5 provides summarized example expressions corresponding to scores of 0, 1, and 2. These examples are provided to illustrate how the scoring rubric is applied in practice.
Scoring Standards and Example Expressions for Algorithm Transparency

As shown in Table 6, the results were organized into a structured scoring matrix. The full dataset is provided in Supplementary Table S2, which serves as the basis for subsequent statistical analysis.
Disclosure Evaluation Scores of Six Representative Medical AI Patents

The empirical workflow is as follows: [Input: raw patent text] → text preprocessing → keyword matching → context extraction → expert scoring → [Output: structured scoring matrix across five dimensions and three jurisdictions]. This pipeline enables the systematic transformation of semantic text into structured evaluation data, integrating legal norms, technical content, and NLP methodology into a unified disclosure assessment framework.
3.4. Empirical Results
Based on the workflow described above, this study systematically analyzed and visualized disclosure scores for 865 medical AI patents. The analysis reveals overall levels of disclosure, dimensional imbalances, and cross-jurisdictional differences, thereby providing the foundation for the subsequent gap analysis and institutional responses.
3.4.1. Overall Disclosure Levels and Dimensional Imbalances
Figure 1 illustrates the overall disclosure results of 865 medical AI patents across the five evaluation dimensions. Figure 1(a) presents the box plot and frequency distribution of total disclosure scores. The distribution approximates normality with a median score of 5.0, a mean of 5.1, and a mode of 6.0, reflecting a moderate overall level of disclosure. Figure 1(b) shows the score composition (0-2) and average score for each dimension. Algorithm transparency records the highest share of score 2 (63.4%) and the lowest share of score 0 (15.4%), with a mean score of 1.48. Training data accessibility shows the lowest share of score 2 (4.6%) and the lowest mean score (0.78). Model reproducibility (mean 0.97) and mathematical support (mean 0.89) also show high proportions of score 0, at 41.5% and 39.4% respectively. Result verifiability has a mean score of 0.97 and is dominated by score 1 (54.2%).
Statistical features of disclosure in medical AI patents (n = 865): (a) Box plot and frequency distribution of total disclosure scores; (b) Stacked bar chart showing the proportion of 0-2 scores for each of the five disclosure dimensions, overlaid with a line representing average scores; (c) Donut chart illustrating the distribution of overall disclosure levels across all patents, with a ranking of zero-score proportions by dimension; (d) Heatmap of co-occurrence patterns among zero-score disclosures across the five dimensions. Abbreviations: Algo = algorithm transparency; Data = training data accessibility; Repro = model reproducibility; Verify = result verifiability; Math = mathematical support.

Figure 1(c) shows the overall distribution of scores across all dimensions: 29.5% received score 0, 39.4% received score 1, and 31.2% received score 2. The inset ranks the proportions of score 0 by dimension, with model reproducibility (28.2%) and mathematical support (26.8%) being the highest, followed by training data accessibility (17.9%) and result verifiability (16.7%). Algorithm transparency records the lowest proportion of score 0 (10.4%). Figure 1(d) further reveals co-occurrence patterns of score 0 across dimensions. The strongest co-occurrence is between model reproducibility and mathematical support (208 cases), appearing most frequently as a simultaneous omission. Other frequent combinations include data accessibility with mathematical support (153), data accessibility with model reproducibility (145), and result verifiability with mathematical support (138). Overall, Figures 1(b–d) present mutually consistent patterns, as dimensions with higher proportions of low scores in Figure 1(b) also rank highest in zero-score prevalence in Figure 1(c) and feature most prominently in the co-occurrence patterns shown in Figure 1(d).
3.4.2. Cross-Jurisdictional Comparison
Figure 2 compares the disclosure scores of medical AI patents across the US, China, and the EU. Notably, as established in the dataset description, the EU data are provided for descriptive reference and exploratory purposes only. Figure 2(a) presents the average score for each dimension. Algorithm transparency shows the highest averages across all jurisdictions (EU 1.48, US 1.54, CN 1.46), while training data accessibility records the lowest (EU 0.90, US 0.94, CN 0.73). Figure 2(b) shows the radar chart of dimensional profiles. The EU and US exhibit similar patterns, with relatively higher averages in algorithm transparency and model reproducibility. China scores lower across most dimensions, particularly in training data accessibility and model reproducibility, highlighting jurisdictional differences in disclosure structures. Figure 2(c) illustrates the distribution of total disclosure scores by jurisdiction. The mean total disclosure scores are 6.2 for the EU, 5.9 for the US, and 4.8 for China.
Cross-jurisdictional comparison of disclosure scores in medical AI patents: (a) Average scores across five dimensions in the US, CN, and EU datasets; (b) Radar chart showing average dimensional scores of the three jurisdictions; (c) Box plots with frequency distributions of total scores; (d) Stacked bar charts displaying the proportion of patents with score 0-2 for each dimension, grouped by jurisdiction. Abbreviations: Algo = algorithm transparency; Data = training data accessibility; Repro = model reproducibility; Verify = result verifiability; Math = mathematical support.

Figure 2(d) compares the proportions of patents at score 0-2 for each dimension. Algorithm transparency is consistently the strongest dimension, with over 60% of patents at score 2 in all three datasets. By contrast, training data accessibility shows divergence: while most patents are at score 1 in all jurisdictions, China has almost no patents at score 2 (1.1%), compared with 14.1% in the US and an observed 12.9% in the EU. Model reproducibility also highlights jurisdictional differences: the EU (67.7%) and US (66.3%) have a majority at score 2, whereas China has nearly half of patents at score 0 (48.6%). Mathematical support shows a similar pattern. The proportions of patents assigned score 0 are 41.9% in China, 34.1% in the US, and 22.6% in the EU. For result verifiability, the proportions of score 2 are 29.0% in the EU, 24.9% in the US, and 19.6% in China.
3.4.3. Statistical Significance and Sensitivity Analysis
To assess the robustness of the overall findings, we conducted a two-step statistical validation focusing on the disclosure gap between China and the US.
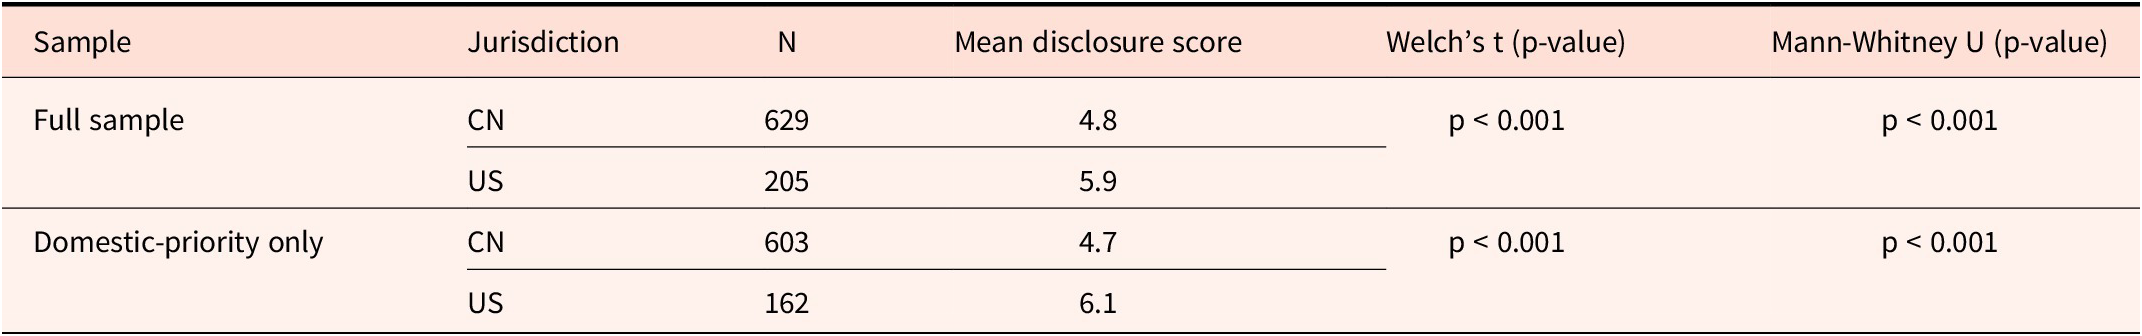
First, we assessed the statistical significance of jurisdictional differences within the full sample. As shown in Table 7, both Welch’s t-test (adjusting for unequal variances and sample sizes) and the non-parametric Mann-Whitney U test confirm that the disclosure gap between the US (mean = 5.9) and China (mean = 4.8) is statistically significant (p < 0.001).
Sensitivity Analysis: Full Sample vs. Domestic-Priority-Only Subsample (CN vs US)

Second, a sensitivity analysis was conducted using a domestic-priority-only subsample. This analysis examines whether the observed disclosure gap between China and the US is sensitive to cross-jurisdictional priority structures. Before constructing this subsample, the priority structure of the granted patent dataset was examined. A patent was classified as domestic-priority if its first priority country coincided with the granting jurisdiction, or if no foreign priority was claimed; all remaining patents were classified as foreign-priority. Overall, 768 patents (88.8%) were domestically originated, while 97 patents (11.2%) claimed foreign priority, with both the Chinese and the US samples dominated by domestic-priority patents (China: 603/629; the US: 162/205). Based on this classification, the sensitivity analysis restricted the comparison to the domestic-priority-only subsample (n = 768), thereby focusing on patents originally filed under each local legal regime and reducing potential cross-jurisdictional priority effects. As reported in Table 7, the difference in average disclosure scores persists in this restricted sample, with mean scores of 4.7 for China and 6.1 for the US, and the mean gap increasing from 1.1 points in the full sample to 1.4 points in the domestic-priority-only subsample.
Across both the full sample and the domestic-priority-only subsample, the disclosure gap between China and the US remains statistically significant (p < 0.001). This consistency across alternative sample specifications indicates that the observed difference is robust to variations in priority structure and sample construction.
3.4.4. Within-Family Comparison as an Internal Control Across Jurisdictions
A within-family comparison was conducted using tri-jurisdictional patent families as an internal control to assess cross-jurisdictional consistency for the same invention. From the dataset of 865 granted medical AI patents, 27 complete tri-jurisdictional patent families (81 patents) were identified, each of which was granted in the US, China, and the EU. As each family corresponds to a single invention, this design allows comparisons across jurisdictions while holding the underlying technical subject matter constant.
All patents within these families were evaluated independently using the same five-dimensional disclosure scoring framework applied in the main analysis. The results indicate a high degree of within-family consistency in disclosure scores across jurisdictions, with no systematic score differences observed among the US, China, and the EU filings within the same family.
A manual qualitative examination of the patent texts further supports this finding. The technical descriptions are substantially identical (near-mirror images) across jurisdictions, while limited differences are observed in claim phrasing and other drafting-related features, including translation and formatting.
Overall, the within-family comparison shows that patent documents corresponding to the same invention exhibit a high level of consistency across jurisdictions. This finding supports the legitimacy of simple patent family consolidation as a methodological choice in the construction of the main dataset.
4. Gap Analysis: Structure, Causes, and Risks
4.1. Structural Gaps in Patent Disclosure
Building on the empirical findings above, this section identifies three major types of structural gaps in current medical AI patent disclosures: overall disclosure insufficiency, dimensional imbalance, and jurisdictional disparities.
4.1.1. Overall Insufficiency
The overall distribution of disclosure scores suggests that insufficiency is a defining feature of medical AI patents. As shown in Figure 1(a), the average total score of the 865 patents was 5.1, close to the median of 5.0. The distribution is mildly left-skewed, with most patents clustered in the range of 3–7 points. This indicates that only a limited number of patents provide comprehensive technical information, while the majority disclose at a moderate level.
Figure 1(c) further indicates that only 31.2% of items achieved score 2, whereas 68.8% remained at score 0 or 1. In other words, nearly seven out of ten disclosure items were either absent or incomplete. The largest share falls at score 1 (39.4%), reflecting a tendency towards partial disclosure. Applicants often provide fragments of technical information, such as naming a model type or noting the use of training data, without including the detailed parameters, datasets, or validation procedures needed to establish a complete disclosure chain.
In summary, these results show that the overall level of sufficiency in medical AI patent disclosure is structurally weak. While a minority of patents reach the standard of complete disclosure, the majority fall into minimal or incomplete categories, demonstrating a systemic pattern of limited disclosure across the dataset.
4.1.2. Dimensional Imbalance
The distribution of scores across the five dimensions demonstrates a notable imbalance. Disclosures are concentrated in algorithm transparency, where structural descriptions of models are relatively common, while other dimensions remain less detailed. Training data accessibility is the least developed dimension, with datasets rarely identified in detail. Model reproducibility and mathematical support also show systematic gaps, as information on parameters, hyperparameters, and mathematical formulations is frequently omitted. Result verifiability occupies an intermediate position, dominated by partial disclosures rather than complete validation processes.
These limitations are reinforced by co-occurrence patterns of nondisclosure. As shown in Figure 1(d), omissions cluster in the same dimensions, most notably in the combination of reproducibility and mathematical support, followed by data-related categories. This suggests that insufficiencies are not isolated but structurally aligned, resulting in a lack of certain technical information needed for reliable implementation.
4.1.3. Jurisdictional Disparities
The cross-jurisdictional comparison reveals that disclosure practices are not uniform across regions but stratified by jurisdiction. As established in the dataset description, our primary jurisdictional findings rely on the comparison between the US (N = 205) and China (N = 629), while the EU data (N = 31) serve as a descriptive reference. Statistical testing confirms a significant difference in disclosure sufficiency between the US and Chinese samples (p < 0.001). The US sample recorded a mean score of 5.9, whereas the Chinese sample recorded 4.8. The exploratory observation of the EU subset showed a numerical mean of 6.2.
These variations are further reflected at the dimensional level. Training data accessibility is consistently the least developed dimension across jurisdictions, but the gap is notable in the Chinese sample, where 1.1% of patents achieved a score of 2, compared with 14.1% in the US. Model reproducibility also showed jurisdictional differences: the US sample had a majority at score 2 (66.3%), whereas nearly half of the patents in the Chinese sample remained at score 0 (48.6%). By contrast, algorithm transparency showed less cross-regional variation, with over 60% of patents achieving score 2 in all three datasets.
This uneven landscape suggests that disclosure insufficiency is not only structural at the dimensional level but also jurisdictional. While higher levels of disclosure sufficiency were observed in the US sample and the EU exploratory subset, the Chinese sample appears to cluster at lower levels in specific categories. These patterns highlight the variation in technical transparency across the different jurisdictions included in this study.
4.2. Institutional, Strategic, and Technical Factors of Insufficient Disclosure
There exists a noticeable structural gap between the actual state of disclosure in medical AI patents and the normative expectations established by law. Existing evidence suggests that this gap is unlikely to be purely incidental, but rather reflects the combined effects of multiple systemic factors.
4.2.1. Structural Drivers of Insufficiency
Certain institutional factors may influence the alignment between legal standards and the actual disclosure levels in granted patents. Academic literature suggests that, in administrative practice, sufficiency requirements can sometimes receive less focus compared to novelty and inventive step.Reference Abolkheir38 For instance, empirical data indicate that rejections based on 35 U.S.C. § 112 (insufficiency of disclosure) constitute less than 5% of all rejections, whereas those based on novelty or obviousness account for 50–80%.Reference Tu and Holman39 Furthermore, institutional time constraints such as the limited average time— approximately 20 hours — allocated for the examination of each application at the USPTO may contribute to the gap between formal legal requirements and the technical transparency of finalized specifications.Reference Frakes and Wasserman40
Commercial incentives also play an important role. Applicants often pursue what has been described as a “minimal compliant disclosure” strategy.Reference Datar41 Patent texts are drafted in functional terms — for instance, stating that “a neural network generates diagnostic predictions” without specifying architecture, parameters, or training processes. These practices serve two strategic aims. First, ambiguity in claim drafting may create so-called “patent traps,” which raise the likelihood of accidental infringement while simultaneously deterring free-riders.Reference Bian42 Second, the construction of “patent thickets,” encircling core technologies with overlapping claims, has been observed in some contexts.Reference Cho and Pei43 While these strategies could serve to broaden claim scope and protect commercially sensitive information, they simultaneously reduce the informational value of patent disclosures for third parties.Reference Zhizai and Xuezhong44
The technical characteristics of AI pose additional challenges to disclosure insufficiency. Deep neural networks, for example, often exhibit non-linear behaviors and distributed weight patterns, which obscure decision pathways and hinder precise technical disclosure.Reference Marey45 Training datasets are commonly subject to privacy and ethical restrictions,Reference Li and Cong46 preventing their open disclosure. Reproducibility is also contingent on contextual factors such as hardware, software libraries, and deployment environments, which rarely appear in patent texts.Reference Desai47 In medical AI, where patents involve sensitive data and high-risk applications, applicants are especially likely to retain model weights and datasets as trade secrets, further constraining the scope of implementable disclosure.Reference Sim48
A further barrier arises from the linguistic nature of patent documents themselves. The patent specification is a hybrid genre of law and technology, shaped by tensions between legal accuracy and communicative clarity. Applicants, typically through patent attorneys, do not primarily draft patent texts for knowledge dissemination, but rather to maximize claim breadth while meeting formal legal standards. This contrasts with academic writing, which prioritizes transparency and openness. Empirical research has shown that patent texts are more likely than journal articles to employ lengthy, complex sentences and legalistic phrasing, making them considerably less readable.Reference Xu49 Moreover, tacit technical knowledge is often difficult to codify, meaning that even absent deliberate evasion, full disclosure may not be practically achievable. Linguistic analysis also indicates that applicants frequently rely on vague formulations, such as “preferred,” “selectively,” or “may,” to comply formally with disclosure rules while avoiding the revelation of sensitive know-how.Reference Arinas50 In this respect, language itself may function as a structural constraint on effective disclosure, contributing to what has been described as a disclosure paradox.
4.2.2. Explanations for Dimensional Imbalance
The unevenness across disclosure dimensions is associated with selective enforcement, strategic behavior, and practical barriers. Administrative scrutiny by patent offices tends to be dimension-specific in certain contexts. Examiners tend to focus on familiar aspects, such as system architecture or input-output descriptions, while paying less attention to mathematical formulations or dataset characteristics. Although the EPO requires disclosure of relevant data features when technical effects depend on them (e.g., EPO Guidelines, G-II 3.3.1), rejections on this ground have been reported to be relatively uncommon.51 Such variation in scrutiny can create incentives for applicants to concentrate on “safe” dimensions while neglecting others.
Applicants’ disclosure strategies might further influence these dimensional differences. There is an observable tendency to disclose lower-risk elements, such as generic algorithm labels (“machine learning,” “convolutional network”), but often omit parameter settings, dataset sources, or validation methods.Reference Liang52 The outcome is a skewed disclosure profile: algorithm transparency is addressed superficially, whereas training data accessibility and mathematical support are systematically underrepresented. The empirical results, including the co-occurrence of zero scores across multiple dimensions, are consistent with this pattern.
Practical and ethical factors also influence the unevenness across dimensions. Medical datasets are tightly regulated under laws such as the General Data Protection Regulation (GDPR) in Europe and the Health Insurance Portability and Accountability Act (HIPAA) in the US. Reproducibility often depends on tacit knowledge, specialized software, or deployment contexts that are difficult to codify in patents.Reference Polanyi53 Mathematical details are frequently withheld as proprietary know-how. These factors help to explain why certain dimensions consistently lag behind others, producing the structural asymmetry evident in Figure 2.
4.2.3. Factors Associated with Cross-Jurisdictional Divergence
The variations in disclosure sufficiency observed across jurisdictions appear to reflect divergent institutional traditions and regulatory environments. At the institutional level, patent offices embody distinct interpretative cultures regarding Article 83 EPC, § 112 U.S.C., and their Chinese counterparts. In the European context, the EPO is often characterized in the case law and secondary literature as adopting a comparatively demanding doctrinal approach to sufficiency, particularly where claimed technical effects depend on training data or algorithmic features. Decisions of the Boards of Appeal (e.g., T 0161/18, T 1539/20, T 0606/21, T 1526/20, T 1191/19) emphasize that such effects must be substantiated by an adequate disclosure of relevant data characteristics. This jurisprudence contributes to a relatively high doctrinal baseline for sufficiency, even though gaps between formal standards and examination practice may still arise. By contrast, USPTO practice has historically subordinated disclosure assessment to novelty and inventive step, resulting in a lower rate of § 112 rejections and permitting relatively broader reliance on functional claiming.54 In China, disclosure guidelines have been recently updated, but enforcement capacity remains limited due to high application volumes and examiners’ constrained technical expertise, which may limit the depth of scrutiny applied to disclosure elements in examination practice.55
Furthermore, broader regulatory and market contexts amplify these divergences. Data governance regimes, for example, affect the feasibility of training data disclosure. In the European Union, the GDPR classifies health and genetic data as “special categories,” subject to explicit safeguards, and requires data protection impact assessments for large-scale health data processing.56 This framework incentivizes firms to adopt a cautious stance when handling medical datasets in patent documents — while in the US, the sectoral approach allows relatively greater flexibility. The HIPAA Privacy Rule permits the use and disclosure of de-identified health data, thereby enabling researchers and firms to reference datasets without triggering full privacy obligations.57 In China, statutory data governance rules create systematic barriers to the circulation and disclosure of training datasets in patent documents. The Cybersecurity Law requires that personal information and important data collected or generated by critical information infrastructure operators (CIIOs) be stored domestically, and outbound transfers are subject to security assessments.58 The Data Security Law establishes a classification and graded protection regime for “important data,” and further mandates outbound transfer controls, applying the Cybersecurity Law to CIIOs while requiring other data processors to follow rules issued by the Cyberspace Administration of China (CAC).59 The Personal Information Protection Law supplements this framework by requiring outbound transfers of personal information to undergo security assessments, certification, standard contracts, or other legally prescribed conditions, and imposes a general localization requirement on both CIIOs and processors that handle personal information in volumes above thresholds set by the CAC.60 Collectively, these provisions restrict the cross-border flow of medical datasets, resulting in systematic under-disclosure in patent filings.
4.3. Risks of Insufficient Disclosure
The deficiencies identified above are not stylistic accidents but structural risks that compromise both the legal and functional foundations of the patent system in the medical AI domain. These risks unfold at multiple and interconnected levels.
One key concern lies in legal validity. Patent law conditions the grant of exclusivity on enabling disclosure, yet many medical AI patents fall short of this threshold. As shown in Figure 2, a large proportion of specifications disclose only partial elements, such as generic references to “machine learning models,” without describing architecture, parameters, or datasets. This omission leaves patents vulnerable to invalidation. The EPO’s decision T 0161/18 exemplifies this risk: the application claimed a neural network for predicting cardiac output but omitted the training data and network architecture, rendering the invention non-reproducible and ultimately refused for lack of enablement. Similar concerns have also been discussed in the US context. Existing empirical study reported that fewer than 5% of USPTO rejections explicitly rely on insufficiency of disclosure, compared with substantially higher rejection rates — often ranging from 50% to 80% — for lack of novelty or obviousness.61 These observations suggest that patents containing limited or incomplete technical disclosure may still reach the granted stage. As a result, questions concerning enablement and reproducibility may be deferred from examination to subsequent validity challenges, rather than being resolved ex ante through the disclosure requirements of the patent system.
Another dimension of risk concerns reproducibility and knowledge transfer. Even where some elements are disclosed, omissions in critical dimensions block downstream implementation. Aboy et al. (2024) reported that fewer than one-third of AI-related patents include evaluation methods, only one-quarter provide mathematical reasoning, and just 2% disclose code lists, figures far below scientific standards of reproducibility.62 These findings align with other studies showing that AI reproducibility depends heavily on context-specific elements, including software libraries and deployment settings.63 Selective disclosure thus mirrors the dimensional gaps identified in the paper and prevents patents from serving as reliable channels of technological diffusion. In decision T 0606/21, the EPO refused a patent application for a trajectory prediction model because the specification did not explain how the neural network could generate a reliable similarity score without a defined trajectory or with incomplete input data. This case illustrates how the absence of clear evaluation mechanisms can compromise both reproducibility and legal enforceability.
Beyond individual patents, insufficient disclosure also generates systemic market-level risks. Divergent enforcement cultures across jurisdictions allow applicants to exploit leniency: minimal disclosure may be tolerated in China or the US but rejected in Europe.64 This divergence fragments the global patent landscape, reducing the citation and integration of weakly disclosed patents while fostering informational asymmetry.65 Over time, such practices contribute to the formation of patent thickets, which raise entry costs and distort competition.66 Strategic disclosure behavior further accelerates the accumulation of formally valid but substantively hollow patents. The cumulative effect is an erosion of the public value of the patent system, constraining system-level innovation in medical AI.
In summary, insufficient disclosure undermines the patent regime across three interrelated fronts: legal legitimacy, technical reproducibility, and industrial relevance. Unless institutional mechanisms reinforce sufficiency standards, the patent system risks devolving into a repository of hollow claims, impeding rather than enabling technological progress.
5. Institutional Responses: Enhancing Disclosure in Medical AI Patents
Building on the empirical findings, this section proposes targeted institutional measures to improve the sufficiency of disclosure in medical AI patents.
5.1. Reinforcing Examination to Address Overall Insufficiency
Examination practice has historically prioritized novelty and inventive step, while sufficiency has received comparatively limited scrutiny.67 To address this problem at its root, examination capacity must be reinforced. One avenue is targeted examiner training in AI-specific domains such as model architectures, training processes, and dataset handling. Enhancing technical literacy would enable examiners to detect disclosure gaps and resist superficial compliance. A further measure is to strengthen enablement review: applications lacking model parameters, training data, or validation methods should trigger formal objections, preventing the grant of patents that are legally valid in form but substantively empty. Finally, particularly complex cases could be referred to an “AI expert consultation pool” composed of external specialists, similar to the technical expert involvement used in biotechnology and pharmaceuticals.68 Compared with post-grant litigation or invalidation, such ex ante scrutiny is more cost-effective and preserves the integrity of the system by filtering out hollow patents before they enter the legal order.
5.2. Targeting Dimensional Imbalance with Checklists and NLP Tools
The second key deficiency lies in the systematic unevenness across disclosure dimensions. The five-dimensional scoring revealed that training data accessibility and mathematical support are consistently underrepresented, while algorithm transparency is often limited to superficial labelling. Such omissions undermine reproducibility and have already led to enforceability failures, as illustrated by the EPO decision T 0606/21, where a trajectory prediction model was refused for lacking evaluation mechanisms.
To mitigate these weaknesses, disclosure standards must be operationalized through structured tools. A “Medical AI Disclosure Checklist,”69 grounded in the five-dimensional framework, could specify the key elements expected in specifications: model type and architecture, dataset characteristics, training parameters, validation metrics, and mathematical components. Rather than imposing rigid requirements, the checklist would serve as an examination aid, increasing clarity and reducing discretion in sufficiency review. It could also function as a self-assessment tool for applicants, encouraging them to check completeness in advance and thereby improving disclosure across all dimensions. This approach is analogous to the biotechnology field, where deposit mechanisms such as the Budapest Treaty have institutionalized disclosure expectations.70
At the same time, NLP can provide automated support. Existing research demonstrates the feasibility of AI in patent retrieval,Reference Shalaby and Zadrozny71 classification,Reference Lee and Hsiang72 and trend analysis.Reference Yun73 Building on such methods, an automated “disclosure completeness report” could flag omissions by mapping text against the checklist. This study itself demonstrated the feasibility of NLP-assisted scoring, showing how unstructured text can be transformed into evaluative indicators. Incorporating such tools into examination practice would help counteract strategic opacity and linguistic ambiguity, enabling examiners to detect superficial disclosures and applicants to self-assess their filings in advance. In this way, dimensional imbalances can be progressively corrected, enhancing reproducibility and knowledge diffusion.
5.3. Harmonizing Practices and Incentivizing Transparency Across Jurisdictions
The third deficiency concerns cross-jurisdictional divergences. Institutional responses might combine harmonization with positive incentives. International cooperation could promote convergence towards higher sufficiency standards, with the EPO’s disclosure requirements offering a useful benchmark. To address the technical opacity of AI, a deposit mechanism for datasets and model parameters could be introduced, analogous to biotechnology’s deposit systems.74 Such repositories would allow sensitive materials to be stored securely while ensuring that patents remain reproducible in practice.
At the same time, disclosure quality can be improved through incentives. Fee reductions, accelerated examination, or formal recognition could be granted to applicants who provide exemplary disclosures. More ambitiously, continued transparency could be rewarded after grant — for example, by offering annuity fee discounts for patentees who submit updated datasets or model versions. In this way, applicants would be encouraged to move from passive compliance to proactive transparency, counteracting the risks of strategic withholding and reducing cross-jurisdictional disparities.
6. Conclusion
This study set out to assess whether medical AI patents provide sufficient disclosure across the US, China, and the EU. Based on a five-dimensional scoring framework applied to 865 granted patents, the results show structural insufficiency, with persistent gaps in technical detail, imbalances across dimensions, and jurisdictional divergences. Training data accessibility and mathematical support are consistently weak, while algorithm transparency performs comparatively better, with over 60% of patents reaching the high score. These weaknesses appear to be systemic and can be associated with under-enforcement, strategic behavior by applicants, technical opacity, and linguistic ambiguity in patent drafting, and they pose challenges to legal validity, reproducibility, and knowledge transfer. By combining doctrinal analysis with NLP and expert scoring, the study contributes systematic empirical evidence and introduces a transferable methodological framework. It further proposes improvements including stronger examination capacity, disclosure checklists, NLP review tools, and deposit mechanisms for data and models, which aims to promote a more transparent, reproducible, and socially valuable patent system aligned with responsible AI innovation.
Supplementary Material
The supplementary material for this article can be found at http://doi.org/10.1017/jme.2026.10256.
Acknowledgements
Ruyi Xiao acknowledges support from the 2024 Innovative Talents International Cooperation Training Program (Project No. 202407070131) of the China Scholarship Council.
Disclosures
The authors have nothing to disclose.