1. Introduction
The declining trend of mortality rates is generally observed in many developed countries. It is widely acknowledged among actuaries and demographers that dynamic mortality models are required to account for the uncertainty associated with the projection of mortality for different generations. From governments who are responsible for pension policy design to insurers who offer retirement income products, it is important to consider and incorporate different factors that would impact the projections of mortality rates. Arguably one of the most discussed and important factors is the so-called cohort effect, that is, the effect of year-of-birth on mortality rates.
It is perhaps not surprising that people born in different years or generations would undergo different mortality experiences. Willets (Reference Willets2004) finds evidence for the existence of cohort trends in the population of England and Wales. Murphy (Reference Murphy2009) discusses the “golden generations” of the British population who were born in early 1930s and have experienced exceptionally rapid improvements in mortality rates. Willets (Reference Willets2004) and Murphy (Reference Murphy2009, Reference Murphy2010) provide detailed discussions on cohort effects including their identification from mortality data and competing explanations. The aforementioned studies are not model based however, but rely on empirical data analysis and qualitative analysis such as descriptive and graphical representations to conclude the significance of cohort effects on population mortality.
For actuarial applications such as longevity risk management (Cairns et al., Reference Cairns, Blake and Dowd2008; Barrieu et al., Reference Barrieu, Bensusan, El Karoui, Hillairet, Loisel, Ravanelli and Salhi2012), one is often interested in building dynamic mortality models with stochastic cohort features. Renshaw and Haberman (Reference Renshaw and Haberman2006) extend the well-known Lee–Carter mortality model (Lee and Carter, Reference Lee and Carter1992) by introducing an age-modulated cohort effect. In a similar way, the Cairns–Blake–Dowd mortality model introduced in Cairns et al. (Reference Cairns, Blake and Dowd2006) is extended to incorporate cohort factors in Cairns et al. (Reference Cairns, Blake, Dowd, Coughlan, Epstein, Ong and Balevich2009). In contrast to studying cohort effects via qualitative arguments, mortality models offer a quantitative and statistical approach to identify and analyse cohort patterns exhibited in mortality data. Note that when using cohort models, the cohort patterns observed can be affected by the choice of identifiability constraints.
There are two main approaches for estimating mortality models. The first approach relies on least-squares estimation based on singular value decomposition (SVD), pioneered by Lee and Carter (Reference Lee and Carter1992) in the mortality context, see also Renshaw and Haberman (Reference Renshaw and Haberman2003), Yang et al. (Reference Yang, Yue and Huang2010) and Shang et al. (Reference Shang, Booth and Hyndman2011). The second approach employs regression-based methods to calibrate mortality models (Brouhns et al., Reference Brouhns, Denuit and Vermunt2002). For some recent studies based on this approach, see O’Hare and Li (Reference O’Hare and Li2012), van Berkum et al. (Reference van Berkum, Antonio and Vellekoop2016) and Enchev et al. (Reference Enchev, Kleinow and Cairns2016). The recent paper Currie (Reference Currie2016) provides a comprehensive summary on mortality modelling based on the generalised linear modelling (GLM) framework. In particular, the paper points out that there are convergence and robustness problems, caused by identifiability issues, that need to be resolved for models with cohort features.
In this paper, we approach the problems of estimating and forecasting mortality with cohort features via state-space methodology, which is a natural extension of the framework recently described in Fung et al. (Reference Fung, Peters and Shevchenko2017) to the cohort model formulation. The main contribution of this paper is to demonstrate how mortality models with cohort effects can be formulated, estimated and forecasted under a Bayesian state-space framework. Other works using the state-space approach for mortality modelling include Pedroza (Reference Pedroza2006), De Jong and Tickle (Reference De Jong and Tickle2006), Kogure et al. (Reference Kogure, Kitsukawa and Kurachi2009) and Liu and Li (Reference Liu and Li2017). In our view, the state-space approach has three major advantages.
First, the ability of modelling, estimating and forecasting mortality under a unified framework can avoid the potential pitfalls of the two-step estimation procedure typically found in the literature. As discussed in details in Fung et al. (Reference Fung, Peters and Shevchenko2017), a common practice of estimating mortality models consists of two steps:
Step 1: Obtain estimates of parameters including period (cohort) effects; the period (cohort) effects are treated as parameters without the assumptions of their dynamics.
Step 2: Assume a time series model, for example ARIMA models, for the period (cohort) effects; parameters of the time series model are then estimated by fitting the model to period (cohort) effects obtained from Step 1.
In a recent study in Leng and Peng (Reference Leng and Peng2016), the authors point out that the least-squares method for the two-step estimation approach utilised in Lee and Carter (Reference Lee and Carter1992) will in general lead to inconsistent estimators unless restrictions are imposed on the possible range of time series models for the underlying dynamics. One may argue that it is more satisfactory to perform estimation and forecasting under a single universal framework, and one such example is the state-space methodology which is well-established in the statistics community.
Second, the ability to provide confidence or credible intervals for the estimated parameters, and hence the quantification of parameter risk in mortality projections, is a significant issue in valuing liabilities in life insurance portfolio and pension schemes. The impact of parameter uncertainty on forecasting mortality rates is documented in Czado et al. (Reference Czado, Delwarde and Denuit2005), Koissi et al. (Reference Koissi, Shapiro and Hognas2006) and Kleinow and Richards (Reference Kleinow and Richards2016). A Bayesian approach to mortality modelling via credit risk plus methodology is considered in Shevchenko et al. (Reference Shevchenko, Hirz and Schmock2015) and Hirz et al. (2017 Reference Hirz, Schmock and Shevchenkoa , 2017 Reference Hirz, Schmock and Shevchenkob ). The rather short time series data used for calibration purpose typically assumed in the literatureFootnote 1 further enforce the need to account for parameter uncertainty where confidence intervals are required. The state-space approach offers a particularly rich and flexible framework for Bayesian and frequentist estimation, where a range of techniques such as filtering, sequential Monte Carlo and Markov chain Monte Carlo (MCMC) methods can be employed (Fung et al., Reference Fung, Peters and Shevchenko2017).
Third, the state-space approach allows for a wide range of mortality models to be considered while estimation and forecasting can still be performed efficiently. Fung et al. (Reference Fung, Peters and Shevchenko2017) show that a majority of the popular mortality models can be cast in state-space formulation; in addition, stochastic volatility features can be introduced to dynamic mortality models where numerical filtering techniques are employed for model estimation. Applications of state-space formulation of mortality models in pricing and risk management of longevity-linked products are, for example, studied in Fung et al. (Reference Fung, Peters and Shevchenko2015), Kogure and Kurachi (Reference Kogure and Kurachi2010) and Liu and Li (Reference Liu and Li2016, Reference Liu and Li2017).
Despite the advantages of the state-space method, the approach is still under explored in our view. A key element that is as yet missing from this literature, that we aim to address in this paper, is the consideration of cohort effects in a state-space modelling setting. Given the fact that cohort effects are known to be present in certain countries, the possibility of exploiting cohort features under a state-space framework will undoubtedly enhance an actuary’s ability to analyse mortality data. The importance of incorporating cohort effects in state-space setting is also emphasised in Liu and Li, where the authors “acknowledge that cohort effects are significant in certain populations, and that it is not trivial to incorporate cohort effects in a state-space representation in which the vector of hidden states evolve over time rather than year of birth” (Reference Liu and Li2017: 66). Therefore, in this paper we focus on addressing this missing piece of model formulation.
The paper is organised as follows. Section 2 provides an overview of different approaches to mortality modelling, leading to the introduction of the state-space methodology. State-space formulation of cohort models is discussed in details in section 3. In section 4, we develop Bayesian inference for cohort models under the state-space framework based on efficient MCMC sampling. Empirical studies for male and female population data from various countries using the state-space cohort models are conducted in section 5. Finally, section 6 concludes.
2. State-Space Approach to Mortality Modelling
In this section we provide an overview of different approaches to modelling mortality as well as their estimation methodologies. Our focus will be on single population mortality modelling, however the essential elements of the approaches and methods discussed can be carried over to multi-population settings, see for example Enchev et al. (Reference Enchev, Kleinow and Cairns2016).
2.1. Stochastic mortality models
The definitions here follow Dowd et al. (Reference Dowd, Cairns, Blake, Coughlan, Epstein and Khalaf-Allah2010). We use q x,t to denote the true mortality rate, that is, the probability of death between time t and t+1 for individuals aged x at time t. The true death rate, denoted by m x,t , is related to the true mortality rate via
 $$q_{{x,t}} {\equals}1{\minus}e^{{{\minus}m_{{x,t}} }} .$$
One can use the observed number of deaths D
xt
and initial exposures
 $E_{{xt}}^{i} $
dataFootnote
2
to obtain the crude mortality rate as
 $\tilde{q}_{{x,t}} {\equals}D_{{xt}} /E_{{xt}}^{i} $
, which is a crude estimate of q
x,t
. Similarly, the crude death rate
 $\tilde{m}_{{x,t}} $
is defined as the ratio of the observed number of deaths D
xt
to the average population size E
xt
, known as central exposures, ages x last birthday during year t
Footnote
3
.
The work of Lee and Carter (Reference Lee and Carter1992) introduced the Lee–Carter (LC) model
 $$\ln \tilde{m}_{{x,t}} {\equals}\alpha _{x} {\plus}\beta _{x} \kappa _{t} {\plus}{\epsilon}_{{x,t}} ,$$
where the terms α
x
and β
x
κ
t
aim to capture the age and period effects, respectively. Since they proposed to use SVD to calibrate the model to mortality data, the noise term
 $${\epsilon}_{{x,t}} $$
is included in addition to the age and period effects. Due to identification issue, it is typical to impose the following constraints
 $$\mathop \sum\limits_{x{\equals}x_{1} }^{x_{p} } \beta _{x} {\equals}1,\,\mathop \sum\limits_{t{\equals}t_{1} }^{t_{n} } {\rm \ztbnd }\kappa _{t} {\equals}0,$$
so that the LC model becomes identifiable. Here p and n represent the number of ages and years, respectively. Note that the crude death rate
 $\tilde{m}_{{x,t}} $
, which is obtained directly using mortality data, is used to obtain estimates of the parameters.
In contrast to the SVD approach where the models are fitted to crude death rates, Brouhns et al. (Reference Brouhns, Denuit and Vermunt2002) considers an alternative approach where mortality models are fitted to the number of deaths instead. Using the number of observed deaths D xt and central exposures E xt , the model proposed by Lee and Carter can be reconsidered as
 $$D_{{xt}} \sim {\rm Poisson}\,(E_{{xt}} \,m_{{x,t}} ),\,{\rm where}\,m_{{x,t}} {\equals}e^{{\alpha _{x} {\plus}\beta _{x} \kappa _{t} }} .$$
In this approach, the number of deaths plays an important role in calibrating the model and consequently the additive error structure in (2) is replaced by the Poisson error structure. Also notice that confusion may arise if one does not distinguish the true and crude death rate, for example it does not make sense to use
 $\tilde{m}_{{x,t}} $
in (4).
Besides having a different statistical assumption on the error structure, the Poisson regression setting, which belongs to the class of models known as generalised linear/non-linear models, has the advantage that the cohort factor can be incorporated while estimation can still be performed without extra difficulty in contrast to the SVD approach. The LC model in the Poisson setup can be enriched by adding a cohort factor γ t−x , where t−x refers to the year-of-birth, as follows:
 $$D_{{xt}} \sim{\rm Poisson}\,(E_{{xt}} \,m_{{x,t}} ),\,{\rm where}\,m_{{x,t}} {\equals}e^{{\alpha _{x} {\plus}\beta _{x} \kappa _{t} {\plus}\beta _{x}^{\gamma } \gamma _{{t{\minus}x}} }} .$$
which was proposed in Renshaw and Haberman (Reference Renshaw and Haberman2006). As t and x take values in {t 1, … , t n } and {x 1, … , x p }, respectively, the cohort index t−x takes values in {t 1−x p , … , t n −x 1}. The dimension of the cohort index is thus n+p−1 which is different to the dimension of the period index n.
The Renshaw–Haberman model (5) is suffering from an identification problem since the model is invariant to the following transformation
 $$\left( {\alpha _{x} ,\beta _{x} ,\kappa _{t} ,\beta _{x}^{\gamma } ,\gamma _{{t{\minus}x}} } \right)\to\left( {\alpha _{x} {\plus}c_{1} \beta _{x} {\plus}c_{2} \beta _{x}^{\gamma } ,{1 \over {c_{3} }}\beta _{x} ,c_{3} \left( {\kappa _{t} {\minus}c_{1} } \right),{1 \over {c_{4} }}\beta _{x}^{\gamma } ,c_{4} \left( {\gamma _{{t{\minus}x}} {\minus}c_{2} } \right)} \right),$$
where c 3≠0 and c 4≠0. One can impose the following parameter constraints
 $$\mathop \sum\limits_{x{\equals}x_{1} }^{x_{p} } \beta _{x} {\equals}1,\,\mathop \sum\limits_{x{\equals}x_{1} }^{x_{p} } \beta _{x}^{\gamma } {\equals}1,\,\mathop \sum\limits_{t{\equals}t_{1} }^{t_{n} } \kappa _{t} {\equals}0,\mathop \sum\limits_{c{\equals}t_{1} {\minus}x_{p} }^{t_{n} {\minus}x_{1} } \gamma _{c} {\equals}0,$$
to ensure a unique model structure is identified. Hunt and Villegas (Reference Hunt and Villegas2015) and Currie (Reference Currie2016) provide further discussions on the identifiability issues for cohort models.
Under the Lee–Carter original approach, one might consider modelling the crude death rate with cohort effects as follows:
 $${\rm ln}\,\tilde{m}_{{x,t}} {\equals}\alpha _{x} {\plus}\beta _{x} \kappa _{t} {\plus}\beta _{x}^{\gamma } \gamma _{{t{\minus}x}} {\plus}{\epsilon}_{{x,t}} .$$
However the dimension of the cohort index would cause difficulty for the SVD estimation approach. One of the goals of the present paper is to show that model (8) can be successfully estimated by considering it as a state-space model instead.
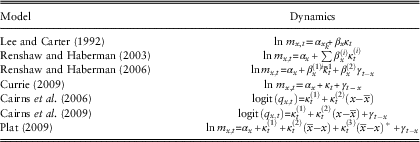
Examples of popular mortality models are provided in Table 1. Renshaw and Haberman (Reference Renshaw and Haberman2003) consider a multi-period
 $\left( {\mathop{\sum}\nolimits_{i{\equals}1}^k {\beta _{x}^{{(i)}} \kappa _{t}^{{(i)}} } } \right)$
extension of the LC model. Renshaw and Haberman (Reference Renshaw and Haberman2006) introduce a cohort factor (γ
t−x
) to LC model. A simplified version of the model in Renshaw and Haberman (Reference Renshaw and Haberman2006) is studied in Currie (Reference Currie2009). Cairns et al. (Reference Cairns, Blake and Dowd2006) propose the so-called Cairns-Blake-Dowd (CBD) model to model
 ${\rm logit}(q_{{x,t}} )\,\colon\!{\equals}{\rm ln}\left( {q_{{x,t}} /(1{\minus}q_{{x,t}} )} \right)$
, where
 $\bar{x}$
is the average age of the sample range, that is
 $\bar{x}{\equals}{1 \over p}\mathop{\sum}\nolimits_{i{\equals}1}^p {x_{i} } $
designed to capture the mature-age mortality dynamics. Cairns et al. (Reference Cairns, Blake, Dowd, Coughlan, Epstein, Ong and Balevich2009) extend the CBD model by incorporating a cohort factor. Identification constraints for the models in Table 1 are discussed in Villegas et al. (Reference Villegas, Millossovich and Kaishev2015).
Remark 2.1 An alternative approach to modelling cohort mortality is to consider the continuous-time modelling of the mortality intensity (force of mortality) μ x+t,t , with x and t taking continuous values. It is of particular relevance for financial and actuarial applications as pricing formulas can be derived and expressed via the mortality intensity. Continuous-time approaches are discussed in Cairns et al. (Reference Cairns, Blake and Dowd2008), and they have been studied extensively in the literature, see for example Biffis (Reference Biffis2005), Dahl and Moller (Reference Dahl and Moller2006), Luciano and Vigna (Reference Luciano and Vigna2008) and Fung et al. (Reference Fung, Ignatieva and Sherris2014).
Examples of dynamic mortality models; here true death/mortality rates are being modelled.

2.2. GLM framework
Estimation of stochastic mortality models such as those presented in Table 1 can be performed based on a flexible approach known as GLM framework (Villegas et al., Reference Villegas, Millossovich and Kaishev2015; Currie, Reference Currie2016).
Given central exposures E
xt
, it is typical to approximate initial exposures as
 $E_{{xt}}^{i} \,\approx\,E_{{xt}} {\plus}{1 \over 2}D_{{xt}} $
. Under the GLM framework, one is interested in modelling the number of deaths D
xt
as random variables. Common examples include Poisson error structure
 $$D_{{xt}} \sim {\rm Poisson}(E_{{xt}} \,m_{{x,t}} )$$
and Binomial error structure
 $$D_{{xt}} \sim {\rm Binomial}(E_{{xt}}^{i} ,\,q_{{x,t}} ).$$
Note that we have the expected values
 $${\Bbb E}\left[ {D_{{xt}} /E_{{xt}} } \right]{\equals}m_{{x,t}} $$
and
 ${\Bbb E}[D_{{xt}} /E_{{xt}}^{i} ]{\equals}q_{{x,t}} $
for the Poisson and Binomial models, respectively. Through the so-called link function g, one can associate the mean
 ${\Bbb E}\left[ {D_{{xt}} /E_{{xt}} } \right]$
or
 ${\Bbb E}[D_{{xt}} /E_{{xt}}^{i} ]$
with a predictor ρ
x,t
as
 $$g\left( {{\Bbb E}\left[ {{{D_{{xt}} } \over {\bar{E}_{{xt}} }}} \right]} \right){\equals}\rho _{{x,t}} $$
where
 $\bar{E}_{{xt}} $
can be initial or central exposures. Typical link functions for the Poisson and Binomial models are the log function and the logit function, respectively.
The models in Table 1, from the viewpoint of GLM framework, provide a specification for the predictor. In particular, the last four models in Table 1 assume linear predictors while the first three models describe non-linear predictors since multiplicative terms of parameters such as β x κ t are involved in the predictor. The latter models can be referred to as generalised non-linear models (Currie, Reference Currie2016).
We note here that a clear advantage of the GLM framework is that it allows sophisticated error structures such as Poisson and Binomial distributions compared to the SVD approach. However, despite its flexibility, the framework involves a two-step procedure for estimation which is in contrast to the state-space approach presented in the following sections where a joint estimation of model parameters and latent factors is performed.
2.3. State-space modelling framework
In this paper we extend previous work, see for example Pedroza (Reference Pedroza2006), Kogure and Kurachi (Reference Kogure and Kurachi2010) and Fung et al. (Reference Fung, Peters and Shevchenko2017), on using state-space techniques to model mortality dynamics with cohort features taken into consideration. We first present a brief review of mortality modelling via state-space representation.
A state-space model consists of two equations: the observation equation and the state equation which are given, respectively, by
 $$z_{t} {\equals}a(\biphi _{ t} , {\mib u}_{ t} ),$$
 $$\phi _{t} {\equals}b(\biphi _{ {t{\minus}1}} ,{\mib u}_{ t} ),$$
where
z
t
represents an observed multi-dimensional time series and the state
ϕ
t
represents a multi-dimensional hidden Markov process. Here,
u
t
and
v
t
are independent random noises and the functions a and b can be non-linear in general. It is clear that each of the mortality models shown in Table 1, with m
x,t
replaced by
 $\tilde{m}_{{x,t}} $
and an inclusion of a noise term, would specify the observation equation of a state-space model, where the period and cohort factors represent the hidden states. A time series model for the period effects will form the state equation, thus completing the description of a state-space system. As an example, the LC model can be reformulated as
 $${\mib y}_{t} {\equals}{\bialpha} {\plus}{ \bibeta} \kappa _{t} {\plus}{\epsilon}_{t} , \quad {\epsilon}_{t} \mathop{ \sim }\limits^{{iid}} {\rm N}\left( {0,I_{p} \sigma _{{\epsilon}}^{2} } \right),$$
 $$\kappa _{t} {\equals}\kappa _{{t{\minus}1}} {\plus}\theta {\plus}\omega _{t} ,\quad \omega _{t} \mathop{ \sim }\limits^{{iid}} {\rm N}\left( {0,\sigma _{\omega }^{2} } \right),$$
where
 $y_{{x,t}} {\equals}{\rm ln}\,\tilde{m}_{{x,t}} $
, I
p
is a p-dimensional identity matrix and N(a, b) denotes the normal distribution with mean a and covariance b.
Fung et al. (Reference Fung, Peters and Shevchenko2017) study two generalisations of the state-space LC system (13) to analyse long-term mortality time series for the Danish population. The first generalisation is to incorporate heteroscedasticity into the model, that is the homogeneous covariance structure
 $I_{p} \sigma _{{\epsilon}}^{2} $
in the observation equation in (13) which is replaced by a heterogeneous covariance matrix
 $I_{p} \sigma _{{{\epsilon},x}}^{2} $
. Note that the product
 $I_{p} \sigma _{{{\epsilon},x}}^{2} $
is a p by p diagonal matrix where the diagonal elements are
 $\sigma _{{{\epsilon},x_{1} }}^{2} ,\,\ldots\,,\sigma _{{{\epsilon},x_{p} }}^{2} $
. This feature turns out to be a major improvement to model fit for Danish mortality data. For simplicity, we assume constant variance in the observation equation for the models considered in the paper. Estimation for models with heteroscedasticity structure can also be performed as discussed in Fung et al. (Reference Fung, Peters and Shevchenko2017).
The second generalisation is to consider stochastic volatility for the latent process, that is the period effect κ t in the state equation in (13), to capture the observed characteristics of the long-term time series data. Specifically, the following extended LC model with stochastic volatility feature is proposed:
 $$y_{t} {\equals}\alpha {\plus}\beta \kappa _{t} {\plus}{\epsilon}_{t} ,\quad {\epsilon}_{t} \mathop{ \sim }\limits^{{iid}} {\rm N}\left( {0,\sigma _{{\epsilon}}^{2} I_{p} } \right),$$
 $$\kappa _{t} {\equals}\kappa _{{t{\minus}1}} {\plus}\theta {\plus}\omega _{t} ,\quad \omega _{t} \!\mid\!\xi _{t} \sim {\rm N}\left( {0,{\rm exp}\{ \xi _{t} \} } \right),$$
 $$\xi _{t} {\equals}\lambda _{1} \xi _{{t{\minus}1}} {\plus}\lambda _{2} {\plus}\zeta _{t} ,\quad \zeta _{t} \mathop{ \sim }\limits^{{iid}} {\rm N}( {0,\sigma _{\xi }^{2} } )$$
where ξ t captures the stochastic volatility for the period effect. Bayesian inference for the model is developed based on particle MCMC method (Andrieu et al., Reference Andrieu, Doucet and Holenstein2010).
Despite the fact that cohort models are essential in mortality modelling as shown in Table 1, a formulation of mortality models with cohort factors incorporated is yet to be studied and analysed in the state-space setting in the literature. In the following we will present and demonstrate our approach for dealing with cohort models via state-space methodology.
3. Cohort Effects: State-Space Formulation
This section presents a formulation of cohort models in state-space framework. We first describe how the cohort factor impacts the evolution of the age-specific death rates. The insight will give us a way to derive a state-space representation of the cohort effects. Bayesian inference for cohort models will be developed in section 4.
3.1. Background
Renshaw and Haberman (Reference Renshaw and Haberman2006) introduces a cohort factor γ
t−x
to the LC model together with an age-modulating coefficient
 $\beta _{x}^{\gamma } $
as follows:
 $${\rm ln}\,m_{{x,t}} {\equals}\alpha _{x} {\plus}\beta _{x} \kappa _{t} {\plus}\beta _{x}^{\gamma } \gamma _{{t{\minus}x}} .$$
Here t−x represents year-of-birth and hence γ t−x is a factor created to capture the cohort effect.
Numerical estimation of the cohort model (15), however, is reported in Villegas et al. (Reference Villegas, Millossovich and Kaishev2015) to produce mixed convergence results based on the regression setup. Robustness of the resulting regression-based cohort models is also questioned as the goodness of model fit is reported to be sensitive to the data being used and the fitting algorithm. These robustness and convergence problems are also noticed in Currie (Reference Currie2016) where the paper presents a comprehensive approach for mortality modelling based on generalised linear and non-linear models, see also section 2.2 for a brief discussion.
Moreover, it is shown in Leng and Peng (Reference Leng and Peng2016) that the two-step estimation approach utilised in Lee and Carter (Reference Lee and Carter1992) will in general lead to inconsistent estimators unless restrictions are imposed on the possible range of time series models for the underlying dynamics. The Bayesian state-space approach, in contrast, is not subject to such restrictions as one can perform estimation and forecasting under a single universal framework. We report our empirical findings for the estimation and forecasting of state-space cohort models in section 5.
3.2. State-space formulation
In this paper we focus on the full cohort model
 $${\rm ln}\,\tilde{m}_{{x,t}} {\equals}\alpha _{x} {\plus}\beta _{x} \kappa _{t} {\plus}\beta _{x}^{\gamma } \gamma _{{t{\minus}x}} {\plus}{\epsilon}_{{x,t}} ,$$
where a dynamics for the crude death rate is being modelled and a noise term ε x,t is included.
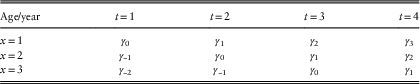
To aid in explaining how we derive a state-space representation of cohort models, we consider a matrix of cells where the row and column corresponds to age (x) and year (t), respectively, see Table 2. Here we assume x=1, … , 3 and t=1, … , 4 for illustration. The cohort factor γ t−x is indexed by the year-of-birth t−x and its value on each cell is displayed in Table 2. We first notice that the value γ t−x is constant on the “cohort direction”, that is on the cells (x, t), (x+1, t+1) and so on.
Values of the cohort factor γ t−x on a matrix of cells (x, t).

Now consider the cohort model (16) and let
 $\gamma _{t}^{x} \,\colon\!{\equals}\,\gamma _{{t{\minus}x}} $
. The model can be expressed in matrix form as
 $$\left( {\matrix{ {{\rm ln}\,\tilde{m}_{{1,t}} } \hfill \cr {{\rm ln}\,\tilde{m}_{{2,t}} } \hfill \cr {{\rm ln}\,\tilde{m}_{{3,t}} } \hfill \cr } } \right){\equals}\left( {\matrix{ {\alpha _{1} } \hfill \cr {\alpha _{2} } \hfill \cr {\alpha _{3} } \hfill \cr } } \right){\plus}\left( {\matrix{ {\beta _{1} } \hfill \cr {\beta _{2} } \hfill \cr {\beta _{3} } \hfill \cr } } \right)\kappa _{t} {\plus}\left( {\matrix{ {\beta _{1}^{\gamma } } \hfill & 0 \hfill & 0 \hfill \cr 0 \hfill & {\beta _{2}^{\gamma } } \hfill & 0 \hfill \cr 0 \hfill & 0 \hfill & {\beta _{3}^{\gamma } } \hfill \cr } } \right)\left( {\matrix{ {\gamma _{t}^{1} } \hfill \cr {\gamma _{t}^{2} } \hfill \cr {\gamma _{t}^{3} } \hfill \cr } } \right){\plus}\left( {\matrix{ {{\epsilon}_{{1,t}} } \hfill \cr {{\epsilon}_{{2,t}} } \hfill \cr {{\epsilon}_{{3,t}} } \hfill \cr } } \right).$$
As time flows from t=1 to t=4, the cohort vector
 $$(\gamma _{t}^{1} ,\gamma _{t}^{2} ,\gamma _{t}^{3} )^{T} $$
, which represents the cohort factor in matrix form, proceeds as
 $$\left( {\matrix{ {\gamma _{1}^{1} ({\equals}\gamma _{0} )} \hfill \cr {\gamma _{1}^{2} ({\equals}\gamma _{{{\minus}1}} )} \hfill \cr {\gamma _{1}^{3} ({\equals}\gamma _{{{\minus}2}} )} \hfill \cr } } \right)\to\left( {\matrix{ {\gamma _{2}^{1} ({\equals}\gamma _{1} )} \hfill \cr {\gamma _{2}^{2} ({\equals}\gamma _{0} )} \hfill \cr {\gamma _{2}^{3} ({\equals}\gamma _{{{\minus}1}} )} \hfill \cr } } \right)\to\left( {\matrix{ {\gamma _{3}^{1} ({\equals}\gamma _{2} )} \hfill \cr {\gamma _{3}^{2} ({\equals}\gamma _{1} )} \hfill \cr {\gamma _{3}^{3} ({\equals}\gamma _{0} )} \hfill \cr } } \right)\to\left( {\matrix{ {\gamma _{4}^{1} ({\equals}\gamma _{3} )} \hfill \cr {\gamma _{4}^{2} ({\equals}\gamma _{2} )} \hfill \cr {\gamma _{4}^{3} ({\equals}\gamma _{1} )} \hfill \cr } } \right).$$
The key observation here from (18) is that the first two elements of the cohort vector at time t−1 will appear as the bottom two elements of the cohort vector at time t. The pattern can also be observed from Table 2. Therefore, the evolution of the cohort vector must satisfy
 $$\left( {\matrix{ {\gamma _{t}^{1} } \hfill \cr {\gamma _{t}^{2} } \hfill \cr {\gamma _{t}^{3} } \hfill \cr } } \right){\equals}\left( {\matrix{ {\rm {\asterisk}} \hfill & {\rm {\asterisk}} \hfill & {\rm {\asterisk}} \hfill \cr 1 \hfill & 0 \hfill & 0 \hfill \cr 0 \hfill & 1 \hfill & 0 \hfill \cr } } \right)\left( {\matrix{ {\gamma _{{t{\minus}1}}^{1} } \hfill \cr {\gamma _{{t{\minus}1}}^{2} } \hfill \cr {\gamma _{{t{\minus}1}}^{3} } \hfill \cr } } \right){\plus}\,\ldots\,,$$
which is in fact a result of the defining property of “cohort”: γ
t−x
=γ
(t−i)−(x−i). Furthermore, it is obvious from (19) that one only needs to model the dynamics of
 $\gamma _{t}^{1} $
but not
 $\gamma _{t}^{2} $
and
 $\gamma _{t}^{3} $
. We will use this observation to derive a state-space formulation of cohort models which is presented next.
Let
 $y_{x} {\equals}{\rm ln}\,\tilde{m}_{{x,t}} $
, in matrix notation we have (recall that
 $\gamma _{t}^{x} \,\colon\!{\equals}\gamma _{{t{\minus}x}} $
)
 $$\left( {\matrix{ {y_{{x_{1} ,t}} } \hfill \cr {y_{{x_{2} ,t}} } \hfill \cr \vdots \hfill \cr {y_{{x_{p} ,t}} } \hfill \cr } } \right){\equals}\left( {\matrix{ {\alpha _{{x_{1} }} } \hfill \cr {\alpha _{{x_{2} }} } \hfill \cr \vdots \hfill \cr {\alpha _{{x_{p} }} } \hfill \cr } } \right){\plus}\left( {\matrix{ {\beta _{{x_{1} }} } \hfill & {\beta _{{x_{1} }}^{\gamma } } \hfill & 0 \hfill & \cdots \hfill & 0 \hfill \cr {\beta _{{x_{2} }} } \hfill & 0 \hfill & {\beta _{{x_{2} }}^{\gamma } } \hfill & \cdots \hfill & 0 \hfill \cr \vdots \hfill & \vdots \hfill & \vdots \hfill & \ddots \hfill & \vdots \hfill \cr {\beta _{{x_{p} }} } \hfill & 0 \hfill & 0 \hfill & \cdots \hfill & {\beta _{{x_{p} }}^{\gamma } } \hfill \cr } } \right)\left( {\matrix{ {\kappa _{t} } \hfill \cr {\gamma _{t}^{{x_{1} }} } \hfill \cr {\gamma _{t}^{{x_{2} }} } \hfill \cr \vdots \hfill \cr {\gamma _{t}^{{x_{p} }} } \hfill \cr } } \right){\plus}\left( {\matrix{ {{\epsilon}_{{x_{1} ,t}} } \hfill \cr {{\epsilon}_{{x_{2} ,t}} } \hfill \cr \vdots \hfill \cr {{\epsilon}_{{x_{p} ,t}} } \hfill \cr } } \right).$$
It is clear that, from (20), we have
 $y_{{x_{i} ,t}} {\equals}\alpha _{{x_{i} }} {\plus}\beta _{{x_{i} }} \kappa _{t} {\plus}\beta _{{x_{i} }}^{\gamma } \gamma _{t}^{{x_{i} }} {\plus}{\epsilon}_{{x_{i} ,t}} $
which corresponds to (16) for
 $i\in\{ 1,\,\ldots\,,p\} $
. Here
 $(\kappa _{t} ,\gamma _{t}^{{x_{1} }} ,\,\ldots\,,\gamma _{t}^{{x_{p} }} )^{{\rm T}} $
is the p+1 dimensional state vector.
From (18)–(19), we can write the state equation in matrix notation as follows:
 $$\left( {\matrix{ {\kappa _{t} } \hfill \cr {\gamma _{t}^{{x_{1} }} } \hfill \cr {\gamma _{t}^{{x_{2} }} } \hfill \cr \vdots \hfill \cr {\gamma _{t}^{{x_{{p{\minus}1}} }} } \hfill \cr {\gamma _{t}^{{x_{p} }} } \hfill \cr } } \right){\equals}\left( {\matrix{ 1 \hfill & 0 \hfill & 0 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr 0 \hfill & \lambda \hfill & 0 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr 0 \hfill & 1 \hfill & 0 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr 0 \hfill & 0 \hfill & 1 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr \vdots \hfill & \vdots \hfill & \vdots \hfill & \ddots \hfill & \vdots \hfill & \vdots \hfill \cr 0 \hfill & 0 \hfill & 0 \hfill & \cdots \hfill & 1 \hfill & 0 \hfill \cr } } \right)\left( {\matrix{ {\kappa _{{t{\minus}1}} } \hfill \cr {\gamma _{{t{\minus}1}}^{{x_{1} }} } \hfill \cr {\gamma _{{t{\minus}1}}^{{x_{2} }} } \hfill \cr \vdots \hfill \cr {\gamma _{{t{\minus}1}}^{{x_{{p{\minus}1}} }} } \hfill \cr {\gamma _{{t{\minus}1}}^{{x_{p} }} } \hfill \cr } } \right){\plus}\left( {\matrix{ \theta \hfill \cr \zeta \hfill \cr 0 \hfill \cr \vdots \hfill \cr 0 \hfill \cr 0 \hfill \cr } } \right){\plus}\left( {\matrix{ {\omega _{t}^{\kappa } } \hfill \cr {\omega _{t}^{\gamma } } \hfill \cr 0 \hfill \cr \vdots \hfill \cr 0 \hfill \cr 0 \hfill \cr } } \right).$$
Here we assume κ t is a random walk with drift process (ARIMA(0, 1, 0))
 $$\kappa _{t} {\equals}\kappa _{{t{\minus}1}} {\plus}\theta {\plus}\omega _{t}^{\kappa } ,\quad \omega _{t}^{\kappa } \mathop{ \sim }\limits^{{iid}} {\rm N}(0,\sigma _{\omega }^{2} ),$$
and the dynamics of
 $\gamma _{t}^{{x_{1} }} $
is described by a stationary AR(1) process (ARIMA(1,0,0))
 $$\gamma _{t}^{{x_{1} }} {\equals}\lambda \gamma _{{t{\minus}1}}^{{x_{1} }} {\plus}\zeta {\plus}\omega _{t}^{\gamma } ,\quad \omega _{t}^{\gamma } \mathop{ \sim }\limits^{{iid}} {\rm N}\left( {0,\sigma _{\gamma }^{2} } \right),$$
where
 $\!\mid\!\lambda \!\mid\!\,\lt\,1$
. It should be note that one may consider non-stationary processes such as the random walk with drift process by fixing λ=1. For illustration purpose we consider stationary processes for the cohort factor in this paper. We will provide further discussion on the modelling of cohort factor in section 5.3.2. One may consider other dynamics for
 $\gamma _{t}^{{x_{1} }} $
by specifying the second row of the p+1 by p+1 matrix in (21). For example, one can consider generally the state equation as
 $$\left( {\matrix{ {\kappa _{t} } \hfill \cr {\gamma _{t}^{{x_{1} }} } \hfill \cr {\gamma _{t}^{{x_{2} }} } \hfill \cr \vdots \hfill \cr {\gamma _{t}^{{x_{{p{\minus}1}} }} } \hfill \cr {\gamma _{t}^{{x_{p} }} } \hfill \cr } } \right){\equals}\left( {\matrix{ 1 \hfill & 0 \hfill & 0 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr 0 \hfill & {\lambda _{1} } \hfill & {\lambda _{2} } \hfill & \cdots \hfill & {\lambda _{{p{\minus}1}} } \hfill & {\lambda _{p} } \hfill \cr 0 \hfill & 1 \hfill & 0 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr 0 \hfill & 0 \hfill & 1 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr \vdots \hfill & \vdots \hfill & \vdots \hfill & \ddots \hfill & \vdots \hfill & \vdots \hfill \cr 0 \hfill & 0 \hfill & 0 \hfill & \cdots \hfill & 1 \hfill & 0 \hfill \cr } } \right)\left( {\matrix{ {\kappa _{{t{\minus}1}} } \hfill \cr {\gamma _{{t{\minus}1}}^{{x_{1} }} } \hfill \cr {\gamma _{{t{\minus}1}}^{{x_{2} }} } \hfill \cr \vdots \hfill \cr {\gamma _{{t{\minus}1}}^{{x_{{p{\minus}1}} }} } \hfill \cr {\gamma _{{t{\minus}1}}^{{x_{p} }} } \hfill \cr } } \right){\plus}\left( {\matrix{ \theta \hfill \cr \zeta \hfill \cr 0 \hfill \cr \vdots \hfill \cr 0 \hfill \cr 0 \hfill \cr } } \right){\plus}\left( {\matrix{ {\omega _{t}^{\kappa } } \hfill \cr {\omega _{t}^{\gamma } } \hfill \cr 0 \hfill \cr \vdots \hfill \cr 0 \hfill \cr 0 \hfill \cr } } \right),$$
where
 $\gamma _{t}^{{x_{1} }} {\equals}\lambda _{1} \gamma _{{t{\minus}1}}^{{x_{1} }} {\plus}\lambda _{2} \gamma _{{t{\minus}1}}^{{x_{2} }} {\plus}\,\ldots\,{\plus}\lambda _{{p{\minus}1}} \gamma _{{t{\minus}1}}^{{x_{{p{\minus}1}} }} {\plus}\lambda _{p} \gamma _{{t{\minus}1}}^{{x_{p} }} {\plus}\zeta {\plus}\omega _{t}^{\gamma } $
which is an ARIMA(p, 0, 0) process since
 $\gamma _{{t{\minus}1}}^{{x_{i} }} {\equals}\gamma _{{t{\minus}i}}^{{x_{1} }} $
, i=2, … , p. Note that in general the state-space modelling approach can handle seasonal ARIMA models as well as non-linear models, see for instance Harvey (Reference Harvey1989), Gourieroux and Monfort (Reference Gourieroux and Monfort1997) and Petris et al. (Reference Petris, Petrone and Campagnoli2009) for their representations in state-space form.
We can express the matrix form of (20)–(21) succinctly as
 $${\mib y}_{\mib t} {\equals}\bialpha {\plus}{\mib B}\bivarphi _{\mib t} {\plus}{\varepsilon}_{\mib t} ,\quad {\epsilon}_{\mib t} \mathop{ \sim }\limits^{{iid}} {\rm N}(0,\sigma _{{\epsilon}}^{2} I_{p} ),$$
 $$\varphi _{\mib t} {\equals}\Lambda \bivarphi _{\mib {t{\minus}1}} {\plus}\Theta {\plus}\biomega _{\mib t} ,\quad \biomega _{\mib t} \mathop{ \sim }\limits^{{iid}} {\rm N}(0,\Upsilon ),$$
where
 $$B{\equals}\left( {\matrix{ {\beta _{{x_{1} }} } \hfill & {\beta _{{x_{1} }}^{\gamma } } \hfill & 0 \hfill & \cdots \hfill & 0 \hfill \cr {\beta _{{x_{2} }} } \hfill & 0 \hfill & {\beta _{{x_{2} }}^{\gamma } } \hfill & \cdots \hfill & 0 \hfill \cr \vdots \hfill & \vdots \hfill & \vdots \hfill & \ddots \hfill & \vdots \hfill \cr {\beta _{{x_{p} }} } \hfill & 0 \hfill & 0 \hfill & \cdots \hfill & {\beta _{{x_{p} }}^{\gamma } } \hfill \cr } } \right),\,{\rm \Lambda }{\equals}\left( {\matrix{ 1 \hfill & 0 \hfill & 0 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr 0 \hfill & \lambda \hfill & 0 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr 0 \hfill & 1 \hfill & 0 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr 0 \hfill & 0 \hfill & 1 \hfill & \cdots \hfill & 0 \hfill & 0 \hfill \cr \vdots \hfill & \vdots \hfill & \vdots \hfill & \ddots \hfill & \vdots \hfill & \vdots \hfill \cr 0 \hfill & 0 \hfill & 0 \hfill & \cdots \hfill & 1 \hfill & 0 \hfill \cr } } \right),\,{\rm \Theta }{\equals}\left( {\matrix{ \theta \hfill \cr \zeta \hfill \cr 0 \hfill \cr \vdots \hfill \cr 0 \hfill \cr 0 \hfill \cr } } \right),$$
and
 $\bivarphi _{\mib t} {\equals}(\kappa _{t} ,\gamma _{t}^{{x_{1} }} ,\,\ldots\,,\gamma _{t}^{{x_{p} }} )^{{\rm T}} $
, I
p
the p-dimensional identity matrix and ϒ is a p+1 by p+1 diagonal matrix with diagonal
 $(\sigma _{\kappa }^{2} ,\sigma _{\gamma }^{2} ,0,\,\ldots\,,0)$
. For simplicity we assume homoscedasticity in the observation equation; heteroscedasticity can be considered as developed in Fung et al. (Reference Fung, Peters and Shevchenko2017). Note that the set of constraints (30) are required for the identification of the cohort model (25).
Remark 3.1 The observation and state equations (20)–(21) imply that the cohort model that we have formulated here belongs to the linear-Gaussian class of state-space models. As a result one can perform efficient maximum-likelihood or Bayesian estimation on fitting the model to data, see Fung et al. (Reference Fung, Peters and Shevchenko2017). In this paper we focus on Bayesian inference so that mortality forecasts can take into account parameter uncertainty. It should also be note that in Fung et al. (Reference Fung, Peters and Shevchenko2017) the formulation of cohort models in state-space framework is only mentioned briefly while their estimation and forecasting were not provided due to the focus and length of the paper. The current paper aims to fill this gap by providing details on how one may derive the formulation of cohort models under the state-space framework and to examine the resulting models comprehensively using a range of mortality data.
3.3. A simplified cohort model
The cohort model (15) assumes that the impact of the cohort factor on age-specific death rates is modulated by the coefficient
 $\beta _{x}^{\gamma } $
. Iteration-based estimation of the cohort model is reported in Cairns et al. (Reference Cairns, Blake, Dowd, Coughlan, Epstein, Ong and Balevich2009) and Hunt and Villegas (Reference Hunt and Villegas2015) to be suffering from convergence problems. As a result, Haberman and Renshaw (Reference Haberman and Renshaw2011) consider to simplify the model structure to
 $${\rm ln}\,m_{{x,t}} {\equals}\alpha _{x} {\plus}\beta _{x} \kappa _{t} {\plus}\gamma _{{t{\minus}x}} .$$
That is, the modulating coefficient
 $\beta _{x}^{\gamma } $
for the cohort factor is set to be one for all age x. It is suggested that the simplified model (27) exhibits better estimation convergence behaviour when fitting the model to mortality data.
Remark 3.2 When fitting cohort models to data based on the Poisson or binomial regression setup via iteration-based estimation, it is typical to assume the starting values of the iteration scheme are coming from the estimates of other similar models, for example the LC model or APC model (Hunt and Villegas, Reference Hunt and Villegas2015; Villegas et al., Reference Villegas, Millossovich and Kaishev2015; Currie, Reference Currie2016). Even doing so the convergence is not guaranteed. We will report in section 5 that our approach based on Bayesian state-space framework do not require such an assumption and is able to successfully perform Bayesian estimation for various countries when cohort patterns are present in the data.
In the following, we will also consider the model
 $$y_{t} {\equals}\alpha {\plus}B^{s} \varphi _{t} {\plus}{\epsilon}_{t} ,\quad {\epsilon}_{t} \mathop{ \sim }\limits^{{iid}} {\rm N}(0,\sigma _{{\epsilon}}^{2} I_{p} ),$$
 $$\varphi _{t} {\equals}\Lambda \varphi _{{t{\minus}1}} {\plus}\Theta {\plus}\omega _{t} ,\quad \omega _{t} \mathop{ \sim }\limits^{{iid}} {\rm N}(0,\Upsilon ),$$
where
 $$B^{s} {\equals}\left( {\matrix{ {\beta _{{x_{1} }} } \hfill & 1 \hfill & 0 \hfill & \cdots \hfill & 0 \hfill \cr {\beta _{{x_{2} }} } \hfill & 0 \hfill & 1 \hfill & \cdots \hfill & 0 \hfill \cr \vdots \hfill & \vdots \hfill & \vdots \hfill & \ddots \hfill & \vdots \hfill \cr {\beta _{{x_{p} }} } \hfill & 0 \hfill & 0 \hfill & \cdots \hfill & 1 \hfill \cr } } \right).$$
It will be referred to as the simplified cohort model. In addition, the following set of parameter constraints
 $$\mathop \sum\limits_{x{\equals}x_{1} }^{x_{p} } \beta _{x} {\equals}1, \mathop \sum\limits_{t{\equals}t_{1} }^{t_{n} } \kappa _{t} {\equals}0, \,\mathop \sum\limits_{c{\equals}t_{1} {\minus}x_{p} }^{t_{n} {\minus}x_{1} } \gamma _{c} {\equals}0,$$
is imposed to ensure the identifiability of the simplified cohort model.
Since our approach is able to estimate both the simplified and full cohort models, (27) and (15), respectively, for a range of mortality data set, we include the simplified cohort model in our empirical analysis examining the performance of the simplified and full cohort models as a comparative study.
4. Bayesian Inference for Cohort Models
In this section we begin by detailing the Bayesian estimation of the full cohort model in state-space formulation (25). Nested models including the simplified cohort model (28) and the LC model (13) will be discussed in section 4.2. We first note that the cohort models and the LC model belong to the class of linear and Gaussian state-space models. As a result one can apply an efficient MCMC estimation algorithm based on Gibbs sampling with conjugate priors combined with forward-backward filtering as described in Fung et al. (Reference Fung, Peters and Shevchenko2017), this forms a special case of the so-called collapsed Gibbs sampler framework of van Dyk and Park (Reference van Dyk and Park2008).
4.1. Bayesian inference for the full cohort model
For the full cohort model (25), the target density is given by
 $$\pi \left( {\varphi _{{0\,\colon\,n}} ,\psi \!\mid\! y_{{1\,\colon\,n}} } \right)\propto\pi (y_{{1\,\colon\,n}} \!\mid\! \varphi _{{0\,\colon\,n}} ,\psi )\pi (\varphi _{{0\,\colon\,n}} \!\mid\! \psi )\pi (\psi )$$
 $${\equals}\mathop \prod\limits_{k{\equals}1}^n \pi (y_{k} \!\mid\! \varphi _{{0\,\colon\,k}} ,\psi )\pi (\varphi _{k} \!\mid\! \varphi _{{k{\minus}1}} ,\psi )\pi (\varphi _{0} )\pi (\psi )$$
where
 $\varphi _{{0\,\colon\,n}} \,\colon\!{\equals}(\kappa _{{0\,\colon\,n}} ,\gamma _{{0\,\colon\,n}}^{{x_{1} }} ,\,\ldots\,,\gamma _{{0\,\colon\,n}}^{{x_{p} }} )$
is the p+1 dimensional latent state vector for
 $t\in\{ 0,\,\ldots\,,n\} $
Footnote
4
and
 ${\mib{\psi }} \,\colon\!{\equals}({\mib{\beta }} ,{\mib{\beta }} ^{\gamma } ,{\mib{\alpha }} ,\theta ,\zeta ,\lambda ,\sigma _{{\epsilon}}^{2} ,\sigma _{\kappa }^{2} ,\sigma _{\gamma }^{2} )$
is the 3p+6 dimensional static parameter vector. In order to simplify the notation, we write t=1, … , n instead of t=t
1, … , t
n
. We perform block sampling for the latent state via the so-called forward-filtering-backward-sampling (FFBS) algorithm (Carter and Kohn, Reference Carter and Kohn1994) and the posterior samples of the static parameters are obtained via conjugate priors. The sampling procedure is described in Algorithm 1, where M is the number of MCMC iterations performed. Note also that the notation
 ${\mib{\psi }} _{{{\minus}\nu }}^{{(i)}} \,\colon\!{\equals}(\psi _{{g_{1} }}^{{(i)}} ,\,\ldots\,,\psi _{{g_{{\nu {\minus}1}} }}^{{(i)}} ,\psi _{{g_{{\nu {\plus}1}} }}^{{(i{\minus}1)}} ,\,\ldots\,,\psi _{{g_{{3p{\plus}6}} }}^{{(i{\minus}1)}} )$
is used in Algorithm 1 where the subscript g
1 refers to the first parameter and so onFootnote
5
. Moreover, the initial values
 $\psi ^{{(0)}} $
of the Markov chain can be set to any reasonable values and after discarding the initial iterations as burn-in period, the assumption of the initial values used will not impact the estimation results if the chain mixes well.
Remark 4.1 Note that some elements of the state vector evolve deterministically as specified in (21). Consequently the joint model decomposes as follows into product measures, which is the joint measures of the random observation and the latent state process, given explicitly by
 $$\eqalignno{ \pi \left( {dy_{{1\colon n}} ,d\kappa _{{0 \colon n}} ,d\gamma _{{0\colon n}} ; \,\psi } \right) & {\equals}\mathop \prod\limits_{t{\equals}1}^n \pi \left( {dy_{t} \!\mid\! \kappa _{t} ,\gamma _{t} ; \psi } \right)\pi \left( {d\kappa _{t} ,d\gamma _{t} \!\mid\! \kappa _{{t{\minus}1}} ,\gamma _{{t{\minus}1}} ; \psi } \right) \cr {\equals}\mathop \prod\limits_{t{\equals}1}^n \pi \left( {dy_{t} \!\mid\! \kappa _{t} ,\gamma _{t} ; \psi } \right)\pi \left( {d\kappa _{t} ,d\gamma _{t}^{{x_{1} }} \!\mid\! \kappa _{{t{\minus}1}} ,\gamma _{{t{\minus}1}}^{{x_{1} }} ; \psi } \right)\delta _{{\gamma _{{t{\minus}1}}^{{x_{1} }} }} \left( {d\gamma _{t}^{{x_{2} }} } \right)\,\ldots\,\delta _{{\gamma _{{t{\minus}1}}^{{x_{{p{\minus}1}} }} }} \left( {d\gamma _{t}^{{x_{p} }} } \right), $$
where δ w is the Dirac mass probability measure centered on point w. Then the MCMC sampling steps involved in Algorithm 1 can be carried out and justified using the Dirac mass probability measure for elements of the state vector that evolve deterministically. For examples of similar models in which Dirac measure is present in the likelihood specification and filtering equations, see for example Andrieu et al. (Reference Andrieu, Doucet and Holenstein2010), Del Moral et al. (Reference Del Moral, Peters and Vergé2013), Doucet et al. (Reference Doucet, Pitt, Deligiannidis and Kohn2015) and Peters et al. (Reference Peters, Targino and Wuthrich2017).
In Algorithm 1, after obtaining
 $\tilde{\kappa }_{{1\,\colon\,n}}^{{(i)}} $
from line 3, one can impose the constraint
 $\mathop{\sum}\nolimits_t {\kappa _{t}^{{(i)}} {\equals}0} $
by setting
 $\kappa _{t}^{{(i)}} {\equals}\tilde{\kappa }_{t}^{{(i)}} {\minus}(1/n)\mathop{\sum}\nolimits_{j{\equals}1}^n {\tilde{\kappa }_{j}^{{(i)}} } $
where t=1, … , n. Similarly, once
 $\tilde{\gamma }_{c}^{{(i)}} $
is obtained from
 $\varphi _{{0\,\colon\,n}}^{{(i)}} $
in line 3, setting
 $\gamma _{c}^{{(i)}} {\equals}\tilde{\gamma }_{c}^{{(i)}} {\minus}(1/(n{\plus}p{\minus}1))\mathop{\sum}\nolimits_{\ell {\equals}1{\minus}x_{p} }^{n{\minus}x_{1} } {\tilde{\gamma }_{\ell }^{{(i)}} } $
, where c=1−x
p
, … , n−x
1, will ensure the constraint
 $\mathop{\sum}\nolimits_c {\gamma _{c}^{{(i)}} {\equals}0} $
is satisfied. To impose the constraint
 $$\mathop{\sum}\nolimits_x {\beta _{x}^{{\left( i \right)}} } {\equals}1$$
, we set
 $\beta _{x}^{{(i)}} {\equals}\tilde{\beta }_{x}^{{(i)}} \!/\!\mathop{\sum}\nolimits_{j{\equals}x_{1} }^{x_{p} } {\tilde{\beta }_{j}^{{(i)}} } $
, where x=x
1, … , x
p
, once
 $\tilde{\beta }^{{(i)}} $
is obtained from line 5–7. Constraint for
 $(\beta ^{\gamma } )^{{(i)}} $
can be imposed similarly.

4.1.1. Forward-backward filtering for latent state dynamics
The FFBS procedure requires to carry out multivariate Kalman filtering forward in time and then sample backwardly using the obtained filtering distributions. For the full cohort model (20)–(21), the conditional distributions involved in the multivariate Kalman filtering recursions are given by
 $$\varphi _{{t{\minus}1}} \!\mid\! y_{{1\,\colon\,t{\minus}1}} \sim {\rm N}(m_{{t{\minus}1}} ,C_{{t{\minus}1}} ),$$
 $$\varphi _{t} \!\mid\! y_{{1\,\colon\,t{\minus}1}} \sim {\rm N}(a_{t} ,R_{t} ),$$
 $$y_{t} \!\mid\! y_{{1\,\colon\,t{\minus}1}} \sim {\rm N}(f_{t} ,Q_{t} ),$$
 $$\varphi _{t} \!\mid\! y_{{1\,\colon\,t}} \sim {\rm N}(m_{t} ,C_{t} ),$$
where
 $$a_{t} {\equals}\Lambda m_{{t{\minus}1}} {\plus}\Theta ,\quad R_{t} {\equals}\Lambda C_{{t{\minus}1}} \Lambda ^{{\rm T}} {\plus}\Upsilon ,$$
 $$f_{t} {\equals}\alpha {\plus}Ba_{t} ,\quad Q_{t} {\equals}BR_{t} B^{{\rm T}} {\plus}\sigma _{{\epsilon}}^{2} I_{p} ,$$
 $$m_{t} {\equals}a_{t} {\plus}R_{t} B^{{\rm T}} Q_{t}^{{{\minus}1}} (y_{t} {\minus}f_{t} ),\quad C_{t} {\equals}R_{t} {\minus}R_{t} B^{{\rm T}} Q_{t}^{{{\minus}1}} BR_{t} .$$
for t=1, … , n. Since
 $$\pi (\varphi _{{0\,\colon\,n}} \!\mid\! \psi ,{\bf y}_{{1\,\colon\,n}} ){\equals}\mathop \prod\limits_{t{\equals}0}^n \pi (\varphi _{t} \!\mid\! \varphi _{{t{\plus}1\,\colon\,n}} ,\psi ,{\bf y}_{{1\,\colon\,n}} ){\equals}\mathop \prod\limits_{t{\equals}0}^n \pi (\varphi _{t} \!\mid\! \varphi _{{t{\plus}1}} ,\psi ,{\bf y}_{{1\,\colon\,t}} ),$$
we see that for a block sampling of the latent state, one can first draw
 $\varphi _{n} $
from N(
m
n
, C
n
) and then, for t=n−1, … , 1, 0 (i.e. backward in time), draws a sample of
 $\varphi _{t} \!\mid _{{\varphi _{{t{\plus}1}} ,\psi ,{\bf y}_{{1\,\colon\,t}} }} $
recursively given a sample of
 $\varphi _{{t{\plus}1}} $
. It turns out that
 $\varphi _{t} \!\mid _{{\varphi _{{t{\plus}1}} ,\psi ,{\bf y}_{{1\,\colon\,t}} }} \sim {\rm N}({\mib{h}} _{t} ,H_{t} )$
where
 $${\mib{h}} _{t} {\equals}{\mib{m}} _{t} {\plus}C_{t} {\rm \Lambda }^{{\rm T}} R_{{t{\plus}1}}^{{{\minus}1}} (\varphi _{{t{\plus}1}} {\minus}{\bf a}_{{t{\plus}1}} ),$$
 $$H_{t} {\equals}C_{t} {\minus}C_{t} {\rm \Lambda }^{{\rm T}} R_{{t{\plus}1}}^{{{\minus}1}} {\rm \Lambda }C_{t} ,$$
based on Kalman smoothing (Carter and Kohn, Reference Carter and Kohn1994).
4.1.2. Posteriors for static parameters
To sample the posterior distribution of the static parameters in Algorithm 1, we assume the following independent conjugate priors:
 $$\alpha _{x} \sim {\rm N}(\tilde{\mu }_{\alpha } ,\tilde{\sigma }_{\alpha }^{2} ),\quad \beta _{x} \sim {\rm N}(\tilde{\mu }_{\beta } ,\tilde{\sigma }_{\beta }^{2} ),\quad \beta _{x}^{\gamma } \sim {\rm N}(\tilde{\mu }_{{\beta ^{\gamma } }} ,\tilde{\sigma }_{{\beta ^{\gamma } }}^{2} ),$$
 $$\theta \sim {\rm N}(\tilde{\mu }_{\theta } ,\tilde{\sigma }_{\theta }^{2} ),\quad \zeta \sim {\rm N}(\tilde{\mu }_{\zeta } ,\tilde{\sigma }_{\zeta }^{2} ),\quad \lambda \sim {\rm N}_{{[{\minus}1,1]}} (\tilde{\mu }_{\lambda } ,\tilde{\sigma }_{\lambda }^{2} ),$$
 $$\sigma _{{\epsilon}}^{2} \sim {\rm IG}(\tilde{a}_{{\epsilon}} ,\tilde{b}_{{\epsilon}} ),\quad \sigma _{\kappa }^{2} \sim {\rm IG}(\tilde{a}_{\kappa } ,\tilde{b}_{\kappa } ),\quad \sigma _{\gamma }^{2} \sim {\rm IG}(\tilde{a}_{\gamma } ,\tilde{b}_{\gamma } ),$$
where N[−1,1] denotes a truncated Gaussian with support [−1, 1] and
 ${\rm IG}(\tilde{a},\tilde{b})$
denotes an inverse-gamma distribution with mean
 $\tilde{b}/(\tilde{a}{\minus}1)$
and variance
 $\tilde{b}^{2} /((\tilde{a}{\minus}1)^{2} (\tilde{a}{\minus}2))$
for
 $\tilde{a}\,\gt\,2$
. The posteriors of the static parameters are then obtained as followsFootnote
6
:
 $$\alpha _{x} \!\mid\! y,\varphi ,\psi _{{{\minus}\alpha _{x} }} \sim {\rm N}\left( {{{\tilde{\sigma }_{\alpha }^{2} \sum_{t{\equals}1}^n (y_{{x,t}} {\minus}\beta _{x} \kappa _{t} {\minus}\beta _{x}^{\gamma } \gamma _{t}^{x} ){\plus}\tilde{\mu }_{\alpha } \sigma _{{\epsilon}}^{2} } \over {\tilde{\sigma }_{\alpha }^{2} n{\plus}\sigma _{{\epsilon}}^{2} }},{{\tilde{\sigma }_{\alpha }^{2} \sigma _{{\epsilon}}^{2} } \over {\tilde{\sigma }_{\alpha }^{2} n{\plus}\sigma _{{\epsilon}}^{2} }}} \right),$$
 $$\beta _{x} \!\mid\! y,\varphi ,\psi _{{{\minus}\beta _{x} }} \sim {\rm N}\left( {{{\tilde{\sigma }_{\beta }^{2} \sum_{t{\equals}1}^n (y_{{x,t}} {\minus}(\alpha _{x} {\plus}\beta _{x}^{\gamma } \gamma _{t}^{x} ))\kappa _{t} {\plus}\tilde{\mu }_{\beta } \sigma _{{\epsilon}}^{2} } \over {\tilde{\sigma }_{\beta }^{2} \sum_{t{\equals}1}^n \kappa _{t}^{2} {\plus}\sigma _{{\epsilon}}^{2} }},{{\tilde{\sigma }_{\beta }^{2} \sigma _{{\epsilon}}^{2} } \over {\tilde{\sigma }_{\beta }^{2} \sum_{t{\equals}1}^n \kappa _{t}^{2} {\plus}\sigma _{{\epsilon}}^{2} }}} \right),$$
 $$\beta _{x}^{\gamma } \!\mid\! y,\varphi ,\psi _{{{\minus}\beta _{x}^{\gamma } }} \sim {\rm N}\left( {{{\tilde{\sigma }_{{\beta ^{\gamma } }}^{2} \sum_{t{\equals}1}^n (y_{{x,t}} {\minus}(\alpha _{x} {\plus}\beta _{x} \kappa _{t} ))\gamma _{t}^{x} {\plus}\tilde{\mu }_{{\beta ^{\gamma } }} \sigma _{{\epsilon}}^{2} } \over {\tilde{\sigma }_{{\beta ^{\gamma } }}^{2} \sum_{t{\equals}1}^n (\gamma _{t}^{x} )^{2} {\plus}\sigma _{{\epsilon}}^{2} }},{{\tilde{\sigma }_{{\beta ^{\gamma } }}^{2} \sigma _{{\epsilon}}^{2} } \over {\tilde{\sigma }_{{\beta ^{\gamma } }}^{2} \sum_{t{\equals}1}^n (\gamma _{t}^{x} )^{2} {\plus}\sigma _{{\epsilon}}^{2} }}} \right),$$
 $$\theta \!\mid\! y,\varphi ,\psi _{{{\minus}\theta }} \sim {\rm N}\left( {{{\tilde{\sigma }_{\theta }^{2} \sum_{t{\equals}1}^n {\rm \ztbnd6 }(\kappa _{t} {\minus}\kappa _{{t{\minus}1}} ){\plus}\tilde{\mu }_{\theta } \sigma _{\omega }^{2} } \over {\tilde{\sigma }_{\theta }^{2} n{\plus}\sigma _{\omega }^{2} }},{{\tilde{\sigma }_{\theta }^{2} \sigma _{\omega }^{2} } \over {\tilde{\sigma }_{\theta }^{2} n{\plus}\sigma _{\omega }^{2} }}} \right),$$
 $$\zeta \!\mid\! y,\varphi ,\psi _{{{\minus}\theta }} \sim {\rm N}\left( {{{\tilde{\sigma }_{\zeta }^{2} \sum_{t{\equals}1}^n (\gamma _{t}^{{x_{1} }} {\minus}\lambda \gamma _{{t{\minus}1}}^{{x_{1} }} ){\plus}\tilde{\mu }_{\zeta } \sigma _{\gamma }^{2} } \over {\tilde{\sigma }_{\zeta }^{2} n{\plus}\sigma _{\gamma }^{2} }},{{\tilde{\sigma }_{\zeta }^{2} \sigma _{\gamma }^{2} } \over {\tilde{\sigma }_{\zeta }^{2} n{\plus}\sigma _{\gamma }^{2} }}} \right),$$
 $$\lambda \!\mid\! y,\varphi ,\psi _{{{\minus}\lambda }} \sim {\rm N}_{{[{\minus}1,1]}} \left( {{{\tilde{\sigma }_{\lambda }^{2} \sum_{t{\equals}1}^n ((\gamma _{t}^{{x_{1} }} {\minus}\zeta )\gamma _{{t{\minus}1}}^{{x_{1} }} ){\plus}\tilde{\mu }_{\lambda } \sigma _{\gamma }^{2} } \over {\tilde{\sigma }_{\lambda }^{2} \sum_{t{\equals}1}^n (\gamma _{{t{\minus}1}}^{{x_{1} }} )^{2} {\plus}\sigma _{\gamma }^{2} }},{{\tilde{\sigma }_{\lambda }^{2} \sigma _{\gamma }^{2} } \over {\tilde{\sigma }_{\lambda }^{2} \sum_{t{\equals}1}^n (\gamma _{{t{\minus}1}}^{{x_{1} }} )^{2} {\plus}\sigma _{\gamma }^{2} }}} \right),$$
 $$\sigma _{{\epsilon}}^{2} \!\mid\! y,\varphi ,\psi _{{{\minus}\sigma _{{\epsilon}}^{2} }} \sim {\rm IG}\left( {\tilde{a}_{{\epsilon}} {\plus}{{np} \over 2},\,\tilde{b}_{{\epsilon}} {\plus}{1 \over 2}\mathop \sum\limits_{x{\equals}x_{1} }^{x_{p} } \mathop \sum\limits_{t{\equals}1}^n \left( {y_{{x,t}} {\minus}\left( {\alpha _{x} {\plus}\beta _{x} \kappa _{t} {\plus}\beta _{x}^{\gamma } \gamma _{t}^{x} } \right)} \right)^{2} } \right),$$
 $$\sigma _{\kappa }^{2} \!\mid\! y,\varphi ,\psi _{{{\minus}\sigma _{\kappa }^{2} }} \sim {\rm IG}\left( {\tilde{a}_{\kappa } {\plus}{n \over 2},\,\tilde{b}_{\kappa } {\plus}{1 \over 2}\mathop \sum\limits_{t{\equals}1}^n \left( {\kappa _{t} {\minus}(\kappa _{{t{\minus}1}} {\plus}\theta )} \right)^{2} } \right),$$
 $$\sigma _{\gamma }^{2} \!\mid\! y,\varphi ,\psi _{{{\minus}\sigma _{\gamma }^{2} }} \sim {\rm IG}\left( {\tilde{a}_{\gamma } {\plus}{n \over 2},\,\tilde{b}_{\gamma } {\plus}{1 \over 2}\mathop \sum\limits_{t{\equals}1}^n \left( {\gamma _{t}^{{x_{1} }} {\minus}\lambda \gamma _{{t{\minus}1}}^{{x_{1} }} } \right)^{2} } \right).$$
We note here that if one is interested in modelling the cohort factor as a random walk with drift process which is non-stationary, one may fix λ=1 and hence there is no need to estimate the parameter λ.
4.2. Bayesian inference for nested models
The MCMC estimation for the full cohort model presented in Algorithm 1 can be applied to the nested models including the simplified cohort model and the LC model with only small adjustments.
The static parameter vector for the simplified cohort model is given by
 $$\psi \,\colon\!{\equals}(\beta ,\alpha ,\theta ,\zeta ,\lambda ,\sigma _{{\epsilon}}^{2} ,\sigma _{\kappa }^{2} ,\sigma _{\gamma }^{2} ),$$
where the sampling of the age-modulating coefficients
 $\beta _{x}^{\gamma } $
for the cohort factor is not required. Consequently line 9–12 in Algorithm 1 can be removed in this case. Moreover, for the simplified cohort model, we set
 $\beta _{x}^{\gamma } {\equals}1$
in the posterior distributions of α
x
, β
x
and
 $\sigma _{{\epsilon}}^{2} $
in (39), (40) and (45), respectively.
The LC model can be viewed as a further nested model of the simplified cohort model with the cohort factor γ
t−x
=0. As a result the state equation is one-dimensional with
 $\varphi _{{0\,\colon\,n}} \,\colon\!{\equals}\kappa _{{0\,\colon\,n}} $
and the static parameter vector consists of
 $$\psi \,\colon\!{\equals}(\beta ,\alpha ,\theta ,\sigma _{{\epsilon}}^{2} ,\sigma _{\kappa }^{2} ).$$
Recall the constraints (3) for the LC model. As a result the constraint
 $\mathop{\sum}\nolimits_c {\gamma _{c}^{{(i)}} } {\equals}0$
in line 4 and the sampling of
 $\beta _{x}^{\gamma } $
in line 9–12 in Algorithm 1 are not required. We also set
 $\gamma _{t}^{x} {\equals}0$
in the posterior distributions for β, α and
 $\sigma _{{\epsilon}}^{2} $
in (39), (40) and (45), respectively. Further details for a Bayesian estimation of the LC model can be found in Fung et al. (Reference Fung, Peters and Shevchenko2017).
5. Empirical Studies
We analyse several sets of mortality data from different countries based on the cohort models formulated in the state-space framework. We consider both the full cohort model and the simplified cohort model. In addition, we compare the cohort models against the LC model for model fitting as well as their forecasting properties. The countries that we consider includes England and Wales (UK), United States (US) and Italy (ITA). We perform our analysis on both male and female mortality data to investigate whether cohort effect within a country is shared for both genders. The data is obtained from the Human Mortality DatabaseFootnote 7 . The year range is from 1970 to 2010, and we restrict our attention to the age range 65–95. Consequently the range for the year-of-birth is 1875–1945.
5.1. Model estimation
We run the Markov chain sampler described in section 4 for 30,000 iterations and the burn-in period is set to be 15,000 iterations to ensure that the chain has arrived to the stationary state; thus we are left with 15,000 posterior samples. For all Gaussian priors
 ${\rm N}(\tilde{\mu },\tilde{\sigma }^{2} )$
, including the truncated Gaussian
 ${\rm N}_{{[{\minus}1,1]}} (\tilde{\mu },\tilde{\sigma }^{2} )$
, we assume
 $\tilde{\mu }{\equals}0$
and
 $\tilde{\sigma }^{2} {\equals}10$
; while for the inverse-gamma priors
 ${\rm IG}(\tilde{a},\tilde{b})$
we set
 $\tilde{a}{\equals}2.01$
and
 $\tilde{b}{\equals}0.01$
. The hyperparameters are chosen and tested to ensure the priors are sufficiently vague. To start the Kalman filter, we assume m
0=0 and C
0 is a diagonal covariance matrix with diagonal elements all equal to 10 (see (34a)). We refer x={x
1, … , x
p
} to age={65, … , 95} and t={t
1, … , t
n
} to year={1970, … , 2010} (i.e. p=31 and n=41).
As noted previously, no particular special initialisation is required with this methodology, it seems relatively robust to the choice of starting points. To start the chain for the full cohort model, initial values of the static parameters are set as follows:
 $$\alpha _{x}^{{(0)}} {\equals}(1/n)\mathop \sum\limits_t y_{{x,t}} $$
,
 $\beta _{x}^{{(0)}} {\equals}(\beta _{x}^{\gamma } )^{{(0)}} {\equals}1/p$
,
 $\theta ^{{(0)}} {\equals}\zeta ^{{(0)}} {\equals}{\minus}0.1$
,
 $(\sigma _{{\epsilon}}^{2} )^{{(0)}} {\equals}(\sigma _{\omega }^{2} )^{{(0)}} {\equals}(\sigma _{\gamma }^{2} )^{{(0)}} {\equals}0.01$
and
 $\lambda ^{{(0)}} {\equals}0.5$
where
 $x\in\{ x_{1} ,\,\ldots\,,x_{p} \} $
. The same set of values is also used for the simplified cohort model except that sampling of
 $\beta _{x}^{\gamma } $
is not required.
5.1.1. Full cohort model
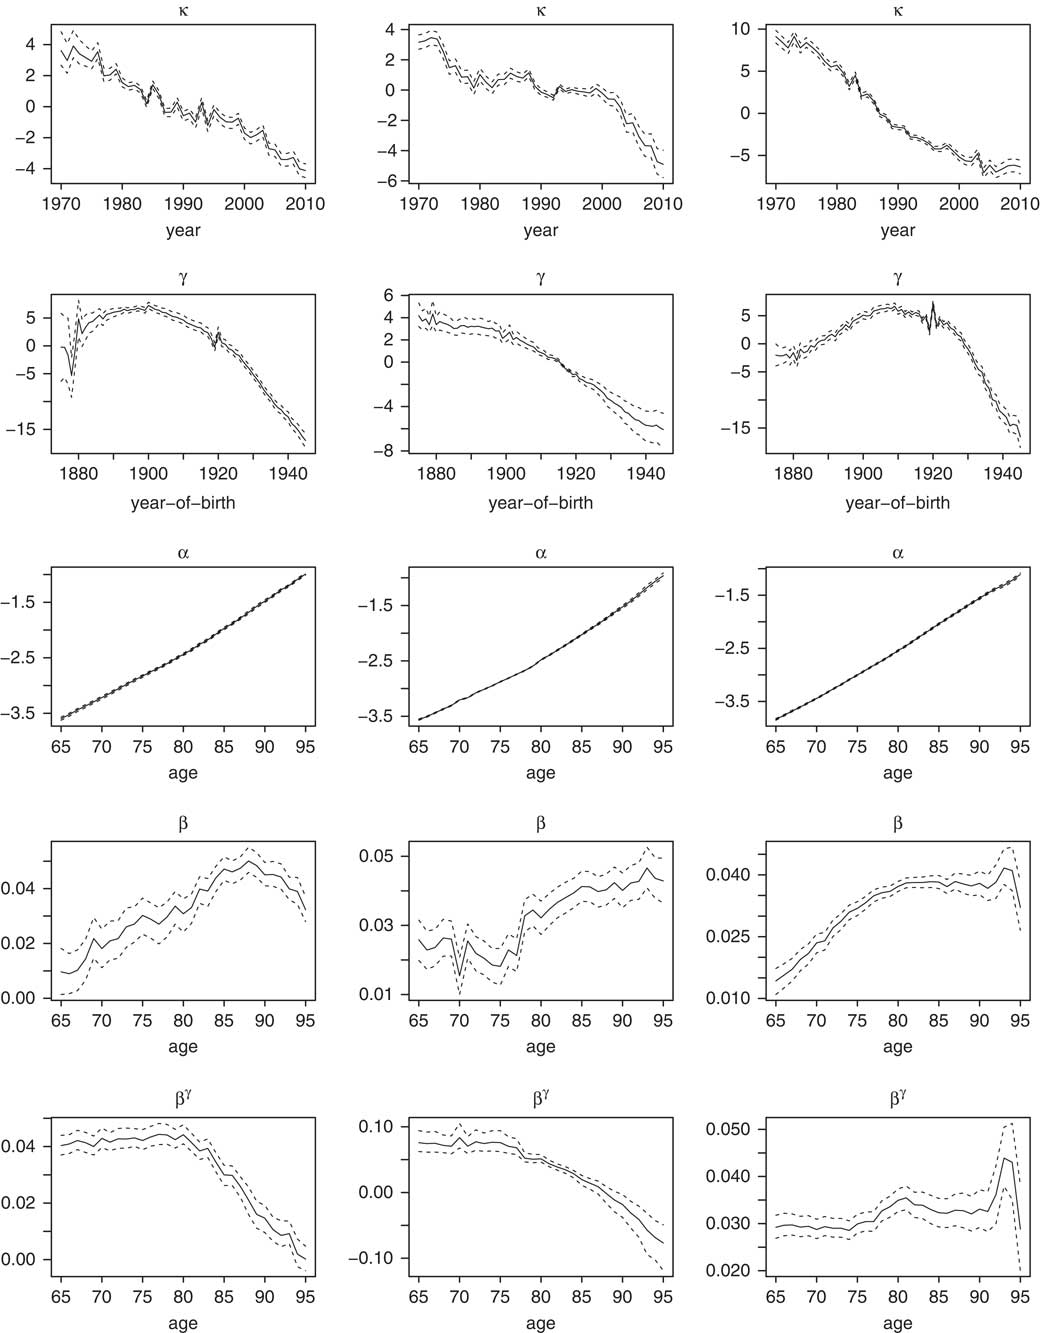
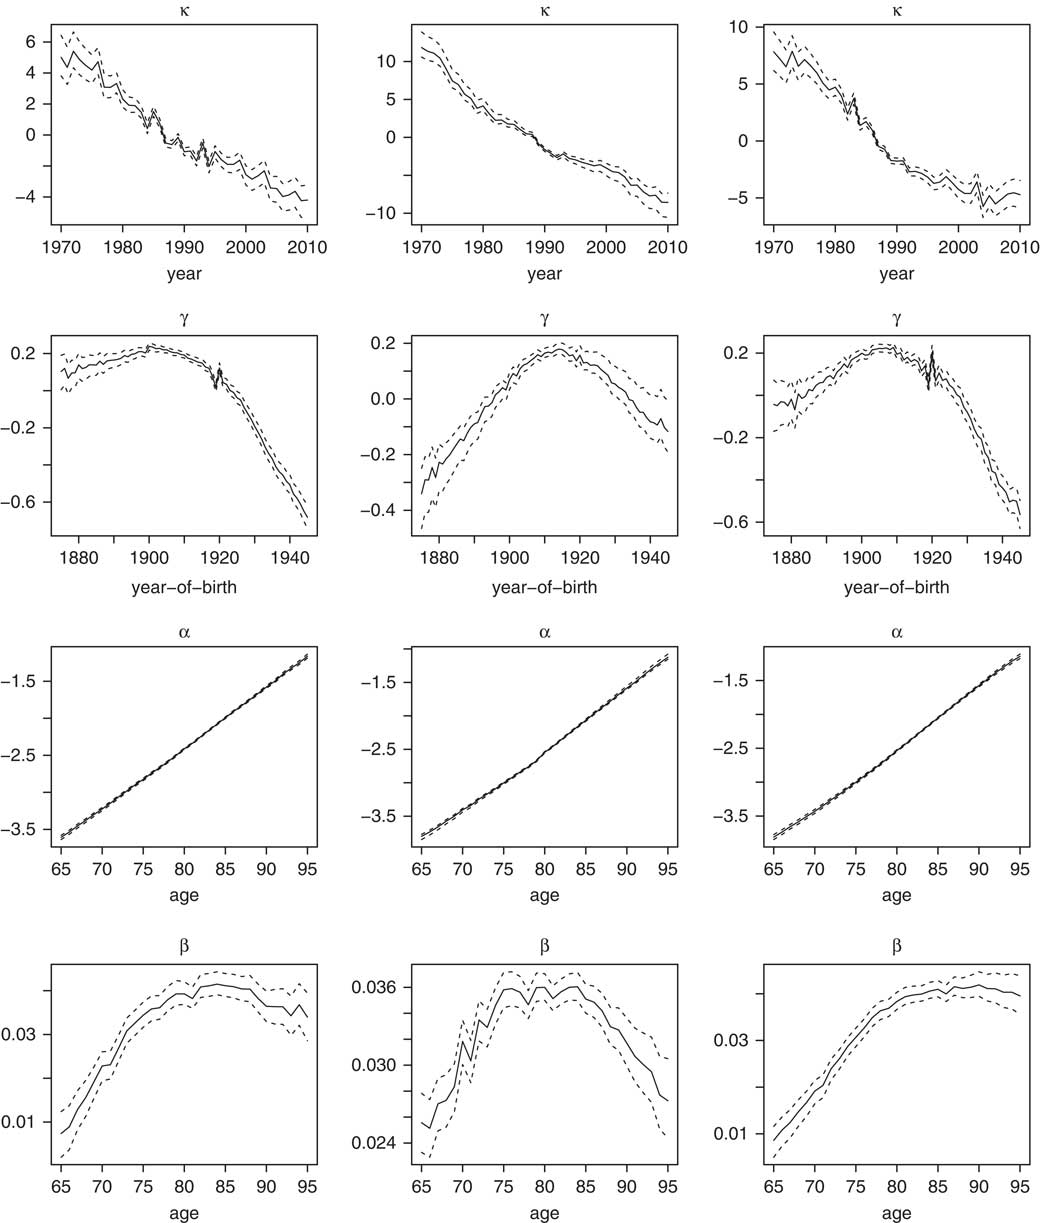
For the full cohort model, the posterior mean and 95% credible intervals for the parameters κ, γ, α, β and
 $\beta ^{\gamma } $
for the UK, US and Italy male populations are shown in Figure 1.
Full cohort model: estimated κ, γ, α, β and β γ for the (left column) UK, (middle column) US and (right column) Italy male populations. Mean (solid line) and 95% credible interval (dash lines) of the posterior distributions are plotted.

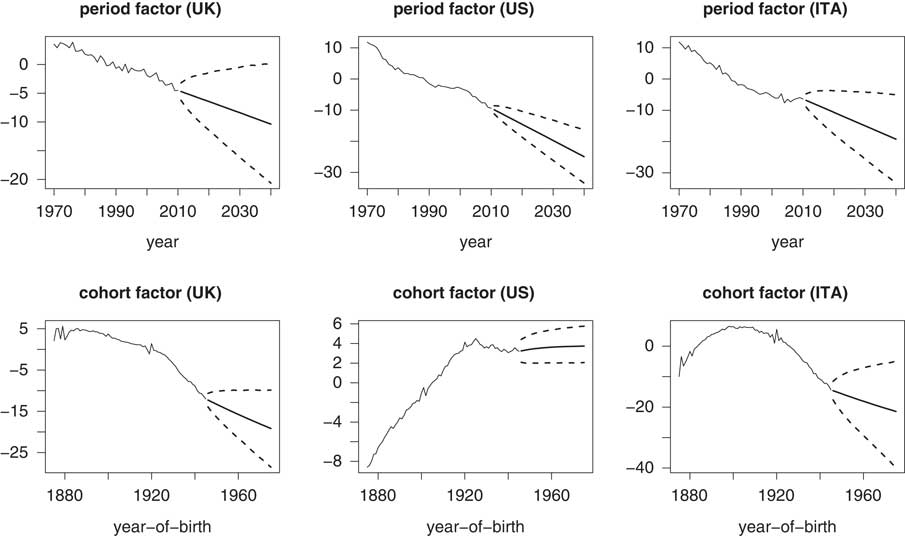
Given the linear trend observed, the assumption that the period effect follows a random walk with drift process seems to be reasonable for the UK and Italy male populations, but is less appropriate for the US male population where structural changes seem to be present for the considered age range (see also Li et al., Reference Li, Chan and Cheung2011; van Berkum et al., Reference van Berkum, Antonio and Vellekoop2016). The estimated cohort factor shows a clear kink around the year-of-birth at 1920 for the UK and Italy data. For the England and Wales population, Cairns et al. (Reference Cairns, Blake, Dowd and Kessler2016) finds evidence to suggest that the anomalies observed for the 1919 and 1920 cohorts are due to unusual pattern of births and the methodology employed to estimate mid-year population, which is related to the First World War. A mild kink also appears around the generation born in 1900 for the US population. The implication for these sudden changes of the cohort factor on model fit will be discussed in more details in section 5.2 where a comparison of the cohort models with the LC model through residuals is presented. The heightened volatility surrounding the first several years of the cohort factor can be attributed to having limited data that are used to infer the cohort factor for the very first birth years, thus creating greater uncertainty.
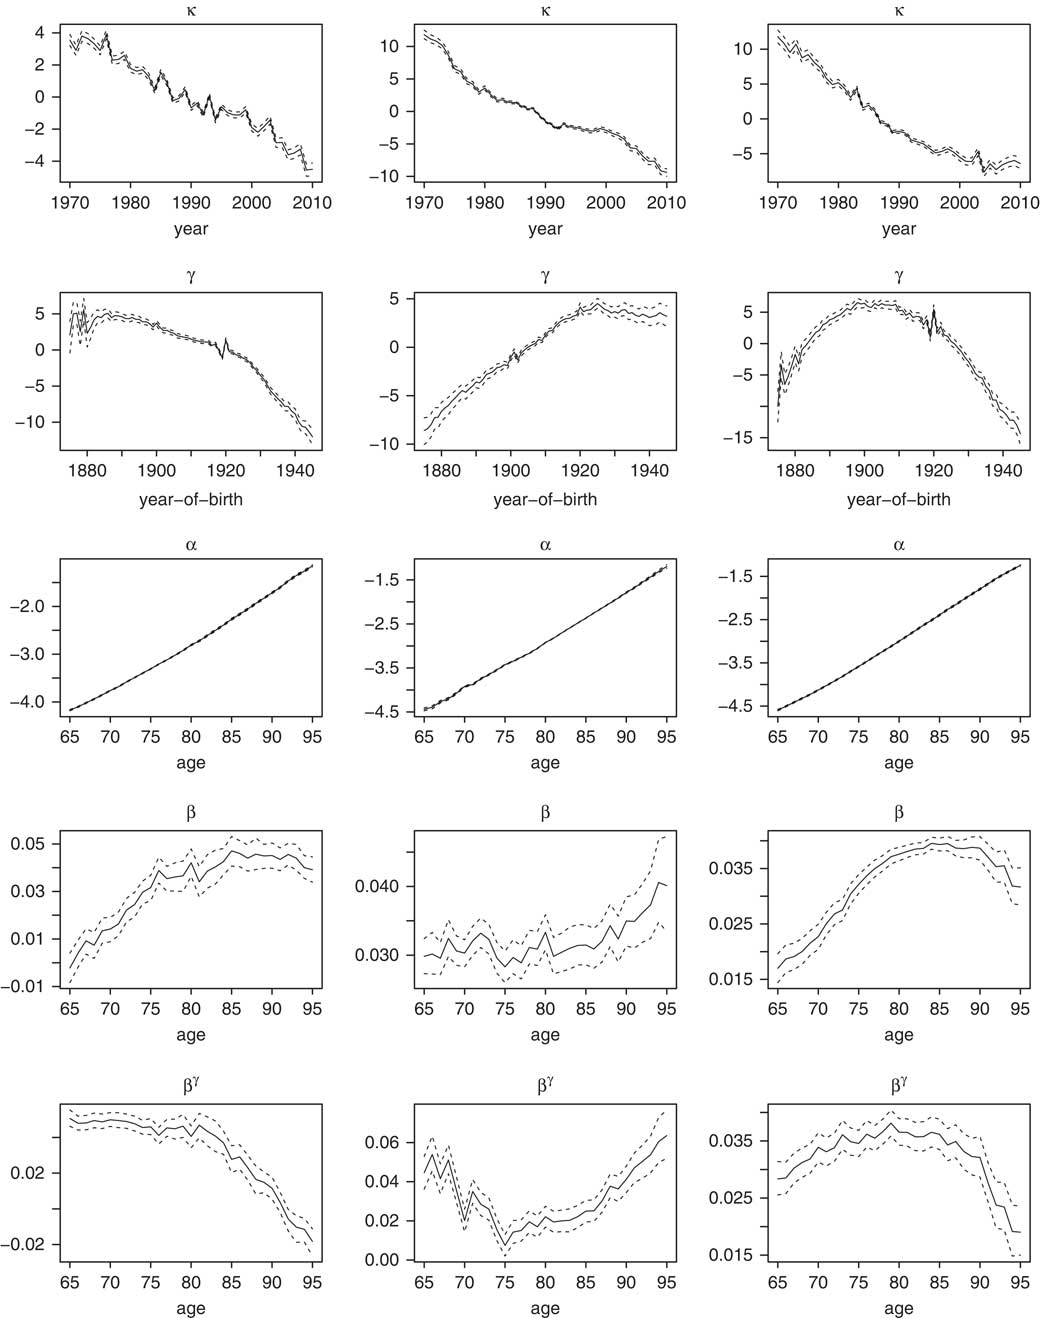
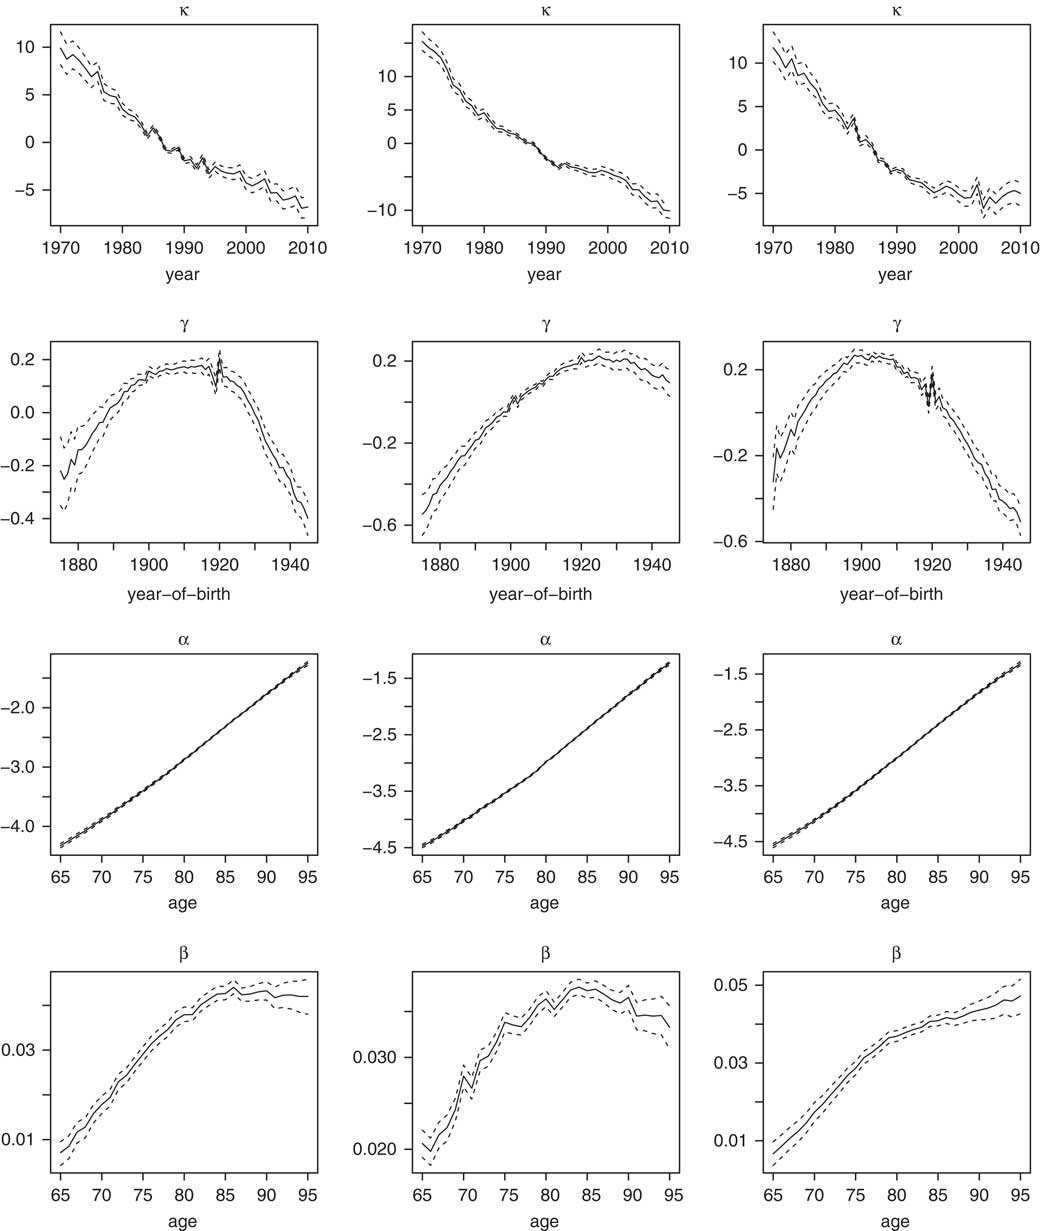
Figure 2 displays the corresponding results for female populations. We also observe similar patterns where the kinks in the cohort factors for the female populations appear at almost exactly the same generations as in the male populations. It suggests that, at least for the countries that we presented here, cohort effect is not gender-specific but is a common phenomenon for people who belong to a particular generation. Such a finding in this case can perhaps be attributed to shared mortality experience in both genders arising from a significant global effect for Europe, corresponding to the First and Second World War.
Full cohort model: estimated κ, γ, α, β and β γ for the (left column) UK, (middle column) US and (right column) Italy female populations. Mean (solid line) and 95% credible interval (dash lines) of the posterior distributions are plotted.

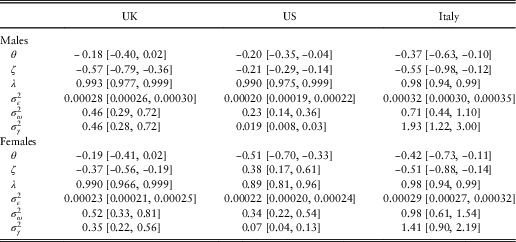
Posterior statistics for the other parameters are displayed in Table 3.
Estimated posterior mean of the static parameters for the full cohort model on male and female population data.

Note: [., .] next to the estimates represents 95% posterior credible interval.
5.1.2. Simplified cohort model
Figure 3 shows the posterior mean and 95% posterior credible intervals for the estimated parameters
κ
,
γ
,
α
,
β
where UK, US and Italy males mortality data are used to fit the simplified cohort model where it is assumed that
 $\beta _{x}^{\gamma } {\equals}1$
for all age x.
Simplified cohort model: estimated κ, γ, α and β for the (left column) UK, (middle column) US and (right column) Italy male populations. Mean (solid line) and 95% credible interval (dash lines) of the posterior distributions are plotted.

The estimated figures from the simplified cohort model share very similar patterns to those obtained from the full cohort model for the UK and Italy data. Interestingly, the same may not be said for the US data, as the estimated
κ
and
γ
are quite different to the corresponding ones obtained from the full cohort model. As the only difference between the simplified and the full cohort model is that
 $\beta _{x}^{\gamma } $
is allowed to be flexible in the full cohort model, the rather substantial difference for the estimated
κ
and
γ
between the simplified and full cohort models might indicate that perhaps the cohort effect is so weak in the data that the model could not distinguish the period effect and cohort effect. We will further examine the possibility of the lack of cohort effect in US mortality data in section 5.2. Note also that the estimated values of γ for the simplified model are significantly smaller than the full model. The reason for this is that the constraint
 $$\mathop{\sum}\NOlimits_x {\beta _{x}^{\gamma } {\equals}1} $$
for the full model dictates that
 $\beta _{x}^{\gamma } $
will take value in the order of 1/p which is substantially smaller than 1, where p=31 is the number of ages considered in the data; while
 $\beta _{x}^{\gamma } {\equals}1$
is assumed for the simplified model. One may consider fixing
 $\beta _{x}^{\gamma } {\equals}1/p$
in the simplified model so that the estimated values of γ will be in the same order of magnitude for both the simplified and full model. However this should not affect the fitting and forecasting of the resulting model.
The corresponding estimation results for female populations are shown in Figure 4. We again observe that the estimates show similarity between the male and female populations for all the three countries, thus suggesting that mortality experiences for both genders share major characteristics.
Simplified cohort model: estimated κ, γ, α and β for the (left column) UK, (middle column) US and (right column) Italy females populations. Mean (solid line) and 95% credible interval (dash lines) of the posterior distributions are plotted.

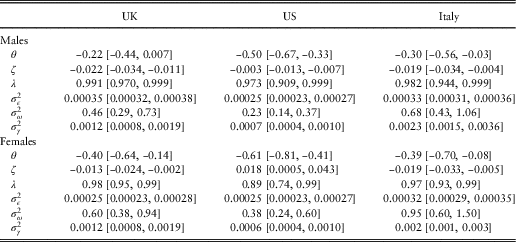
Posterior estimates for other static parameters for the simplified cohort model on male and female mortality data are reported in Table 4.
Estimated posterior mean of the static parameters for the simplified cohort model on male and female population data.

Note: [., .] represents 95% posterior credible interval.
5.1.3. Robustness of the Bayesian state-space approach
To compare the robustness of the estimation performance of the Bayesian state-space approach with the GLM approach (section 2.2), we have tested the estimation of cohort models via the GLM approach using the R package called StMoMo (Version 0.4.0), see Villegas et al. (Reference Villegas, Millossovich and Kaishev2015), Hunt and Villegas (Reference Hunt and Villegas2015).
We consider males mortality data from seven countries including US, UK, France, Australia, Denmark, Netherland and Italy. When fitting the cohort models in StMoMo (using the rh() function with log link), we employ the estimated parameters from the LC model as the initial values of the estimation scheme for the cohort models as suggested in Villegas et al. (Reference Villegas, Millossovich and Kaishev2015). The age range and year range are 65–95 and 1970–2010, respectively.
For the simplified cohort model, the estimation scheme under the GLM approach fails to converge for data from US, France and Netherland. In contrast, the Bayesian state-space approach is able to estimate the model for all mortality data from the countries considered with sensible results produced.
For the full cohort model, the GLM approach is successful in estimating the model for data from France and Italy while unsuccessful for data from US, UK, Australia, Denmark and Netherland. On the other hand, the Bayesian state-space approach is able to estimate the model for all mortality data from the countries considered again with sensible results produced.
It should be note that the population data we have considered are not exhaustive but the results suggest that the Bayesian state-space approach is more robust compared to the GLM approach for the estimation of cohort models confirming the robustness issues found in Hunt and Villegas (Reference Hunt and Villegas2015)Footnote 8 .
5.2. Model fitting: comparison with LC model
We examine the fitting of the cohort models via residual heatmap as well as model ranking via deviance information criterion (DIC). We emphasise the importance of a comparison for the cohort models with the LC model since if cohort patterns are present in mortality data, the ordinary LC model should not be able to capture this phenomenon but cohort models are designed to accomplish this.
5.2.1. Residual heatmap
Residuals under a state-space model are defined as the difference between the observed data y t and the mean of the in-sample one-step-ahead model forecast given by (see (34c))
 $${\Bbb E}\left[ {y_{t} \!\mid\! \psi ,y_{{1\,\colon\,t{\minus}1}} } \right]{\equals}f_{t} ,$$
where t=1, … , n. Explicitly, we have
 $$e_{t} \,\colon\!{\equals}y_{t} {\minus}f_{t} $$
where e t is the vector of residuals at time t. Using the posterior mean as point estimator for the static parameters, we obtain the mean of the in-sample one-step-ahead forecast f t via Kalman filtering for the cohort models and the LC model.
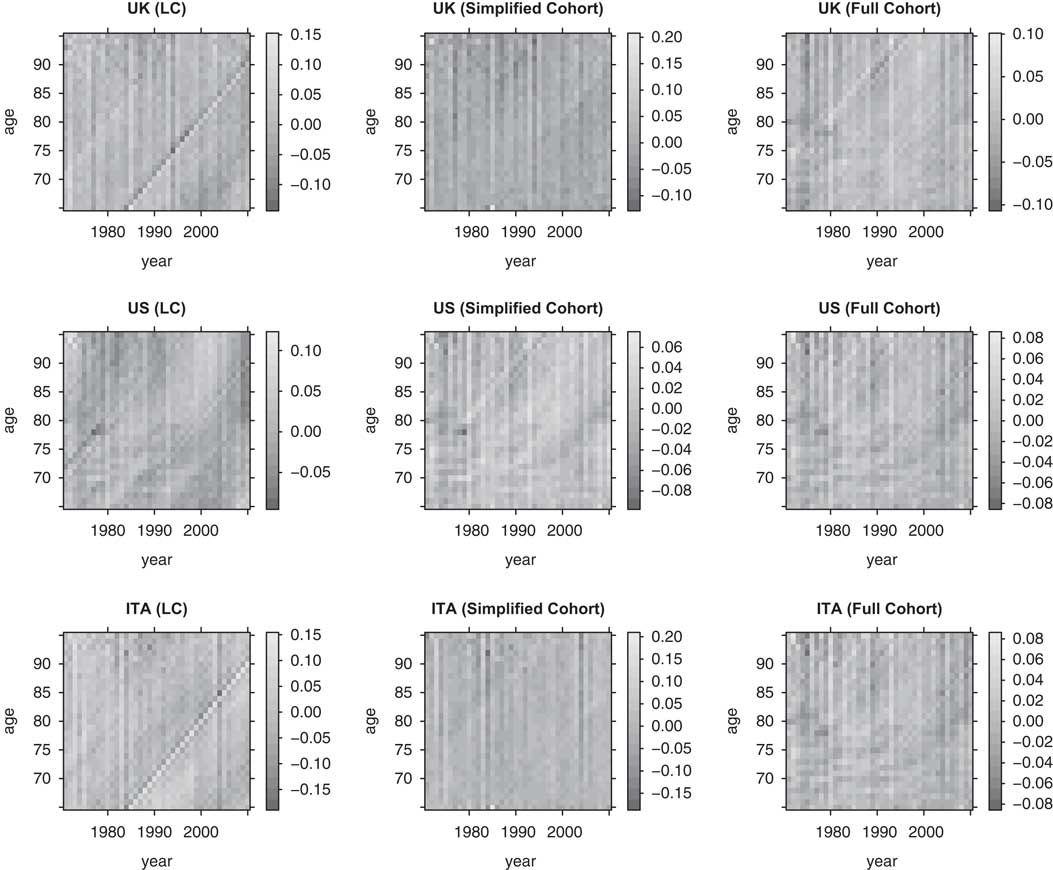
Figure 5 shows residual heatmaps produced from the LC model, the simplified cohort model and the full cohort model for the UK, US and Italy male populations. The distinctive diagonal bands observed for the fitting of the LC model for the UK and Italy population, which correspond to the generations born around 1920, clearly suggest that cohort effects are strongly present in these countries and the LC model fails to account for these patterns. In contrast, the cohort models considered are capable of capturing these effects which is supported by the observation that the diagonal bands are removed from the residual plots. These results are consistent with the estimated cohort factors shown in Figures 1 and 2 where an apparent irregularity appears around the cohort born in 1920.
Residual heatmap produced from the Lee–Carter model, the simplified cohort model and the full cohort model for the UK, US and Italy male populations.

Residual heatmap from the LC model for the US male population, on the other hand, shows only small traces of diagonal bands around the cohorts 1900 and 1920 which are barely noticeable. The corresponding plots from the cohort models show that these bands are diminished even further. The very faint occurrence of the diagonal bands for the US males data is compatible with the remarks suggested in section 5.1 that there is no clear evidence that the US male population exhibits certain cohort patterns.
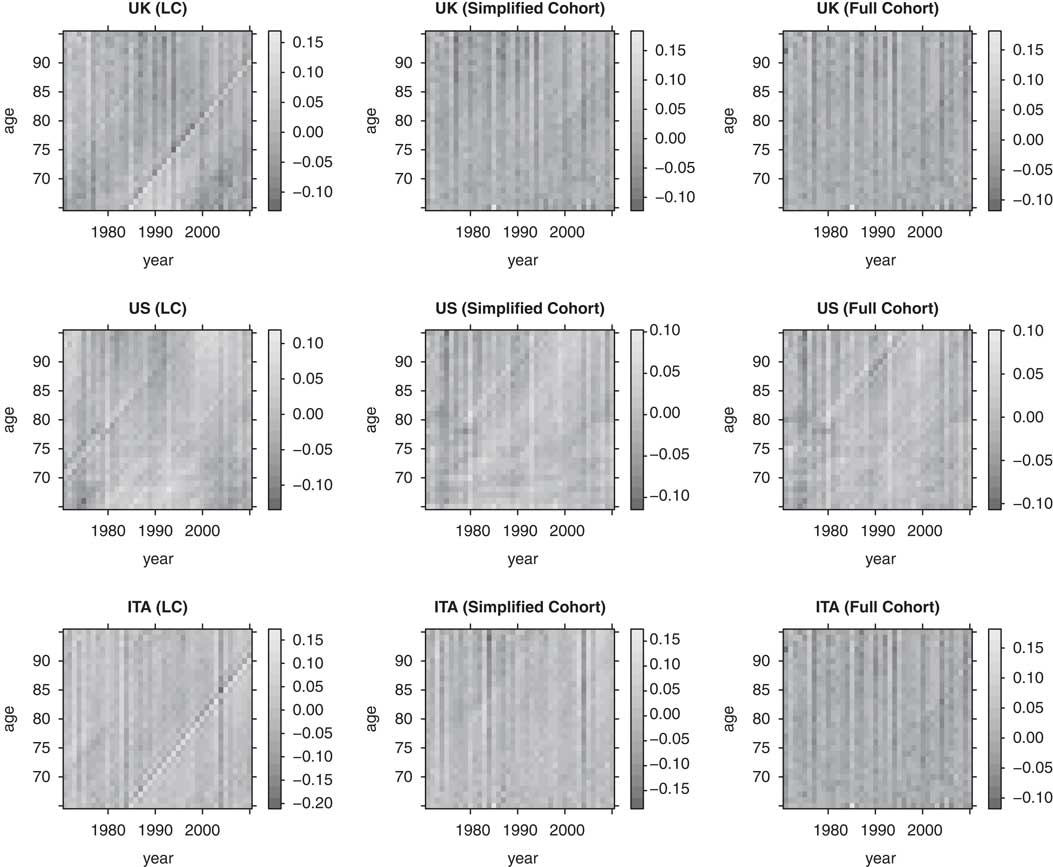
Corresponding residual heatmaps for the female populations are displayed in Figure 6. The results follow very closely to the discussion for the male populations. It provides further evidence that major mortality characteristics including cohort effects are not gender specific in the considered countries.
Residual heatmap produced from the Lee–Carter model, the simplified cohort model and the full cohort model for the UK, US and Italy female populations.

The residual plots shown here also suggest that the deciding factor for the presence of cohort patterns in a specific country depend on whether there are any abrupt irregularities observed in the estimated cohort factor; such non-smooth irregularities indicate that strong cohort patterns exist in the data where the LC model is not able to capture. On the other hand, if the estimated cohort factor is reasonably smooth as for the US data, cohort factors in mortality models may be not be required.
5.2.2. DIC
We perform model ranking using DIC which is designed specifically for Bayesian models taking into account the trade-off between model fits and complexity (Spiegelhalter et al., Reference Spiegelhalter, Best, Carlin and van der Linde2002). There are several versions of DIC and here we will focus on the so-called conditional DIC where the latent states are treated as parameters when calculating the conditional likelihood (Celeux et al., Reference Celeux, Forbes, Robert and Titterington2006; Chan and Grant, Reference Chan and Grant2016).
Specifically, the conditional DIC utilises the conditional log-likelihood which is given by
 $${\rm ln}\,\pi ({\mib{y}} _{{1\,\colon\,n}} \!\mid\! \psi ,\varphi _{{0\,\colon\,n}} ){\equals}{\minus}{1 \over 2}\mathop \sum\limits_{x{\equals}x_{1} }^{x_{p} } \mathop \sum\limits_{t{\equals}t_{1} }^{t_{n} } \left( {{\rm ln}2\pi \sigma _{{\epsilon}}^{2} {\plus}\left( {{{y_{{x,t}} {\minus}(\alpha _{x} {\plus}\beta _{x} \kappa _{t} {\plus}\beta _{x}^{\gamma } \gamma _{{t{\minus}x}} )} \over {\sigma _{{\epsilon}} }}} \right)^{2} } \right),$$
for the full cohort model; conditional log-likelihoods for the simplified cohort model and the LC model can be obtained similarly. Denote
 ${\bf \Psi }\,\colon\!{\equals}(\psi ,\varphi _{{0\,\colon\,n}} )$
, one defines
 $$D({\bf \Psi }){\equals}{\minus}2{\rm ln}\,\pi ({\bf y}_{{1\,\colon\,n}} \!\mid\! {\bf \Psi }){\plus}2{\rm ln}\,h({\bf y}_{{1\,\colon\,n}} ),$$
as the deviance of the model. As h( y 1:n ) is independent to the models considered, it is typical to assume h( y 1:n )=1. The effective number of parameters p D is defined to be
 $$p_{D} {\equals}\bar{D}({\bf \Psi }){\minus}D({\bf \bar{\Psi }}),$$
where
 $\bar{D}({\bf \Psi })$
is the mean of
 $D({\bf \Psi })$
while
 ${\bf \bar{\Psi }}$
is the posterior mean of
 ${\bf \Psi }$
. One then defines the conditional DIC as
 $${\rm DIC}\,\colon\!{\equals}\bar{D}({\bf \Psi }){\plus}p_{D} {\equals}2\bar{D}({\bf \Psi }){\minus}D({\bf \bar{\Psi }}),$$
which can be calculated using the MCMC samples obtained as described in section 4. Note that models with smaller DIC values are ranked higher then models with larger DIC values.
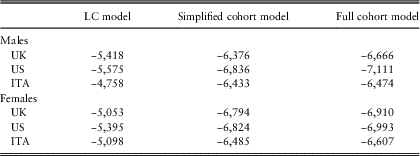
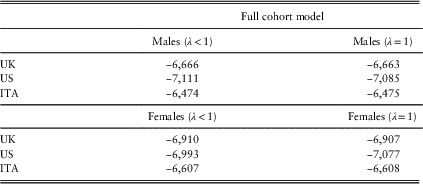
Table 5 reports the estimated conditional DIC values obtained for the considered models on male and female population data. We observe that the improved fits are more than compensated for the complexity arising from the inclusion of cohort factors for the considered countries based on the estimated DIC values. The improvement of model fits is more significant for the simplified cohort model over the LC model than the full cohort model over the simplified cohort model. Interestingly, there is a distinct improvement in using cohort models over the LC model on the US mortality data, despite the lack of cohort patterns for the US data shown in Figures 5 and 6. It suggests that multi-factor models are preferred for the US population over a single period factor model such as the LC model. Whether a multi-period model or a period-cohort model is preferred for the US data is an interesting question which is, however, beyond the scope of the current paper.
DIC values for the considered models on male and female population data.

Note: ITA, Italy.
5.3. Forecasting from cohort models
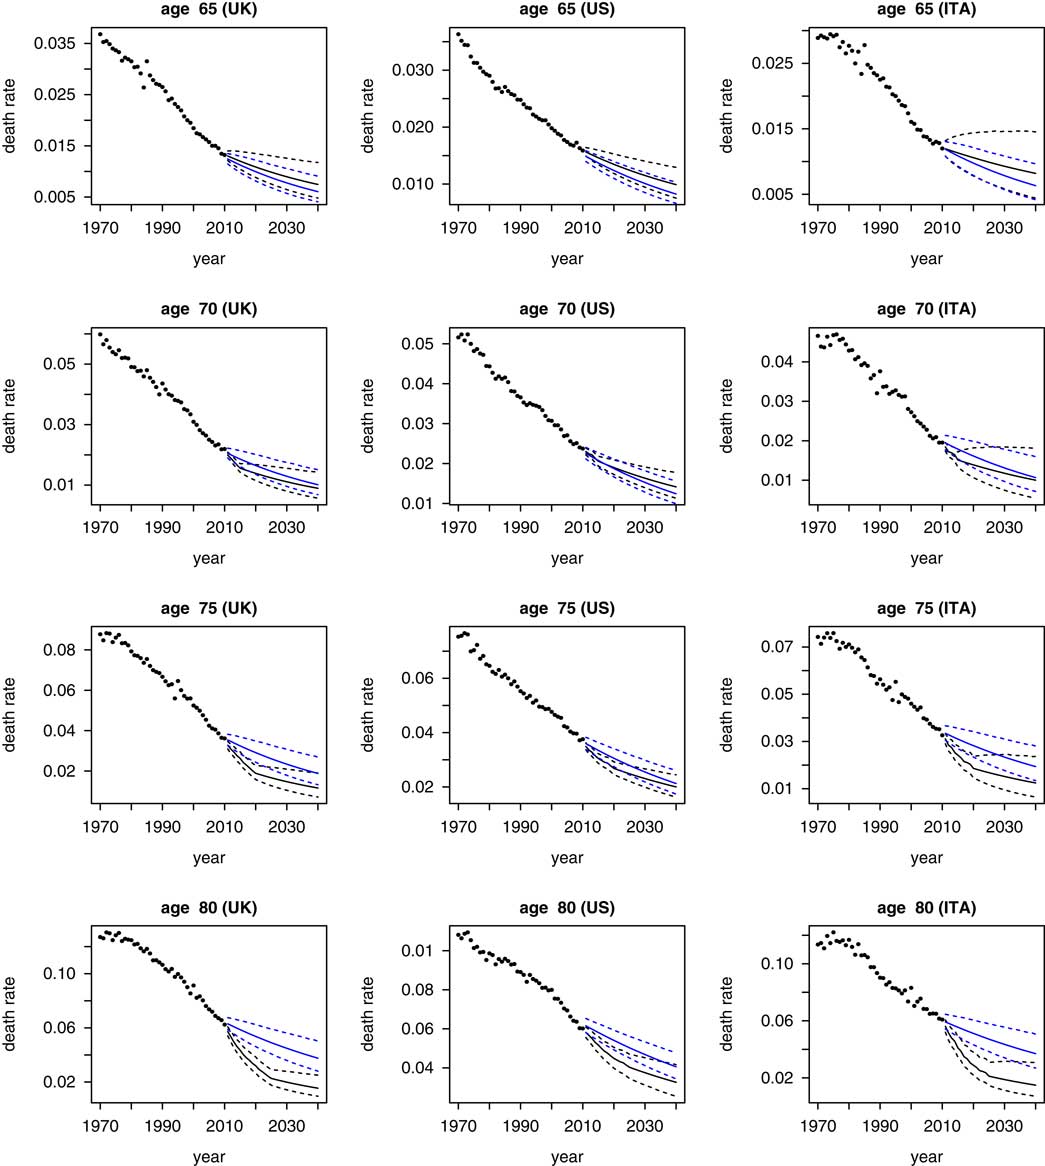
Forecasting of death rates for the cohort models and LC model is studied here. One of the advantages of considering Bayesian inference via MCMC sampling for state-space mortality models is that the forecasting distributions of death rates can be derived rigorously and the samples of the forecasting distributions can be easily generated from the samples obtained from the MCMC estimation step.
Explicitly, we can express the forecasting distribution for the cohort models as
 $$\pi ({\bf y}_{{n{\plus}k}} \!\mid\! {\bf y}_{{1\,\colon\,n}} ){\equals}\smallint ^ \pi ({\bf y}_{{n{\plus}k}} \!\mid\! \varphi _{{n{\plus}k}} ,\psi )\pi (\varphi _{{n{\plus}k}} \!\mid\! \varphi _{{n{\plus}k{\minus}1}} ,\psi )\,\ldots\,\pi (\varphi _{n} ,\psi \!\mid\! {\bf y}_{{1\,\colon\,n}} )\, {\rm }d{\mib{\psi }} d\varphi _{{n\,\colon\,n{\plus}k}} ,$$
where
 $\pi ({\bf y}_{{n{\plus}k}} \!\mid\! {\bf y}_{{1\,\colon\,n}} )$
is the k-step ahead forecasting posterior predictive distribution. It means that one can simulate the forecasting samples of the dynamic factors to obtain recursively the forecasting samples of death rates as follow
 $$\varphi _{{n{\plus}k}}^{{(\ell )}} \sim {\rm N}\left( {{\rm \Lambda }^{{(\ell )}} \varphi _{{n{\plus}k{\minus}1}}^{{(\ell )}} {\plus}{\rm \Theta }^{{(\ell )}} ,\Upsilon ^{{(\ell )}} } \right),$$
 $${\bf y}_{{n{\plus}k}}^{{(\ell )}} \sim {\rm N}\left( {\alpha ^{{(\ell )}} {\plus}B^{{(\ell )}} \varphi _{{n{\plus}k}}^{{(\ell )}} ,\left( {\sigma _{{\epsilon}}^{2} } \right)^{{(\ell )}} 1_{p} } \right),$$
for the full cohort model, where
 $\ell {\equals}1,\,\ldots\,,L$
and L is the number of MCMC samples after burn-in. For the simplified cohort model one simply replaces B by B
s
. Forecasting for the LC model can be carried out by setting φ=κ in (56) and forecasting samples of death rates are obtained recursively as follow
 $$\kappa _{{n{\plus}k}}^{{(\ell )}} \sim {\rm N}\left( {\kappa _{{n{\plus}k{\minus}1}}^{{(\ell )}} {\plus}\theta ^{{(\ell )}} ,\left( {\sigma _{\omega }^{2} } \right)^{{(\ell )}} } \right),$$
 $${\bf y}_{{n{\plus}k}}^{{(\ell )}} \sim {\rm N}\left( {\alpha ^{{(\ell )}} {\plus}\beta ^{{(\ell )}} \kappa _{{n{\plus}k}}^{{(\ell )}} ,\left( {\sigma _{{\epsilon}}^{2} } \right)^{{(\ell )}} 1_{p} } \right),$$
which is a special case of (57).
5.3.1. Projection of death rates
Figure 7 displays the mean and 95% posterior predictive forecast interval of the forecasted death rates from the full cohort model and LC model based on UK, US and Italy male mortality data for selected ages 65, 70, 75 and 80.
Forecast death rates for the UK, US and Italy male populations from the full cohort model (black lines) and the Lee–Carter model (blue lines). Solid circles: observed data; solid lines: posterior mean; dash lines: 95% forecasting interval.

We observe that forecasts from the full cohort model show substantial difference to the forecasts from the LC model for the UK and Italy populations, while the difference is noticeably smaller for the US data. It is consistent with our results found in sections 5.1 and 5.2 that fitting of the cohort models suggest that cohort effect is strong for the UK and Italy populations but is weak for the US mortality data. As a result, it is expected that, from the forecasting perspective, cohort models will show greater difference to the LC model for the UK and Italy data but will be less so for the US data, which is confirmed by the forecasting results shown here.
Another important observation is that there is a clear change of trend for the forecasted death rates from the full cohort model. A closer inspection suggests that the change appears at the generation born in 1945. For example, the change is located in year 2020 for the forecasted death rates for age 75, which corresponds to the cohort with year-of-birth at 1945; the same conclusion can be drawn from the forecasted death rates for other ages. Interestingly, the most recent generation considered in our data is exactly the year-of-birth at 1945Footnote 9 . This observation indicates that this change of trend behaviour is a consequence of the projection of the cohort factor which starts at 1945Footnote 10 . We provide further discussion on this issue in details in section 5.3.2.
The corresponding forecasting distributions based on female mortality data are shown in Figure 8. The observations remarked above can also be applied in this case. As discussed in sections 5.1 and 5.2, we find that male and female populations in the studied countries show similar mortality features including cohort patterns in terms of model fitting. The result here signals that the same can be said from the forecasting standpoint.
Forecast death rates for the UK, US and Italy female populations from the full cohort model (black lines) and the Lee–Carter model (blue lines). Solid circles: observed data; solid lines: posterior mean; dash lines: 95% forecasting interval.

A comparison of forecasting from the full cohort model and the simplified cohort model is shown in Figure 9 for the male populations and in Figure 10 for the female populations. It is clear that the full and simplified models generate similar forecasting distribution for the UK and Italy populations. However, the forecasting intervals produced by the simplified model are substantially wider than the intervals generated by the full cohort model for the US male population; the difference is even more pronounced for the female populations. These results suggest that if cohort patterns are strongly present in the data, then there is little difference between the full model and the simplified model in terms of model fitting and forecasting. On the contrary, if the data show only a weak presence of cohort patterns, the full cohort model can lead to significant different fitting and forecasting results to the simplified cohort model, which indicates that cohort models may not be required in this case.
Forecast death rates for the UK, US and Italy male populations from the full cohort model (black lines) and the simplified cohort model (red lines). Solid circles: observed data; solid lines: posterior mean; dash lines: 95% forecasting interval.

Forecast death rates for the UK, US and Italy female populations from the full cohort model (black lines) and the simplified cohort model (red lines). Solid circles: observed data; solid lines: posterior mean; dash lines: 95% forecasting interval.

5.3.2. Projection of period and cohort factors
The regular occurrence of trend-changing behaviour of the forecasted death rates at year-of-birth 1945, which was discussed in section 5.3.1, suggest that this phenomenon may originate from the projection of cohort factor starting at year-of-birth 1945.
To investigate this, we plot the projection of the period and cohort factors from the full cohort model in Figure 11 for the male populations and Figure 12 for the female populations in the considered countries.
Projection of the period factor κ and cohort factor γ from the full cohort model for the UK, US and Italy male populations.

Projection of the period factor κ and cohort factor γ from the full cohort model for the UK, US and Italy female populations.

We first notice that the projected period factor continues the linear trend as expected for both genders in UK, US and Italy populations. It reassures that the projection of the period factor behaves properly and therefore we should focus on the projection of the cohort factor to explain the aforementioned trend-changing behaviour.
Interestingly, we observe from the male populations that there is a slight change of direction of the projected cohort factor starting from the year 1945 compared to the trend during the calibration period 1920–1945 in the UK population. We observe essentially no change of direction for the US population and a significant change of direction for the Italy population. The same observation also applies to the female mortality data.
These results strongly indicate that whether a change of trend will be observed for the forecasted death rates depend on the property of the projected cohort factor; namely it depends on whether there will be a change of direction from the estimated cohort factor when the projection starts. In the UK and Italy cases, the change of direction of the projected cohort factor at year 1945 is observed and hence results in the trend-changing behaviour of the forecasted death rates shown in Figures 7 and 8, in contrast to the case of US data. Note also that these results are consistent with our discussion in previous sections that cohort patterns are strongly presence in the UK and Italy data while for the US data cohort patterns are not clear.
To investigate the consequences of using non-stationary process to model the cohort factor under the Bayesian state-space framework, we also considered the random walk with drift process to model the cohort factor by fixing λ=1 in our estimation of the full cohort model. However, in our setup we found that there is essentially no difference of assuming λ<1 (stationary process) and λ=1 (non-stationary) in terms of DIC, see Table 6.
DIC values for the full cohort models on male and female population data for cases with λ<1 and λ=1.

Note: ITA, Italy.
The estimated cohort factors shown in Figures 1–4 in fact raise questions about whether it is reasonable to assume that cohort factor dynamics can be captured by stationary ARIMA models which are commonly found in the literature. One may argue that cohort factors apparently exhibit trend changing behaviour. Recently there are growing interests in applying structural change dynamics for the period factor, see Li et al. (Reference Li, Chan and Cheung2011), van Berkum et al. (Reference van Berkum, Antonio and Vellekoop2016) and Liu and Li (Reference Liu and Li2017). The results suggest that this new type of models may be equally suitable for the cohort factor dynamics. However the investigation of this issue is out-of-scope of the current paper and will be left for future research.
6. Conclusion
In this paper we investigate the formulation, estimation and forecasting of cohort models under the state-space approach. The state-space framework provides a unified environment where estimation and forecasting of dynamics mortality models can be carried out in a statistically rigorous manner. Continuing development of advanced statistical techniques in numerical filtering and model estimations suggest that state-space method can be an essential tool to handle the modelling of human mortality. The paper contributes to the literature in this area by showing that cohort models are compatible with the state-space framework.
We demonstrate in this paper that the problem of cohort factors being indexed according to year-of-birth instead of year can be overcome by considering a multi-dimensional state-space system. The defining property of the cohort factor imposes a restriction on the observation and state equations of the resulting state-space mortality model. Dynamics of the period and cohort factors are specified in the state equation which allows for a range of time series models to be considered.
By treating the period and cohort factors as the state dynamics of a state-space model, Bayesian inference for cohort models can be performed based on filtering and MCMC method. We develop an efficient MCMC sampler for the resulting model involving a combination of conjugate Gibbs sampling steps for the static parameters and a forward-backward Kalman filtering for the latent state dynamics. The overall algorithm can be applied naturally to the full cohort model as well as its nested models including the simplified cohort model and the LC model.
We apply the cohort models in state-space formulation to analyse male and female mortality data of the UK, US and Italy population. The Bayesian approach allows us to present estimation of the cohort models where parameter uncertainty is properly quantified and accounted for. Our empirical studies show that UK and Italy populations exhibit strong cohort patterns while cohort patterns for the US population are weak. We also find that both genders share common mortality characteristics including cohort effects for the considered countries. Examination of residual heatmaps produced from the cohort models and LC model suggest that cohort models are able to capture cohort effects while the LC model fails to do so. Using DIC for model ranking, we find that the full cohort model is preferred over the simplified cohort model, which in turn outperform the LC model for the considered countries. We show that forecasted death rates from cohort models display trend-changing behaviour at the year where cohort factors are projected, for countries that show strong presence of cohort patterns.
Our estimation and forecasting studies of state-space cohort models suggest that more sophisticated models such as structural change models may be required to capture the dynamics of cohort factors adequately. Moreover, the observed mortality characteristics shared by both genders indicate that one can generalise the approach proposed in this paper to multi-population setting where common period and cohort factors can be assumed for male and female populations within a country. Recently there are also growing interests in applying state-space method to deal with the problem of pricing and hedging of longevity risk (Liu and Li, Reference Liu and Li2016, Reference Liu and Li2017). The approach presented in this paper can significantly enhance the capability of the state-space methodology to solving practical problems involving longevity risk since cohort models are shown to be compatible with the state-space framework. Applications of the state-space cohort models studied in this paper to the key issues in longevity risk pricing and management will be left for future research.
Acknowledgements
This research was supported by the CSIRO-Monash Superannuation Research Cluster, a collaboration among CSIRO, Monash University, Griffith University, the University of Western Australia, the University of Warwick, and stakeholders of the retirement system in the interest of better outcomes for all. This research was also partially supported under the Australian Research Council’s Discovery Projects funding scheme (project number: DP160103489). We acknowledge the grant of the interdisciplinary project “Research on Urban Intelligence” from Research Organization of Information and Systems in Japan.